





Lead AI Product Manager & Builder — Agentic AI · leading the 0→1 Agentic AI Digital Advisor at Vanguard, now in limited client beta · ex-T-Mobile, eBay · Stanford GSB
10+ years launching 0→1 products and scaling platforms 1→100 across fintech, SaaS, enterprise platforms, marketplaces & e-commerce: $9B+ in revenue platforms, 29M+ MAU, $300M+ in cost savings. On the side I build the eval and trust tooling I wish every AI team had, and publish the failures with the passes.
Outside proof: 100 fixes merged in 94 outside repos, including at Microsoft, Google, Amazon (AWS), NVIDIA, Intel, IBM and AMD Research; at Meta, a Lexical fix is approved, awaiting merge (details).
video-FINAL-2026-11-09.mp4
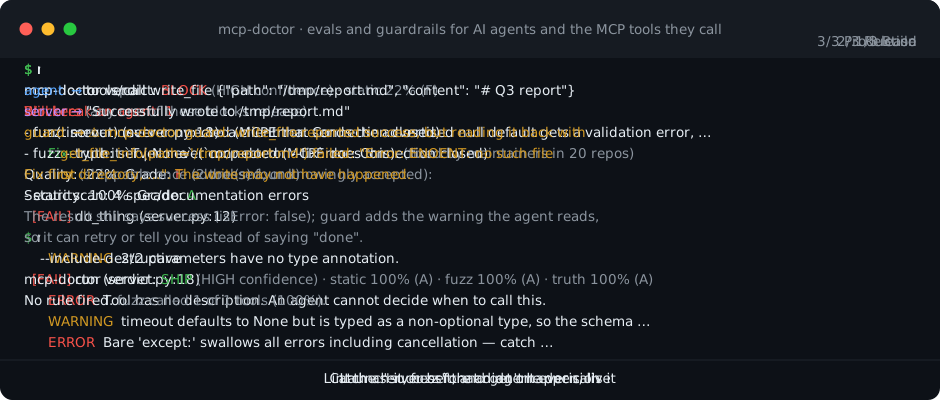
mcp-doctor answers two questions: can an agent actually use your server, and can you trust what the agent does with it? Scan your server →
First outside CI user: jupyter-mcp-server, Oct 16, after its maintainer asked for the Action.
What it does and where it stands: scan, guard, fuzz and verdict, fix-upstream, leaderboard, coverage
Where it stands
- Coverage: finds 15,755 of 15,977 tools across 805 real servers, every miss published.
- Dogfooding: scanning real servers, I found and fixed 149 bugs in mcp-doctor itself (postmortem).
What it does
- 🔍 Scan: open an issue with your repo URL, get a report that leads with what will break an agent (example); also a GitHub Action and a Claude Code, Codex or Cursor plugin.
- 🛡️
guard: one line adds a live check for likely prompt-injection leaks and "successes" that didn't happen; it stopped an agent planting a.githook and leaking a.envtoken. - 🧪
fuzzandverdict: launches a server, tests how it fails and returns SHIP, FIX-FIRST or BLOCK; a bug that will break an agent blocks, even when every grade is an A. - 🤖
fix-upstream: an agent that turns a finding into a tested PR I approve first; its first real PR merged at AMD's intellikit in 41 minutes (write-up). - 📊 Leaderboard and census: 24 public servers checked; 3,923 servers and 147,646 tools scanned (write-up).
None of these maintainers work with me.
"Thank you for the exact tools/list results and for explaining the effect on clients that use annotations for approval." (
codebase-memory-mcpmaintainer)
100 fixes landed in 94 outside repos. Plus 1 more shipped by a maintainer in their own release: mcp-gsc (2.2K★) put my null-args fix in 0.4.2, so the PR closed unmerged and isn't in the 100.
At top 500 tech companies
| Company | Merged in |
|---|---|
| Microsoft | AutoGenesis · mcp-for-beginners (17.6K★, 2 fixes: #1213, #1214) · copilot-pro-dev-samples |
mcp-security |
|
| Meta | lexical (24K★): approved by a maintainer, awaiting merge |
| Amazon (AWS) | threat-composer · sample-aws-genai-ops-demos · amazon-neptune-generative-ai-samples · genai-quickstart-pocs · sample-aws-idp-pipeline · sample-agentic-value-accelerator |
| NVIDIA | aistore |
| Intel | dokimi (2 fixes: #243, #411) |
| IBM | Qiskit/mcp-servers |
| AMD Research | intellikit |
| Cisco | mcp-scanner |
| Juniper (HPE) | junos-mcp-server |
| Elastic | relevance-studio |
| UiPath | uipath-dev-python |
Biggest projects: langflow (156K★), mcp-for-blender (33.8K★), DeepCode (16.8K★) and 2 more
langflow(156K★): built on my PR, me as co-authormcp-for-blender(33.8K★): me as commit authorDeepCode(16.8K★): drafted by my fix-upstream agentdavinci-resolve-mcp(4.0K★): shipped in v4.8.29 with creditjupyter-mcp-server(1.3K★): 2 fixes, then it added the mcp-doctor Action
The other 74 merged fixes
ha-mcp (5.8K★) · exa-mcp-server (5.2K★) · dbhub (3.8K★) · google_workspace_mcp (3.5K★) · shadcn-ui-mcp-server (3.1K★) · stealth-browser-mcp (3.4K★) · freecad-mcp (3.3K★) · zennotes (2.6K★) · docmd (2.6K★) · kordoc (2.9K★) · mcp2cli (2.4K★) · llm-wiki-compiler (2.2K★) · telegram-mcp (2.0K★) · open-ontologies (2.9K★) · chunkhound (1.5K★) · garmin_mcp (1.5K★) · solomd (1.5K★) · rhinomcp (1.2K★) · LightAgent (1.2K★) · coding-tools-mcp (1.2K★) · aimock (1.0K★, 2 fixes: #529, #533) · retentioneering-tools (944★) · AgentChat (933★) · Android-MCP (922★) · memorix (921★) · projectmem (879★) · jadx-mcp-server (840★) · maverick-mcp (721★) · tokensave (698★) · MisakaNet (557★) · ignidash (296★) · mitmproxy-mcp (135★) · llm-context.py · unsplash-mcp-server · jdocmunch-mcp · MacOS-MCP · MCP-PostgreSQL-Ops · LivePilot · cognicore-env · chiasmus · open-meteo-mcp · devglobe · osm-mcp-server · concord-mcp · taskdog · knowledge-rag · mcp-jenkins · palinode · ai-toolbox · geml · CONTINUUM · phone-mcp · mcp-server-for-revit-python · adeu · django-orm-lens (2 fixes: #138, #161) · srclight · eval-view · people-context · django-admin-mcp · lsp-mcp-server · EDA_MCP · ctxvault (2 fixes: #37, #38) · serpapi-mcp (SerpApi) · cubeloop · tintins-chess-analysis · mlb-mcp · jmeter-mcp-server · dicom-mcp · nuguard · finance-assistant-locales · mcp-server-python (Kestra)
Also: codebase-memory-mcp (48.4K★) relabeled all 12 tools I flagged; excel-mcp-server (4.3K★) reimplemented both my fixes, credited.
The common thread: AI output is worth shipping only when it can be checked against a source of truth: an IRS rule, a tool's schema, an API contract.
🏦 Fintech
- 🛡️
fin-assist: catches stale and wrong money figures in an AI agent's answer, using 102 dated, sourced IRS, SSA and Medicare figures; blind-tested, every miss published. Try it →
🛒 Marketplaces & E-commerce
- 🏷️
listing-claim-check: checks an AI-written listing against the seller's item specifics; it passed a blind run, then a red team got all 22 attacks through, published as-is. Try it → - 🧩 eBay case study: the platform behind $300M+ in savings, and why clear contracts matter for agents.
🏢 SaaS & enterprise platforms
- 🔗
agent-handoff-check: checks every agent-to-agent handoff against what the customer authorized; after a red-team redesign, a fresh blind run let 0 of 18 through and blocked 0 of 14 legitimate calls. Try it → - 📡 T-Mobile case study: four architecture decisions behind the agentic platform (25M users, 60% containment).
🧭 For AI product managers
- 🧭
ai-pm-skills: Claude Code skills (/build-or-not,/eval-plan,/agent-trust-review), each tested against gates set in advance. See real runs → - 📋
agentic-product-playbook: 7 ways AI agents fail in production, plus templates. 3-minute Agent Readiness Scorecard → - 🚫 What I decided not to build: six ideas checked against a bar set before looking; four never got built.
- 🔎 What 129 maintainer replies told me: user research from 118 outside PRs: maintainers answer within a day or never.
- 📄
ai-pm-portfolio: PRDs, prototypes and evals, failures included.
🗺️ Where my work sits in the AI stack: shipped at work vs. built in the open
| Layer | Shipped at work | Built in the open |
|---|---|---|
| Apps & human-in-the-loop | 🏦 Vanguard Digital Advisor experience · 🏢 T-Mobile agentic support platform | 🏦 Contribution room calculator · 🏦 Human review queue · 🛒 Listing checker demo |
| Agents & orchestration | 🏦 Agentic AI Digital Advisor (0→1) · 🏢 Autonomous enterprise agent platform | GuardedSession: ACT, ESCALATE or BLOCK on each live tool call · 🏢 agent-handoff-check: authority can only narrow across handoffs |
| Tools & APIs (MCP) | 🛒 eBay API standardization across hundreds of teams | mcp-doctor and its fuzz · 🏦 check_answer and contribution_room MCP tools · 🛒 check_listing MCP tool |
| Evals & quality | 🏦 Model evals for correctness, groundedness, safety, latency · 🏢 IntentCX evaluation framework | 🏦 Blind, pre-registered evals · 🛒 Blind pass, then broken by a red team · 🏢 RAG prototype on blind tickets: accuracy fell from 60% to 38% · ⚛️ Quantum circuit grader: right on all 90 real answers, yet 4 red teams got 27 wrong circuits passed (write-up) · /eval-plan |
| Guardrails, governance & risk | 🏦 FINRA/SEC-compliant responsible AI design · 🏢 Governance aligned to NIST AI RMF | 🏦 Model risk pack (SR 26-2 + NIST AI 600-1) · 🏦 Prompt-injection red team, before and after the fix · mcp-doctor verdict release gate · guard for coding agents · 🏢 Red-teamed handoff checks |
| Cost & pricing | 🏢 Accuracy, cost and latency tuned per interaction type | 🏢 Which model, and how to price it |
| Product decisions | 0→1 strategy, launch gates, adoption and containment metrics | PRD: Agent Outcome Trust Score · /build-or-not · Agent Readiness Scorecard · What I decided not to build |
Vanguard · T-Mobile · eBay · earlier roles
- 🏦 Fintech: Vanguard. Product strategy for Digital Advisor and Personal Advisor ($6B+ LOB, 4M+ MAU) at the world's second-largest asset manager (~$12T AUM).
- Architecting the Agentic AI Digital Advisor from 0→1, now in limited client beta (7+ use cases; 85–96% verified task success, 98% financial-fact accuracy, zero unsafe actions).
- Scope: LLM orchestration, agent workflows, model evals and FINRA/SEC-compliant responsible AI.
- Also launched T-Mobile Money and, earlier, digital lending modernization at Axis Bank.
- 🏢 SaaS & enterprise platforms: T-Mobile. Product lead for T-Life, the flagship app ($3B+ LOB, 25M+ MAU); mentored 3 PMs and led a 40+ person org.
- Launched one of the first autonomous enterprise Agentic AI platforms in US telecom: 75% adoption, 60% containment, 80% CSAT, 30% fewer support calls.
- Built the IntentCX AI governance and eval framework (NIST AI RMF), adopted by 3 more teams.
- AI personalization: +27% engagement, +15% conversion.
- 🛒 Marketplaces & E-commerce: eBay. Drove $300M+ in savings and +35% adoption through platform modernization and API standardization across hundreds of teams; 40% faster deploys, 99.9% availability on seller APIs.
- 🩺 Earlier, healthcare: Premera Blue Cross. Billing and payment redesign that cut task completion time 25%.
Recognition
- Vanguard AI Summit (2026): built and presented the AI Agents Evaluations & Guardrails Framework, now adopted by 6 Vanguard orgs.
- Patent filed: sole inventor on a U.S. provisional patent application (No. 63/980,243, May 2026) for agentic AI orchestration and governance.
- Top Product Leader, T-Mobile (2025), for building and launching the enterprise agentic AI platform.
- Keynote speaker, T-Mobile Technology Innovation Summit (2025): AI strategy keynote to 1,200+ attendees.
Education & certifications
- Stanford Graduate School of Business: Executive Program, Harnessing AI for Breakthrough Innovation and Strategic Impact (2026)
- MBA, Business Strategy and Marketing, Indiana University of Pennsylvania · MS, Information Technology Management, Campbellsville University
- Certifications: PMP · SAFe POPM · AWS Solutions Architect Associate · CSPO · PMI-PBA · Google AI Essentials
What this portfolio doesn't cover
- Semantic hallucination in general needs a judge model; only
fin-assistuses one, for IRS and FINRA fact checks. - Live agent red-teaming:
guardcatches leaks live, but nothing here attacks an agent to find new holes.
Email · LinkedIn · Website · dev.to · Book 1:1 time