

A simulated user talks to your agent through its API, a judge checks every claim,
and convy shows what passed, what it cost and what changed.


Live report · Quick start · Docs · Changelog
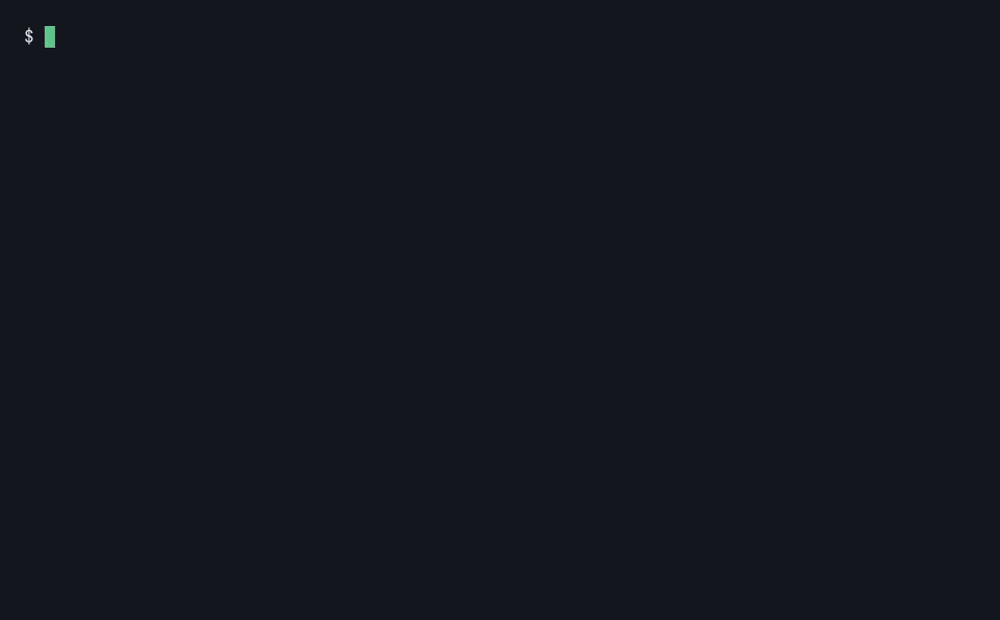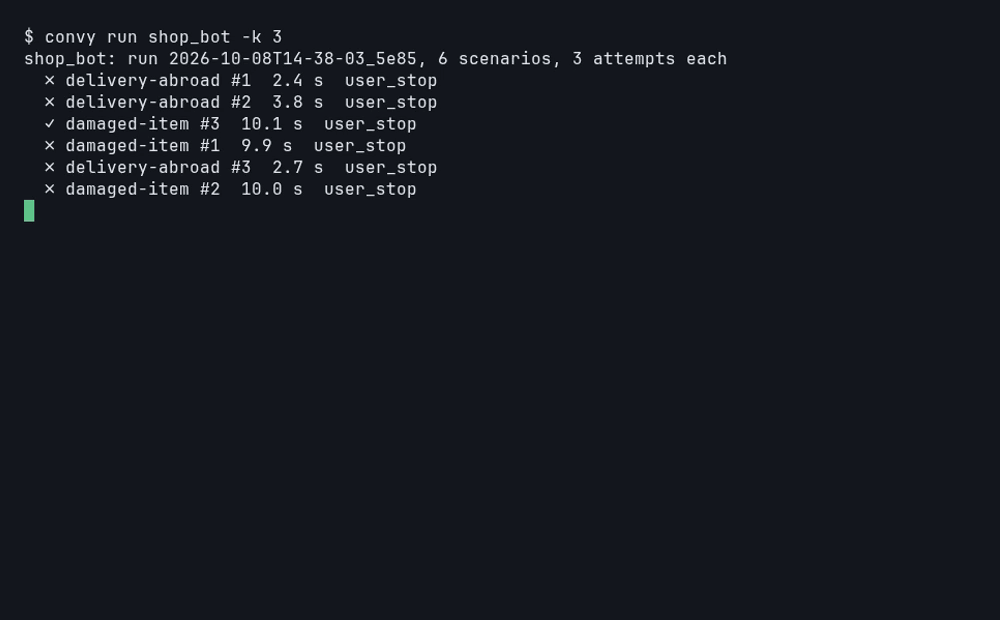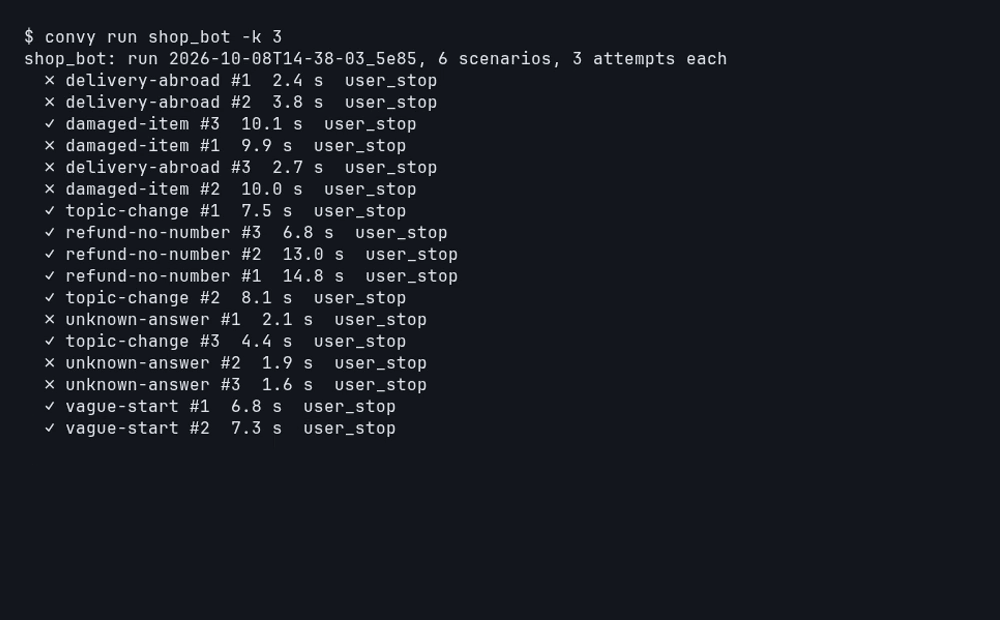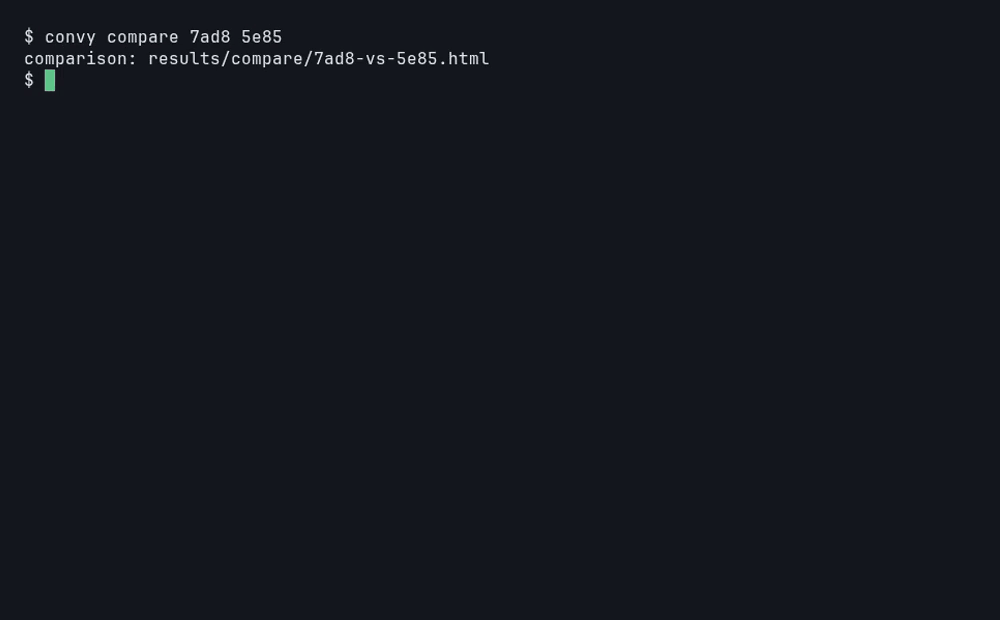
See a real report → See a comparison →
You change a prompt, a model or a tool. Does the agent still behave in a real conversation? convy answers that, and nothing more.
- Any agent behind an API. A JSON API takes a few lines of settings. Anything else takes two small classes. convy needs neither the agent's code nor its model.
- Real conversations. The simulated user asks vague questions, changes its mind and gives details late. The judge checks plain-language claims about the dialogue.
- Numbers you can act on. Pass rate over repeated attempts, the agent's tokens and its answer time. And a page that shows what changed between two builds.
- Small. Four dependencies. No platform, no account, no containers.
uvx convy init my-bench              # a project with examples
cd my-bench
uv run convy run echo --smoke        # check convy itself: free, no models called
cp .env.example .env                 # add the address and key of your model gateway
uv run convy run echo                # a real run with the simulated user and the judge
convy prints where the report is: results/<agent>/<run>/report.html. Open it in a browser.
A new project looks like this:
my-bench/
├── gateway.py        # the model gateway, shared by models.py and the agents
├── models.py         # the models that play the user and the judge
├── agents/           # one file per agent
├── scenarios/        # one YAML file per scenario, in folders if you like
└── results/          # a folder per run with its report, and the index
A scenario says who the user is, what they want, and what must be true of the dialogue:
id: clarify-backup
max_turns: 6
user: |
  You need a backup script. Start short: "Make me a backup script".
  Give details only when the assistant asks for them:
  back up ~/photos to /mnt/backup, once a day.
judge:
  - Before giving a finished script, the agent asked what to back up and where to
  - The final script copies ~/photos to /mnt/backup and runs once a day
The judge decides each claim on its own and says why. The report shows which claim failed, in which attempt, next to the dialogue. More in Scenarios.
An agent with a JSON API needs only settings. Put this in agents/support_bot.py:
from convy import JsonAgent, JsonEndpoint, TokenPaths

agent = JsonAgent(
    JsonEndpoint("https://bot.example.com/api/chat"),
    body={"session_id": "{session}", "message": "{text}"},
    reply="data.answer",
    tokens=TokenPaths(input="data.usage.input_tokens", output="data.usage.output_tokens"),
)
Then check the connection and run it:
uv run convy run support_bot --smoke   # the agent answers for real, nothing else is called
uv run convy run support_bot -k 3      # every scenario, three attempts each
Keys, streaming, logins, blocking clients and certificates are in Connect an agent.
Run the old build and the new one, then name the two runs:
uv run convy compare 7ad8 5e85 # before, then afterThe page shows each number before and after. Green is better, red is worse, and grey with ~ means
the change is within noise. Scenarios are grouped as Worse, Better and Same, and you can read both
dialogues side by side. More in
The report.
Checked against their docs on 8 October 2026.
- Scenario by LangWatch also has a simulated user and a judge. You write scenarios as code in Python, TypeScript or Go and run them with pytest or vitest. Pick it if you want scenarios next to your tests, or to script a dialogue step by step.
- promptfoo tests prompts, models and agents, and does red teaming. Its simulated user is one provider among many. Pick it if you need a wide toolkit.
- deepeval has a conversation simulator you call from Python, and many ready metrics. Pick it if you want those metrics.
convy does one job. It checks a running agent through its API, with scenarios in YAML, repeated attempts and a verdict per claim. Then it shows what changed between two builds, and whether the change is real or noise. The report is a file: no account, no server.
convy is in alpha. The Python API and the format of runs may change before 1.0. Every change is in the changelog.
convy run runs models.py and agents/*.py. Treat a project like its tests: run only what you
trust. See the security policy.
| page | what is in it |
|---|---|
| Connect an agent | JSON agents, your own classes, tokens, certificates |
| Scenarios | how to write them, verdicts, convy run options |
| The judge | how sure it is, --trust, your own judge |
| Runs | the run folder, stop and resume, exit codes |
| The report | tiles, statuses, the scenario window, comparing runs |
| Results as data | a run as tables, convy export, pandas |
| Run from Python | the library behind the command |
| The shop demo | the bot behind the live report |
| Architecture | for people who change convy's code |
Issues and pull requests are welcome. Read CONTRIBUTING.md first, and follow the Code of Conduct. Report vulnerabilities privately, as the security policy says.