diff --git a/.dockerignore b/.dockerignore index 22ec965249..b9f228c009 100644 --- a/.dockerignore +++ b/.dockerignore @@ -11,3 +11,11 @@ python/flexflow/core/legion_cffi_header.py *.pb.h *.o *.a + +# Ignore inference assets +/inference/weights/* +/inference/tokenizer/* +/inference/prompt/* +/inference/output/* + +/tests/inference/python_test_configs/*.json diff --git a/.github/PULL_REQUEST_TEMPLATE.md b/.github/PULL_REQUEST_TEMPLATE.md index 183028b022..e8177cd9b7 100644 --- a/.github/PULL_REQUEST_TEMPLATE.md +++ b/.github/PULL_REQUEST_TEMPLATE.md @@ -10,6 +10,3 @@ Linked Issues: Issues closed by this PR: - Closes # -**Before merging:** - -- [ ] Did you update the [flexflow-third-party](https://github.com/flexflow/flexflow-third-party) repo, if modifying any of the Cmake files, the build configs, or the submodules? diff --git a/.github/README.md b/.github/README.md new file mode 100644 index 0000000000..c4f6baada6 --- /dev/null +++ b/.github/README.md @@ -0,0 +1,261 @@ +# FlexFlow Serve: Low-Latency, High-Performance LLM Serving +![build](https://github.com/flexflow/flexflow/workflows/build/badge.svg?branch=inference) ![gpu tests](https://github.com/flexflow/flexflow/workflows/gpu-ci/badge.svg?branch=inference) ![multinode gpu tests](https://github.com/flexflow/flexflow/workflows/multinode-test/badge.svg?branch=master) ![docker](https://github.com/flexflow/flexflow/workflows/docker-build/badge.svg?branch=inference) ![pip](https://github.com/flexflow/flexflow/workflows/pip-install/badge.svg?branch=inference) ![shell-check](https://github.com/flexflow/flexflow/workflows/Shell%20Check/badge.svg?branch=inference) ![clang-format](https://github.com/flexflow/flexflow/workflows/clang-format%20Check/badge.svg?branch=inference) [![Documentation Status](https://readthedocs.org/projects/flexflow/badge/?version=latest)](https://flexflow.readthedocs.io/en/latest/?badge=latest) + + +--- + +## News🔥: + +* [09/02/2023] Adding AMD GPU support, released Docker images for ROCM 5.3->5.6 +* [08/16/2023] Adding Starcoder model support +* [08/14/2023] Released Docker images for different CUDA versions + +## What is FlexFlow Serve + +The high computational and memory requirements of generative large language +models (LLMs) make it challenging to serve them quickly and cheaply. +FlexFlow Serve is an open-source compiler and distributed system for +__low latency__, __high performance__ LLM serving. FlexFlow Serve outperforms +existing systems by 1.3-2.0x for single-node, multi-GPU inference and by +1.4-2.4x for multi-node, multi-GPU inference. + +

+Performance comparison +

+ + +## Install FlexFlow Serve + + +### Requirements +* OS: Linux +* GPU backend: Hip-ROCm or CUDA + * CUDA version: 10.2 – 12.0 + * NVIDIA compute capability: 6.0 or higher +* Python: 3.6 or higher +* Package dependencies: [see here](https://github.com/flexflow/FlexFlow/blob/inference/requirements.txt) + +### Install with pip +You can install FlexFlow Serve using pip: + +```bash +pip install flexflow +``` + +### Try it in Docker +If you run into any issue during the install, or if you would like to use the C++ API without needing to install from source, you can also use our pre-built Docker package for different CUDA versions (NVIDIA backend) and multiple ROCM versions (AMD backend). To download and run our pre-built Docker container: + +```bash +docker run --gpus all -it --rm --shm-size=8g ghcr.io/flexflow/flexflow-cuda-12.0:latest +``` + +To download a Docker container for a backend other than CUDA v12.0, you can replace the `cuda-12.0` suffix with any of the following backends: `cuda-11.1`, `cuda-11.2`, `cuda-11.3`, `cuda-11.4`, `cuda-11.5`, `cuda-11.6`, `cuda-11.7`, `cuda-11.8`, and `hip_rocm-5.3`, `hip_rocm-5.4`, `hip_rocm-5.5`, `hip_rocm-5.6`). More info on the Docker images, with instructions to build a new image from source, or run with additional configurations, can be found [here](../docker/README.md). + +### Build from source + +You can install FlexFlow Serve from source code by building the inference branch of FlexFlow. Please follow these [instructions](https://flexflow.readthedocs.io/en/latest/installation.html). + +## Quickstart +The following example shows how to deploy an LLM using FlexFlow Serve and accelerate its serving using [speculative inference](#speculative-inference). First, we import `flexflow.serve` and initialize the FlexFlow Serve runtime. Note that `memory_per_gpu` and `zero_copy_memory_per_node` specify the size of device memory on each GPU (in MB) and zero-copy memory on each node (in MB), respectively. +We need to make sure the aggregated GPU memory and zero-copy memory are **both** sufficient to store LLM parameters in non-offloading serving. FlexFlow Serve combines tensor and pipeline model parallelism for LLM serving. +```python +import flexflow.serve as ff + +ff.init( + num_gpus=4, + memory_per_gpu=14000, + zero_copy_memory_per_node=30000, + tensor_parallelism_degree=4, + pipeline_parallelism_degree=1 + ) +``` +Second, we specify the LLM to serve and the SSM(s) used to accelerate LLM serving. The list of supported LLMs and SSMs is available at [supported models](#supported-llms-and-ssms). +```python +# Specify the LLM +llm = ff.LLM("meta-llama/Llama-2-7b-hf") + +# Specify a list of SSMs (just one in this case) +ssms=[] +ssm = ff.SSM("JackFram/llama-68m") +ssms.append(ssm) +``` +Next, we declare the generation configuration and compile both the LLM and SSMs. Note that all SSMs should run in the **beam search** mode, and the LLM should run in the **tree verification** mode to verify the speculated tokens from SSMs. You can also use the following arguments to specify serving configuration when compiling LLMs and SSMs: + +* max\_requests\_per\_batch: the maximum number of requests to serve in a batch (default: 16) +* max\_seq\_length: the maximum number of tokens in a request (default: 256) +* max\_tokens\_per\_batch: the maximum number of tokens to process in a batch (default: 128) + +```python +# Create the sampling configs +generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 +) + +# Compile the SSMs for inference and load the weights into memory +for ssm in ssms: + ssm.compile(generation_config) + +# Compile the LLM for inference and load the weights into memory +llm.compile(generation_config, + max_requests_per_batch = 16, + max_seq_length = 256, + max_tokens_per_batch = 128, + ssms=ssms) +``` +Next, we call `llm.start_server()` to start an LLM server running on a seperate background thread, which allows users to perform computations in parallel with LLM serving. Finally, we call `llm.generate` to generate the output, which is organized as a list of `GenerationResult`, which include the output tokens and text. After all serving requests are processed, you can either call `llm.stop_server()` to terminate the background thread or directly exit the python program, which will automatically terminate the background server thread. +```python +llm.start_server() +result = llm.generate("Here are some travel tips for Tokyo:\n") +llm.stop_server() # This invocation is optional +``` + +### Incremental decoding +
+Expand here +
+ +```python +import flexflow.serve as ff + +# Initialize the FlexFlow runtime. ff.init() takes a dictionary or the path to a JSON file with the configs +ff.init( + num_gpus=4, + memory_per_gpu=14000, + zero_copy_memory_per_node=30000, + tensor_parallelism_degree=4, + pipeline_parallelism_degree=1 + ) + +# Create the FlexFlow LLM +llm = ff.LLM("meta-llama/Llama-2-7b-hf") + +# Create the sampling configs +generation_config = ff.GenerationConfig( + do_sample=True, temperature=0.9, topp=0.8, topk=1 +) + +# Compile the LLM for inference and load the weights into memory +llm.compile(generation_config, + max_requests_per_batch = 16, + max_seq_length = 256, + max_tokens_per_batch = 128) + +# Generation begins! +llm.start_server() +result = llm.generate("Here are some travel tips for Tokyo:\n") +llm.stop_server() # This invocation is optional +``` + +
+ +### C++ interface +If you'd like to use the C++ interface (mostly used for development and benchmarking purposes), you should install from source, and follow the instructions below. + +
+Expand here +
+ +#### Downloading models +Before running FlexFlow Serve, you should manually download the LLM and SSM(s) model of interest using the [inference/utils/download_hf_model.py](https://github.com/flexflow/FlexFlow/blob/inference/inference/utils/download_hf_model.py) script (see example below). By default, the script will download all of a model's assets (weights, configs, tokenizer files, etc...) into the cache folder `~/.cache/flexflow`. If you would like to use a different folder, you can request that via the parameter `--cache-folder`. + +```bash +python3 ./inference/utils/download_hf_model.py ... +``` + +#### Running the C++ examples +A C++ example is available at [this folder](../inference/spec_infer/). After building FlexFlow Serve, the executable will be available at `/build_dir/inference/spec_infer/spec_infer`. You can use the following command-line arguments to run FlexFlow Serve: + +* `-ll:gpu`: number of GPU processors to use on each node for serving an LLM (default: 0) +* `-ll:fsize`: size of device memory on each GPU in MB +* `-ll:zsize`: size of zero-copy memory (pinned DRAM with direct GPU access) in MB. FlexFlow Serve keeps a replica of the LLM parameters on zero-copy memory, and therefore requires that the zero-copy memory is sufficient for storing the LLM parameters. +* `-llm-model`: the LLM model ID from HuggingFace (e.g. "meta-llama/Llama-2-7b-hf") +* `-ssm-model`: the SSM model ID from HuggingFace (e.g. "JackFram/llama-160m"). You can use multiple `-ssm-model`s in the command line to launch multiple SSMs. +* `-cache-folder`: the folder +* `-data-parallelism-degree`, `-tensor-parallelism-degree` and `-pipeline-parallelism-degree`: parallelization degrees in the data, tensor, and pipeline dimensions. Their product must equal the number of GPUs available on the machine. When any of the three parallelism degree arguments is omitted, a default value of 1 will be used. +* `-prompt`: (optional) path to the prompt file. FlexFlow Serve expects a json format file for prompts. In addition, users can also use the following API for registering requests: +* `-output-file`: (optional) filepath to use to save the output of the model, together with the generation latency + +For example, you can use the following command line to serve a LLaMA-7B or LLaMA-13B model on 4 GPUs and use two collectively boost-tuned LLaMA-68M models for speculative inference. + +```bash +./inference/spec_infer/spec_infer -ll:gpu 4 -ll:cpu 4 -ll:fsize 14000 -ll:zsize 30000 -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-68m -prompt /path/to/prompt.json -tensor-parallelism-degree 4 --fusion +``` +
+ +## Speculative Inference +A key technique that enables FlexFlow Serve to accelerate LLM serving is speculative +inference, which combines various collectively boost-tuned small speculative +models (SSMs) to jointly predict the LLM’s outputs; the predictions are organized as a +token tree, whose nodes each represent a candidate token sequence. The correctness +of all candidate token sequences represented by a token tree is verified against the +LLM’s output in parallel using a novel tree-based parallel decoding mechanism. +FlexFlow Serve uses an LLM as a token tree verifier instead of an incremental decoder, +which largely reduces the end-to-end inference latency and computational requirement +for serving generative LLMs while provably preserving model quality. + +

+A Speculative Inference Demo +

+ +### Supported LLMs and SSMs + +FlexFlow Serve currently supports all HuggingFace models with the following architectures: +* `LlamaForCausalLM` / `LLaMAForCausalLM` (e.g. LLaMA/LLaMA-2, Guanaco, Vicuna, Alpaca, ...) +* `OPTForCausalLM` (models from the OPT family) +* `RWForCausalLM` (models from the Falcon family) +* `GPTBigCodeForCausalLM` (models from the Starcoder family) + +Below is a list of models that we have explicitly tested and for which a SSM may be available: + +| Model | Model id on HuggingFace | Boost-tuned SSMs | +| :---- | :---- | :---- | +| LLaMA-7B | meta-llama/Llama-2-7b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-13B | decapoda-research/llama-13b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-30B | decapoda-research/llama-30b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-65B | decapoda-research/llama-65b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-7B | meta-llama/Llama-2-7b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-13B | meta-llama/Llama-2-13b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-70B | meta-llama/Llama-2-70b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| OPT-6.7B | facebook/opt-6.7b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-13B | facebook/opt-13b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-30B | facebook/opt-30b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-66B | facebook/opt-66b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| Falcon-7B | tiiuae/falcon-7b | | +| Falcon-40B | tiiuae/falcon-40b | | +| StarCoder-7B | bigcode/starcoderbase-7b | | +| StarCoder-15.5B | bigcode/starcoder | | + +### CPU Offloading +FlexFlow Serve also offers offloading-based inference for running large models (e.g., llama-7B) on a single GPU. CPU offloading is a choice to save tensors in CPU memory, and only copy the tensor to GPU when doing calculation. Notice that now we selectively offload the largest weight tensors (weights tensor in Linear, Attention). Besides, since the small model occupies considerably less space, it it does not pose a bottleneck for GPU memory, the offloading will bring more runtime space and computational cost, so we only do the offloading for the large model. [TODO: update instructions] You can run the offloading example by enabling the `-offload` and `-offload-reserve-space-size` flags. + +### Quantization +FlexFlow Serve supports int4 and int8 quantization. The compressed tensors are stored on the CPU side. Once copied to the GPU, these tensors undergo decompression and conversion back to their original precision. Please find the compressed weight files in our s3 bucket, or use [this script](../inference/utils/compress_llama_weights.py) from [FlexGen](https://github.com/FMInference/FlexGen) project to do the compression manually. + +### Prompt Datasets +We provide five prompt datasets for evaluating FlexFlow Serve: [Chatbot instruction prompts](https://specinfer.s3.us-east-2.amazonaws.com/prompts/chatbot.json), [ChatGPT Prompts](https://specinfer.s3.us-east-2.amazonaws.com/prompts/chatgpt.json), [WebQA](https://specinfer.s3.us-east-2.amazonaws.com/prompts/webqa.json), [Alpaca](https://specinfer.s3.us-east-2.amazonaws.com/prompts/alpaca.json), and [PIQA](https://specinfer.s3.us-east-2.amazonaws.com/prompts/piqa.json). + +## TODOs + +FlexFlow Serve is under active development. We currently focus on the following tasks and strongly welcome all contributions from bug fixes to new features and extensions. + +* AMD benchmarking. We are actively working on benchmarking FlexFlow Serve on AMD GPUs and comparing it with the performance on NVIDIA GPUs. +* Chatbot prompt templates and Multi-round conversations +* Support for FastAPI server +* Integration with LangChain for document question answering + +## Acknowledgements +This project is initiated by members from CMU, Stanford, and UCSD. We will be continuing developing and supporting FlexFlow Serve. Please cite FlexFlow Serve as: + +``` bibtex +@misc{miao2023specinfer, + title={SpecInfer: Accelerating Generative Large Language Model Serving with Speculative Inference and Token Tree Verification}, + author={Xupeng Miao and Gabriele Oliaro and Zhihao Zhang and Xinhao Cheng and Zeyu Wang and Rae Ying Yee Wong and Alan Zhu and Lijie Yang and Xiaoxiang Shi and Chunan Shi and Zhuoming Chen and Daiyaan Arfeen and Reyna Abhyankar and Zhihao Jia}, + year={2023}, + eprint={2305.09781}, + archivePrefix={arXiv}, + primaryClass={cs.CL} +} +``` + +## License +FlexFlow uses Apache License 2.0. diff --git a/.github/workflows/build-skip.yml b/.github/workflows/build-skip.yml index b3ab69e9c1..8635c0d137 100644 --- a/.github/workflows/build-skip.yml +++ b/.github/workflows/build-skip.yml @@ -3,6 +3,7 @@ on: pull_request: paths-ignore: - "include/**" + - "inference/**" - "cmake/**" - "config/**" - "deps/**" diff --git a/.github/workflows/build.yml b/.github/workflows/build.yml index ada29c5798..d05856f1a9 100644 --- a/.github/workflows/build.yml +++ b/.github/workflows/build.yml @@ -3,6 +3,7 @@ on: pull_request: paths: - "include/**" + - "inference/**" - "cmake/**" - "config/**" - "deps/**" @@ -15,6 +16,7 @@ on: - "master" paths: - "include/**" + - "inference/**" - "cmake/**" - "config/**" - "deps/**" @@ -38,6 +40,8 @@ jobs: matrix: gpu_backend: ["cuda", "hip_rocm"] fail-fast: false + env: + FF_GPU_BACKEND: ${{ matrix.gpu_backend }} steps: - name: Checkout Git Repository uses: actions/checkout@v3 @@ -49,6 +53,7 @@ jobs: - name: Install CUDA uses: Jimver/cuda-toolkit@v0.2.11 + if: ${{ matrix.gpu_backend == 'cuda' }} id: cuda-toolkit with: cuda: "11.8.0" @@ -56,13 +61,13 @@ jobs: use-github-cache: "false" - name: Install system dependencies - run: FF_GPU_BACKEND=${{ matrix.gpu_backend }} .github/workflows/helpers/install_dependencies.sh + run: .github/workflows/helpers/install_dependencies.sh - name: Install conda and FlexFlow dependencies uses: conda-incubator/setup-miniconda@v2 with: activate-environment: flexflow - environment-file: conda/environment.yml + environment-file: conda/flexflow.yml auto-activate-base: false - name: Build FlexFlow @@ -70,17 +75,25 @@ jobs: export CUDNN_DIR="$CUDA_PATH" export CUDA_DIR="$CUDA_PATH" export FF_HOME=$(pwd) - export FF_GPU_BACKEND=${{ matrix.gpu_backend }} export FF_CUDA_ARCH=70 + export FF_HIP_ARCH=gfx1100,gfx1036 + export hip_version=5.6 + export FF_BUILD_ALL_INFERENCE_EXAMPLES=ON + + if [[ "${FF_GPU_BACKEND}" == "cuda" ]]; then + export FF_BUILD_ALL_EXAMPLES=ON + export FF_BUILD_UNIT_TESTS=ON + else + export FF_BUILD_ALL_EXAMPLES=OFF + export FF_BUILD_UNIT_TESTS=OFF + fi + cores_available=$(nproc --all) n_build_cores=$(( cores_available -1 )) if (( $n_build_cores < 1 )) ; then n_build_cores=1 ; fi mkdir build cd build - if [[ "${FF_GPU_BACKEND}" == "cuda" ]]; then - export FF_BUILD_ALL_EXAMPLES=ON - export FF_BUILD_UNIT_TESTS=ON - fi + ../config/config.linux make -j $n_build_cores @@ -89,25 +102,24 @@ jobs: export CUDNN_DIR="$CUDA_PATH" export CUDA_DIR="$CUDA_PATH" export FF_HOME=$(pwd) - export FF_GPU_BACKEND=${{ matrix.gpu_backend }} export FF_CUDA_ARCH=70 - cd build + export FF_HIP_ARCH=gfx1100,gfx1036 + export hip_version=5.6 + export FF_BUILD_ALL_INFERENCE_EXAMPLES=ON + if [[ "${FF_GPU_BACKEND}" == "cuda" ]]; then - export FF_BUILD_ALL_EXAMPLES=ON + export FF_BUILD_ALL_EXAMPLES=ON export FF_BUILD_UNIT_TESTS=ON + else + export FF_BUILD_ALL_EXAMPLES=OFF + export FF_BUILD_UNIT_TESTS=OFF fi + + cd build ../config/config.linux sudo make install sudo ldconfig - - name: Check availability of Python flexflow.core module - if: ${{ matrix.gpu_backend == 'cuda' }} - run: | - export LD_LIBRARY_PATH="$CUDA_PATH/lib64/stubs:$LD_LIBRARY_PATH" - sudo ln -s "$CUDA_PATH/lib64/stubs/libcuda.so" "$CUDA_PATH/lib64/stubs/libcuda.so.1" - export CPU_ONLY_TEST=1 - python -c "import flexflow.core; exit()" - - name: Run C++ unit tests if: ${{ matrix.gpu_backend == 'cuda' }} run: | @@ -115,9 +127,19 @@ jobs: export CUDA_DIR="$CUDA_PATH" export LD_LIBRARY_PATH="$CUDA_PATH/lib64/stubs:$LD_LIBRARY_PATH" export FF_HOME=$(pwd) + sudo ln -s "$CUDA_PATH/lib64/stubs/libcuda.so" "$CUDA_PATH/lib64/stubs/libcuda.so.1" cd build ./tests/unit/unit-test + - name: Check availability of flexflow modules in Python + run: | + if [[ "${FF_GPU_BACKEND}" == "cuda" ]]; then + export LD_LIBRARY_PATH="$CUDA_PATH/lib64/stubs:$LD_LIBRARY_PATH" + fi + # Remove build folder to check that the installed version can run independently of the build files + rm -rf build + python -c "import flexflow.core; import flexflow.serve as ff; exit()" + makefile-build: name: Build FlexFlow with the Makefile runs-on: ubuntu-20.04 @@ -163,5 +185,4 @@ jobs: cd python make -j $n_build_cores - export CPU_ONLY_TEST=1 python -c 'import flexflow.core' diff --git a/.github/workflows/clang-format-check.yml b/.github/workflows/clang-format-check.yml index 46c9bf3be2..fdf53e8254 100644 --- a/.github/workflows/clang-format-check.yml +++ b/.github/workflows/clang-format-check.yml @@ -10,7 +10,7 @@ jobs: - check: "src" exclude: '\.proto$' - check: "include" - - check: "nmt" + - check: "inference" - check: "python" - check: "scripts" - check: "tests" diff --git a/.github/workflows/docker-build-skip.yml b/.github/workflows/docker-build-skip.yml index 59b584c6c4..e5d7de858f 100644 --- a/.github/workflows/docker-build-skip.yml +++ b/.github/workflows/docker-build-skip.yml @@ -13,27 +13,22 @@ concurrency: cancel-in-progress: true jobs: - docker-build: - name: Build and Install FlexFlow in a Docker Container - runs-on: ubuntu-20.04 + docker-build-rocm: + name: Build and Install FlexFlow in a Docker Container (ROCm backend) + runs-on: ubuntu-latest strategy: matrix: - gpu_backend: ["cuda", "hip_rocm"] - cuda_version: ["11.1", "11.2", "11.3", "11.5", "11.6", "11.7", "11.8"] - # The CUDA version doesn't matter when building for hip_rocm, so we just pick one arbitrarily (11.8) to avoid building for hip_rocm once per number of CUDA version supported - exclude: - - gpu_backend: "hip_rocm" - cuda_version: "11.1" - - gpu_backend: "hip_rocm" - cuda_version: "11.2" - - gpu_backend: "hip_rocm" - cuda_version: "11.3" - - gpu_backend: "hip_rocm" - cuda_version: "11.5" - - gpu_backend: "hip_rocm" - cuda_version: "11.6" - - gpu_backend: "hip_rocm" - cuda_version: "11.7" + hip_version: ["5.3", "5.4", "5.5", "5.6"] + fail-fast: false + steps: + - run: 'echo "No docker-build required"' + + docker-build-cuda: + name: Build and Install FlexFlow in a Docker Container (CUDA backend) + runs-on: ubuntu-latest + strategy: + matrix: + cuda_version: ["11.1", "11.6", "11.7", "11.8", "12.0", "12.1", "12.2"] fail-fast: false steps: - run: 'echo "No docker-build required"' diff --git a/.github/workflows/docker-build.yml b/.github/workflows/docker-build.yml index d059a0605f..d16179434b 100644 --- a/.github/workflows/docker-build.yml +++ b/.github/workflows/docker-build.yml @@ -7,10 +7,11 @@ on: - ".github/workflows/docker-build.yml" push: branches: + - "inference" - "master" - schedule: - # Run every week on Sunday at midnight PT (3am ET / 8am UTC) to keep the docker images updated - - cron: "0 8 * * 0" + # schedule: + # # Run every week on Sunday at midnight PT (3am ET / 8am UTC) to keep the docker images updated + # - cron: "0 8 * * 0" workflow_dispatch: # Cancel outdated workflows if they are still running @@ -19,53 +20,106 @@ concurrency: cancel-in-progress: true jobs: - docker-build: - name: Build and Install FlexFlow in a Docker Container + rocm-builder-start: + name: Start an AWS instance to build the ROCM Docker images + runs-on: ubuntu-latest + if: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' }} + env: + ROCM_BUILDER_INSTANCE_ID: ${{ secrets.ROCM_BUILDER_INSTANCE_ID }} + steps: + - name: Configure AWS credentials + uses: aws-actions/configure-aws-credentials@v1 + with: + aws-access-key-id: ${{ secrets.AWS_ACCESS_KEY_ID }} + aws-secret-access-key: ${{ secrets.AWS_SECRET_ACCESS_KEY }} + aws-region: us-east-2 + + - name: Start EC2 instance + run: aws ec2 start-instances --instance-ids $ROCM_BUILDER_INSTANCE_ID + + docker-build-rocm: + name: Build and Install FlexFlow in a Docker Container (ROCm backend) runs-on: ubuntu-20.04 + if: ${{ ( github.event_name != 'push' && github.event_name != 'schedule' && github.event_name != 'workflow_dispatch' ) || github.ref_name != 'inference' }} + env: + FF_GPU_BACKEND: "hip_rocm" + hip_version: 5.6 + steps: + - name: Checkout Git Repository + uses: actions/checkout@v3 + with: + submodules: recursive + + - name: Free additional space on runner + run: .github/workflows/helpers/free_space_on_runner.sh + + - name: Build Docker container + run: FF_HIP_ARCH="gfx1100,gfx1036" ./docker/build.sh flexflow + + - name: Check availability of flexflow modules in Python + run: docker run --entrypoint /bin/bash flexflow-${FF_GPU_BACKEND}-${hip_version}:latest -c "python -c 'import flexflow.core; import flexflow.serve as ff; exit()'" + + + docker-build-and-publish-rocm: + name: Build and Deploy FlexFlow Docker Containers (ROCm backend) + needs: rocm-builder-start + runs-on: [self-hosted, rocm_builder] + if: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' }} strategy: matrix: - gpu_backend: ["cuda", "hip_rocm"] - cuda_version: ["11.1", "11.2", "11.3", "11.5", "11.6", "11.7", "11.8"] - # The CUDA version doesn't matter when building for hip_rocm, so we just pick one arbitrarily (11.8) to avoid building for hip_rocm once per number of CUDA version supported - exclude: - - gpu_backend: "hip_rocm" - cuda_version: "11.1" - - gpu_backend: "hip_rocm" - cuda_version: "11.2" - - gpu_backend: "hip_rocm" - cuda_version: "11.3" - - gpu_backend: "hip_rocm" - cuda_version: "11.5" - - gpu_backend: "hip_rocm" - cuda_version: "11.6" - - gpu_backend: "hip_rocm" - cuda_version: "11.7" + hip_version: ["5.3", "5.4", "5.5", "5.6"] fail-fast: false env: - FF_GPU_BACKEND: ${{ matrix.gpu_backend }} - cuda_version: ${{ matrix.cuda_version }} - branch_name: ${{ github.head_ref || github.ref_name }} + FF_GPU_BACKEND: "hip_rocm" + hip_version: ${{ matrix.hip_version }} steps: - name: Checkout Git Repository uses: actions/checkout@v3 with: submodules: recursive - - name: Free additional space on runner + - name: Build Docker container + # On push to inference, build for all compatible architectures, so that we can publish + # a pre-built general-purpose image. On all other cases, only build for one architecture + # to save time. + run: FF_HIP_ARCH=all ./docker/build.sh flexflow + + - name: Check availability of flexflow modules in Python + run: docker run --entrypoint /bin/bash flexflow-${FF_GPU_BACKEND}-${hip_version}:latest -c "python -c 'import flexflow.core; import flexflow.serve as ff; exit()'" + + - name: Publish Docker environment image (on push to inference) env: - deploy_needed: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' ) && env.branch_name == 'inference' }} - build_needed: ${{ matrix.gpu_backend == 'hip_rocm' || ( matrix.gpu_backend == 'cuda' && matrix.cuda_version == '11.8' ) }} + FLEXFLOW_CONTAINER_TOKEN: ${{ secrets.FLEXFLOW_CONTAINER_TOKEN }} run: | - if [[ $deploy_needed == "true" || $build_needed == "true" ]]; then - .github/workflows/helpers/free_space_on_runner.sh - else - echo "Skipping this step to save time" - fi + ./docker/publish.sh flexflow-environment + ./docker/publish.sh flexflow + + docker-build-cuda: + name: Build and Install FlexFlow in a Docker Container (CUDA backend) + runs-on: ubuntu-20.04 + strategy: + matrix: + cuda_version: ["11.1", "11.6", "11.7", "11.8", "12.0", "12.1", "12.2"] + fail-fast: false + env: + FF_GPU_BACKEND: "cuda" + cuda_version: ${{ matrix.cuda_version }} + steps: + - name: Checkout Git Repository + if: ${{ ( ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' ) || matrix.cuda_version == '12.0' }} + uses: actions/checkout@v3 + with: + submodules: recursive + + - name: Free additional space on runner + if: ${{ ( ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' ) || matrix.cuda_version == '12.0' }} + run: .github/workflows/helpers/free_space_on_runner.sh - name: Build Docker container + if: ${{ ( ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' ) || matrix.cuda_version == '12.0' }} env: - deploy_needed: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' ) && env.branch_name == 'inference' }} - build_needed: ${{ matrix.gpu_backend == 'hip_rocm' || ( matrix.gpu_backend == 'cuda' && matrix.cuda_version == '11.8' ) }} + deploy_needed: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' }} + build_needed: ${{ matrix.cuda_version == '12.0' }} run: | # On push to inference, build for all compatible architectures, so that we can publish # a pre-built general-purpose image. On all other cases, only build for one architecture @@ -74,41 +128,44 @@ jobs: export FF_CUDA_ARCH=all ./docker/build.sh flexflow elif [[ $build_needed == "true" ]]; then - export FF_CUDA_ARCH=70 + export FF_CUDA_ARCH=86 ./docker/build.sh flexflow - else - echo "Skipping build to save time" fi - - name: Check availability of Python flexflow.core module - if: ${{ matrix.gpu_backend == 'cuda' }} - env: - deploy_needed: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' ) && env.branch_name == 'inference' }} - build_needed: ${{ matrix.gpu_backend == 'hip_rocm' || ( matrix.gpu_backend == 'cuda' && matrix.cuda_version == '11.8' ) }} - run: | - if [[ $deploy_needed == "true" || $build_needed == "true" ]]; then - docker run --env CPU_ONLY_TEST=1 --entrypoint /bin/bash flexflow-cuda-${cuda_version}:latest -c "export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH; sudo ln -s /usr/local/cuda/lib64/stubs/libcuda.so /usr/local/cuda/lib64/stubs/libcuda.so.1; python -c 'import flexflow.core; exit()'" - else - echo "Skipping test to save time" - fi + - name: Check availability of flexflow modules in Python + if: ${{ ( ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' ) || matrix.cuda_version == '12.0' }} + run: docker run --entrypoint /bin/bash flexflow-${FF_GPU_BACKEND}-${cuda_version}:latest -c "export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH; sudo ln -s /usr/local/cuda/lib64/stubs/libcuda.so /usr/local/cuda/lib64/stubs/libcuda.so.1; python -c 'import flexflow.core; import flexflow.serve as ff; exit()'" - name: Publish Docker environment image (on push to inference) - if: github.repository_owner == 'flexflow' + if: ${{ github.repository_owner == 'flexflow' && ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' }} env: FLEXFLOW_CONTAINER_TOKEN: ${{ secrets.FLEXFLOW_CONTAINER_TOKEN }} - deploy_needed: ${{ ( github.event_name == 'push' || github.event_name == 'schedule' ) && env.branch_name == 'inference' }} run: | - if [[ $deploy_needed == "true" ]]; then - ./docker/publish.sh flexflow-environment - ./docker/publish.sh flexflow - else - echo "No need to update Docker containers in ghrc.io registry at this time." - fi + ./docker/publish.sh flexflow-environment + ./docker/publish.sh flexflow + + rocm-builder-stop: + needs: docker-build-and-publish-rocm + if: ${{ always() && ( github.event_name == 'push' || github.event_name == 'schedule' || github.event_name == 'workflow_dispatch' ) && github.ref_name == 'inference' }} + runs-on: ubuntu-latest + name: Stop the AWS instance we used to build the ROCM Docker images + env: + ROCM_BUILDER_INSTANCE_ID: ${{ secrets.ROCM_BUILDER_INSTANCE_ID }} + steps: + - name: Configure AWS credentials + uses: aws-actions/configure-aws-credentials@v1 + with: + aws-access-key-id: ${{ secrets.AWS_ACCESS_KEY_ID }} + aws-secret-access-key: ${{ secrets.AWS_SECRET_ACCESS_KEY }} + aws-region: us-east-2 + + - name: Start EC2 instance + run: aws ec2 stop-instances --instance-ids $ROCM_BUILDER_INSTANCE_ID notify-slack: name: Notify Slack in case of failure runs-on: ubuntu-20.04 - needs: docker-build + needs: [docker-build-cuda, docker-build-and-publish-rocm] if: ${{ failure() && github.event_name == 'schedule' && github.repository_owner == 'flexflow' }} steps: - name: Send Slack message diff --git a/.github/workflows/gpu-ci-daemon.yml b/.github/workflows/gpu-ci-daemon.yml index 603b44c34e..b36e7b49e1 100644 --- a/.github/workflows/gpu-ci-daemon.yml +++ b/.github/workflows/gpu-ci-daemon.yml @@ -34,5 +34,6 @@ jobs: run: | pip3 install pip --upgrade pip3 install pyopenssl --upgrade + pip3 install urllib3 --upgrade pip3 install pygithub python3 .github/workflows/helpers/gpu_ci_helper.py --daemon diff --git a/.github/workflows/gpu-ci-skip.yml b/.github/workflows/gpu-ci-skip.yml index 157f3c271a..f4cb950931 100644 --- a/.github/workflows/gpu-ci-skip.yml +++ b/.github/workflows/gpu-ci-skip.yml @@ -8,9 +8,15 @@ on: - "python/**" - "setup.py" - "include/**" + - "inference/**" - "src/**" + - "tests/inference/**" + - "conda/flexflow.yml" - ".github/workflows/gpu-ci.yml" - - "tests/multi_gpu_tests.sh" + - "tests/cpp_gpu_tests.sh" + - "tests/inference_tests.sh" + - "tests/training_tests.sh" + - "tests/python_interface_test.sh" workflow_dispatch: concurrency: @@ -30,10 +36,18 @@ jobs: needs: gpu-ci-concierge steps: - run: 'echo "No gpu-ci required"' - - gpu-ci-flexflow: - name: Single Machine, Multiple GPUs Tests + + inference-tests: + name: Inference Tests runs-on: ubuntu-20.04 needs: gpu-ci-concierge steps: - run: 'echo "No gpu-ci required"' + + training-tests: + name: Training Tests + runs-on: ubuntu-20.04 + # if: ${{ github.event_name != 'pull_request' || github.base_ref != 'inference' }} + needs: inference-tests + steps: + - run: 'echo "No gpu-ci required"' diff --git a/.github/workflows/gpu-ci.yml b/.github/workflows/gpu-ci.yml index 3b679e9f20..7bdb6805a8 100644 --- a/.github/workflows/gpu-ci.yml +++ b/.github/workflows/gpu-ci.yml @@ -1,21 +1,8 @@ name: "gpu-ci" on: - pull_request: - paths: - - "cmake/**" - - "config/**" - - "deps/**" - - "python/**" - - "setup.py" - - "include/**" - - "src/**" - - ".github/workflows/gpu-ci.yml" - - "tests/cpp_gpu_tests.sh" - - "tests/multi_gpu_tests.sh" - - "tests/python_interface_test.sh" push: branches: - - "master" + - "inference" paths: - "cmake/**" - "config/**" @@ -23,10 +10,14 @@ on: - "python/**" - "setup.py" - "include/**" + - "inference/**" - "src/**" + - "tests/inference/**" + - "conda/flexflow.yml" - ".github/workflows/gpu-ci.yml" - "tests/cpp_gpu_tests.sh" - - "tests/multi_gpu_tests.sh" + - "tests/inference_tests.sh" + - "tests/training_tests.sh" - "tests/python_interface_test.sh" workflow_dispatch: @@ -48,12 +39,13 @@ jobs: run: | pip3 install pip --upgrade pip3 install pyopenssl --upgrade + pip3 install urllib3 --upgrade pip3 install pygithub python3 .github/workflows/helpers/gpu_ci_helper.py python-interface-check: name: Check Python Interface - runs-on: self-hosted + runs-on: [self-hosted, gpu] defaults: run: shell: bash -l {0} # required to use an activated conda environment @@ -77,7 +69,7 @@ jobs: with: miniconda-version: "latest" activate-environment: flexflow - environment-file: conda/flexflow-cpu.yml + environment-file: conda/flexflow.yml auto-activate-base: false auto-update-conda: false @@ -89,7 +81,7 @@ jobs: run: | export PATH=$CONDA_PREFIX/bin:$PATH export FF_HOME=$(pwd) - export FF_USE_PREBUILT_LEGION=OFF + export FF_USE_PREBUILT_LEGION=OFF #remove this after fixing python path issue in Legion mkdir build cd build ../config/config.linux @@ -106,6 +98,7 @@ jobs: run: | export PATH=$CONDA_PREFIX/bin:$PATH export FF_HOME=$(pwd) + export FF_USE_PREBUILT_LEGION=OFF #remove this after fixing python path issue in Legion cd build ../config/config.linux make install @@ -124,45 +117,138 @@ jobs: export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$CONDA_PREFIX/lib ./tests/align/test_all_operators.sh - gpu-ci-flexflow: - name: Single Machine, Multiple GPUs Tests - runs-on: self-hosted - needs: python-interface-check + inference-tests: + name: Inference Tests + runs-on: [self-hosted, gpu] + defaults: + run: + shell: bash -l {0} # required to use an activated conda environment + env: + CONDA: "3" + HUGGINGFACE_TOKEN: ${{ secrets.HUGGINGFACE_TOKEN }} + needs: gpu-ci-concierge container: image: ghcr.io/flexflow/flexflow-environment-cuda-11.8:latest options: --gpus all --shm-size=8192m steps: - name: Install updated git version run: sudo add-apt-repository ppa:git-core/ppa -y && sudo apt update -y && sudo apt install -y --no-install-recommends git + - name: Checkout Git Repository uses: actions/checkout@v3 with: submodules: recursive + + - name: Install conda and FlexFlow dependencies + uses: conda-incubator/setup-miniconda@v2 + with: + miniconda-version: "latest" + activate-environment: flexflow + environment-file: conda/flexflow.yml + auto-activate-base: false + + - name: Build FlexFlow + run: | + export PATH=$CONDA_PREFIX/bin:$PATH + export FF_HOME=$(pwd) + export FF_USE_PREBUILT_LEGION=OFF #remove this after fixing python path issue in Legion + export FF_BUILD_ALL_INFERENCE_EXAMPLES=ON + mkdir build + cd build + ../config/config.linux + make -j + + - name: Run inference tests + env: + CPP_INFERENCE_TESTS: ${{ vars.CPP_INFERENCE_TESTS }} + run: | + export PATH=$CONDA_PREFIX/bin:$PATH + export FF_HOME=$(pwd) + export CUDNN_DIR=/usr/local/cuda + export CUDA_DIR=/usr/local/cuda + export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$CONDA_PREFIX/lib + + # GPT tokenizer test + # ./tests/gpt_tokenizer_test.sh + + # Inference tests + source ./build/set_python_envs.sh + ./tests/inference_tests.sh + + - name: Save inference output as an artifact + if: always() + run: | + cd inference + tar -zcvf output.tar.gz ./output + + - name: Upload artifact + uses: actions/upload-artifact@v3 + if: always() + with: + name: output + path: inference/output.tar.gz + + # Github persists the .cache folder across different runs/containers + - name: Clear cache + if: always() + run: sudo rm -rf ~/.cache + + training-tests: + name: Training Tests + runs-on: [self-hosted, gpu] + # skip this time-consuming test for PRs to the inference branch + # if: ${{ github.event_name != 'pull_request' || github.base_ref != 'inference' }} + defaults: + run: + shell: bash -l {0} # required to use an activated conda environment + env: + CONDA: "3" + needs: inference-tests + container: + image: ghcr.io/flexflow/flexflow-environment-cuda-11.8:latest + options: --gpus all --shm-size=8192m + steps: + - name: Install updated git version + run: sudo add-apt-repository ppa:git-core/ppa -y && sudo apt update -y && sudo apt install -y --no-install-recommends git + + - name: Checkout Git Repository + uses: actions/checkout@v3 + with: + submodules: recursive + + - name: Install conda and FlexFlow dependencies + uses: conda-incubator/setup-miniconda@v2 + with: + miniconda-version: "latest" + activate-environment: flexflow + environment-file: conda/flexflow.yml + auto-activate-base: false - name: Build and Install FlexFlow run: | - export PATH=/opt/conda/bin:$PATH + export PATH=$CONDA_PREFIX/bin:$PATH export FF_HOME=$(pwd) export FF_BUILD_ALL_EXAMPLES=ON - export FF_USE_PREBUILT_LEGION=OFF + export FF_BUILD_ALL_INFERENCE_EXAMPLES=ON + export FF_USE_PREBUILT_LEGION=OFF #remove this after fixing python path issue in Legion pip install . --verbose - name: Check FlexFlow Python interface (pip) run: | - export PATH=/opt/conda/bin:$PATH + export PATH=$CONDA_PREFIX/bin:$PATH export FF_HOME=$(pwd) - export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/opt/conda/lib + export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$CONDA_PREFIX/lib ./tests/python_interface_test.sh after-installation - name: Run multi-gpu tests run: | - export PATH=/opt/conda/bin:$PATH + export PATH=$CONDA_PREFIX/bin:$PATH export CUDNN_DIR=/usr/local/cuda export CUDA_DIR=/usr/local/cuda export FF_HOME=$(pwd) - export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/opt/conda/lib + export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$CONDA_PREFIX/lib # C++ tests ./tests/cpp_gpu_tests.sh 4 # Python tests - ./tests/multi_gpu_tests.sh 4 + ./tests/training_tests.sh 4 diff --git a/.github/workflows/helpers/install_cudnn.sh b/.github/workflows/helpers/install_cudnn.sh index 318134e331..7c11a4a420 100755 --- a/.github/workflows/helpers/install_cudnn.sh +++ b/.github/workflows/helpers/install_cudnn.sh @@ -44,6 +44,9 @@ elif [[ "$cuda_version" == "11.7" ]]; then elif [[ "$cuda_version" == "11.8" ]]; then CUDNN_LINK=https://developer.download.nvidia.com/compute/redist/cudnn/v8.7.0/local_installers/11.8/cudnn-linux-x86_64-8.7.0.84_cuda11-archive.tar.xz CUDNN_TARBALL_NAME=cudnn-linux-x86_64-8.7.0.84_cuda11-archive.tar.xz +elif [[ "$cuda_version" == "12.0" ]]; then + echo "CUDNN support for CUDA version 12.0 not yet added" + exit 1 fi wget -c -q $CUDNN_LINK if [[ "$cuda_version" == "11.6" || "$cuda_version" == "11.7" || "$cuda_version" == "11.8" ]]; then diff --git a/.github/workflows/helpers/install_dependencies.sh b/.github/workflows/helpers/install_dependencies.sh index 5ab211c962..6435a37eea 100755 --- a/.github/workflows/helpers/install_dependencies.sh +++ b/.github/workflows/helpers/install_dependencies.sh @@ -7,24 +7,61 @@ cd "${BASH_SOURCE[0]%/*}" # General dependencies echo "Installing apt dependencies..." -sudo apt-get update && sudo apt-get install -y --no-install-recommends wget binutils git zlib1g-dev libhdf5-dev && \ +sudo apt-get update && sudo apt-get install -y --no-install-recommends wget binutils git zlib1g-dev libhdf5-dev jq && \ sudo rm -rf /var/lib/apt/lists/* -# Install CUDNN -./install_cudnn.sh - -# Install HIP dependencies if needed FF_GPU_BACKEND=${FF_GPU_BACKEND:-"cuda"} +hip_version=${hip_version:-"5.6"} if [[ "${FF_GPU_BACKEND}" != @(cuda|hip_cuda|hip_rocm|intel) ]]; then echo "Error, value of FF_GPU_BACKEND (${FF_GPU_BACKEND}) is invalid." exit 1 -elif [[ "$FF_GPU_BACKEND" == "hip_cuda" || "$FF_GPU_BACKEND" = "hip_rocm" ]]; then +fi +# Install CUDNN if needed +if [[ "$FF_GPU_BACKEND" == "cuda" || "$FF_GPU_BACKEND" = "hip_cuda" ]]; then + # Install CUDNN + ./install_cudnn.sh + # Install NCCL + ./install_nccl.sh +fi +# Install HIP dependencies if needed +if [[ "$FF_GPU_BACKEND" == "hip_cuda" || "$FF_GPU_BACKEND" = "hip_rocm" ]]; then echo "FF_GPU_BACKEND: ${FF_GPU_BACKEND}. Installing HIP dependencies" - wget https://repo.radeon.com/amdgpu-install/22.20.5/ubuntu/focal/amdgpu-install_22.20.50205-1_all.deb - sudo apt-get install -y ./amdgpu-install_22.20.50205-1_all.deb - rm ./amdgpu-install_22.20.50205-1_all.deb + # Check that hip_version is one of 5.3,5.4,5.5,5.6 + if [[ "$hip_version" != "5.3" && "$hip_version" != "5.4" && "$hip_version" != "5.5" && "$hip_version" != "5.6" ]]; then + echo "hip_version '${hip_version}' is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + # Compute script name and url given the version + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.6.50600-1_all.deb + if [ "$hip_version" = "5.3" ]; then + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.3.50300-1_all.deb + elif [ "$hip_version" = "5.4" ]; then + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.4.50400-1_all.deb + elif [ "$hip_version" = "5.5" ]; then + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.5.50500-1_all.deb + fi + AMD_GPU_SCRIPT_URL="https://repo.radeon.com/amdgpu-install/${hip_version}/ubuntu/focal/${AMD_GPU_SCRIPT_NAME}" + # Download and install AMD GPU software with ROCM and HIP support + wget "$AMD_GPU_SCRIPT_URL" + sudo apt-get install -y ./${AMD_GPU_SCRIPT_NAME} + sudo rm ./${AMD_GPU_SCRIPT_NAME} sudo amdgpu-install -y --usecase=hip,rocm --no-dkms - sudo apt-get install -y hip-dev hipblas miopen-hip rocm-hip-sdk + sudo apt-get install -y hip-dev hipblas miopen-hip rocm-hip-sdk rocm-device-libs + + # Install protobuf v3.20.x manually + sudo apt-get update -y && sudo apt-get install -y pkg-config zip g++ zlib1g-dev unzip python autoconf automake libtool curl make + git clone -b 3.20.x https://github.com/protocolbuffers/protobuf.git + cd protobuf/ + git submodule update --init --recursive + ./autogen.sh + ./configure + cores_available=$(nproc --all) + n_build_cores=$(( cores_available -1 )) + if (( n_build_cores < 1 )) ; then n_build_cores=1 ; fi + make -j $n_build_cores + sudo make install + sudo ldconfig + cd .. else echo "FF_GPU_BACKEND: ${FF_GPU_BACKEND}. Skipping installing HIP dependencies" fi diff --git a/.github/workflows/helpers/install_nccl.sh b/.github/workflows/helpers/install_nccl.sh new file mode 100755 index 0000000000..ca88668d84 --- /dev/null +++ b/.github/workflows/helpers/install_nccl.sh @@ -0,0 +1,51 @@ +#!/bin/bash +set -euo pipefail +set -x + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +# Add NCCL key ring +ubuntu_version=$(lsb_release -rs) +ubuntu_version=${ubuntu_version//./} +wget "https://developer.download.nvidia.com/compute/cuda/repos/ubuntu${ubuntu_version}/x86_64/cuda-keyring_1.0-1_all.deb" +sudo dpkg -i cuda-keyring_1.0-1_all.deb +sudo apt update -y +rm -f cuda-keyring_1.0-1_all.deb + +# Install NCCL +cuda_version=${1:-11.8.0} +cuda_version=$(echo "${cuda_version}" | cut -f1,2 -d'.') +echo "Installing NCCL for CUDA version: ${cuda_version} ..." + +# We need to run a different install command based on the CUDA version, otherwise running `sudo apt install libnccl2 libnccl-dev` +# will automatically upgrade CUDA to the latest version. + +if [[ "$cuda_version" == "11.0" ]]; then + sudo apt install libnccl2=2.15.5-1+cuda11.0 libnccl-dev=2.15.5-1+cuda11.0 +elif [[ "$cuda_version" == "11.1" ]]; then + sudo apt install libnccl2=2.8.4-1+cuda11.1 libnccl-dev=2.8.4-1+cuda11.1 +elif [[ "$cuda_version" == "11.2" ]]; then + sudo apt install libnccl2=2.8.4-1+cuda11.2 libnccl-dev=2.8.4-1+cuda11.2 +elif [[ "$cuda_version" == "11.3" ]]; then + sudo apt install libnccl2=2.9.9-1+cuda11.3 libnccl-dev=2.9.9-1+cuda11.3 +elif [[ "$cuda_version" == "11.4" ]]; then + sudo apt install libnccl2=2.11.4-1+cuda11.4 libnccl-dev=2.11.4-1+cuda11.4 +elif [[ "$cuda_version" == "11.5" ]]; then + sudo apt install libnccl2=2.11.4-1+cuda11.5 libnccl-dev=2.11.4-1+cuda11.5 +elif [[ "$cuda_version" == "11.6" ]]; then + sudo apt install libnccl2=2.12.12-1+cuda11.6 libnccl-dev=2.12.12-1+cuda11.6 +elif [[ "$cuda_version" == "11.7" ]]; then + sudo apt install libnccl2=2.14.3-1+cuda11.7 libnccl-dev=2.14.3-1+cuda11.7 +elif [[ "$cuda_version" == "11.8" ]]; then + sudo apt install libnccl2=2.16.5-1+cuda11.8 libnccl-dev=2.16.5-1+cuda11.8 +elif [[ "$cuda_version" == "12.0" ]]; then + sudo apt install libnccl2=2.18.3-1+cuda12.0 libnccl-dev=2.18.3-1+cuda12.0 +elif [[ "$cuda_version" == "12.1" ]]; then + sudo apt install libnccl2=2.18.3-1+cuda12.1 libnccl-dev=2.18.3-1+cuda12.1 +elif [[ "$cuda_version" == "12.2" ]]; then + sudo apt install libnccl2=2.18.3-1+cuda12.2 libnccl-dev=2.18.3-1+cuda12.2 +else + echo "Installing NCCL for CUDA version ${cuda_version} is not supported" + exit 1 +fi diff --git a/.github/workflows/helpers/oracle_con.py b/.github/workflows/helpers/oracle_con.py new file mode 100644 index 0000000000..0891d66e99 --- /dev/null +++ b/.github/workflows/helpers/oracle_con.py @@ -0,0 +1,37 @@ +import oci +import argparse +import os + +parser = argparse.ArgumentParser(description="Program with optional flags") +group = parser.add_mutually_exclusive_group() +group.add_argument("--start", action="store_true", help="Start action") +group.add_argument("--stop", action="store_true", help="Stop action") +parser.add_argument("--instance_id", type=str, required=True, help="instance id required") +args = parser.parse_args() + +oci_key_content = os.getenv("OCI_CLI_KEY_CONTENT") + +config = { + "user": os.getenv("OCI_CLI_USER"), + "key_content": os.getenv("OCI_CLI_KEY_CONTENT"), + "fingerprint": os.getenv("OCI_CLI_FINGERPRINT"), + "tenancy": os.getenv("OCI_CLI_TENANCY"), + "region": os.getenv("OCI_CLI_REGION") +} + +# Initialize the OCI configuration +oci.config.validate_config(config) + +# Initialize the ComputeClient to interact with VM instances +compute = oci.core.ComputeClient(config) + +# Replace 'your_instance_id' with the actual instance ID of your VM +instance_id = args.instance_id + +# Perform the action +if args.start: + # Start the VM + compute.instance_action(instance_id, "START") +else: + # Stop the VM + compute.instance_action(instance_id, "STOP") diff --git a/.github/workflows/helpers/prebuild_legion.sh b/.github/workflows/helpers/prebuild_legion.sh new file mode 100755 index 0000000000..9f5cbe147a --- /dev/null +++ b/.github/workflows/helpers/prebuild_legion.sh @@ -0,0 +1,75 @@ +#! /usr/bin/env bash +set -euo pipefail + +# Parse input params +python_version=${python_version:-"empty"} +gpu_backend=${gpu_backend:-"empty"} +gpu_backend_version=${gpu_backend_version:-"empty"} + +if [[ "${gpu_backend}" != @(cuda|hip_cuda|hip_rocm|intel) ]]; then + echo "Error, value of gpu_backend (${gpu_backend}) is invalid. Pick between 'cuda', 'hip_cuda', 'hip_rocm' or 'intel'." + exit 1 +else + echo "Pre-building Legion with GPU backend: ${gpu_backend}" +fi + +if [[ "${gpu_backend}" == "cuda" || "${gpu_backend}" == "hip_cuda" ]]; then + # Check that CUDA version is supported. Versions above 12.0 not supported because we don't publish docker images for it yet. + if [[ "$gpu_backend_version" != @(11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0) ]]; then + echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0}" + exit 1 + fi + export cuda_version="$gpu_backend_version" +elif [[ "${gpu_backend}" == "hip_rocm" ]]; then + # Check that HIP version is supported + if [[ "$gpu_backend_version" != @(5.3|5.4|5.5|5.6) ]]; then + echo "hip_version is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + export hip_version="$gpu_backend_version" +else + echo "gpu backend: ${gpu_backend} and gpu_backend_version: ${gpu_backend_version} not yet supported." + exit 1 +fi + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +export FF_GPU_BACKEND="${gpu_backend}" +export FF_CUDA_ARCH=all +export FF_HIP_ARCH=all +export BUILD_LEGION_ONLY=ON +export INSTALL_DIR="/usr/legion" +export python_version="${python_version}" + +# Build Docker Flexflow Container +echo "building docker" +../../../docker/build.sh flexflow + +# Cleanup any existing container with the same name +docker rm prelegion || true + +# Create container to be able to copy data from the image +docker create --name prelegion flexflow-"${gpu_backend}"-"${gpu_backend_version}":latest + +# Copy legion libraries to host +echo "extract legion library assets" +mkdir -p ../../../prebuilt_legion_assets +rm -rf ../../../prebuilt_legion_assets/tmp || true +docker cp prelegion:$INSTALL_DIR ../../../prebuilt_legion_assets/tmp + + +# Create the tarball file +cd ../../../prebuilt_legion_assets/tmp +export LEGION_TARBALL="legion_ubuntu-20.04_${gpu_backend}-${gpu_backend_version}_py${python_version}.tar.gz" + +echo "Creating archive $LEGION_TARBALL" +tar -zcvf "../$LEGION_TARBALL" ./ +cd .. +echo "Checking the size of the Legion tarball..." +du -h "$LEGION_TARBALL" + + +# Cleanup +rm -rf tmp/* +docker rm prelegion diff --git a/.github/workflows/multinode-test.yml b/.github/workflows/multinode-test.yml index 37f81b615f..226f953b38 100644 --- a/.github/workflows/multinode-test.yml +++ b/.github/workflows/multinode-test.yml @@ -25,6 +25,7 @@ jobs: run: | pip3 install pip --upgrade pip3 install pyopenssl --upgrade + pip3 install urllib3 --upgrade pip3 install pygithub python3 .github/workflows/helpers/gpu_ci_helper.py @@ -77,7 +78,7 @@ jobs: export OMPI_ALLOW_RUN_AS_ROOT=1 export OMPI_ALLOW_RUN_AS_ROOT_CONFIRM=1 export OMPI_MCA_btl_vader_single_copy_mechanism=none - ./tests/multi_gpu_tests.sh 2 2 + ./tests/training_tests.sh 2 2 multinode-gpu-test-ucx: name: Multinode GPU Test with UCX @@ -128,7 +129,7 @@ jobs: export OMPI_ALLOW_RUN_AS_ROOT=1 export OMPI_ALLOW_RUN_AS_ROOT_CONFIRM=1 export OMPI_MCA_btl_vader_single_copy_mechanism=none - ./tests/multi_gpu_tests.sh 2 2 + ./tests/training_tests.sh 2 2 multinode-gpu-test-native-ucx: name: Multinode GPU Test with native UCX @@ -176,7 +177,7 @@ jobs: export OMPI_ALLOW_RUN_AS_ROOT=1 export OMPI_ALLOW_RUN_AS_ROOT_CONFIRM=1 export OMPI_MCA_btl_vader_single_copy_mechanism=none - ./tests/multi_gpu_tests.sh 2 2 + ./tests/training_tests.sh 2 2 notify-slack: name: Notify Slack in case of failure diff --git a/.github/workflows/pip-deploy.yml b/.github/workflows/pip-deploy.yml new file mode 100644 index 0000000000..66fdf00c9a --- /dev/null +++ b/.github/workflows/pip-deploy.yml @@ -0,0 +1,72 @@ +name: "pip-deploy" +on: + workflow_dispatch: + +concurrency: + group: pip-deploy-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + build-n-publish: + name: Build and publish Python 🐍 distributions 📦 to PyPI and TestPyPI + runs-on: ubuntu-20.04 + permissions: + # IMPORTANT: this permission is mandatory for trusted publishing + id-token: write + + steps: + - name: Checkout Git Repository + uses: actions/checkout@v3 + with: + submodules: recursive + + - name: Free additional space on runner + run: .github/workflows/helpers/free_space_on_runner.sh + + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.x" + + - name: Install pypa/build + run: >- + python3 -m + pip install + build + --user + + - name: Build a source tarball + env: + DEPLOY_TO_TEST_PYPI: ${{ vars.DEPLOY_TO_TEST_PYPI }} + run: >- + python3 -m + build + --sdist + --outdir dist/ + . + + - name: Publish distribution 📦 to Test PyPI + if: ${{ vars.DEPLOY_TO_TEST_PYPI == 'true' }} + uses: pypa/gh-action-pypi-publish@release/v1 + with: + repository-url: https://test.pypi.org/legacy/ + + - name: Publish distribution 📦 to PyPI + if: ${{ vars.DEPLOY_TO_TEST_PYPI == 'false' }} + uses: pypa/gh-action-pypi-publish@release/v1 + + - name: Get package version + if: ${{ vars.DEPLOY_TO_TEST_PYPI == 'false' }} + run: | + # when running setup.py outside of pip install, we need to manually install the modules that are imported in the script + pip install setuptools requests cmake-build-extension + version=$(python setup.py --version) + echo "PY_VERSION=${version}" >> $GITHUB_ENV + + - name: Create Git tag + if: ${{ vars.DEPLOY_TO_TEST_PYPI == 'false' }} + uses: mathieudutour/github-tag-action@v6.1 + with: + github_token: ${{ secrets.FLEXFLOW_TOKEN }} + custom_tag: ${{ env.PY_VERSION }} + diff --git a/.github/workflows/pip-install-skip.yml b/.github/workflows/pip-install-skip.yml index f2606b94d8..92c3223e32 100644 --- a/.github/workflows/pip-install-skip.yml +++ b/.github/workflows/pip-install-skip.yml @@ -7,6 +7,7 @@ on: - "deps/**" - "python/**" - "setup.py" + - "requirements.txt" - ".github/workflows/helpers/install_dependencies.sh" - ".github/workflows/pip-install.yml" workflow_dispatch: diff --git a/.github/workflows/pip-install.yml b/.github/workflows/pip-install.yml index 7d60d3bf52..3562134987 100644 --- a/.github/workflows/pip-install.yml +++ b/.github/workflows/pip-install.yml @@ -7,6 +7,7 @@ on: - "deps/**" - "python/**" - "setup.py" + - "requirements.txt" - ".github/workflows/helpers/install_dependencies.sh" - ".github/workflows/pip-install.yml" push: @@ -18,6 +19,7 @@ on: - "deps/**" - "python/**" - "setup.py" + - "requirements.txt" - ".github/workflows/helpers/install_dependencies.sh" - ".github/workflows/pip-install.yml" workflow_dispatch: @@ -64,10 +66,11 @@ jobs: export FF_HOME=$(pwd) export FF_CUDA_ARCH=70 pip install . --verbose + # Remove build folder to check that the installed version can run independently of the build files + rm -rf build - - name: Check availability of Python flexflow.core module + - name: Check availability of flexflow modules in Python run: | export LD_LIBRARY_PATH="$CUDA_PATH/lib64/stubs:$LD_LIBRARY_PATH" sudo ln -s "$CUDA_PATH/lib64/stubs/libcuda.so" "$CUDA_PATH/lib64/stubs/libcuda.so.1" - export CPU_ONLY_TEST=1 - python -c "import flexflow.core; exit()" + python -c 'import flexflow.core; import flexflow.serve as ff; exit()' diff --git a/.github/workflows/prebuild-legion.yml b/.github/workflows/prebuild-legion.yml new file mode 100644 index 0000000000..267daaee6b --- /dev/null +++ b/.github/workflows/prebuild-legion.yml @@ -0,0 +1,84 @@ +name: "prebuild-legion" +on: + push: + branches: + - "inference" + paths: + - "cmake/**" + - "config/**" + - "deps/legion/**" + - ".github/workflows/helpers/install_dependencies.sh" + workflow_dispatch: +concurrency: + group: prebuild-legion-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + prebuild-legion: + name: Prebuild Legion with CMake + runs-on: ubuntu-20.04 + defaults: + run: + shell: bash -l {0} # required to use an activated conda environment + strategy: + matrix: + gpu_backend: ["cuda", "hip_rocm"] + gpu_backend_version: ["11.8", "5.6"] + python_version: ["3.11"] + exclude: + - gpu_backend: "cuda" + gpu_backend_version: "5.6" + - gpu_backend: "hip_rocm" + gpu_backend_version: "11.8" + fail-fast: false + steps: + - name: Checkout Git Repository + uses: actions/checkout@v3 + with: + submodules: recursive + + - name: Free additional space on runner + run: .github/workflows/helpers/free_space_on_runner.sh + + - name: Build Legion + env: + gpu_backend: ${{ matrix.gpu_backend }} + gpu_backend_version: ${{ matrix.gpu_backend_version }} + python_version: ${{ matrix.python_version }} + run: .github/workflows/helpers/prebuild_legion.sh + + - name: Archive compiled Legion library (CUDA) + uses: actions/upload-artifact@v3 + with: + name: legion_ubuntu-20.04_${{ matrix.gpu_backend }}-${{ matrix.gpu_backend_version }}_py${{ matrix.python_version }} + path: prebuilt_legion_assets/legion_ubuntu-20.04_${{ matrix.gpu_backend }}-${{ matrix.gpu_backend_version }}_py${{ matrix.python_version }}.tar.gz + + create-release: + name: Create new release + runs-on: ubuntu-20.04 + needs: prebuild-legion + steps: + - name: Checkout Git Repository + uses: actions/checkout@v3 + - name: Free additional space on runner + run: .github/workflows/helpers/free_space_on_runner.sh + - name: Create folder for artifacts + run: mkdir artifacts unwrapped_artifacts + - name: Download artifacts + uses: actions/download-artifact@v3 + with: + path: ./artifacts + - name: Display structure of downloaded files + working-directory: ./artifacts + run: ls -R + - name: Unwrap all artifacts + working-directory: ./artifacts + run: find . -maxdepth 2 -mindepth 2 -type f -name "*.tar.gz" -exec mv {} ../unwrapped_artifacts/ \; + - name: Get datetime + run: echo "RELEASE_DATETIME=$(date '+%Y-%m-%dT%H-%M-%S')" >> $GITHUB_ENV + - name: Release + env: + NAME: ${{ env.RELEASE_DATETIME }} + TAG_NAME: ${{ env.RELEASE_DATETIME }} + GITHUB_TOKEN: ${{ secrets.FLEXFLOW_TOKEN }} + run: gh release create $TAG_NAME ./unwrapped_artifacts/*.tar.gz --repo flexflow/flexflow-third-party diff --git a/.gitignore b/.gitignore index b2e3c59ced..7f6a3c4137 100644 --- a/.gitignore +++ b/.gitignore @@ -15,6 +15,11 @@ __pycache__/ # C extensions *.so +/inference/weights/* +/inference/tokenizer/* +/inference/prompt/* +/inference/output/* + # Distribution / packaging .Python build/ @@ -83,10 +88,7 @@ docs/build/ # Doxygen documentation docs/doxygen/output/ - -# Exhale documentation -docs/source/_doxygen/ -docs/source/c++_api/ +docs/doxygen/cpp_api/ # PyBuilder .pybuilder/ @@ -179,3 +181,10 @@ train-labels-idx1-ubyte # Logs logs/ +gpt_tokenizer + +# pip version +python/flexflow/version.txt + +inference_tensors +tests/inference/python_test_configs/*.json diff --git a/.gitmodules b/.gitmodules index b8419fda94..c68582d4ac 100644 --- a/.gitmodules +++ b/.gitmodules @@ -19,3 +19,7 @@ [submodule "deps/json"] path = deps/json url = https://github.com/nlohmann/json.git +[submodule "deps/tokenizers-cpp"] + path = deps/tokenizers-cpp + url = https://github.com/mlc-ai/tokenizers-cpp.git + fetchRecurseSubmodules = true \ No newline at end of file diff --git a/CMakeLists.txt b/CMakeLists.txt index 81845dd7b3..377ede0d0d 100644 --- a/CMakeLists.txt +++ b/CMakeLists.txt @@ -1,6 +1,7 @@ cmake_minimum_required(VERSION 3.10) project(FlexFlow) + include(ExternalProject) # Set policy CMP0074 to eliminate cmake warnings @@ -12,7 +13,21 @@ if (CMAKE_VERSION VERSION_GREATER_EQUAL "3.24.0") endif() set(CMAKE_MODULE_PATH ${CMAKE_MODULE_PATH} ${CMAKE_CURRENT_LIST_DIR}/cmake) set(FLEXFLOW_ROOT ${CMAKE_CURRENT_LIST_DIR}) -set(CMAKE_CXX_FLAGS "${CMAKE_CXX_FLAGS} -UNDEBUG") +set(CMAKE_CXX_FLAGS "-std=c++17 ${CMAKE_CXX_FLAGS} -fPIC -UNDEBUG") +set(CMAKE_HIP_FLAGS "-std=c++17 ${CMAKE_HIP_FLAGS} -fPIC -UNDEBUG") + +# set std 17 +#set(CMAKE_CXX_STANDARD 17) +#set(CMAKE_CUDA_STANDARD 17) + +option(INFERENCE_TESTS "Run inference tests" OFF) +set(LIBTORCH_PATH "${CMAKE_CURRENT_SOURCE_DIR}/../libtorch" CACHE STRING "LibTorch Path") +if (INFERENCE_TESTS) + find_package(Torch REQUIRED PATHS ${LIBTORCH_PATH} NO_DEFAULT_PATH) + set(CMAKE_CXX_FLAGS "-std=c++17 ${CMAKE_CXX_FLAGS} -fPIC ${TORCH_CXX_FLAGS}") + message(STATUS "LIBTORCH_PATH: ${LIBTORCH_PATH}") + message(STATUS "TORCH_LIBRARIES: ${TORCH_LIBRARIES}") +endif() # Set a default build type if none was specified set(default_build_type "Debug") @@ -22,8 +37,22 @@ if(NOT CMAKE_BUILD_TYPE AND NOT CMAKE_CONFIGURATION_TYPES) STRING "Choose the type of build." FORCE) endif() +if(INSTALL_DIR) + message(STATUS "INSTALL_DIR: ${INSTALL_DIR}") + set(CMAKE_INSTALL_PREFIX ${INSTALL_DIR} CACHE PATH "Installation directory" FORCE) +else() + # Install DIR not set. Use default, unless a conda environment is active + if (DEFINED ENV{CONDA_PREFIX} AND NOT FF_BUILD_FROM_PYPI) + set(CONDA_PREFIX $ENV{CONDA_PREFIX}) + # Set CMAKE_INSTALL_PREFIX to the Conda environment's installation path + set(CMAKE_INSTALL_PREFIX ${CONDA_PREFIX} CACHE PATH "Installation directory" FORCE) + message(STATUS "Active conda environment detected. Setting CMAKE_INSTALL_PREFIX: ${CMAKE_INSTALL_PREFIX}") + endif() +endif() + # do not disable assertions even if in release mode set(CMAKE_CXX_FLAGS_RELEASE "${CMAKE_CXX_FLAGS_RELEASE} -UNDEBUG") +set(CMAKE_HIP_FLAGS_RELEASE "${CMAKE_HIP_FLAGS_RELEASE} -UNDEBUG") if(${CMAKE_SYSTEM_NAME} MATCHES "Linux") set(LIBEXT ".so") @@ -38,111 +67,23 @@ option(BUILD_SHARED_LIBS "Build shared libraries instead of static ones" ON) # option for using Python option(FF_USE_PYTHON "Enable Python" ON) +# option for building legion only +option(BUILD_LEGION_ONLY "Build Legion only" OFF) + # option to download pre-compiled NCCL/Legion libraries option(FF_USE_PREBUILT_NCCL "Enable use of NCCL pre-compiled library, if available" ON) option(FF_USE_PREBUILT_LEGION "Enable use of Legion pre-compiled library, if available" ON) option(FF_USE_ALL_PREBUILT_LIBRARIES "Enable use of all pre-compiled libraries, if available" OFF) -# option for using Python -set(FF_GASNET_CONDUITS aries udp mpi ibv ucx) +# option for using network +set(FF_GASNET_CONDUITS aries udp mpi ibv) set(FF_GASNET_CONDUIT "mpi" CACHE STRING "Select GASNet conduit ${FF_GASNET_CONDUITS}") set_property(CACHE FF_GASNET_CONDUIT PROPERTY STRINGS ${FF_GASNET_CONDUITS}) set(FF_LEGION_NETWORKS "" CACHE STRING "Network backend(s) to use") -if ((FF_LEGION_NETWORKS STREQUAL "gasnet" AND FF_GASNET_CONDUIT STREQUAL "ucx") OR FF_LEGION_NETWORKS STREQUAL "ucx") - if("${FF_UCX_URL}" STREQUAL "") - set(UCX_URL "https://github.com/openucx/ucx/releases/download/v1.14.0-rc1/ucx-1.14.0.tar.gz") - else() - set(UCX_URL "${FF_UCX_URL}") - endif() - - set(UCX_DIR ${CMAKE_CURRENT_BINARY_DIR}/ucx) - get_filename_component(UCX_COMPRESSED_FILE_NAME "${UCX_URL}" NAME) - # message(STATUS "UCX_URL: ${UCX_URL}") - # message(STATUS "UCX_COMPRESSED_FILE_NAME: ${UCX_COMPRESSED_FILE_NAME}") - set(UCX_COMPRESSED_FILE_PATH "${CMAKE_CURRENT_BINARY_DIR}/${UCX_COMPRESSED_FILE_NAME}") - set(UCX_BUILD_NEEDED OFF) - set(UCX_CONFIG_FILE ${UCX_DIR}/config.txt) - set(UCX_BUILD_OUTPUT ${UCX_DIR}/build.log) - - if(EXISTS ${UCX_CONFIG_FILE}) - file(READ ${UCX_CONFIG_FILE} PREV_UCX_CONFIG) - # message(STATUS "PREV_UCX_CONFIG: ${PREV_UCX_CONFIG}") - if("${UCX_URL}" STREQUAL "${PREV_UCX_CONFIG}") - # configs match - no build needed - set(UCX_BUILD_NEEDED OFF) - else() - message(STATUS "UCX configuration has changed - rebuilding...") - set(UCX_BUILD_NEEDED ON) - endif() - else() - message(STATUS "Configuring and building UCX...") - set(UCX_BUILD_NEEDED ON) - endif() - - if(UCX_BUILD_NEEDED) - if(NOT EXISTS "${UCX_COMPRESSED_FILE_PATH}") - message(STATUS "Downloading openucx/ucx from: ${UCX_URL}") - file( - DOWNLOAD - "${UCX_URL}" "${UCX_COMPRESSED_FILE_PATH}" - SHOW_PROGRESS - STATUS status - LOG log - ) - - list(GET status 0 status_code) - list(GET status 1 status_string) - - if(status_code EQUAL 0) - message(STATUS "Downloading... done") - else() - message(FATAL_ERROR "error: downloading '${UCX_URL}' failed - status_code: ${status_code} - status_string: ${status_string} - log: - --- LOG BEGIN --- - ${log} - --- LOG END ---" - ) - endif() - else() - message(STATUS "${UCX_COMPRESSED_FILE_NAME} already exists") - endif() - - execute_process(COMMAND mkdir -p ${UCX_DIR}) - execute_process(COMMAND tar xzf ${UCX_COMPRESSED_FILE_PATH} -C ${UCX_DIR} --strip-components 1) - message(STATUS "Building UCX...") - execute_process( - COMMAND sh -c "cd ${UCX_DIR} && ${UCX_DIR}/contrib/configure-release --prefix=${UCX_DIR}/install --enable-mt && make -j8 && make install" - RESULT_VARIABLE UCX_BUILD_STATUS - OUTPUT_FILE ${UCX_BUILD_OUTPUT} - ERROR_FILE ${UCX_BUILD_OUTPUT} - ) - - if(UCX_BUILD_STATUS) - message(FATAL_ERROR "UCX build result = ${UCX_BUILD_STATUS} - see ${UCX_BUILD_OUTPUT} for more details") - endif() - - # Currently, we use default build configurations for UCX and therefore only save URL as configuration settings - file(WRITE ${UCX_CONFIG_FILE} "${UCX_URL}") - endif() - - if (FF_LEGION_NETWORKS STREQUAL "gasnet" AND FF_GASNET_CONDUIT STREQUAL "ucx") - set(ENV{UCX_HOME} "${UCX_DIR}/install") - install(DIRECTORY ${UCX_DIR}/install/bin/ DESTINATION bin) - install(DIRECTORY ${UCX_DIR}/install/include/ DESTINATION include) - install(DIRECTORY ${UCX_DIR}/install/lib/ DESTINATION lib) - install(DIRECTORY ${UCX_DIR}/install/share/ DESTINATION share) - endif() - - if (FF_LEGION_NETWORKS STREQUAL "ucx") - set(ucx_DIR ${UCX_DIR}/cmake) - set(ENV{Legion_NETWORKS} "ucx") - message(STATUS "Legion_NETWORKS: $ENV{Legion_NETWORKS}") - endif() -else() - message(STATUS "FF_GASNET_CONDUIT: ${FF_GASNET_CONDUIT}") +message(STATUS "FF_LEGION_NETWORKS: ${FF_LEGION_NETWORKS}") +if (FF_LEGION_NETWORKS STREQUAL "gasnet") + message(STATUS "FF_GASNET_CONDUIT: ${FF_GASNET_CONDUIT}") endif() set(FF_GPU_BACKENDS cuda hip_cuda hip_rocm intel) @@ -151,9 +92,14 @@ set_property(CACHE FF_GPU_BACKEND PROPERTY STRINGS ${FF_GPU_BACKENDS}) # option for cuda arch set(FF_CUDA_ARCH "autodetect" CACHE STRING "Target CUDA Arch") -if (FF_CUDA_ARCH STREQUAL "") +if ((FF_GPU_BACKEND STREQUAL "cuda" OR FF_GPU_BACKEND STREQUAL "hip_cuda") AND FF_CUDA_ARCH STREQUAL "") message(FATAL_ERROR "FF_CUDA_ARCH cannot be an empty string. Set it to `autodetect`, `all`, or pass one or multiple valid CUDA archs.") endif() +# option for hip arch +set(FF_HIP_ARCH "all" CACHE STRING "Target HIP Arch") +if (FF_GPU_BACKEND STREQUAL "hip_rocm" AND FF_CUDA_ARCH STREQUAL "") + message(FATAL_ERROR "FF_HIP_ARCH cannot be an empty string. Set it to `all`, or pass one or multiple valid HIP archs.") +endif() # option for nccl option(FF_USE_NCCL "Run FlexFlow with NCCL" OFF) @@ -166,6 +112,7 @@ set(FF_MAX_DIM "4" CACHE STRING "Maximum dimention of tensors") # option for legion option(FF_USE_EXTERNAL_LEGION "Use pre-installed Legion" OFF) +set(LEGION_MAX_RETURN_SIZE "32768" CACHE STRING "Maximum Legion return size") set(FLEXFLOW_EXT_LIBRARIES "") set(FLEXFLOW_INCLUDE_DIRS "") @@ -177,10 +124,10 @@ set(LD_FLAGS $ENV{LD_FLAGS}) # Set global FLAGS list(APPEND CC_FLAGS - -std=c++11) - + -std=c++17) list(APPEND NVCC_FLAGS - -std=c++11) + -std=c++17) + add_compile_options(${CC_FLAGS}) set(CUDA_NVCC_FLAGS ${CUDA_NVCC_FLAGS} ${NVCC_FLAGS}) @@ -205,14 +152,17 @@ if(FF_GPU_BACKEND STREQUAL "hip_cuda" OR FF_GPU_BACKEND STREQUAL "hip_rocm") set(ROCM_PATH "/opt/rocm" CACHE STRING "Default ROCM installation directory.") endif() -# ZLIB -include(zlib) - # CUDA if (FF_GPU_BACKEND STREQUAL "cuda" OR FF_GPU_BACKEND STREQUAL "hip_cuda") include(cuda) endif() +# HIP +if (FF_GPU_BACKEND STREQUAL "hip_rocm" OR FF_GPU_BACKEND STREQUAL "hip_cuda") + enable_language(HIP) + include(hip) +endif() + # CUDNN if (FF_GPU_BACKEND STREQUAL "cuda" OR FF_GPU_BACKEND STREQUAL "hip_cuda") include(cudnn) @@ -232,112 +182,216 @@ endif() # Legion include(legion) -# json -include(json) - -# variant -include(variant) - -# optional -include(optional) - -if (FF_GPU_BACKEND STREQUAL "cuda") - list(APPEND FF_CC_FLAGS - -DFF_USE_CUDA) - list(APPEND FF_NVCC_FLAGS - -DFF_USE_CUDA) -elseif (FF_GPU_BACKEND STREQUAL "hip_cuda") - list(APPEND FF_CC_FLAGS - -DFF_USE_HIP_CUDA) - list(APPEND FF_HIPCC_FLAGS - -DFF_USE_HIP_CUDA) -elseif (FF_GPU_BACKEND STREQUAL "hip_rocm") - list(APPEND FF_CC_FLAGS - -DFF_USE_HIP_ROCM) - list(APPEND FF_HIPCC_FLAGS - -DFF_USE_HIP_ROCM) -else() -endif() +# Not build FlexFlow if BUILD_LEGION_ONLY is ON +if(NOT BUILD_LEGION_ONLY) + # NCCL + if(FF_USE_NCCL) + if(FF_GPU_BACKEND STREQUAL "hip_cuda" OR FF_GPU_BACKEND STREQUAL "cuda") + include(nccl) + endif() + list(APPEND FF_CC_FLAGS + -DFF_USE_NCCL) + list(APPEND FF_NVCC_FLAGS + -DFF_USE_NCCL) + endif() -# Start build FlexFlow -if (CMAKE_BUILD_TYPE STREQUAL "Debug") + # Inference tests + if(INFERENCE_TESTS) list(APPEND FF_CC_FLAGS - -DFF_DEBUG) + -DINFERENCE_TESTS) list(APPEND FF_NVCC_FLAGS - -DFF_DEBUG) -endif() + -DINFERENCE_TESTS) + endif() + + # json + include(json) + + # variant + include(variant) + + # optional + include(optional) + + if (FF_GPU_BACKEND STREQUAL "cuda") + list(APPEND FF_CC_FLAGS + -DFF_USE_CUDA) + list(APPEND FF_NVCC_FLAGS + -DFF_USE_CUDA) + elseif (FF_GPU_BACKEND STREQUAL "hip_cuda") + list(APPEND FF_CC_FLAGS + -DFF_USE_HIP_CUDA) + list(APPEND FF_HIPCC_FLAGS + -DFF_USE_HIP_CUDA) + elseif (FF_GPU_BACKEND STREQUAL "hip_rocm") + list(APPEND FF_CC_FLAGS + -DFF_USE_HIP_ROCM) + list(APPEND FF_HIPCC_FLAGS + -DFF_USE_HIP_ROCM) + else() + endif() -message(STATUS "FlexFlow MAX_DIM: ${FF_MAX_DIM}") + # Start build FlexFlow + if (CMAKE_BUILD_TYPE STREQUAL "Debug") + list(APPEND FF_CC_FLAGS + -DFF_DEBUG) + list(APPEND FF_NVCC_FLAGS + -DFF_DEBUG) + endif() -list(APPEND FF_CC_FLAGS - -DMAX_TENSOR_DIM=${FF_MAX_DIM}) + message(STATUS "FlexFlow MAX_DIM: ${FF_MAX_DIM}") + message(STATUS "LEGION_MAX_RETURN_SIZE: ${LEGION_MAX_RETURN_SIZE}") -if(FF_USE_AVX2) list(APPEND FF_CC_FLAGS - -DFF_USE_AVX2 - -mavx2) -endif() + -DMAX_TENSOR_DIM=${FF_MAX_DIM} + -DLEGION_MAX_RETURN_SIZE=${LEGION_MAX_RETURN_SIZE}) -list(APPEND FF_NVCC_FLAGS - -Wno-deprecated-gpu-targets - -DMAX_TENSOR_DIM=${FF_MAX_DIM}) - -list(APPEND FF_LD_FLAGS - -lrt - -ldl - -rdynamic) - -# Set FF FLAGS -add_compile_options(${FF_CC_FLAGS}) -set(CUDA_NVCC_FLAGS ${CUDA_NVCC_FLAGS} ${FF_NVCC_FLAGS} -UNDEBUG) -link_libraries(${FF_LD_FLAGS}) + if(FF_USE_AVX2) + list(APPEND FF_CC_FLAGS + -DFF_USE_AVX2 + -mavx2) + endif() -list(APPEND FLEXFLOW_INCLUDE_DIRS - ${FLEXFLOW_ROOT}/include - ${FLEXFLOW_ROOT}) + list(APPEND FF_NVCC_FLAGS + -Wno-deprecated-gpu-targets + -DMAX_TENSOR_DIM=${FF_MAX_DIM} + -DLEGION_MAX_RETURN_SIZE=${LEGION_MAX_RETURN_SIZE}) + + list(APPEND FF_LD_FLAGS + -lrt + -ldl + -rdynamic + -lstdc++fs) + + # Set FF FLAGS + add_compile_options(${FF_CC_FLAGS}) + set(CUDA_NVCC_FLAGS ${CUDA_NVCC_FLAGS} ${FF_NVCC_FLAGS} -UNDEBUG) + link_libraries(${FF_LD_FLAGS}) + + list(APPEND FLEXFLOW_INCLUDE_DIRS + ${FLEXFLOW_ROOT}/include + ${FLEXFLOW_ROOT}) + + file(GLOB_RECURSE FLEXFLOW_HDR + LIST_DIRECTORIES False + ${FLEXFLOW_ROOT}/include/*.h) + + #list(APPEND FLEXFLOW_HDR ${FLEXFLOW_ROOT}/inference/file_loader.h) -file(GLOB_RECURSE FLEXFLOW_HDR - LIST_DIRECTORIES False - ${FLEXFLOW_ROOT}/include/*.h) + file(GLOB_RECURSE FLEXFLOW_SRC + LIST_DIRECTORIES False + ${FLEXFLOW_ROOT}/src/*.cc) + + list(REMOVE_ITEM FLEXFLOW_SRC "${FLEXFLOW_ROOT}/src/runtime/cpp_driver.cc") + #list(APPEND FLEXFLOW_SRC ${FLEXFLOW_ROOT}/inference/file_loader.cc) -file(GLOB_RECURSE FLEXFLOW_SRC - LIST_DIRECTORIES False - ${FLEXFLOW_ROOT}/src/*.cc) -list(REMOVE_ITEM FLEXFLOW_SRC "${FLEXFLOW_ROOT}/src/runtime/cpp_driver.cc") + set(FLEXFLOW_CPP_DRV_SRC + ${FLEXFLOW_ROOT}/src/runtime/cpp_driver.cc) -set(FLEXFLOW_CPP_DRV_SRC - ${FLEXFLOW_ROOT}/src/runtime/cpp_driver.cc) + add_library(substitution_loader SHARED + ${FLEXFLOW_ROOT}/src/runtime/substitution_loader.cc) + target_include_directories(substitution_loader PRIVATE ${FLEXFLOW_INCLUDE_DIRS}) + target_link_libraries(substitution_loader nlohmann_json::nlohmann_json) -add_library(substitution_loader SHARED - ${FLEXFLOW_ROOT}/src/runtime/substitution_loader.cc) -target_include_directories(substitution_loader PRIVATE ${FLEXFLOW_INCLUDE_DIRS}) -target_link_libraries(substitution_loader nlohmann_json::nlohmann_json) + #message("FLEXFLOW_INCLUDE_DIRS: ${FLEXFLOW_INCLUDE_DIRS}") -#message("FLEXFLOW_INCLUDE_DIRS: ${FLEXFLOW_INCLUDE_DIRS}") + # compile flexflow lib + if (FF_GPU_BACKEND STREQUAL "cuda") + file(GLOB_RECURSE FLEXFLOW_GPU_SRC + LIST_DIRECTORIES False + ${FLEXFLOW_ROOT}/src/*.cu) -# compile flexflow lib -if (FF_GPU_BACKEND STREQUAL "cuda") - file(GLOB_RECURSE FLEXFLOW_GPU_SRC - LIST_DIRECTORIES False - ${FLEXFLOW_ROOT}/src/*.cu) + add_compile_definitions(FF_USE_CUDA) - add_compile_definitions(FF_USE_CUDA) + if(BUILD_SHARED_LIBS) + cuda_add_library(flexflow SHARED ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC} OPTIONS ${CUDA_GENCODE}) + else() + cuda_add_library(flexflow STATIC ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC} OPTIONS ${CUDA_GENCODE}) + endif() + elseif(FF_GPU_BACKEND STREQUAL "hip_cuda" OR FF_GPU_BACKEND STREQUAL "hip_rocm") + file(GLOB_RECURSE FLEXFLOW_GPU_SRC + LIST_DIRECTORIES False + ${FLEXFLOW_ROOT}/src/*.cpp) + + set_source_files_properties(${FLEXFLOW_GPU_SRC} PROPERTIES LANGUAGE HIP) + set_source_files_properties(${FLEXFLOW_SRC} PROPERTIES LANGUAGE HIP) + + if(BUILD_SHARED_LIBS) + add_library(flexflow SHARED ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC}) + else() + add_library(flexflow STATIC ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC}) + endif() - if(BUILD_SHARED_LIBS) - cuda_add_library(flexflow SHARED ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC} OPTIONS ${CUDA_GENCODE}) + list(APPEND CMAKE_PREFIX_PATH ${ROCM_PATH}/hip ${ROCM_PATH}) + + find_package(hip REQUIRED) + + if (FF_GPU_BACKEND STREQUAL "hip_cuda") + # The targets defined by the hip cmake config only target amd devices. + # For targeting nvidia devices, we'll make our own interface target, + # hip_device_nvidia, that includes the rocm and hip headers. + add_library(hip_device_nvidia INTERFACE) + + if (NOT FF_CUDA_ARCH STREQUAL "") + target_compile_options(hip_device_nvidia INTERFACE -arch=compute_${FF_CUDA_ARCH}) + endif() + + target_include_directories(hip_device_nvidia SYSTEM INTERFACE ${HIP_INCLUDE_DIRS} ${ROCM_PATH}/include) + target_include_directories(hip_device_nvidia INTERFACE ${HIP_INCLUDE_DIRS} ${ROCM_PATH}/include) + + add_compile_definitions(FF_USE_HIP_CUDA) + + # Linking cuda: + # We do not explicitly link cuda. hipcc when targeting nvidia will + # use nvcc under the hood. nvcc when used for linking will handle + # linking cuda dependencies + target_link_libraries(flexflow hip_device_nvidia) + elseif(FF_GPU_BACKEND STREQUAL "hip_rocm") + find_package(hipblas REQUIRED) + find_package(miopen REQUIRED) + if(FF_USE_NCCL) + find_package(rccl REQUIRED) + endif() + # find_package(rocrand REQUIRED) + find_library(HIP_RAND_LIBRARY hiprand REQUIRED) + + add_compile_definitions(FF_USE_HIP_ROCM) + + if (FF_HIP_ARCH STREQUAL "") + message(FATAL_ERROR "FF_HIP_ARCH is undefined") + endif() + set_property(TARGET flexflow PROPERTY HIP_ARCHITECTURES "${HIP_ARCH_LIST}") + + message(STATUS "FF_GPU_BACKEND: ${FF_GPU_BACKEND}") + message(STATUS "FF_HIP_ARCH: ${FF_HIP_ARCH}") + message(STATUS "HIP_ARCH_LIST: ${HIP_ARCH_LIST}") + get_property(CHECK_HIP_ARCHS TARGET flexflow PROPERTY HIP_ARCHITECTURES) + message(STATUS "CHECK_HIP_ARCHS: ${CHECK_HIP_ARCHS}") + message(STATUS "HIP_CLANG_PATH: ${HIP_CLANG_PATH}") + + # The hip cmake config module defines three targets, + # hip::amdhip64, hip::host, and hip::device. + # + # hip::host and hip::device are interface targets. hip::amdhip64 is an + # imported target for libamdhip. + # + # You do not directly link to hip::amdhip64. hip::host links to hip::amdhip64 + # and hip::device links to hip::host. Link to hip::host to just use hip without + # compiling any GPU code. Link to hip::device to compile the GPU device code. + # + # Docs (outdated): + # https://rocmdocs.amd.com/en/latest/Installation_Guide/Using-CMake-with-AMD-ROCm.html + target_link_libraries(flexflow hip::device roc::hipblas MIOpen ${HIP_RAND_LIBRARY}) + if(FF_USE_NCCL) + target_link_libraries(flexflow rccl) + endif() + endif() else() - cuda_add_library(flexflow STATIC ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC} OPTIONS ${CUDA_GENCODE}) + message(FATAL_ERROR "Unsupported FF_GPU_BACKEND for cmake: ${FF_GPU_BACKEND}") endif() -elseif(FF_GPU_BACKEND STREQUAL "hip_cuda" OR FF_GPU_BACKEND STREQUAL "hip_rocm") - file(GLOB_RECURSE FLEXFLOW_GPU_SRC - LIST_DIRECTORIES False - ${FLEXFLOW_ROOT}/src/*.cpp) - if(BUILD_SHARED_LIBS) - add_library(flexflow SHARED ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC}) - else() - add_library(flexflow STATIC ${FLEXFLOW_GPU_SRC} ${FLEXFLOW_SRC}) + if(FF_USE_NCCL AND (FF_GPU_BACKEND STREQUAL "hip_cuda" OR FF_GPU_BACKEND STREQUAL "cuda")) + add_dependencies(flexflow ${NCCL_NAME}) endif() list(APPEND CMAKE_PREFIX_PATH ${ROCM_PATH}/hip ${ROCM_PATH}) @@ -413,146 +467,195 @@ else() target_link_libraries(flexflow ${LEGION_LIBRARY} ${FLEXFLOW_EXT_LIBRARIES} nlohmann_json::nlohmann_json mpark_variant optional) endif() -#library api version, bump from time to time -set(SOVERSION 1) - -set_target_properties(flexflow PROPERTIES POSITION_INDEPENDENT_CODE ON) -set_target_properties(flexflow PROPERTIES OUTPUT_NAME "flexflow${INSTALL_SUFFIX}") -set_target_properties(flexflow PROPERTIES SOVERSION ${SOVERSION}) -if (CMAKE_SYSTEM_NAME STREQUAL "Linux") - set_target_properties(flexflow PROPERTIES BUILD_RPATH "\$ORIGIN") - set_target_properties(flexflow PROPERTIES INSTALL_RPATH "\$ORIGIN") -elseif (CMAKE_SYSTEM_NAME STREQUAL "Darwin") - set_target_properties(flexflow PROPERTIES BUILD_RPATH "@loader_path") - set_target_properties(flexflow PROPERTIES INSTALL_RPATH "@loader_path") -endif() + #library api version, bump from time to time + set(SOVERSION 1) -# python related -if (FF_USE_PYTHON) - # create flexflow_cffi_header.py - add_custom_command(TARGET flexflow - PRE_BUILD - COMMAND ${FLEXFLOW_ROOT}/python/flexflow_cffi_build.py --ffhome-dir ${FLEXFLOW_ROOT} --output-dir ${FLEXFLOW_ROOT}/python/flexflow/core - WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR} - COMMENT "Creating flexflow_cffi_header.py..." - ) - # generate the Legion Python bindings library - add_custom_command(TARGET flexflow - POST_BUILD - COMMAND ${PYTHON_EXECUTABLE} ${CMAKE_CURRENT_SOURCE_DIR}/deps/legion/bindings/python/setup.py build --cmake-build-dir ${Legion_BINARY_DIR}/runtime --prefix ${Legion_BINARY_DIR} --build-lib=${Legion_BINARY_DIR}/bindings/python ${Legion_PYTHON_EXTRA_INSTALL_ARGS} - WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR}/deps/legion/bindings/python - ) - # create flexflow_python interpreter. When building from pip, we install the FF_HOME/python/flexflow_python script instead. - if (NOT FF_BUILD_FROM_PYPI) + set_target_properties(flexflow PROPERTIES POSITION_INDEPENDENT_CODE ON) + set_target_properties(flexflow PROPERTIES OUTPUT_NAME "flexflow${INSTALL_SUFFIX}") + set_target_properties(flexflow PROPERTIES SOVERSION ${SOVERSION}) + if (CMAKE_SYSTEM_NAME STREQUAL "Linux") + set_target_properties(flexflow PROPERTIES BUILD_RPATH "\$ORIGIN") + set_target_properties(flexflow PROPERTIES INSTALL_RPATH "\$ORIGIN") + elseif (CMAKE_SYSTEM_NAME STREQUAL "Darwin") + set_target_properties(flexflow PROPERTIES BUILD_RPATH "@loader_path") + set_target_properties(flexflow PROPERTIES INSTALL_RPATH "@loader_path") + endif() + + # python related + if (FF_USE_PYTHON) + find_package(Python COMPONENTS Interpreter Development) + # create flexflow_cffi_header.py add_custom_command(TARGET flexflow PRE_BUILD - COMMAND ${PYTHON_EXECUTABLE} ${FLEXFLOW_ROOT}/python/flexflow_python_build.py --build-dir ${CMAKE_BINARY_DIR} + COMMAND ${FLEXFLOW_ROOT}/python/flexflow_cffi_build.py --ffhome-dir ${FLEXFLOW_ROOT} --output-dir ${FLEXFLOW_ROOT}/python/flexflow/core WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR} - COMMENT "Creating flexflow_python interpreter..." + COMMENT "Creating flexflow_cffi_header.py..." ) - install(PROGRAMS ${CMAKE_BINARY_DIR}/flexflow_python DESTINATION "bin") + if (NOT FF_BUILD_FROM_PYPI) + # generate the Legion Python bindings library. When building from pip, we need to do this post-install to prevent Legion from overwriting the path to the Legion shared library + add_custom_command(TARGET flexflow + POST_BUILD + COMMAND ${Python_EXECUTABLE} ${CMAKE_CURRENT_SOURCE_DIR}/deps/legion/bindings/python/setup.py build --cmake-build-dir ${Legion_BINARY_DIR}/runtime --prefix ${Legion_BINARY_DIR} --build-lib=${Legion_BINARY_DIR}/bindings/python ${Legion_PYTHON_EXTRA_INSTALL_ARGS} + WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR}/deps/legion/bindings/python + ) + # create flexflow_python interpreter. When building from pip, we install the FF_HOME/python/flexflow_python script instead. + add_custom_command(TARGET flexflow + PRE_BUILD + COMMAND ${Python_EXECUTABLE} ${FLEXFLOW_ROOT}/python/flexflow_python_build.py --build-dir ${CMAKE_BINARY_DIR} + WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR} + COMMENT "Creating flexflow_python interpreter..." + ) + install(PROGRAMS ${CMAKE_BINARY_DIR}/flexflow_python DESTINATION "bin") + endif() + endif() + + if (INFERENCE_TESTS) + target_link_libraries(flexflow "${TORCH_LIBRARIES}") + set_property(TARGET flexflow PROPERTY CXX_STANDARD 14) endif() -endif() -# build binary -option(FF_BUILD_RESNET "build resnet example" OFF) -option(FF_BUILD_RESNEXT "build resnext example" OFF) -option(FF_BUILD_ALEXNET "build alexnet example" OFF) -option(FF_BUILD_DLRM "build DLRM example" OFF) -option(FF_BUILD_XDL "build XDL example" OFF) -option(FF_BUILD_INCEPTION "build inception example" OFF) -option(FF_BUILD_CANDLE_UNO "build candle uno example" OFF) -option(FF_BUILD_TRANSFORMER "build transformer example" OFF) -option(FF_BUILD_MOE "build mixture of experts example" OFF) -option(FF_BUILD_MLP_UNIFY "build mlp unify example" OFF) -option(FF_BUILD_SPLIT_TEST "build split test example" OFF) -option(FF_BUILD_SPLIT_TEST_2 "build split test 2 example" OFF) -option(FF_BUILD_ALL_EXAMPLES "build all examples. Overrides others" OFF) -option(FF_BUILD_UNIT_TESTS "build non-operator unit tests" OFF) -option(FF_BUILD_SUBSTITUTION_TOOL "build substitution conversion tool" OFF) -option(FF_BUILD_VISUALIZATION_TOOL "build substitution visualization tool" OFF) - -if(FF_BUILD_UNIT_TESTS) - set(BUILD_GMOCK OFF) - add_subdirectory(deps/googletest) - enable_testing() - add_subdirectory(tests/unit) -endif() + # build binary + option(FF_BUILD_TOKENIZER "build tokenizer=cpp for LLM serving" OFF) + option(FF_BUILD_RESNET "build resnet example" OFF) + option(FF_BUILD_RESNEXT "build resnext example" OFF) + option(FF_BUILD_ALEXNET "build alexnet example" OFF) + option(FF_BUILD_DLRM "build DLRM example" OFF) + option(FF_BUILD_XDL "build XDL example" OFF) + option(FF_BUILD_INCEPTION "build inception example" OFF) + option(FF_BUILD_CANDLE_UNO "build candle uno example" OFF) + option(FF_BUILD_TRANSFORMER "build transformer example" OFF) + option(FF_BUILD_MOE "build mixture of experts example" OFF) + option(FF_BUILD_MLP_UNIFY "build mlp unify example" OFF) + option(FF_BUILD_SPLIT_TEST "build split test example" OFF) + option(FF_BUILD_SPLIT_TEST_2 "build split test 2 example" OFF) + option(FF_BUILD_MLP_UNIFY_INFERENCE "build mlp unify inference example" OFF) + option(FF_BUILD_ALL_INFERENCE_EXAMPLES "build all inference examples. Overrides others" OFF) + option(FF_BUILD_ALL_EXAMPLES "build all examples. Overrides others" OFF) + option(FF_BUILD_UNIT_TESTS "build non-operator unit tests" OFF) + option(FF_BUILD_SUBSTITUTION_TOOL "build substitution conversion tool" OFF) + option(FF_BUILD_VISUALIZATION_TOOL "build substitution visualization tool" OFF) + + if(FF_BUILD_UNIT_TESTS) + set(BUILD_GMOCK OFF) + add_subdirectory(deps/googletest) + enable_testing() + add_subdirectory(tests/unit) + endif() -if(FF_BUILD_SUBSTITUTION_TOOL) - add_subdirectory(tools/protobuf_to_json) -endif() + if(FF_BUILD_SUBSTITUTION_TOOL) + add_subdirectory(tools/protobuf_to_json) + endif() -if(FF_BUILD_VISUALIZATION_TOOL) - add_subdirectory(tools/substitutions_to_dot) -endif() + if(FF_BUILD_VISUALIZATION_TOOL) + add_subdirectory(tools/substitutions_to_dot) + endif() -if(FF_BUILD_RESNET OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/ResNet) -endif() + if(FF_BUILD_ALL_INFERENCE_EXAMPLES OR FF_BUILD_TOKENIZER) + # Ensure Rust is installed + execute_process(COMMAND rustc --version + RESULT_VARIABLE RUST_COMMAND_RESULT + OUTPUT_VARIABLE RUSTC_OUTPUT + ERROR_QUIET) + if(NOT RUST_COMMAND_RESULT EQUAL 0) + message(FATAL_ERROR "Rust is not installed on the system. Please install it by running: 'curl https://sh.rustup.rs -sSf | sh -s -- -y' and following the instructions on the screen.") + endif() + # Ensure Cargo is installed + execute_process(COMMAND cargo --version + RESULT_VARIABLE CARGO_RESULT + OUTPUT_QUIET ERROR_QUIET) + if(NOT CARGO_RESULT EQUAL 0) + message(FATAL_ERROR "Rust is installed, but cargo is not. Please install it by running: 'curl https://sh.rustup.rs -sSf | sh -s -- -y' and following the instructions on the screen.") + endif() + add_subdirectory(deps/tokenizers-cpp tokenizers EXCLUDE_FROM_ALL) + target_include_directories(flexflow PUBLIC deps/tokenizers-cpp/include) + target_link_libraries(flexflow tokenizers_cpp) + endif() + if(FF_BUILD_RESNET OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/ResNet) + endif() -if(FF_BUILD_RESNEXT OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/resnext50) -endif() + if(FF_BUILD_RESNEXT OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/resnext50) + endif() -if(FF_BUILD_ALEXNET OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/AlexNet) -endif() + if(FF_BUILD_ALEXNET OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/AlexNet) + endif() -if(FF_BUILD_MLP_UNIFY OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/MLP_Unify) -endif() + if(FF_BUILD_MLP_UNIFY OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/MLP_Unify) + endif() -if(FF_BUILD_SPLIT_TEST OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/split_test) -endif() + if(FF_BUILD_SPLIT_TEST OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/split_test) + endif() -if(FF_BUILD_SPLIT_TEST_2 OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/split_test_2) -endif() + if(FF_BUILD_SPLIT_TEST_2 OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/split_test_2) + endif() -if(FF_BUILD_INCEPTION OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/InceptionV3) -endif() + if(FF_BUILD_INCEPTION OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/InceptionV3) + endif() -#TODO: Once functional add to BUILD_ALL_EXAMPLES -if(FF_BUILD_CANDLE_UNO OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/candle_uno) -endif() + #TODO: Once functional add to BUILD_ALL_EXAMPLES + if(FF_BUILD_CANDLE_UNO OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/candle_uno) + endif() -if(FF_BUILD_DLRM OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/DLRM) + if(FF_BUILD_DLRM OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/DLRM) - #add_executable(generate_dlrm_hetero_strategy src/runtime/dlrm_strategy_hetero.cc) - #target_include_directories(generate_dlrm_hetero_strategy PUBLIC ${FLEXFLOW_INCLUDE_DIRS}) + #add_executable(generate_dlrm_hetero_strategy src/runtime/dlrm_strategy_hetero.cc) + #target_include_directories(generate_dlrm_hetero_strategy PUBLIC ${FLEXFLOW_INCLUDE_DIRS}) - #add_executable(generate_dlrm_strategy src/runtime/dlrm_strategy.cc) - #target_include_directories(generate_dlrm_strategy PUBLIC ${FLEXFLOW_INCLUDE_DIRS}) -endif() + #add_executable(generate_dlrm_strategy src/runtime/dlrm_strategy.cc) + #target_include_directories(generate_dlrm_strategy PUBLIC ${FLEXFLOW_INCLUDE_DIRS}) + endif() -if(FF_BUILD_XDL OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/XDL) -endif() + if(FF_BUILD_XDL OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/XDL) + endif() -if(FF_BUILD_TRANSFORMER OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/Transformer) -endif() + if(FF_BUILD_TRANSFORMER OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/Transformer) + endif() -if(FF_BUILD_MOE OR FF_BUILD_ALL_EXAMPLES) - add_subdirectory(examples/cpp/mixture_of_experts) -endif() + if(FF_BUILD_MOE OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(examples/cpp/mixture_of_experts) + endif() -# installation -set(INCLUDE_DEST "include") -set(LIB_DEST "lib") -install(FILES ${FLEXFLOW_HDR} DESTINATION ${INCLUDE_DEST}) -install(TARGETS flexflow DESTINATION ${LIB_DEST}) -# install python -if (FF_USE_PYTHON) - execute_process(COMMAND python -c "from distutils import sysconfig; print(sysconfig.get_python_lib(plat_specific=False,standard_lib=False))" OUTPUT_VARIABLE PY_DEST OUTPUT_STRIP_TRAILING_WHITESPACE) - install( - DIRECTORY ${FLEXFLOW_ROOT}/python/flexflow/ - DESTINATION ${PY_DEST}/flexflow - FILES_MATCHING - PATTERN "*.py") -endif() + if(FF_BUILD_ALL_INFERENCE_EXAMPLES OR FF_BUILD_ALL_EXAMPLES) + add_subdirectory(inference/spec_infer) + add_subdirectory(inference/incr_decoding) + endif() + + + # installation + set(INCLUDE_DEST "include") + set(LIB_DEST "lib") + install(FILES ${FLEXFLOW_HDR} DESTINATION ${INCLUDE_DEST}) + install(TARGETS flexflow DESTINATION ${LIB_DEST}) + # install python + if (FF_USE_PYTHON) + find_package(Python COMPONENTS Interpreter Development) + execute_process(COMMAND ${Python_EXECUTABLE} -c "import site, os; print([pkg for func in (site.getsitepackages(), site.getusersitepackages()) for pkg in ([func] if isinstance(func, str) else func) if os.access(pkg, os.W_OK)][0])" OUTPUT_VARIABLE PY_DEST OUTPUT_STRIP_TRAILING_WHITESPACE) + if (NOT FF_BUILD_FROM_PYPI) + install( + DIRECTORY ${FLEXFLOW_ROOT}/python/flexflow/ + DESTINATION ${PY_DEST}/flexflow + FILES_MATCHING + PATTERN "*.py") + else() + # pip automatically installs all *.py files in the python/flexflow folder, but because flexflow_cffi_header.py is generated at build time, we have to install it manually. + install( + PROGRAMS ${FLEXFLOW_ROOT}/python/flexflow/core/flexflow_cffi_header.py + DESTINATION ${PY_DEST}/flexflow/core + ) + # Use setup.py script to re-install the Python bindings library with the right library paths. + # Need to put the instructions in a subfolder because of issue below: + # https://stackoverflow.com/questions/43875499/do-post-processing-after-make-install-in-cmake + add_subdirectory(cmake/pip_install) + endif() + endif() +endif() # if(NOT BUILD_LEGION_ONLY) diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md index ff77cb4612..c3c0b5173f 100644 --- a/CONTRIBUTING.md +++ b/CONTRIBUTING.md @@ -119,7 +119,26 @@ After adding the DNN layers, the next step before compiling the model for traini #### Model compilation -TODO +Model compilation consists of the following steps: + +1. We initialize an operator for each layer in the model, via the function `create_operators_from_layers()`. Layers work with `Tensor` input/weights/outputs, and are created directly by the user when writing a FlexFlow program. Operators work with `ParallelTensor` objects and they are responsible for running computations by launching kernels on GPUs. +2. Launch the graph optimize task (`GRAPH_OPTIMIZE_TASK_ID`), implemented by`PCG::Graph::graph_optimize_task`, which returns `PCG::GraphOptimalViewSerialized` + 1. call `deserialize_graph_optimal_view(...)` to get `PCG::Graph *best_graph` and `std::unordered_map optimal_views` from deserialized `PCG::GraphOptimalViewSerialized` + 2. `convert_graph_to_operators()` + 3. print the dot of the best graph obtained + 4. map inputs to parallel tensor and weights to parallel tensor? -> strange for loop to understand better +3. Init performance metrics via the `FFModel::update_metrics_task` +4. Perform inplace optimizations (if enabled) +5. Loop through the operators to do the following (to be understood better): + 1. `parameters.push_back(op->weights[i]);` for each weight in each operator + 2. `op->map_output_tensors(*this);` + 3. `((ParallelOp *)op)->create_input_partition(*this);` if the operator is a parallel operator +6. Check correctness of the operator's input and output tensors' settings +7. Perform fusion optimizations, if enabled +8. Print all operators and their input and output regions +9. Create the tensor for the label +10. Initialize the optimizer +11. In training mode, if NCCL is enabled, initialize all the communicators and other objects ## Continuous Integration @@ -131,8 +150,9 @@ We currently implement CI testing using Github Workflows. Each workflow is defin 4. `gpu-ci.yml`: runs all the tests that require a GPU to run. 5. `gpu-ci-daemon.yml`: an helper workflow that turns on/off the GPU instance used by the test above 6. `multinode-test.yml`: runs the same GPU tests from the `gpu-ci.yml` workflow, but using multiple (simulated) nodes. The test currently simulates two nodes, each with 2 GPUs. To run FlexFlow on multiple nodes, we compile Legion with GASNET enabled, and choose MPI as the GASNET conduit. Compared to the single-node version, this test is much more time-consuming (about 4h instead 40mins at the time of writing), so we only run the test on the FlexFlow `master` branch every other day. -7. `pip-install.yml`: checks the build & installation of FlexFlow using `pip` -8. `shell-check.yml`: runs shellcheck on all bash scripts in the repo +7. `pip-deploy.yml`: builds the `flexflow` pip package and publishes it on `TestPyPI` (if the repository environment variable `DEPLOY_TO_TEST_PYPI` is unset, or set to `false`) or `PyPI` (if `DEPLOY_TO_TEST_PYPI` is set to `true`). When deploying to `PyPI`, a new git tag (with the pip package version) will also be created, and associated with the commit hash that triggered the workflow. The `pip-deploy.yml` can only be launched manually via workflow dispatch. More on the pip packaging in the [section below](#pip-packages). +8. `pip-install.yml`: checks the build & installation of FlexFlow using `pip` +9. `shell-check.yml`: runs shellcheck on all bash scripts in the repo We also have three placeholder workflows: `build-skip.yml`, `docker-build-skip.yml`, `gpu-ci-skip` and `pip-install-skip.yml`. These always pass and are used only in the case of skipped workflows whose status is required to merge a PR; we implement the "hack" officially recommended by Github ([see here](https://docs.github.com/en/repositories/configuring-branches-and-merges-in-your-repository/defining-the-mergeability-of-pull-requests/troubleshooting-required-status-checks#handling-skipped-but-required-checks)). @@ -208,12 +228,82 @@ Finally, we define the jobs that will run when the workflow is triggered. Each j Each step in a job will be executed sequentially, and if it fails, the remaining steps will be cancelled and the job will be marked as `failed`. Each step is specified by either reusing a Github action or running a shell command (or a script file). For instance, in the example above, the first step uses the Github Action `actions/checkout@v3` to check out the repository, the second step uses the `Jimver/cuda-toolkit@v0.2.11` action to install CUDA, whereas the third step runs a bash script stored in the repo at the path `.github/workflows/helpers/install_dependencies.sh`. +## Pip packages +This section illustrates how we support the automatic deployment of FlexFlow to the `PyPI` and `Test PyPI` repositories. Publishing FlexFlow on `PyPI` makes it possible for users to install FlexFlow on their machine by simply running: + +```bash +pip install flexflow +``` + +To install from `Test PyPI`, on the other hand, one can use: + +```bash +pip install flexflow --extra-index-url https://test.pypi.org/simple/ +``` + +The installation process currently takes approximately the same time as installing from source by running the command `pip install .` from `FF_HOME` after having cloned the repo. However, installing directly from PyPI allows the user to automatically install the Python dependencies, and removes the step of having to manually clone the repo with all its submodules. + +Below, we discuss some important properties of PyPI. + +### Packaging +When building a `pip` package from a repository, we can decide what files from the repository will be included in the package, and which ones will be left out. To do that, we write a [MANIFEST.in](https://github.com/flexflow/FlexFlow/blob/master/MANIFEST.in) file, according to the syntax from the [official instructions](https://packaging.python.org/en/latest/guides/using-manifest-in/). In particular, we manually include the submodules (which would otherwise be left out by default), we remove the `.git` folders, which are not needed to build FlexFlow, as well as the `triton` folder, whose contents are not currently in use. Finally, we request that the version.txt file, whose role is described in the section below, is included in the package distribution. Because this file is generated at build time, it would be left out by default if we didn't manually include it. + +### Source VS Wheel distribution +PyPI allows you to upload a source distribution, together with one (or more) binary distributions of your package. A `pip` package's pre-compiled binary is called a Wheel (formerly, Egg). The advantage of publishing Wheel distributions instead of just the source code is that the installation of the package will be much faster for the user, who will just need to download the binary, and extract its files in the proper locations (all of this is handled automatically when running `pip install `). If only the source code is available, on the other hand, `pip install ` will first need to compile the package, and then install it. + +`PyPI` allows you to upload multiple Wheels to support different Python versions (the Wheel compatible with version of Python installed on the user's machine is downloaded automatically when the user runs `pip install `), but unfortunately does not yet support uploading a Wheel for each CUDA version, and automatically downloading the relevant one depending on the user's machine configuration. Instead, one needs to upload a Wheel with a distinct name for each CUDA version, and the user will need to specify the name manually at dowload time. For this reason, to keep things simple, we only publish the source distribution at this moment, and plan to upload Wheels that are specific to each Python version and CUDA version at a later time. + +### Versioning + +PyPI imposes some strict versioning requirements. Among other things, versions need to follow a specific format, and once a given version of a package is published, it can never be replaced. In addition, even if the publisher deletes a version, nobody can never upload a source distribution / Wheel with that same version number again. Finally, when multiple versions of the same package are published, the one with the highest version number (not the one that was uploaded last) will be installed by default. + +When publishing a package on PyPI, the version attached to the upload is determined by the `setup.py` script. You can check which version string will be used by running `python setup.py --version`. + +The simplest way to version a `pip`package is to hard-code the version number in the `setup.py` script, and committing a change to the repository every time the `pip` package is to be updated. This approach, however, is incompatible with having a script or workflow to automatically update the `pip` package. + +If we intend to deploy the latest code to PyPI automatically, we need a way to automatically assign a properly-formatted version string to the code we want to upload. Further, we need to ensure that the assigned version is (1) different from any version (of the same package) already published on PyPI and (2) larger than any previous version. Finally, a trickier requirement is that: (3) at any point in time, the `setup.py` script included in a given version of our package should output a version string that exactly matches the version string recorded in the metadata attached to the package's version at publication time. More about this below. + +We follow a simple approach to automatically version the latest code: use the publication's date to generate the version string. For example, on Aug 12, 2023, we can use version string 23.08.12. Assuming that we publish at most one version per day, and that we always publish from the same timezone, we will be able to meet requirements (1) and (2). An additional enhancement to be able to support the update of the package more than once per day (which may be needed in development phase, or if a mistake is made), instead of using the day of the month (12 for August 12, 2023) for the sub-sub-version, we use an index that starts at 0 every month, and is incremented by +1 every time we upload a new version of the package within the same calendar month. So if on Aug 12, 2023 we are updating the package for the first time in the month, we will use version string 23.08.0; if later the same day (or any time before Sept 1, 2023) we wish to upload a new version, we will use string 23.08.1, and so forth. + +Having illustrated the general versioning policy, we will need to implement it carefully in `setup.py` to ensure that we meet requirement (3). You can take a look at the `compute_version()` function to see how this is done in practice. The key realization is that we cannot simply compute today's date (using any of the Python libraries that let us do that) and transform it into a string, nor simply get from PyPI the latest available version of our package, and, if it was published on the same calendar month, increment the sub-subversion by +1 to generate the version string of the new upload. We can best illustrate why we cannot do that with an example: +- Today, Aug 12, 2023, we wish to upload a new version to PyPI. As we said above, the version string is computed by `setup.py`. A naive way to do so in `setup.py` would be to compute the date using `date.today()`, and transform the year and month into digit form to generate the version (23) and sub-version (08) parts of the version string. We could then check on PyPI what was the latest published version of the package as of today, and if we found that it was, say, 23.08.05, we would use 5+1=6 as the sub-sub-version for the new upload (so the final version string would be 23.08.06). +- Over the next few days, we upload 3 more versions +- A week later, on Aug 18, 2023, a user trying to install our package, runs `pip install `. To determine which version it should install, the `pip install` script downloads the most recent X versions of `` on the user's machine, and, for each version, re-computes the version string by running `python setup.py --version`. When the script attempts to recompute the version string on the package 23.08.06 (which we uploaded on Aug 12, 2023), it will reconstruct the version string by replaying the same instructions that were run on Aug. 12, and obtain a different version string, as follows. Using the current date, the user will obtain: version=23, sub-version=08, which match the metadata. Checking the latest version of the package available on PyPI, the script finds version 23.08.09 (there were three more submissions since Aug 12). This will translate to sub-sub-version=9+1=10. Noticing that the version included in the Aug 12 package's metadata (23.08.06) does not match the recomputed version (23.08.10), the script will generate unexpected and undesired behavior. + +To prevent accidentally breaking requirement (3) as illustrated in the scenario from the example above, we employ a simple hack: when computing our package's version string for the first time by running `setup.py`, we save the string to a file, `python/flexflow/version.txt`, which is added to the `.gitignore` and as such, never committed to the repo. As long as the `version.txt` exists, any subsequent run of `setup.py` will simply read the file, and output the same version string, no matter on which day and/or how many new versions of the package have been uploaded to PyPI since then. When packaging our code to upload it on PyPI, we ensure to delete the `version.txt` file, compute the version string, and then include the `version.txt` in the source distribution that we upload to `PyPI`. In this way, when the user attempts to install the package, `pip install` will download the most recent available versions, run `setup.py` from each distribution, and for each distribution, `setup.py` will always output the correct version string, because it will just read the string recorded in that distribution's `version.txt`. + +### Test PyPI +Given all the complexities and restrictions of PyPI, Test PyPI was created as a "copy" of PyPI to be used for testing and for being able to make mistakes without affecting the user, or forever losing the opportunity to use a given package name and/or version. We take advantage of Test PyPI as follows. If we intend to deploy to PyPI, we can first deploy to Test PyPI, check the results, fix any issue, and only later deploy to PyPI. All our `pip` related scripts in the repo have been designed to support both Test PyPI and PyPI. In order to let `setup.py` know that it should package a distribution for Test PyPI, one can simply export the following environment variable: + +```bash +export DEPLOY_TO_TEST_PYPI=true +``` + +Conversely, to upload to PyPI, one can either leave `DEPLOY_TO_TEST_PYPI` unset, or export + +```bash +export DEPLOY_TO_TEST_PYPI=false +``` + +WARNING!!! More likely than not, the latest version of the `flexflow` package on Test PyPI and PyPI will be out of sync. This is to be expected, because one may need to upload a few drafts on Test PyPI to detect and correct some bugs, before publishing the definitive version on PyPI. Having different latest versions on the two repositories should not cause any issue. However, after uploading to Test PyPI and before uploading to PyPI (or viceversa), **it is EXTREMELY IMPORTANT** to delete the `python/flexflow/version.txt` file. + +An easy way to avoid forgetting this, is to only deploy on Test PyPI/PyPI using the `pip-deploy.yml`, which is designed to only upload to one of the two repositories at a given time. + +### Build vs install dependencies + +FlexFlow requires some other Python packages in order to run. In addition, even building FlexFlow requires some packages, and you cannot run `setup.py` without those build requirements. There is a way for us to specify these _install_ and _build_ requirements in such a way that `pip` will detect if they are missing, and install them. We record the build requirements in the `pyproject.toml` file, whereas we specify the installation requirements by passing a list with each package's name to the `install_requires` key of the `setup()` function in `setup.py`. The installation requirements are automatically read from the `requirements.txt` file. + + ## Contributing to FlexFlow We want to make contributing to this project as easy and transparent as possible. ### Formatting We use `clang-format` to format our C++ code. If you make changes to the code and the Clang format CI test is failing, you can lint your code by running: `./scripts/format.sh` from the main folder of this repo. +### Documenting the code +We follow the Python Docstring conventions for documenting the Python code. We document the C++ code using comments in any of the conventioned supported by Doxygen [see here](https://doxygen.nl/manual/docblocks.html). + + ### Pull Requests We actively welcome your pull requests. diff --git a/FlexFlow.mk b/FlexFlow.mk index b434045893..14f32a7639 100644 --- a/FlexFlow.mk +++ b/FlexFlow.mk @@ -59,7 +59,8 @@ GEN_SRC += $(shell find $(FF_HOME)/src/loss_functions/ -name '*.cc')\ $(shell find $(FF_HOME)/src/runtime/ -name '*.cc')\ $(shell find $(FF_HOME)/src/utils/dot/ -name '*.cc')\ $(shell find $(FF_HOME)/src/dataloader/ -name '*.cc')\ - $(shell find $(FF_HOME)/src/c/ -name '*.cc') + $(shell find $(FF_HOME)/src/c/ -name '*.cc')\ + $(shell find $(FF_HOME)/inference/ -name 'file_loader.cc') GEN_SRC := $(filter-out $(FF_HOME)/src/runtime/cpp_driver.cc, $(GEN_SRC)) FF_CUDA_SRC += $(shell find $(FF_HOME)/src/loss_functions/ -name '*.cu')\ @@ -94,15 +95,17 @@ ifneq ($(strip $(FF_USE_PYTHON)), 1) endif -INC_FLAGS += -I${FF_HOME}/include -I${FF_HOME}/deps/optional/include -I${FF_HOME}/deps/variant/include -I${FF_HOME}/deps/json/include +INC_FLAGS += -I${FF_HOME}/include -I${FF_HOME}/inference -I${FF_HOME}/deps/optional/include -I${FF_HOME}/deps/variant/include -I${FF_HOME}/deps/json/include -I${FF_HOME}/deps/tokenizers-cpp/include -I${FF_HOME}/deps/tokenizers-cpp/sentencepiece/src CC_FLAGS += -DMAX_TENSOR_DIM=$(MAX_DIM) -DLEGION_MAX_RETURN_SIZE=32768 NVCC_FLAGS += -DMAX_TENSOR_DIM=$(MAX_DIM) -DLEGION_MAX_RETURN_SIZE=32768 HIPCC_FLAGS += -DMAX_TENSOR_DIM=$(MAX_DIM) -DLEGION_MAX_RETURN_SIZE=32768 GASNET_FLAGS += # For Point and Rect typedefs -CC_FLAGS += -std=c++11 -NVCC_FLAGS += -std=c++11 -HIPCC_FLAGS += -std=c++11 +CC_FLAGS += -std=c++17 +NVCC_FLAGS += -std=c++17 +HIPCC_FLAGS += -std=c++17 + +LD_FLAGS += -L$(FF_HOME)/deps/tokenizers-cpp/example/tokenizers -ltokenizers_cpp -ltokenizers_c -L$(FF_HOME)/deps/tokenizers-cpp/example/tokenizers/sentencepiece/src -lsentencepiece ifeq ($(strip $(FF_USE_NCCL)), 1) INC_FLAGS += -I$(MPI_HOME)/include -I$(NCCL_HOME)/include diff --git a/INSTALL.md b/INSTALL.md index d2e3c1d2f6..1734319540 100644 --- a/INSTALL.md +++ b/INSTALL.md @@ -1,4 +1,4 @@ -# Installing FlexFlow +# Building from source To build and install FlexFlow, follow the instructions below. ## 1. Download the source code @@ -30,7 +30,7 @@ If you are planning to build the Python interface, you will need to install seve The `conda` environment can be created and activated as: ``` -conda env create -f conda/environment.yml +conda env create -f conda/flexflow.yml conda activate flexflow ``` @@ -42,7 +42,7 @@ You can configure a FlexFlow build by running the `config/config.linux` file in 3. `FF_CUDA_ARCH` is used to set the architecture of targeted GPUs, for example, the value can be 60 if the GPU architecture is Pascal. To build for more than one architecture, pass a list of comma separated values (e.g. `FF_CUDA_ARCH=70,75`). To compile FlexFlow for all GPU architectures that are detected on the machine, pass `FF_CUDA_ARCH=autodetect` (this is the default value, so you can also leave `FF_CUDA_ARCH` unset. If you want to build for all GPU architectures compatible with FlexFlow, pass `FF_CUDA_ARCH=all`. **If your machine does not have any GPU, you have to set FF_CUDA_ARCH to at least one valid architecture code (or `all`)**, since the compiler won't be able to detect the architecture(s) automatically. 4. `FF_USE_PYTHON` controls whether to build the FlexFlow Python interface. 5. `FF_USE_NCCL` controls whether to build FlexFlow with NCCL support. By default, it is set to ON. -6. `FF_LEGION_NETWORKS` is used to enable distributed run of FlexFlow. If you want to run FlexFlow on multiple nodes, follow instructions in [MULTI-NODE.md](MULTI-NODE.md) and set the corresponding parameters as follows: +6. `FF_LEGION_NETWORKS` is used to enable distributed run of FlexFlow. If you want to run FlexFlow on multiple nodes, follow instructions in the [Multinode tutorial](https://flexflow.readthedocs.io/en/latest/multinode.html) and set the corresponding parameters as follows: * To build FlexFlow with GASNet, set `FF_LEGION_NETWORKS=gasnet` and `FF_GASNET_CONDUIT` as a specific conduit (e.g. `ibv`, `mpi`, `udp`, `ucx`) in `config/config.linux` when configuring the FlexFlow build. Set `FF_UCX_URL` when you want to customize the URL to download UCX. * To build FlexFlow with native UCX, set `FF_LEGION_NETWORKS=ucx` in `config/config.linux` when configuring the FlexFlow build. Set `FF_UCX_URL` when you want to customize the URL to download UCX. 8. `FF_BUILD_EXAMPLES` controls whether to build all C++ example programs. @@ -85,10 +85,11 @@ export FF_HOME=/path/to/FlexFlow ### Run FlexFlow Python examples The Python examples are in the [examples/python](https://github.com/flexflow/FlexFlow/tree/master/examples/python). The native, Keras integration and PyTorch integration examples are listed in `native`, `keras` and `pytorch` respectively. -To run the Python examples, you have two options: you can use the `flexflow_python` interpreter, available in the `build` folder, or you can use the native Python interpreter. If you choose to use the native Python interpreter, you should either install FlexFlow, or, if you prefer to build without installing, export the following flags: +To run the Python examples, you have two options: you can use the `flexflow_python` interpreter, available in the `build` folder, or you can use the native Python interpreter. If you choose to use the native Python interpreter, you should either install FlexFlow, or, if you prefer to build without installing, export the required environment flags by running the following command (edit the path if your build folder is not named `build`): -* `export PYTHONPATH="${FF_HOME}/python:${FF_HOME}/build/deps/legion/bindings/python:${PYTHONPATH}"` -* `export LD_LIBRARY_PATH="${FF_HOME}/build:${FF_HOME}/build/deps/legion/lib:${LD_LIBRARY_PATH}"` +``` +source ./build/set_python_envs.sh +``` **We recommend that you run the** `mnist_mlp` **test under** `native` **using the following cmd to check if FlexFlow has been installed correctly:** @@ -96,7 +97,7 @@ To run the Python examples, you have two options: you can use the `flexflow_pyth cd "$FF_HOME" ./python/flexflow_python examples/python/native/mnist_mlp.py -ll:py 1 -ll:gpu 1 -ll:fsize -ll:zsize ``` -A script to run all the Python examples is available at `tests/multi_gpu_tests.sh` +A script to run all the Python examples is available at `tests/training_tests.sh` ### Run FlexFlow C++ examples diff --git a/MANIFEST.in b/MANIFEST.in new file mode 100644 index 0000000000..64f20c1890 --- /dev/null +++ b/MANIFEST.in @@ -0,0 +1,4 @@ +graft deps +recursive-exclude . .git +prune triton +include python/flexflow/version.txt diff --git a/MULTI-NODE.md b/MULTI-NODE.md index 78edba62c0..28f2eab8ed 100644 --- a/MULTI-NODE.md +++ b/MULTI-NODE.md @@ -1,29 +1,90 @@ -# Running FlexFlow On Multiple Nodes -To build, install, and run FlexFlow on multiple nodes, follow the instructions below. We take AWS as an example to present the instructions. +# Running FlexFlow on Multiple Nodes + +To build, install, and run FlexFlow on multiple nodes, follow the instructions below. We will use AWS as an example to present the instructions. ## 1. Spin up instances -Spin up multiple instances with GPU support. We choose p3.2xlarge with [Deep Learning AMI GPU PyTorch 1.13.1 (Ubuntu 20.04)](https://aws.amazon.com/releasenotes/aws-deep-learning-ami-neuron-pytorch-1-13-ubuntu-20-04/) to simplify the procedure. -Place the instances in a [placement group](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/placement-groups.html) which utilizes `cluster` as strategy to achieve the low-latency network performance. +Spin up multiple instances with GPU support. For AWS, we recommend using p3.2xlarge with [Deep Learning AMI GPU PyTorch 1.13.1 (Ubuntu 20.04)](https://aws.amazon.com/releasenotes/aws-deep-learning-ami-neuron-pytorch-1-13-ubuntu-20-04/) to simplify the procedure. + +Place the instances in a [placement group](https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/placement-groups.html) that utilizes the `cluster` strategy to achieve low-latency network performance. -To enable the communications between instances, you should attach the same security group to all instances and add an inbound rule in the security group to enable all the incoming traffic from the same security group. An example inbound rule is as follows: +To enable communication between instances, attach the same security group to all instances and add an inbound rule in the security group to allow all incoming traffic from the same security group. An example inbound rule is as follows: ``` Type: Custom TCP Port range: 1 - 65535 Source: Custom (use the security group ID) ``` -## 2. Configure and build FlexFlow -Follow steps 1 to 5 in [INSTALL.md](INSTALL.md) to download the source code, install system dependencies, install the Python dependencies, configure the FlexFlow build, and build FlexFlow **on each instance**. You can skip the step 2 (Install system dependencies) if you have spun up instances with Deep Learning AMI which comes preconfigured with CUDA. Otherwise, you need to install system dependencies on each instance. +You can also use your own GPU cluster, as long as all machines are interconnected with a low-latency network. + +## 2. Configure and build UCX + +Find the latest source code release for UCX at https://github.com/openucx/ucx/releases. As of writing this documentation, the latest UCX was 1.15.0 at https://github.com/openucx/ucx/releases/download/v1.15.0/ucx-1.15.0.tar.gz. Extract it and switch to the directory with UCX source code, and run: + +``` +CUDA_PATH=/usr/local/cuda +PREFIX=$PWD/install +./contrib/configure-release-mt --prefix="$PREFIX" --without-go --enable-mt --with-cuda="$CUDA_PATH" +make -j install +echo "$PREFIX" +``` + +Replace `{{ CUDA_PATH }}` with the path of your CUDA installation. If you don't know the path, try `which nvcc`. Take note of the path of UCX installation, echoed as part of the last command. + +## 3. Configure and build FlexFlow + +Follow steps 1 to 5 in [INSTALL.md](INSTALL.md#1-download-the-source-code) to download the source code, install system dependencies, install the Python dependencies, configure the FlexFlow build, and build FlexFlow **on each instance at the same path**. Or you can use NFS to mount home directory of each instance so that only a single build is necessary. + +You can skip step 2 (Install system dependencies) if you have spun up instances with Deep Learning AMI, which comes preconfigured with CUDA. Otherwise, you need to install system dependencies on each instance. + +For step 4 (Configuring the FlexFlow build), here are the parameters that need to be configured: +* Set `FF_LEGION_NETWORKS=ucx` +* Set `UCX_DIR` to the UCX installation path mentioned in [Configure and build UCX](#2-configure-and-build-ucx) + +Other configuration options are optional. + +## 4. Configure MPI + +MPI is an easy way to launch FlexFlow across all instances simultaneously and set up communication between them. + +To use MPI, enable non-interactive `ssh` logins between instances. This can be done by referring to the [Open MPI documentation](https://docs.open-mpi.org/en/v5.0.0rc9/running-apps/ssh.html). Here are the detailed steps: + +1. Choose one of the nodes as the main instance and create a public/private key pair on the instance. This will be the instance from which you launch MPI commands. Run the following command: + +``` +ssh-keygen -t ed25519 +``` + +This will create a public key at `~/.ssh/id_ed25519.pub` and a private key at `~/.ssh/id_ed25519`. -## 3. Test FlexFlow -Follow the step 6 in [INSTALL.md](INSTALL.md) to set environment variables. +2. Append the contents of the **public key** to `~/.ssh/authorized_keys` on all machines (if the file does not exist, create one). Execute the following command on **all instances**: -A script to run a Python example on multiple nodes is available at `scripts/mnist_mlp_run.sh` and you can run the script using [`mpirun`](https://www.open-mpi.org/doc/current/man1/mpirun.1.php) or [`srun`](https://slurm.schedmd.com/srun.html). For example, to run the script with MPI, you need to first enable non-interactive `ssh` logins (refer to [Open MPI doc](https://docs.open-mpi.org/en/v5.0.0rc9/running-apps/ssh.html)) between instances and then run: ``` -mpirun --host :,: -np ./scripts/mnist_mlp_run.sh +mkdir -p ~/.ssh +echo '' >> ~/.ssh/authorized_keys ``` -If you encounter some errors like `WARNING: Open MPI accepted a TCP connection from what appears to be a -another Open MPI process but cannot find a corresponding process -entry for that peer.`, add the parameter `--mca btl_tcp_if_include` in the `mpirun` command. (refer to [stack overflow question](https://stackoverflow.com/questions/15072563/running-mpi-on-two-hosts)) \ No newline at end of file +Replace `` with the public key from `~/.ssh/id_ed25519.pub` on the main instance. It should be a single line containing a string like: +``` +ssh-ed25519 AAAAC3NzaC1lZDI1NTE5AAAAIOy5NKYdE8Cwgid59rx6xMqyj9vLaWuXIwy/BSRiK4su instance +``` + +3. Create a hostfile at `~/hostfile`, with one line for each instance (add more lines if you have more instances): + +``` + slots= + slots= +``` + +`` and `` refer to the number of slots available for each instance, respectively. Set it to one if you have a GPU on each instance. + +4. SSH into each host and make sure you can log into them. It may ask you to verify the public key. Make sure to trust the public key so that it doesn't ask you again. + +5. Test MPI by running `mpirun -N 1 --hostfile ~/hostfile hostname`. It should display the hostname of all your nodes. If you encounter any errors like `WARNING: Open MPI accepted a TCP connection from what appears to be another Open MPI process but cannot find a corresponding process entry for that peer.`, add the parameter `--mca btl_tcp_if_include` in the `mpirun` command (refer to [this Stack Overflow question](https://stackoverflow.com/questions/15072563/running-mpi-on-two-hosts)). + +## 5. Test FlexFlow + +Follow step 6 in the [Build from source guide](https://flexflow.readthedocs.io/en/latest/installation.html) to set the environment variables. + +A script to run a Python example on multiple nodes is available at `scripts/mnist_mlp_run.sh`. Run the script to test FlexFlow on mnist mlp training. You can adjust the script to run any other program. Make sure to change the `FLEXFLOW_DIR` and `UCX_DIR` variables in it to appropriate paths. + diff --git a/README.md b/README.md index 9ad900fb3c..95790a90e5 100644 --- a/README.md +++ b/README.md @@ -1,72 +1,54 @@ -# FlexFlow -![build](https://github.com/flexflow/flexflow/workflows/build/badge.svg?branch=master) ![gpu tests](https://github.com/flexflow/flexflow/workflows/gpu-ci/badge.svg?branch=master) ![multinode gpu tests](https://github.com/flexflow/flexflow/workflows/multinode-test/badge.svg?branch=master) ![docker](https://github.com/flexflow/flexflow/workflows/docker-build/badge.svg?branch=master) ![pip](https://github.com/flexflow/flexflow/workflows/pip-install/badge.svg?branch=master) ![shell-check](https://github.com/flexflow/flexflow/workflows/Shell%20Check/badge.svg?branch=master) ![clang-format](https://github.com/flexflow/flexflow/workflows/clang-format%20Check/badge.svg?branch=master) [![Documentation Status](https://readthedocs.org/projects/flexflow/badge/?version=latest)](https://flexflow.readthedocs.io/en/latest/?badge=latest) +# FlexFlow: Low-Latency, High-Performance Training and Serving +![build](https://github.com/flexflow/flexflow/workflows/build/badge.svg?branch=inference) ![gpu tests](https://github.com/flexflow/flexflow/workflows/gpu-ci/badge.svg?branch=inference) ![multinode gpu tests](https://github.com/flexflow/flexflow/workflows/multinode-test/badge.svg?branch=master) ![docker](https://github.com/flexflow/flexflow/workflows/docker-build/badge.svg?branch=inference) ![pip](https://github.com/flexflow/flexflow/workflows/pip-install/badge.svg?branch=inference) ![shell-check](https://github.com/flexflow/flexflow/workflows/Shell%20Check/badge.svg?branch=inference) ![clang-format](https://github.com/flexflow/flexflow/workflows/clang-format%20Check/badge.svg?branch=inference) [![Documentation Status](https://readthedocs.org/projects/flexflow/badge/?version=latest)](https://flexflow.readthedocs.io/en/latest/?badge=latest) -FlexFlow is a deep learning framework that accelerates distributed DNN training by automatically searching for efficient parallelization strategies. FlexFlow provides a drop-in replacement for PyTorch and TensorFlow Keras. Running existing PyTorch and Keras programs in FlexFlow only requires [a few lines of changes to the program](https://flexflow.ai/keras). -## Install FlexFlow -To install FlexFlow from source code, please read the [instructions](https://flexflow.readthedocs.io/en/latest/installation.html). If you would like to quickly try FlexFlow, we also provide pre-built Docker packages for several versions of CUDA and for the `hip_rocm` backend, together with [Dockerfiles](./docker) if you wish to build the containers manually. More info on the Docker images can be found [here](./docker/README.md). You can also use `conda` to install the FlexFlow Python package (coming soon). +--- -## PyTorch Support -Users can also use FlexFlow to optimize the parallelization performance of existing PyTorch models in two steps. First, a PyTorch model can be exported to the FlexFlow model format using `flexflow.torch.fx.torch_to_flexflow`. -```python -import torch -import flexflow.torch.fx as fx +## News 🔥: -model = MyPyTorchModule() -fx.torch_to_flexflow(model, "mymodel.ff") -``` +* [09/02/2023] Adding AMD GPU support, released Docker images for ROCM 5.3->5.6 +* [08/16/2023] Adding Starcoder model support +* [08/14/2023] Released Docker image for different CUDA versions + +## Install FlexFlow -Second, a FlexFlow program can directly import a previously saved PyTorch model and [autotune](https://www.usenix.org/conference/osdi22/presentation/unger) the parallelization performance for a given parallel machine. -```python -from flexflow.pytorch.model import PyTorchModel +### Requirements +* OS: Linux +* GPU backend: Hip-ROCm or CUDA + * CUDA version: 10.2 – 12.0 + * NVIDIA compute capability: 6.0 or higher +* Python: 3.6 or higher +* Package dependencies: [see here](https://github.com/flexflow/FlexFlow/blob/inference/requirements.txt) -def top_level_task(): - torch_model = PyTorchModel("mymodel.ff") - output_tensor = torch_model.apply(ffmodel, input_tensor) - ## Model compilation - ffmodel.compile(optimizer='adam', loss='sparse_categorical_crossentropy', metrics=['accuracy']) - ## Model training - (x_train, y_train) = cifar10.load_data() - ffmodel.fit(x_train, y_train, epochs=30) +### Install with pip +You can install FlexFlow using pip: + +```bash +pip install flexflow ``` -**More FlexFlow PyTorch examples**: see the [pytorch examples folder](https://github.com/flexflow/FlexFlow/tree/master/examples/python/pytorch). +### Try it in Docker +If you run into any issue during the install, or if you would like to use the C++ API without needing to install from source, you can also use our pre-built Docker package for different CUDA versions and the `hip_rocm` backend. To download and run our pre-built Docker container: + +```bash +docker run --gpus all -it --rm --shm-size=8g ghcr.io/flexflow/flexflow-cuda-12.0:latest +``` -## TensorFlow Keras and ONNX Support -FlexFlow prioritizes PyTorch compatibility, but also includes frontends for [Tensorflow Keras](./docs/source/keras.rst) and [ONNX](./docs/source/onnx.rst) models. +To download a Docker container for a backend other than CUDA v12.0, you can replace the `cuda-12.0` suffix with any of the following backends: `cuda-11.1`, `cuda-11.6`, `cuda-11.7`, `cuda-11.8`, `cuda-12.0`, `cuda-12.1`, `cuda-12.1`, and `hip_rocm-5.3`, `hip_rocm-5.4`, `hip_rocm-5.5`, `hip_rocm-5.6`. More info on the Docker images, with instructions to build a new image from source, or run with additional configurations, can be found [here](./docker/README.md). -## C++ Interface -For users that prefer to program in C/C++. FlexFlow supports a C++ program inference that is equivalent to its Python APIs. +### Build from source -**More FlexFlow C++ examples**: see the [C++ examples folder](https://github.com/flexflow/FlexFlow/tree/master/examples/cpp). +You can install FlexFlow Serve from source code by building the inference branch of FlexFlow. Please follow these [instructions](https://flexflow.readthedocs.io/en/latest/installation.html). -## Command-Line Flags -In addition to setting runtime configurations in a FlexFlow Python/C++ program, the FlexFlow runtime also accepts command-line arguments for various runtime parameters: +## Get Started! -FlexFlow training flags: -* `-e` or `--epochs`: number of total epochs to run (default: 1) -* `-b` or `--batch-size`: global batch size in each iteration (default: 64) -* `-p` or `--print-freq`: print frequency (default: 10) -* `-d` or `--dataset`: path to the training dataset. If not set, synthetic data is used to conduct training. +To get started, check out the quickstart guides below for the FlexFlow training and serving libraries. -Legion runtime flags: -* `-ll:gpu`: number of GPU processors to use on each node (default: 0) -* `-ll:fsize`: size of device memory on each GPU (in MB) -* `-ll:zsize`: size of zero-copy memory (pinned DRAM with direct GPU access) on each node (in MB). This is used for prefecthing training images from disk. -* `-ll:cpu`: number of data loading workers (default: 4) -* `-ll:util`: number of utility threads to create per process (default: 1) -* `-ll:bgwork`: number of background worker threads to create per process (default: 1) +* [FlexFlow Train](./TRAIN.md) +* [FlexFlow Serve](./SERVE.md) -Performance auto-tuning flags: -* `--search-budget` or `--budget`: the number of iterations for the MCMC search (default: 0) -* `--search-alpha` or `--alpha`: a hyper-parameter for the search procedure (default: 0.05) -* `--export-strategy` or `--export`: path to export the best discovered strategy (default: None) -* `--import-strategy` or `--import`: path to import a previous saved strategy (default: None) -* `--enable-parameter-parallel`: allow FlexFlow to explore parameter parallelism for performance auto-tuning. (By default FlexFlow only considers data and model parallelism.) -* `--enable-attribute-parallel`: allow FlexFlow to explore attribute parallelism for performance auto-tuning. (By default FlexFlow only considers data and model parallelism.) -For performance tuning related flags: see [performance autotuning](https://flexflow.ai/search). ## Contributing @@ -75,6 +57,14 @@ Please let us know if you encounter any bugs or have any suggestions by [submitt We welcome all contributions to FlexFlow from bug fixes to new features and extensions. ## Citations + +**FlexFlow Serve:** + +* Xupeng Miao, Gabriele Oliaro, Zhihao Zhang, Xinhao Cheng, Zeyu Wang, Rae Ying Yee Wong, Alan Zhu, Lijie Yang, Xiaoxiang Shi, Chunan Shi, Zhuoming Chen, Daiyaan Arfeen, Reyna Abhyankar, Zhihao Jia. [SpecInfer: Accelerating Generative Large Language Model Serving with Speculative Inference and Token Tree Verification](https://arxiv.org/abs/2305.09781). In ArXiV, May 2023. + + +**FlexFlow Train:** + * Colin Unger, Zhihao Jia, Wei Wu, Sina Lin, Mandeep Baines, Carlos Efrain Quintero Narvaez, Vinay Ramakrishnaiah, Nirmal Prajapati, Pat McCormick, Jamaludin Mohd-Yusof, Xi Luo, Dheevatsa Mudigere, Jongsoo Park, Misha Smelyanskiy, and Alex Aiken. [Unity: Accelerating DNN Training Through Joint Optimization of Algebraic Transformations and Parallelization](https://www.usenix.org/conference/osdi22/presentation/unger). In Proceedings of the Symposium on Operating Systems Design and Implementation (OSDI), July 2022. * Zhihao Jia, Matei Zaharia, and Alex Aiken. [Beyond Data and Model Parallelism for Deep Neural Networks](https://cs.stanford.edu/~zhihao/papers/sysml19a.pdf). In Proceedings of the 2nd Conference on Machine Learning and Systems (MLSys), April 2019. @@ -86,3 +76,4 @@ FlexFlow is developed and maintained by teams at CMU, Facebook, Los Alamos Natio ## License FlexFlow uses Apache License 2.0. + diff --git a/SERVE.md b/SERVE.md new file mode 100644 index 0000000000..9472d50a62 --- /dev/null +++ b/SERVE.md @@ -0,0 +1,275 @@ +# FlexFlow Serve: Low-Latency, High-Performance LLM Serving + + +## What is FlexFlow Serve + +The high computational and memory requirements of generative large language +models (LLMs) make it challenging to serve them quickly and cheaply. +FlexFlow Serve is an open-source compiler and distributed system for +__low latency__, __high performance__ LLM serving. FlexFlow Serve outperforms +existing systems by 1.3-2.0x for single-node, multi-GPU inference and by +1.4-2.4x for multi-node, multi-GPU inference. + +

+Performance comparison +
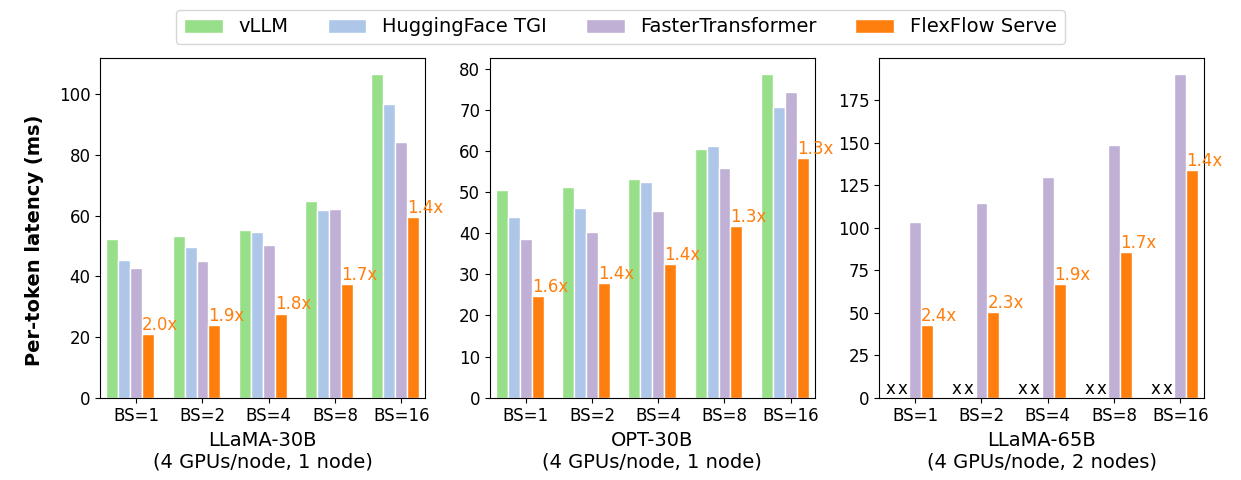
+ + +## Quickstart +The following example shows how to deploy an LLM using FlexFlow Serve and accelerate its serving using [speculative inference](#speculative-inference). First, we import `flexflow.serve` and initialize the FlexFlow Serve runtime. Note that `memory_per_gpu` and `zero_copy_memory_per_node` specify the size of device memory on each GPU (in MB) and zero-copy memory on each node (in MB), respectively. +We need to make sure the aggregated GPU memory and zero-copy memory are **both** sufficient to store LLM parameters in non-offloading serving. FlexFlow Serve combines tensor and pipeline model parallelism for LLM serving. +```python +import flexflow.serve as ff + +ff.init( + num_gpus=4, + memory_per_gpu=14000, + zero_copy_memory_per_node=30000, + tensor_parallelism_degree=4, + pipeline_parallelism_degree=1 + ) +``` +Second, we specify the LLM to serve and the SSM(s) used to accelerate LLM serving. The list of supported LLMs and SSMs is available at [supported models](#supported-llms-and-ssms). +```python +# Specify the LLM +llm = ff.LLM("meta-llama/Llama-2-7b-hf") + +# Specify a list of SSMs (just one in this case) +ssms=[] +ssm = ff.SSM("JackFram/llama-68m") +ssms.append(ssm) +``` +Next, we declare the generation configuration and compile both the LLM and SSMs. Note that all SSMs should run in the **beam search** mode, and the LLM should run in the **tree verification** mode to verify the speculated tokens from SSMs. +```python +# Create the sampling configs +generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 +) + +# Compile the SSMs for inference and load the weights into memory +for ssm in ssms: + ssm.compile(generation_config) + +# Compile the LLM for inference and load the weights into memory +llm.compile(generation_config, ssms=ssms) +``` +Finally, we call `llm.generate` to generate the output, which is organized as a list of `GenerationResult`, which include the output tokens and text. +```python +result = llm.generate("Here are some travel tips for Tokyo:\n") +``` + +### Incremental decoding + +
+Expand here +
+ +```python + +import flexflow.serve as ff + +# Initialize the FlexFlow runtime. ff.init() takes a dictionary (as a positional argument) or named key-value parameters +ff.init( + num_gpus=4, + memory_per_gpu=14000, + zero_copy_memory_per_node=30000, + tensor_parallelism_degree=4, + pipeline_parallelism_degree=1 + ) + +# Create the FlexFlow LLM +llm = ff.LLM("meta-llama/Llama-2-7b-hf") + +# Create the sampling configs +generation_config = ff.GenerationConfig( + do_sample=True, temperature=0.9, topp=0.8, topk=1 +) + +# Compile the LLM for inference and load the weights into memory +llm.compile(generation_config) + +# Generation begins! +result = llm.generate("Here are some travel tips for Tokyo:\n") + +``` + +
+ +### C++ interface +If you'd like to use the C++ interface (mostly used for development and benchmarking purposes), you should install from source, and follow the instructions below. + +
+Expand here +
+ +#### Downloading models + +Before running FlexFlow Serve, you should manually download the LLM and SSM(s) model of interest using the [inference/utils/download_hf_model.py](https://github.com/flexflow/FlexFlow/blob/inference/inference/utils/download_hf_model.py) script (see example below). By default, the script will download all of a model's assets (weights, configs, tokenizer files, etc...) into the cache folder `~/.cache/flexflow`. If you would like to use a different folder, you can request that via the parameter `--cache-folder`. + +```bash +python3 ./inference/utils/download_hf_model.py ... +``` + +#### Running the C++ examples +A C++ example is available at [this folder](../inference/spec_infer/). After building FlexFlow Serve, the executable will be available at `/build_dir/inference/spec_infer/spec_infer`. You can use the following command-line arguments to run FlexFlow Serve: + +* `-ll:gpu`: number of GPU processors to use on each node for serving an LLM (default: 0) +* `-ll:fsize`: size of device memory on each GPU in MB +* `-ll:zsize`: size of zero-copy memory (pinned DRAM with direct GPU access) in MB. FlexFlow Serve keeps a replica of the LLM parameters on zero-copy memory, and therefore requires that the zero-copy memory is sufficient for storing the LLM parameters. +* `-llm-model`: the LLM model ID from HuggingFace (e.g. "meta-llama/Llama-2-7b-hf") +* `-ssm-model`: the SSM model ID from HuggingFace (e.g. "JackFram/llama-160m"). You can use multiple `-ssm-model`s in the command line to launch multiple SSMs. +* `-cache-folder`: the folder +* `-data-parallelism-degree`, `-tensor-parallelism-degree` and `-pipeline-parallelism-degree`: parallelization degrees in the data, tensor, and pipeline dimensions. Their product must equal the number of GPUs available on the machine. When any of the three parallelism degree arguments is omitted, a default value of 1 will be used. +* `-prompt`: (optional) path to the prompt file. FlexFlow Serve expects a json format file for prompts. In addition, users can also use the following API for registering requests: +* `-output-file`: (optional) filepath to use to save the output of the model, together with the generation latency + +For example, you can use the following command line to serve a LLaMA-7B or LLaMA-13B model on 4 GPUs and use two collectively boost-tuned LLaMA-68M models for speculative inference. + +```bash +./inference/spec_infer/spec_infer -ll:gpu 4 -ll:cpu 4 -ll:fsize 14000 -ll:zsize 30000 -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-68m -prompt /path/to/prompt.json -tensor-parallelism-degree 4 --fusion +``` +
+ +## Speculative Inference +A key technique that enables FlexFlow Serve to accelerate LLM serving is speculative +inference, which combines various collectively boost-tuned small speculative +models (SSMs) to jointly predict the LLM’s outputs; the predictions are organized as a +token tree, whose nodes each represent a candidate token sequence. The correctness +of all candidate token sequences represented by a token tree is verified against the +LLM’s output in parallel using a novel tree-based parallel decoding mechanism. +FlexFlow Serve uses an LLM as a token tree verifier instead of an incremental decoder, +which largely reduces the end-to-end inference latency and computational requirement +for serving generative LLMs while provably preserving model quality. + +

+A Speculative Inference Demo +
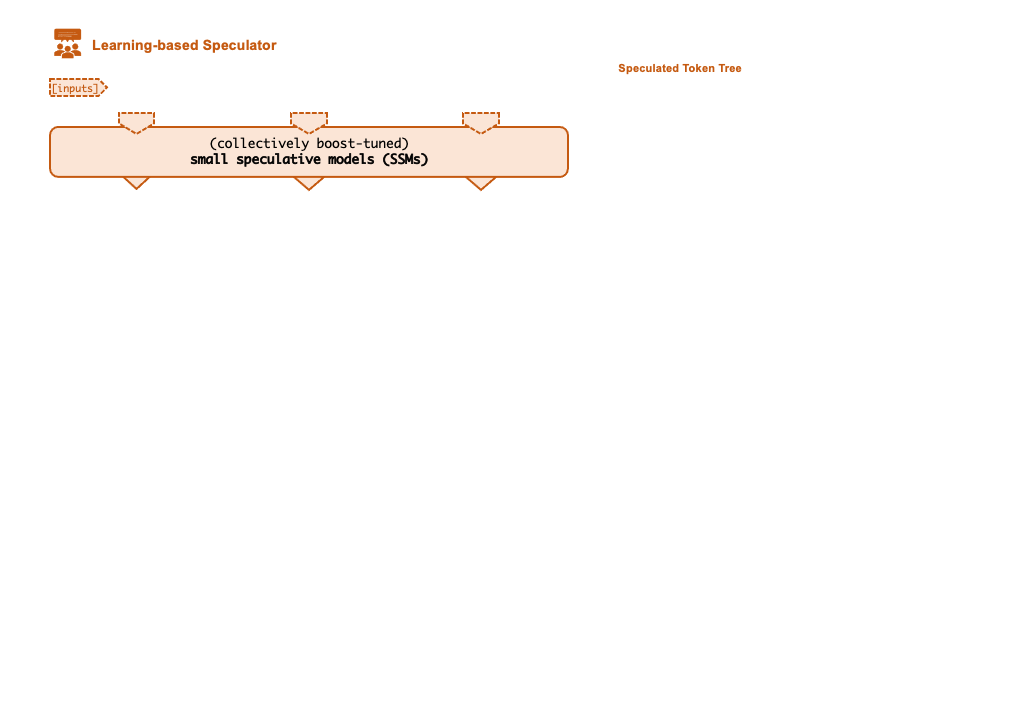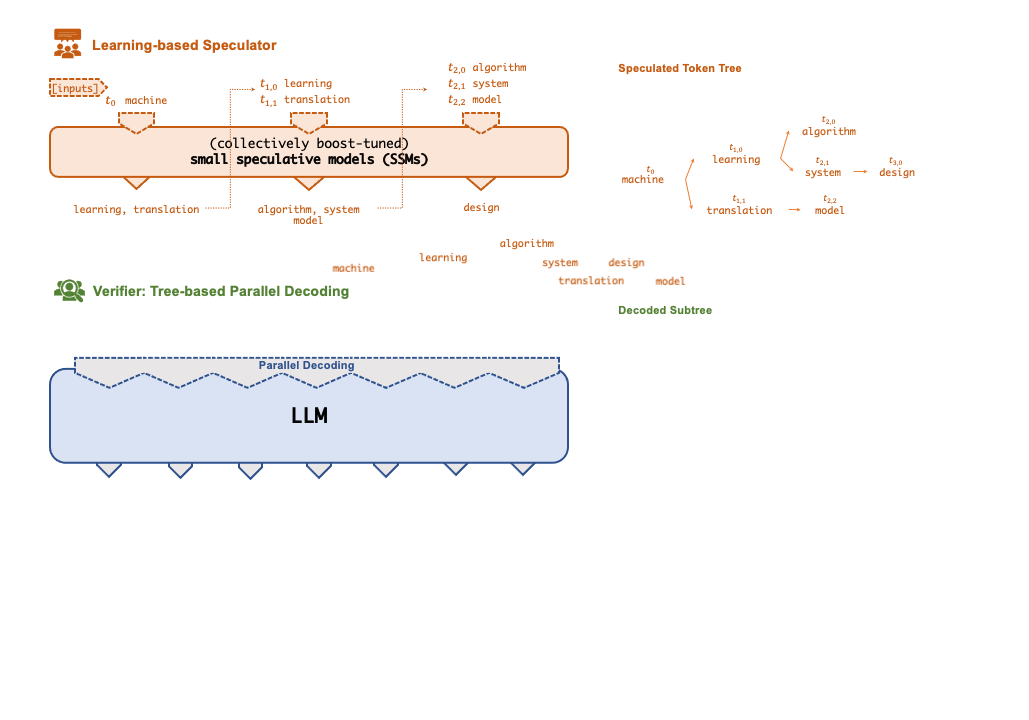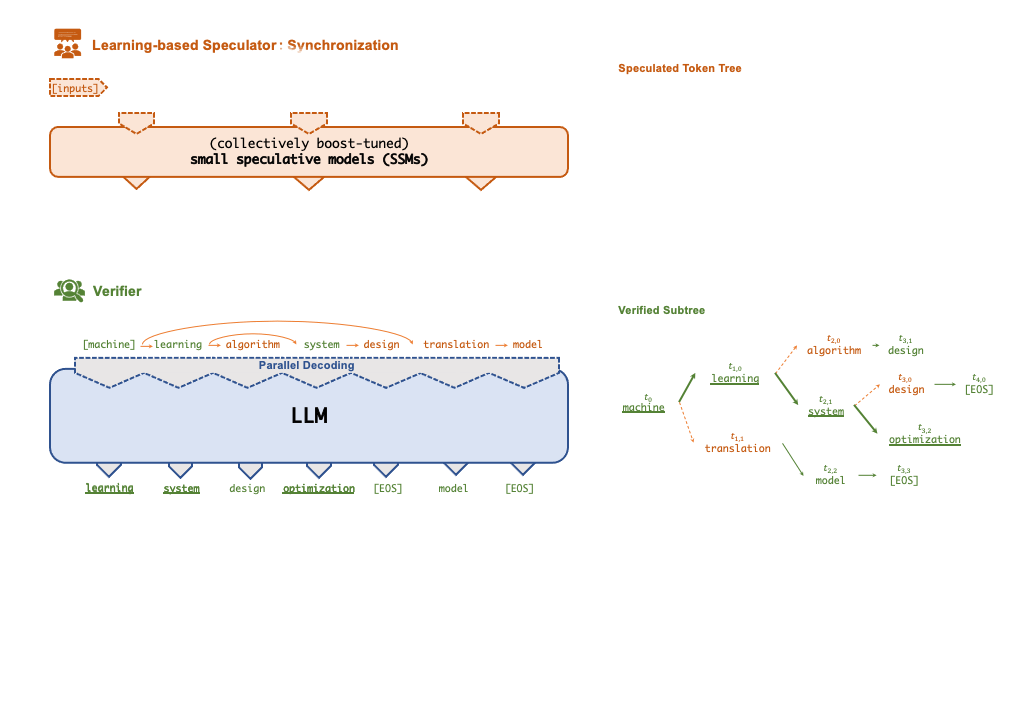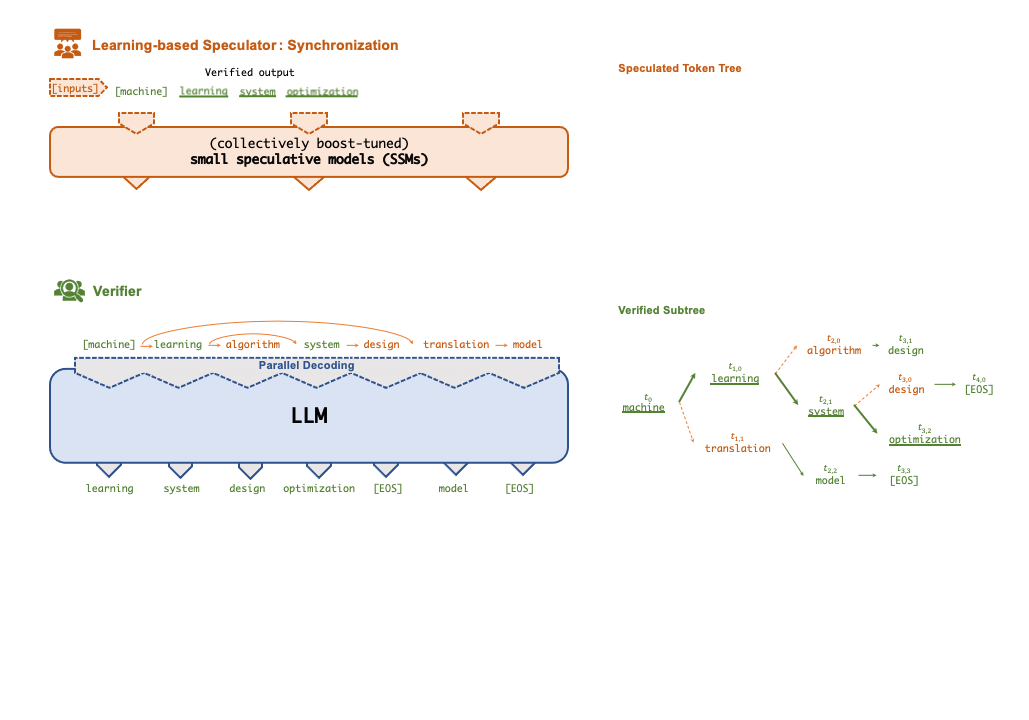
+ +### Supported LLMs and SSMs + +FlexFlow Serve currently supports all HuggingFace models with the following architectures: +* `LlamaForCausalLM` / `LLaMAForCausalLM` (e.g. LLaMA/LLaMA-2, Guanaco, Vicuna, Alpaca, ...) +* `OPTForCausalLM` (models from the OPT family) +* `RWForCausalLM` (models from the Falcon family) +* `GPTBigCodeForCausalLM` (models from the Starcoder family) + +Below is a list of models that we have explicitly tested and for which a SSM may be available: + +| Model | Model id on HuggingFace | Boost-tuned SSMs | +| :---- | :---- | :---- | +| LLaMA-7B | meta-llama/Llama-2-7b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-13B | decapoda-research/llama-13b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-30B | decapoda-research/llama-30b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-65B | decapoda-research/llama-65b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-7B | meta-llama/Llama-2-7b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-13B | meta-llama/Llama-2-13b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| LLaMA-2-70B | meta-llama/Llama-2-70b-hf | [LLaMA-68M](https://huggingface.co/JackFram/llama-68m) , [LLaMA-160M](https://huggingface.co/JackFram/llama-160m) | +| OPT-6.7B | facebook/opt-6.7b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-13B | facebook/opt-13b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-30B | facebook/opt-30b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| OPT-66B | facebook/opt-66b | [OPT-125M](https://huggingface.co/facebook/opt-125m) | +| Falcon-7B | tiiuae/falcon-7b | | +| Falcon-40B | tiiuae/falcon-40b | | +| StarCoder-15.5B | bigcode/starcoder | | + + +### CPU Offloading +FlexFlow Serve also offers offloading-based inference for running large models (e.g., llama-7B) on a single GPU. CPU offloading is a choice to save tensors in CPU memory, and only copy the tensor to GPU when doing calculation. Notice that now we selectively offload the largest weight tensors (weights tensor in Linear, Attention). Besides, since the small model occupies considerably less space, it it does not pose a bottleneck for GPU memory, the offloading will bring more runtime space and computational cost, so we only do the offloading for the large model. [TODO: update instructions] You can run the offloading example by enabling the `-offload` and `-offload-reserve-space-size` flags. + +### Quantization +FlexFlow Serve supports int4 and int8 quantization. The compressed tensors are stored on the CPU side. Once copied to the GPU, these tensors undergo decompression and conversion back to their original precision. Please find the compressed weight files in our s3 bucket, or use [this script](../inference/utils/compress_llama_weights.py) from [FlexGen](https://github.com/FMInference/FlexGen) project to do the compression manually. [TODO: update instructions for quantization]. + +### Prompt Datasets +We provide five prompt datasets for evaluating FlexFlow Serve: [Chatbot instruction prompts](https://specinfer.s3.us-east-2.amazonaws.com/prompts/chatbot.json), [ChatGPT Prompts](https://specinfer.s3.us-east-2.amazonaws.com/prompts/chatgpt.json), [WebQA](https://specinfer.s3.us-east-2.amazonaws.com/prompts/webqa.json), [Alpaca](https://specinfer.s3.us-east-2.amazonaws.com/prompts/alpaca.json), and [PIQA](https://specinfer.s3.us-east-2.amazonaws.com/prompts/piqa.json). + + + + +## Python Interface Features and Interaction Methods + +FlexFlow Serve provides a comprehensive Python interface for serving with low latency and high performance. This interface facilitates the deployment and interaction with the serving platform for a variety of applications, from chatbots and prompt templates to retrieval augmented generation and API services. + +### Chatbot with Gradio + +The Python interface allows setting up a chatbot application using Gradio, enabling interactive dialogues with users through a user-friendly web interface. + +#### Implementation Steps +1. **FlexFlow Initialization:** Configure and initialize FlexFlow Serve with the desired settings and the specific LLM. +```python +import gradio as gr +import flexflow.serve as ff + +ff.init(num_gpus=2, memory_per_gpu=14000, ...) +``` +2. **Gradio Interface Setup:** Implement a function to generate responses from user inputs and set up the Gradio Chat Interface for interaction. +```python +def generate_response(user_input): + result = llm.generate(user_input) + return result.output_text.decode('utf-8') +``` +3. **Running the Interface:** Launch the Gradio interface to interact with the LLM through a web-based chat interface. +```python +iface = gr.ChatInterface(fn=generate_response) +iface.launch() +``` +4. **Shutdown:** Properly stop the FlexFlow server after interaction is complete. + + + +### Langchain Usecases +FlexFlow Serve supports langchain usecases including dynamic prompt template handling and RAG usecases, enabling the customization of model responses based on structured input templates and Retrieval Augmented Generation. + +#### Implementation Steps +1. **FlexFlow Initialization**: Start by initializing FlexFlow Serve with the appropriate configurations. +2. **LLM Setup**: Compile and load the LLM for text generation. +3. **Prompt Template/RAG Setup**: Configure prompt templates to guide the model's responses. +4. **Response Generation**: Use the LLM with the prompt template to generate responses. + + +### Python FastAPI Entrypoint +Flexflow Serve also supports deploying and managing LLMs with FastAPI, offering a RESTful API interface for generating responses from models. + +```python +@app.on_event("startup") +async def startup_event(): + global llm + # Initialize and compile the LLM model + llm.compile( + generation_config, + # ... other params as needed + ) + llm.start_server() + +@app.post("/generate/") +async def generate(prompt_request: PromptRequest): + # ... exception handling + full_output = llm.generate([prompt_request.prompt])[0].output_text.decode('utf-8') + # ... split prompt and response text for returning results + return {"prompt": prompt_request.prompt, "response": full_output} +``` + + + + +## TODOs + +FlexFlow Serve is still under active development. We currently focus on the following tasks and strongly welcome all contributions from bug fixes to new features and extensions. + +* AMD benchmarking. We are actively working on benchmarking FlexFlow Serve on AMD GPUs and comparing it with the performance on NVIDIA GPUs. + +## Acknowledgements +This project is initiated by members from CMU, Stanford, and UCSD. We will be continuing developing and supporting FlexFlow Serve. Please cite FlexFlow Serve as: + +``` bibtex +@misc{miao2023specinfer, + title={SpecInfer: Accelerating Generative Large Language Model Serving with Speculative Inference and Token Tree Verification}, + author={Xupeng Miao and Gabriele Oliaro and Zhihao Zhang and Xinhao Cheng and Zeyu Wang and Rae Ying Yee Wong and Alan Zhu and Lijie Yang and Xiaoxiang Shi and Chunan Shi and Zhuoming Chen and Daiyaan Arfeen and Reyna Abhyankar and Zhihao Jia}, + year={2023}, + eprint={2305.09781}, + archivePrefix={arXiv}, + primaryClass={cs.CL} +} +``` + +## License +FlexFlow uses Apache License 2.0. diff --git a/TRAIN.md b/TRAIN.md new file mode 100644 index 0000000000..1595274a4c --- /dev/null +++ b/TRAIN.md @@ -0,0 +1,65 @@ +# FlexFlow Train: Distributed DNN Training with Flexible Parallelization Strategies. +FlexFlow Train is a deep learning framework that accelerates distributed DNN training by automatically searching for efficient parallelization strategies. FlexFlow Train provides a drop-in replacement for PyTorch and TensorFlow Keras. Running existing PyTorch and Keras programs in FlexFlow oTrain nly requires [a few lines of changes to the program](https://flexflow.ai/keras). + + +## PyTorch Support +Users can also use FlexFlow Train to optimize the parallelization performance of existing PyTorch models in two steps. First, a PyTorch model can be exported to the FlexFlow model format using `flexflow.torch.fx.torch_to_flexflow`. +```python +import torch +import flexflow.torch.fx as fx + +model = MyPyTorchModule() +fx.torch_to_flexflow(model, "mymodel.ff") +``` + +Second, a FlexFlow Train program can directly import a previously saved PyTorch model and [autotune](https://www.usenix.org/conference/osdi22/presentation/unger) the parallelization performance for a given parallel machine. + +```python +from flexflow.pytorch.model import PyTorchModel + +def top_level_task(): + torch_model = PyTorchModel("mymodel.ff") + output_tensor = torch_model.apply(ffmodel, input_tensor) + ## Model compilation + ffmodel.compile(optimizer='adam', loss='sparse_categorical_crossentropy', metrics=['accuracy']) + ## Model training + (x_train, y_train) = cifar10.load_data() + ffmodel.fit(x_train, y_train, epochs=30) +``` + +**More FlexFlow PyTorch examples**: see the [pytorch examples folder](https://github.com/flexflow/FlexFlow/tree/master/examples/python/pytorch). + +## TensorFlow Keras and ONNX Support +FlexFlow Train prioritizes PyTorch compatibility, but also includes frontends for [Tensorflow Keras](./docs/source/keras.rst) and [ONNX](./docs/source/onnx.rst) models. + +## C++ Interface +For users that prefer to program in C/C++. FlexFlow Train supports a C++ program inference that is equivalent to its Python APIs. + +**More FlexFlow C++ examples**: see the [C++ examples folder](https://github.com/flexflow/FlexFlow/tree/master/examples/cpp). + + +## Command-Line Flags +In addition to setting runtime configurations in a FlexFlow Train Python/C++ program, the FlexFlow Train runtime also accepts command-line arguments for various runtime parameters: + +FlexFlow training flags: +* `-e` or `--epochs`: number of total epochs to run (default: 1) +* `-b` or `--batch-size`: global batch size in each iteration (default: 64) +* `-p` or `--print-freq`: print frequency (default: 10) +* `-d` or `--dataset`: path to the training dataset. If not set, synthetic data is used to conduct training. + +Legion runtime flags: +* `-ll:gpu`: number of GPU processors to use on each node (default: 0) +* `-ll:fsize`: size of device memory on each GPU (in MB) +* `-ll:zsize`: size of zero-copy memory (pinned DRAM with direct GPU access) on each node (in MB). This is used for prefecthing training images from disk. +* `-ll:cpu`: number of data loading workers (default: 4) +* `-ll:util`: number of utility threads to create per process (default: 1) +* `-ll:bgwork`: number of background worker threads to create per process (default: 1) + +Performance auto-tuning flags: +* `--search-budget` or `--budget`: the number of iterations for the MCMC search (default: 0) +* `--search-alpha` or `--alpha`: a hyper-parameter for the search procedure (default: 0.05) +* `--export-strategy` or `--export`: path to export the best discovered strategy (default: None) +* `--import-strategy` or `--import`: path to import a previous saved strategy (default: None) +* `--enable-parameter-parallel`: allow FlexFlow Train to explore parameter parallelism for performance auto-tuning. (By default FlexFlow Train only considers data and model parallelism.) +* `--enable-attribute-parallel`: allow FlexFlow Train to explore attribute parallelism for performance auto-tuning. (By default FlexFlow Train only considers data and model parallelism.) +For performance tuning related flags: see [performance autotuning](https://flexflow.ai/search). diff --git a/bootcamp_demo/ff_alexnet_cifar10.py b/bootcamp_demo/ff_alexnet_cifar10.py deleted file mode 100644 index cb0b0e99ad..0000000000 --- a/bootcamp_demo/ff_alexnet_cifar10.py +++ /dev/null @@ -1,70 +0,0 @@ -#./flexflow_python $FF_HOME/bootcamp_demo/ff_alexnet_cifar10.py -ll:py 1 -ll:gpu 1 -ll:fsize 2048 -ll:zsize 12192 - -from flexflow.core import * -from flexflow.keras.datasets import cifar10 -from flexflow.torch.model import PyTorchModel -from PIL import Image - -def top_level_task(): - ffconfig = FFConfig() - ffconfig.parse_args() - print("Python API batchSize(%d) workersPerNodes(%d) numNodes(%d)" %(ffconfig.get_batch_size(), ffconfig.get_workers_per_node(), ffconfig.get_num_nodes())) - ffmodel = FFModel(ffconfig) - - dims_input = [ffconfig.get_batch_size(), 3, 229, 229] - input_tensor = ffmodel.create_tensor(dims_input, DataType.DT_FLOAT) - - torch_model = PyTorchModel("alexnet.ff") - output_tensors = torch_model.apply(ffmodel, [input_tensor]) - - ffoptimizer = SGDOptimizer(ffmodel, 0.01) - ffmodel.set_sgd_optimizer(ffoptimizer) - ffmodel.compile(loss_type=LossType.LOSS_SPARSE_CATEGORICAL_CROSSENTROPY, metrics=[MetricsType.METRICS_ACCURACY, MetricsType.METRICS_SPARSE_CATEGORICAL_CROSSENTROPY]) - label_tensor = ffmodel.get_label_tensor() - - num_samples = 10000 - - (x_train, y_train), (x_test, y_test) = cifar10.load_data(num_samples) - - full_input_np = np.zeros((num_samples, 3, 229, 229), dtype=np.float32) - - for i in range(0, num_samples): - image = x_train[i, :, :, :] - image = image.transpose(1, 2, 0) - pil_image = Image.fromarray(image) - pil_image = pil_image.resize((229,229), Image.NEAREST) - image = np.array(pil_image, dtype=np.float32) - image = image.transpose(2, 0, 1) - full_input_np[i, :, :, :] = image - - full_input_np /= 255 - - y_train = y_train.astype('int32') - full_label_np = y_train - - dataloader_input = ffmodel.create_data_loader(input_tensor, full_input_np) - dataloader_label = ffmodel.create_data_loader(label_tensor, full_label_np) - - num_samples = dataloader_input.num_samples - - ffmodel.init_layers() - - epochs = ffconfig.get_epochs() - - ts_start = ffconfig.get_current_time() - - ffmodel.fit(x=dataloader_input, y=dataloader_label, epochs=epochs) - - ts_end = ffconfig.get_current_time() - run_time = 1e-6 * (ts_end - ts_start); - print("epochs %d, ELAPSED TIME = %.4fs, THROUGHPUT = %.2f samples/s\n" %(epochs, run_time, num_samples * epochs / run_time)); - - # perf_metrics = ffmodel.get_perf_metrics() - # accuracy = perf_metrics.get_accuracy() - # if accuracy < ModelAccuracy.CIFAR10_CNN.value: - # assert 0, 'Check Accuracy' - - -if __name__ == "__main__": - print("cifar10 cnn") - top_level_task() diff --git a/bootcamp_demo/keras_cnn_cifar10.py b/bootcamp_demo/keras_cnn_cifar10.py deleted file mode 100644 index a62f625449..0000000000 --- a/bootcamp_demo/keras_cnn_cifar10.py +++ /dev/null @@ -1,56 +0,0 @@ -#./flexflow_python $FF_HOME/bootcamp_demo/keras_cnn_cifar10.py -ll:py 1 -ll:gpu 1 -ll:fsize 2048 -ll:zsize 12192 - -# from keras.models import Model, Sequential -# from keras.layers import Input, Flatten, Dense, Activation, Conv2D, MaxPooling2D, Dropout -# from keras.optimizers import SGD -# from keras.datasets import cifar10 -# from keras import losses -# from keras import metrics - -from flexflow.keras.models import Model, Sequential -from flexflow.keras.layers import Input, Flatten, Dense, Activation, Conv2D, MaxPooling2D, Dropout -from flexflow.keras.optimizers import SGD -from flexflow.keras.datasets import cifar10 -from flexflow.keras import losses -from flexflow.keras import metrics - -import numpy as np - -def top_level_task(): - num_classes = 10 - - num_samples = 10000 - - #(x_train, y_train), (x_test, y_test) = cifar10.load_data() - (x_train, y_train), (x_test, y_test) = cifar10.load_data(num_samples) - - x_train = x_train.astype('float32') - x_train /= 255 - y_train = y_train.astype('int32') - print("shape: ", x_train.shape[1:]) - - model = Sequential() - - model.add(Conv2D(filters=32, input_shape=(3,32,32), kernel_size=(3,3), strides=(1,1), padding="valid", activation="relu")) - model.add(Conv2D(filters=32, kernel_size=(3,3), strides=(1,1), padding="valid", activation="relu")) - model.add(MaxPooling2D(pool_size=(2,2), strides=(2,2), padding="valid")) - model.add(Conv2D(filters=64, kernel_size=(3,3), strides=(1,1), padding="valid", activation="relu")) - model.add(Conv2D(filters=64, kernel_size=(3,3), strides=(1,1), padding="valid")) - model.add(Activation("relu")) - model.add(MaxPooling2D(pool_size=(2,2), strides=(2,2), padding="valid")) - model.add(Flatten()) - model.add(Dense(512)) - model.add(Activation("relu")) - model.add(Dropout(0.5)) - model.add(Dense(num_classes)) - model.add(Activation("softmax")) - - opt = SGD(learning_rate=0.01) - model.compile(optimizer=opt, loss='sparse_categorical_crossentropy', metrics=['accuracy', 'sparse_categorical_crossentropy']) - print(model.summary()) - - model.fit(x_train, y_train, batch_size=64, epochs=4) - -if __name__ == "__main__": - print("Functional API, cifar10 cnn") - top_level_task() \ No newline at end of file diff --git a/bootcamp_demo/torch_alexnet_cifar10.py b/bootcamp_demo/torch_alexnet_cifar10.py deleted file mode 100644 index 394161c5a3..0000000000 --- a/bootcamp_demo/torch_alexnet_cifar10.py +++ /dev/null @@ -1,44 +0,0 @@ -#./flexflow_python $FF_HOME/bootcamp_demo/torch_alexnet_cifar10.py -ll:py 1 -ll:gpu 1 -ll:fsize 2048 -ll:zsize 12192 - -# https://github.com/pytorch/vision/blob/master/torchvision/models/alexnet.py - -import torch.nn as nn -import torch -import flexflow.torch.fx as fx -import torchvision.models as models - -class AlexNet(nn.Module): - def __init__(self, num_classes: int = 1000) -> None: - super(AlexNet, self).__init__() - self.features = nn.Sequential( - nn.Conv2d(3, 64, kernel_size=11, stride=4, padding=2), - nn.ReLU(inplace=True), - nn.MaxPool2d(kernel_size=3, stride=2), - nn.Conv2d(64, 192, kernel_size=5, padding=2), - nn.ReLU(inplace=True), - nn.MaxPool2d(kernel_size=3, stride=2), - nn.Conv2d(192, 384, kernel_size=3, padding=1), - nn.ReLU(inplace=True), - nn.Conv2d(384, 256, kernel_size=3, padding=1), - nn.ReLU(inplace=True), - nn.Conv2d(256, 256, kernel_size=3, padding=1), - nn.ReLU(inplace=True), - nn.MaxPool2d(kernel_size=3, stride=2), - ) - self.classifier = nn.Sequential( - nn.Linear(256 * 6 * 6, 4096), - nn.ReLU(inplace=True), - nn.Linear(4096, 4096), - nn.ReLU(inplace=True), - nn.Linear(4096, num_classes), - nn.Softmax(), - ) - - def forward(self, x: torch.Tensor) -> torch.Tensor: - x = self.features(x) - x = torch.flatten(x, 1) - x = self.classifier(x) - return x - -model = AlexNet(num_classes=10) -fx.torch_to_flexflow(model, "alexnet.ff") \ No newline at end of file diff --git a/cmake/cuda.cmake b/cmake/cuda.cmake index f4111d8ea6..45ecc1798b 100644 --- a/cmake/cuda.cmake +++ b/cmake/cuda.cmake @@ -13,8 +13,19 @@ if(CUDA_FOUND) # set cuda runtime and driver lib # override cublas and curand because the FindCUDA module may not find the correct libs set(CUDADRV_LIBRARIES ${CUDA_TOOLKIT_ROOT_DIR}/lib64/stubs/libcuda${LIBEXT}) - set(CUDA_CUBLAS_LIBRARIES ${CUDA_TOOLKIT_ROOT_DIR}/lib64/libcublas${LIBEXT}) - set(CUDA_curand_LIBRARY ${CUDA_TOOLKIT_ROOT_DIR}/lib64/libcurand${LIBEXT}) + if(CUBLAS_PATH) + set(CUBLAS_ROOT ${CUBLAS_PATH}) + else() + set(CUBLAS_ROOT ${CUDA_TOOLKIT_ROOT_DIR}) + endif() + set(CUDA_CUBLAS_LIBRARIES ${CUBLAS_ROOT}/lib64/libcublas${LIBEXT}) + if(CURAND_PATH) + set(CURAND_ROOT ${CURAND_PATH}) + else() + set(CURAND_ROOT ${CUDA_TOOLKIT_ROOT_DIR}) + endif() + set(CUDA_curand_LIBRARY ${CURAND_ROOT}/lib64/libcurand${LIBEXT}) + list(APPEND FLEXFLOW_EXT_LIBRARIES ${CUDADRV_LIBRARIES} ${CUDA_CUBLAS_LIBRARIES} @@ -53,8 +64,12 @@ if(CUDA_FOUND) message( STATUS "CUDA Detected CUDA_ARCH : ${DETECTED_CUDA_ARCH}" ) set(FF_CUDA_ARCH ${DETECTED_CUDA_ARCH}) # Set FF_CUDA_ARCH to the list of all GPU architectures compatible with FlexFlow - elseif("${FF_CUDA_ARCH}" STREQUAL "all") - set(FF_CUDA_ARCH 60,61,62,70,72,75,80,86) + elseif("${FF_CUDA_ARCH}" STREQUAL "all") + if(CUDA_VERSION VERSION_GREATER_EQUAL "11.8") + set(FF_CUDA_ARCH 60,61,62,70,72,75,80,86,90) + else() + set(FF_CUDA_ARCH 60,61,62,70,72,75,80,86) + endif() endif() # create CUDA_GENCODE list based on FF_CUDA_ARCH @@ -66,6 +81,7 @@ if(CUDA_FOUND) endforeach() string(REGEX REPLACE "([0-9]+)" "-gencode arch=compute_\\1,code=sm_\\1" CUDA_GENCODE "${CUDA_GENCODE}") + set(CMAKE_CUDA_COMPILER "${CUDA_NVCC_EXECUTABLE}") #output message( STATUS "CUDA_VERSION: ${CUDA_VERSION}") message( STATUS "CUDA root path : ${CUDA_TOOLKIT_ROOT_DIR}" ) @@ -76,6 +92,7 @@ if(CUDA_FOUND) message( STATUS "CURAND libraries : ${CUDA_curand_LIBRARY}" ) message( STATUS "CUDA Arch : ${FF_CUDA_ARCH}" ) message( STATUS "CUDA_GENCODE: ${CUDA_GENCODE}") + message( STATUS "CMAKE_CUDA_COMPILER: ${CMAKE_CUDA_COMPILER}") list(APPEND FLEXFLOW_INCLUDE_DIRS ${CUDA_INCLUDE_DIRS}) diff --git a/cmake/hip.cmake b/cmake/hip.cmake new file mode 100644 index 0000000000..25f2e05e19 --- /dev/null +++ b/cmake/hip.cmake @@ -0,0 +1,12 @@ +if (NOT FF_HIP_ARCH STREQUAL "") + if (FF_HIP_ARCH STREQUAL "all") + set(FF_HIP_ARCH "gfx900,gfx902,gfx904,gfx906,gfx908,gfx909,gfx90a,gfx90c,gfx940,gfx1010,gfx1011,gfx1012,gfx1013,gfx1030,gfx1031,gfx1032,gfx1033,gfx1034,gfx1035,gfx1036,gfx1100,gfx1101,gfx1102,gfx1103") + endif() + string(REPLACE "," "," HIP_ARCH_LIST "${FF_HIP_ARCH}") +endif() + +message(STATUS "FF_HIP_ARCH: ${FF_HIP_ARCH}") +if(FF_GPU_BACKEND STREQUAL "hip_rocm") + #set(HIP_CLANG_PATH ${ROCM_PATH}/llvm/bin CACHE STRING "Path to the clang compiler by ROCM" FORCE) + set(GPU_TARGETS "${FF_HIP_ARCH}" CACHE STRING "The GPU TARGETs") +endif() diff --git a/cmake/legion.cmake b/cmake/legion.cmake index b4cfad20e2..2afb507d3b 100644 --- a/cmake/legion.cmake +++ b/cmake/legion.cmake @@ -132,6 +132,10 @@ else() set(Legion_EMBED_GASNet_VERSION "GASNet-2022.3.0" CACHE STRING "GASNet version") set(Legion_NETWORKS "gasnetex" CACHE STRING "GASNet conduit") set(GASNet_CONDUIT ${FF_GASNET_CONDUIT}) + elseif("${FF_LEGION_NETWORKS}" STREQUAL "ucx") + set(ucx_ROOT ${UCX_PATH}/lib/cmake) + message(STATUS "Find ucx: ${UCX_PATH}") + set(Legion_NETWORKS "ucx" CACHE STRING "Enable UCX") endif() message(STATUS "GASNET ROOT: $ENV{GASNet_ROOT_DIR}") set(Legion_MAX_DIM ${FF_MAX_DIM} CACHE STRING "Maximum number of dimensions") @@ -142,8 +146,11 @@ else() set(Legion_USE_HIP ON CACHE BOOL "enable Legion_USE_HIP" FORCE) if (FF_GPU_BACKEND STREQUAL "hip_cuda") set(Legion_HIP_TARGET "CUDA" CACHE STRING "Legion_HIP_TARGET CUDA" FORCE) + set(Legion_CUDA_ARCH ${FF_CUDA_ARCH} CACHE STRING "Legion CUDA ARCH" FORCE) elseif(FF_GPU_BACKEND STREQUAL "hip_rocm") set(Legion_HIP_TARGET "ROCM" CACHE STRING "Legion HIP_TARGET ROCM" FORCE) + set(Legion_HIP_ARCH ${FF_HIP_ARCH} CACHE STRING "Legion HIP ARCH" FORCE) + message(STATUS "Legion_HIP_ARCH: ${Legion_HIP_ARCH}") endif() endif() set(Legion_REDOP_COMPLEX OFF CACHE BOOL "disable complex") diff --git a/cmake/nccl.cmake b/cmake/nccl.cmake index 04a23dcb8a..c140a44ec8 100644 --- a/cmake/nccl.cmake +++ b/cmake/nccl.cmake @@ -109,8 +109,9 @@ else() message( STATUS "NCCL include : ${NCCL_INCLUDE_DIRS}" ) message( STATUS "NCCL libraries : ${NCCL_LIBRARIES}" ) add_library(nccl SHARED IMPORTED) + + # Build NCCL from source else() - # Build NCCL from source message(STATUS "Building NCCL from source") list(TRANSFORM CUDA_GENCODE PREPEND "NVCC_GENCODE=" OUTPUT_VARIABLE NCCL_BUILD_NVCC_GENCODE) diff --git a/cmake/pip_install/CMakeLists.txt b/cmake/pip_install/CMakeLists.txt new file mode 100644 index 0000000000..105133a310 --- /dev/null +++ b/cmake/pip_install/CMakeLists.txt @@ -0,0 +1,10 @@ +# Use setup.py script to re-install the Python bindings library with the right library paths +if (FF_USE_PYTHON) + execute_process(COMMAND ${Python_EXECUTABLE} -c "import site, os; print([pkg for func in (site.getsitepackages(), site.getusersitepackages()) for pkg in ([func] if isinstance(func, str) else func) if os.access(pkg, os.W_OK)][0])" OUTPUT_VARIABLE PY_DEST OUTPUT_STRIP_TRAILING_WHITESPACE) + if(FF_BUILD_FROM_PYPI) + install(CODE "execute_process(COMMAND ${CMAKE_COMMAND} -E echo \"Editing path to Legion library using path: ${PY_DEST}/flexflow/lib \")") + # CMAKE_CURRENT_SOURCE_DIR=/usr/FlexFlow/cmake/pip_install + # Legion_BINARY_DIR=/usr/FlexFlow/build//deps/legion + install(CODE "execute_process(COMMAND ${Python_EXECUTABLE} ${CMAKE_CURRENT_SOURCE_DIR}/../../deps/legion/bindings/python/setup.py install --cmake-build-dir ${Legion_BINARY_DIR}/runtime --prefix ${PY_DEST}/flexflow ${Legion_PYTHON_EXTRA_INSTALL_ARGS} WORKING_DIRECTORY ${CMAKE_CURRENT_SOURCE_DIR}/../../deps/legion/bindings/python)") + endif() +endif() diff --git a/cmake/zlib.cmake b/cmake/zlib.cmake deleted file mode 100644 index 0281e02b88..0000000000 --- a/cmake/zlib.cmake +++ /dev/null @@ -1,8 +0,0 @@ -find_package(ZLIB REQUIRED) -if(ZLIB_FOUND) - list(APPEND FLEXFLOW_EXT_LIBRARIES - ${ZLIB_LIBRARIES}) - message( STATUS "ZLIB libraries : ${ZLIB_LIBRARIES}" ) -else() - message( FATAL_ERROR "ZLIB package not found") -endif() \ No newline at end of file diff --git a/conda/build.sh b/conda/build.sh deleted file mode 100755 index 0e84b7489a..0000000000 --- a/conda/build.sh +++ /dev/null @@ -1,30 +0,0 @@ -#! /usr/bin/env bash -set -euo pipefail - -# Cd into FF_HOME -cd "${BASH_SOURCE[0]%/*}/../" - -# build flexflow -# "search and replace" bash syntax used below to make shellcheck happy. -# see here: https://wiki-dev.bash-hackers.org/syntax/pe -CXXFLAGS="${CXXFLAGS//-O2/}" -CXXFLAGS="${CXXFLAGS//-std=c++17/}" -CXXFLAGS="${CXXFLAGS//-DNDEBUG/}" -CXXFLAGS="${CXXFLAGS//-D_FORTIFY_SOURCE=2/}" -export CXXFLAGS -CPPFLAGS="${CPPFLAGS//-O2/}" -CPPFLAGS="${CPPFLAGS//-std=c++17/}" -CPPFLAGS="${CPPFLAGS//-DNDEBUG/}" -CPPFLAGS="${CPPFLAGS//-D_FORTIFY_SOURCE=2/}" -export CPPFLAGS - -#export CUDNN_HOME=/projects/opt/centos7/cuda/10.1 -#export CUDA_HOME=/projects/opt/centos7/cuda/10.1 -export PROTOBUF_DIR=$BUILD_PREFIX -export FF_HOME=$SRC_DIR -export LG_RT_DIR=$SRC_DIR/legion/runtime -#export FF_ENABLE_DEBUG=1 -#export DEBUG=0 - -cd python -make diff --git a/conda/environment.yml b/conda/environment.yml index 05992a8bf7..48cd8ddb33 100644 --- a/conda/environment.yml +++ b/conda/environment.yml @@ -3,13 +3,16 @@ channels: - defaults - conda-forge dependencies: - - python>=3.6 + - python>=3.6,<3.12 - cffi>=1.11.0 - Pillow - pybind11 + - rust - cmake-build-extension + - jq - pip - pip: - qualname>=0.1.0 - keras_preprocessing>=1.1.2 - numpy>=1.16.0 + - requests diff --git a/conda/flexflow-cpu.yml b/conda/flexflow-cpu.yml deleted file mode 100644 index ced02b9db4..0000000000 --- a/conda/flexflow-cpu.yml +++ /dev/null @@ -1,19 +0,0 @@ -name: flexflow -channels: - - defaults - - conda-forge -dependencies: - - python>=3.6 - - cffi>=1.11.0 - - Pillow - - pybind11 - - cmake-build-extension - - pytest - - pip - - pip: - - qualname>=0.1.0 - - keras_preprocessing>=1.1.2 - - numpy>=1.16.0 - - torch --index-url https://download.pytorch.org/whl/cpu - - torchaudio --index-url https://download.pytorch.org/whl/cpu - - torchvision --index-url https://download.pytorch.org/whl/cpu diff --git a/conda/flexflow.yml b/conda/flexflow.yml new file mode 100644 index 0000000000..67ef6b3419 --- /dev/null +++ b/conda/flexflow.yml @@ -0,0 +1,27 @@ +name: flexflow +channels: + - defaults + - conda-forge +dependencies: + - python>=3.6,<3.12 + - cffi>=1.11.0 + - Pillow + - pybind11 + - rust + - cmake-build-extension + - jq + - pytest + - pip + - pip: + - qualname>=0.1.0 + - keras_preprocessing>=1.1.2 + - numpy>=1.16.0 + - torch>=1.13.1 --index-url https://download.pytorch.org/whl/cpu + - torchaudio>=0.13.1 --index-url https://download.pytorch.org/whl/cpu + - torchvision>=0.14.1 --index-url https://download.pytorch.org/whl/cpu + - regex + - onnx + - transformers>=4.31.0 + - sentencepiece + - einops + - requests diff --git a/conda/meta.yaml b/conda/meta.yaml deleted file mode 100644 index b6e14b2957..0000000000 --- a/conda/meta.yaml +++ /dev/null @@ -1,28 +0,0 @@ -package: - name: flexflow - version: "1.0" - -source: - git_rev: master - git_url: https://github.com/flexflow/FlexFlow.git - -build: - number: 0 - -requirements: - build: - - make - - git - - zlib - - protobuf - - {{ compiler('c') }} - - {{ compiler('cxx') }} - host: - - python - - cffi - run: - - cffi - - numpy - - python - - zlib - - keras-preprocessing diff --git a/conda/pytorch-gpu.yml b/conda/pytorch-gpu.yml index 677e71d73f..85d24ced17 100644 --- a/conda/pytorch-gpu.yml +++ b/conda/pytorch-gpu.yml @@ -3,7 +3,7 @@ channels: - defaults - conda-forge dependencies: - - python>=3.6 + - python>=3.6,<3.12 - pip - pip: - numpy>=1.16.0 diff --git a/config/config.inc b/config/config.inc index 6497dae40a..35709971ad 100644 --- a/config/config.inc +++ b/config/config.inc @@ -24,7 +24,20 @@ fi #set installation dir if [ -n "$INSTALL_DIR" ]; then - SET_INSTALL_DIR="-DCMAKE_INSTALL_PREFIX=${INSTALL_DIR}" + SET_INSTALL_DIR="-DINSTALL_DIR=${INSTALL_DIR}" +fi + +if [ "$INFERENCE_TESTS" = "ON" ]; then + SET_INFERENCE_TESTS="-DINFERENCE_TESTS=ON" +else + SET_INFERENCE_TESTS="-DINFERENCE_TESTS=OFF" +fi + +#set cmake prefix path dir +if [ -n "$LIBTORCH_PATH" ]; then + SET_LIBTORCH_PATH="-DLIBTORCH_PATH=${LIBTORCH_PATH}" +else + SET_LIBTORCH_PATH="" fi # set build type @@ -37,6 +50,11 @@ if [ -n "$FF_CUDA_ARCH" ]; then SET_CUDA_ARCH="-DFF_CUDA_ARCH=${FF_CUDA_ARCH}" fi +# set HIP Arch +if [ -n "$FF_HIP_ARCH" ]; then + SET_HIP_ARCH="-DFF_HIP_ARCH=${FF_HIP_ARCH}" +fi + # set CUDA dir if [ -n "$CUDA_DIR" ]; then SET_CUDA="-DCUDA_PATH=${CUDA_DIR}" @@ -44,11 +62,30 @@ if [ -n "$CUDA_DIR" ]; then SET_CUDA_LIB_PATH="CUDA_PATH=${CUDA_PATH}" fi +# set cublas dir +if [ -n "$CUBLAS_DIR" ]; then + SET_CUBLAS="-DCUBLAS_PATH=${CUBLAS_DIR}" +fi + +# set curand dir +if [ -n "$CURAND_DIR" ]; then + SET_CURAND="-DCURAND_PATH=${CURAND_DIR}" +fi + # set cudnn dir if [ -n "$CUDNN_DIR" ]; then SET_CUDNN="-DCUDNN_PATH=${CUDNN_DIR}" fi +# build legion only +if [ "$BUILD_LEGION_ONLY" = "ON" ]; then + SET_BUILD_LEGION_ONLY="-DBUILD_LEGION_ONLY=ON" +elif [ "$BUILD_LEGION_ONLY" = "OFF" ]; then + SET_BUILD_LEGION_ONLY="-DBUILD_LEGION_ONLY=OFF" +else + SET_BUILD_LEGION_ONLY="-DBUILD_LEGION_ONLY=OFF" +fi + # enable Python if [ "$FF_USE_PYTHON" = "ON" ]; then SET_PYTHON="-DFF_USE_PYTHON=ON" @@ -89,6 +126,10 @@ if [ "$FF_LEGION_NETWORKS" = "gasnet" ]; then fi elif [ "$FF_LEGION_NETWORKS" = "ucx" ]; then SET_LEGION_NETWORKS+=" -DFF_LEGION_NETWORKS=ucx" + # set ucx dir + if [ -n "$UCX_DIR" ]; then + SET_UCX="-DUCX_PATH=${UCX_DIR}" + fi fi # build C++ examples @@ -99,6 +140,13 @@ elif [ "$FF_BUILD_ALL_EXAMPLES" = "OFF" ]; then else SET_EXAMPLES="-DFF_BUILD_ALL_EXAMPLES=ON" fi +if [ "$FF_BUILD_ALL_INFERENCE_EXAMPLES" = "ON" ]; then + SET_INFERENCE_EXAMPLES="-DFF_BUILD_ALL_INFERENCE_EXAMPLES=ON" +elif [ "$FF_BUILD_ALL_INFERENCE_EXAMPLES" = "OFF" ]; then + SET_INFERENCE_EXAMPLES="-DFF_BUILD_ALL_INFERENCE_EXAMPLES=OFF" +else + SET_INFERENCE_EXAMPLES="-DFF_BUILD_ALL_INFERENCE_EXAMPLES=ON" +fi # enable C++ unit tests if [ "$FF_BUILD_UNIT_TESTS" = "ON" ]; then @@ -147,11 +195,18 @@ if [ -n "$FF_MAX_DIM" ]; then SET_MAX_DIM="-DFF_MAX_DIM=${FF_MAX_DIM}" fi +#set LEGION_MAX_RETURN_SIZE +if [ -n "$LEGION_MAX_RETURN_SIZE" ]; then + SET_LEGION_MAX_RETURN_SIZE="-DLEGION_MAX_RETURN_SIZE=${LEGION_MAX_RETURN_SIZE}" +fi + # set ROCM path if [ -n "$ROCM_PATH" ]; then SET_ROCM_PATH="-DROCM_PATH=${ROCM_PATH}" fi +ADD_ROCM_TO_PATH="" + # set GPU backend if [ -n "$FF_GPU_BACKEND" ]; then SET_FF_GPU_BACKEND="-DFF_GPU_BACKEND=${FF_GPU_BACKEND}" @@ -184,17 +239,18 @@ if [ -n "$FF_GPU_BACKEND" ]; then chmod +x "$(pwd)/nvidia_hipcc" SET_CXX="-DCMAKE_CXX_COMPILER=$(pwd)/nvidia_hipcc -DCMAKE_CXX_LINKER=$(pwd)/nvidia_hipcc" else + ADD_ROCM_TO_PATH="PATH=${PATH}:${ROCM_PATH}/bin" SET_CXX="-DCMAKE_CXX_COMPILER=$ROCM_PATH/bin/hipcc -DCMAKE_CXX_LINKER=$ROCM_PATH/bin/hipcc -DHIP_PATH=$ROCM_PATH/hip -DCMAKE_CXX_FLAGS='-I${MPICH_DIR}/include' -DCMAKE_EXE_LINKER_FLAGS='-L${MPICH_DIR}/lib -lmpi' -DCMAKE_SHARED_LINKER_FLAGS='-L${MPICH_DIR}/lib -lmpi'" fi fi fi fi -CMAKE_FLAGS="-DCUDA_USE_STATIC_CUDA_RUNTIME=OFF -DLegion_HIJACK_CUDART=OFF ${SET_CC} ${SET_CXX} ${SET_INSTALL_DIR} ${SET_BUILD} ${SET_CUDA_ARCH} ${SET_CUDA} ${SET_CUDNN} ${SET_PYTHON} ${SET_NCCL} ${SET_NCCL_DIR} ${SET_LEGION_NETWORKS} ${SET_EXAMPLES} ${SET_USE_PREBUILT_LEGION} ${SET_USE_PREBUILT_NCCL} ${SET_USE_ALL_PREBUILT_LIBRARIES} ${SET_BUILD_UNIT_TESTS} ${SET_AVX2} ${SET_MAX_DIM} ${SET_ROCM_PATH} ${SET_FF_GPU_BACKEND}" +CMAKE_FLAGS="-DCUDA_USE_STATIC_CUDA_RUNTIME=OFF -DLegion_HIJACK_CUDART=OFF ${SET_CC} ${SET_CXX} ${SET_INSTALL_DIR} ${SET_INFERENCE_TESTS} ${SET_LIBTORCH_PATH} ${SET_BUILD} ${SET_CUDA_ARCH} ${SET_CUDA} ${SET_CUBLAS} ${SET_CURAND} ${SET_CUDNN} ${SET_HIP_ARCH} ${SET_PYTHON} ${SET_BUILD_LEGION_ONLY} ${SET_NCCL} ${SET_NCCL_DIR} ${SET_LEGION_NETWORKS} ${SET_UCX} ${SET_EXAMPLES} ${SET_INFERENCE_EXAMPLES} ${SET_USE_PREBUILT_LEGION} ${SET_USE_PREBUILT_NCCL} ${SET_USE_ALL_PREBUILT_LIBRARIES} ${SET_BUILD_UNIT_TESTS} ${SET_AVX2} ${SET_MAX_DIM} ${SET_LEGION_MAX_RETURN_SIZE} ${SET_ROCM_PATH} ${SET_FF_GPU_BACKEND}" function run_cmake() { SRC_LOCATION=${SRC_LOCATION:=`dirname $0`/../} -CMAKE_COMMAND="${SET_CC_FLAGS} ${SET_NVCC_FLAGS} ${SET_LD_FLAGS} ${SET_CUDA_LIB_PATH} cmake ${CMAKE_FLAGS} $* ${SRC_LOCATION}" +CMAKE_COMMAND="${SET_CC_FLAGS} ${SET_NVCC_FLAGS} ${SET_LD_FLAGS} ${SET_CUDA_LIB_PATH} ${ADD_ROCM_TO_PATH} cmake ${CMAKE_FLAGS} $* ${SRC_LOCATION}" echo $CMAKE_COMMAND eval $CMAKE_COMMAND } diff --git a/config/config.linux b/config/config.linux index d3729aea4c..9a00d3b69f 100755 --- a/config/config.linux +++ b/config/config.linux @@ -1,5 +1,4 @@ #!/bin/bash - # set the CC and CXX, usually it is not needed as cmake can detect it # set CC and CXX to mpicc and mpic++ when enable gasnet # CC=mpicc @@ -11,24 +10,46 @@ #LD_FLAGS=${LD_FLAGS+=""} #set install dir -#INSTALL_DIR= +INSTALL_DIR=${INSTALL_DIR:-} # set build type BUILD_TYPE=${BUILD_TYPE:-Release} +INFERENCE_TESTS=${INFERENCE_TESTS:-OFF} +LIBTORCH_PATH=${LIBTORCH_PATH:-"$(realpath ../..)/libtorch"} +if [[ "$INFERENCE_TESTS" == "ON" && ! -d "$LIBTORCH_PATH" ]]; then + cwd="$(pwd)" + cd ../.. + wget https://download.pytorch.org/libtorch/nightly/cpu/libtorch-shared-with-deps-latest.zip + unzip libtorch-shared-with-deps-latest.zip + rm libtorch-shared-with-deps-latest.zip + LIBTORCH_PATH="$(pwd)/libtorch" + cd "$cwd" +fi + # set CUDA Arch to the desired GPU architecture(s) to target (e.g. pass "FF_CUDA_ARCH=60" for Pascal). # To pass more than one value, separate architecture numbers with a comma (e.g. FF_CUDA_ARCH=70,75). # Alternatively, set "FF_CUDA_ARCH=autodetect" to build FlexFlow for all architectures detected on the machine, # or set "FF_CUDA_ARCH=all" to build FlexFlow for all supported GPU architectures FF_CUDA_ARCH=${FF_CUDA_ARCH:-"autodetect"} - -# set CUDNN dir in case cmake cannot autodetect a path -CUDNN_DIR=${CUDNN_DIR:-"/usr/local/cuda"} +# FF_HIP_ARCH only supports building for a specific AMD architecture, a list of architectures separated by a comma +# or all available architectures. TODO: support autodetect +FF_HIP_ARCH=${FF_HIP_ARCH:-"all"} # set CUDA dir in case cmake cannot autodetect a path CUDA_DIR=${CUDA_DIR:-"/usr/local/cuda"} -#set NCCL dir +# set CUBLAS dir in case it is not stored in the CUDA DIR +CUBLAS_DIR=${CUBLAS_DIR:-"/usr/local/cuda"} + +# set CURAND dir in case it is not stored in the CUDA DIR +CURAND_DIR=${CURAND_DIR:-"/usr/local/cuda"} + +# set CUDNN dir in case cmake cannot autodetect a path +CUDNN_DIR=${CUDNN_DIR:-"/usr/local/cuda"} + +# if not use PREBUILD_NCCL, you can set NCCL_DIR to use external nccl lib, +# otherwise, we will build nccl from source NCCL_DIR=${NCCL_DIR:-"/usr/local/cuda"} # enable Python @@ -40,11 +61,12 @@ FF_LEGION_NETWORKS=${FF_LEGION_NETWORKS:-} # select GASNET conduit FF_GASNET_CONDUIT=${FF_GASNET_CONDUIT:-ofi} -# set UCX URL -FF_UCX_URL=${FF_UCX_URL:-""} +# set UCX dir if Legion networks is set to ucx +UCX_DIR=${UCX_DIR:-""} # build C++ examples FF_BUILD_ALL_EXAMPLES=${FF_BUILD_ALL_EXAMPLES:-OFF} +FF_BUILD_ALL_INFERENCE_EXAMPLES=${FF_BUILD_ALL_INFERENCE_EXAMPLES:-ON} # build C++ unit tests FF_BUILD_UNIT_TESTS=${FF_BUILD_UNIT_TESTS:-OFF} @@ -52,6 +74,7 @@ FF_BUILD_UNIT_TESTS=${FF_BUILD_UNIT_TESTS:-OFF} # use precompiled NCCL and Legion libraries, where available FF_USE_PREBUILT_NCCL=${FF_USE_PREBUILT_NCCL:-OFF} FF_USE_PREBUILT_LEGION=${FF_USE_PREBUILT_LEGION:-OFF} + # use the flag below to use both the NCCL and Legion pre-built libraries. # when the flag below is set to ON, the two flags above are ignored. FF_USE_ALL_PREBUILT_LIBRARIES=${FF_USE_ALL_PREBUILT_LIBRARIES:-OFF} @@ -62,6 +85,12 @@ FF_USE_AVX2=${FF_USE_AVX2:-OFF} # set MAX_DIM FF_MAX_DIM=${FF_MAX_DIM:-5} +# set BUILD_LEGION_ONLY +BUILD_LEGION_ONLY=${BUILD_LEGION_ONLY:-OFF} + +# set LEGION_MAX_RETURN_SIZE +LEGION_MAX_RETURN_SIZE=${LEGION_MAX_RETURN_SIZE:-262144} + # set ROCM path ROCM_PATH=${ROCM_PATH:-"/opt/rocm"} @@ -77,7 +106,7 @@ fi function get_build_configs() { # Create a string with the values of the variables set in this script - BUILD_CONFIGS="FF_CUDA_ARCH=${FF_CUDA_ARCH} CUDNN_DIR=${CUDNN_DIR} CUDA_DIR=${CUDA_DIR} NCCL_DIR=${NCCL_DIR} FF_USE_PYTHON=${FF_USE_PYTHON} FF_GASNET_CONDUIT=${FF_GASNET_CONDUIT} FF_UCX_URL=${FF_UCX_URL} FF_LEGION_NETWORKS=${FF_LEGION_NETWORKS} FF_BUILD_ALL_EXAMPLES=${FF_BUILD_ALL_EXAMPLES} FF_BUILD_UNIT_TESTS=${FF_BUILD_UNIT_TESTS} FF_USE_PREBUILT_NCCL=${FF_USE_PREBUILT_NCCL} FF_USE_PREBUILT_LEGION=${FF_USE_PREBUILT_LEGION} FF_USE_ALL_PREBUILT_LIBRARIES=${FF_USE_ALL_PREBUILT_LIBRARIES} FF_USE_AVX2=${FF_USE_AVX2} FF_MAX_DIM=${FF_MAX_DIM} ROCM_PATH=${ROCM_PATH} FF_GPU_BACKEND=${FF_GPU_BACKEND}" + BUILD_CONFIGS="FF_CUDA_ARCH=${FF_CUDA_ARCH} FF_HIP_ARCH=${FF_HIP_ARCH} CUDA_DIR=${CUDA_DIR} CUDNN_DIR=${CUDNN_DIR} CUBLAS_DIR=${CUBLAS_DIR} CURAND_DIR=${CURAND_DIR} NCCL_DIR=${NCCL_DIR} FF_USE_PYTHON=${FF_USE_PYTHON} BUILD_LEGION_ONLY=${BUILD_LEGION_ONLY} FF_GASNET_CONDUIT=${FF_GASNET_CONDUIT} UCX_DIR=${UCX_DIR} FF_LEGION_NETWORKS=${FF_LEGION_NETWORKS} FF_BUILD_ALL_EXAMPLES=${FF_BUILD_ALL_EXAMPLES} FF_BUILD_ALL_INFERENCE_EXAMPLES=${FF_BUILD_ALL_INFERENCE_EXAMPLES} FF_BUILD_UNIT_TESTS=${FF_BUILD_UNIT_TESTS} FF_USE_PREBUILT_NCCL=${FF_USE_PREBUILT_NCCL} FF_USE_PREBUILT_LEGION=${FF_USE_PREBUILT_LEGION} FF_USE_ALL_PREBUILT_LIBRARIES=${FF_USE_ALL_PREBUILT_LIBRARIES} FF_USE_AVX2=${FF_USE_AVX2} FF_MAX_DIM=${FF_MAX_DIM} ROCM_PATH=${ROCM_PATH} FF_GPU_BACKEND=${FF_GPU_BACKEND} INSTALL_DIR=${INSTALL_DIR}" } if [[ -n "$1" && ( "$1" == "CMAKE_FLAGS" || "$1" == "CUDA_PATH" ) ]]; then diff --git a/deps/tokenizers-cpp b/deps/tokenizers-cpp new file mode 160000 index 0000000000..4f42c9fa74 --- /dev/null +++ b/deps/tokenizers-cpp @@ -0,0 +1 @@ +Subproject commit 4f42c9fa74946d70af86671a3804b6f2433e5dac diff --git a/docker/README.md b/docker/README.md index 916b78acf6..010aadf762 100644 --- a/docker/README.md +++ b/docker/README.md @@ -2,50 +2,61 @@ This folder contains the Dockerfiles and scripts that you can use to quickly run FlexFlow with no manual installation required. To use the containers, follow the steps below. ## Prerequisites -You will need a machine with a NVIDIA GPU, with drivers installed. You will also need to have Docker and the [Nvidia Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/install-guide.html#getting-started) installed on the host machine. +You can build and run the FlexFlow Docker images on any machine, but if you want to train or serve a model, you will need a machine with a NVIDIA or AMD GPU, with drivers installed. You will also need to have Docker and the [Nvidia Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/install-guide.html#getting-started) installed on the host machine. If using an AMD GPU, follow the [Deploy ROCm Docker containers](https://rocm.docs.amd.com/en/latest/deploy/docker.html) instructions. ## Downloading a pre-built package The fastest way to run FlexFlow is to use one of the pre-built containers, which we update for each commit to the `inference` branch (the `inference` branch is currently ahead of the `master` branch). The available containers are the following, and can be found [at this link](https://github.com/orgs/flexflow/packages?repo_name=FlexFlow): -* `flexflow`: the pre-built version of FlexFlow. We currently publish one version targeting GPUs with a `hip_rocm` backend (`flexflow-hip_rocm`), and several versions for CUDA GPUs (one for each of the following CUDA versions 11.1, 11.2, 11.3, 11.5, 11.6, 11.7, and 11.8). The CUDA images are named `flexflow-cuda-`, e.g. [flexflow-cuda-11.8](https://github.com/orgs/flexflow/packages/container/package/flexflow-cuda-11.8) -* `flexflow-environment`: this is the base layer for `flexflow`. The packages are used in CI or for internal use, and contain all the dependencies needed to build/run Flexflow. You may find them useful if you want to build FlexFlow yourself. We also publish one version of `flexflow-environment` for `hip_rocm` and one for each CUDA version in the list above. The naming convention is similar, too. For example, the `flexflow-environment` image for CUDA 11.8 is tagged [flexflow-environment-cuda-11.8](https://github.com/orgs/flexflow/packages/container/package/flexflow-environment-cuda-11.8). +* `flexflow`: the pre-built version of FlexFlow. We currently publish four version targeting AMD GPUs (ROCm versions: 5.3, 5.4, 5.5 and 5.6 ), and several versions for CUDA GPUs (CUDA versions: 11.1, 11.6, 11.7, 11.8, 12.0, 12.1, and 12.2). The CUDA images are named `flexflow--`, e.g. [flexflow-hip_rocm-5.6](https://github.com/flexflow/FlexFlow/pkgs/container/flexflow-hip_rocm-5.6) or [flexflow-cuda-12.0](https://github.com/orgs/flexflow/packages/container/package/flexflow-cuda-12.0) or +* `flexflow-environment`: this is the base layer for `flexflow`. The packages are used in CI or for internal use, and contain all the dependencies needed to build/run Flexflow. You may find them useful if you want to build FlexFlow yourself. We also publish four version of `flexflow-environment` for AMD GPUs and, for NVIDIA GPUs, one for each CUDA version in the list above. The naming convention is similar, too. For example, the `flexflow-environment` image for CUDA 12.0 is tagged [flexflow-environment-cuda-12.0](https://github.com/orgs/flexflow/packages/container/package/flexflow-environment-cuda-12.0). The easiest way to download any of the Docker containers above is to call: ``` -FF_GPU_BACKEND= cuda_version= ./docker/pull.sh +./docker/pull.sh ``` -where `CONTAINER_NAME` is `flexflow` (or `flexflow-environment`), and `FF_GPU_BACKEND`/`cuda_version` are optional environment variables you can use if you wish to download the docker image for a GPU backend and/or cuda version other than those installed on your machine (leaving these variables unset will let the script autodetect which version to download depending on your setup). +where `CONTAINER_NAME` is `flexflow` (or `flexflow-environment`). By default, the script will assume a NVIDIA backend and attempt to detect the CUDA version on your machine, to download the relevant container. If your machine has AMD GPUs, or no GPUs, or if you want to specify the CUDA/ROCM version to download, set the environment variables below: + +* `FF_GPU_BACKEND` (supported options: `cuda`, `hip_rocm`) to specify the GPU backend of the Docker container to be downloaded. +* `cuda_version` (supported options: 11.1, 11.6, 11.7, 11.8, 12.0, 12.1 and 12.2) to specify the CUDA version, when using a `cuda` backend. If `FF_GPU_BACKEND` is set to `hip_rocm`, the `cuda_version` env will be ignored +* `hip_version` (supported options: 5.3, 5.4, 5.5, 5.6) to specify the ROCm version, when using a HIP backend. If `FF_GPU_BACKEND` is set to `cuda`, the `hip_version` env will be ignored. + After downloading a container you can use the `run.sh` script to run it by following the instructions in the section below. ## Building a Docker container from scratch -If you prefer to build one of the Docker containers from scratch, you can do so with the help of the `build.sh` script. You can configure the build via the same environment variables that you'd use to configure a CMake build (refer to the [Installation guide](../INSTALL.md) and to the `config/config.linux` file). For example, to build for a CUDA backend, you can export `FF_GPU_BACKEND=cuda` (you can also omit this since `cuda` is the default value for `FF_GPU_BACKEND`). When building for the `cuda` backend, you can pick the CUDA version by setting the optional environment variable `cuda_version`, e.g.: `export cuda_version=11.8`. Leaving the `cuda_version` variable blank will let the script autodetect the CUDA version installed on the host machine, and build for that version. Setting the `cuda_version` env will have no effect when building for a GPU backend other than CUDA. +If you prefer to build one of the Docker containers from scratch, you can do so with the help of the `build.sh` script. You can configure the build via the same environment variables that you'd use to configure a CMake build (refer to the [Installation guide](https://flexflow.readthedocs.io/en/latest/installation.html) and to the `config/config.linux` file). For example, to build for a CUDA backend, you can export `FF_GPU_BACKEND=cuda` (you can also omit this since `cuda` is the default value for `FF_GPU_BACKEND`). When building for the `cuda` backend, you can pick the CUDA version by setting the optional environment variable `cuda_version`, e.g.: `export cuda_version=12.0`. Leaving the `cuda_version` variable blank will let the script autodetect the CUDA version installed on the host machine, and build for that version. Setting the `cuda_version` env will have no effect when building for a GPU backend other than CUDA. Similarly, you can pick the ROCm version by setting `hip_version` when the backend is `FF_GPU_BACKEND=hip_rocm`, whereas the env will be ignored for non-HIP backends. To build the FlexFlow container, run (the `flexflow` argument of the build script can be omitted): ``` -FF_GPU_BACKEND= cuda_version= ./docker/build.sh flexflow +./docker/build.sh flexflow ``` If you only want to build the `flexflow-environment` image (the base layers of the `flexflow` container, used in CI and for other internal purposes), run: ``` -FF_GPU_BACKEND= cuda_version= ./docker/build.sh flexflow-environment +./docker/build.sh flexflow-environment ``` ## Running a Docker container -After having either built or downloaded a Docker container by following the instructions above, you can run it with the following command (image name argument of the run script can be omitted). Once again, you can set the `FF_GPU_BACKEND` and `cuda_version` optional environment variables to run the docker image with the desired GPU backend and CUDA version. Leaving these variables unset will instruct the script to autodetect the GPU backend and CUDA version installed on the current machine and run the Docker container with it if available. +After having either built or downloaded a Docker container by following the instructions above, you can run it with the following command (image name argument of the run script can be omitted). Once again, you can set the `FF_GPU_BACKEND`, `cuda_version` and `hip_version` optional environment variables to run the docker image with the desired GPU backend and CUDA/HIP version: + +* `FF_GPU_BACKEND` (supported options: `cuda`, `hip_rocm`) to specify the GPU backend of the Docker container to be run. +* `cuda_version` (supported options: 11.1, 11.6, 11.7, 11.8, 12.0, 12.1, 12.2) to specify the CUDA version, when using a `cuda` backend. If `FF_GPU_BACKEND` is set to `hip_rocm`, the `cuda_version` env will be ignored +* `hip_version` (supported options: 5.3, 5.4, 5.5, 5.6) to specify the ROCm version, when using a HIP backend. If `FF_GPU_BACKEND` is set to `cuda`, the `hip_version` env will be ignored. + +Leaving these variables unset will assume a GPU backend, and instruct the script to autodetect the CUDA version installed on the current machine and run the Docker container with it if available. ``` -FF_GPU_BACKEND= cuda_version= ./docker/run.sh --image_name flexflow +./docker/run.sh --image_name flexflow ``` If you wish to run the `flexflow-environment` container, run: ``` -FF_GPU_BACKEND= cuda_version= ./docker/run.sh --image_name flexflow-environment +./docker/run.sh --image_name flexflow-environment ``` N.B.: If you don't have GPUs available on the machine, or you wish to run the docker image without attaching GPUs, you can set the environment variable `ATTACH_GPUS=false` before running the script. diff --git a/docker/build.sh b/docker/build.sh index 6ed5cbe00e..8ecacbc6d4 100755 --- a/docker/build.sh +++ b/docker/build.sh @@ -2,7 +2,7 @@ set -euo pipefail # Usage: ./build.sh -# Optional environment variables: FF_GPU_BACKEND, cuda_version +# Optional environment variables: FF_GPU_BACKEND, cuda_version, hip_version # Cd into $FF_HOME. Assumes this script is in $FF_HOME/docker cd "${BASH_SOURCE[0]%/*}/.." @@ -11,6 +11,8 @@ cd "${BASH_SOURCE[0]%/*}/.." image=${1:-flexflow} FF_GPU_BACKEND=${FF_GPU_BACKEND:-cuda} cuda_version=${cuda_version:-"empty"} +hip_version=${hip_version:-"empty"} +python_version=${python_version:-latest} # Check docker image name if [[ "$image" != @(flexflow-environment|flexflow) ]]; then @@ -28,52 +30,98 @@ else echo "Building $image docker image with default GPU backend: cuda" fi +# base image to use when building the flexflow environment docker image. +ff_environment_base_image="ubuntu:20.04" +# gpu backend version suffix for the docker image. +gpu_backend_version="" + if [[ "${FF_GPU_BACKEND}" == "cuda" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then # Autodetect cuda version if not specified if [[ $cuda_version == "empty" ]]; then - cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}') + # shellcheck disable=SC2015 + cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}' || true) # Change cuda_version eg. V11.7.99 to 11.7 cuda_version=${cuda_version:1:4} + if [[ -z "$cuda_version" ]]; then + echo "Could not detect CUDA version. Please specify one manually by setting the 'cuda_version' env." + exit 1 + fi fi # Check that CUDA version is supported, and modify cuda version to include default subsubversion - if [[ "$cuda_version" == @(11.1|11.3|11.7) ]]; then + if [[ "$cuda_version" == @(11.1|11.3|11.7|12.0|12.1) ]]; then cuda_version_input=${cuda_version}.1 - elif [[ "$cuda_version" == @(11.2|11.5|11.6) ]]; then + elif [[ "$cuda_version" == @(11.2|11.5|11.6|12.2) ]]; then cuda_version_input=${cuda_version}.2 + elif [[ "$cuda_version" == @(11.4) ]]; then + cuda_version_input=${cuda_version}.3 elif [[ "$cuda_version" == @(11.8) ]]; then cuda_version_input=${cuda_version}.0 else - echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.5|11.6|11.7|11.8}" + echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0|12.1|12.2}" exit 1 fi - # Set cuda version suffix to docker image name + # Use CUDA 12.2 for all versions greater or equal to 12.2 for now (the Docker machine with CUDNN is not yet available) + if [[ "$cuda_version" == @(12.3|12.4|12.5|12.6|12.7|12.8|12.9) ]]; then + cuda_version=12.2 + cuda_version_input=${cuda_version}.2 + fi echo "Building $image docker image with CUDA $cuda_version" - cuda_version="-${cuda_version}" -else - # Empty cuda version suffix for non-CUDA images - cuda_version="" - # Pick a default CUDA version for the base docker image from NVIDIA - cuda_version_input="11.8.0" + ff_environment_base_image="nvidia/cuda:${cuda_version_input}-cudnn8-devel-ubuntu20.04" + gpu_backend_version="-${cuda_version}" +fi + +if [[ "${FF_GPU_BACKEND}" == "hip_rocm" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then + # Autodetect HIP version if not specified + if [[ $hip_version == "empty" ]]; then + # shellcheck disable=SC2015 + hip_version=$(command -v hipcc >/dev/null 2>&1 && hipcc --version | grep "HIP version:" | awk '{print $NF}' || true) + # Change hip_version eg. 5.6.31061-8c743ae5d to 5.6 + hip_version=${hip_version:0:3} + if [[ -z "$hip_version" ]]; then + echo "Could not detect HIP version. Please specify one manually by setting the 'hip_version' env." + exit 1 + fi + fi + # Check that HIP version is supported + if [[ "$hip_version" != @(5.3|5.4|5.5|5.6) ]]; then + echo "hip_version is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + echo "Building $image docker image with HIP $hip_version" + if [[ "${FF_GPU_BACKEND}" == "hip_rocm" ]]; then + gpu_backend_version="-${hip_version}" + fi +fi + +# Get number of cores available on the machine. Build with all cores but one, to prevent RAM choking +cores_available=$(nproc --all) +n_build_cores=$(( cores_available -1 )) + +# check python_version +if [[ "$python_version" != @(3.8|3.9|3.10|3.11|latest) ]]; then + echo "python_version not supported!" + exit 0 fi -docker build --build-arg "FF_GPU_BACKEND=${FF_GPU_BACKEND}" --build-arg "cuda_version=${cuda_version_input}" -t "flexflow-environment-${FF_GPU_BACKEND}${cuda_version}" -f docker/flexflow-environment/Dockerfile . +docker build --build-arg "ff_environment_base_image=${ff_environment_base_image}" --build-arg "N_BUILD_CORES=${n_build_cores}" --build-arg "FF_GPU_BACKEND=${FF_GPU_BACKEND}" --build-arg "hip_version=${hip_version}" --build-arg "python_version=${python_version}" -t "flexflow-environment-${FF_GPU_BACKEND}${gpu_backend_version}" -f docker/flexflow-environment/Dockerfile . # If the user only wants to build the environment image, we are done if [[ "$image" == "flexflow-environment" ]]; then exit 0 fi -# Gather arguments needed to build the FlexFlow image -# Get number of cores available on the machine. Build with all cores but one, to prevent RAM choking -cores_available=$(nproc --all) -n_build_cores=$(( cores_available -1 )) +# Done with flexflow-environment image -# If FF_CUDA_ARCH is set to autodetect, we need to perform the autodetection here because the Docker -# image will not have access to GPUs during the build phase (due to a Docker restriction). In all other -# cases, we pass the value of FF_CUDA_ARCH directly to Cmake. -if [[ "${FF_CUDA_ARCH:-autodetect}" == "autodetect" ]]; then - # Get CUDA architecture(s), if GPUs are available - cat << EOF > ./get_gpu_arch.cu +########################################################################################### + +# Build flexflow image if requested +if [[ "${FF_GPU_BACKEND}" == "cuda" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then + # If FF_CUDA_ARCH is set to autodetect, we need to perform the autodetection here because the Docker + # image will not have access to GPUs during the build phase (due to a Docker restriction). In all other + # cases, we pass the value of FF_CUDA_ARCH directly to Cmake. + if [[ "${FF_CUDA_ARCH:-autodetect}" == "autodetect" ]]; then + # Get CUDA architecture(s), if GPUs are available + cat << EOF > ./get_gpu_arch.cu #include int main() { int count = 0; @@ -87,24 +135,25 @@ int main() { return 0; } EOF - gpu_arch_codes="" - if command -v nvcc &> /dev/null - then - nvcc ./get_gpu_arch.cu -o ./get_gpu_arch - gpu_arch_codes="$(./get_gpu_arch)" - fi - gpu_arch_codes="$(echo "$gpu_arch_codes" | xargs -n1 | sort -u | xargs)" - gpu_arch_codes="${gpu_arch_codes// /,}" - rm -f ./get_gpu_arch.cu ./get_gpu_arch - - if [[ -n "$gpu_arch_codes" ]]; then - echo "Host machine has GPUs with architecture codes: $gpu_arch_codes" - echo "Configuring FlexFlow to build for the $gpu_arch_codes code(s)." - FF_CUDA_ARCH="${gpu_arch_codes}" - export FF_CUDA_ARCH - else - echo "FF_CUDA_ARCH is set to 'autodetect', but the host machine does not have any compatible GPUs." - exit 1 + gpu_arch_codes="" + if command -v nvcc &> /dev/null + then + nvcc ./get_gpu_arch.cu -o ./get_gpu_arch + gpu_arch_codes="$(./get_gpu_arch)" + fi + gpu_arch_codes="$(echo "$gpu_arch_codes" | xargs -n1 | sort -u | xargs)" + gpu_arch_codes="${gpu_arch_codes// /,}" + rm -f ./get_gpu_arch.cu ./get_gpu_arch + + if [[ -n "$gpu_arch_codes" ]]; then + echo "Host machine has GPUs with architecture codes: $gpu_arch_codes" + echo "Configuring FlexFlow to build for the $gpu_arch_codes code(s)." + FF_CUDA_ARCH="${gpu_arch_codes}" + export FF_CUDA_ARCH + else + echo "FF_CUDA_ARCH is set to 'autodetect', but the host machine does not have any compatible GPUs." + exit 1 + fi fi fi @@ -114,4 +163,4 @@ fi # Set value of BUILD_CONFIGS get_build_configs -docker build --build-arg "N_BUILD_CORES=${n_build_cores}" --build-arg "FF_GPU_BACKEND=${FF_GPU_BACKEND}" --build-arg "BUILD_CONFIGS=${BUILD_CONFIGS}" --build-arg "cuda_version=${cuda_version}" -t "flexflow-${FF_GPU_BACKEND}${cuda_version}" -f docker/flexflow/Dockerfile . +docker build --build-arg "N_BUILD_CORES=${n_build_cores}" --build-arg "FF_GPU_BACKEND=${FF_GPU_BACKEND}" --build-arg "BUILD_CONFIGS=${BUILD_CONFIGS}" --build-arg "gpu_backend_version=${gpu_backend_version}" -t "flexflow-${FF_GPU_BACKEND}${gpu_backend_version}" -f docker/flexflow/Dockerfile . diff --git a/docker/flexflow-environment/Dockerfile b/docker/flexflow-environment/Dockerfile index 50497197c9..6ca337f58d 100644 --- a/docker/flexflow-environment/Dockerfile +++ b/docker/flexflow-environment/Dockerfile @@ -1,11 +1,11 @@ -ARG cuda_version -FROM nvidia/cuda:${cuda_version}-cudnn8-devel-ubuntu20.04 +ARG ff_environment_base_image +FROM ${ff_environment_base_image} LABEL org.opencontainers.image.source=https://github.com/flexflow/FlexFlow LABEL org.opencontainers.image.description="FlexFlow environment container" # Install basic dependencies -RUN apt-get update && apt-get install -y --no-install-recommends wget sudo binutils git zlib1g-dev lsb-release nano libhdf5-dev && \ +RUN apt-get update && apt-get install -y --no-install-recommends wget sudo binutils git zlib1g-dev lsb-release nano gdb libhdf5-dev jq && \ rm -rf /var/lib/apt/lists/* /etc/apt/sources.list.d/cuda.list /etc/apt/sources.list.d/nvidia-ml.list && \ apt-get update && DEBIAN_FRONTEND=noninteractive apt-get install -y --no-install-recommends software-properties-common && \ apt-get update && DEBIAN_FRONTEND=noninteractive apt-get install -y --no-install-recommends build-essential apt-utils \ @@ -16,14 +16,30 @@ RUN apt-get update && apt-get install -y --no-install-recommends wget sudo binut apt-get upgrade -y libstdc++6 # Install Python3 with Miniconda -RUN wget -c -q https://repo.continuum.io/miniconda/Miniconda3-latest-Linux-x86_64.sh && \ - mv Miniconda3-latest-Linux-x86_64.sh ~/Miniconda3-latest-Linux-x86_64.sh && \ - chmod +x ~/Miniconda3-latest-Linux-x86_64.sh && \ - bash ~/Miniconda3-latest-Linux-x86_64.sh -b -p /opt/conda && \ - rm ~/Miniconda3-latest-Linux-x86_64.sh && \ - /opt/conda/bin/conda upgrade --all && \ - /opt/conda/bin/conda install conda-build conda-verify && \ - /opt/conda/bin/conda clean -ya +ARG python_version "latest" +#RUN MINICONDA_SCRIPT_NAME=Miniconda3-latest-Linux-x86_64.sh; \ +RUN MINICONDA_SCRIPT_NAME=Miniconda3-py311_23.5.2-0-Linux-x86_64.sh; \ + if [ "$python_version" != "3.8" ] && [ "$python_version" != "3.9" ] && [ "$python_version" != "3.10" ] && [ "$python_version" != "3.11" ] && [ "$python_version" != "latest" ]; then \ + echo "python_version '${python_version}' is not supported, please choose among {3.8, 3.9, 3.10, 3.11 or latest (default)}"; \ + exit 1; \ + fi; \ + if [ "${python_version}" = "3.8" ]; then \ + MINICONDA_SCRIPT_NAME=Miniconda3-py38_23.5.2-0-Linux-x86_64.sh; \ + elif [ "${python_version}" = "3.9" ]; then \ + MINICONDA_SCRIPT_NAME=Miniconda3-py39_23.5.2-0-Linux-x86_64.sh; \ + elif [ "${python_version}" = "3.10" ]; then \ + MINICONDA_SCRIPT_NAME=Miniconda3-py310_23.5.2-0-Linux-x86_64.sh; \ + elif [ "${python_version}" = "3.11" ]; then \ + MINICONDA_SCRIPT_NAME=Miniconda3-py311_23.5.2-0-Linux-x86_64.sh; \ + fi; \ + wget -c -q https://repo.continuum.io/miniconda/${MINICONDA_SCRIPT_NAME} && \ + mv ./${MINICONDA_SCRIPT_NAME} ~/${MINICONDA_SCRIPT_NAME} && \ + chmod +x ~/${MINICONDA_SCRIPT_NAME} && \ + bash ~/${MINICONDA_SCRIPT_NAME} -b -p /opt/conda && \ + rm ~/${MINICONDA_SCRIPT_NAME} && \ + /opt/conda/bin/conda upgrade --all && \ + /opt/conda/bin/conda install conda-build conda-verify && \ + /opt/conda/bin/conda clean -ya # Optionally install HIP dependencies # Note that amd's docs say to also install the `hip-runtime-nvidia` package. This @@ -31,13 +47,36 @@ RUN wget -c -q https://repo.continuum.io/miniconda/Miniconda3-latest-Linux-x86_6 # in the container. It also attempts to install packages for a graphical install. # For our container, we don't need `hip-runtime-nvidia` ARG FF_GPU_BACKEND "cuda" +ARG hip_version "5.6" +ARG N_BUILD_CORES +# set MAKEFLAGS to speedup any dependency that uses make +ENV MAKEFLAGS "${MAKEFLAGS} -j${N_BUILD_CORES}" + RUN if [ "$FF_GPU_BACKEND" = "hip_cuda" ] || [ "$FF_GPU_BACKEND" = "hip_rocm" ]; then \ echo "FF_GPU_BACKEND: ${FF_GPU_BACKEND}. Installing HIP dependencies"; \ - wget https://repo.radeon.com/amdgpu-install/22.20.5/ubuntu/bionic/amdgpu-install_22.20.50205-1_all.deb; \ - apt-get install -y ./amdgpu-install_22.20.50205-1_all.deb; \ - rm ./amdgpu-install_22.20.50205-1_all.deb; \ + # Check that hip_version is one of 5.3,5.4,5.5,5.6 + if [ "$hip_version" != "5.3" ] && [ "$hip_version" != "5.4" ] && [ "$hip_version" != "5.5" ] && [ "$hip_version" != "5.6" ]; then \ + echo "hip_version '${hip_version}' is not supported, please choose among {5.3, 5.4, 5.5, 5.6}"; \ + exit 1; \ + fi; \ + # Compute script name and url given the version + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.6.50600-1_all.deb; \ + if [ "$hip_version" = "5.3" ]; then \ + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.3.50300-1_all.deb; \ + elif [ "$hip_version" = "5.4" ]; then \ + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.4.50400-1_all.deb; \ + elif [ "$hip_version" = "5.5" ]; then \ + AMD_GPU_SCRIPT_NAME=amdgpu-install_5.5.50500-1_all.deb; \ + fi; \ + AMD_GPU_SCRIPT_URL="https://repo.radeon.com/amdgpu-install/${hip_version}/ubuntu/focal/${AMD_GPU_SCRIPT_NAME}"; \ + # Download and install AMD GPU software with ROCM and HIP support + wget $AMD_GPU_SCRIPT_URL; \ + apt-get install -y ./${AMD_GPU_SCRIPT_NAME}; \ + rm ./${AMD_GPU_SCRIPT_NAME}; \ amdgpu-install -y --usecase=hip,rocm --no-dkms; \ - apt-get install -y hip-dev hipblas miopen-hip rocm-hip-sdk; \ + apt-get install -y hip-dev hipblas miopen-hip rocm-hip-sdk rocm-device-libs; \ + # Install protobuf dependencies + apt-get update -y && sudo apt-get install -y pkg-config zip g++ zlib1g-dev autoconf automake libtool make; \ else \ echo "FF_GPU_BACKEND: ${FF_GPU_BACKEND}. Skipping installing HIP dependencies"; \ fi @@ -51,8 +90,12 @@ ENV CUDA_DIR /usr/local/cuda # Install python packages and other dependencies RUN conda install -c conda-forge cmake make pillow cmake-build-extension pybind11 numpy pandas keras-preprocessing # Install CPU-only Pytorch and related dependencies -RUN conda install pytorch torchvision torchaudio cpuonly -c pytorch -RUN conda install -c conda-forge onnx transformers sentencepiece -RUN pip3 install tensorflow +RUN conda install pytorch torchvision torchaudio -c pytorch +RUN conda install -c conda-forge onnx transformers>=4.31.0 sentencepiece einops +RUN pip3 install tensorflow notebook + +# Install Rust +RUN curl https://sh.rustup.rs -sSf | sh -s -- -y +ENV PATH /root/.cargo/bin:$PATH ENTRYPOINT ["/bin/bash"] diff --git a/docker/flexflow/Dockerfile b/docker/flexflow/Dockerfile index 0cda5cbc18..60f9d4d653 100644 --- a/docker/flexflow/Dockerfile +++ b/docker/flexflow/Dockerfile @@ -1,6 +1,6 @@ ARG FF_GPU_BACKEND "cuda" -ARG cuda_version "" -FROM flexflow-environment-$FF_GPU_BACKEND$cuda_version:latest +ARG gpu_backend_version "" +FROM flexflow-environment-$FF_GPU_BACKEND$gpu_backend_version:latest LABEL org.opencontainers.image.source=https://github.com/flexflow/FlexFlow LABEL org.opencontainers.image.description="FlexFlow container" @@ -15,6 +15,15 @@ COPY . . ARG BUILD_CONFIGS ARG N_BUILD_CORES +# Create install directory if needed +RUN for pair in $BUILD_CONFIGS; do \ + key=${pair%%=*}; \ + value=${pair#*=}; \ + if [ "$key" = "INSTALL_DIR" ] && [ -n "$value" ]; then \ + mkdir -p "$value"; \ + fi; \ + done + # Build and install C++ and Python versions of FlexFlow RUN mkdir -p build && cd build && \ eval "$BUILD_CONFIGS" ../config/config.linux && \ diff --git a/docker/publish.sh b/docker/publish.sh index b8668d3c0e..c70419a9cc 100755 --- a/docker/publish.sh +++ b/docker/publish.sh @@ -2,7 +2,7 @@ set -euo pipefail # Usage: ./publish.sh -# Optional environment variables: FF_GPU_BACKEND, cuda_version +# Optional environment variables: FF_GPU_BACKEND, cuda_version, hip_version # Cd into directory holding this script cd "${BASH_SOURCE[0]%/*}" @@ -11,6 +11,7 @@ cd "${BASH_SOURCE[0]%/*}" image=${1:-flexflow} FF_GPU_BACKEND=${FF_GPU_BACKEND:-cuda} cuda_version=${cuda_version:-"empty"} +hip_version=${hip_version:-"empty"} # Check docker image name if [[ "${image}" != @(flexflow-environment|flexflow) ]]; then @@ -18,6 +19,9 @@ if [[ "${image}" != @(flexflow-environment|flexflow) ]]; then exit 1 fi +# gpu backend version suffix for the docker image. +gpu_backend_version="" + # Check GPU backend if [[ "${FF_GPU_BACKEND}" != @(cuda|hip_cuda|hip_rocm|intel) ]]; then echo "Error, value of FF_GPU_BACKEND (${FF_GPU_BACKEND}) is invalid. Pick between 'cuda', 'hip_cuda', 'hip_rocm' or 'intel'." @@ -31,25 +35,50 @@ fi if [[ "${FF_GPU_BACKEND}" == "cuda" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then # Autodetect cuda version if not specified if [[ $cuda_version == "empty" ]]; then - cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}') + # shellcheck disable=SC2015 + cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}' || true) # Change cuda_version eg. V11.7.99 to 11.7 cuda_version=${cuda_version:1:4} + if [[ -z "$cuda_version" ]]; then + echo "Could not detect CUDA version. Please specify one manually by setting the 'cuda_version' env." + exit 1 + fi fi # Check that CUDA version is supported - if [[ "$cuda_version" != @(11.1|11.3|11.7|11.2|11.5|11.6|11.8) ]]; then - echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.5|11.6|11.7|11.8}" + if [[ "$cuda_version" != @(11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0|12.1|12.2) ]]; then + echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0|12.1|12.2}" exit 1 fi # Set cuda version suffix to docker image name echo "Publishing $image docker image with CUDA $cuda_version" - cuda_version="-${cuda_version}" -else - # Empty cuda version suffix for non-CUDA images - cuda_version="" + gpu_backend_version="-${cuda_version}" +fi + +if [[ "${FF_GPU_BACKEND}" == "hip_rocm" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then + # Autodetect HIP version if not specified + if [[ $hip_version == "empty" ]]; then + # shellcheck disable=SC2015 + hip_version=$(command -v hipcc >/dev/null 2>&1 && hipcc --version | grep "HIP version:" | awk '{print $NF}' || true) + # Change hip_version eg. 5.6.31061-8c743ae5d to 5.6 + hip_version=${hip_version:0:3} + if [[ -z "$hip_version" ]]; then + echo "Could not detect HIP version. Please specify one manually by setting the 'hip_version' env." + exit 1 + fi + fi + # Check that HIP version is supported + if [[ "$hip_version" != @(5.3|5.4|5.5|5.6) ]]; then + echo "hip_version is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + echo "Pubilishing $image docker image with HIP $hip_version" + if [[ "${FF_GPU_BACKEND}" == "hip_rocm" ]]; then + gpu_backend_version="-${hip_version}" + fi fi # Check that image exists -docker image inspect "${image}-${FF_GPU_BACKEND}${cuda_version}":latest > /dev/null +docker image inspect "${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest > /dev/null # Log into container registry FLEXFLOW_CONTAINER_TOKEN=${FLEXFLOW_CONTAINER_TOKEN:-} @@ -59,8 +88,8 @@ echo "$FLEXFLOW_CONTAINER_TOKEN" | docker login ghcr.io -u flexflow --password-s # Tag image to be uploaded git_sha=${GITHUB_SHA:-$(git rev-parse HEAD)} if [ -z "$git_sha" ]; then echo "Commit hash cannot be detected, cannot publish the docker image to ghrc.io"; exit; fi -docker tag "${image}-${FF_GPU_BACKEND}${cuda_version}":latest ghcr.io/flexflow/"${image}-${FF_GPU_BACKEND}${cuda_version}":latest +docker tag "${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest ghcr.io/flexflow/"${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest # Upload image -docker push ghcr.io/flexflow/"${image}-${FF_GPU_BACKEND}${cuda_version}":latest +docker push ghcr.io/flexflow/"${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest diff --git a/docker/pull.sh b/docker/pull.sh index f8624a1072..f641e1a591 100755 --- a/docker/pull.sh +++ b/docker/pull.sh @@ -2,7 +2,7 @@ set -euo pipefail # Usage: ./pull.sh -# Optional environment variables: FF_GPU_BACKEND, cuda_version +# Optional environment variables: FF_GPU_BACKEND, cuda_version, hip_version # Cd into directory holding this script cd "${BASH_SOURCE[0]%/*}" @@ -11,6 +11,7 @@ cd "${BASH_SOURCE[0]%/*}" image=${1:-flexflow} FF_GPU_BACKEND=${FF_GPU_BACKEND:-cuda} cuda_version=${cuda_version:-"empty"} +hip_version=${hip_version:-"empty"} # Check docker image name if [[ "${image}" != @(flexflow-environment|flexflow) ]]; then @@ -28,31 +29,63 @@ else echo "Downloading $image docker image with default GPU backend: cuda" fi +# gpu backend version suffix for the docker image. +gpu_backend_version="" + if [[ "${FF_GPU_BACKEND}" == "cuda" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then # Autodetect cuda version if not specified if [[ $cuda_version == "empty" ]]; then - cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}') + # shellcheck disable=SC2015 + cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}' || true) # Change cuda_version eg. V11.7.99 to 11.7 cuda_version=${cuda_version:1:4} + if [[ -z "$cuda_version" ]]; then + echo "Could not detect CUDA version. Please specify one manually by setting the 'cuda_version' env." + exit 1 + fi fi # Check that CUDA version is supported - if [[ "$cuda_version" != @(11.1|11.3|11.7|11.2|11.5|11.6|11.8) ]]; then - echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.5|11.6|11.7|11.8}" + if [[ "$cuda_version" != @(11.1|11.6|11.7|11.8|12.0|12.1|12.2) ]]; then + echo "cuda_version is not available for download, please choose among {11.1|11.6|11.7|11.8|12.0|12.1|12.2}" exit 1 fi + # Use CUDA 12.2 for all versions greater or equal to 12.2 for now + if [[ "$cuda_version" == @(12.3|12.4|12.5|12.6|12.7|12.8|12.9) ]]; then + cuda_version=12.2 + fi # Set cuda version suffix to docker image name echo "Downloading $image docker image with CUDA $cuda_version" - cuda_version="-${cuda_version}" -else - # Empty cuda version suffix for non-CUDA images - cuda_version="" + gpu_backend_version="-${cuda_version}" +fi + +if [[ "${FF_GPU_BACKEND}" == "hip_rocm" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then + # Autodetect HIP version if not specified + if [[ $hip_version == "empty" ]]; then + # shellcheck disable=SC2015 + hip_version=$(command -v hipcc >/dev/null 2>&1 && hipcc --version | grep "HIP version:" | awk '{print $NF}' || true) + # Change hip_version eg. 5.6.31061-8c743ae5d to 5.6 + hip_version=${hip_version:0:3} + if [[ -z "$hip_version" ]]; then + echo "Could not detect HIP version. Please specify one manually by setting the 'hip_version' env." + exit 1 + fi + fi + # Check that HIP version is supported + if [[ "$hip_version" != @(5.3|5.4|5.5|5.6) ]]; then + echo "hip_version is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + echo "Downloading $image docker image with HIP $hip_version" + if [[ "${FF_GPU_BACKEND}" == "hip_rocm" ]]; then + gpu_backend_version="-${hip_version}" + fi fi # Download image -docker pull ghcr.io/flexflow/"$image-${FF_GPU_BACKEND}${cuda_version}" +docker pull ghcr.io/flexflow/"$image-${FF_GPU_BACKEND}${gpu_backend_version}" # Tag downloaded image -docker tag ghcr.io/flexflow/"$image-${FF_GPU_BACKEND}${cuda_version}":latest "$image-${FF_GPU_BACKEND}${cuda_version}":latest +docker tag ghcr.io/flexflow/"$image-${FF_GPU_BACKEND}${gpu_backend_version}":latest "$image-${FF_GPU_BACKEND}${gpu_backend_version}":latest # Check that image exists -docker image inspect "${image}-${FF_GPU_BACKEND}${cuda_version}":latest > /dev/null +docker image inspect "${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest > /dev/null diff --git a/docker/run.sh b/docker/run.sh index 307628f4fd..666c8e1121 100755 --- a/docker/run.sh +++ b/docker/run.sh @@ -2,7 +2,7 @@ set -euo pipefail # Usage: ./run.sh -# Optional environment variables: FF_GPU_BACKEND, cuda_version, ATTACH_GPUS, SHM_SIZE +# Optional environment variables: FF_GPU_BACKEND, cuda_version, hip_version, ATTACH_GPUS, SHM_SIZE # Cd into directory holding this script cd "${BASH_SOURCE[0]%/*}" @@ -11,12 +11,16 @@ cd "${BASH_SOURCE[0]%/*}" image=${1:-flexflow} FF_GPU_BACKEND=${FF_GPU_BACKEND:-cuda} cuda_version=${cuda_version:-"empty"} +hip_version=${hip_version:-"empty"} # Parameter controlling whether to attach GPUs to the Docker container ATTACH_GPUS=${ATTACH_GPUS:-true} gpu_arg="" if $ATTACH_GPUS ; then gpu_arg="--gpus all" ; fi +# Whether to attach inference weights / files (make sure to download the weights first) +ATTACH_INFERENCE_FILES=${ATTACH_INFERENCE_FILES:-false} + # Amount of shared memory to give the Docker container access to # If you get a Bus Error, increase this value. If you don't have enough memory # on your machine, decrease this value. @@ -38,35 +42,82 @@ else echo "Running $image docker image with default GPU backend: cuda" fi +# gpu backend version suffix for the docker image. +gpu_backend_version="" + if [[ "${FF_GPU_BACKEND}" == "cuda" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then # Autodetect cuda version if not specified if [[ $cuda_version == "empty" ]]; then - cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}') + # shellcheck disable=SC2015 + cuda_version=$(command -v nvcc >/dev/null 2>&1 && nvcc --version | grep "release" | awk '{print $NF}' || true) # Change cuda_version eg. V11.7.99 to 11.7 cuda_version=${cuda_version:1:4} + if [[ -z "$cuda_version" ]]; then + echo "Could not detect CUDA version. Please specify one manually by setting the 'cuda_version' env." + exit 1 + fi fi # Check that CUDA version is supported - if [[ "$cuda_version" != @(11.1|11.3|11.7|11.2|11.5|11.6|11.8) ]]; then - echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.5|11.6|11.7|11.8}" + if [[ "$cuda_version" != @(11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0|12.1|12.2) ]]; then + echo "cuda_version is not supported, please choose among {11.1|11.2|11.3|11.4|11.5|11.6|11.7|11.8|12.0|12.1|12.2}" exit 1 fi + # Use CUDA 12.2 for all versions greater or equal to 12.2 for now + if [[ "$cuda_version" == @(12.3|12.4|12.5|12.6|12.7|12.8|12.9) ]]; then + cuda_version=12.2 + fi # Set cuda version suffix to docker image name echo "Running $image docker image with CUDA $cuda_version" - cuda_version_hyphen="-${cuda_version}" -else - # Empty cuda version suffix for non-CUDA images - cuda_version_hyphen="" + gpu_backend_version="-${cuda_version}" +fi + +if [[ "${FF_GPU_BACKEND}" == "hip_rocm" || "${FF_GPU_BACKEND}" == "hip_cuda" ]]; then + # Autodetect HIP version if not specified + if [[ $hip_version == "empty" ]]; then + # shellcheck disable=SC2015 + hip_version=$(command -v hipcc >/dev/null 2>&1 && hipcc --version | grep "HIP version:" | awk '{print $NF}' || true) + # Change hip_version eg. 5.6.31061-8c743ae5d to 5.6 + hip_version=${hip_version:0:3} + if [[ -z "$hip_version" ]]; then + echo "Could not detect HIP version. Please specify one manually by setting the 'hip_version' env." + exit 1 + fi + fi + # Check that HIP version is supported + if [[ "$hip_version" != @(5.3|5.4|5.5|5.6) ]]; then + echo "hip_version is not supported, please choose among {5.3, 5.4, 5.5, 5.6}" + exit 1 + fi + echo "Running $image docker image with HIP $hip_version" + if [[ "${FF_GPU_BACKEND}" == "hip_rocm" ]]; then + gpu_backend_version="-${hip_version}" + fi fi # Check that image exists, if fails, print the default error message. -if [[ "$(docker images -q "$image"-"$FF_GPU_BACKEND""$cuda_version_hyphen":latest 2> /dev/null)" == "" ]]; then - echo "" - echo "To download the docker image, run:" - echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} cuda_version=${cuda_version} $(pwd)/pull.sh $image" - echo "To build the docker image from source, run:" - echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} cuda_version=${cuda_version} $(pwd)/build.sh $image" - echo "" +if [[ "$(docker images -q "${image}-${FF_GPU_BACKEND}${gpu_backend_version}":latest 2> /dev/null)" == "" ]]; then + echo "Error, ${image}-${FF_GPU_BACKEND}${gpu_backend_version}:latest does not exist!" + if [[ "${FF_GPU_BACKEND}" == "cuda" ]]; then + echo "" + echo "To download the docker image, run:" + echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} cuda_version=${cuda_version} $(pwd)/pull.sh $image" + echo "To build the docker image from source, run:" + echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} cuda_version=${cuda_version} $(pwd)/build.sh $image" + echo "" + elif [[ "${FF_GPU_BACKEND}" == "hip_rocm" ]]; then + echo "" + echo "To download the docker image, run:" + echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} hip_version=${hip_version} $(pwd)/pull.sh $image" + echo "To build the docker image from source, run:" + echo " FF_GPU_BACKEND=${FF_GPU_BACKEND} hip_version=${hip_version} $(pwd)/build.sh $image" + echo "" + fi exit 1 fi -eval docker run -it "$gpu_arg" "--shm-size=${SHM_SIZE}" "${image}-${FF_GPU_BACKEND}${cuda_version_hyphen}:latest" +inference_volumes="" +if $ATTACH_INFERENCE_FILES ; then + inference_volumes="-v ~/.cache/flexflow:/usr/FlexFlow/inference"; +fi + +eval docker run -it "$gpu_arg" "--shm-size=${SHM_SIZE}" "${inference_volumes}" "${image}-${FF_GPU_BACKEND}${gpu_backend_version}:latest" diff --git a/docs/Makefile b/docs/Makefile index 5424c5bc9f..d14c2ef91f 100644 --- a/docs/Makefile +++ b/docs/Makefile @@ -15,7 +15,7 @@ help: .PHONY: help Makefile clean clean: - rm -rf build source/_doxygen/ source/c++_api/ doxygen/output + rm -rf build doxygen/output doxygen/cpp_api @$(SPHINXBUILD) -M clean "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O) # Catch-all target: route all unknown targets to Sphinx using the new diff --git a/docs/doxygen/Doxyfile b/docs/doxygen/Doxyfile index b38bfc12b5..aafa65d79b 100644 --- a/docs/doxygen/Doxyfile +++ b/docs/doxygen/Doxyfile @@ -44,7 +44,7 @@ PROJECT_NUMBER = # for a project that appears at the top of each page and should give viewer a # quick idea about the purpose of the project. Keep the description short. -PROJECT_BRIEF = A distributed deep learning framework that supports flexible parallelization strategies. +PROJECT_BRIEF = "A distributed deep learning framework that supports flexible parallelization strategies." # With the PROJECT_LOGO tag one can specify a logo or an icon that is included # in the documentation. The maximum height of the logo should not exceed 55 @@ -150,7 +150,7 @@ INLINE_INHERITED_MEMB = NO # shortest path that makes the file name unique will be used # The default value is: YES. -FULL_PATH_NAMES = YES +FULL_PATH_NAMES = NO # The STRIP_FROM_PATH tag can be used to strip a user-defined part of the path. # Stripping is only done if one of the specified strings matches the left-hand @@ -874,12 +874,7 @@ WARN_LOGFILE = # spaces. See also FILE_PATTERNS and EXTENSION_MAPPING # Note: If this tag is empty the current directory is searched. -INPUT = $(FF_HOME)/align -INPUT += $(FF_HOME)/bootcamp_demo -INPUT += $(FF_HOME)/examples INPUT += $(FF_HOME)/include -INPUT += $(FF_HOME)/nmt -INPUT += $(FF_HOME)/python INPUT += $(FF_HOME)/src # This tag can be used to specify the character encoding of the source files @@ -911,12 +906,10 @@ INPUT_ENCODING = UTF-8 FILE_PATTERNS = *.c \ *.cc \ - *.cpp \ *.cu \ + *.cpp \ *.h \ - *.hpp \ - *.md \ - *.py + *.hpp # The RECURSIVE tag can be used to specify whether or not subdirectories should # be searched for input files as well. @@ -2110,7 +2103,7 @@ MAN_LINKS = NO # captures the structure of the code including all documentation. # The default value is: NO. -GENERATE_XML = YES +GENERATE_XML = NO # The XML_OUTPUT tag is used to specify where the XML pages will be put. If a # relative path is entered the value of OUTPUT_DIRECTORY will be put in front of diff --git a/docs/source/chatbot.rst b/docs/source/chatbot.rst new file mode 100644 index 0000000000..c41307e231 --- /dev/null +++ b/docs/source/chatbot.rst @@ -0,0 +1,64 @@ +:tocdepth: 1 +******** +Chatbot +******** + +The chatbot use case involves setting up a conversational AI model using FlexFlow Serve, capable of engaging in interactive dialogues with users. + +Requirements +============ + +- FlexFlow Serve setup with required configurations. +- Gradio or any interactive interface tool. + +Implementation +============== + +1. FlexFlow Initialization + Initialize FlexFlow Serve with desired configurations and specific LLM model. + +2. Gradio Interface Setup + Define a function for response generation based on user inputs. Setup Gradio Chat Interface for interaction. + + .. code-block:: python + + def generate_response(user_input): + result = llm.generate(user_input) + return result.output_text.decode('utf-8') + + +3. Running the Interface + Launch the Gradio interface and interact with the model by entering text inputs. + + .. image:: /imgs/gradio_interface.png + :alt: Gradio Chatbot Interface + :align: center + +4. Shutdown + Stop the FlexFlow server after interaction. + +Example +======= + +Complete code example can be found here: + +1. `Chatbot Example with incremental decoding `__ + +2. `Chatbot Example with speculative inference `__ + + +Example Implementation: + + .. code-block:: python + + import gradio as gr + import flexflow.serve as ff + + ff.init(num_gpus=2, memory_per_gpu=14000, ...) + + def generate_response(user_input): + result = llm.generate(user_input) + return result.output_text.decode('utf-8') + + iface = gr.ChatInterface(fn=generate_response) + iface.launch() \ No newline at end of file diff --git a/docs/source/conf.py b/docs/source/conf.py index 0e614f37c2..f67c0dae01 100644 --- a/docs/source/conf.py +++ b/docs/source/conf.py @@ -13,28 +13,42 @@ import os import sys import subprocess +import shutil +import sphinx # only needed for the manual post processing +from pathlib import Path +from m2r2 import convert +from docutils.core import publish_string +import re def get_parent_dir_path(path): return os.path.abspath(os.path.join(path, "..")) docs_path = get_parent_dir_path(os.path.dirname(os.path.abspath(__file__))) doxygen_path = os.path.join(docs_path, "doxygen") +doxygen_output = os.path.join(doxygen_path, "output") +doxygen_cpp_api_out = os.path.join(doxygen_path, "cpp_api") FF_HOME = get_parent_dir_path(docs_path) python_package_path = os.path.join(FF_HOME, "python") sys.path.insert(0, os.path.abspath(python_package_path)) # Build the Doxygen docs -#subprocess.call(f'cd {doxygen_path}; FF_HOME={FF_HOME} doxygen', shell=True) +shutil.rmtree(doxygen_cpp_api_out, ignore_errors=True) +for gpu_backend in ("cuda", "hip"): + doxygen_dest = os.path.join(doxygen_cpp_api_out, f"{gpu_backend}_api") + os.makedirs(doxygen_dest, exist_ok=True) + exclude_extension = ".cu" if gpu_backend == "hip" else ".cpp" + doxygen_cmd = f'export FF_HOME={FF_HOME}; ( cat Doxyfile ; echo "EXCLUDE_PATTERNS+=*{exclude_extension}" ) | doxygen -' + subprocess.check_call(doxygen_cmd, cwd=doxygen_path, shell=True) + subprocess.check_call(f'mv {os.path.join(doxygen_output, "html")}/* {doxygen_dest}/', shell=True) import sphinx_rtd_theme # -- Project information ----------------------------------------------------- project = 'FlexFlow' -copyright = '2020, Stanford, LANL, CMU, Facebook' -author = 'Stanford, LANL, CMU, Facebook' - +copyright = '2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical)' +author = 'CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical)' # -- General configuration --------------------------------------------------- @@ -45,8 +59,6 @@ def get_parent_dir_path(path): 'sphinx_rtd_theme', 'sphinx.ext.autodoc', 'm2r2', - 'breathe', - 'exhale', ] # Theme options are theme-specific and customize the look and feel of a theme @@ -55,6 +67,7 @@ def get_parent_dir_path(path): html_theme_options = { "collapse_navigation" : False } +html_extra_path = [doxygen_cpp_api_out] # Add any paths that contain templates here, relative to this directory. # templates_path = ['_templates'] @@ -86,27 +99,50 @@ def get_parent_dir_path(path): # so a file named "default.css" will overwrite the builtin "default.css". # html_static_path = ['_static'] -# Breathe + Exhale configuration -# Setup the breathe extension -breathe_projects = { - "FlexFlow": "./_doxygen/xml" -} -breathe_default_project = "FlexFlow" - -c_plus_plus_src_dirs = " ".join([f"\"{os.path.join(FF_HOME, 'src', dirname)}\"" for dirname in ("loss_functions", "mapper", "metrics_functions", "ops", "parallel_ops", "recompile", "runtime", "utils")]) -# Setup the exhale extension -exhale_args = { - # These arguments are required - "containmentFolder": "./c++_api", - "rootFileName": "c++_api_root.rst", - "doxygenStripFromPath": "..", - # Heavily encouraged optional argument (see docs) - #"rootFileTitle": "Library API", - # Suggested optional arguments - "createTreeView": True, - # TIP: if using the sphinx-bootstrap-theme, you need - # "treeViewIsBootstrap": True, - "exhaleExecutesDoxygen": True, - "exhaleDoxygenStdin": f'INPUT = {c_plus_plus_src_dirs}' -} +def manual_post_processing(app, exception): + if exception is None and app.builder.name == 'html': # build succeeded + print(f'Post-processing HTML docs at path {app.outdir}') + build_dir = Path(app.outdir) + + # List of subfolders to search + folder_paths = [build_dir, build_dir / 'developers_guide'] + + for folder_path in folder_paths: + + # Only get HTML files in build dir, not subfolders + html_files = folder_path.glob('*.html') + + for html_file in html_files: + content = html_file.read_text() + + # Find dropdown menus, and manually convert their contents + pattern = r'
\nExpand here\n
(.*?)
' + blocks = re.findall(pattern, content, re.DOTALL) + + for block in blocks: + # Convert Markdown to HTML + rst = convert(block, github_markdown=True) + html = publish_string(rst, writer_name='html') + html_str = html.decode('utf-8') + + # Replace block with converted HTML + content = content.replace(block, html_str) + + # Add space after dropdown menu block + content = content.replace('', + '\n

') + + # Replace incorrect links + content = content.replace('href="../docker/README.md"', 'href="docker.html"') + content = content.replace('href="./TRAIN.md"', 'href="train_overview.html"') + content = content.replace('href="./SERVE.md"', 'href="serve_overview.html"') + content = content.replace('href="./docs/source/keras.rst"', 'href="keras.html"') + content = content.replace('href="./docs/source/onnx.rst"', 'href="onnx.html"') + + + html_file.write_text(content) + + +def setup(app): + app.connect('build-finished', manual_post_processing) diff --git a/docs/source/cpp_api.rst b/docs/source/cpp_api.rst new file mode 100644 index 0000000000..b5d39be62e --- /dev/null +++ b/docs/source/cpp_api.rst @@ -0,0 +1,10 @@ +************* +C++ API +************* + +The FlexFlow backend is at the core of FlexFlow Train and FlexFlow Serve. It is written entirely in C/C++ and CUDA/HIP. This section documents the API, which is generated by Doxygen and it is available at the following links: + +* `CUDA version <./cuda_api/index.html>`_ (default version) +* `HIP version <./hip_api/index.html>`_ + +The two versions only differ when it comes to the GPU kernels, so the great majority of the entries are identical. If you are unsure which version to use, take a look at the CUDA version. diff --git a/docs/source/developers_guide.rst b/docs/source/developers_guide/developers_guide.rst similarity index 64% rename from docs/source/developers_guide.rst rename to docs/source/developers_guide/developers_guide.rst index 107135fae4..a125e60460 100644 --- a/docs/source/developers_guide.rst +++ b/docs/source/developers_guide/developers_guide.rst @@ -2,5 +2,5 @@ Developers Guide ****************** -.. mdinclude:: ../../CONTRIBUTING.md +.. mdinclude:: ../../../CONTRIBUTING.md :start-line: 2 diff --git a/docs/source/developers_guide/ff_internals.rst b/docs/source/developers_guide/ff_internals.rst new file mode 100644 index 0000000000..15c0804255 --- /dev/null +++ b/docs/source/developers_guide/ff_internals.rst @@ -0,0 +1,6 @@ +******************* +FlexFlow Internals +******************* + +.. mdinclude:: internals.md + :start-line: 2 diff --git a/docs/source/developers_guide/internals.md b/docs/source/developers_guide/internals.md new file mode 100644 index 0000000000..243b14a174 --- /dev/null +++ b/docs/source/developers_guide/internals.md @@ -0,0 +1,15 @@ +# FlexFlow Internals + +## The Parallel Computation Graph (PCG) + +FlexFlow uses a _Parallel Computation Graph (PCG)_ to simultaneously represent tensor operations, as well as parallelism choices and data movement across nodes. + +### Tensor representations + +There are two types of tensor representations in FlexFlow: a [Tensor](./cuda_api/de/da9/structFlexFlow_1_1TensorBase.html) and a [ParallelTensor](./cuda_api/d3/dfc/structFlexFlow_1_1ParallelTensorBase.html). The first variant is used when writing a FlexFlow DNN program, whereas the second is used by the runtime to run all the computations in a distributed fashion. `Tensor` and `ParallelTensor` are implemented as typedef-ed pointers to, respectively, the `TensorBase` (defined in `include/flexflow/tensor.h`) and `ParallelTensorBase` (defined in `include/flexflow/parallel_tensor.h`) structs. + +The `ParallelTensor` struct contains all the information that a `Tensor` also stores, but in addition, it also codifies how the tensor should be parallelized. For instance, a ParallelTensor records how each dimension is *partitioned*, how many *replicas* of the tensors have been created, and the *mapping* between the partitions of the tensors and the physical machines that will store them. + +## Transformation generation + +## Joint optimization diff --git a/docs/source/docker.rst b/docs/source/docker.rst index 4a457a8dcc..63f84e460c 100644 --- a/docs/source/docker.rst +++ b/docs/source/docker.rst @@ -1,3 +1,4 @@ +:tocdepth: 1 ************* Docker ************* diff --git a/docs/source/imgs/gradio_api.png b/docs/source/imgs/gradio_api.png new file mode 100644 index 0000000000..7bf1b99a5e Binary files /dev/null and b/docs/source/imgs/gradio_api.png differ diff --git a/docs/source/imgs/gradio_interface.png b/docs/source/imgs/gradio_interface.png new file mode 100644 index 0000000000..9584d76fb3 Binary files /dev/null and b/docs/source/imgs/gradio_interface.png differ diff --git a/docs/source/index.rst b/docs/source/index.rst index 7af62e417e..6aa47d157b 100644 --- a/docs/source/index.rst +++ b/docs/source/index.rst @@ -7,47 +7,40 @@ Welcome to FlexFlow's documentation! ==================================== .. toctree:: - :maxdepth: 2 :caption: Getting Started welcome installation docker - jupyter + multinode .. toctree:: - :maxdepth: 2 - :caption: Interoperability + :caption: FlexFlow Serve - keras - pytorch - onnx + serve_overview + serve_usecases + serve_api .. toctree:: - :maxdepth: 2 - :caption: Examples - - mt5 + :caption: FlexFlow Train -.. toctree:: - :maxdepth: 3 - :caption: Python API + train_overview + train_interface + train_examples - python/models - python/layers - python/dataloader + train_python_api .. toctree:: - :maxdepth: 2 - :caption: C++ API + :caption: FlexFlow Backend - c++_api/c++_api_root + cpp_api .. toctree:: - :maxdepth: 2 + :maxdepth: 3 :caption: Developers Guide - developers_guide + developers_guide/developers_guide.rst +.. developers_guide/ff_internals.rst .. Indices and tables diff --git a/docs/source/installation.rst b/docs/source/installation.rst index 109b546834..95ec8596e6 100644 --- a/docs/source/installation.rst +++ b/docs/source/installation.rst @@ -1,5 +1,6 @@ +:tocdepth: 1 ************* -Installing FlexFlow +Building from source ************* .. mdinclude:: ../../INSTALL.md diff --git a/docs/source/jupyter.rst b/docs/source/jupyter.rst deleted file mode 100644 index 2e37bfb183..0000000000 --- a/docs/source/jupyter.rst +++ /dev/null @@ -1,6 +0,0 @@ -***************** -Jupyter Notebook -***************** - -.. mdinclude:: ../../jupyter_notebook/README.md - :start-line: 2 diff --git a/docs/source/keras.rst b/docs/source/keras.rst index eb4f2d7fa7..f1c0743c70 100644 --- a/docs/source/keras.rst +++ b/docs/source/keras.rst @@ -1,6 +1,7 @@ -************* -Keras Support -************* +:tocdepth: 1 +**************** +Keras Interface +**************** FlexFlow provides a drop-in replacement for TensorFlow Keras. Running an existing Keras program on the FlexFlow backend only requires a few lines of changes to the program. The detailed instructions are as follows: diff --git a/docs/source/mt5.rst b/docs/source/mt5.rst index c9c3af080a..8a632b90d6 100644 --- a/docs/source/mt5.rst +++ b/docs/source/mt5.rst @@ -1,6 +1,6 @@ -**************** -HuggingFace mT5 -**************** +************************ +mT5 Model +************************ .. mdinclude:: ../../examples/python/pytorch/mt5/README.md :start-line: 2 diff --git a/docs/source/multinode.rst b/docs/source/multinode.rst new file mode 100644 index 0000000000..8827200582 --- /dev/null +++ b/docs/source/multinode.rst @@ -0,0 +1,8 @@ +:tocdepth: 1 +****************** +Multinode tutorial +****************** + + +.. mdinclude:: ../../MULTI-NODE.md + :start-line: 3 diff --git a/docs/source/onnx.rst b/docs/source/onnx.rst index 91b314ac96..b6bc49b146 100644 --- a/docs/source/onnx.rst +++ b/docs/source/onnx.rst @@ -1,3 +1,4 @@ +:tocdepth: 1 ************* ONNX Support ************* diff --git a/docs/source/prompt_template.rst b/docs/source/prompt_template.rst new file mode 100644 index 0000000000..7f987b0f18 --- /dev/null +++ b/docs/source/prompt_template.rst @@ -0,0 +1,55 @@ +:tocdepth: 1 +**************** +Prompt Template +**************** + +Prompt templates guide the model's response generation. This use case demonstrates setting up FlexFlow Serve to integrate with Langchain and using prompt templates to handle dynamic prompt templates. + +Requirements +============ + +- FlexFlow Serve setup with appropriate configurations. +- Langchain integration with templates for prompt management. + +Implementation +============== + +1. FlexFlow Initialization + Initialize and configure FlexFlow Serve. + +2. LLM Setup + Compile and start the server for text generation. + +3. Prompt Template Setup + Setup a prompt template for guiding model's responses. + +4. Response Generation + Use the LLM with the prompt template to generate a response. + +5. Shutdown + Stop the FlexFlow server after generating the response. + +Example +======= + +Complete code example can be found here: + +1. `Prompt Template Example with incremental decoding `__ + +2. `Prompt Template Example with speculative inference `__ + + +Example Implementation: + + .. code-block:: python + + import flexflow.serve as ff + from langchain.prompts import PromptTemplate + + ff_llm = FlexFlowLLM(...) + ff_llm.compile_and_start(...) + + template = "Question: {question}\nAnswer:" + prompt = PromptTemplate(template=template, input_variables=["question"]) + + response = ff_llm.generate("Who was the US president in 1997?") diff --git a/docs/source/pytorch.rst b/docs/source/pytorch.rst index a6d4e23311..3dbe337d55 100644 --- a/docs/source/pytorch.rst +++ b/docs/source/pytorch.rst @@ -1,6 +1,7 @@ -*************** -PyTorch Support -*************** +:tocdepth: 1 +****************** +PyTorch Interface +****************** Users can use FlexFlow to optimize the parallelization performance of existing PyTorch models in two steps. The PyTorch support requires the `PyTorch FX module `_, so make sure your PyTorch is up to date. diff --git a/docs/source/rag.rst b/docs/source/rag.rst new file mode 100644 index 0000000000..640b2fe131 --- /dev/null +++ b/docs/source/rag.rst @@ -0,0 +1,90 @@ +:tocdepth: 1 +******** +RAG Q&A +******** + +Retrieval Augmented Generation (RAG) combines language models with external knowledge. This use case integrates RAG with FlexFlow Serve for Q&A with documents. + +Requirements +============ + +- FlexFlow Serve setup. +- Retriever setup for RAG. + +Implementation +============== + +1. FlexFlow Initialization + Initialize and configure FlexFlow Serve. + +2. Data Retrieval Setup + Setup a retriever for sourcing information relevant to user queries. + +3. RAG Integration + Integrate the retriever with FlexFlow Serve. + +4. Response Generation + Use the LLM with RAG to generate responses based on model's knowledge and retrieved information. + +5. Shutdown + The FlexFlow server automatically shuts down after generating the response. + +Example +======= + +A complete code example for a web-document Q&A using FlexFlow can be found here: + +1. `Rag Q&A Example with incremental decoding `__ + +2. `Rag Q&A Example with speculative inference `__ + + +Example Implementation: + + .. code-block:: python + + # imports + + # compile and start server + ff_llm = FlexFlowLLM(...) + gen_config = ff.GenerationConfig(...) + ff_llm.compile_and_start(...) + ff_llm_wrapper = FF_LLM_wrapper(flexflow_llm=ff_llm) + + + # Load web page content + loader = WebBaseLoader("https://example.com/data") + data = loader.load() + + # Split text + text_splitter = RecursiveCharacterTextSplitter(...) + all_splits = text_splitter.split_documents(data) + + # Initialize embeddings + embeddings = OpenAIEmbeddings(...) + + # Create VectorStore + vectorstore = Chroma.from_documents(all_splits, embeddings) + + # Use VectorStore as a retriever + retriever = vectorstore.as_retriever() + + # Apply similarity search + question = "Example Question" + docs = vectorstore.similarity_search(question) + max_chars_per_doc = 100 + docs_text = ''.join([docs[i].page_content[:max_chars_per_doc] for i in range(len(docs))]) + + # Using a Prompt Template + prompt_rag = PromptTemplate.from_template( + "Summarize the main themes in these retrieved docs: {docs_text}" + ) + + # Build Chain + llm_chain_rag = LLMChain(llm=ff_llm_wrapper, prompt=prompt_rag) + + # Run + rag_result = llm_chain_rag(docs_text) + + # Stop the server + ff_llm.stop_server() \ No newline at end of file diff --git a/docs/source/serve_api.rst b/docs/source/serve_api.rst new file mode 100644 index 0000000000..6a607cbf0c --- /dev/null +++ b/docs/source/serve_api.rst @@ -0,0 +1,7 @@ +************************** +FlexFlow Serve Python API +************************** + +.. toctree:: + serve_fastapi + serve_gradioapi \ No newline at end of file diff --git a/docs/source/serve_fastapi.rst b/docs/source/serve_fastapi.rst new file mode 100644 index 0000000000..62a28e5937 --- /dev/null +++ b/docs/source/serve_fastapi.rst @@ -0,0 +1,106 @@ +:tocdepth: 1 +*********************** +FlexFlow Serve FastAPI +*********************** + +Introduction +============ + +The Python API for FlexFlow Serve enables users to initialize, manage and interact with large language models (LLMs) via FastAPI or Gradio. + +Requirements +------------ + +- FlexFlow Serve setup with necessary configurations. +- FastAPI and Uvicorn for running the API server. + +API Configuration +================= + +Users can configure the API using FastAPI to handle requests and manage the model. + +1. FastAPI Application Initialization + Initialize the FastAPI application to create API endpoints. + +2. Request Model Definition + Define the model for API requests using Pydantic. + +3. Global Variable for LLM Model + Declare a global variable to store the LLM model. + +Example +------- + +.. code-block:: python + + from fastapi import FastAPI + from pydantic import BaseModel + import flexflow.serve as ff + + app = FastAPI() + + class PromptRequest(BaseModel): + prompt: str + + llm = None + +Endpoint Creation +================= + +Create API endpoints for LLM interactions to handle generation requests. + +1. Initialize Model on Startup + Use the FastAPI event handler to initialize and compile the LLM model when the API server starts. + +2. Generate Response Endpoint + Create a POST endpoint to generate responses based on the user's prompt. + +Example +------- + +.. code-block:: python + + @app.on_event("startup") + async def startup_event(): + global llm + # Initialize and compile the LLM model + llm.compile( + generation_config, + # ... other params as needed + ) + llm.start_server() + + @app.post("/generate/") + async def generate(prompt_request: PromptRequest): + # ... exception handling + full_output = llm.generate([prompt_request.prompt])[0].output_text.decode('utf-8') + # ... split prompt and response text for returning results + return {"prompt": prompt_request.prompt, "response": full_output} + +Running and Testing +=================== + +Instructions for running and testing the FastAPI server. + +1. Run the FastAPI Server + Use Uvicorn to run the FastAPI server with specified host and port. + +2. Testing the API + Make requests to the API endpoints and verify the responses. + +Example +------- + +.. code-block:: bash + + # Running within the inference/python folder: + uvicorn entrypoint.fastapi_incr:app --reload --port 3000 + +Full API Entrypoint Code +========================= + +A complete code example for a web-document Q&A using FlexFlow can be found here: + +1. `FastAPI Example with incremental decoding `__ + +2. `FastAPI Example with speculative inference `__ diff --git a/docs/source/serve_gradioapi.rst b/docs/source/serve_gradioapi.rst new file mode 100644 index 0000000000..ed19e05347 --- /dev/null +++ b/docs/source/serve_gradioapi.rst @@ -0,0 +1,30 @@ +:tocdepth: 1 +************************* +FlexFlow Serve Gradio API +************************* + +Introduction +============ + +Users can also set up the API endpoints with a Gradio Chatbot Interface. + +Requirements +------------ + +- FlexFlow Serve setup with necessary configurations. +- Running the gradio chatbot interface. + +Example +======== + +In a running gradio chatbot interface, hit the "Use via API" button on the bottom left. + + .. image:: /imgs/gradio_interface.png + :alt: Gradio Chatbot Interface + :align: center + +Users can easily access an API endpoint for sending prompts to the model. + + .. image:: /imgs/gradio_api.png + :alt: Gradio API + :align: center \ No newline at end of file diff --git a/docs/source/serve_overview.rst b/docs/source/serve_overview.rst new file mode 100644 index 0000000000..35c992a853 --- /dev/null +++ b/docs/source/serve_overview.rst @@ -0,0 +1,7 @@ +:tocdepth: 1 +************* +Serving Overview +************* + +.. mdinclude:: ../../SERVE.md + :start-line: 3 diff --git a/docs/source/serve_usecases.rst b/docs/source/serve_usecases.rst new file mode 100644 index 0000000000..4aa3fd2807 --- /dev/null +++ b/docs/source/serve_usecases.rst @@ -0,0 +1,8 @@ +******************* +Serving Usecases +******************* + +.. toctree:: + chatbot + prompt_template + rag \ No newline at end of file diff --git a/docs/source/train_examples.rst b/docs/source/train_examples.rst new file mode 100644 index 0000000000..84d58c3465 --- /dev/null +++ b/docs/source/train_examples.rst @@ -0,0 +1,6 @@ +************* +Training Examples +************* + +.. toctree:: + mt5 \ No newline at end of file diff --git a/docs/source/train_interface.rst b/docs/source/train_interface.rst new file mode 100644 index 0000000000..ce81fc1f3c --- /dev/null +++ b/docs/source/train_interface.rst @@ -0,0 +1,8 @@ +******************* +Training Interface +******************* + +.. toctree:: + keras + pytorch + onnx \ No newline at end of file diff --git a/docs/source/train_overview.rst b/docs/source/train_overview.rst new file mode 100644 index 0000000000..58898ad35c --- /dev/null +++ b/docs/source/train_overview.rst @@ -0,0 +1,7 @@ +:tocdepth: 1 +************* +Training Overview +************* + +.. mdinclude:: ../../TRAIN.md + :start-line: 3 diff --git a/docs/source/train_python_api.rst b/docs/source/train_python_api.rst new file mode 100644 index 0000000000..40451dedf9 --- /dev/null +++ b/docs/source/train_python_api.rst @@ -0,0 +1,11 @@ +******************* +Python API +******************* +This section documents the Python API for FlexFlow Train. + +.. toctree:: + :maxdepth: 3 + + python/models + python/layers + python/dataloader \ No newline at end of file diff --git a/docs/source/welcome.rst b/docs/source/welcome.rst index 8108b1dd67..7f73f15563 100644 --- a/docs/source/welcome.rst +++ b/docs/source/welcome.rst @@ -1,3 +1,4 @@ +:tocdepth: 1 ************* Overview ************* diff --git a/examples/python/keras/callback.py b/examples/python/keras/callback.py index f4ebc03d17..c647822957 100644 --- a/examples/python/keras/callback.py +++ b/examples/python/keras/callback.py @@ -20,6 +20,7 @@ from flexflow.keras.datasets import cifar10 from flexflow.keras import backend as K from accuracy import ModelAccuracy +import flexflow.core as ff import numpy as np @@ -68,4 +69,6 @@ def top_level_task(): if __name__ == "__main__": print("Functional API, cifar10 cnn callback") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/elementwise_max_min.py b/examples/python/keras/elementwise_max_min.py index 95291f1273..52a80b431b 100644 --- a/examples/python/keras/elementwise_max_min.py +++ b/examples/python/keras/elementwise_max_min.py @@ -1,5 +1,6 @@ from flexflow.keras.layers import Dense, Input, Maximum, Minimum import flexflow.keras.optimizers +import flexflow.core as ff import numpy as np @@ -54,7 +55,8 @@ def elementwise_min(): epochs = 2 ) - if __name__ == '__main__': + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) elementwise_max() elementwise_min() diff --git a/examples/python/keras/elementwise_mul_broadcast.py b/examples/python/keras/elementwise_mul_broadcast.py index d68476a6cb..1405871a7a 100644 --- a/examples/python/keras/elementwise_mul_broadcast.py +++ b/examples/python/keras/elementwise_mul_broadcast.py @@ -1,6 +1,6 @@ from flexflow.keras.layers import Dense, Input, Reshape, Multiply import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np def broadcast1(): @@ -92,8 +92,9 @@ def broadcast_both(): epochs = 2 ) - if __name__ == '__main__': + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) broadcast1() broadcast2() broadcast_both() diff --git a/examples/python/keras/func_cifar10_alexnet.py b/examples/python/keras/func_cifar10_alexnet.py index c0ade0b722..a4f8dc61ac 100644 --- a/examples/python/keras/func_cifar10_alexnet.py +++ b/examples/python/keras/func_cifar10_alexnet.py @@ -77,5 +77,7 @@ def top_level_task(): if __name__ == "__main__": print("Functional API, cifar10 alexnet") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn.py b/examples/python/keras/func_cifar10_cnn.py index 423541386f..ce0358da53 100644 --- a/examples/python/keras/func_cifar10_cnn.py +++ b/examples/python/keras/func_cifar10_cnn.py @@ -61,7 +61,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=160, callbacks=[VerifyMetrics(ModelAccuracy.CIFAR10_CNN), EpochVerifyMetrics(ModelAccuracy.CIFAR10_CNN)]) + if __name__ == "__main__": print("Functional API, cifar10 cnn") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn_concat.py b/examples/python/keras/func_cifar10_cnn_concat.py index 72dfdeffaf..4fe0f5ce18 100644 --- a/examples/python/keras/func_cifar10_cnn_concat.py +++ b/examples/python/keras/func_cifar10_cnn_concat.py @@ -75,5 +75,7 @@ def top_level_task(): if __name__ == "__main__": print("Functional API, cifar10 cnn concat") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn_concat_model.py b/examples/python/keras/func_cifar10_cnn_concat_model.py index 39885bac8c..c8838de1eb 100644 --- a/examples/python/keras/func_cifar10_cnn_concat_model.py +++ b/examples/python/keras/func_cifar10_cnn_concat_model.py @@ -75,7 +75,10 @@ def top_level_task(): model.fit([x_train, x_train], y_train, epochs=160, callbacks=[VerifyMetrics(ModelAccuracy.CIFAR10_CNN), EpochVerifyMetrics(ModelAccuracy.CIFAR10_CNN)]) + if __name__ == "__main__": print("Functional API, cifar10 cnn concat model") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn_concat_seq_model.py b/examples/python/keras/func_cifar10_cnn_concat_seq_model.py index cda95beb49..3e4f939283 100644 --- a/examples/python/keras/func_cifar10_cnn_concat_seq_model.py +++ b/examples/python/keras/func_cifar10_cnn_concat_seq_model.py @@ -68,7 +68,10 @@ def top_level_task(): model.fit([x_train, x_train], y_train, epochs=160, callbacks=[VerifyMetrics(ModelAccuracy.CIFAR10_CNN), EpochVerifyMetrics(ModelAccuracy.CIFAR10_CNN)]) + if __name__ == "__main__": print("Functional API, cifar10 cnn concat sequential model") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn_nested.py b/examples/python/keras/func_cifar10_cnn_nested.py index def8a6bcf4..7391ba5a2b 100644 --- a/examples/python/keras/func_cifar10_cnn_nested.py +++ b/examples/python/keras/func_cifar10_cnn_nested.py @@ -67,7 +67,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=160, callbacks=[VerifyMetrics(ModelAccuracy.CIFAR10_CNN), EpochVerifyMetrics(ModelAccuracy.CIFAR10_CNN)]) + if __name__ == "__main__": print("Functional API, cifar10 cnn nested") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_cifar10_cnn_net2net.py b/examples/python/keras/func_cifar10_cnn_net2net.py index 5434e28aca..695a1157dd 100644 --- a/examples/python/keras/func_cifar10_cnn_net2net.py +++ b/examples/python/keras/func_cifar10_cnn_net2net.py @@ -120,5 +120,7 @@ def top_level_task(): if __name__ == "__main__": print("Functional API, cifarf10 cnn teach student") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_cnn.py b/examples/python/keras/func_mnist_cnn.py index a81ddd0f94..8f2041dfe2 100644 --- a/examples/python/keras/func_mnist_cnn.py +++ b/examples/python/keras/func_mnist_cnn.py @@ -70,7 +70,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=5, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_CNN), EpochVerifyMetrics(ModelAccuracy.MNIST_CNN)]) + if __name__ == "__main__": print("Functional API, mnist cnn") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_cnn_concat.py b/examples/python/keras/func_mnist_cnn_concat.py index 54c1f32d36..64bb2cdbb0 100644 --- a/examples/python/keras/func_mnist_cnn_concat.py +++ b/examples/python/keras/func_mnist_cnn_concat.py @@ -61,7 +61,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=5, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_CNN), EpochVerifyMetrics(ModelAccuracy.MNIST_CNN)]) + if __name__ == "__main__": print("Functional API, mnist cnn concat") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_mlp.py b/examples/python/keras/func_mnist_mlp.py index 5521f193c1..ddf2022366 100644 --- a/examples/python/keras/func_mnist_mlp.py +++ b/examples/python/keras/func_mnist_mlp.py @@ -54,7 +54,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=10, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) + if __name__ == "__main__": print("Functional API, mnist mlp") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_mlp_concat.py b/examples/python/keras/func_mnist_mlp_concat.py index 29b982cea8..6b282f65e6 100644 --- a/examples/python/keras/func_mnist_mlp_concat.py +++ b/examples/python/keras/func_mnist_mlp_concat.py @@ -76,7 +76,10 @@ def top_level_task(): model.fit(x_train, y_train, epochs=5, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) + if __name__ == "__main__": print("Functional API, mnist mlp concat") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_mlp_concat2.py b/examples/python/keras/func_mnist_mlp_concat2.py index 5a35bd9f8b..b309a00187 100644 --- a/examples/python/keras/func_mnist_mlp_concat2.py +++ b/examples/python/keras/func_mnist_mlp_concat2.py @@ -87,7 +87,10 @@ def top_level_task(): model.fit([x_train, x_train, x_train], y_train, epochs=10, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) + if __name__ == "__main__": print("Functional API, mnist mlp concat with input") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/func_mnist_mlp_net2net.py b/examples/python/keras/func_mnist_mlp_net2net.py index ed8589e22e..0b44029938 100644 --- a/examples/python/keras/func_mnist_mlp_net2net.py +++ b/examples/python/keras/func_mnist_mlp_net2net.py @@ -88,7 +88,10 @@ def top_level_task(): student_model.fit(x_train, y_train, epochs=160, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) + if __name__ == "__main__": print("Functional API, mnist mlp teach student") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() - gc.collect() \ No newline at end of file + gc.collect() diff --git a/examples/python/keras/gather.py b/examples/python/keras/gather.py index 15ccd61579..f14d737d17 100644 --- a/examples/python/keras/gather.py +++ b/examples/python/keras/gather.py @@ -1,7 +1,7 @@ from flexflow.keras.layers import Dense, Input, Reshape from flexflow.keras.backend.internal import gather import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np @@ -42,4 +42,6 @@ def gather_example(): if __name__ == '__main__': + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) gather_example() diff --git a/examples/python/keras/identity_loss.py b/examples/python/keras/identity_loss.py index d0396c6d46..8e26fc246b 100644 --- a/examples/python/keras/identity_loss.py +++ b/examples/python/keras/identity_loss.py @@ -15,7 +15,7 @@ from flexflow.keras.layers import Dense, Input, Reshape, Multiply import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np def test_identity_loss(): @@ -36,4 +36,6 @@ def test_identity_loss(): if __name__ == "__main__": + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) test_identity_loss() diff --git a/examples/python/keras/reduce_sum.py b/examples/python/keras/reduce_sum.py index 3857738d4b..33030e2cec 100644 --- a/examples/python/keras/reduce_sum.py +++ b/examples/python/keras/reduce_sum.py @@ -15,7 +15,7 @@ from flexflow.keras.layers import Dense, Input, Reshape, Multiply import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np def test_reduce_sum1(): @@ -74,6 +74,8 @@ def test_reduce_sum3(): if __name__ == "__main__": + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) test_reduce_sum1() test_reduce_sum2() test_reduce_sum3() diff --git a/examples/python/keras/regularizer.py b/examples/python/keras/regularizer.py index 3b1e30d04d..3a24129db2 100644 --- a/examples/python/keras/regularizer.py +++ b/examples/python/keras/regularizer.py @@ -2,7 +2,7 @@ from flexflow.keras.layers import Dense, Input, Reshape from flexflow.keras.backend.internal import gather import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np @@ -26,4 +26,6 @@ def regularizer_example(): if __name__ == '__main__': + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) regularizer_example() diff --git a/examples/python/keras/reshape.py b/examples/python/keras/reshape.py index 1acce1b2b6..ae756a8f70 100644 --- a/examples/python/keras/reshape.py +++ b/examples/python/keras/reshape.py @@ -55,7 +55,10 @@ def top_level_task(): print(model.summary()) model.fit(x_train, y_train, epochs=10, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) + if __name__ == "__main__": print("Functional API, mnist mlp") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() gc.collect() diff --git a/examples/python/keras/rsqrt.py b/examples/python/keras/rsqrt.py index be55c8a1fd..e33873ecd5 100644 --- a/examples/python/keras/rsqrt.py +++ b/examples/python/keras/rsqrt.py @@ -16,7 +16,7 @@ from flexflow.keras.layers import Dense, Input from flexflow.keras.backend.internal import rsqrt import flexflow.keras.optimizers - +import flexflow.core as ff import numpy as np def test_rsqrt(): @@ -40,4 +40,6 @@ def test_rsqrt(): if __name__ == "__main__": + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) test_rsqrt() diff --git a/examples/python/keras/seq_cifar10_cnn.py b/examples/python/keras/seq_cifar10_cnn.py index 80f4390d4c..66ea8530e0 100644 --- a/examples/python/keras/seq_cifar10_cnn.py +++ b/examples/python/keras/seq_cifar10_cnn.py @@ -54,6 +54,9 @@ def top_level_task(): model.fit(x_train, y_train, epochs=80, callbacks=[VerifyMetrics(ModelAccuracy.CIFAR10_CNN), EpochVerifyMetrics(ModelAccuracy.CIFAR10_CNN)]) + if __name__ == "__main__": - print("Sequantial model, cifar10 cnn") + print("Sequential model, cifar10 cnn") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_mnist_cnn.py b/examples/python/keras/seq_mnist_cnn.py index eaf0fdfc16..09ad4ea4cf 100644 --- a/examples/python/keras/seq_mnist_cnn.py +++ b/examples/python/keras/seq_mnist_cnn.py @@ -55,6 +55,9 @@ def top_level_task(): model.fit(x_train, y_train, epochs=5, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_CNN), EpochVerifyMetrics(ModelAccuracy.MNIST_CNN)]) + if __name__ == "__main__": print("Sequential model, mnist cnn") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_mnist_cnn_nested.py b/examples/python/keras/seq_mnist_cnn_nested.py index 2c92349cd6..628129ddb9 100644 --- a/examples/python/keras/seq_mnist_cnn_nested.py +++ b/examples/python/keras/seq_mnist_cnn_nested.py @@ -65,6 +65,9 @@ def top_level_task(): model.fit(x_train, y_train, epochs=5, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_CNN), EpochVerifyMetrics(ModelAccuracy.MNIST_CNN)]) + if __name__ == "__main__": print("Sequential model, mnist cnn nested model") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_mnist_cnn_net2net.py b/examples/python/keras/seq_mnist_cnn_net2net.py index 4b9c9c16ba..e2a04ba686 100644 --- a/examples/python/keras/seq_mnist_cnn_net2net.py +++ b/examples/python/keras/seq_mnist_cnn_net2net.py @@ -98,6 +98,9 @@ def top_level_task(): create_student_model_cnn(teacher_model, num_classes, x_train, y_train) + if __name__ == "__main__": print("Sequential model, mnist mlp teacher student") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_mnist_mlp.py b/examples/python/keras/seq_mnist_mlp.py index 21c7435eb7..46b774a2e1 100644 --- a/examples/python/keras/seq_mnist_mlp.py +++ b/examples/python/keras/seq_mnist_mlp.py @@ -55,6 +55,9 @@ def top_level_task(): model.fit(x_train, y_train, epochs=20, callbacks=[VerifyMetrics(ModelAccuracy.MNIST_MLP), EpochVerifyMetrics(ModelAccuracy.MNIST_MLP)]) model.evaluate(x=x_train, y=y_train) + if __name__ == "__main__": print("Sequential model, mnist mlp") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_mnist_mlp_net2net.py b/examples/python/keras/seq_mnist_mlp_net2net.py index 628f76db3a..c7a7d7a6f8 100644 --- a/examples/python/keras/seq_mnist_mlp_net2net.py +++ b/examples/python/keras/seq_mnist_mlp_net2net.py @@ -91,6 +91,9 @@ def top_level_task(): create_student_model_mlp(teacher_model, num_classes, x_train, y_train) + if __name__ == "__main__": print("Sequential model, mnist mlp teacher student") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/seq_reuters_mlp.py b/examples/python/keras/seq_reuters_mlp.py index 5412ad0599..ed748f67d8 100644 --- a/examples/python/keras/seq_reuters_mlp.py +++ b/examples/python/keras/seq_reuters_mlp.py @@ -19,6 +19,7 @@ from flexflow.keras.datasets import reuters from flexflow.keras.preprocessing.text import Tokenizer from flexflow.keras.callbacks import Callback, VerifyMetrics +import flexflow.core as ff import numpy as np from accuracy import ModelAccuracy @@ -61,6 +62,9 @@ def top_level_task(): model.fit(x_train, y_train, epochs=epochs, callbacks=[VerifyMetrics(ModelAccuracy.REUTERS_MLP)]) + if __name__ == "__main__": print("Sequential model, reuters mlp") + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/keras/unary.py b/examples/python/keras/unary.py index 622e15dc2d..63c83b9af2 100644 --- a/examples/python/keras/unary.py +++ b/examples/python/keras/unary.py @@ -62,4 +62,6 @@ def top_level_task(): if __name__ == "__main__": print("alexnet keras") - top_level_task() \ No newline at end of file + configs = ff.get_configs() + ff.init_flexflow_runtime(configs) + top_level_task() diff --git a/examples/python/native/alexnet.py b/examples/python/native/alexnet.py index 61397cefc1..6d6e58a7f2 100644 --- a/examples/python/native/alexnet.py +++ b/examples/python/native/alexnet.py @@ -3,7 +3,7 @@ from accuracy import ModelAccuracy from PIL import Image -import argparse +import argparse, json import numpy as np @@ -133,7 +133,18 @@ def test_accuracy(): parser = argparse.ArgumentParser() parser.add_argument("-a", "--test_acc", action="store_true", help="Test accuracy flag") + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) args, unknown = parser.parse_known_args() + configs_dict = None + if args.config_file is not None: + with open(args.config_file) as f: + configs_dict = json.load(f) + init_flexflow_runtime(configs_dict) if args.test_acc: print("Testing cifar10 alexnet training accuracy") test_accuracy() diff --git a/examples/python/native/cifar10_cnn.py b/examples/python/native/cifar10_cnn.py index 44bdce4519..11bc936617 100644 --- a/examples/python/native/cifar10_cnn.py +++ b/examples/python/native/cifar10_cnn.py @@ -2,7 +2,7 @@ from flexflow.keras.datasets import cifar10 from accuracy import ModelAccuracy -import argparse +import argparse, json def top_level_task(): @@ -90,7 +90,18 @@ def test_accuracy(): parser = argparse.ArgumentParser() parser.add_argument("-a", "--test_acc", action="store_true", help="Test accuracy flag") + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) args, unknown = parser.parse_known_args() + configs_dict = None + if args.config_file is not None: + with open(args.config_file) as f: + configs_dict = json.load(f) + init_flexflow_runtime(configs_dict) if args.test_acc: print("Testing cifar10 cnn training accuracy") test_accuracy() diff --git a/examples/python/native/cifar10_cnn_attach.py b/examples/python/native/cifar10_cnn_attach.py index ba4288c8cd..e200cc03cf 100644 --- a/examples/python/native/cifar10_cnn_attach.py +++ b/examples/python/native/cifar10_cnn_attach.py @@ -144,4 +144,6 @@ def top_level_task(): if __name__ == "__main__": print("cifar10 cnn attach") + configs = get_configs() + init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/native/cifar10_cnn_concat.py b/examples/python/native/cifar10_cnn_concat.py index b177295ad6..7234116b3c 100644 --- a/examples/python/native/cifar10_cnn_concat.py +++ b/examples/python/native/cifar10_cnn_concat.py @@ -70,6 +70,10 @@ def top_level_task(): if accuracy < ModelAccuracy.CIFAR10_CNN.value: assert 0, 'Check Accuracy' + + if __name__ == "__main__": print("cifar10 cnn concat") + configs = get_configs() + init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/native/mnist_cnn.py b/examples/python/native/mnist_cnn.py index 6eabbe57db..f6787a4827 100644 --- a/examples/python/native/mnist_cnn.py +++ b/examples/python/native/mnist_cnn.py @@ -18,7 +18,7 @@ from flexflow.keras.datasets import mnist from accuracy import ModelAccuracy -import argparse +import argparse, json def top_level_task(): @@ -89,7 +89,18 @@ def test_accuracy(): parser = argparse.ArgumentParser() parser.add_argument("-a", "--test_acc", action="store_true", help="Test accuracy flag") + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) args, unknown = parser.parse_known_args() + configs_dict = None + if args.config_file is not None: + with open(args.config_file) as f: + configs_dict = json.load(f) + init_flexflow_runtime(configs_dict) if args.test_acc: print("Testing mnist cnn training accuracy") test_accuracy() diff --git a/examples/python/native/mnist_mlp.py b/examples/python/native/mnist_mlp.py index aefe7cfd57..8763eba40c 100644 --- a/examples/python/native/mnist_mlp.py +++ b/examples/python/native/mnist_mlp.py @@ -3,7 +3,7 @@ from flexflow.keras.datasets import mnist from accuracy import ModelAccuracy -import argparse +import argparse, json def top_level_task(): @@ -75,7 +75,18 @@ def test_accuracy(): parser = argparse.ArgumentParser() parser.add_argument("-a", "--test_acc", action="store_true", help="Test accuracy flag") + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) args, unknown = parser.parse_known_args() + configs_dict = None + if args.config_file is not None: + with open(args.config_file) as f: + configs_dict = json.load(f) + init_flexflow_runtime(configs_dict) if args.test_acc: print("Testing mnist mlp training accuracy") test_accuracy() diff --git a/examples/python/native/mnist_mlp_attach.py b/examples/python/native/mnist_mlp_attach.py index 6e7c8f8405..1294432ec5 100644 --- a/examples/python/native/mnist_mlp_attach.py +++ b/examples/python/native/mnist_mlp_attach.py @@ -134,4 +134,6 @@ def top_level_task(): if __name__ == "__main__": print("mnist mlp attach") + configs = get_configs() + init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/native/print_layers.py b/examples/python/native/print_layers.py index 22b87e0b86..481ecc3477 100644 --- a/examples/python/native/print_layers.py +++ b/examples/python/native/print_layers.py @@ -119,6 +119,9 @@ def top_level_task(): # ffmodel.print_layers(0) + if __name__ == "__main__": print("alexnet") + configs = get_configs() + init_flexflow_runtime(configs) top_level_task() diff --git a/examples/python/native/split.py b/examples/python/native/split.py index dfd8b0e572..f79ff04e14 100644 --- a/examples/python/native/split.py +++ b/examples/python/native/split.py @@ -77,6 +77,9 @@ def top_level_task(): # if accuracy < ModelAccuracy.CIFAR10_CNN.value: # assert 0, 'Check Accuracy' + if __name__ == "__main__": print("cifar10 cnn split") + configs = get_configs() + init_flexflow_runtime(configs) top_level_task() diff --git a/img/overview.png b/img/overview.png new file mode 100644 index 0000000000..5264e2d41a Binary files /dev/null and b/img/overview.png differ diff --git a/img/performance.png b/img/performance.png new file mode 100644 index 0000000000..668e579197 Binary files /dev/null and b/img/performance.png differ diff --git a/img/spec_infer_demo.gif b/img/spec_infer_demo.gif new file mode 100644 index 0000000000..c0fda87b71 Binary files /dev/null and b/img/spec_infer_demo.gif differ diff --git a/include/flexflow/accessor.h b/include/flexflow/accessor.h index 6f95354823..65ab33b513 100644 --- a/include/flexflow/accessor.h +++ b/include/flexflow/accessor.h @@ -61,6 +61,7 @@ class GenericTensorAccessorW { float *get_float_ptr() const; double *get_double_ptr() const; half *get_half_ptr() const; + char *get_byte_ptr() const; DataType data_type; Legion::Domain domain; void *ptr; @@ -79,6 +80,7 @@ class GenericTensorAccessorR { float const *get_float_ptr() const; double const *get_double_ptr() const; half const *get_half_ptr() const; + char const *get_byte_ptr() const; DataType data_type; Legion::Domain domain; void const *ptr; diff --git a/include/flexflow/batch_config.h b/include/flexflow/batch_config.h new file mode 100644 index 0000000000..009d1c250a --- /dev/null +++ b/include/flexflow/batch_config.h @@ -0,0 +1,204 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#pragma once + +#include "flexflow/ffconst.h" +#include "legion.h" +#include +#include + +// #define MAX_SEQ_LEN 1024 +// #define BATCH_SIZE 2 +// #define BATCH_SIZE 16 +// #define MAX_REQUESTS 256 + +namespace FlexFlow { + +class InferenceResult; +class BeamInferenceResult; + +using BatchConfigFuture = Legion::Future; +using InferenceResultFuture = Legion::Future; +using BeamSearchBatchConfigFuture = Legion::Future; +using TreeVerifyBatchConfigFuture = Legion::Future; +using BeamInferenceResultFuture = Legion::Future; + +class BatchConfig { +public: + using RequestGuid = size_t; + using TokenId = int; + BatchConfig(); + int num_active_requests() const; + int num_active_tokens() const; + static int max_requests_per_batch(); + static int max_tokens_per_batch(); + static int max_verify_tokens_per_batch(); + static int max_spec_tree_token_num(); + static int max_sequence_length(); + friend std::ostream &operator<<(std::ostream &os, BatchConfig const &bc); + void print() const; + void save_to_file(std::string const &filename) const; + virtual InferenceMode get_mode() const; + static BatchConfig const *from_future(BatchConfigFuture const &future); + // Maximum possible values for different parameters + // These maximum values are used for copying BatchConfig + // across workers + static int const MAX_NUM_REQUESTS = 64; + static int const MAX_NUM_TOKENS = 1024; + static int const MAX_SPEC_TREE_TOKEN_NUM = 64; + + // Set by update + int num_tokens; + // number of tokens in prompt phase, start offset of tokens in inc_decoding + // phase. num_tokens - num_prompt_tokens = num_generation_tokens; + int num_generation_tokens; + + struct PerRequestInfo { + int first_token_depth_in_request; + int first_token_offset_in_batch; + int num_tokens_in_batch; + int max_sequence_length; + + // request id in batch config: + int batch_config_request_id; + bool prompt_phase = false; + RequestGuid request_guid; + }; + struct PerTokenInfo { + int abs_depth_in_request; + int request_index; + TokenId token_id; + }; + + struct BitMask { + unsigned long long mask[MAX_SPEC_TREE_TOKEN_NUM] = {0}; + + // how many tokens before the tree, every sub requests need this part of + // cache + int non_tree_cache_size = 0; + + // current tree size + int tree_size = 0; + + int this_layer_size = 0; + + // input length-> prompt/root + int prompt_size = 0; + }; + + BitMask causalMask[MAX_NUM_REQUESTS]; + PerRequestInfo requestsInfo[MAX_NUM_REQUESTS]; + PerTokenInfo tokensInfo[MAX_NUM_TOKENS]; + + bool request_completed[MAX_NUM_REQUESTS]; + bool request_running[MAX_NUM_REQUESTS]; +}; + +class TreeVerifyBatchConfig : public BatchConfig { +public: + TreeVerifyBatchConfig(); + ~TreeVerifyBatchConfig(); + InferenceMode get_mode() const; + friend std::ostream &operator<<(std::ostream &os, + TreeVerifyBatchConfig const &bc); + void print() const; + void save_to_file(std::string const &filename) const; + struct CommittedTokensInfo { + int token_index; // the index of the token in the previous batch + int request_index; // request index in the batch + int token_depth; // position of the token in the request's sequence + }; + + int num_tokens_to_commit; + CommittedTokensInfo committed_tokens[MAX_NUM_TOKENS]; +}; + +struct InferenceResult { + static int const MAX_NUM_TOKENS = BatchConfig::MAX_NUM_TOKENS; + BatchConfig::TokenId token_ids[MAX_NUM_TOKENS]; +}; + +class BeamSearchBatchConfig : public BatchConfig { +public: + BeamSearchBatchConfig(); + BeamSearchBatchConfig(int model_id); + BeamSearchBatchConfig(size_t beam_width, size_t target_iterations); + BeamSearchBatchConfig(BeamSearchBatchConfig const &other, int model_id); + InferenceMode get_mode() const; + + ~BeamSearchBatchConfig(); + + friend std::ostream &operator<<(std::ostream &os, + BeamSearchBatchConfig const &bc); + void print() const; + void save_to_file(std::string const &filename) const; + bool done() const; + int max_beam_depth_all_requests() const; + int current_depth_all_requests() const; + int get_speculative_request_num() const; + + size_t beam_width; + size_t target_iterations; + + // how many requests is in speculative phase + int speculative_request_num = 0; + inline static int const MAX_BEAM_WIDTH = 3; + inline static int const MAX_BEAM_DEPTH = 8; + + // maximum tree branches for a request + inline static int const MAX_SPECULATIVE_TREE_BRANCHES = 3; + + int model_id; + + struct BeamSearchPerRequestInfo { + int beam_size; + int current_depth = -1; + int max_depth = MAX_BEAM_DEPTH; + + BatchConfig::TokenId + tokens[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + float probs[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + int parent_id[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + int sub_request_num; + }; + + struct BeamSearchPerTokenInfo { + int sub_request_index; + }; + + BeamSearchPerRequestInfo beamRequestsInfo[MAX_NUM_REQUESTS]; + BeamSearchPerTokenInfo + beamTokenInfo[MAX_NUM_TOKENS + + MAX_SPEC_TREE_TOKEN_NUM * MAX_NUM_REQUESTS]; + + int sub_requests[MAX_NUM_REQUESTS]; + +private: + size_t current_iteration; +}; + +struct BeamInferenceResult { + static int const MAX_NUM_TOKENS = BatchConfig::MAX_NUM_TOKENS; + BatchConfig::TokenId + token_ids[MAX_NUM_TOKENS * + BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + float probs[MAX_NUM_TOKENS * + BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + int parent_id[MAX_NUM_TOKENS * + BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/config.h b/include/flexflow/config.h index b6a27a4f2a..bf118a565f 100644 --- a/include/flexflow/config.h +++ b/include/flexflow/config.h @@ -16,22 +16,25 @@ #ifndef _FLEXFLOW_CONFIG_H_ #define _FLEXFLOW_CONFIG_H_ #include "ffconst.h" +#include "flexflow/batch_config.h" #include "legion.h" #include #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) #include #include #elif defined(FF_USE_HIP_ROCM) -#include +#include #include #else #error "Unknown device" #endif #include "tl/optional.hpp" +#ifdef FF_USE_NCCL #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) #include #else -#include +#include +#endif #endif namespace FlexFlow { @@ -39,14 +42,15 @@ namespace FlexFlow { // ======================================================== // Define Runtime Constants // ======================================================== -#define MAX_NUM_INPUTS 256 -#define MAX_NUM_WEIGHTS 64 -#define MAX_NUM_OUTPUTS 256 -#define MAX_NUM_FUSED_OPERATORS 64 -#define MAX_NUM_FUSED_TENSORS 64 +#define MAX_NUM_INPUTS 2048 +#define MAX_NUM_WEIGHTS 2048 +#define MAX_NUM_OUTPUTS 2048 +#define MAX_NUM_FUSED_OPERATORS 2048 +#define MAX_NUM_FUSED_TENSORS 2048 #define MAX_NUM_WORKERS 1024 #define MAX_FILENAME 200 #define MAX_OPNAME 128 +#define MAX_NUM_TRANSFORMER_LAYERS 100 // DataLoader #define MAX_SAMPLES_PER_LOAD 64 #define MAX_FILE_LENGTH 128 @@ -72,6 +76,19 @@ struct FFHandler { #endif void *workSpace; size_t workSpaceSize; + void *batch_config_metadata; + + // request info + token info + topolopgy mask info + size_t batch_config_metadata_size = + sizeof(BatchConfig::tokensInfo) + sizeof(BatchConfig::requestsInfo) + + sizeof(BeamSearchBatchConfig::beamTokenInfo) + + sizeof(BeamSearchBatchConfig::beamRequestsInfo) + + sizeof(BatchConfig::causalMask) + + sizeof(TreeVerifyBatchConfig::committed_tokens) + + sizeof(BatchConfig::request_completed); + void *offload_reserve_space; + size_t offload_reserve_space_size; + DataType quantization_type; bool allowTensorOpMathConversion; #ifdef FF_USE_NCCL ncclComm_t ncclComm; @@ -80,6 +97,8 @@ struct FFHandler { struct FFInitInfo { size_t workSpaceSize; + size_t offload_reserve_space_size; + DataType quantization_type; bool allowTensorOpMathConversion; // int myRank, allRanks; }; @@ -125,21 +144,30 @@ class FFConfig { Legion::Context lg_ctx; Legion::Runtime *lg_hlr; Legion::IndexSpaceT<1> all_gpu_task_is; + // Legion::FieldSpace field_space; + bool benchmarking, profiling, perform_fusion; + bool inference_debugging; Legion::FieldSpace field_space; - bool syntheticInput, profiling, perform_fusion; + bool syntheticInput; size_t simulator_work_space_size; size_t search_budget; float search_alpha; bool search_overlap_backward_update; CompMode computationMode; + bool cpu_offload; + size_t offload_reserve_space_size; + DataType quantization_type; // Control parallelizable dimensions bool only_data_parallel; bool enable_sample_parallel; bool enable_parameter_parallel; bool enable_attribute_parallel; bool enable_inplace_optimizations; + // Control parallelism degrees in inference int data_parallelism_degree; int tensor_parallelism_degree; + int pipeline_parallelism_degree; + // Control Tensor Op Math Conversion bool allow_tensor_op_math_conversion; std::string dataset_path; diff --git a/include/flexflow/ffconst.h b/include/flexflow/ffconst.h index 060983b020..512645e624 100644 --- a/include/flexflow/ffconst.h +++ b/include/flexflow/ffconst.h @@ -33,6 +33,8 @@ enum DataType { DT_HALF = 43, DT_FLOAT = 44, DT_DOUBLE = 45, + DT_INT4 = 46, + DT_INT8 = 47, DT_NONE = 49, }; @@ -64,6 +66,12 @@ enum MetricsType { METRICS_MEAN_ABSOLUTE_ERROR = 1032, }; +enum InferenceMode { + INC_DECODING_MODE = 2001, + BEAM_SEARCH_MODE = 2002, + TREE_VERIFY_MODE = 2003, +}; + // This is consistent with TASO's OpType // https://github.com/jiazhihao/TASO/blob/master/include/taso/ops.h#L75-L138 enum OperatorType { @@ -129,6 +137,7 @@ enum OperatorType { OP_SHAPE, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#Shape OP_SIZE, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#Size OP_TOPK, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#TopK + OP_ARG_TOPK, OP_WHERE, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#Where OP_CEIL, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#Ceil OP_CAST, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#Cast @@ -150,7 +159,19 @@ enum OperatorType { OP_POW, // https://pytorch.org/docs/stable/generated/torch.pow.html OP_MEAN, // https://pytorch.org/docs/stable/generated/torch.mean.html OP_LAYERNORM, + OP_RESIDUAL_LAYERNORM, + OP_ADD_BIAS_RESIDUAL_LAYERNORM, + OP_SIGMOID_SILU_MULTI, + OP_EXPERTS, OP_GATHER, // https://pytorch.org/docs/stable/generated/torch.gather.html + OP_RMS_NORM, + OP_RESIDUAL_RMS_NORM, + OP_BEAM_TOPK, + OP_ARGMAX, + OP_INC_MULTIHEAD_SELF_ATTENTION, + OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION, + OP_TREE_INC_MULTIHEAD_SELF_ATTENTION, + OP_SAMPLING, // Parallel Ops OP_REPARTITION, OP_COMBINE, @@ -162,6 +183,15 @@ enum OperatorType { OP_INVALID, }; +enum ModelType { + UNKNOWN = 3001, + LLAMA = 3002, + OPT = 3003, + FALCON = 3004, + STARCODER = 3005, + MPT = 3006 +}; + enum PMParameter { PM_OP_TYPE, // AnyOp PM_NUM_INPUTS, // AnyOp diff --git a/include/flexflow/ffconst_utils.h b/include/flexflow/ffconst_utils.h index fcd881e57e..421a139d57 100644 --- a/include/flexflow/ffconst_utils.h +++ b/include/flexflow/ffconst_utils.h @@ -8,8 +8,16 @@ namespace FlexFlow { std::string get_operator_type_name(OperatorType type); +size_t data_type_size(DataType type); + +#define INT4_NUM_OF_ELEMENTS_PER_GROUP 32 + +size_t get_quantization_to_byte_size(DataType type, + DataType quantization_type, + size_t num_elements); + std::ostream &operator<<(std::ostream &, OperatorType); }; // namespace FlexFlow -#endif // _FLEXFLOW_FFCONST_UTILS_H \ No newline at end of file +#endif // _FLEXFLOW_FFCONST_UTILS_H diff --git a/include/flexflow/fftype.h b/include/flexflow/fftype.h index a71c85dbc8..1cd90fda26 100644 --- a/include/flexflow/fftype.h +++ b/include/flexflow/fftype.h @@ -8,15 +8,16 @@ namespace FlexFlow { class LayerID { public: + static const LayerID NO_ID; LayerID(); - LayerID(size_t id); + LayerID(size_t id, size_t transformer_layer_id, size_t model_id); bool is_valid_id() const; friend bool operator==(LayerID const &lhs, LayerID const &rhs); public: - size_t id; + size_t id, transformer_layer_id, model_id; }; }; // namespace FlexFlow -#endif // _FF_TYPE_H \ No newline at end of file +#endif // _FF_TYPE_H diff --git a/include/flexflow/flexflow_c.h b/include/flexflow/flexflow_c.h index 2ddc8549fa..83bfb045c7 100644 --- a/include/flexflow/flexflow_c.h +++ b/include/flexflow/flexflow_c.h @@ -47,6 +47,14 @@ FF_NEW_OPAQUE_TYPE(flexflow_dlrm_config_t); FF_NEW_OPAQUE_TYPE(flexflow_dataloader_4d_t); FF_NEW_OPAQUE_TYPE(flexflow_dataloader_2d_t); FF_NEW_OPAQUE_TYPE(flexflow_single_dataloader_t); +// Inference +FF_NEW_OPAQUE_TYPE(flexflow_batch_config_t); +FF_NEW_OPAQUE_TYPE(flexflow_tree_verify_batch_config_t); +FF_NEW_OPAQUE_TYPE(flexflow_beam_search_batch_config_t); +FF_NEW_OPAQUE_TYPE(flexflow_inference_manager_t); +FF_NEW_OPAQUE_TYPE(flexflow_request_manager_t); +FF_NEW_OPAQUE_TYPE(flexflow_file_data_loader_t); +FF_NEW_OPAQUE_TYPE(flexflow_generation_result_t); // ----------------------------------------------------------------------- // FFConfig @@ -72,12 +80,31 @@ int flexflow_config_get_epochs(flexflow_config_t handle); bool flexflow_config_get_enable_control_replication(flexflow_config_t handle); +int flexflow_config_get_data_parallelism_degree(flexflow_config_t handle_); + +int flexflow_config_get_tensor_parallelism_degree(flexflow_config_t handle_); + +int flexflow_config_get_pipeline_parallelism_degree(flexflow_config_t handle_); + +void flexflow_config_set_data_parallelism_degree(flexflow_config_t handle_, + int value); + +void flexflow_config_set_tensor_parallelism_degree(flexflow_config_t handle_, + int value); + +void flexflow_config_set_pipeline_parallelism_degree(flexflow_config_t handle_, + int value); + int flexflow_config_get_python_data_loader_type(flexflow_config_t handle); + +bool flexflow_config_get_offload(flexflow_config_t handle); + // ----------------------------------------------------------------------- // FFModel // ----------------------------------------------------------------------- -flexflow_model_t flexflow_model_create(flexflow_config_t config); +flexflow_model_t flexflow_model_create(flexflow_config_t config, + bool cpu_offload); void flexflow_model_destroy(flexflow_model_t handle); @@ -199,9 +226,10 @@ flexflow_tensor_t flexflow_tensor_t flexflow_model_add_embedding(flexflow_model_t handle, const flexflow_tensor_t input, - int num_entires, + int num_entries, int out_dim, enum AggrMode aggr, + enum DataType dtype, flexflow_op_t shared_op, flexflow_initializer_t kernel_initializer, char const *name); @@ -230,8 +258,39 @@ flexflow_tensor_t flexflow_model_add_layer_norm(flexflow_model_t handle, int *axes, bool elementwise_affine, float eps, + bool use_bias, char const *name); +flexflow_tensor_t * + flexflow_model_add_residual_layer_norm(flexflow_model_t handle, + const flexflow_tensor_t input, + const flexflow_tensor_t residual1, + const flexflow_tensor_t residual2, + bool use_two_residuals, + int n, + int *axes, + bool elementwise_affine, + float eps, + bool use_bias, + char const *name); + +flexflow_tensor_t *flexflow_model_add_add_bias_residual_layer_norm( + flexflow_model_t handle, + const flexflow_tensor_t input, + const flexflow_tensor_t residual, + int n, + int *axes, + bool elementwise_affine, + float eps, + bool use_bias, + char const *name); + +flexflow_tensor_t + flexflow_model_add_sigmoid_silu_multi(flexflow_model_t handle, + const flexflow_tensor_t input1, + const flexflow_tensor_t input2, + char const *name); + flexflow_tensor_t flexflow_model_add_batch_matmul(flexflow_model_t handle, const flexflow_tensor_t a, @@ -374,6 +433,166 @@ flexflow_tensor_t flexflow_model_add_multihead_attention( flexflow_initializer_t kernel_initializer, char const *name); +flexflow_tensor_t flexflow_model_add_inc_multihead_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_spec_inc_multihead_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_inc_multihead_self_attention_verify( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_inc_multiquery_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_spec_inc_multiquery_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_inc_multiquery_self_attention_verify( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name); + +flexflow_tensor_t flexflow_model_add_rms_norm(flexflow_model_t handle_, + const flexflow_tensor_t input_, + float eps, + int dim, + char const *name); + +flexflow_tensor_t * + flexflow_model_add_residual_rms_norm(flexflow_model_t handle_, + const flexflow_tensor_t input1_, + const flexflow_tensor_t input2_, + float eps, + int dim, + char const *name); + +flexflow_tensor_t flexflow_model_add_arg_top_k(flexflow_model_t handle_, + const flexflow_tensor_t input_, + int k, + bool sorted, + bool speculative_decoding, + char const *name); + +flexflow_tensor_t flexflow_model_add_beam_top_k(flexflow_model_t handle_, + const flexflow_tensor_t input_, + int max_beam_size, + bool sorted, + char const *name); + +flexflow_tensor_t flexflow_model_add_sampling(flexflow_model_t handle_, + const flexflow_tensor_t input_, + float top_p, + char const *name); + +flexflow_tensor_t flexflow_model_add_argmax(flexflow_model_t handle_, + const flexflow_tensor_t input_, + bool beam_search, + char const *name); + void flexflow_model_set_sgd_optimizer(flexflow_model_t handle, flexflow_sgd_optimizer_t optimizer); @@ -393,6 +612,18 @@ flexflow_tensor_t flexflow_model_get_parameter_by_id(flexflow_model_t handle, flexflow_perf_metrics_t flexflow_model_get_perf_metrics(flexflow_model_t handle); +void flexflow_model_set_transformer_layer_id(flexflow_model_t handle, int id); + +void flexflow_model_generate(flexflow_model_t handle_, + int num_requests, + char const **input_text, + int max_num_chars, + char **output_text, + int max_seq_length, + int **output_length_and_tokens); + +void flexflow_model_set_position_offset(flexflow_model_t handle, int offset); + // ----------------------------------------------------------------------- // Tensor // ----------------------------------------------------------------------- @@ -702,6 +933,112 @@ void flexflow_op_forward(flexflow_op_t handle, flexflow_model_t model); void flexflow_perform_registration(void); +// ----------------------------------------------------------------------- +// BatchConfig +// ----------------------------------------------------------------------- + +flexflow_batch_config_t flexflow_batch_config_create(void); + +void flexflow_batch_config_destroy(flexflow_batch_config_t handle); + +// ----------------------------------------------------------------------- +// TreeVerifyBatchConfig +// ----------------------------------------------------------------------- + +flexflow_tree_verify_batch_config_t + flexflow_tree_verify_batch_config_create(void); + +void flexflow_tree_verify_batch_config_destroy( + flexflow_tree_verify_batch_config_t handle); + +// ----------------------------------------------------------------------- +// BeamSearchBatchConfig +// ----------------------------------------------------------------------- + +flexflow_beam_search_batch_config_t + flexflow_beam_search_batch_config_create(void); + +void flexflow_beam_search_batch_config_destroy( + flexflow_beam_search_batch_config_t handle); + +// ----------------------------------------------------------------------- +// RequestManager +// ----------------------------------------------------------------------- + +flexflow_request_manager_t flexflow_request_manager_get_request_manager(void); + +// void flexflow_request_manager_destroy(flexflow_request_manager_t handle_); + +void flexflow_request_manager_set_max_requests_per_batch( + flexflow_request_manager_t handle_, int max_num_requests); + +void flexflow_request_manager_set_max_tokens_per_batch( + flexflow_request_manager_t handle_, int max_num_tokens); + +void flexflow_request_manager_set_max_spec_tree_token_num( + flexflow_request_manager_t handle_, int max_num_tokens); + +void flexflow_request_manager_set_max_sequence_length( + flexflow_request_manager_t handle_, int max_seq_length); + +void flexflow_request_manager_register_tokenizer( + flexflow_request_manager_t handle_, + enum ModelType model_type, + int bos_token_id, + int eos_token_id, + char const *tokenizer_filepath); + +void flexflow_request_manager_register_output_filepath( + flexflow_request_manager_t handle_, char const *output_filepath); + +int flexflow_request_manager_register_ssm_model( + flexflow_request_manager_t handle_, flexflow_model_t model_handle_); + +void flexflow_request_manager_start_background_server( + flexflow_request_manager_t handle_, flexflow_model_t model_handle_); + +void flexflow_request_manager_terminate_background_server( + flexflow_request_manager_t handle_); + +// ----------------------------------------------------------------------- +// InferenceManager +// ----------------------------------------------------------------------- + +flexflow_inference_manager_t + flexflow_inference_manager_get_inference_manager(void); + +// void flexflow_inference_manager_destroy(flexflow_inference_manager_t +// handle_); + +void flexflow_inference_manager_compile_model_and_allocate_buffer( + flexflow_inference_manager_t handle_, flexflow_model_t model_handle); + +void flexflow_inference_manager_init_operators_inference( + flexflow_inference_manager_t handle_, flexflow_model_t model_handle); + +void flexflow_inference_manager_register_model_weights_loader( + flexflow_inference_manager_t handle_, + flexflow_model_t model_handle, + flexflow_file_data_loader_t loader_handle); + +// ----------------------------------------------------------------------- +// FileDataLoader +// ----------------------------------------------------------------------- + +flexflow_file_data_loader_t + flexflow_file_data_loader_create(char const *weight_file_path, + int num_q_heads, + int num_kv_heads, + int hidden_dim, + int qkv_inner_dim, + int tensor_parallelism_degree, + bool use_full_precision); + +void flexflow_file_data_loader_destroy(flexflow_file_data_loader_t handle_); + +void flexflow_file_data_loader_load_weights(flexflow_file_data_loader_t handle_, + flexflow_model_t model_handle_); + #ifdef __cplusplus } #endif diff --git a/include/flexflow/gpt_tokenizer.h b/include/flexflow/gpt_tokenizer.h new file mode 100644 index 0000000000..ec08435809 --- /dev/null +++ b/include/flexflow/gpt_tokenizer.h @@ -0,0 +1,221 @@ +// version 0.1 +// Licensed under the MIT License . +// SPDX-License-Identifier: MIT +// Copyright (c) 2019-2020 zili wang . + +#include +#include +#include +#include +#include +#include +#include +#include +#include +#include +#include +#include +#include + +using json = nlohmann::json; + +typedef std::pair bigram_pair; +typedef std::pair wbigram_pair; + +struct hash_pair { + template + size_t operator()(std::pair const &p) const { + auto hash1 = std::hash{}(p.first); + auto hash2 = std::hash{}(p.second); + return hash1 ^ hash2; + } +}; + +enum tokenizer_mode { GPT2_TOKENIZER, OPT_TOKENIZER }; + +class GPT_Tokenizer { + +public: + GPT_Tokenizer(tokenizer_mode mode_, + std::string const &vocab_file, + std::string const &merge_file, + std::string const &bos_token_str = "", + const std::string eos_token_str = "", + const std::string pad_token_str = "", + const std::string unk_token_str = "", + const std::string mask_token_str = "") { + mode = mode_; + load_vocab(vocab_file); + load_merge(merge_file); + bos_token = bos_token_str; + eos_token = eos_token_str; + pad_token = pad_token_str; + unk_token = unk_token_str; + mask_token = mask_token_str; + bytes_encoder = bytes_to_unicode(); + unicode_to_bytes(); + }; + // ~GPT_Tokenizer(); + std::vector bpe(std::wstring token); + std::vector tokenize(std::string str); + int32_t convert_token_to_id(std::string token); + void encode(std::string str, + size_t max_length, + std::vector *input_ids, + std::vector *mask_ids); + std::string decode(std::vector input_ids, + std::vector mask_ids); + tokenizer_mode mode; + std::string bos_token; + std::string eos_token; + std::string pad_token; + std::string unk_token; + std::string mask_token; + std::string strip(std::string const &inpt); + +private: + std::unordered_map vocab; + std::unordered_map inverse_vocab; + std::unordered_map bpe_ranks; + wchar_t *bytes_to_unicode(); + void unicode_to_bytes(); + wchar_t *bytes_encoder; + std::unordered_map bytes_decoder; + uint32_t cache_max_size = 500000; + uint32_t cache_word_max_length = 30; + std::string unicode_letter_expr = + "\\u0041-\\u005A\\u0061-\\u007A\\u00AA-\\u00AA\\u00B5-\\u00B5" + "\\u00BA-\\u00BA\\u00C0-\\u00D6\\u00D8-\\u00F6\\u00F8-\\u02C1" + "\\u02C6-\\u02D1\\u02E0-\\u02E4\\u02EC-\\u02EC\\u02EE-\\u02EE" + "\\u0370-\\u0374\\u0376-\\u0377\\u037A-\\u037D\\u037F-\\u037F" + "\\u0386-\\u0386\\u0388-\\u038A\\u038C-\\u038C\\u038E-\\u03A1" + "\\u03A3-\\u03F5\\u03F7-\\u0481\\u048A-\\u052F\\u0531-\\u0556" + "\\u0559-\\u0559\\u0560-\\u0588\\u05D0-\\u05EA\\u05EF-\\u05F2" + "\\u0620-\\u064A\\u066E-\\u066F\\u0671-\\u06D3\\u06D5-\\u06D5" + "\\u06E5-\\u06E6\\u06EE-\\u06EF\\u06FA-\\u06FC\\u06FF-\\u06FF" + "\\u0710-\\u0710\\u0712-\\u072F\\u074D-\\u07A5\\u07B1-\\u07B1" + "\\u07CA-\\u07EA\\u07F4-\\u07F5\\u07FA-\\u07FA\\u0800-\\u0815" + "\\u081A-\\u081A\\u0824-\\u0824\\u0828-\\u0828\\u0840-\\u0858" + "\\u0860-\\u086A\\u08A0-\\u08B4\\u08B6-\\u08C7\\u0904-\\u0939" + "\\u093D-\\u093D\\u0950-\\u0950\\u0958-\\u0961\\u0971-\\u0980" + "\\u0985-\\u098C\\u098F-\\u0990\\u0993-\\u09A8\\u09AA-\\u09B0" + "\\u09B2-\\u09B2\\u09B6-\\u09B9\\u09BD-\\u09BD\\u09CE-\\u09CE" + "\\u09DC-\\u09DD\\u09DF-\\u09E1\\u09F0-\\u09F1\\u09FC-\\u09FC" + "\\u0A05-\\u0A0A\\u0A0F-\\u0A10\\u0A13-\\u0A28\\u0A2A-\\u0A30" + "\\u0A32-\\u0A33\\u0A35-\\u0A36\\u0A38-\\u0A39\\u0A59-\\u0A5C" + "\\u0A5E-\\u0A5E\\u0A72-\\u0A74\\u0A85-\\u0A8D\\u0A8F-\\u0A91" + "\\u0A93-\\u0AA8\\u0AAA-\\u0AB0\\u0AB2-\\u0AB3\\u0AB5-\\u0AB9" + "\\u0ABD-\\u0ABD\\u0AD0-\\u0AD0\\u0AE0-\\u0AE1\\u0AF9-\\u0AF9" + "\\u0B05-\\u0B0C\\u0B0F-\\u0B10\\u0B13-\\u0B28\\u0B2A-\\u0B30" + "\\u0B32-\\u0B33\\u0B35-\\u0B39\\u0B3D-\\u0B3D\\u0B5C-\\u0B5D" + "\\u0B5F-\\u0B61\\u0B71-\\u0B71\\u0B83-\\u0B83\\u0B85-\\u0B8A" + "\\u0B8E-\\u0B90\\u0B92-\\u0B95\\u0B99-\\u0B9A\\u0B9C-\\u0B9C" + "\\u0B9E-\\u0B9F\\u0BA3-\\u0BA4\\u0BA8-\\u0BAA\\u0BAE-\\u0BB9" + "\\u0BD0-\\u0BD0\\u0C05-\\u0C0C\\u0C0E-\\u0C10\\u0C12-\\u0C28" + "\\u0C2A-\\u0C39\\u0C3D-\\u0C3D\\u0C58-\\u0C5A\\u0C60-\\u0C61" + "\\u0C80-\\u0C80\\u0C85-\\u0C8C\\u0C8E-\\u0C90\\u0C92-\\u0CA8" + "\\u0CAA-\\u0CB3\\u0CB5-\\u0CB9\\u0CBD-\\u0CBD\\u0CDE-\\u0CDE" + "\\u0CE0-\\u0CE1\\u0CF1-\\u0CF2\\u0D04-\\u0D0C\\u0D0E-\\u0D10" + "\\u0D12-\\u0D3A\\u0D3D-\\u0D3D\\u0D4E-\\u0D4E\\u0D54-\\u0D56" + "\\u0D5F-\\u0D61\\u0D7A-\\u0D7F\\u0D85-\\u0D96\\u0D9A-\\u0DB1" + "\\u0DB3-\\u0DBB\\u0DBD-\\u0DBD\\u0DC0-\\u0DC6\\u0E01-\\u0E30" + "\\u0E32-\\u0E33\\u0E40-\\u0E46\\u0E81-\\u0E82\\u0E84-\\u0E84" + "\\u0E86-\\u0E8A\\u0E8C-\\u0EA3\\u0EA5-\\u0EA5\\u0EA7-\\u0EB0" + "\\u0EB2-\\u0EB3\\u0EBD-\\u0EBD\\u0EC0-\\u0EC4\\u0EC6-\\u0EC6" + "\\u0EDC-\\u0EDF\\u0F00-\\u0F00\\u0F40-\\u0F47\\u0F49-\\u0F6C" + "\\u0F88-\\u0F8C\\u1000-\\u102A\\u103F-\\u103F\\u1050-\\u1055" + "\\u105A-\\u105D\\u1061-\\u1061\\u1065-\\u1066\\u106E-\\u1070" + "\\u1075-\\u1081\\u108E-\\u108E\\u10A0-\\u10C5\\u10C7-\\u10C7" + "\\u10CD-\\u10CD\\u10D0-\\u10FA\\u10FC-\\u1248\\u124A-\\u124D" + "\\u1250-\\u1256\\u1258-\\u1258\\u125A-\\u125D\\u1260-\\u1288" + "\\u128A-\\u128D\\u1290-\\u12B0\\u12B2-\\u12B5\\u12B8-\\u12BE" + "\\u12C0-\\u12C0\\u12C2-\\u12C5\\u12C8-\\u12D6\\u12D8-\\u1310" + "\\u1312-\\u1315\\u1318-\\u135A\\u1380-\\u138F\\u13A0-\\u13F5" + "\\u13F8-\\u13FD\\u1401-\\u166C\\u166F-\\u167F\\u1681-\\u169A" + "\\u16A0-\\u16EA\\u16F1-\\u16F8\\u1700-\\u170C\\u170E-\\u1711" + "\\u1720-\\u1731\\u1740-\\u1751\\u1760-\\u176C\\u176E-\\u1770" + "\\u1780-\\u17B3\\u17D7-\\u17D7\\u17DC-\\u17DC\\u1820-\\u1878" + "\\u1880-\\u1884\\u1887-\\u18A8\\u18AA-\\u18AA\\u18B0-\\u18F5" + "\\u1900-\\u191E\\u1950-\\u196D\\u1970-\\u1974\\u1980-\\u19AB" + "\\u19B0-\\u19C9\\u1A00-\\u1A16\\u1A20-\\u1A54\\u1AA7-\\u1AA7" + "\\u1B05-\\u1B33\\u1B45-\\u1B4B\\u1B83-\\u1BA0\\u1BAE-\\u1BAF" + "\\u1BBA-\\u1BE5\\u1C00-\\u1C23\\u1C4D-\\u1C4F\\u1C5A-\\u1C7D" + "\\u1C80-\\u1C88\\u1C90-\\u1CBA\\u1CBD-\\u1CBF\\u1CE9-\\u1CEC" + "\\u1CEE-\\u1CF3\\u1CF5-\\u1CF6\\u1CFA-\\u1CFA\\u1D00-\\u1DBF" + "\\u1E00-\\u1F15\\u1F18-\\u1F1D\\u1F20-\\u1F45\\u1F48-\\u1F4D" + "\\u1F50-\\u1F57\\u1F59-\\u1F59\\u1F5B-\\u1F5B\\u1F5D-\\u1F5D" + "\\u1F5F-\\u1F7D\\u1F80-\\u1FB4\\u1FB6-\\u1FBC\\u1FBE-\\u1FBE" + "\\u1FC2-\\u1FC4\\u1FC6-\\u1FCC\\u1FD0-\\u1FD3\\u1FD6-\\u1FDB" + "\\u1FE0-\\u1FEC\\u1FF2-\\u1FF4\\u1FF6-\\u1FFC\\u2071-\\u2071" + "\\u207F-\\u207F\\u2090-\\u209C\\u2102-\\u2102\\u2107-\\u2107" + "\\u210A-\\u2113\\u2115-\\u2115\\u2119-\\u211D\\u2124-\\u2124" + "\\u2126-\\u2126\\u2128-\\u2128\\u212A-\\u212D\\u212F-\\u2139" + "\\u213C-\\u213F\\u2145-\\u2149\\u214E-\\u214E\\u2183-\\u2184" + "\\u2C00-\\u2C2E\\u2C30-\\u2C5E\\u2C60-\\u2CE4\\u2CEB-\\u2CEE" + "\\u2CF2-\\u2CF3\\u2D00-\\u2D25\\u2D27-\\u2D27\\u2D2D-\\u2D2D" + "\\u2D30-\\u2D67\\u2D6F-\\u2D6F\\u2D80-\\u2D96\\u2DA0-\\u2DA6" + "\\u2DA8-\\u2DAE\\u2DB0-\\u2DB6\\u2DB8-\\u2DBE\\u2DC0-\\u2DC6" + "\\u2DC8-\\u2DCE\\u2DD0-\\u2DD6\\u2DD8-\\u2DDE\\u2E2F-\\u2E2F" + "\\u3005-\\u3006\\u3031-\\u3035\\u303B-\\u303C\\u3041-\\u3096" + "\\u309D-\\u309F\\u30A1-\\u30FA\\u30FC-\\u30FF\\u3105-\\u312F" + "\\u3131-\\u318E\\u31A0-\\u31BF\\u31F0-\\u31FF\\u3400-\\u4DBF" + "\\u4E00-\\u9FFC\\uA000-\\uA48C\\uA4D0-\\uA4FD\\uA500-\\uA60C" + "\\uA610-\\uA61F\\uA62A-\\uA62B\\uA640-\\uA66E\\uA67F-\\uA69D" + "\\uA6A0-\\uA6E5\\uA717-\\uA71F\\uA722-\\uA788\\uA78B-\\uA7BF" + "\\uA7C2-\\uA7CA\\uA7F5-\\uA801\\uA803-\\uA805\\uA807-\\uA80A" + "\\uA80C-\\uA822\\uA840-\\uA873\\uA882-\\uA8B3\\uA8F2-\\uA8F7" + "\\uA8FB-\\uA8FB\\uA8FD-\\uA8FE\\uA90A-\\uA925\\uA930-\\uA946" + "\\uA960-\\uA97C\\uA984-\\uA9B2\\uA9CF-\\uA9CF\\uA9E0-\\uA9E4" + "\\uA9E6-\\uA9EF\\uA9FA-\\uA9FE\\uAA00-\\uAA28\\uAA40-\\uAA42" + "\\uAA44-\\uAA4B\\uAA60-\\uAA76\\uAA7A-\\uAA7A\\uAA7E-\\uAAAF" + "\\uAAB1-\\uAAB1\\uAAB5-\\uAAB6\\uAAB9-\\uAABD\\uAAC0-\\uAAC0" + "\\uAAC2-\\uAAC2\\uAADB-\\uAADD\\uAAE0-\\uAAEA\\uAAF2-\\uAAF4" + "\\uAB01-\\uAB06\\uAB09-\\uAB0E\\uAB11-\\uAB16\\uAB20-\\uAB26" + "\\uAB28-\\uAB2E\\uAB30-\\uAB5A\\uAB5C-\\uAB69\\uAB70-\\uABE2" + "\\uAC00-\\uD7A3\\uD7B0-\\uD7C6\\uD7CB-\\uD7FB\\uF900-\\uFA6D" + "\\uFA70-\\uFAD9\\uFB00-\\uFB06\\uFB13-\\uFB17\\uFB1D-\\uFB1D" + "\\uFB1F-\\uFB28\\uFB2A-\\uFB36\\uFB38-\\uFB3C\\uFB3E-\\uFB3E" + "\\uFB40-\\uFB41\\uFB43-\\uFB44\\uFB46-\\uFBB1\\uFBD3-\\uFD3D" + "\\uFD50-\\uFD8F\\uFD92-\\uFDC7\\uFDF0-\\uFDFB\\uFE70-\\uFE74" + "\\uFE76-\\uFEFC\\uFF21-\\uFF3A\\uFF41-\\uFF5A\\uFF66-\\uFFBE" + "\\uFFC2-\\uFFC7\\uFFCA-\\uFFCF\\uFFD2-\\uFFD7\\uFFDA-\\uFFDC"; + + std::string unicode_number_expr = + "\\u0030-\\u0039\\u00B2-\\u00B3\\u00B9-\\u00B9\\u00BC-\\u00BE" + "\\u0660-\\u0669\\u06F0-\\u06F9\\u07C0-\\u07C9\\u0966-\\u096F" + "\\u09E6-\\u09EF\\u09F4-\\u09F9\\u0A66-\\u0A6F\\u0AE6-\\u0AEF" + "\\u0B66-\\u0B6F\\u0B72-\\u0B77\\u0BE6-\\u0BF2\\u0C66-\\u0C6F" + "\\u0C78-\\u0C7E\\u0CE6-\\u0CEF\\u0D58-\\u0D5E\\u0D66-\\u0D78" + "\\u0DE6-\\u0DEF\\u0E50-\\u0E59\\u0ED0-\\u0ED9\\u0F20-\\u0F33" + "\\u1040-\\u1049\\u1090-\\u1099\\u1369-\\u137C\\u16EE-\\u16F0" + "\\u17E0-\\u17E9\\u17F0-\\u17F9\\u1810-\\u1819\\u1946-\\u194F" + "\\u19D0-\\u19DA\\u1A80-\\u1A89\\u1A90-\\u1A99\\u1B50-\\u1B59" + "\\u1BB0-\\u1BB9\\u1C40-\\u1C49\\u1C50-\\u1C59\\u2070-\\u2070" + "\\u2074-\\u2079\\u2080-\\u2089\\u2150-\\u2182\\u2185-\\u2189" + "\\u2460-\\u249B\\u24EA-\\u24FF\\u2776-\\u2793\\u2CFD-\\u2CFD" + "\\u3007-\\u3007\\u3021-\\u3029\\u3038-\\u303A\\u3192-\\u3195" + "\\u3220-\\u3229\\u3248-\\u324F\\u3251-\\u325F\\u3280-\\u3289" + "\\u32B1-\\u32BF\\uA620-\\uA629\\uA6E6-\\uA6EF\\uA830-\\uA835" + "\\uA8D0-\\uA8D9\\uA900-\\uA909\\uA9D0-\\uA9D9\\uA9F0-\\uA9F9" + "\\uAA50-\\uAA59\\uABF0-\\uABF9\\uFF10-\\uFF19"; + + std::wstring wpat_expr = utf8_to_wstring( + "'s|'t|'re|'ve|'m|'ll|'d| ?[" + unicode_letter_expr + "]+| ?[" + + unicode_number_expr + "]+| ?[^\\s" + unicode_letter_expr + + unicode_number_expr + "]+|\\s+(?!\\S)|\\s+"); + + const std::wregex pat = std::wregex(wpat_expr); + std::unordered_map> cache; + void load_vocab(std::string const &vocab_file); + void load_merge(std::string const &merge_file); + + std::unordered_set + get_pairs(std::vector word); + std::wstring utf8_to_wstring(std::string const &src); + std::u32string utf8_to_utf32(std::string const &src); + std::string wstring_to_utf8(std::wstring const &src); + std::string utf32_to_utf8(std::u32string const &src); + + std::vector split(std::string const &s, + std::regex rgx = std::regex("\\s+")); +}; diff --git a/include/flexflow/inference.h b/include/flexflow/inference.h new file mode 100644 index 0000000000..f24a797ffd --- /dev/null +++ b/include/flexflow/inference.h @@ -0,0 +1,50 @@ +/* Copyright 2022 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#pragma once +#include "flexflow/batch_config.h" +#include +#include + +namespace FlexFlow { + +struct GenerationConfig { + bool do_sample = false; + float temperature = 0.8; + float topp = 0.6; + GenerationConfig(bool _do_sample, float _temperature, float _topp) { + temperature = _temperature > 0 ? _temperature : temperature; + topp = _topp > 0 ? _topp : topp; + do_sample = _do_sample; + } + GenerationConfig() {} +}; + +struct GenerationResult { + using RequestGuid = BatchConfig::RequestGuid; + using TokenId = BatchConfig::TokenId; + RequestGuid guid; + std::string input_text; + std::string output_text; + std::vector input_tokens; + std::vector output_tokens; +}; + +#include +#include + +std::string join_path(std::vector const &paths); + +} // namespace FlexFlow diff --git a/include/flexflow/layer.h b/include/flexflow/layer.h index 0c1d7a6092..69a57e4e1c 100644 --- a/include/flexflow/layer.h +++ b/include/flexflow/layer.h @@ -52,6 +52,7 @@ class Layer { bool trainableInputs[MAX_NUM_INPUTS]; int numInputs, numWeights, numOutputs; bool profiling; + bool inference_debugging; private: std::unordered_map int_properties; diff --git a/include/flexflow/machine_view.h b/include/flexflow/machine_view.h index b843555e06..807b0c9c0d 100644 --- a/include/flexflow/machine_view.h +++ b/include/flexflow/machine_view.h @@ -3,10 +3,12 @@ #include "legion.h" #include +#ifdef FF_USE_NCCL #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) #include #else -#include +#include +#endif #endif #include "flexflow/config.h" diff --git a/include/flexflow/mapper.h b/include/flexflow/mapper.h index 71be1892aa..e8337818ec 100644 --- a/include/flexflow/mapper.h +++ b/include/flexflow/mapper.h @@ -83,11 +83,10 @@ class FFMapper : public NullMapper { Task const &task, MapTaskInput const &input, MapTaskOutput &output); - virtual void map_replicate_task(const MapperContext ctx, - Task const &task, - MapTaskInput const &input, - MapTaskOutput const &default_output, - MapReplicateTaskOutput &output); + virtual void replicate_task(const MapperContext ctx, + Task const &task, + ReplicateTaskInput const &input, + ReplicateTaskOutput &output); virtual void select_task_variant(const MapperContext ctx, Task const &task, SelectVariantInput const &input, diff --git a/include/flexflow/model.h b/include/flexflow/model.h index fe73e6a0e3..dfbae3999f 100644 --- a/include/flexflow/model.h +++ b/include/flexflow/model.h @@ -17,6 +17,7 @@ #include "accessor.h" #include "config.h" #include "device.h" +#include "flexflow/inference.h" #include "flexflow/memory_optimization.h" #include "flexflow/node.h" #include "flexflow/operator_params.h" @@ -30,6 +31,7 @@ #include "optimizer.h" #include "parallel_tensor.h" #include "recompile.h" +#include "runtime.h" #include "simulator.h" #include "tensor.h" #include "tl/optional.hpp" @@ -50,11 +52,17 @@ enum TaskIDs { LOAD_IMAGES_TASK_ID, NORMALIZE_IMAGES_TASK_ID, ELEMENTBINARY_INIT_TASK_ID, + ELEMENTBINARY_INF_TASK_ID, ELEMENTBINARY_FWD_TASK_ID, ELEMENTBINARY_BWD_TASK_ID, ELEMENTUNARY_INIT_TASK_ID, ELEMENTUNARY_FWD_TASK_ID, + ELEMENTUNARY_INF_TASK_ID, ELEMENTUNARY_BWD_TASK_ID, + EXPERTS_INIT_TASK_ID, + EXPERTS_FWD_TASK_ID, + EXPERTS_BWD_TASK_ID, + EXPERTS_INF_TASK_ID, CONV2D_INIT_TASK_ID, CONV2D_INIT_PARA_TASK_ID, CONV2D_FWD_TASK_ID, @@ -65,6 +73,7 @@ enum TaskIDs { DROPOUT_BWD_TASK_ID, EMBED_INIT_TASK_ID, EMBED_FWD_TASK_ID, + EMBED_INF_TASK_ID, EMBED_BWD_TASK_ID, GATHER_INIT_TASK_ID, GATHER_FWD_TASK_ID, @@ -96,9 +105,17 @@ enum TaskIDs { BATCHMATMUL_BWD_TASK_ID, LAYERNORM_INIT_TASK_ID, LAYERNORM_FWD_TASK_ID, + LAYERNORM_INF_TASK_ID, LAYERNORM_BWD_TASK_ID, + RESIDUAL_LAYERNORM_INIT_TASK_ID, + RESIDUAL_LAYERNORM_INF_TASK_ID, + ADD_BIAS_RESIDUAL_LAYERNORM_INIT_TASK_ID, + ADD_BIAS_RESIDUAL_LAYERNORM_INF_TASK_ID, + SIGMOID_SILU_MULTI_INIT_TASK_ID, + SIGMOID_SILU_MULTI_INF_TASK_ID, LINEAR_INIT_TASK_ID, LINEAR_INIT_PARA_TASK_ID, + LINEAR_INF_TASK_ID, LINEAR_FWD_TASK_ID, LINEAR_BWD_TASK_ID, LINEAR_BWD2_TASK_ID, @@ -109,6 +126,7 @@ enum TaskIDs { SOFTMAX_INIT_TASK_ID, SOFTMAX_FWD_TASK_ID, SOFTMAX_BWD_TASK_ID, + SOFTMAX_INF_TASK_ID, CONCAT_INIT_TASK_ID, CONCAT_FWD_TASK_ID, CONCAT_BWD_TASK_ID, @@ -127,16 +145,40 @@ enum TaskIDs { TOPK_INIT_TASK_ID, TOPK_FWD_TASK_ID, TOPK_BWD_TASK_ID, + ARG_TOPK_INIT_TASK_ID, + ARG_TOPK_INF_TASK_ID, + ARG_TOPK_INF_SPECULATIVE_TASK_ID, + SAMPLING_INIT_TASK_ID, + SAMPLING_INF_TASK_ID, + ARGMAX_INIT_TASK_ID, + ARGMAX_BEAM_INF_TASK_ID, + ARGMAX_NORM_INF_TASK_ID, TRANSPOSE_INIT_TASK_ID, TRANSPOSE_FWD_TASK_ID, TRANSPOSE_BWD_TASK_ID, ATTENTION_INIT_TASK_ID, ATTENTION_FWD_TASK_ID, ATTENTION_BWD_TASK_ID, + RMSNORM_INIT_TASK_ID, + RMSNORM_FWD_TASK_ID, + RMSNORM_INF_TASK_ID, + RESIDUAL_RMSNORM_INIT_TASK_ID, + RESIDUAL_RMSNORM_INF_TASK_ID, + BEAM_TOPK_INIT_TASK_ID, + BEAM_TOPK_INF_TASK_ID, + INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + INC_MULTIHEAD_SELF_ATTENTION_FWD_TASK_ID, + INC_MULTIHEAD_SELF_ATTENTION_BWD_TASK_ID, + INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + TREE_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + TREE_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, MSELOSS_BWD_TASK_ID, FUSEDOP_INIT_TASK_ID, FUSEDOP_FWD_TASK_ID, FUSEDOP_BWD_TASK_ID, + FUSEDOP_INF_TASK_ID, NOOP_INIT_TASK_ID, // Metrics tasks METRICS_COMP_TASK_ID, @@ -161,6 +203,7 @@ enum TaskIDs { // NCCL tasks NCCL_GETUNIQUEID_TASK_ID, NCCL_INIT_COMMS_TASK_ID, + NCCL_FINISH_COMMS_TASK_ID, // Search STRATEGY_SEARCH_TASK_ID, // Graph @@ -198,6 +241,15 @@ enum TaskIDs { FUSED_PARALLELOP_INIT_TASK_ID, FUSED_PARALLELOP_FWD_TASK_ID, FUSED_PARALLELOP_BWD_TASK_ID, + // InferenceManager & RequestManager + RM_LOAD_TOKENS_TASK_ID, + RM_LOAD_POSITION_TASK_ID, + RM_LOAD_BATCH_CONFIG_TASK_ID, + RM_PREPARE_NEXT_BATCH_TASK_ID, + RM_PREPARE_NEXT_BATCH_INIT_TASK_ID, + RM_PREPARE_NEXT_BATCH_BEAM_TASK_ID, + RM_PREPARE_NEXT_BATCH_VERIFY_TASK_ID, + RM_BACKGROUND_SERVING_TASK_ID, // Custom tasks CUSTOM_GPU_TASK_ID_FIRST, CUSTOM_GPU_TASK_ID_1, @@ -221,6 +273,8 @@ enum TaskIDs { // Make sure PYTHON_TOP_LEVEL_TASK_ID is // consistent with python/main.cc PYTHON_TOP_LEVEL_TASK_ID = 11111, + // Tensor Equal Task + TENSOR_EQUAL_TASK_ID, }; enum ShardingID { @@ -264,24 +318,38 @@ class Dropout; class ElementBinary; class ElementUnary; class Embedding; +class Experts; class Flat; class Gather; class Group_by; class LayerNorm; +class ResidualLayerNorm; +class AddBiasResidualLayerNorm; +class SigmoidSiluMulti; class Linear; class MultiHeadAttention; +class IncMultiHeadSelfAttention; +class TreeIncMultiHeadSelfAttention; class Pool2D; class Reduce; class Reshape; class Softmax; class Split; class TopK; +class ArgTopK; class Transpose; +class RMSNorm; +class ResidualRMSNorm; +class BeamTopK; +class SpecIncMultiHeadSelfAttention; +class Sampling; +class ArgMax; class Combine; class AllReduce; class Repartition; class Reduction; class Replicate; +class AllReduce; class FusedParallelOp; class ParallelOpInfo; @@ -331,12 +399,14 @@ std::vector class FFModel { public: - FFModel(FFConfig &config); + FFModel(FFConfig &config, bool cpu_offload = false); + ~FFModel(); static constexpr float PROPAGATION_CHANCE = 0.25; static constexpr float CONTINUE_PROPAGATION_CHANCE = 0.75; static constexpr float PROPAGATION_SIZE_WEIGHT = 1.0; + bool cpu_offload; // C++ APIs for constructing models // Add an exp layer Tensor exp(const Tensor x, char const *name = NULL); @@ -428,7 +498,7 @@ class FFModel { char const *name = NULL); // Add an embedding layer Tensor embedding(const Tensor input, - int num_entires, + int num_entries, int outDim, AggrMode aggr, DataType dtype = DT_FLOAT, @@ -474,13 +544,41 @@ class FFModel { PoolType type = POOL_MAX, ActiMode activation = AC_MODE_NONE, char const *name = NULL); - // Add a batch_norm layer + // Add a layer_norm layer Tensor layer_norm(const Tensor input, std::vector const &axes, bool elementwise_affine, float eps, + bool use_bias = true, DataType data_type = DT_NONE, char const *name = NULL); + // Add a layer_norm layer with residual(s) + void residual_layer_norm(const Tensor input, + const Tensor residual1, + const Tensor residual2, + Tensor *outputs, + bool use_two_residuals, + std::vector const &axes, + bool elementwise_affine, + float eps, + bool use_bias = true, + DataType data_type = DT_NONE, + char const *name = NULL); + // Add a add_bias_residual_layer_norm layer + void add_bias_residual_layer_norm(const Tensor input, + const Tensor residual, + Tensor *outputs, + std::vector const &axes, + bool elementwise_affine, + float eps, + bool use_bias = true, + DataType data_type = DT_NONE, + char const *name = NULL); + // Add a sigmoid_silu_multi layer + Tensor sigmoid_silu_multi(const Tensor input1, + const Tensor input2, + DataType data_type = DT_NONE, + char const *name = NULL); // Add a batch_norm layer Tensor batch_norm(const Tensor input, bool relu = true, char const *name = NULL); @@ -490,12 +588,32 @@ class FFModel { int a_seq_length_dim = -1, int b_seq_length_dim = -1, char const *name = nullptr); + // Add a root mean square layer + Tensor rms_norm(const Tensor input, + float eps, + int dim, + DataType data_type = DT_NONE, + char const *name = NULL); + // Add a residual root mean square layer + void residual_rms_norm(const Tensor input1, + const Tensor input2, + Tensor *outputs, + float eps, + int dim, + DataType data_type = DT_NONE, + char const *name = NULL); + // Add a beam search top k layer + Tensor beam_top_k(const Tensor input, + int max_beam_size, + bool sorted, + char const *name = NULL); + // Add a dense layer Tensor dense(const Tensor input, int outDim, ActiMode activation = AC_MODE_NONE, bool use_bias = true, - DataType data_type = DT_FLOAT, + DataType data_type = DT_NONE, Layer const *shared_op = NULL, Initializer *kernel_initializer = NULL, Initializer *bias_initializer = NULL, @@ -507,6 +625,16 @@ class FFModel { // Add a concat layer Tensor concat(int n, Tensor const *tensors, int axis, char const *name = NULL); + // Add an experts layer + Tensor experts( + Tensor const *inputs, + int num_experts, + int experts_start_idx, + int experts_output_dim_size, + float alpha, + int experts_num_layers = 1, // number of linear layers per expert + int experts_internal_dim_size = 0, // hidden dimension for internal layers + char const *name = NULL); // Add a mean layer Tensor mean(const Tensor input, std::vector const &dims, @@ -530,6 +658,7 @@ class FFModel { // Add a softmax layer Tensor softmax(const Tensor input, int dim = -1, + DataType data_type = DT_NONE, bool last_layer = false, char const *name = NULL); // Create input tensors and constants @@ -549,6 +678,14 @@ class FFModel { int k, bool sorted, char const *name = NULL); + Tensor arg_top_k(const Tensor input, + // Tensor *outputs, + int k, + bool sorted, + bool speculative_decoding, + char const *name = NULL); + Tensor argmax(const Tensor input, bool beam_search, char const *name = NULL); + Tensor sampling(const Tensor input, float top_p, char const *name = NULL); Tensor multihead_attention(const Tensor query, const Tensor key, const Tensor value, @@ -560,8 +697,124 @@ class FFModel { bool bias = true, bool add_bias_kv = false, bool add_zero_attn = false, + DataType data_type = DT_NONE, Initializer *kernel_initializer = NULL, char const *name = NULL); + Tensor inc_multihead_self_attention(const Tensor input, + int embed_dim, + int num_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + Tensor + spec_inc_multihead_self_attention(const Tensor input, + int embed_dim, + int num_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + Tensor inc_multihead_self_attention_verify( + const Tensor input, + int embed_dim, + int num_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + Tensor inc_multiquery_self_attention(const Tensor input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + Tensor + spec_inc_multiquery_self_attention(const Tensor input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + Tensor inc_multiquery_self_attention_verify( + const Tensor input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim = 0, + int vdim = 0, + float dropout = 0.0f, + bool bias = false, + bool add_bias_kv = false, + bool add_zero_attn = false, + DataType data_type = DT_NONE, + Initializer *kernel_initializer = NULL, + bool apply_rotary_embedding = false, + bool scaling_query = false, + float scaling_factor = 1.0f, + bool qk_prod_scaling = true, + bool position_bias = false, + char const *name = NULL); + // ======================================== + // Inference APIs + // ======================================== + std::vector generate(std::vector &prompts, + int max_seq_length); + Tensor create_tensor_legion_ordering(int num_dim, int const dims[], DataType data_type, @@ -693,6 +946,7 @@ class FFModel { auto input_shapes = get_input_shape(input); if (!params.is_valid(input_shapes)) { + printf("!params.is_valid(input_shapes)\n"); return PCG::Node::INVALID_NODE; } @@ -700,7 +954,7 @@ class FFModel { std::pair::type, Params> key{ input_shapes, params}; - auto &cache = get::type, Params>, T *>>(this->cached_ops); auto const &it = cache.find(key); @@ -775,17 +1029,33 @@ class FFModel { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + // ======================================== + // Internal APIs that should not be invoked from applications + // ======================================== void reset_metrics(); void init_operators(); + void init_operators_inference( + std::vector const &batch_inputs, + std::vector const &batch_outputs); void prefetch(); void forward(int seq_length = -1); void compute_metrics(); void get_metrics(); void backward(int seq_length = -1); void update(); + bool apply_fusion( + std::vector const &operators, + std::vector &new_operators, + std::unordered_map> + *parallel_tensor_mapping = nullptr); + bool check_operators_integrity( + std::vector const &old_operators, + std::unordered_map> + *pt_mapping = nullptr); void unified_update(); bool apply_fusion(std::vector const &operators, std::vector &new_operators); + Op *get_final_operator() const; void compile(LossType loss_type, std::vector const &metrics, @@ -794,6 +1064,9 @@ class FFModel { LossType loss_type, std::vector const &metrics, CompMode comp_mode = COMP_MODE_TRAINING); + void compile_inference(); + void set_transformer_layer_id(int id); + void set_position_offset(int offset); void graph_optimize(size_t budget, bool only_data_parallel, std::unique_ptr &best_graph, @@ -827,7 +1100,7 @@ class FFModel { std::unordered_map>> get_bwd_edge_map() const; - // Internal funcitons + // Internal functions Legion::IndexSpace get_or_create_task_is(ParallelConfig const &pc); Legion::IndexSpace get_or_create_task_is(MachineView const &view); Legion::IndexSpace get_or_create_task_is(Legion::Domain const &domain); @@ -835,6 +1108,7 @@ class FFModel { Legion::IndexSpace get_task_is(Legion::Domain const &domain) const; Legion::IndexSpace get_task_is(ParallelConfig const &pc) const; Legion::IndexSpace get_task_is(MachineView const &view) const; + bool is_transformer_block(int layer_idx) const; bool is_mlp_block(int layer_idx) const; void create_operators_from_layers(); @@ -852,6 +1126,9 @@ class FFModel { public: size_t op_global_guid, layer_global_guid; size_t tensor_global_guid, parallel_tensor_global_guid, node_global_guid; + size_t current_transformer_layer_id; + // positional embedding start offset + int position_offset; FFConfig config; FFIterationConfig iter_config; Optimizer *optimizer; @@ -897,6 +1174,9 @@ class FFModel { ElementUnary *>, std::unordered_map, Embedding *>, + std::unordered_map< + std::pair, ExpertsParams>, + Experts *>, std::unordered_map, Flat *>, std::unordered_map< std::pair, @@ -908,6 +1188,19 @@ class FFModel { Group_by *>, std::unordered_map, LayerNorm *>, + std::unordered_map, + ResidualLayerNormParams>, + ResidualLayerNorm *>, + std::unordered_map< + std::pair, + AddBiasResidualLayerNormParams>, + AddBiasResidualLayerNorm *>, + std::unordered_map< + std::pair, + SigmoidSiluMultiParams>, + SigmoidSiluMulti *>, std::unordered_map, Linear *>, std::unordered_map, @@ -917,6 +1210,21 @@ class FFModel { ParallelTensorShape>, MultiHeadAttentionParams>, MultiHeadAttention *>, + std::unordered_map< + std::pair, + IncMultiHeadSelfAttention *>, + std::unordered_map, + BeamTopK *>, + std::unordered_map, + Sampling *>, + std::unordered_map, + ArgMax *>, + std::unordered_map< + std::pair, + SpecIncMultiHeadSelfAttention *>, + std::unordered_map< + std::pair, + TreeIncMultiHeadSelfAttention *>, std::unordered_map, Reduce *>, std::unordered_map, @@ -925,8 +1233,16 @@ class FFModel { std::unordered_map, Softmax *>, std::unordered_map, TopK *>, + std::unordered_map, + ArgTopK *>, std::unordered_map, Transpose *>, + std::unordered_map, + RMSNorm *>, + std::unordered_map< + std::pair, + ResidualRMSNormParams>, + ResidualRMSNorm *>, std::unordered_map, Repartition *>, std::unordered_map, @@ -937,12 +1253,16 @@ class FFModel { AllReduce *>, std::unordered_map, Combine *>, + std::unordered_map, + AllReduce *>, std::unordered_map, FusedParallelOp *>> cached_ops; std::unordered_map cached_noop_ops; std::unordered_map cached_input_ops; std::vector all_valid_views; + int model_id; // unique incremental id assigned to each model. Used in the + // inference_debugging mode. #ifdef FF_USE_NCCL std::unordered_map view_hash_to_nccl_comms; #endif @@ -971,6 +1291,9 @@ class FFModel { ElementUnary * unary(OperatorType op, char const *name = NULL, float scalar = 0.0); PCG::Node new_node(Op *); + static int model_counter; // number of instantiated FFModel objects. Used to + // assign a unique incremental id to each model. + // Used in the inference_debugging mode. }; class UtilityTasks { diff --git a/include/flexflow/op_meta.h b/include/flexflow/op_meta.h index 512844db92..60785a1e29 100644 --- a/include/flexflow/op_meta.h +++ b/include/flexflow/op_meta.h @@ -15,6 +15,10 @@ class OpMeta { public: FFHandler handle; bool profiling; // Measure the run time of the task + bool inference_debugging; + int decoding_step; + char op_name[MAX_OPNAME]; + LayerID layer_guid; bool trainableInputs[MAX_NUM_INPUTS]; DataType input_type[MAX_NUM_INPUTS]; DataType weight_type[MAX_NUM_WEIGHTS]; diff --git a/include/flexflow/operator.h b/include/flexflow/operator.h index 3fd84ce55b..1b19bdb82f 100644 --- a/include/flexflow/operator.h +++ b/include/flexflow/operator.h @@ -1,12 +1,22 @@ #ifndef _OPERATOR_H #define _OPERATOR_H +#include "flexflow/accessor.h" +#include "flexflow/batch_config.h" #include "flexflow/fftype.h" #include "flexflow/machine_view.h" #include "flexflow/parallel_tensor.h" #include "flexflow/utils/dot/record_formatter.h" #include +#include +#include +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + namespace FlexFlow { extern LegionRuntime::Logger::Category log_measure; @@ -19,11 +29,33 @@ enum class MappingRecordType { INPUT_OUTPUT, INPUT_WEIGHT }; enum class MappingOperation { PARTITION, REPLICATE }; +/** @brief A class to keep track of a dimension relation between two tensors + * used by an operator. + * + * Dimension relations are one-to-one mappings between the dimensions of the + * input, weights, and output tensors of an operator. Introduced in the Unity + * paper, dimension relations allow FlexFlow to keep track of an operator's + * parallelization plans as part of the Parallel Computation Graph (PCG). + * + * Each ParallelDimMappingRecord only keeps track of a single dimension + * relation. + * + * ParallelDimMappingRecord objects must be initialized with a + * MappingRecordType, which can be INPUT_OUTPUT, if the ParallelDimMappingRecord + * is tracking a dimension relation between the input and the output tensor, or + * INPUT_WEIGHT, if the ParallelDimMappingRecord is tracking a dimension + * relation between the input tensor and the weights tensor. + * + */ class ParallelDimMappingRecord { private: ParallelDimMappingRecord(MappingRecordType); public: + /** + * @brief We disable this constructor because ParallelDimMappingRecord objects + * must specify the MappingRecordType upon creation. + */ ParallelDimMappingRecord() = delete; static ParallelDimMappingRecord input_output_record( @@ -160,6 +192,7 @@ class Op { const ParallelTensor input4 = NULL); Op(int guid, bool profiling, + bool inference_debugging, OperatorType otype, DataType dtype, char const *name, @@ -185,9 +218,143 @@ class Op { virtual bool get_weight_parameter(TNParameter, DIMParameter, int *) const; // Pure virtual functions that must be implemented virtual void init(FFModel const &) = 0; + virtual void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) { + assert(false); + }; virtual void forward(FFModel const &) = 0; virtual void backward(FFModel const &) = 0; + // Pure virtual functions for inference + virtual Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) { + assert(false); + }; virtual void print_layer(FFModel const &model) = 0; + template + static std::string get_op_name_without_uid(OpMetaType *m) { + std::string op_name_without_uid = std::string(m->op_name); + size_t last_underscore = op_name_without_uid.length() - 1; + for (int i = op_name_without_uid.length() - 1; i > 0; i--) { + if (!(std::isdigit(m->op_name[i]) || m->op_name[i] == '_')) { + break; + } else if (m->op_name[i] == '_') { + last_underscore = i; + } + } + op_name_without_uid.erase(last_underscore); + return op_name_without_uid; + } + template + static void save_inference_tensors_to_file( + OpMetaType *m, + int shard_id, + BatchConfig const *bc, + std::vector input_tensors, + std::vector weight_tensors, + std::vector output_tensors, + bool before_kernel = false) { + // Check if output directory exists, and create it if it does not + char const *folder_path = "./inference_tensors"; + struct stat st = {0}; + if (stat(folder_path, &st) == -1) { + // Directory does not exist, create it + mkdir(folder_path, 0700); + } + // output base filepath, shared by all tensors from the same operator + std::string op_name_without_uid = get_op_name_without_uid(m); + std::string base_filepath = + "./inference_tensors/model_" + std::to_string(m->layer_guid.model_id) + + "_decoding-step_" + std::to_string(m->decoding_step) + "_layer-num_" + + std::to_string(m->layer_guid.transformer_layer_id) + "_layer-name_" + + op_name_without_uid + "_shard-id_" + std::to_string(shard_id); + if (before_kernel) { + base_filepath += "_pre"; + } + // save batch config, if passed + if (bc != nullptr) { + bc->save_to_file(base_filepath + "_batch-config"); + } + // save all inputs + for (int i = 0; i < input_tensors.size(); i++) { + std::string filename = base_filepath + "_input_" + std::to_string(i); + if (input_tensors[i].data_type == DT_FLOAT) { + save_tensor(input_tensors[i].get_float_ptr(), + input_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (input_tensors[i].data_type == DT_HALF) { + save_tensor(input_tensors[i].get_half_ptr(), + input_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (input_tensors[i].data_type == DT_INT32) { + save_tensor(input_tensors[i].get_int32_ptr(), + input_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (input_tensors[i].data_type == DT_INT64) { + save_tensor(input_tensors[i].get_int64_ptr(), + input_tensors[i].domain.get_volume(), + filename.c_str()); + } else { + assert(false && "Tensor data type not supported"); + } + } + // only dump the weights once + if (m->decoding_step == 0) { + for (int i = 0; i < weight_tensors.size(); i++) { + std::string filename = base_filepath + "_weight_" + std::to_string(i); + if (weight_tensors[i].data_type == DT_FLOAT) { + save_tensor(weight_tensors[i].get_float_ptr(), + weight_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (weight_tensors[i].data_type == DT_HALF) { + save_tensor(weight_tensors[i].get_half_ptr(), + weight_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (weight_tensors[i].data_type == DT_INT32) { + save_tensor(weight_tensors[i].get_int32_ptr(), + weight_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (weight_tensors[i].data_type == DT_INT64) { + save_tensor(weight_tensors[i].get_int64_ptr(), + weight_tensors[i].domain.get_volume(), + filename.c_str()); + } else { + assert(false && "Tensor data type not supported"); + } + } + } + // save all outputs + for (int i = 0; i < output_tensors.size(); i++) { + std::string filename = base_filepath + "_output_" + std::to_string(i); + if (output_tensors[i].data_type == DT_FLOAT) { + save_tensor(output_tensors[i].get_float_ptr(), + output_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (output_tensors[i].data_type == DT_HALF) { + save_tensor(output_tensors[i].get_half_ptr(), + output_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (output_tensors[i].data_type == DT_INT32) { + save_tensor(output_tensors[i].get_int32_ptr(), + output_tensors[i].domain.get_volume(), + filename.c_str()); + } else if (output_tensors[i].data_type == DT_INT64) { + save_tensor(output_tensors[i].get_int64_ptr(), + output_tensors[i].domain.get_volume(), + filename.c_str()); + } else { + assert(false && "Tensor data type not supported"); + } + } + // increase count of decoding steps + if (!before_kernel) { + m->decoding_step++; + } + } virtual bool measure_operator_cost(Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const = 0; @@ -239,15 +406,29 @@ class Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void + finish_nccl_comms_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); #endif protected: void set_argumentmap_for_init(FFModel const &ff, Legion::ArgumentMap &argmap); + void set_argumentmap_for_init_inference(FFModel const &ff, + Legion::ArgumentMap &argmap, + ParallelTensor const output0); void set_argumentmap_for_forward(FFModel const &ff, Legion::ArgumentMap &argmap); + void set_argumentmap_for_inference(FFModel const &ff, + Legion::ArgumentMap &argmap, + ParallelTensor const output0); void set_argumentmap_for_backward(FFModel const &ff, Legion::ArgumentMap &argmap); void set_opmeta_from_futuremap(FFModel const &ff, Legion::FutureMap const &fm); + void set_opmeta_from_futuremap_inference(FFModel const &ff, + Legion::FutureMap const &fm, + ParallelTensor const output0); void solve_parallel_dim_mappings( std::vector const &inputs, std::vector const &weights, @@ -267,8 +448,11 @@ class Op { ParallelParameter weights[MAX_NUM_WEIGHTS]; bool trainableInputs[MAX_NUM_INPUTS]; OpMeta *meta[MAX_NUM_WORKERS]; + std::map inference_meta; int numInputs, numWeights, numOutputs; bool profiling; + bool inference_debugging; + bool add_bias_only_once; #ifdef FF_USE_NCCL ncclUniqueId ncclId; #endif diff --git a/include/flexflow/operator_params.h b/include/flexflow/operator_params.h index 84653ac9ca..b6815968ba 100644 --- a/include/flexflow/operator_params.h +++ b/include/flexflow/operator_params.h @@ -1,10 +1,14 @@ #ifndef _OPERATOR_PARAMS_H #define _OPERATOR_PARAMS_H +#include "flexflow/ops/add_bias_residual_layer_norm_params.h" #include "flexflow/ops/aggregate_params.h" #include "flexflow/ops/aggregate_spec_params.h" +#include "flexflow/ops/arg_topk_params.h" +#include "flexflow/ops/argmax_params.h" #include "flexflow/ops/attention_params.h" #include "flexflow/ops/batch_matmul_params.h" +#include "flexflow/ops/beam_topk_params.h" #include "flexflow/ops/cast_params.h" #include "flexflow/ops/concat_params.h" #include "flexflow/parallel_ops/allreduce_params.h" @@ -13,18 +17,28 @@ #include "flexflow/ops/element_binary_params.h" #include "flexflow/ops/element_unary_params.h" #include "flexflow/ops/embedding_params.h" +#include "flexflow/ops/experts_params.h" #include "flexflow/ops/flat_params.h" #include "flexflow/ops/gather_params.h" #include "flexflow/ops/groupby_params.h" +#include "flexflow/ops/inc_multihead_self_attention_params.h" #include "flexflow/ops/layer_norm_params.h" #include "flexflow/ops/linear_params.h" #include "flexflow/ops/pool_2d_params.h" #include "flexflow/ops/reduce_params.h" #include "flexflow/ops/reshape_params.h" +#include "flexflow/ops/residual_layer_norm_params.h" +#include "flexflow/ops/residual_rms_norm_params.h" +#include "flexflow/ops/rms_norm_params.h" +#include "flexflow/ops/sampling_params.h" +#include "flexflow/ops/sigmoid_silu_multi_params.h" #include "flexflow/ops/softmax_params.h" +#include "flexflow/ops/spec_inc_multihead_self_attention_params.h" #include "flexflow/ops/split_params.h" #include "flexflow/ops/topk_params.h" #include "flexflow/ops/transpose_params.h" +#include "flexflow/ops/tree_inc_multihead_self_attention_params.h" +#include "flexflow/parallel_ops/allreduce_params.h" #include "flexflow/parallel_ops/combine_params.h" #include "flexflow/parallel_ops/fused_parallel_op_params.h" #include "flexflow/parallel_ops/partition_params.h" @@ -50,13 +64,25 @@ using OperatorParameters = mp::variant; + AddBiasResidualLayerNorm(FFModel &model, + Params const ¶ms, + Input const &inputs, + char const *name = nullptr, + bool allocate_weights = false); + AddBiasResidualLayerNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + const ParallelTensor _residual, + std::vector const &axes, + bool _elementwise_affine, + bool _use_bias, + float _eps, + bool allocate_weights, + char const *name); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + + AddBiasResidualLayerNormParams get_params() const; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void inference_kernel(AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + T const *input_ptr, + T const *attn_bias_ptr, + T const *residual_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + ffStream_t stream); + static void inference_kernel_wrapper(AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + GenericTensorAccessorR const &input, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &residual, + GenericTensorAccessorR const &attn_bias, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta); + +public: + bool elementwise_affine, use_bias; + int64_t effective_batch_size, effective_num_elements; + float eps; + std::vector axes; +}; + +class AddBiasResidualLayerNormMeta : public OpMeta { +public: + AddBiasResidualLayerNormMeta(FFHandler handle, + AddBiasResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator); + ~AddBiasResidualLayerNormMeta(void); + +public: + bool elementwise_affine, use_bias; + int64_t effective_batch_size, effective_num_elements; + float eps; + void *mean_ptr, *rstd_ptr, *ds_ptr, *db_ptr, *scale_ptr, *bias_ptr; + Realm::RegionInstance reserveInst; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/ops/add_bias_residual_layer_norm_params.h b/include/flexflow/ops/add_bias_residual_layer_norm_params.h new file mode 100644 index 0000000000..87fe2fb562 --- /dev/null +++ b/include/flexflow/ops/add_bias_residual_layer_norm_params.h @@ -0,0 +1,30 @@ +#pragma once + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct AddBiasResidualLayerNormParams { + LayerID layer_guid; + std::vector axes; + bool elementwise_affine; + float eps; + bool use_bias; + char name[MAX_OPNAME]; + bool is_valid( + std::pair const &) const; +}; + +bool operator==(AddBiasResidualLayerNormParams const &, + AddBiasResidualLayerNormParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::AddBiasResidualLayerNormParams const &) const; +}; +} // namespace std diff --git a/include/flexflow/ops/aggregate.h b/include/flexflow/ops/aggregate.h index 4eeb695e92..3ba4f414d1 100644 --- a/include/flexflow/ops/aggregate.h +++ b/include/flexflow/ops/aggregate.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_AGGREGATE_H_ #define _FLEXFLOW_AGGREGATE_H_ +#include "flexflow/inference.h" #include "flexflow/model.h" #include "flexflow/ops/aggregate_params.h" @@ -8,7 +9,7 @@ namespace FlexFlow { #define AGGREGATE_MAX_K 4 #define AGGREGATE_MAX_BATCH_SIZE 64 -#define AGGREGATE_MAX_N 12 +#define AGGREGATE_MAX_N 128 class AggregateMeta : public OpMeta { public: @@ -26,7 +27,7 @@ class Aggregate : public Op { ParallelTensor const *inputs, int _n, float _lambda_bal, - char const *name); + char const *name = nullptr); Aggregate(FFModel &model, Aggregate const &other, std::vector const &inputs); @@ -35,7 +36,16 @@ class Aggregate : public Op { Input const &inputs, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; void print_layer(FFModel const &model) override { assert(0); @@ -81,6 +91,10 @@ class Aggregate : public Op { int const batch_size, int out_dim); void serialize(Legion::Serializer &s) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + Input const &inputs, + int num_inputs); bool measure_operator_cost(Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const override; diff --git a/include/flexflow/ops/aggregate_params.h b/include/flexflow/ops/aggregate_params.h index f746881d89..deaa04b3e7 100644 --- a/include/flexflow/ops/aggregate_params.h +++ b/include/flexflow/ops/aggregate_params.h @@ -9,6 +9,7 @@ namespace FlexFlow { struct AggregateParams { int n; float lambda_bal; + char name[MAX_OPNAME]; bool is_valid(std::vector const &) const; }; bool operator==(AggregateParams const &, AggregateParams const &); diff --git a/include/flexflow/ops/aggregate_spec.h b/include/flexflow/ops/aggregate_spec.h index 8c1966e72a..4302dd0733 100644 --- a/include/flexflow/ops/aggregate_spec.h +++ b/include/flexflow/ops/aggregate_spec.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_AGGREGATE_SPEC_H_ #define _FLEXFLOW_AGGREGATE_SPEC_H_ +#include "flexflow/inference.h" #include "flexflow/model.h" #include "flexflow/ops/aggregate_spec_params.h" @@ -27,7 +28,16 @@ class AggregateSpec : public Op { float _lambda_bal, char const *name); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; void print_layer(FFModel const &model) override { assert(0); diff --git a/include/flexflow/ops/aggregate_spec_params.h b/include/flexflow/ops/aggregate_spec_params.h index eb662f4c07..69e8574cba 100644 --- a/include/flexflow/ops/aggregate_spec_params.h +++ b/include/flexflow/ops/aggregate_spec_params.h @@ -9,6 +9,7 @@ namespace FlexFlow { struct AggregateSpecParams { int n; float lambda_bal; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(AggregateSpecParams const &, AggregateSpecParams const &); diff --git a/include/flexflow/ops/arg_topk.h b/include/flexflow/ops/arg_topk.h new file mode 100644 index 0000000000..3822a5e41e --- /dev/null +++ b/include/flexflow/ops/arg_topk.h @@ -0,0 +1,110 @@ +#ifndef _FLEXFLOW_ARG_TOPK_H_ +#define _FLEXFLOW_ARG_TOPK_H_ + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/node.h" +#include "flexflow/ops/arg_topk_params.h" + +namespace FlexFlow { + +class ArgTopKMeta : public OpMeta { +public: + ArgTopKMeta(FFHandler handle, Op const *op); + bool sorted; + int k; + bool speculative_decoding; +}; + +class ArgTopK : public Op { +public: + using Params = ArgTopKParams; + using Input = ParallelTensor; + ArgTopK(FFModel &model, + LayerID const &layer_guid, + const ParallelTensor input, + int k, + bool sorted, + bool speculative_decoding, + char const *name); + ArgTopK(FFModel &model, + LayerID const &layer_guid, + ArgTopK const &other, + const ParallelTensor input); + ArgTopK(FFModel &model, + Params const ¶ms, + Input const input, + char const *name = nullptr); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static InferenceResult + inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static BeamInferenceResult inference_speculative_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + void serialize(Legion::Serializer &s) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void forward_kernel(ArgTopKMeta const *m, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + size_t batch_size, + int length, + int k, + bool sorted, + BeamSearchBatchConfig const *bc, + ffStream_t stream); + static void forward_kernel_wrapper(ArgTopKMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &prob, + GenericTensorAccessorW const &indices, + int batch_size, + BeamSearchBatchConfig const *bc); + Params get_params() const; + +public: + int k; + bool sorted; + bool speculative_decoding; +}; + +}; // namespace FlexFlow + +#endif diff --git a/include/flexflow/ops/arg_topk_params.h b/include/flexflow/ops/arg_topk_params.h new file mode 100644 index 0000000000..b2876c011f --- /dev/null +++ b/include/flexflow/ops/arg_topk_params.h @@ -0,0 +1,29 @@ +#ifndef _FLEXFLOW_ARG_TOPK_PARAMS_H +#define _FLEXFLOW_ARG_TOPK_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct ArgTopKParams { + LayerID layer_guid; + int k; + bool sorted; + bool speculative_decoding; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; +bool operator==(ArgTopKParams const &, ArgTopKParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::ArgTopKParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_ARG_TOPK_PARAMS_H diff --git a/include/flexflow/ops/argmax.h b/include/flexflow/ops/argmax.h new file mode 100644 index 0000000000..298059e3ed --- /dev/null +++ b/include/flexflow/ops/argmax.h @@ -0,0 +1,112 @@ +#ifndef _FLEXFLOW_ARG_MAX_H_ +#define _FLEXFLOW_ARG_MAX_H_ + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/node.h" +#include "flexflow/ops/argmax_params.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +class ArgMaxMeta : public OpMeta { +public: + bool beam_search; + float *probs; + void *d_temp_storage; + size_t temp_storage_bytes = 0; + int *d_offsets; + void *d_out; + Realm::RegionInstance reserveInst; + ArgMaxMeta(FFHandler handler, + Op const *op, + Legion::Domain const &input_domain, + Legion::Domain const &output_domain, + GenericTensorAccessorW input, + int batch_size, + int total_ele, + MemoryAllocator &gpu_mem_allocator); + ~ArgMaxMeta(void); +}; + +class ArgMax : public Op { +public: + using Params = ArgMaxParams; + using Input = ParallelTensor; + ArgMax(FFModel &model, + const ParallelTensor input, + bool beam_search, + char const *name); + ArgMax(FFModel &model, ArgMax const &other, const ParallelTensor input); + ArgMax(FFModel &model, + Params const ¶ms, + Input const input, + char const *name = nullptr); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static BeamInferenceResult + inference_task_beam(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static InferenceResult + inference_task_norm(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + void serialize(Legion::Serializer &s) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void forward_kernel(ArgMaxMeta const *m, + DT *input_ptr, + int *indices_ptr, + float *prob_ptr, + int *parent_ptr, + int length, + int batch_size, + ffStream_t stream); + static void forward_kernel_wrapper(ArgMaxMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + GenericTensorAccessorW const &parent, + int batch_size); + Params get_params() const; + +public: + bool beam_search; +}; + +}; // namespace FlexFlow + +#endif \ No newline at end of file diff --git a/include/flexflow/ops/argmax_params.h b/include/flexflow/ops/argmax_params.h new file mode 100644 index 0000000000..9ddb8e1fe3 --- /dev/null +++ b/include/flexflow/ops/argmax_params.h @@ -0,0 +1,25 @@ +#ifndef _FLEXFLOW_ARGMAX_PARAMS_H +#define _FLEXFLOW_ARGMAX_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct ArgMaxParams { + bool beam_search; + bool is_valid(ParallelTensorShape const &) const; + char name[MAX_OPNAME]; +}; +bool operator==(ArgMaxParams const &, ArgMaxParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::ArgMaxParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_ARGMAX_PARAMS_H \ No newline at end of file diff --git a/include/flexflow/ops/attention.h b/include/flexflow/ops/attention.h index 2903497af9..7f52e0dad4 100644 --- a/include/flexflow/ops/attention.h +++ b/include/flexflow/ops/attention.h @@ -3,6 +3,7 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" +#include "flexflow/inference.h" #include "flexflow/layer.h" #include "flexflow/node.h" #include "flexflow/op_meta.h" @@ -64,8 +65,17 @@ class MultiHeadAttention : public Op { Layer const *layer, std::vector const &inputs); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } diff --git a/include/flexflow/ops/attention_params.h b/include/flexflow/ops/attention_params.h index b72923a65c..89906407d3 100644 --- a/include/flexflow/ops/attention_params.h +++ b/include/flexflow/ops/attention_params.h @@ -11,6 +11,7 @@ struct MultiHeadAttentionParams { int embed_dim, num_heads, kdim, vdim; float dropout; bool bias, add_bias_kv, add_zero_attn; + char name[MAX_OPNAME]; bool is_valid(std::tuple const &) const; }; diff --git a/include/flexflow/ops/beam_topk.h b/include/flexflow/ops/beam_topk.h new file mode 100644 index 0000000000..9466ba2a3b --- /dev/null +++ b/include/flexflow/ops/beam_topk.h @@ -0,0 +1,112 @@ +#ifndef _FLEXFLOW_BEAM_TOPK_H_ +#define _FLEXFLOW_BEAM_TOPK_H_ + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/node.h" +#include "flexflow/ops/beam_topk_params.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +class BeamTopKMeta : public OpMeta { +public: + BeamTopKMeta(FFHandler handle, + Op const *op, + MemoryAllocator &gpu_mem_allocator); + ~BeamTopKMeta(void); + bool sorted; + int max_beam_width; + int *parent_ids; + void *acc_probs; + int *block_start_index; + int *request_id; + int *tokens_per_request; + Realm::RegionInstance reserveInst; +}; + +class BeamTopK : public Op { +public: + using Params = BeamTopKParams; + using Input = ParallelTensor; + BeamTopK(FFModel &model, + const ParallelTensor input, + LayerID const &_layer_guid, + int max_beam_width, + bool sorted, + char const *name); + BeamTopK(FFModel &model, BeamTopK const &other, const ParallelTensor input); + BeamTopK(FFModel &model, + Params const ¶ms, + Input const input, + char const *name = nullptr); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static BeamInferenceResult + inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + void serialize(Legion::Serializer &s) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void forward_kernel(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted, + ffStream_t stream); + static void forward_kernel_wrapper(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + GenericTensorAccessorR const &input, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted); + Params get_params() const; + +public: + bool sorted; + int max_beam_width; +}; + +}; // namespace FlexFlow + +#endif diff --git a/include/flexflow/ops/beam_topk_params.h b/include/flexflow/ops/beam_topk_params.h new file mode 100644 index 0000000000..3e09848c9a --- /dev/null +++ b/include/flexflow/ops/beam_topk_params.h @@ -0,0 +1,28 @@ +#ifndef _FLEXFLOW_BEAM_TOPK_PARAMS_H +#define _FLEXFLOW_BEAM_TOPK_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct BeamTopKParams { + LayerID layer_guid; + bool sorted; + int max_beam_width; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; +bool operator==(BeamTopKParams const &, BeamTopKParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::BeamTopKParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_BEAM_TOPK_PARAMS_H diff --git a/include/flexflow/ops/cast.h b/include/flexflow/ops/cast.h index 2d69b9469e..a88e7d6bb0 100644 --- a/include/flexflow/ops/cast.h +++ b/include/flexflow/ops/cast.h @@ -34,10 +34,19 @@ class Cast : public Op { Params const ¶ms, Input const &input, char const *name = nullptr); - void init(FFModel const &); - void forward(FFModel const &); - void backward(FFModel const &); - void print_layer(FFModel const &model) { + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { assert(0); } static Op * @@ -83,7 +92,7 @@ class Cast : public Op { bool measure_operator_cost(Simulator *sim, MachineView const &pc, - CostMetrics &cost_metrics) const; + CostMetrics &cost_metrics) const override; void serialize(Legion::Serializer &s) const override; static PCG::Node deserialize(FFModel &ff, Legion::Deserializer &d, diff --git a/include/flexflow/ops/cast_params.h b/include/flexflow/ops/cast_params.h index efef3de890..38a69e8a69 100644 --- a/include/flexflow/ops/cast_params.h +++ b/include/flexflow/ops/cast_params.h @@ -8,6 +8,7 @@ namespace FlexFlow { struct CastParams { DataType dtype; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(CastParams const &, CastParams const &); diff --git a/include/flexflow/ops/concat_params.h b/include/flexflow/ops/concat_params.h index 2987b25424..b1a7e74c55 100644 --- a/include/flexflow/ops/concat_params.h +++ b/include/flexflow/ops/concat_params.h @@ -7,7 +7,7 @@ namespace FlexFlow { struct ConcatParams { int axis; - + char name[MAX_OPNAME]; bool is_valid(std::vector const &) const; }; diff --git a/include/flexflow/ops/conv_2d_params.h b/include/flexflow/ops/conv_2d_params.h index 9aac91e315..562d5adef9 100644 --- a/include/flexflow/ops/conv_2d_params.h +++ b/include/flexflow/ops/conv_2d_params.h @@ -13,6 +13,7 @@ struct Conv2DParams { padding_w, groups; ActiMode activation; bool use_bias; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &input) const; void solve_dims(ParallelTensorShape const &input, diff --git a/include/flexflow/ops/dropout_params.h b/include/flexflow/ops/dropout_params.h index 61aee12f9f..eb1a4d98cf 100644 --- a/include/flexflow/ops/dropout_params.h +++ b/include/flexflow/ops/dropout_params.h @@ -9,6 +9,7 @@ namespace FlexFlow { struct DropoutParams { float rate; unsigned long long seed; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(DropoutParams const &, DropoutParams const &); diff --git a/include/flexflow/ops/element_binary.h b/include/flexflow/ops/element_binary.h index 677ff23ce2..4df7ea7bd8 100644 --- a/include/flexflow/ops/element_binary.h +++ b/include/flexflow/ops/element_binary.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_ELEMENT_BINARY_H #define _FLEXFLOW_ELEMENT_BINARY_H +#include "flexflow/inference.h" #include "flexflow/layer.h" #include "flexflow/node.h" #include "flexflow/operator.h" @@ -14,6 +15,7 @@ class ElementBinary : public Op { using Input = std::pair; ElementBinary(FFModel &model, + LayerID const &layer_guid, OperatorType type, const ParallelTensor x, const ParallelTensor y, @@ -22,11 +24,19 @@ class ElementBinary : public Op { ElementBinary(FFModel &model, Params const ¶ms, Input const &inputs, - char const *name = nullptr, - bool inplace_a = false); + char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } @@ -46,6 +56,10 @@ class ElementBinary : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void backward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, @@ -53,6 +67,7 @@ class ElementBinary : public Op { bool measure_operator_cost(Simulator *sim, MachineView const &pc, CostMetrics &cost_metrics) const override; + void serialize(Legion::Serializer &) const override; static PCG::Node deserialize(FFModel &ff, Legion::Deserializer &d, diff --git a/include/flexflow/ops/element_binary_params.h b/include/flexflow/ops/element_binary_params.h index c70e1b597a..7810790366 100644 --- a/include/flexflow/ops/element_binary_params.h +++ b/include/flexflow/ops/element_binary_params.h @@ -2,13 +2,17 @@ #define _FLEXFLOW_ELEMENT_BINARY_PARAMS_H #include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { struct ElementBinaryParams { + LayerID layer_guid; OperatorType type; bool inplace_a; + char name[MAX_OPNAME]; + bool is_valid( std::pair const &) const; diff --git a/include/flexflow/ops/element_unary.h b/include/flexflow/ops/element_unary.h index 5291159aac..ddef59549c 100644 --- a/include/flexflow/ops/element_unary.h +++ b/include/flexflow/ops/element_unary.h @@ -3,6 +3,7 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" +#include "flexflow/inference.h" #include "flexflow/layer.h" #include "flexflow/node.h" #include "flexflow/op_meta.h" @@ -25,7 +26,6 @@ class ElementUnaryMeta : public OpMeta { DataType data_type; bool inplace; float scalar; - char op_name[MAX_OPNAME]; }; class ElementUnary : public Op { @@ -45,8 +45,17 @@ class ElementUnary : public Op { Input const x, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } @@ -67,6 +76,10 @@ class ElementUnary : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void backward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, diff --git a/include/flexflow/ops/element_unary_params.h b/include/flexflow/ops/element_unary_params.h index 00683c89a0..16cb015e3c 100644 --- a/include/flexflow/ops/element_unary_params.h +++ b/include/flexflow/ops/element_unary_params.h @@ -2,6 +2,7 @@ #define _FLEXFLOW_ELEMENTARY_UNARY_PARAMS_H #include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { @@ -11,6 +12,7 @@ struct ElementUnaryParams { bool inplace; float scalar = 0.0; LayerID layer_guid; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/embedding.h b/include/flexflow/ops/embedding.h index 91caf06af0..ed89fcf37a 100644 --- a/include/flexflow/ops/embedding.h +++ b/include/flexflow/ops/embedding.h @@ -49,8 +49,17 @@ class Embedding : public Op { bool allocate_weights = false, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; // void update(const FFModel&); void print_layer(FFModel const &model) override { assert(0); @@ -71,6 +80,10 @@ class Embedding : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void backward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, diff --git a/include/flexflow/ops/embedding_params.h b/include/flexflow/ops/embedding_params.h index 71e5cc8b20..d813132048 100644 --- a/include/flexflow/ops/embedding_params.h +++ b/include/flexflow/ops/embedding_params.h @@ -12,6 +12,7 @@ struct EmbeddingParams { LayerID layer_guid; AggrMode aggr; DataType data_type; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/experts.h b/include/flexflow/ops/experts.h new file mode 100644 index 0000000000..d68957d890 --- /dev/null +++ b/include/flexflow/ops/experts.h @@ -0,0 +1,172 @@ +#pragma once + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/ops/experts_params.h" + +namespace FlexFlow { + +class ExpertsMeta : public OpMeta { +public: + ExpertsMeta(FFHandler handler, + int _num_experts, + int _experts_start_idx, + int _data_dim, + int _out_dim, + int _experts_num_layers, + int _experts_internal_dim_size, + int _effective_batch_size, + int _num_chosen_experts, + float _alpha, + bool _use_bias, + ActiMode _activation); + ~ExpertsMeta(void); + + // Thrust helper arrays + int *sorted_indices; + int *original_indices; + int *non_zero_expert_labels; + int *temp_sequence; + int *exp_local_label_to_index; + int *expert_start_indexes; + int *num_assignments_per_expert; // numbers of tokes assigned to each expert. + // Values may exceed the expert capacity + int *capped_num_assignments_per_expert; + int *destination_start_indices; + float const **token_idx_array; + float const **dev_weights; + float const **weight_idx_array1; + float const **weight_idx_array2; + float const **coefficient_idx_array; + float **output_idx_array; + float const **bias_idx_array1; + float const **bias_idx_array2; + float const *one_ptr; + float const **one_ptr_array; + + // array of arrays to store cublasGemmBatchedEx outputs before aggregation + float **batch_outputs1; + float **batch_outputs2; + float **dev_batch_outputs1; + float **dev_batch_outputs2; + + int num_experts; + int experts_start_idx; + int data_dim; + int out_dim; + int experts_num_layers; + int experts_internal_dim_size; + int effective_batch_size; + int num_chosen_experts; + int expert_capacity; + float alpha; + bool use_bias; + ActiMode activation; +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) + cudnnActivationDescriptor_t actiDesc; + cudnnTensorDescriptor_t resultTensorDesc1; + cudnnTensorDescriptor_t resultTensorDesc2; +#else + miopenActivationDescriptor_t actiDesc; + miopenTensorDescriptor_t resultTensorDesc1; + miopenTensorDescriptor_t resultTensorDesc2; +#endif +}; + +// definitions for the CUDA kernel +#define MAX_BATCH_SIZE 1024 * 2 // 32 * 10 +#define MAX_EXPERTS_PER_BLOCK 32 + +class Experts : public Op { +public: + using Params = ExpertsParams; + using Input = std::vector; + Experts(FFModel &model, + Params const ¶ms, + Input const &inputs, + bool allocate_weights = false, + char const *name = nullptr); + Experts(FFModel &model, + LayerID const &layer_guid, + ParallelTensor const *inputs, + int _num_experts, + int _experts_start_idx, + int _experts_output_dim_size, + float _alpha, + int _experts_num_layers, + int _experts_internal_dim_size, + bool _use_bias, + ActiMode _activation, + bool allocate_weights, + char const *name = nullptr); + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override; + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + Input const &inputs, + int num_inputs); + Params get_params() const; + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void forward_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void forward_kernel_wrapper(ExpertsMeta const *m, + float const *input, + int const *indices, + float const *topk_gate_preds, + float *output, + float const *weights, + float const *biases, + int num_active_tokens, + int chosen_experts, + int batch_size, + int out_dim); + static void backward_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + +public: + int num_experts; + int experts_start_idx; + int experts_output_dim_size; + int data_dim; + int out_dim; + int effective_batch_size; + int num_chosen_experts; + float alpha; + int experts_num_layers; + int experts_internal_dim_size; + bool use_bias; + ActiMode activation; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/ops/experts_params.h b/include/flexflow/ops/experts_params.h new file mode 100644 index 0000000000..90cce47526 --- /dev/null +++ b/include/flexflow/ops/experts_params.h @@ -0,0 +1,34 @@ +#pragma once + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/operator.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct ExpertsParams { + LayerID layer_guid; + int num_experts; + int experts_start_idx; + int experts_output_dim_size; + float alpha; + int experts_num_layers; + int experts_internal_dim_size; + bool use_bias; + ActiMode activation; + char name[MAX_OPNAME]; + + bool is_valid(std::vector const &) const; +}; + +bool operator==(ExpertsParams const &, ExpertsParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::ExpertsParams const &) const; +}; +} // namespace std diff --git a/include/flexflow/ops/flat_params.h b/include/flexflow/ops/flat_params.h index 5f821b0416..fc006849e5 100644 --- a/include/flexflow/ops/flat_params.h +++ b/include/flexflow/ops/flat_params.h @@ -7,6 +7,7 @@ namespace FlexFlow { struct FlatParams { + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; void solve_dims(ParallelTensorShape const &input, ParallelDim output_dims[MAX_TENSOR_DIM], diff --git a/include/flexflow/ops/fused.h b/include/flexflow/ops/fused.h index 87d35da902..a8326e9ab4 100644 --- a/include/flexflow/ops/fused.h +++ b/include/flexflow/ops/fused.h @@ -23,14 +23,32 @@ class FusedOp : public Op { SOURCE_OUTPUT, }; FusedOp(FFModel &model, Op *op); - bool add_operator(FFModel &model, Op *op); + static bool use_same_regions( + ParallelTensor const source_tensor, + ParallelTensor const target_tensor, + std::unordered_map> + *pt_mapping = nullptr); + bool add_operator( + FFModel &model, + Op *op, + std::unordered_map> + *parallel_tensor_mapping = nullptr); ParallelTensor init_inout(FFModel &model, const ParallelTensor input) { assert(0); return ParallelTensor(); } void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } @@ -38,6 +56,10 @@ class FusedOp : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void forward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, diff --git a/include/flexflow/ops/gather_params.h b/include/flexflow/ops/gather_params.h index 768d135e88..de27cdfc7c 100644 --- a/include/flexflow/ops/gather_params.h +++ b/include/flexflow/ops/gather_params.h @@ -1,6 +1,8 @@ #ifndef _FLEXFLOW_GATHER_PARAMS_H #define _FLEXFLOW_GATHER_PARAMS_H +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { @@ -8,6 +10,7 @@ namespace FlexFlow { struct GatherParams { int legion_dim; LayerID layer_guid; + char name[MAX_OPNAME]; bool is_valid( std::pair const &input) const; }; diff --git a/include/flexflow/ops/groupby.h b/include/flexflow/ops/groupby.h index 4a15f6f439..ec6cdfb9ab 100644 --- a/include/flexflow/ops/groupby.h +++ b/include/flexflow/ops/groupby.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_GROUPBY_H_ #define _FLEXFLOW_GROUPBY_H_ +#include "flexflow/inference.h" #include "flexflow/model.h" #include "flexflow/node.h" #include "flexflow/ops/groupby_params.h" @@ -9,8 +10,9 @@ namespace FlexFlow { class GroupByMeta : public OpMeta { public: - GroupByMeta(FFHandler handle, int n); + GroupByMeta(FFHandler handle, int n, float _alpha); ~GroupByMeta(void); + float alpha; float **dev_region_ptrs; }; @@ -33,8 +35,17 @@ class Group_by : public Op { Input const &inputs, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } @@ -62,26 +73,22 @@ class Group_by : public Op { Op *materialize(FFModel &ff, ParallelTensor inputs[], int num_inputs) const override; - static void - forward_kernel_wrapper(GroupByMeta const *m, - float const *input, - int const *exp_assign, - float **outputs, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim); - static void - backward_kernel_wrapper(GroupByMeta const *m, - float *input_grad, - int const *exp_assign, - float **output_grads, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim); + static void forward_kernel_wrapper(GroupByMeta const *m, + float const *input, + int const *exp_assign, + float **outputs, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim); + static void backward_kernel_wrapper(GroupByMeta const *m, + float *input_grad, + int const *exp_assign, + float **output_grads, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim); bool measure_operator_cost(Simulator *sim, MachineView const &pc, CostMetrics &cost_metrics) const override; diff --git a/include/flexflow/ops/groupby_params.h b/include/flexflow/ops/groupby_params.h index 24a74f5412..4f6245863a 100644 --- a/include/flexflow/ops/groupby_params.h +++ b/include/flexflow/ops/groupby_params.h @@ -9,6 +9,7 @@ namespace FlexFlow { struct Group_byParams { int n; float alpha; + char name[MAX_OPNAME]; bool is_valid( std::pair const &) const; }; diff --git a/include/flexflow/ops/inc_multihead_self_attention.h b/include/flexflow/ops/inc_multihead_self_attention.h new file mode 100644 index 0000000000..43dc527bc8 --- /dev/null +++ b/include/flexflow/ops/inc_multihead_self_attention.h @@ -0,0 +1,211 @@ +#ifndef _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_H +#define _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_H + +#include "flexflow/accessor.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/inference.h" +#include "flexflow/layer.h" +#include "flexflow/node.h" +#include "flexflow/op_meta.h" +#include "flexflow/operator.h" +#include "flexflow/ops/inc_multihead_self_attention_params.h" +#include "flexflow/utils/memory_allocator.h" +#include "math.h" +#include +#include +#if defined(FF_USE_HIP_ROCM) +#include +#endif + +namespace FlexFlow { + +class IncMultiHeadSelfAttentionMeta; + +class IncMultiHeadSelfAttention : public Op { +public: + using Params = IncMultiHeadSelfAttentionParams; + using Input = ParallelTensor; + + IncMultiHeadSelfAttention(FFModel &model, + LayerID const &layer_guid, + ParallelTensor const _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name); + IncMultiHeadSelfAttention(FFModel &model, + ParallelTensor const _input, + ParallelTensor const _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name); + IncMultiHeadSelfAttention(FFModel &model, + IncMultiHeadSelfAttention const &other, + ParallelTensor const input, + bool allocate_weights); + IncMultiHeadSelfAttention(FFModel &model, + Params const ¶ms, + Input const &inputs, + bool allocate_weights = false, + char const *name = nullptr); + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + bool get_int_parameter(PMParameter, int *) const override; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const override; + + static void inference_kernel_wrapper(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias); + Params get_params() const; + +public: + int num_q_heads, num_kv_heads, tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias; + bool final_bias, add_zero_attn, apply_rotary_embedding, scaling_query, + qk_prod_scaling, position_bias; + int qSize, kSize, vSize, qProjSize, kProjSize, vProjSize, oProjSize; + int qoSeqLength, kvSeqLength; + DataType quantization_type; + bool offload; +}; + +class IncMultiHeadSelfAttentionMeta : public OpMeta { +public: + IncMultiHeadSelfAttentionMeta(FFHandler handler, + IncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads); + IncMultiHeadSelfAttentionMeta(FFHandler handler, + InferenceMode infer_mode, + Op const *attn, + int _qSize, + int _kSize, + int _vSize, + int _qProjSize, + int _kProjSize, + int _vProjSize, + int _oProjSize, + bool _apply_rotary_embedding, + bool _qkv_bias, + bool _scaling_query, + bool _qk_prod_scaling, + bool _position_bias, + bool _final_bias, + float _scaling_factor, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _global_num_q_heads, + int _global_num_kv_heads, + int _num_q_heads, + int _num_kv_heads, + DataType _quantization_type, + bool _offload); + ~IncMultiHeadSelfAttentionMeta(void); + +public: + Realm::RegionInstance reserveInst; + size_t weights_params, weightSize, biasSize, reserveSpaceSize, + quantized_weightSize; + int qSize, kSize, vSize, qProjSize, kProjSize, vProjSize, oProjSize; + int global_num_q_heads, global_num_kv_heads, num_q_heads, num_kv_heads, + hidden_size; + bool *has_load_weights; + bool *apply_rotary_embedding; + bool *qkv_bias; + bool *final_bias; + bool *scaling_query; + bool *qk_prod_scaling; + bool *position_bias; + float scaling_factor; + void *weight_ptr, *bias_ptr; // for weight offload + void *devQKVProjArray, *keyCache, *valueCache; + void *qk_prods, *qk_prods_softmax; + void *attn_heads; + char *quantized_weight_ptr; + BatchConfig::PerTokenInfo *token_infos; + BatchConfig::PerRequestInfo *request_infos; + DataType quantization_type; + bool offload; +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) + // cudaStream_t task_local_stream; + cudnnTensorDescriptor_t qk_tensor; + cuFloatComplex *complex_input; +#elif defined(FF_USE_HIP_ROCM) + miopenTensorDescriptor_t qk_tensor; + // typedef hipFloatComplex attFloatComplex; + hipFloatComplex *complex_input; +#endif +}; + +}; // namespace FlexFlow + +#endif // _FLEXFLOW_ATTENTION_H diff --git a/include/flexflow/ops/inc_multihead_self_attention_params.h b/include/flexflow/ops/inc_multihead_self_attention_params.h new file mode 100644 index 0000000000..58681069e2 --- /dev/null +++ b/include/flexflow/ops/inc_multihead_self_attention_params.h @@ -0,0 +1,35 @@ +#ifndef _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H +#define _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct IncMultiHeadSelfAttentionParams { + LayerID layer_guid; + int embed_dim, num_q_heads, kdim, vdim, num_kv_heads, + tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, position_bias; + DataType quantization_type; + bool offload; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; + +bool operator==(IncMultiHeadSelfAttentionParams const &, + IncMultiHeadSelfAttentionParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::IncMultiHeadSelfAttentionParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H diff --git a/include/flexflow/ops/kernels/concat_kernels.h b/include/flexflow/ops/kernels/concat_kernels.h index 755e1800da..4da6aaf5e2 100644 --- a/include/flexflow/ops/kernels/concat_kernels.h +++ b/include/flexflow/ops/kernels/concat_kernels.h @@ -12,7 +12,6 @@ class ConcatMeta : public OpMeta { public: ConcatMeta(FFHandler handle) : OpMeta(handle){}; int legion_axis; - char op_name[MAX_OPNAME]; }; namespace Kernels { diff --git a/include/flexflow/ops/kernels/conv_2d_kernels.h b/include/flexflow/ops/kernels/conv_2d_kernels.h index a848d83d60..7b2a0fe135 100644 --- a/include/flexflow/ops/kernels/conv_2d_kernels.h +++ b/include/flexflow/ops/kernels/conv_2d_kernels.h @@ -28,7 +28,6 @@ class Conv2DMeta : public OpMeta { miopenConvBwdDataAlgorithm_t bwdDataAlgo; #endif bool relu, use_bias; - char op_name[MAX_OPNAME]; }; namespace Kernels { diff --git a/include/flexflow/ops/kernels/decompress_kernels.h b/include/flexflow/ops/kernels/decompress_kernels.h new file mode 100644 index 0000000000..7cfedd6265 --- /dev/null +++ b/include/flexflow/ops/kernels/decompress_kernels.h @@ -0,0 +1,43 @@ +#ifndef _FLEXFLOW_DECOMPRESS_KERNELS_H +#define _FLEXFLOW_DECOMPRESS_KERNELS_H + +#include "flexflow/device.h" + +namespace FlexFlow { +namespace Kernels { + +template +__global__ void decompress_int4_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize); +template +__global__ void decompress_int8_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize); + +template +__global__ void decompress_int4_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template +__global__ void decompress_int8_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads); +// template +// void decompress_weight_bias(T1 *input_weight_ptr, +// T2 *weight_ptr, +// T2 *params, +// int group_size, +// int tensor_size); + +} // namespace Kernels +} // namespace FlexFlow + +#endif // _FLEXFLOW_DECOMPRESS_KERNELS_H diff --git a/include/flexflow/ops/kernels/element_binary_kernels.h b/include/flexflow/ops/kernels/element_binary_kernels.h index 50c7f2b80c..5740fde660 100644 --- a/include/flexflow/ops/kernels/element_binary_kernels.h +++ b/include/flexflow/ops/kernels/element_binary_kernels.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_OPS_KERNELS_ELEMENT_BINARY_KERNELS_H #define _FLEXFLOW_OPS_KERNELS_ELEMENT_BINARY_KERNELS_H +#include "flexflow/accessor.h" #include "flexflow/device.h" #include "flexflow/fftype.h" #include "flexflow/op_meta.h" @@ -9,7 +10,7 @@ namespace FlexFlow { class ElementBinaryMeta : public OpMeta { public: - ElementBinaryMeta(FFHandler handle); + ElementBinaryMeta(FFHandler handle, Op const *op); #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) cudnnTensorDescriptor_t input1Tensor, input2Tensor, outputTensor; cudnnOpTensorDescriptor_t opDesc; @@ -24,7 +25,6 @@ class ElementBinaryMeta : public OpMeta { bool broadcast_input1, broadcast_input2; int batch_size; size_t replicate_size; - char op_name[MAX_OPNAME]; }; namespace Kernels { @@ -36,9 +36,9 @@ void init_kernel(ElementBinaryMeta *m, Legion::Domain const &output_domain); void forward_kernel_wrapper(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr); + GenericTensorAccessorR const &in1, + GenericTensorAccessorR const &in2, + GenericTensorAccessorW const &out); void backward_kernel_wrapper(ElementBinaryMeta const *m, float const *out_grad_ptr, @@ -49,10 +49,11 @@ void backward_kernel_wrapper(ElementBinaryMeta const *m, namespace Internal { +template void forward_kernel(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr, + DT const *in1_ptr, + DT const *in2_ptr, + DT *out_ptr, ffStream_t stream); void backward_kernel(ElementBinaryMeta const *m, float const *out_grad_ptr, @@ -67,4 +68,4 @@ void backward_kernel(ElementBinaryMeta const *m, } // namespace Kernels } // namespace FlexFlow -#endif // _FLEXFLOW_OPS_KERNELS_ELEMENT_BINARY_KERNELS_H \ No newline at end of file +#endif // _FLEXFLOW_OPS_KERNELS_ELEMENT_BINARY_KERNELS_H diff --git a/include/flexflow/ops/kernels/inc_multihead_self_attention_kernels.h b/include/flexflow/ops/kernels/inc_multihead_self_attention_kernels.h new file mode 100644 index 0000000000..9bf2f581e2 --- /dev/null +++ b/include/flexflow/ops/kernels/inc_multihead_self_attention_kernels.h @@ -0,0 +1,112 @@ +#ifndef _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_ATTENTION_KERNELS_H +#define _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_ATTENTION_KERNELS_H + +#define QKV_WEIGHT_NUM 3 +#define KV_WEIGHT_NUM 2 + +#include "flexflow/batch_config.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/op_meta.h" +#include "flexflow/ops/inc_multihead_self_attention.h" + +namespace FlexFlow { +namespace Kernels { +namespace IncMultiHeadAttention { + +template +void compute_attention_kernel_generation(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + DT *output_ptr, + ffStream_t stream); + +template +void compute_o_prod_bias(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *weight_ptr, + DT const *bias_ptr, + int num_tokens, + ffStream_t stream); + +template +__global__ void apply_position_bias_qkprd(DT *input_ptr, + int num_tokens, + int num_total_tokens, + int num_heads, + int global_num_q_heads, + int shard_id); + +template +__global__ void apply_proj_bias_w(DT *input_ptr, + DT const *bias_ptr, + int num_tokens, + int qkv_weight_size, + int oProjSize); + +template +__global__ void apply_proj_bias_qkv(DT *input_ptr, + DT const *bias_ptr, + int shard_id, + int num_tokens, + int qProjSize, + int kProjSize, + int vProjSize, + int num_heads, + int num_kv_heads, + bool scaling_query, + float scaling_factor); + +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +template +__global__ void + apply_rotary_embedding(DT *input_ptr, + cuFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_heads, + int num_tokens, + int num_kv_heads, + int q_block_size, + int k_block_size, + int q_array_size, + bool q_tensor); +#elif defined(FF_USE_HIP_ROCM) +template +__global__ void + apply_rotary_embedding(DT *input_ptr, + hipFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_heads, + int num_tokens, + int num_kv_heads, + int q_block_size, + int k_block_size, + int q_array_size, + bool q_tensor); +#endif + +template +void compute_qkv_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + ffStream_t stream); + +template +void pre_build_weight_kernel(IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + ffStream_t stream); +} // namespace IncMultiHeadAttention +} // namespace Kernels +} // namespace FlexFlow + +#endif // _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_ATTENTION_KERNELS_H diff --git a/include/flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh b/include/flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh new file mode 100644 index 0000000000..d1e0e050b2 --- /dev/null +++ b/include/flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh @@ -0,0 +1,524 @@ +#ifndef _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_UTILS_H +#define _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_UTILS_H + +#include "flexflow/inference.h" + +namespace FlexFlow { + +////////////////basic datatype////////////////////// +struct half4 { + half x; + half y; + half z; + half w; +}; + +struct half8 { + half x; + half y; + half z; + half w; + half a; + half b; + half c; + half d; +}; +struct float8 { + float x; + float y; + float z; + float w; + float a; + float b; + float c; + float d; +}; + +////////////////data type/////////////// +template +struct VEC_K {}; +template <> +struct VEC_K { + using Type = float; +}; +template <> +struct VEC_K { + using Type = float2; +}; +template <> +struct VEC_K { + using Type = float4; +}; +template <> +struct VEC_K { + using Type = half; +}; +template <> +struct VEC_K { + using Type = half2; +}; +template <> +struct VEC_K { + using Type = half4; +}; + +// data type for QK production +template +struct Vec_fp32_ {}; + +template <> +struct Vec_fp32_ { + using Type = float; +}; +template <> +struct Vec_fp32_ { + using Type = float2; +}; +template <> +struct Vec_fp32_ { + using Type = float4; +}; +template <> +struct Vec_fp32_ { + using Type = float; +}; +template <> +struct Vec_fp32_ { + using Type = float2; +}; +template <> +struct Vec_fp32_ { + using Type = float4; +}; +template <> +struct Vec_fp32_ { + using Type = float8; +}; + +template +struct VEC_V {}; +template <> +struct VEC_V { + using Type = float4; +}; +template <> +struct VEC_V { + using Type = half8; +}; + +////////////////data structures half/////////////// + +////////////////////////////////////floating point +/// operations/////////////////////////////////////////// + +template +inline __device__ Acc mul(A a, B b) { + return Acc{}; // for compile +} +template <> +inline __device__ float mul(float a, float b) { + return a * b; +} + +template <> +inline __device__ float2 mul(float2 a, float2 b) { + float2 c; + c.x = a.x * b.x; + c.y = a.y * b.y; + return c; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +template <> +inline __device__ float2 mul(float a, float2 b) { + float2 c; + c.x = a * b.x; + c.y = a * b.y; + return c; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +template <> +inline __device__ float4 mul(float4 a, float4 b) { + float4 c; + c.x = a.x * b.x; + c.y = a.y * b.y; + c.z = a.z * b.z; + c.w = a.w * b.w; + return c; +} + +// template <> +// inline __device__ float4 mul(half4 a, half4 b) { +// float4 c; +// c.x = a.x * b.x; +// c.y = a.y * b.y; +// c.z = a.z * b.z; +// c.w = a.w * b.w; +// return c; +// } + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float fma(float a, float b, float c) { + return a * b + c; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float2 fma(float2 a, float2 b, float2 c) { + float2 d; + d.x = fma(a.x, b.x, c.x); + d.y = fma(a.y, b.y, c.y); + return d; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float2 fma(float a, float2 b, float2 c) { + float2 d; + d.x = fma(a, b.x, c.x); + d.y = fma(a, b.y, c.y); + return d; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float4 fma(float4 a, float4 b, float4 c) { + float4 d; + d.x = fma(a.x, b.x, c.x); + d.y = fma(a.y, b.y, c.y); + d.z = fma(a.z, b.z, c.z); + d.w = fma(a.w, b.w, c.w); + return d; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float4 fma(float a, float4 b, float4 c) { + float4 d; + d.x = fma(a, b.x, c.x); + d.y = fma(a, b.y, c.y); + d.z = fma(a, b.z, c.z); + d.w = fma(a, b.w, c.w); + return d; +} + +inline __device__ float8 fma(float a, float8 f1, float8 f2) { + float8 res; + res.x = fma(a, f1.x, f2.x); + res.y = fma(a, f1.y, f2.y); + res.z = fma(a, f1.z, f2.z); + res.w = fma(a, f1.w, f2.w); + res.a = fma(a, f1.a, f2.a); + res.b = fma(a, f1.b, f2.b); + res.c = fma(a, f1.c, f2.c); + res.d = fma(a, f1.d, f2.d); + return res; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float add(float a, float b) { + return a + b; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float2 add(float2 a, float2 b) { + float2 c; + c.x = add(a.x, b.x); + c.y = add(a.y, b.y); + return c; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float4 add(float4 a, float4 b) { + float4 c; + c.x = add(a.x, b.x); + c.y = add(a.y, b.y); + c.z = add(a.z, b.z); + c.w = add(a.w, b.w); + return c; +} + +inline __device__ float8 add(float8 f1, float8 f2) { + float8 res; + res.x = add(f1.x, f2.x); + res.y = add(f1.y, f2.y); + res.z = add(f1.z, f2.z); + res.w = add(f1.w, f2.w); + res.a = add(f1.a, f2.a); + res.b = add(f1.b, f2.b); + res.c = add(f1.c, f2.c); + res.d = add(f1.d, f2.d); + return res; +} + +inline __device__ float sum(float v) { + return v; +} + +template +inline __device__ __host__ T div_up(T m, T n) { + return (m + n - 1) / n; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float sum(float2 v) { + return v.x + v.y; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float sum(float4 v) { + return v.x + v.y + v.z + v.w; +} + +inline __device__ float cast_to_float(float u) { + return u; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float2 cast_to_float(float2 u) { + return u; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float4 cast_to_float(float4 u) { + return u; +} + +inline __device__ float cast_to_float(half u) { + return __half2float(u); +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float2 cast_to_float(half2 u) { + float2 tmp; + tmp.x = __half2float(u.x); + tmp.y = __half2float(u.y); + return tmp; +} + +//////////////////////////////////////////////////////////////////////////////////////////////////// + +inline __device__ float4 cast_to_float(half4 u) { + float4 tmp; + tmp.x = __half2float(u.x); + tmp.y = __half2float(u.y); + tmp.z = __half2float(u.z); + tmp.w = __half2float(u.w); + return tmp; +} +inline __device__ float8 cast_to_float(half8 u) { + float8 tmp; + tmp.x = __half2float(u.x); + tmp.y = __half2float(u.y); + tmp.z = __half2float(u.z); + tmp.w = __half2float(u.w); + tmp.a = __half2float(u.a); + tmp.b = __half2float(u.b); + tmp.c = __half2float(u.c); + tmp.d = __half2float(u.d); + return tmp; +} + +inline __device__ void convert_from_float(float4 &dst, float4 src) { + dst = src; +} +inline __device__ void convert_from_float(float &dst, float src) { + dst = src; +} +inline __device__ void convert_from_float(float2 &dst, float2 src) { + dst = src; +} +inline __device__ void convert_from_float(float8 &dst, float8 src) { + dst = src; +} + +inline __device__ void convert_from_float(half4 &dst, float4 src) { + dst.x = __float2half(src.x); + dst.y = __float2half(src.y); + dst.z = __float2half(src.z); + dst.w = __float2half(src.w); +} + +inline __device__ void convert_from_float(half8 &dst, float8 src) { + dst.x = __float2half(src.x); + dst.y = __float2half(src.y); + dst.z = __float2half(src.z); + dst.w = __float2half(src.w); + dst.a = __float2half(src.a); + dst.b = __float2half(src.b); + dst.c = __float2half(src.c); + dst.d = __float2half(src.d); +} +inline __device__ void convert_from_float(half2 &dst, float2 src) { + dst.x = __float2half(src.x); + dst.y = __float2half(src.y); +} +inline __device__ void convert_from_float(half &dst, float src) { + dst = __float2half(src); +} + +//////////////////////////////////////utils/////////////////////////////////////////////// + +template +inline __device__ void zero(T &dst) { + constexpr int WORDS = sizeof(T) / 4; + union { + T raw; + uint32_t words[WORDS]; + } tmp; +#pragma unroll + for (int ii = 0; ii < WORDS; ++ii) { + tmp.words[ii] = 0u; + } + dst = tmp.raw; +} + +template +inline __device__ float qk_dot_(K_vec const (&q)[N], K_vec const (&k)[N]) { + // use float32 to get better accuracy + using Vec_sum = typename Vec_fp32_::Type; + // Compute the parallel products for Q*K^T (treat vector lanes separately). + Vec_sum qk_vec = + mul(cast_to_float(q[0]), cast_to_float(k[0])); +#pragma unroll + for (int ii = 1; ii < N; ++ii) { + qk_vec = FlexFlow::fma(cast_to_float(q[ii]), cast_to_float(k[ii]), qk_vec); + } + + // Finalize the reduction across lanes. + float qk = sum(qk_vec); +#pragma unroll + for (int mask = THREADS_PER_KEY / 2; mask >= 1; mask /= 2) { + qk += __shfl_xor_sync(uint32_t(-1), qk, mask); + } + return qk; +} +template +struct Qk_dot { + template + static inline __device__ float dot(K_vec const (&q)[N], K_vec const (&k)[N]) { + return qk_dot_(q, k); + } +}; + +template +inline __device__ float block_sum(float *red_smem, float sum) { + + // Decompose the thread index into warp / lane. + int warp = threadIdx.x / WARP_SIZE; + int lane = threadIdx.x % WARP_SIZE; + +// Compute the sum per warp. +#pragma unroll + for (int mask = WARP_SIZE / 2; mask >= 1; mask /= 2) { + sum += __shfl_xor_sync(uint32_t(-1), sum, mask); + } + + // Warp leaders store the data to shared memory. + if (lane == 0) { + red_smem[warp] = sum; + } + + // Make sure the data is in shared memory. + __syncthreads(); + + // The warps compute the final sums. + if (lane < WARPS_PER_BLOCK) { + sum = red_smem[lane]; + } + +// Parallel reduction inside the warp. +#pragma unroll + for (int mask = WARPS_PER_BLOCK / 2; mask >= 1; mask /= 2) { + sum += __shfl_xor_sync(uint32_t(-1), sum, mask); + } + + // Broadcast to other threads. + return __shfl_sync(uint32_t(-1), sum, 0); +} + +template +inline size_t smem_size_in_bytes(int hidden_size_per_head, + int max_sequence_length, + int threads_per_value, + int threads_per_block) { + // The amount of shared memory needed to store the Q*K^T values in float. + + size_t qk_sz = div_up(max_sequence_length + 1, 4) * 16; + size_t logits_sz = qk_sz; + + // The total size needed during softmax. + size_t softmax_sz = qk_sz + logits_sz; + size_t q_size = hidden_size_per_head * sizeof(DT); + + // The number of partial rows to reduce in the final reduction. + int rows_per_red = threads_per_block / threads_per_value; + // The amount of storage needed to finalize the outputs. + size_t red_sz = rows_per_red * hidden_size_per_head * sizeof(float) / 2; + // The max. + return max(softmax_sz, red_sz) + q_size; +} + +template +inline void smem_size_in_bytes_tree(int hidden_size_per_head, + int max_sequence_length, + int threads_per_value, + int threads_per_block, + TreeVerifyBatchConfig const *bc, + int shared_mem[]) { + + int max_query_length = 0; + int max_total_length = 0; + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + max_query_length = + max(max_query_length, bc->requestsInfo[i].num_tokens_in_batch); + max_total_length = max(max_total_length, + bc->requestsInfo[i].first_token_depth_in_request + + bc->requestsInfo[i].num_tokens_in_batch); + } + + // todo fix this + int max_qk_length = max_query_length; + + // The amount of shared memory needed to store the Q*K^T values in float. + size_t qk_sz = div_up(max_qk_length + 1, 4) * 16; + + size_t logits_sz = qk_sz; + + // The total size needed during softmax. + size_t softmax_sz = qk_sz + logits_sz; + + size_t q_size = hidden_size_per_head * sizeof(DT); + + // The number of partial rows to reduce in the final reduction. + int rows_per_red = threads_per_block / threads_per_value; + // The amount of storage needed to finalize the outputs. + // use 4 + size_t red_sz = rows_per_red * hidden_size_per_head * sizeof(float) / 2; + // The max. + shared_mem[0] = qk_sz; + shared_mem[1] = softmax_sz + red_sz + q_size; +} + +template +struct threads_per_value_t { + static int const value = Dh * sizeof(T) / 16; +}; + +} // namespace FlexFlow +#endif // _FLEXFLOW_OPS_KERNELS_INC_MULTIHEAD_SELF_UTILS_H \ No newline at end of file diff --git a/include/flexflow/ops/kernels/linear_kernels.h b/include/flexflow/ops/kernels/linear_kernels.h index 6ca9fb89ac..a5fdc7c602 100644 --- a/include/flexflow/ops/kernels/linear_kernels.h +++ b/include/flexflow/ops/kernels/linear_kernels.h @@ -4,12 +4,18 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" #include "flexflow/op_meta.h" +#include "flexflow/ops/linear.h" namespace FlexFlow { class LinearMeta : public OpMeta { public: - LinearMeta(FFHandler handle, int batch_size); + LinearMeta(FFHandler handle, + int batch_size, + Linear const *li, + MemoryAllocator gpu_mem_allocator, + int weightSize); + ~LinearMeta(void); #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) cudnnTensorDescriptor_t outputTensor; cudnnActivationDescriptor_t actiDesc; @@ -17,13 +23,18 @@ class LinearMeta : public OpMeta { miopenTensorDescriptor_t outputTensor; miopenActivationDescriptor_t actiDesc; #endif - float const *one_ptr; + void *one_ptr; + void *weight_ptr; + DataType weight_ptr_type; + DataType quantization_type; + bool offload; + char *quantized_weight_ptr; + size_t quantized_weightSize; ActiMode activation; RegularizerMode kernel_reg_type; float kernel_reg_lambda; - bool use_bias; - DataType input_type, weight_type, output_type; - char op_name[MAX_OPNAME]; + bool use_bias, add_bias_only_once; + Realm::RegionInstance reserveInst; }; namespace Kernels { @@ -51,6 +62,7 @@ void backward_kernel_wrapper(LinearMeta const *m, bool use_activation(ActiMode mode); namespace Internal { +template void forward_kernel(LinearMeta const *m, void const *input_ptr, void *output_ptr, @@ -60,6 +72,7 @@ void forward_kernel(LinearMeta const *m, int out_dim, int batch_size, ffStream_t stream); +template void backward_kernel(LinearMeta const *m, void const *input_ptr, void *input_grad_ptr, @@ -72,6 +85,8 @@ void backward_kernel(LinearMeta const *m, int out_dim, int batch_size, ffStream_t stream); +template +__global__ void build_one_ptr(DT *one_ptr, int batch_size); } // namespace Internal } // namespace Linear } // namespace Kernels diff --git a/include/flexflow/ops/kernels/pool_2d_kernels.h b/include/flexflow/ops/kernels/pool_2d_kernels.h index ac86cb50c3..7f73a8295d 100644 --- a/include/flexflow/ops/kernels/pool_2d_kernels.h +++ b/include/flexflow/ops/kernels/pool_2d_kernels.h @@ -14,7 +14,6 @@ class Pool2DMeta : public OpMeta { ffActivationDescriptor_t actiDesc; ffPoolingDescriptor_t poolDesc; bool relu; - char op_name[MAX_OPNAME]; }; namespace Kernels { diff --git a/include/flexflow/ops/kernels/residual_rms_norm_kernels.h b/include/flexflow/ops/kernels/residual_rms_norm_kernels.h new file mode 100644 index 0000000000..0eef4ca72b --- /dev/null +++ b/include/flexflow/ops/kernels/residual_rms_norm_kernels.h @@ -0,0 +1,55 @@ +#ifndef _FLEXFLOW_OPS_KERNELS_RESIDUAL_RMSNORM_KERNELS_H +#define _FLEXFLOW_OPS_KERNELS_RESIDUAL_RMSNORM_KERNELS_H + +#include "flexflow/accessor.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/op_meta.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { +using Legion::coord_t; + +class ResidualRMSNorm; + +class ResidualRMSNormMeta : public OpMeta { +public: + ResidualRMSNormMeta(FFHandler handler, + ResidualRMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator); + ~ResidualRMSNormMeta(void); +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) + cudnnTensorDescriptor_t inputTensor, outputTensor; + cudnnReduceTensorDescriptor_t reduceDesc; +#else + miopenTensorDescriptor_t inputTensor, outputTensor; + miopenReduceTensorDescriptor_t reduceDesc; +#endif + +public: + float eps; + void *rms_ptr; + void *norm_ptr; + + float alpha; + float beta; + + int in_dim; + int batch_size; + int num_elements; + Realm::RegionInstance reserveInst; +}; + +namespace Kernels { +namespace ResidualRMSNorm { +void forward_kernel_wrapper(ResidualRMSNormMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &residual_output, + GenericTensorAccessorW const &output); +} // namespace ResidualRMSNorm +} // namespace Kernels +} // namespace FlexFlow + +#endif // _FLEXFLOW_OPS_KERNELS_RMSNORM_KERNELS_H diff --git a/include/flexflow/ops/kernels/rms_norm_kernels.h b/include/flexflow/ops/kernels/rms_norm_kernels.h new file mode 100644 index 0000000000..35c5aa69fa --- /dev/null +++ b/include/flexflow/ops/kernels/rms_norm_kernels.h @@ -0,0 +1,53 @@ +#ifndef _FLEXFLOW_OPS_KERNELS_RMSNORM_KERNELS_H +#define _FLEXFLOW_OPS_KERNELS_RMSNORM_KERNELS_H + +#include "flexflow/accessor.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/op_meta.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { +using Legion::coord_t; + +class RMSNorm; + +class RMSNormMeta : public OpMeta { +public: + RMSNormMeta(FFHandler handler, + RMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator); + ~RMSNormMeta(void); +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) + cudnnTensorDescriptor_t inputTensor, outputTensor; + cudnnReduceTensorDescriptor_t reduceDesc; +#else + miopenTensorDescriptor_t inputTensor, outputTensor; + miopenReduceTensorDescriptor_t reduceDesc; +#endif + +public: + float eps; + void *rms_ptr; + void *norm_ptr; + + float alpha; + float beta; + + int in_dim; + int batch_size; + int num_elements; + Realm::RegionInstance reserveInst; +}; + +namespace Kernels { +namespace RMSNorm { +void forward_kernel_wrapper(RMSNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output); +} // namespace RMSNorm +} // namespace Kernels +} // namespace FlexFlow + +#endif // _FLEXFLOW_OPS_KERNELS_RMSNORM_KERNELS_H diff --git a/include/flexflow/ops/kernels/softmax_kernels.h b/include/flexflow/ops/kernels/softmax_kernels.h index 9aec9f57c9..21b546c360 100644 --- a/include/flexflow/ops/kernels/softmax_kernels.h +++ b/include/flexflow/ops/kernels/softmax_kernels.h @@ -15,37 +15,43 @@ class SoftmaxMeta : public OpMeta { Legion::Domain const &input_domain); #if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) cudnnTensorDescriptor_t inputTensor; + cudnnTensorDescriptor_t outputTensor; #else miopenTensorDescriptor_t inputTensor; + miopenTensorDescriptor_t outputTensor; #endif bool profiling; + bool inference_debugging; int dim; + DataType input_type, output_type; bool last_layer; - char op_name[MAX_OPNAME]; }; namespace Kernels { namespace Softmax { - +template void forward_kernel_wrapper(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr); - + DT const *input_ptr, + DT *output_ptr); +template void backward_kernel_wrapper(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements); namespace Internal { +template void forward_kernel(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr, + DT const *input_ptr, + DT *output_ptr, ffStream_t stream); + +template void backward_kernel(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements, ffStream_t stream); } // namespace Internal diff --git a/include/flexflow/ops/layer_norm.h b/include/flexflow/ops/layer_norm.h index de5ed48df2..9e48d81190 100644 --- a/include/flexflow/ops/layer_norm.h +++ b/include/flexflow/ops/layer_norm.h @@ -1,7 +1,8 @@ #pragma once +#include "flexflow/inference.h" #include "flexflow/model.h" - +#include "flexflow/utils/memory_allocator.h" namespace FlexFlow { class LayerNormMeta; @@ -20,13 +21,23 @@ class LayerNorm : public Op { const ParallelTensor _input, std::vector const &axes, bool _elementwise_affine, + bool _use_bias, float _eps, bool allocate_weights, char const *name); - void init(FFModel const &); - void forward(FFModel const &); - void backward(FFModel const &); - void print_layer(FFModel const &model) { + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { assert(0); } static Op * @@ -52,13 +63,17 @@ class LayerNorm : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void backward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); bool measure_operator_cost(Simulator *sim, MachineView const &pc, - CostMetrics &cost_metrics) const; + CostMetrics &cost_metrics) const override; template static void forward_kernel(LayerNormMeta const *m, T const *input_ptr, @@ -90,7 +105,7 @@ class LayerNorm : public Op { T *beta_grad_ptr); public: - bool elementwise_affine; + bool elementwise_affine, use_bias; int64_t effective_batch_size, effective_num_elements; float eps; std::vector axes; @@ -98,14 +113,17 @@ class LayerNorm : public Op { class LayerNormMeta : public OpMeta { public: - LayerNormMeta(FFHandler handle, LayerNorm const *ln); + LayerNormMeta(FFHandler handle, + LayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator); + ~LayerNormMeta(void); public: - bool elementwise_affine; + bool elementwise_affine, use_bias; int64_t effective_batch_size, effective_num_elements; float eps; void *mean_ptr, *rstd_ptr, *ds_ptr, *db_ptr, *scale_ptr, *bias_ptr; - char op_name[MAX_OPNAME]; + Realm::RegionInstance reserveInst; }; }; // namespace FlexFlow diff --git a/include/flexflow/ops/layer_norm_params.h b/include/flexflow/ops/layer_norm_params.h index 5d06428f4f..3effce6204 100644 --- a/include/flexflow/ops/layer_norm_params.h +++ b/include/flexflow/ops/layer_norm_params.h @@ -1,5 +1,7 @@ #pragma once +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { @@ -9,6 +11,8 @@ struct LayerNormParams { std::vector axes; bool elementwise_affine; float eps; + bool use_bias; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/linear.h b/include/flexflow/ops/linear.h index 286bcdf717..a32df80537 100644 --- a/include/flexflow/ops/linear.h +++ b/include/flexflow/ops/linear.h @@ -1,9 +1,11 @@ #ifndef _FLEXFLOW_LINEAR_H #define _FLEXFLOW_LINEAR_H +#include "flexflow/inference.h" #include "flexflow/node.h" #include "flexflow/operator.h" #include "flexflow/ops/linear_params.h" +#include "flexflow/utils/memory_allocator.h" namespace FlexFlow { @@ -24,6 +26,8 @@ class Linear : public Op { float kernel_reg_lambda, bool _use_bias, DataType _data_type, + DataType _quantization_type, + bool offload, bool allocate_weights, char const *name); Linear(FFModel &model, @@ -37,8 +41,17 @@ class Linear : public Op { bool allocate_weights = false); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override; bool get_int_parameter(PMParameter, int *) const override; static Op * @@ -49,6 +62,10 @@ class Linear : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void forward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, @@ -79,6 +96,7 @@ class Linear : public Op { private: Linear(int guid, bool profiling, + bool inference_debugging, const ParallelTensor input, int out_dim, ActiMode activation, @@ -86,19 +104,19 @@ class Linear : public Op { bool allocate_weights, char const *name); - template + template static OpMeta * init_task_with_dim(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); - template + template static void forward_task_with_dim(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); - template + template static void backward_task_with_dim(Legion::Task const *task, std::vector const ®ions, @@ -116,6 +134,8 @@ class Linear : public Op { float kernel_reg_lambda; bool use_bias; ParallelTensor replica; + DataType quantization_type; + bool offload; }; }; // namespace FlexFlow diff --git a/include/flexflow/ops/linear_params.h b/include/flexflow/ops/linear_params.h index 2c41694960..9a62ebd857 100644 --- a/include/flexflow/ops/linear_params.h +++ b/include/flexflow/ops/linear_params.h @@ -18,6 +18,9 @@ class LinearParams { ActiMode activation; RegularizerMode kernel_reg_type; float kernel_reg_lambda; + DataType quantization_type; + bool offload; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &input_shape) const; void solve_dims(const ParallelTensor input, diff --git a/include/flexflow/ops/mean.h b/include/flexflow/ops/mean.h index 3dc0ac9aa5..33d041031c 100644 --- a/include/flexflow/ops/mean.h +++ b/include/flexflow/ops/mean.h @@ -11,10 +11,10 @@ class Mean : public Op { std::vector const &dims, bool keepdims, char const *name); - void init(FFModel const &); - void forward(FFModel const &); - void backward(FFModel const &); - void print_layer(FFModel const &model) { + void init(FFModel const &) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + void print_layer(FFModel const &model) override { assert(0); } @@ -32,7 +32,7 @@ class Mean : public Op { Legion::Runtime *runtime); bool measure_operator_cost(Simulator *sim, MachineView const &pc, - CostMetrics &cost_metrics) const; + CostMetrics &cost_metrics) const override; }; }; // namespace FlexFlow diff --git a/include/flexflow/ops/noop.h b/include/flexflow/ops/noop.h index 5f39c999e6..e07d10a05e 100644 --- a/include/flexflow/ops/noop.h +++ b/include/flexflow/ops/noop.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_NOOP_H #define _FLEXFLOW_NOOP_H +#include "flexflow/inference.h" #include "flexflow/model.h" namespace FlexFlow { @@ -17,7 +18,16 @@ class NoOp : public Op { const ParallelTensor output, char const *name = NULL); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; void print_layer(FFModel const &model) override { assert(0); diff --git a/include/flexflow/ops/pool_2d_params.h b/include/flexflow/ops/pool_2d_params.h index 7d4f1f1c12..54af7f9db6 100644 --- a/include/flexflow/ops/pool_2d_params.h +++ b/include/flexflow/ops/pool_2d_params.h @@ -10,6 +10,7 @@ struct Pool2DParams { int kernel_h, kernel_w, stride_h, stride_w, padding_h, padding_w; PoolType pool_type; ActiMode activation; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &input) const; void solve_dims(ParallelTensorShape const &input, diff --git a/include/flexflow/ops/reduce_params.h b/include/flexflow/ops/reduce_params.h index a4777f2be9..478649584f 100644 --- a/include/flexflow/ops/reduce_params.h +++ b/include/flexflow/ops/reduce_params.h @@ -1,5 +1,7 @@ #pragma once +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { @@ -8,6 +10,7 @@ struct ReduceParams { std::vector axes; bool keepdims; LayerID layer_guid; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/reshape_params.h b/include/flexflow/ops/reshape_params.h index f6aa4f8c51..15753c8e17 100644 --- a/include/flexflow/ops/reshape_params.h +++ b/include/flexflow/ops/reshape_params.h @@ -1,6 +1,8 @@ #ifndef _FLEXFLOW_RESHAPE_PARAMS_H #define _FLEXFLOW_RESHAPE_PARAMS_H +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" #include "flexflow/parallel_tensor.h" namespace FlexFlow { @@ -8,6 +10,7 @@ namespace FlexFlow { struct ReshapeParams { std::vector shape; LayerID layer_guid; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/residual_layer_norm.h b/include/flexflow/ops/residual_layer_norm.h new file mode 100644 index 0000000000..0e9be82125 --- /dev/null +++ b/include/flexflow/ops/residual_layer_norm.h @@ -0,0 +1,112 @@ +#pragma once + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/utils/memory_allocator.h" +namespace FlexFlow { + +class ResidualLayerNormMeta; + +class ResidualLayerNorm : public Op { +public: + using Params = ResidualLayerNormParams; + using Input = std::tuple; + ResidualLayerNorm(FFModel &model, + Params const ¶ms, + Input const &inputs, + bool allocate_weights = false, + char const *name = nullptr); + ResidualLayerNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + const ParallelTensor _residual1, + const ParallelTensor _residual2, + bool _use_two_residuals, + std::vector const &axes, + bool _elementwise_affine, + bool _use_bias, + float _eps, + bool allocate_weights, + char const *name); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + ResidualLayerNormParams get_params() const; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void inference_kernel(ResidualLayerNormMeta const *m, + T const *input_ptr, + T const *residual1_ptr, + T const *residual2_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + ffStream_t stream); + static void inference_kernel_wrapper(ResidualLayerNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &residual1, + GenericTensorAccessorR const &residual2, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta); + +public: + bool elementwise_affine, use_bias, use_two_residuals; + int64_t effective_batch_size, effective_num_elements; + float eps; + std::vector axes; +}; + +class ResidualLayerNormMeta : public OpMeta { +public: + ResidualLayerNormMeta(FFHandler handle, + ResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator); + ~ResidualLayerNormMeta(void); + +public: + bool elementwise_affine, use_bias, use_two_residuals; + int64_t effective_batch_size, effective_num_elements; + float eps; + void *mean_ptr, *rstd_ptr, *ds_ptr, *db_ptr, *scale_ptr, *bias_ptr; + Realm::RegionInstance reserveInst; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/ops/residual_layer_norm_params.h b/include/flexflow/ops/residual_layer_norm_params.h new file mode 100644 index 0000000000..949ae0c799 --- /dev/null +++ b/include/flexflow/ops/residual_layer_norm_params.h @@ -0,0 +1,32 @@ +#pragma once + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct ResidualLayerNormParams { + LayerID layer_guid; + std::vector axes; + bool elementwise_affine; + float eps; + bool use_bias; + bool use_two_residuals; + char name[MAX_OPNAME]; + bool is_valid(std::tuple const &) const; +}; + +bool operator==(ResidualLayerNormParams const &, + ResidualLayerNormParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::ResidualLayerNormParams const &) const; +}; +} // namespace std diff --git a/include/flexflow/ops/residual_rms_norm.h b/include/flexflow/ops/residual_rms_norm.h new file mode 100644 index 0000000000..0d92a236e8 --- /dev/null +++ b/include/flexflow/ops/residual_rms_norm.h @@ -0,0 +1,87 @@ +#ifndef _FLEXFLOW_RESIDUAL_RMS_NORM_H +#define _FLEXFLOW_RESIDUAL_RMS_NORM_H + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/ops/residual_rms_norm_params.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +class ResidualRMSNormMeta; + +class ResidualRMSNorm : public Op { +public: + using Params = ResidualRMSNormParams; + using Input = std::pair; + ResidualRMSNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input1, + const ParallelTensor _input2, + float _eps, + int dim, + bool allocate_weights, + char const *name); + ResidualRMSNorm(FFModel &model, + ResidualRMSNormParams const ¶ms, + Input const &inputs, + bool allocate_weights, + char const *name = nullptr); + + ResidualRMSNorm(FFModel &model, + ResidualRMSNorm const &other, + Input const &inputs, + bool allocate_weights); + void init(FFModel const &) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + ResidualRMSNormParams get_params() const; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void forward_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + +public: + float eps; + int effective_batch_size; + int dim, data_dim; +}; +} // namespace FlexFlow +#endif // _FLEXFLOW_RESIDUAL_RMS_NORM_H diff --git a/include/flexflow/ops/residual_rms_norm_params.h b/include/flexflow/ops/residual_rms_norm_params.h new file mode 100644 index 0000000000..a4e4de59ab --- /dev/null +++ b/include/flexflow/ops/residual_rms_norm_params.h @@ -0,0 +1,30 @@ +#ifndef _FLEXFLOW_RESIDUAL_RMSNORM_PARAMS_H +#define _FLEXFLOW_RESIDUAL_RMSNORM_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct ResidualRMSNormParams { + LayerID layer_guid; + float eps; + int dim; + char name[MAX_OPNAME]; + bool is_valid( + std::pair const &input) const; +}; + +bool operator==(ResidualRMSNormParams const &, ResidualRMSNormParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::ResidualRMSNormParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_RESIDUAL_RMSNORM_PARAMS_H \ No newline at end of file diff --git a/include/flexflow/ops/rms_norm.h b/include/flexflow/ops/rms_norm.h new file mode 100644 index 0000000000..1dc940ebd3 --- /dev/null +++ b/include/flexflow/ops/rms_norm.h @@ -0,0 +1,86 @@ +#ifndef _FLEXFLOW_RMS_NORM_H +#define _FLEXFLOW_RMS_NORM_H + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/ops/rms_norm_params.h" +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +class RMSNormMeta; + +class RMSNorm : public Op { +public: + using Params = RMSNormParams; + using Input = ParallelTensor; + RMSNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + float _eps, + int dim, + bool allocate_weights, + char const *name); + RMSNorm(FFModel &model, + RMSNormParams const ¶ms, + ParallelTensor input, + bool allocate_weights, + char const *name = nullptr); + + RMSNorm(FFModel &model, + RMSNorm const &other, + const ParallelTensor input, + bool allocate_weights); + void init(FFModel const &) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + RMSNormParams get_params() const; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void forward_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + +public: + float eps; + int effective_batch_size; + int dim, data_dim; +}; +} // namespace FlexFlow +#endif // _FLEXFLOW_RMS_NORM_H diff --git a/include/flexflow/ops/rms_norm_params.h b/include/flexflow/ops/rms_norm_params.h new file mode 100644 index 0000000000..2e4ceecf48 --- /dev/null +++ b/include/flexflow/ops/rms_norm_params.h @@ -0,0 +1,29 @@ +#ifndef _FLEXFLOW_RMSNORM_PARAMS_H +#define _FLEXFLOW_RMSNORM_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct RMSNormParams { + LayerID layer_guid; + float eps; + int dim; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; + +bool operator==(RMSNormParams const &, RMSNormParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::RMSNormParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_RMSNORM_PARAMS_H \ No newline at end of file diff --git a/include/flexflow/ops/sampling.h b/include/flexflow/ops/sampling.h new file mode 100644 index 0000000000..1696582cc1 --- /dev/null +++ b/include/flexflow/ops/sampling.h @@ -0,0 +1,117 @@ +#ifndef _FLEXFLOW_SAMPLING_TOPK_H_ +#define _FLEXFLOW_SAMPLING_TOPK_H_ + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/node.h" +#include "flexflow/ops/sampling_params.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include +#include +#elif defined(FF_USE_HIP_ROCM) +#include +#include +#endif +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +class SamplingMeta : public OpMeta { +public: + float top_p; + void *sorted_logits; + int *sorted_idx; + int *begin_offset; + int *end_offset; + int *idx; + void *d_temp_storage; + size_t temp_storage_bytes; + Realm::RegionInstance reserveInst; +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) + curandState *state; +#elif defined(FF_USE_HIP_ROCM) + hiprandState *state; +#endif + SamplingMeta(FFHandler handle, + Op const *op, + int batch_size, + int total_ele, + GenericTensorAccessorW input, + MemoryAllocator &gpu_mem_allocator); + ~SamplingMeta(void); +}; + +class Sampling : public Op { +public: + using Params = SamplingParams; + using Input = ParallelTensor; + Sampling(FFModel &model, + const ParallelTensor input, + float top_p, + char const *name); + Sampling(FFModel &model, Sampling const &other, const ParallelTensor input); + Sampling(FFModel &model, + Params const ¶ms, + Input const input, + char const *name = nullptr); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static InferenceResult + inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + void serialize(Legion::Serializer &s) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void forward_kernel(SamplingMeta const *m, + DT *input_ptr, + int *indices_ptr, + float top_p, + int length, + int batch_size, + ffStream_t stream); + static void forward_kernel_wrapper(SamplingMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + int batch_size); + Params get_params() const; + +public: + float top_p; +}; + +}; // namespace FlexFlow + +#endif \ No newline at end of file diff --git a/include/flexflow/ops/sampling_params.h b/include/flexflow/ops/sampling_params.h new file mode 100644 index 0000000000..ddc98a3d6c --- /dev/null +++ b/include/flexflow/ops/sampling_params.h @@ -0,0 +1,25 @@ +#ifndef _FLEXFLOW_SAMPLING_PARAMS_H +#define _FLEXFLOW_SAMPLING_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct SamplingParams { + float top_p; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; +bool operator==(SamplingParams const &, SamplingParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::SamplingParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_SAMPLING_PARAMS_H \ No newline at end of file diff --git a/include/flexflow/ops/sigmoid_silu_multi.h b/include/flexflow/ops/sigmoid_silu_multi.h new file mode 100644 index 0000000000..604438260a --- /dev/null +++ b/include/flexflow/ops/sigmoid_silu_multi.h @@ -0,0 +1,85 @@ +#pragma once + +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/utils/memory_allocator.h" +namespace FlexFlow { + +class SigmoidSiluMultiMeta; + +class SigmoidSiluMulti : public Op { +public: + using Params = SigmoidSiluMultiParams; + using Input = std::pair; + SigmoidSiluMulti(FFModel &model, + Params const ¶ms, + Input const &inputs, + char const *name = nullptr); + SigmoidSiluMulti(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input1, + const ParallelTensor _input2, + char const *name = nullptr); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); + + SigmoidSiluMultiParams get_params() const; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &pc, + CostMetrics &cost_metrics) const override; + template + static void inference_kernel(SigmoidSiluMultiMeta const *m, + int num_elements, + T const *input1_ptr, + T const *input2_ptr, + T *output_ptr, + ffStream_t stream); + static void inference_kernel_wrapper(SigmoidSiluMultiMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorW const &output); +}; + +class SigmoidSiluMultiMeta : public OpMeta { +public: + SigmoidSiluMultiMeta(FFHandler handle, + SigmoidSiluMulti const *ln, + MemoryAllocator &gpu_mem_allocator); + ~SigmoidSiluMultiMeta(void); + +public: + Realm::RegionInstance reserveInst; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/ops/sigmoid_silu_multi_params.h b/include/flexflow/ops/sigmoid_silu_multi_params.h new file mode 100644 index 0000000000..eb152db5c1 --- /dev/null +++ b/include/flexflow/ops/sigmoid_silu_multi_params.h @@ -0,0 +1,25 @@ +#pragma once + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct SigmoidSiluMultiParams { + LayerID layer_guid; + char name[MAX_OPNAME]; + bool is_valid( + std::pair const &) const; +}; + +bool operator==(SigmoidSiluMultiParams const &, SigmoidSiluMultiParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t operator()(FlexFlow::SigmoidSiluMultiParams const &) const; +}; +} // namespace std diff --git a/include/flexflow/ops/softmax.h b/include/flexflow/ops/softmax.h index 2616294a3a..b145d7ca37 100644 --- a/include/flexflow/ops/softmax.h +++ b/include/flexflow/ops/softmax.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_SOFTMAX_H #define _FLEXFLOW_SOFTMAX_H +#include "flexflow/inference.h" #include "flexflow/layer.h" #include "flexflow/node.h" #include "flexflow/operator.h" @@ -13,6 +14,7 @@ class Softmax : public Op { using Params = SoftmaxParams; using Input = ParallelTensor; Softmax(FFModel &model, + LayerID const &_layer_guid, const ParallelTensor logit, int dim, bool _last_layer, @@ -22,7 +24,16 @@ class Softmax : public Op { const Input input, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; void print_layer(FFModel const &model) override { @@ -44,19 +55,28 @@ class Softmax : public Op { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); bool measure_operator_cost(Simulator *sim, MachineView const &pc, CostMetrics &cost_metrics) const override; + void serialize(Legion::Serializer &) const override; + static PCG::Node deserialize(FFModel &ff, + Legion::Deserializer &d, + ParallelTensor inputs[], + int num_inputs); Params get_params() const; private: - template + template static void forward_task_with_dim(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); - template + template static void backward_task_with_dim(Legion::Task const *task, std::vector const ®ions, diff --git a/include/flexflow/ops/softmax_params.h b/include/flexflow/ops/softmax_params.h index 545e3a5cb9..a6ad3a2dbd 100644 --- a/include/flexflow/ops/softmax_params.h +++ b/include/flexflow/ops/softmax_params.h @@ -6,7 +6,9 @@ namespace FlexFlow { struct SoftmaxParams { + LayerID layer_guid; int dim; + char name[MAX_OPNAME]; bool last_layer; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/spec_inc_multihead_self_attention.h b/include/flexflow/ops/spec_inc_multihead_self_attention.h new file mode 100644 index 0000000000..a0d01092bf --- /dev/null +++ b/include/flexflow/ops/spec_inc_multihead_self_attention.h @@ -0,0 +1,151 @@ +#ifndef _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_H +#define _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_H + +#include "flexflow/accessor.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/inference.h" +#include "flexflow/layer.h" +#include "flexflow/node.h" +#include "flexflow/op_meta.h" +#include "flexflow/operator.h" +#include "flexflow/ops/inc_multihead_self_attention.h" +#include "flexflow/ops/spec_inc_multihead_self_attention_params.h" +#include "math.h" +#include +#include + +namespace FlexFlow { + +class SpecIncMultiHeadSelfAttentionMeta; + +class SpecIncMultiHeadSelfAttention : public Op { +public: + using Params = SpecIncMultiHeadSelfAttentionParams; + using Input = ParallelTensor; + + SpecIncMultiHeadSelfAttention(FFModel &model, + LayerID const &layer_guid, + const ParallelTensor _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + char const *name); + SpecIncMultiHeadSelfAttention(FFModel &model, + const ParallelTensor _input, + const ParallelTensor _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + char const *name); + SpecIncMultiHeadSelfAttention(FFModel &model, + SpecIncMultiHeadSelfAttention const &other, + const ParallelTensor input, + bool allocate_weights); + SpecIncMultiHeadSelfAttention(FFModel &model, + Params const ¶ms, + Input const &inputs, + bool allocate_weights = false, + char const *name = nullptr); + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + bool get_int_parameter(PMParameter, int *) const override; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + Op *materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const override; + bool measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const override; + + static void + inference_kernel_wrapper(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias); + Params get_params() const; + +public: + int num_q_heads, num_kv_heads, tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias; + bool final_bias, add_zero_attn, apply_rotary_embedding, scaling_query, + qk_prod_scaling, position_bias; + int qSize, kSize, vSize, qProjSize, kProjSize, vProjSize, oProjSize; + int qoSeqLength, kvSeqLength; +}; + +class SpecIncMultiHeadSelfAttentionMeta : public IncMultiHeadSelfAttentionMeta { +public: + SpecIncMultiHeadSelfAttentionMeta(FFHandler handler, + SpecIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads); + ~SpecIncMultiHeadSelfAttentionMeta(void); + +public: + Realm::RegionInstance beam_search_reserve_inst; + BeamSearchBatchConfig::BeamSearchPerTokenInfo *beam_token_infos; + BeamSearchBatchConfig::BeamSearchPerRequestInfo *beam_request_infos; + bool *request_completed; + BatchConfig::BitMask *causalMask; +}; + +}; // namespace FlexFlow + +#endif // _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_H diff --git a/include/flexflow/ops/spec_inc_multihead_self_attention_params.h b/include/flexflow/ops/spec_inc_multihead_self_attention_params.h new file mode 100644 index 0000000000..1461224ba9 --- /dev/null +++ b/include/flexflow/ops/spec_inc_multihead_self_attention_params.h @@ -0,0 +1,33 @@ +#ifndef _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H +#define _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct SpecIncMultiHeadSelfAttentionParams { + LayerID layer_guid; + int embed_dim, num_q_heads, num_kv_heads, kdim, vdim; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, position_bias; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; + +bool operator==(SpecIncMultiHeadSelfAttentionParams const &, + SpecIncMultiHeadSelfAttentionParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t + operator()(FlexFlow::SpecIncMultiHeadSelfAttentionParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_SPEC_INC_MULTIHEAD_SELF_ATTENTION_PARAMS_H diff --git a/include/flexflow/ops/split.h b/include/flexflow/ops/split.h index 6c0736a76f..95c569738d 100644 --- a/include/flexflow/ops/split.h +++ b/include/flexflow/ops/split.h @@ -22,6 +22,15 @@ class Split : public Op { const Input input, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; void print_layer(FFModel const &model) override { diff --git a/include/flexflow/ops/split_params.h b/include/flexflow/ops/split_params.h index f0f3b2e956..e21a1ab4a1 100644 --- a/include/flexflow/ops/split_params.h +++ b/include/flexflow/ops/split_params.h @@ -8,6 +8,7 @@ namespace FlexFlow { struct SplitParams { std::vector splits; int legion_axis; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/topk.h b/include/flexflow/ops/topk.h index 6b1613c828..47144bf6d7 100644 --- a/include/flexflow/ops/topk.h +++ b/include/flexflow/ops/topk.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_TOPK_H_ #define _FLEXFLOW_TOPK_H_ +#include "flexflow/inference.h" #include "flexflow/model.h" #include "flexflow/node.h" #include "flexflow/ops/topk_params.h" @@ -28,8 +29,17 @@ class TopK : public Op { Input const input, char const *name = nullptr); void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void print_layer(FFModel const &model) override { assert(0); } diff --git a/include/flexflow/ops/topk_params.h b/include/flexflow/ops/topk_params.h index 8b9a0f1bd5..01c6ae9da7 100644 --- a/include/flexflow/ops/topk_params.h +++ b/include/flexflow/ops/topk_params.h @@ -9,6 +9,7 @@ namespace FlexFlow { struct TopKParams { int k; bool sorted; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(TopKParams const &, TopKParams const &); diff --git a/include/flexflow/ops/transpose_params.h b/include/flexflow/ops/transpose_params.h index 42737ee3e9..2e3e34007a 100644 --- a/include/flexflow/ops/transpose_params.h +++ b/include/flexflow/ops/transpose_params.h @@ -6,6 +6,7 @@ namespace FlexFlow { struct TransposeParams { std::vector perm; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; diff --git a/include/flexflow/ops/tree_inc_multihead_self_attention.h b/include/flexflow/ops/tree_inc_multihead_self_attention.h new file mode 100644 index 0000000000..02df0c0137 --- /dev/null +++ b/include/flexflow/ops/tree_inc_multihead_self_attention.h @@ -0,0 +1,156 @@ +#ifndef _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_H +#define _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_H + +#include "flexflow/accessor.h" +#include "flexflow/device.h" +#include "flexflow/fftype.h" +#include "flexflow/inference.h" +#include "flexflow/layer.h" +#include "flexflow/node.h" +#include "flexflow/op_meta.h" +#include "flexflow/operator.h" +#include "flexflow/ops/inc_multihead_self_attention.h" +#include "flexflow/ops/tree_inc_multihead_self_attention_params.h" +#include "math.h" +#include +#include + +namespace FlexFlow { + +class TreeIncMultiHeadSelfAttentionMeta; + +class TreeIncMultiHeadSelfAttention : public Op { +public: + using Params = TreeIncMultiHeadSelfAttentionParams; + using Input = ParallelTensor; + + TreeIncMultiHeadSelfAttention(FFModel &model, + LayerID const &layer_guid, + const ParallelTensor _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name); + TreeIncMultiHeadSelfAttention(FFModel &model, + const ParallelTensor _input, + const ParallelTensor _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name); + TreeIncMultiHeadSelfAttention(FFModel &model, + TreeIncMultiHeadSelfAttention const &other, + const ParallelTensor input, + bool allocate_weights); + TreeIncMultiHeadSelfAttention(FFModel &model, + Params const ¶ms, + Input const &inputs, + bool allocate_weights = false, + char const *name = nullptr); + static Op * + create_operator_from_layer(FFModel &model, + Layer const *layer, + std::vector const &inputs); + void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void forward(FFModel const &) override; + void backward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; + void print_layer(FFModel const &model) override { + assert(0); + } + bool get_int_parameter(PMParameter, int *) const override; + + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + bool measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const override; + + static void inference_kernel_wrapper(TreeIncMultiHeadSelfAttentionMeta *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias); + + Params get_params() const; + +public: + int num_q_heads, num_kv_heads, tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias; + bool final_bias, add_zero_attn, apply_rotary_embedding, scaling_query, + qk_prod_scaling, position_bias; + int qSize, kSize, vSize, qProjSize, kProjSize, vProjSize, oProjSize; + int qoSeqLength, kvSeqLength; + DataType quantization_type; + bool offload; +}; + +class TreeIncMultiHeadSelfAttentionMeta : public IncMultiHeadSelfAttentionMeta { +public: + TreeIncMultiHeadSelfAttentionMeta(FFHandler handler, + TreeIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads); + ~TreeIncMultiHeadSelfAttentionMeta(void); + +public: + int num_active_tokens; + Realm::RegionInstance committed_token_reserve_inst; + TreeVerifyBatchConfig::CommittedTokensInfo *committed_token_infos; + bool *request_completed; + BatchConfig::BitMask *causalMask; +}; + +}; // namespace FlexFlow + +#endif // _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_H diff --git a/include/flexflow/ops/tree_inc_multihead_self_attention_params.h b/include/flexflow/ops/tree_inc_multihead_self_attention_params.h new file mode 100644 index 0000000000..d1a51b8b8f --- /dev/null +++ b/include/flexflow/ops/tree_inc_multihead_self_attention_params.h @@ -0,0 +1,36 @@ +#ifndef _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_PARAMS_H +#define _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_PARAMS_H + +#include "flexflow/ffconst.h" +#include "flexflow/fftype.h" +#include "flexflow/parallel_tensor.h" + +namespace FlexFlow { + +struct TreeIncMultiHeadSelfAttentionParams { + LayerID layer_guid; + int embed_dim, num_q_heads, kdim, vdim, num_kv_heads, + tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, position_bias; + DataType quantization_type; + bool offload; + char name[MAX_OPNAME]; + bool is_valid(ParallelTensorShape const &) const; +}; + +bool operator==(TreeIncMultiHeadSelfAttentionParams const &, + TreeIncMultiHeadSelfAttentionParams const &); + +} // namespace FlexFlow + +namespace std { +template <> +struct hash { + size_t + operator()(FlexFlow::TreeIncMultiHeadSelfAttentionParams const &) const; +}; +} // namespace std + +#endif // _FLEXFLOW_INC_MULTIHEAD_SELF_ATTENTION_VERIFY_PARAMS_H diff --git a/include/flexflow/parallel_ops/allreduce.h b/include/flexflow/parallel_ops/allreduce.h index a28d4cef9e..8e3f92efe0 100644 --- a/include/flexflow/parallel_ops/allreduce.h +++ b/include/flexflow/parallel_ops/allreduce.h @@ -24,8 +24,21 @@ class AllReduce : public ParallelOp { Input const input, char const *name = nullptr); void create_input_partition(FFModel &model) override; + void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) override; void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &bc, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; bool append_parallel_op_info( @@ -34,6 +47,11 @@ class AllReduce : public ParallelOp { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); + static void inference_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void forward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, diff --git a/include/flexflow/parallel_ops/combine.h b/include/flexflow/parallel_ops/combine.h index 310e599f54..2e4fdb86a9 100644 --- a/include/flexflow/parallel_ops/combine.h +++ b/include/flexflow/parallel_ops/combine.h @@ -3,6 +3,7 @@ #include "flexflow/layer.h" #include "flexflow/node.h" +#include "flexflow/op_meta.h" #include "flexflow/operator.h" #include "flexflow/parallel_ops/combine_params.h" #include "parallel_op.h" @@ -24,8 +25,21 @@ class Combine : public ParallelOp { Input const input, char const *name = nullptr); void create_input_partition(FFModel &model) override; + void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) override; void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &bc, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; bool append_parallel_op_info( diff --git a/include/flexflow/parallel_ops/combine_params.h b/include/flexflow/parallel_ops/combine_params.h index 74ef01e08f..8ca05f7f50 100644 --- a/include/flexflow/parallel_ops/combine_params.h +++ b/include/flexflow/parallel_ops/combine_params.h @@ -6,6 +6,7 @@ namespace FlexFlow { struct CombineParams { int combine_legion_dim; int combine_degree; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(CombineParams const &, CombineParams const &); diff --git a/include/flexflow/parallel_ops/fused_parallel_op_params.h b/include/flexflow/parallel_ops/fused_parallel_op_params.h index cba3844a4c..8c56b30998 100644 --- a/include/flexflow/parallel_ops/fused_parallel_op_params.h +++ b/include/flexflow/parallel_ops/fused_parallel_op_params.h @@ -7,6 +7,7 @@ namespace FlexFlow { struct FusedParallelOpParams { std::vector parallel_ops; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(FusedParallelOpParams const &, FusedParallelOpParams const &); diff --git a/include/flexflow/parallel_ops/kernels/allreduce_kernels.h b/include/flexflow/parallel_ops/kernels/allreduce_kernels.h index 02a5026fcf..93b82079cc 100644 --- a/include/flexflow/parallel_ops/kernels/allreduce_kernels.h +++ b/include/flexflow/parallel_ops/kernels/allreduce_kernels.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_OPS_KERNELS_ALLREDUCE_KERNELS_H #define _FLEXFLOW_OPS_KERNELS_ALLREDUCE_KERNELS_H +#include "flexflow/batch_config.h" #include "flexflow/device.h" #include "flexflow/fftype.h" #include "flexflow/op_meta.h" @@ -16,6 +17,12 @@ class AllReduceMeta : public OpMeta { namespace Kernels { namespace AllReduce { +void inference_kernel_wrapper(AllReduceMeta const *m, + BatchConfig const *bc, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &output); + + void forward_kernel_wrapper(AllReduceMeta const *m, GenericTensorAccessorR const &input, GenericTensorAccessorW const &output); diff --git a/include/flexflow/parallel_ops/kernels/combine_kernels.h b/include/flexflow/parallel_ops/kernels/combine_kernels.h index 6f540679a2..456013cd81 100644 --- a/include/flexflow/parallel_ops/kernels/combine_kernels.h +++ b/include/flexflow/parallel_ops/kernels/combine_kernels.h @@ -4,6 +4,7 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" #include "flexflow/op_meta.h" +#include "flexflow/parallel_ops/combine.h" namespace FlexFlow { diff --git a/include/flexflow/parallel_ops/kernels/reduction_kernels.h b/include/flexflow/parallel_ops/kernels/reduction_kernels.h index e9f6a9d070..51ddced227 100644 --- a/include/flexflow/parallel_ops/kernels/reduction_kernels.h +++ b/include/flexflow/parallel_ops/kernels/reduction_kernels.h @@ -3,8 +3,16 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" +#include "flexflow/op_meta.h" +#include "flexflow/parallel_ops/reduction.h" namespace FlexFlow { + +class ReductionMeta : public OpMeta { +public: + ReductionMeta(FFHandler handle, Reduction const *reduct); +}; + namespace Kernels { namespace Reduction { diff --git a/include/flexflow/parallel_ops/kernels/replicate_kernels.h b/include/flexflow/parallel_ops/kernels/replicate_kernels.h index 619d06efef..d5d52797c3 100644 --- a/include/flexflow/parallel_ops/kernels/replicate_kernels.h +++ b/include/flexflow/parallel_ops/kernels/replicate_kernels.h @@ -3,8 +3,16 @@ #include "flexflow/device.h" #include "flexflow/fftype.h" +#include "flexflow/op_meta.h" +#include "flexflow/parallel_ops/replicate.h" namespace FlexFlow { + +class ReplicateMeta : public OpMeta { +public: + ReplicateMeta(FFHandler handle, Replicate const *repl); +}; + namespace Kernels { namespace Replicate { diff --git a/include/flexflow/parallel_ops/parallel_op.h b/include/flexflow/parallel_ops/parallel_op.h index a374b7ab40..0bf573996c 100644 --- a/include/flexflow/parallel_ops/parallel_op.h +++ b/include/flexflow/parallel_ops/parallel_op.h @@ -24,6 +24,12 @@ class ParallelOp : public Op { virtual void forward(FFModel const &) = 0; virtual void backward(FFModel const &) = 0; virtual void create_input_partition(FFModel &model) = 0; + virtual void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(false); + } void print_layer(FFModel const &model){}; virtual bool measure_operator_cost(Simulator *sim, MachineView const &pc, @@ -34,6 +40,8 @@ class ParallelOp : public Op { public: Legion::LogicalPartition input_lp, output_grad_lp; + std::unordered_map + inference_input_lps; }; }; // namespace FlexFlow diff --git a/include/flexflow/parallel_ops/partition.h b/include/flexflow/parallel_ops/partition.h index 5c2fa9c228..4b0013b11d 100644 --- a/include/flexflow/parallel_ops/partition.h +++ b/include/flexflow/parallel_ops/partition.h @@ -1,6 +1,7 @@ #ifndef _FLEXFLOW_PARTITION_H #define _FLEXFLOW_PARTITION_H +#include "flexflow/inference.h" #include "flexflow/layer.h" #include "flexflow/node.h" #include "flexflow/operator.h" @@ -24,8 +25,21 @@ class Repartition : public ParallelOp { Input const input, char const *name = nullptr); void create_input_partition(FFModel &model) override; + void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) override; void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &bc, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; bool append_parallel_op_info( diff --git a/include/flexflow/parallel_ops/partition_params.h b/include/flexflow/parallel_ops/partition_params.h index 921ab43eaf..33ccf6b02c 100644 --- a/include/flexflow/parallel_ops/partition_params.h +++ b/include/flexflow/parallel_ops/partition_params.h @@ -6,6 +6,7 @@ namespace FlexFlow { struct RepartitionParams { int repartition_legion_dim; int repartition_degree; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(RepartitionParams const &, RepartitionParams const &); diff --git a/include/flexflow/parallel_ops/reduction.h b/include/flexflow/parallel_ops/reduction.h index fed5f049c7..89f8bfbee0 100644 --- a/include/flexflow/parallel_ops/reduction.h +++ b/include/flexflow/parallel_ops/reduction.h @@ -25,12 +25,29 @@ class Reduction : public ParallelOp { Input const input, char const *name = nullptr); void create_input_partition(FFModel &model) override; + void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) override; void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &bc, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; bool append_parallel_op_info( std::vector ¶llel_ops) const override; + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void forward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, diff --git a/include/flexflow/parallel_ops/reduction_params.h b/include/flexflow/parallel_ops/reduction_params.h index fab7da2626..60b6c4f6aa 100644 --- a/include/flexflow/parallel_ops/reduction_params.h +++ b/include/flexflow/parallel_ops/reduction_params.h @@ -6,6 +6,7 @@ namespace FlexFlow { struct ReductionParams { int reduction_legion_dim; int reduction_degree; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(ReductionParams const &, ReductionParams const &); diff --git a/include/flexflow/parallel_ops/replicate.h b/include/flexflow/parallel_ops/replicate.h index ac41a6437e..719d99dd8d 100644 --- a/include/flexflow/parallel_ops/replicate.h +++ b/include/flexflow/parallel_ops/replicate.h @@ -10,6 +10,8 @@ namespace FlexFlow { +class ReplicateMeta; + class Replicate : public ParallelOp { public: using Params = ReplicateParams; @@ -25,16 +27,29 @@ class Replicate : public ParallelOp { Input const input, char const *name = nullptr); void create_input_partition(FFModel &model) override; + void create_input_partition_inference( + FFModel &model, + std::vector const &batch_inputs, + std::vector const &batch_outputs) override; void init(FFModel const &) override; + void init_inference(FFModel const &, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void forward(FFModel const &) override; + Legion::FutureMap inference(FFModel const &, + BatchConfigFuture const &bc, + std::vector const &, + std::vector const &, + MachineView const *mv = nullptr) override; void backward(FFModel const &) override; bool get_int_parameter(PMParameter, int *) const override; bool append_parallel_op_info( std::vector ¶llel_ops) const override; - static void init_task(Legion::Task const *task, - std::vector const ®ions, - Legion::Context ctx, - Legion::Runtime *runtime); + static OpMeta *init_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); static void forward_task(Legion::Task const *task, std::vector const ®ions, Legion::Context ctx, @@ -43,7 +58,11 @@ class Replicate : public ParallelOp { std::vector const ®ions, Legion::Context ctx, Legion::Runtime *runtime); - + static void forward_kernel_wrapper(ReplicateMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &output, + size_t num_elements, + size_t num_replicas); template static void forward_task_with_type(Legion::Task const *task, diff --git a/include/flexflow/parallel_ops/replicate_params.h b/include/flexflow/parallel_ops/replicate_params.h index 06edbc1ddc..da1f94217c 100644 --- a/include/flexflow/parallel_ops/replicate_params.h +++ b/include/flexflow/parallel_ops/replicate_params.h @@ -6,6 +6,7 @@ namespace FlexFlow { struct ReplicateParams { int replicate_legion_dim; int replicate_degree; + char name[MAX_OPNAME]; bool is_valid(ParallelTensorShape const &) const; }; bool operator==(ReplicateParams const &, ReplicateParams const &); diff --git a/include/flexflow/parallel_tensor.h b/include/flexflow/parallel_tensor.h index d98ffdc666..a04c1afe86 100644 --- a/include/flexflow/parallel_tensor.h +++ b/include/flexflow/parallel_tensor.h @@ -170,6 +170,20 @@ struct ParallelTensorBase { bool get_tensor(FFModel const *model, T *data, bool get_parameters); ParallelTensorShape get_shape() const; + template + bool tensor_equal(FFConfig &config, ParallelTensorBase &tensor); + static bool + tensor_equal_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + template + static bool tensor_equal_task_with_dim( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + private: template bool get_input_sub_tensor_via_mappings(ParallelConfig const &pc, diff --git a/include/flexflow/request_manager.h b/include/flexflow/request_manager.h new file mode 100644 index 0000000000..a38a3b2671 --- /dev/null +++ b/include/flexflow/request_manager.h @@ -0,0 +1,312 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#pragma once + +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/model.h" +#include "flexflow/utils/file_loader.h" +#include +#include +#include + +namespace FlexFlow { + +class FFModel; +class BeamTree; +class RequestManager; +using tokenizers::Tokenizer; + +class InferenceManager { +public: + InferenceManager(); + static InferenceManager *get_inference_manager(); + void compile_model_and_allocate_buffer(FFModel *model); + void init_operators_inference(FFModel *model); + Legion::FutureMap inference(FFModel *model, int index, BatchConfig const &bc); + Legion::FutureMap + inference(FFModel *model, int index, BatchConfigFuture const &bc); + void load_input_tokens_from_batch_config(FFModel *model, + BatchConfigFuture const &bc, + ParallelTensor const input, + FFHandler *handlers); + void load_positions(FFModel *model, + BatchConfigFuture const &bc, + ParallelTensor position_input, + int offset); + void register_model_weights_loader(FFModel *, FileDataLoader *); + void load_inference_metadata_batch_config(FFModel *model, + BatchConfigFuture const &bc, + FFHandler *handlers); + +public: + std::unordered_map> tensor_buffer; + std::unordered_map model_weights_loaders; +}; + +struct Request { + enum Status { + PENDING = 101, // loading prompt + RUNNING = 102, // running inference + COMPLETED = 103, // finished and verified + FINISHING = 104, // finishing request, but not yet verified + }; + BatchConfig::RequestGuid guid; + int max_sequence_length; + int initial_len; + int ssm_cache_size = 0; + int llm_cache_size = 0; + + Status status = PENDING; + std::vector tokens; + + std::vector beam_trees; +}; + +// store the result of beam search +struct BeamTree { + struct treeLayer { + BeamSearchBatchConfig::TokenId + tokens[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + int parent_ids[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + float probs[BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES]; + int nodes_num_this_layer = 0; + }; + treeLayer treeLayers[BeamSearchBatchConfig::MAX_BEAM_DEPTH + 1]; +}; + +// struct BeamTree_v2 { +// std::vector tokens; +// std::vector parent_ids; +// std::vector probs; +// }; + +class RequestManager { +public: + enum Status { + INITIALIZED = 1001, + SERVING = 1002, + TERMINATED = 1003, + }; + using RequestGuid = BatchConfig::RequestGuid; + using TokenId = BatchConfig::TokenId; + + static const RequestGuid INVALID_GUID = 0; + RequestManager(); + static RequestManager *get_request_manager(); + size_t get_num_processed_requests(); + size_t get_num_ssms(); + + void set_max_requests_per_batch(int max_num_requests); + int get_max_requests_per_batch(); + void set_max_tokens_per_batch(int max_num_tokens); + int get_max_tokens_per_batch(); + void set_max_spec_tree_token_num(int max_num_tokens); + int get_max_spec_tree_token_num(); + int get_max_verify_tokens_per_batch(); + void set_max_sequence_length(int max_seq_length); + void push_spec_infer_tree_width(int tree_width); + int get_max_sequence_length(); + int register_ssm_model(FFModel *model); + void register_tokenizer(ModelType model_type, + int bos_token_id, + int eos_token_id, + std::string const &path); + void register_output_filepath(std::string const &); + void initBitMask(BatchConfig::BitMask &bitmask, int initLength); + void appendPendingRequest(BatchConfig::BitMask &bitmask, int initLength); + void appendBitMask(BatchConfig::BitMask &bitmask, + int newNodes, + int preBeamSize, + int old_sub_num, + BeamTree const tree, + int currentDepth); + void updateBitMask(BatchConfig::BitMask &bitmask, + int initLength, + int non_tree_size); + + FFModel *get_ssm_model(int model_id); + + void serve_incr_decoding(FFModel *model); + void serve_spec_infer(FFModel *model); + GenerationResult get_generation_result(RequestGuid const &guid); + RequestGuid register_new_request(std::string const &prompt, + int max_sequence_length); + RequestGuid register_new_request(std::vector const &prompt, + int max_sequence_length); + // Methods to start and terminate request manager's background task + void start_background_server(FFModel *model); + bool is_background_server_terminated(); + void terminate_background_server(); + static void terminate_background_server_at_exit(); + // Methods to check and mark request completion + bool is_request_completed(RequestGuid const &guid); + void trigger_request_completion_future(RequestGuid const &guid); + // Methods for preparing next batches + BatchConfig prepare_next_batch(BatchConfig const &bc, + InferenceResult const &result); + BatchConfigFuture prepare_next_batch(BatchConfigFuture const &bc, + InferenceResultFuture const &result, + Legion::Context ctx, + Legion::Runtime *runtime); + BeamSearchBatchConfig + prepare_next_batch_beam(BeamSearchBatchConfig const &old_bc, + BeamInferenceResult const &result); + BeamSearchBatchConfigFuture + prepare_next_batch_beam(BeamSearchBatchConfigFuture const &old_bc, + BeamInferenceResultFuture const &result, + Legion::Context ctx, + Legion::Runtime *runtime); + BeamSearchBatchConfig + prepare_next_batch_init(TreeVerifyBatchConfig const &old_bc, + InferenceResult const &result, + int model_id); + BeamSearchBatchConfigFuture + prepare_next_batch_init(TreeVerifyBatchConfigFuture const &old_bc, + InferenceResultFuture const &result, + int model_id, + Legion::Context ctx, + Legion::Runtime *runtime); + TreeVerifyBatchConfig prepare_next_batch_verify( + std::vector const &old_batches); + TreeVerifyBatchConfigFuture prepare_next_batch_verify( + std::vector const &old_batches, + Legion::Context ctx, + Legion::Runtime *runtime); + + void store_beam_metadata(BeamSearchBatchConfig const &old_bc, + BeamInferenceResult const &result); + void update_beam_metadata(BeamSearchBatchConfig &new_bc, + BeamSearchBatchConfig const &old_bc, + BeamTree &tree, + int request_index); + + std::vector> + traverse_beam_tree(BeamSearchBatchConfig const &old_bc, + int request_index, + int first_token_depth_in_request); + + // remove guid after put the cached tree in request + std::vector> merge_dfs_trees( + std::vector>> + input_trees, + int root_depth, + RequestGuid guid); + + std::vector> traverse_verify_tree( + size_t guid, + std::vector> const + &inputSerializedTree, + std::vector> const + &outputSerializedTree); + static void background_serving_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void + load_tokens_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static void + load_positions_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + + static void + load_batch_config_task(Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + static BatchConfig prepare_next_batch_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + + static BeamSearchBatchConfig prepare_next_batch_beam_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + + static BeamSearchBatchConfig prepare_next_batch_init_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + + static TreeVerifyBatchConfig prepare_next_batch_verify_task( + Legion::Task const *task, + std::vector const ®ions, + Legion::Context ctx, + Legion::Runtime *runtime); + +private: + // configuration parameters + int max_requests_per_batch; + int max_tokens_per_batch; + int max_spec_tree_token_num; + int max_sequence_length; + Status request_manager_status; + + // tree width in each speculative step, if not specified 1 + std::vector spec_infer_tree_width; + + // private fields + std::unique_ptr tokenizer_; + bool verbose; + ModelType model_type; + int bos_token_id; + int eos_token_id; + std::string output_filepath; + std::queue pending_request_queue; + std::unordered_map all_requests; + std::unordered_map request_generation_results; + std::mutex request_queue_mutex; + std::unordered_map *> request_to_promise; + std::mutex request_to_promise_mutex; + RequestGuid next_available_guid; + + // TODO: Move this two vector to request struct + std::unordered_map>> + dfs_tree_inputs; + std::unordered_map>> + committed_tokens; + + // Multi-model support + std::vector ssm_models; + + // Performance profiling + size_t num_processed_requests; + + // Background server handler + Legion::Future background_server_handler; + +private: + struct ProfileInfo { + int llm_decoding_steps; + int ssm_decoding_steps; + double start_time, finish_time; + }; + std::unordered_map profiling_requests; + double total_request_run_time; +}; + +}; // namespace FlexFlow diff --git a/include/flexflow/runtime.h b/include/flexflow/runtime.h new file mode 100644 index 0000000000..e1371300ec --- /dev/null +++ b/include/flexflow/runtime.h @@ -0,0 +1,31 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#ifndef _FLEXFLOW_RUNTIME_H_ +#define _FLEXFLOW_RUNTIME_H_ + +#include "config.h" + +namespace FlexFlow { + +class FFRuntime { +public: + FFRuntime(FFConfig &config); + FFHandler handlers[MAX_NUM_WORKERS]; +}; + +} // namespace FlexFlow + +#endif // _FLEXFLOW_RUNTIME_H_ diff --git a/include/flexflow/simulator.h b/include/flexflow/simulator.h index 9ee1b1eb09..e410f66325 100644 --- a/include/flexflow/simulator.h +++ b/include/flexflow/simulator.h @@ -38,6 +38,7 @@ class LinearMeta; class Pool2DMeta; class ElementUnaryMeta; class ElementBinaryMeta; +class LayerNormMeta; // class EmbeddingMeta; // class SoftmaxMeta; class BatchMatmulMeta; @@ -684,8 +685,6 @@ class TaskManager { std::map hash_to_forward_task, hash_to_backward_task; }; -size_t data_type_size(DataType); - using ProfilingRecordKey = std::tuple; class Simulator { @@ -756,7 +755,8 @@ class Simulator { LinearMeta *linear_meta; Pool2DMeta *pool2d_meta; ElementUnaryMeta *ele_unary_meta; - ElementBinaryMeta *ele_binary_meta; + LayerNormMeta *layernorm_meta; + // ElementBinaryMeta *ele_binary_meta; // EmbeddingMeta *embedding_meta; // SoftmaxMeta *softmax_meta; BatchMatmulMeta *batch_matmul_meta; diff --git a/include/flexflow/substitution_loader.h b/include/flexflow/substitution_loader.h index 9f9db223f2..e0c252ffd8 100644 --- a/include/flexflow/substitution_loader.h +++ b/include/flexflow/substitution_loader.h @@ -41,95 +41,101 @@ NLOHMANN_JSON_SERIALIZE_ENUM(PMParameter, {PM_PARALLEL_DEGREE, "PM_PARALLEL_DEGREE"}, {PM_PAD, "PM_PAD"}}) -NLOHMANN_JSON_SERIALIZE_ENUM(OperatorType, - {{OP_INVALID, nullptr}, - {OP_NOOP, "OP_NOOP"}, - {OP_CONV2D, "OP_CONV2D"}, - {OP_DROPOUT, "OP_DROPOUT"}, - {OP_LINEAR, "OP_LINEAR"}, - {OP_BATCHMATMUL, "OP_BATCHMATMUL"}, - {OP_POOL2D, "OP_POOL2D_MAX"}, - {OP_SCALAR_MULTIPLY, "OP_SCALAR_MULTIPLY"}, - {OP_SCALAR_ADD, "OP_SCALAR_ADD"}, - {OP_SCALAR_FLOOR_DIV, "OP_SCALAR_FLOOR_DIV"}, - {OP_SCALAR_TRUE_DIV, "OP_SCALAR_TRUE_DIV"}, - {OP_SCALAR_SUB, "OP_SCALAR_SUB"}, - {OP_RELU, "OP_RELU"}, - {OP_IDENTITY, "OP_IDENTITY"}, - {OP_SIGMOID, "OP_SIGMOID"}, - {OP_TANH, "OP_TANH"}, - {OP_ELU, "OP_ELU"}, - {OP_FLAT, "OP_FLAT"}, - {OP_SOFTMAX, "OP_SOFTMAX"}, - {OP_BATCHNORM, "OP_BATCHNORM"}, - {OP_CONCAT, "OP_CONCAT"}, - {OP_SPLIT, "OP_SPLIT"}, - {OP_EMBEDDING, "OP_EMBEDDING"}, - {OP_GROUP_BY, "OP_GROUP_BY"}, - {OP_CACHE, "OP_CACHE"}, - {OP_AGGREGATE, "OP_AGGREGATE"}, - {OP_AGG_SPEC, "OP_AGG_SPEC"}, - {OP_RESHAPE, "OP_RESHAPE"}, - {OP_REVERSE, "OP_REVERSE"}, - {OP_TRANSPOSE, "OP_TRANSPOSE"}, - {OP_EW_ADD, "OP_EW_ADD"}, - {OP_EW_MUL, "OP_EW_MUL"}, - {OP_MATMUL, "OP_MATMUL"}, - {OP_MUL, "OP_MUL"}, - {OP_ENLARGE, "OP_ENLARGE"}, - {OP_MERGE_GCONV, "OP_MERGE_GCONV"}, - {OP_CONSTANT_IMM, "OP_CONSTANT_IMM"}, - {OP_CONSTANT_ICONV, "OP_CONSTANT_ICONV"}, - {OP_CONSTANT_ONE, "OP_CONSTANT_ONE"}, - {OP_CONSTANT_POOL, "OP_CONSTANT_POOL"}, - {OP_SQUEEZE, "OP_SQUEEZE"}, - {OP_UNSQUEEZE, "OP_UNSQUEEZE"}, - {OP_EW_SUB, "OP_EW_SUB"}, - {OP_EW_DIV, "OP_EW_DIV"}, - {OP_EW_EQUAL, "OP_EW_EQUAL"}, - {OP_EW_GREATER, "OP_EW_GREATER"}, - {OP_EW_LESS, "OP_EW_LESS"}, - {OP_EW_MAX, "OP_EW_MAX"}, - {OP_EW_MIN, "OP_EW_MIN"}, - {OP_REDUCE_ARGMAX, "OP_REDUCE_ARGMAX"}, - {OP_REDUCE_ARGMIN, "OP_REDUCE_ARGMIN"}, - {OP_REDUCE_MAX, "OP_REDUCE_MAX"}, - {OP_REDUCE_MEAN, "OP_REDUCE_MEAN"}, - {OP_REDUCE_MIN, "OP_REDUCE_MIN"}, - {OP_REDUCE_PROD, "OP_REDUCE_PROD"}, - {OP_REDUCE_SUM, "OP_REDUCE_SUM"}, - {OP_PAD, "OP_PAD"}, - {OP_SHAPE, "OP_SHAPE"}, - {OP_SIZE, "OP_SIZE"}, - {OP_TOPK, "OP_TOPK"}, - {OP_WHERE, "OP_WHERE"}, - {OP_CEIL, "OP_CEIL"}, - {OP_CAST, "OP_CAST"}, - {OP_EXP, "OP_EXP"}, - {OP_ROUND, "OP_ROUND"}, - {OP_LOG, "OP_LOG"}, - {OP_LOGICAL_NOT, "OP_LOGICAL_NOT"}, - {OP_SQRT, "OP_SQRT"}, - {OP_SIN, "OP_SIN"}, - {OP_COS, "OP_COS"}, - {OP_LEAKYRELU, "OP_LEAKYRELU"}, - {OP_SLICE, "OP_SLICE"}, - {OP_RESIZE, "OP_RESIZE"}, - {OP_PRELU, "OP_PRELU"}, - {OP_GELU, "OP_GELU"}, - {OP_MULTIHEAD_ATTENTION, - "OP_MULTIHEAD_ATTENTION"}, - {OP_FUSED, "OP_FUSED"}, - {OP_RSQRT, "OP_RSQRT"}, - {OP_POW, "OP_POW"}, - {OP_MEAN, "OP_MEAN"}, - {OP_LAYERNORM, "OP_LAYERNORM"}, - {OP_REPARTITION, "OP_PARTITION"}, - {OP_COMBINE, "OP_COMBINE"}, - {OP_REPLICATE, "OP_REPLICATE"}, - {OP_REDUCTION, "OP_REDUCE"}, - {OP_PIPELINE, "OP_PIPELINE"}, - {OP_FUSED_PARALLEL, "OP_FUSED_PARALLEL"}}) +NLOHMANN_JSON_SERIALIZE_ENUM( + OperatorType, + {{OP_INVALID, nullptr}, + {OP_NOOP, "OP_NOOP"}, + {OP_CONV2D, "OP_CONV2D"}, + {OP_DROPOUT, "OP_DROPOUT"}, + {OP_LINEAR, "OP_LINEAR"}, + {OP_BATCHMATMUL, "OP_BATCHMATMUL"}, + {OP_POOL2D, "OP_POOL2D_MAX"}, + {OP_SCALAR_MULTIPLY, "OP_SCALAR_MULTIPLY"}, + {OP_SCALAR_ADD, "OP_SCALAR_ADD"}, + {OP_SCALAR_FLOOR_DIV, "OP_SCALAR_FLOOR_DIV"}, + {OP_SCALAR_TRUE_DIV, "OP_SCALAR_TRUE_DIV"}, + {OP_SCALAR_SUB, "OP_SCALAR_SUB"}, + {OP_RELU, "OP_RELU"}, + {OP_IDENTITY, "OP_IDENTITY"}, + {OP_SIGMOID, "OP_SIGMOID"}, + {OP_TANH, "OP_TANH"}, + {OP_ELU, "OP_ELU"}, + {OP_FLAT, "OP_FLAT"}, + {OP_SOFTMAX, "OP_SOFTMAX"}, + {OP_BATCHNORM, "OP_BATCHNORM"}, + {OP_CONCAT, "OP_CONCAT"}, + {OP_SPLIT, "OP_SPLIT"}, + {OP_EMBEDDING, "OP_EMBEDDING"}, + {OP_GROUP_BY, "OP_GROUP_BY"}, + {OP_CACHE, "OP_CACHE"}, + {OP_AGGREGATE, "OP_AGGREGATE"}, + {OP_AGG_SPEC, "OP_AGG_SPEC"}, + {OP_RESHAPE, "OP_RESHAPE"}, + {OP_REVERSE, "OP_REVERSE"}, + {OP_TRANSPOSE, "OP_TRANSPOSE"}, + {OP_EW_ADD, "OP_EW_ADD"}, + {OP_EW_MUL, "OP_EW_MUL"}, + {OP_MATMUL, "OP_MATMUL"}, + {OP_MUL, "OP_MUL"}, + {OP_ENLARGE, "OP_ENLARGE"}, + {OP_MERGE_GCONV, "OP_MERGE_GCONV"}, + {OP_CONSTANT_IMM, "OP_CONSTANT_IMM"}, + {OP_CONSTANT_ICONV, "OP_CONSTANT_ICONV"}, + {OP_CONSTANT_ONE, "OP_CONSTANT_ONE"}, + {OP_CONSTANT_POOL, "OP_CONSTANT_POOL"}, + {OP_SQUEEZE, "OP_SQUEEZE"}, + {OP_UNSQUEEZE, "OP_UNSQUEEZE"}, + {OP_EW_SUB, "OP_EW_SUB"}, + {OP_EW_DIV, "OP_EW_DIV"}, + {OP_EW_EQUAL, "OP_EW_EQUAL"}, + {OP_EW_GREATER, "OP_EW_GREATER"}, + {OP_EW_LESS, "OP_EW_LESS"}, + {OP_EW_MAX, "OP_EW_MAX"}, + {OP_EW_MIN, "OP_EW_MIN"}, + {OP_REDUCE_ARGMAX, "OP_REDUCE_ARGMAX"}, + {OP_REDUCE_ARGMIN, "OP_REDUCE_ARGMIN"}, + {OP_REDUCE_MAX, "OP_REDUCE_MAX"}, + {OP_REDUCE_MEAN, "OP_REDUCE_MEAN"}, + {OP_REDUCE_MIN, "OP_REDUCE_MIN"}, + {OP_REDUCE_PROD, "OP_REDUCE_PROD"}, + {OP_REDUCE_SUM, "OP_REDUCE_SUM"}, + {OP_PAD, "OP_PAD"}, + {OP_SHAPE, "OP_SHAPE"}, + {OP_SIZE, "OP_SIZE"}, + {OP_TOPK, "OP_TOPK"}, + {OP_WHERE, "OP_WHERE"}, + {OP_CEIL, "OP_CEIL"}, + {OP_CAST, "OP_CAST"}, + {OP_EXP, "OP_EXP"}, + {OP_ROUND, "OP_ROUND"}, + {OP_LOG, "OP_LOG"}, + {OP_LOGICAL_NOT, "OP_LOGICAL_NOT"}, + {OP_SQRT, "OP_SQRT"}, + {OP_SIN, "OP_SIN"}, + {OP_COS, "OP_COS"}, + {OP_LEAKYRELU, "OP_LEAKYRELU"}, + {OP_SLICE, "OP_SLICE"}, + {OP_RESIZE, "OP_RESIZE"}, + {OP_PRELU, "OP_PRELU"}, + {OP_GELU, "OP_GELU"}, + {OP_MULTIHEAD_ATTENTION, "OP_MULTIHEAD_ATTENTION"}, + {OP_INC_MULTIHEAD_SELF_ATTENTION, "OP_INC_MULTIHEAD_SELF_ATTENTION"}, + {OP_FUSED, "OP_FUSED"}, + {OP_RSQRT, "OP_RSQRT"}, + {OP_POW, "OP_POW"}, + {OP_MEAN, "OP_MEAN"}, + {OP_LAYERNORM, "OP_LAYERNORM"}, + {OP_RESIDUAL_LAYERNORM, "OP_RESIDUAL_LAYERNORM"}, + {OP_ADD_BIAS_RESIDUAL_LAYERNORM, "OP_ADD_BIAS_RESIDUAL_LAYERNORM"}, + {OP_SIGMOID_SILU_MULTI, "OP_SIGMOID_SILU_MULTI"}, + {OP_RMS_NORM, "OP_RMS_NORM"}, + {OP_RESIDUAL_RMS_NORM, "OP_RESIDUAL_RMS_NORM"}, + {OP_REPARTITION, "OP_PARTITION"}, + {OP_COMBINE, "OP_COMBINE"}, + {OP_REPLICATE, "OP_REPLICATE"}, + {OP_REDUCTION, "OP_REDUCE"}, + {OP_PIPELINE, "OP_PIPELINE"}, + {OP_FUSED_PARALLEL, "OP_FUSED_PARALLEL"}}) namespace FlexFlow { namespace substitution_loader { diff --git a/include/flexflow/utils/cuda_helper.h b/include/flexflow/utils/cuda_helper.h index d077995884..d01ebc8854 100644 --- a/include/flexflow/utils/cuda_helper.h +++ b/include/flexflow/utils/cuda_helper.h @@ -1,9 +1,13 @@ #ifndef _FLEXFLOW_CUDA_HELPER_H_ #define _FLEXFLOW_CUDA_HELPER_H_ +#include "flexflow/accessor.h" #include "flexflow/ffconst.h" #include "legion.h" #include #include +#ifdef FF_USE_NCCL +#include +#endif #define FatalError(s) \ do { \ @@ -83,11 +87,19 @@ template __global__ void copy_kernel(DT *dst, const DT *src, Legion::coord_t size); template + +__global__ void copy_kernel_discrete(DT *dst, + const DT *src, + Legion::coord_t size, + size_t *index); + __global__ void copy_kernel_with_replicate(DT *dst, const DT *src, Legion::coord_t origin_size, Legion::coord_t size); + + template __global__ void add_kernel(T *data_ptr, T const *grad_ptr, size_t size); @@ -137,18 +149,41 @@ __host__ void updateGAS(float *para_ptr, float learning_rate); template -void print_tensor(T const *ptr, size_t num_elements, char const *prefix); +void print_tensor(T const *ptr, + size_t num_elements, + char const *prefix, + int shard_id = 0); +template +void print_beam_tensor(T const *ptr, + size_t num_elements, + int skip, + int channel, + char const *prefix); + template void save_tensor(T const *ptr, size_t num_elements, char const *file_name); +template +T *download_tensor(T const *ptr, size_t num_elements); + +template +bool download_tensor(T const *ptr, T *dst, size_t num_elements); + cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, - Legion::Domain domain); + Legion::Domain domain, + DataType data_type = DT_FLOAT); + cudnnStatus_t cudnnSetTensorDescriptorFromDomain4SoftMax(cudnnTensorDescriptor_t tensor, Legion::Domain domain, DataType data_type = DT_FLOAT); cudaDataType_t ff_to_cuda_datatype(DataType type); - cudnnDataType_t ff_to_cudnn_datatype(DataType type); -#endif \ No newline at end of file +#ifdef FF_USE_NCCL +ncclDataType_t ff_to_nccl_datatype(DataType type); +#endif + +cudaDataType_t cudnn_to_cuda_datatype(cudnnDataType_t type); +cudnnDataType_t cuda_to_cudnn_datatype(cudaDataType_t type); +#endif diff --git a/include/flexflow/utils/file_loader.h b/include/flexflow/utils/file_loader.h new file mode 100644 index 0000000000..646eb18da2 --- /dev/null +++ b/include/flexflow/utils/file_loader.h @@ -0,0 +1,56 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#pragma once + +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/model.h" + +using namespace std; +using namespace FlexFlow; + +class FileDataLoader { +public: + FileDataLoader(std::string _prompts_filepath, + std::string _weights_folder, + int _num_heads, + int _num_kv_heads, + size_t _hidden_dim, + size_t _qkv_inner_dim, + int _tensor_parallelism_degree, + bool _use_full_precision); + + BatchConfig::TokenId *generate_requests(int num, int length); + + template + void load_single_weight_tensor(FFModel *ff, Layer *l, int weight_idx); + + void load_quantization_weight(FFModel *ff, Layer *l, int weight_idx); + void load_weights(FFModel *ff); + + void load_positions(FFModel *ff, + Tensor pt, + ParallelTensor position_pt, + int max_seq_length, + int offset); + +private: + int num_heads, num_kv_heads, tensor_parallelism_degree; + size_t hidden_dim, qkv_inner_dim; + std::string prompts_filepath; + std::string weights_folder; + bool use_full_precision; +}; diff --git a/include/flexflow/utils/hip_helper.h b/include/flexflow/utils/hip_helper.h index 8c589305c2..3a8716aeb5 100644 --- a/include/flexflow/utils/hip_helper.h +++ b/include/flexflow/utils/hip_helper.h @@ -1,9 +1,13 @@ #ifndef _FLEXFLOW_HIP_HELPER_H_ #define _FLEXFLOW_HIP_HELPER_H_ +#include "flexflow/accessor.h" #include "flexflow/ffconst.h" #include "legion.h" -#include +#include #include +#ifdef FF_USE_NCCL +#include +#endif #define FatalError(s) \ do { \ @@ -139,9 +143,23 @@ __host__ void updateGAS(float *para_ptr, template void print_tensor(T const *ptr, size_t num_elements, char const *prefix); +template +void save_tensor(T const *ptr, size_t num_elements, char const *file_name); + +template +T *download_tensor(T const *ptr, size_t num_elements); + +template +bool download_tensor(T const *ptr, T *dst, size_t num_elements); + miopenStatus_t cudnnSetTensorDescriptorFromDomain(miopenTensorDescriptor_t tensor, - Legion::Domain domain); + Legion::Domain domain, + DataType data_type = DT_FLOAT); + +miopenStatus_t + cudnnSetTensorDescriptorFromDomain4SoftMax(miopenTensorDescriptor_t tensor, + Legion::Domain domain); miopenStatus_t cudnnSetTensorDescriptorFromDomain4SoftMax(miopenTensorDescriptor_t tensor, @@ -150,6 +168,9 @@ miopenStatus_t hipblasDatatype_t ff_to_cuda_datatype(DataType type); miopenDataType_t ff_to_cudnn_datatype(DataType type); +#ifdef FF_USE_NCCL +ncclDataType_t ff_to_nccl_datatype(DataType type); +#endif void handle_unimplemented_hip_kernel(OperatorType op_type); #endif diff --git a/include/flexflow/utils/memory_allocator.h b/include/flexflow/utils/memory_allocator.h new file mode 100644 index 0000000000..8e50a4c3b3 --- /dev/null +++ b/include/flexflow/utils/memory_allocator.h @@ -0,0 +1,67 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#ifndef _FLEXFLOW_UTILS_MEMORY_ALLOCATOR_H_ +#define _FLEXFLOW_UTILS_MEMORY_ALLOCATOR_H_ + +#include "flexflow/config.h" + +namespace FlexFlow { + +class MemoryAllocator { +public: + MemoryAllocator(Legion::Memory memory); + void create_legion_instance(Realm::RegionInstance &inst, size_t size); + void register_reserved_work_space(void *base, size_t size); + inline void *allocate_reserved_untyped(size_t datalen) { + void *ptr = static_cast(reserved_ptr) + reserved_allocated_size; + reserved_allocated_size += datalen; + assert(reserved_allocated_size <= reserved_total_size); + return ptr; + } + template + inline DT *allocate_reserved(size_t count) { + void *ptr = static_cast(reserved_ptr) + reserved_allocated_size; + reserved_allocated_size += sizeof(DT) * count; + assert(reserved_allocated_size <= reserved_total_size); + return static_cast
(ptr); + } + + inline void *allocate_instance_untyped(size_t datalen) { + void *ptr = static_cast(instance_ptr) + instance_allocated_size; + instance_allocated_size += datalen; + assert(instance_allocated_size <= instance_total_size); + return ptr; + } + + template + inline DT *allocate_instance(size_t count) { + void *ptr = static_cast(instance_ptr) + instance_allocated_size; + instance_allocated_size += sizeof(DT) * count; + assert(instance_allocated_size <= instance_total_size); + return static_cast
(ptr); + } + +public: + Legion::Memory memory; + void *reserved_ptr; + void *instance_ptr; + size_t reserved_total_size, reserved_allocated_size; + size_t instance_total_size, instance_allocated_size; +}; + +}; // namespace FlexFlow + +#endif // _FLEXFLOW_RUNTIME_H_ diff --git a/inference/.gitignore b/inference/.gitignore new file mode 100644 index 0000000000..1da34a668b --- /dev/null +++ b/inference/.gitignore @@ -0,0 +1,6 @@ +configs +weights +tokenizers +prompt +output +.env \ No newline at end of file diff --git a/inference/MODEL_WEIGHTS.md b/inference/MODEL_WEIGHTS.md new file mode 100644 index 0000000000..d78fb37be9 --- /dev/null +++ b/inference/MODEL_WEIGHTS.md @@ -0,0 +1,28 @@ +To convert the weights of a HuggingFace LLM to SpecInfer's weight format, we first load the model and modify the tensor names to match SpecInfer's convention, and then convert these tensors to numpy arrays to store them in binary files. + +```python +from transformers import AutoModelForCausalLM +model = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-2-7b-hf") + +for name, params in model.named_parameters(): + for name, params in model.named_parameters(): + name = ( + name.replace(".", "_") + .replace("self_attn", "attention") + .replace("q_proj", "wq") + .replace("k_proj", "wk") + .replace("v_proj", "wv") + .replace("o_proj", "wo") + .replace("mlp", "feed_forward") + .replace("gate_proj", "w1") + .replace("down_proj", "w2") + .replace("up_proj", "w3") + .replace("input_layernorm", "attention_norm") + .replace("post_attention_layernorm", "ffn_norm") + .replace("embed_tokens", "tok_embeddings") + .replace("lm_head", "output") + .replace("model_", "") + ) + params.detach().cpu().numpy().tofile('weights/llama_7B_weights/' + name) +``` + diff --git a/inference/incr_decoding/CMakeLists.txt b/inference/incr_decoding/CMakeLists.txt new file mode 100644 index 0000000000..3e1a1521d7 --- /dev/null +++ b/inference/incr_decoding/CMakeLists.txt @@ -0,0 +1,38 @@ +cmake_minimum_required(VERSION 3.10) + +project(FlexFlow_IncrDecoding) +set(project_target incr_decoding) + + +set(CPU_SRC + ${FLEXFLOW_CPP_DRV_SRC} + incr_decoding.cc + ../models/llama.cc + ../models/opt.cc + ../models/falcon.cc + ../models/starcoder.cc + ../models/mpt.cc) + +if (FF_GPU_BACKEND STREQUAL "cuda" OR FF_GPU_BACKEND STREQUAL "hip_cuda") + cuda_add_executable(${project_target} ${CPU_SRC}) + if (FF_GPU_BACKEND STREQUAL "hip_cuda") + target_compile_definitions(${project_target} PRIVATE __HIP_PLATFORM_NVIDIA__) + endif() +elseif(FF_GPU_BACKEND STREQUAL "hip_rocm") + set_source_files_properties(${CPU_SRC} PROPERTIES LANGUAGE HIP) + hip_add_executable(${project_target} ${CPU_SRC}) + if (FF_HIP_ARCH STREQUAL "") + message(FATAL_ERROR "FF_HIP_ARCH is empty!") + endif() + set_property(TARGET ${project_target} PROPERTY HIP_ARCHITECTURES "${FF_HIP_ARCH}") + target_compile_definitions(${project_target} PRIVATE __HIP_PLATFORM_AMD__) +else() + message(FATAL_ERROR "Compilation of ${project_target} for ${FF_GPU_BACKEND} backend not yet supported") +endif() + +target_include_directories(${project_target} PRIVATE ${FLEXFLOW_INCLUDE_DIRS} ${CMAKE_INSTALL_INCLUDEDIR}) +target_include_directories(${project_target} PRIVATE ${CMAKE_SOURCE_DIR}/inference) +target_link_libraries(${project_target} -Wl,--whole-archive flexflow -Wl,--no-whole-archive ${FLEXFLOW_EXT_LIBRARIES}) + +set(BIN_DEST "bin") +install(TARGETS ${project_target} DESTINATION ${BIN_DEST}) diff --git a/nmt/Makefile b/inference/incr_decoding/Makefile similarity index 54% rename from nmt/Makefile rename to inference/incr_decoding/Makefile index 261da88655..0e4b79f51f 100644 --- a/nmt/Makefile +++ b/inference/incr_decoding/Makefile @@ -13,38 +13,25 @@ # limitations under the License. # -ifndef LG_RT_DIR -$(error LG_RT_DIR variable is not defined, aborting build) -endif - # Flags for directing the runtime makefile what to include DEBUG ?= 0 # Include debugging symbols +MAX_DIM ?= 4 # Maximum number of dimensions OUTPUT_LEVEL ?= LEVEL_DEBUG # Compile time logging level USE_CUDA ?= 1 # Include CUDA support (requires CUDA) -USE_GASNET ?= 1 # Include GASNet support (requires GASNet) -USE_HDF ?= 0 # Include HDF5 support (requires HDF5) +USE_GASNET ?= 0 # Include GASNet support (requires GASNet) +USE_HDF ?= 1 # Include HDF5 support (requires HDF5) ALT_MAPPERS ?= 0 # Include alternative mappers (not recommended) # Put the binary file name here -OUTFILE ?= nmt +OUTFILE ?= llama_pipeline # List all the application source files here -GEN_SRC ?= nmt.cc rnn_mapper.cc # .cc files -GEN_GPU_SRC ?= lstm.cu linear.cu embed.cu rnn.cu softmax_data_parallel.cu ../cnn_helper.cu# .cu files +ifndef CUDA_HOME +CUDA_HOME = $(patsubst %/bin/nvcc,%,$(shell which nvcc | head -1)) +endif -# You can modify these variables, some will be appended to by the runtime makefile -INC_FLAGS ?= -CC_FLAGS ?= -NVCC_FLAGS ?= -GASNET_FLAGS ?= -LD_FLAGS ?= -lcudnn -lcublas -lcurand -# For Point and Rect typedefs -CC_FLAGS += -std=c++11 -NVCC_FLAGS += -std=c++11 -########################################################################### -# -# Don't change anything below here -# -########################################################################### -include $(LG_RT_DIR)/runtime.mk +ifndef FF_HOME +$(error FF_HOME variable is not defined, aborting build) +endif +include $(FF_HOME)/FlexFlow.mk diff --git a/inference/incr_decoding/incr_decoding.cc b/inference/incr_decoding/incr_decoding.cc new file mode 100644 index 0000000000..aae7256ffe --- /dev/null +++ b/inference/incr_decoding/incr_decoding.cc @@ -0,0 +1,293 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include "models/falcon.h" +#include "models/llama.h" +#include "models/mpt.h" +#include "models/opt.h" +#include "models/starcoder.h" +#include + +#include + +using namespace FlexFlow; +using namespace Legion; +using json = nlohmann::json; + +LegionRuntime::Logger::Category log_app("llama"); + +struct FilePaths { + std::string cache_folder_path; + std::string prompt_file_path; + std::string output_file_path; +}; + +void parse_input_args(char **argv, + int argc, + FilePaths &paths, + std::string &llm_model_name, + bool &use_full_precision, + bool &verbose, + bool &do_sample, + float &temperature, + float &topp, + int &max_requests_per_batch, + int &max_tokens_per_batch, + int &max_sequence_length) { + for (int i = 1; i < argc; i++) { + // llm model type + if (!strcmp(argv[i], "-llm-model")) { + llm_model_name = std::string(argv[++i]); + for (char &c : llm_model_name) { + c = std::tolower(c); + } + continue; + } + // cache folder + if (!strcmp(argv[i], "-cache-folder")) { + paths.cache_folder_path = std::string(argv[++i]); + continue; + } + // prompts + if (!strcmp(argv[i], "-prompt")) { + paths.prompt_file_path = std::string(argv[++i]); + continue; + } + // output file + if (!strcmp(argv[i], "-output-file")) { + paths.output_file_path = std::string(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--use-full-precision")) { + use_full_precision = true; + continue; + } + // verbose logging to stdout + if (!strcmp(argv[i], "--verbose")) { + verbose = true; + continue; + } + if (!strcmp(argv[i], "--do-sample")) { + do_sample = true; + continue; + } + if (!strcmp(argv[i], "--temperature")) { + temperature = std::stof(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--topp")) { + topp = std::stof(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--max-requests-per-batch")) { + max_requests_per_batch = std::stoi(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--max-tokens-per-batch")) { + max_tokens_per_batch = std::stoi(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--max-sequence-length")) { + max_sequence_length = std::stoi(argv[++i]); + continue; + } + } + if (paths.cache_folder_path.empty()) { + char const *ff_cache_path = std::getenv("FF_CACHE_PATH"); + paths.cache_folder_path = ff_cache_path ? std::string(ff_cache_path) + : std::string("~/.cache/flexflow"); + } + // Expand ~ to the home directory if needed + wordexp_t p; + wordexp(paths.cache_folder_path.c_str(), &p, 0); + paths.cache_folder_path = p.we_wordv[0]; + wordfree(&p); +} + +void FlexFlow::top_level_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + FFConfig ffconfig; + if (ffconfig.cpu_offload == false && ffconfig.quantization_type != DT_NONE) { + assert(false && "Doesn't support quantization in non-offload mode"); + } + FilePaths file_paths; + std::string llm_model_name; + bool use_full_precision = false; + bool verbose = false; + bool do_sample = false; + float temperature = 0.0f; + float topp = 0.0f; + int max_requests_per_batch = 8; + int max_tokens_per_batch = 128; + int max_sequence_length = 256; + + InputArgs const &command_args = HighLevelRuntime::get_input_args(); + char **argv = command_args.argv; + int argc = command_args.argc; + parse_input_args(argv, + argc, + file_paths, + llm_model_name, + use_full_precision, + verbose, + do_sample, + temperature, + topp, + max_requests_per_batch, + max_tokens_per_batch, + max_sequence_length); + + assert(ffconfig.data_parallelism_degree * ffconfig.tensor_parallelism_degree * + ffconfig.pipeline_parallelism_degree == + ffconfig.numNodes * ffconfig.workersPerNode); + + std::string config_filepath = join_path( + {file_paths.cache_folder_path, "configs", llm_model_name, "config.json"}); + std::string tokenizer_filepath = + join_path({file_paths.cache_folder_path, "tokenizers", llm_model_name}); + std::string weights_filepath = + join_path({file_paths.cache_folder_path, + "weights", + llm_model_name, + use_full_precision ? "full-precision" : "half-precision"}); + std::ifstream config_file_handle(config_filepath); + if (!config_file_handle.good()) { + std::cout << "Model config file " << config_filepath << " not found." + << std::endl; + assert(false); + } + json model_config = json::parse(config_file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + ModelType model_type = ModelType::UNKNOWN; + auto architectures = model_config["architectures"]; + for (auto const &str : architectures) { + if (str == "LlamaForCausalLM" || str == "LLaMAForCausalLM") { + model_type = ModelType::LLAMA; + break; + } else if (str == "OPTForCausalLM") { + model_type = ModelType::OPT; + break; + } else if (str == "RWForCausalLM" || str == "FalconForCausalLM") { + model_type = ModelType::FALCON; + break; + } else if (str == "GPTBigCodeForCausalLM") { + model_type = ModelType::STARCODER; + break; + } else if (str == "MPTForCausalLM") { + model_type = ModelType::MPT; + break; + } + } + int bos_token_id = model_config.find("bos_token_id") == model_config.end() + ? -1 + : (int)model_config.at("bos_token_id"); + int eos_token_id = model_config.find("eos_token_id") == model_config.end() + ? -1 + : (int)model_config.at("eos_token_id"); + + assert(model_type != ModelType::UNKNOWN && + "Invalid LLM model type passed (or no type was passed)."); + + GenerationConfig generationConfig(do_sample, temperature, topp); + RequestManager *rm = RequestManager::get_request_manager(); + rm->set_max_requests_per_batch(max_requests_per_batch); + rm->set_max_tokens_per_batch(max_tokens_per_batch); + rm->set_max_sequence_length(max_sequence_length); + rm->register_tokenizer( + model_type, bos_token_id, eos_token_id, tokenizer_filepath); + rm->register_output_filepath(file_paths.output_file_path); + + FFModel model(ffconfig, ffconfig.cpu_offload); + if (model_type == ModelType::LLAMA) { + LLAMA::create_llama_model(model, + config_filepath, + weights_filepath, + INC_DECODING_MODE, + generationConfig, + use_full_precision); + } else if (model_type == ModelType::OPT) { + OPT::create_opt_model(model, + config_filepath, + weights_filepath, + INC_DECODING_MODE, + use_full_precision); + } else if (model_type == ModelType::FALCON) { + FALCON::create_falcon_model(model, + config_filepath, + weights_filepath, + INC_DECODING_MODE, + use_full_precision); + } else if (model_type == ModelType::STARCODER) { + STARCODER::create_starcoder_model(model, + config_filepath, + weights_filepath, + INC_DECODING_MODE, + generationConfig, + use_full_precision); + } else if (model_type == ModelType::MPT) { + MPT::create_mpt_model(model, + config_filepath, + weights_filepath, + INC_DECODING_MODE, + generationConfig, + use_full_precision); + } else { + assert(false && "unknow model type"); + } + + rm->start_background_server(&model); + + int total_num_requests = 0; + { + using json = nlohmann::json; + std::ifstream file_handle(file_paths.prompt_file_path); + assert(file_handle.good() && "Prompt file does not exist."); + json prompt_json = json::parse(file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + std::vector prompts; + for (auto &prompt : prompt_json) { + std::string text = prompt.get(); + printf("Prompt[%d]: %s\n", total_num_requests, text.c_str()); + total_num_requests++; + prompts.push_back(text); + } + std::vector result = + model.generate(prompts, 128 /*max_sequence_length*/); + } + + // terminate the request manager by stopping the background thread + rm->terminate_background_server(); + + // Execution fence + { + Future future = runtime->issue_execution_fence(ctx); + future.get_void_result(); + } + + // float* data + std::cout << "----------inference finished--------------" << std::endl; + + // free tokenizer space in memory +} + +void FlexFlow::register_custom_tasks() {} diff --git a/inference/models/falcon.cc b/inference/models/falcon.cc new file mode 100644 index 0000000000..a529411ddb --- /dev/null +++ b/inference/models/falcon.cc @@ -0,0 +1,257 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "falcon.h" + +namespace FlexFlow { + +using namespace Legion; +using json = nlohmann::json; + +void FALCON::create_falcon_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + bool use_full_precision) { + FalconConfig falcon_config(model_config_file_path); + falcon_config.print(); + + if (ff.config.tensor_parallelism_degree > falcon_config.n_head || + falcon_config.n_head % ff.config.tensor_parallelism_degree != 0) { + assert(false && "The number of attention heads is smaller, or it is not " + "divisible by the tensor parallelism degree"); + } + + std::unordered_map weights_layers; + + Tensor input; + { + // assert(falcon_config.max_num_tokens <= BatchConfig::MAX_NUM_TOKENS); + int const token_dims[] = { + (mode == TREE_VERIFY_MODE || mode == BEAM_SEARCH_MODE) + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(), + 1}; + input = ff.create_tensor<2>(token_dims, DT_INT32); + } + + std::vector axes = {0}; + + Initializer *embed_init = new UniformInitializer(std::rand(), 0, 0); + Tensor token = ff.embedding(input, + falcon_config.vocab_size, + falcon_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "word_embeddings"); + + Tensor mha = nullptr, mlp_output = nullptr; + Tensor res_ln_outputs[2] = {nullptr, nullptr}; + + for (int i = 0; i < falcon_config.n_layer; i++) { + // set transformer layer id + ff.set_transformer_layer_id(i); + + // step 1: attention + Tensor att_norm = nullptr; + if (i == 0) { + att_norm = ff.layer_norm( + token, + axes, + true, + falcon_config.layer_norm_epsilon, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_input_layernorm") + .c_str()); + } else { + ff.residual_layer_norm( + token, + mha, + mlp_output, + res_ln_outputs, + true, + axes, + true, + falcon_config.layer_norm_epsilon, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_input_layernorm") + .c_str()); + token = res_ln_outputs[0]; + att_norm = res_ln_outputs[1]; + } + + switch (mode) { + case BEAM_SEARCH_MODE: { + mha = ff.spec_inc_multiquery_self_attention( + att_norm, + falcon_config.hidden_size, + falcon_config.n_head, + falcon_config.n_head_kv, + falcon_config.hidden_size / falcon_config.n_head, + falcon_config.hidden_size / falcon_config.n_head, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + NULL, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + + case TREE_VERIFY_MODE: { + mha = ff.inc_multiquery_self_attention_verify( + att_norm, + falcon_config.hidden_size, + falcon_config.n_head, + falcon_config.n_head_kv, + falcon_config.hidden_size / falcon_config.n_head, + falcon_config.hidden_size / falcon_config.n_head, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + nullptr, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + + case INC_DECODING_MODE: { + mha = ff.inc_multiquery_self_attention( + att_norm, + falcon_config.hidden_size, + falcon_config.n_head, + falcon_config.n_head_kv, + falcon_config.hidden_size / falcon_config.n_head, + falcon_config.hidden_size / falcon_config.n_head, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + nullptr, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + default: { + assert(false); + } + } + + Tensor dense_h_to_4h = ff.dense( + att_norm, + falcon_config.hidden_size * 4, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_mlp_dense_h_to_4h") + .c_str()); + + dense_h_to_4h = ff.gelu(dense_h_to_4h); + + mlp_output = ff.dense( + dense_h_to_4h, + falcon_config.hidden_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_mlp_dense_4h_to_h") + .c_str()); + } + // final normalization and linear + ff.residual_layer_norm(token, + mha, + mlp_output, + res_ln_outputs, + true, + axes, + true, + falcon_config.layer_norm_epsilon, + true, + DT_NONE, + "ln_f"); + Tensor ln_f = res_ln_outputs[1]; + + Tensor lm_head = ff.dense(ln_f, + falcon_config.vocab_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + "lm_head"); + + Tensor output; + if (mode == BEAM_SEARCH_MODE) { + Tensor softmax = ff.softmax(lm_head, -1); + output = ff.argmax(softmax, /*beam_Search*/ true); + } else { + output = ff.argmax(lm_head, /*beam_Search*/ false); + } + + FileDataLoader *fileloader = + new FileDataLoader("", + weight_file_path, + falcon_config.n_head, + falcon_config.n_head_kv, + falcon_config.hidden_size, + falcon_config.hidden_size / falcon_config.n_head, + ff.config.tensor_parallelism_degree, + use_full_precision); + + InferenceManager *im = InferenceManager::get_inference_manager(); + im->register_model_weights_loader(&ff, fileloader); +} + +}; // namespace FlexFlow diff --git a/inference/models/falcon.h b/inference/models/falcon.h new file mode 100644 index 0000000000..fce2dade3f --- /dev/null +++ b/inference/models/falcon.h @@ -0,0 +1,100 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#pragma once + +// #include "file_loader.h" +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include +#include +using json = nlohmann::json; + +namespace FlexFlow { + +class FALCON { +public: + struct FalconConfig { + FalconConfig(std::string const &model_config_file_path) { + std::ifstream config_file(model_config_file_path); + if (config_file.is_open()) { + try { + json model_config; + config_file >> model_config; + bias = model_config["bias"]; + hidden_size = model_config["hidden_size"]; + layer_norm_epsilon = model_config["layer_norm_epsilon"]; + multi_query = model_config["multi_query"]; + n_head = (model_config.find("n_head") != model_config.end()) + ? model_config["n_head"] + : model_config["num_attention_heads"]; + if (model_config.contains("n_head_kv")) { + n_head_kv = model_config["n_head_kv"]; + } else { + n_head_kv = 1; + } + n_layer = (model_config.find("n_layer") != model_config.end()) + ? model_config["n_layer"] + : model_config["num_hidden_layers"]; + parallel_attn = model_config["parallel_attn"]; + vocab_size = model_config["vocab_size"]; + } catch (json::exception const &e) { + std::cerr << "Error parsing JSON file: " << e.what() << std::endl; + assert(false); + } + } else { + std::cerr << "Error opening JSON file " << model_config_file_path + << std::endl; + assert(false); + } + // max_seq_len = BatchConfig::MAX_SEQ_LENGTH; + // max_num_tokens = BatchConfig::MAX_NUM_TOKENS; + max_beam_width = BeamSearchBatchConfig::MAX_BEAM_WIDTH; + max_beam_depth = BeamSearchBatchConfig::MAX_BEAM_DEPTH; + } + + void print() const { + std::cout << "Falcon Config:" << std::endl; + std::cout << "\tbias: " << bias << std::endl; + std::cout << "\thidden_size: " << hidden_size << std::endl; + std::cout << "\tlayer_norm_epsilon: " << layer_norm_epsilon << std::endl; + std::cout << "\tmulti_query: " << multi_query << std::endl; + std::cout << "\tn_head: " << n_head << std::endl; + std::cout << "\tn_head_kv: " << n_head << std::endl; + std::cout << "\tn_layer: " << n_layer << std::endl; + std::cout << "\tparallel_attn: " << parallel_attn << std::endl; + std::cout << "\tvocab_size: " << vocab_size << std::endl; + + // std::cout << "\tmax_seq_len: " << max_seq_len << std::endl; + // std::cout << "\tmax_num_tokens: " << max_num_tokens << std::endl; + std::cout << "\tmax_beam_width: " << max_beam_width << std::endl; + std::cout << "\tmax_beam_depth: " << max_beam_depth << std::endl; + } + + bool bias, multi_query, parallel_attn; + int hidden_size, n_head, n_head_kv, n_layer, vocab_size; + float layer_norm_epsilon; + // int max_seq_len, max_num_tokens; + int max_beam_width, max_beam_depth; + }; + + static void create_falcon_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + bool use_full_precision = false); +}; + +}; // namespace FlexFlow diff --git a/inference/models/llama.cc b/inference/models/llama.cc new file mode 100644 index 0000000000..517f534438 --- /dev/null +++ b/inference/models/llama.cc @@ -0,0 +1,282 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "llama.h" + +namespace FlexFlow { + +using namespace Legion; +using json = nlohmann::json; + +void LLAMA::create_llama_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generation_config, + bool use_full_precision) { + // do not apply cpu offload in beam search model. + LLAMAConfig llama_config(model_config_file_path); + llama_config.print(); + + if (ff.config.tensor_parallelism_degree > llama_config.num_attention_heads || + llama_config.num_attention_heads % ff.config.tensor_parallelism_degree != + 0) { + assert(false && "The number of attention heads is smaller, or it is not " + "divisible by the tensor parallelism degree"); + } + + std::unordered_map weights_layers; + + Tensor input; + { + int const token_dims[] = { + (mode == TREE_VERIFY_MODE || mode == BEAM_SEARCH_MODE) + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(), + 1}; + input = ff.create_tensor<2>(token_dims, DT_INT32); + } + + Initializer *embed_init = new UniformInitializer(std::rand(), 0, 0); + + Tensor token = ff.embedding(input, + llama_config.vocab_size, + llama_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "tok_embeddings"); + + Tensor w2 = nullptr; + + for (int i = 0; i < llama_config.num_hidden_layers; i++) { + // set transformer layer id + ff.set_transformer_layer_id(i); + + // step 1: attention + Tensor att_norm = nullptr; + Tensor token_att_norm[2] = {nullptr, nullptr}; + if (i == 0) { + att_norm = ff.rms_norm( + token, + llama_config.rms_norm_eps, + llama_config.hidden_size, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_attention_norm") + .c_str()); + } else { + ff.residual_rms_norm( + token, + w2, + token_att_norm, + llama_config.rms_norm_eps, + llama_config.hidden_size, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_attention_norm") + .c_str()); + token = token_att_norm[0]; + att_norm = token_att_norm[1]; + } + + Tensor mha; + switch (mode) { + case BEAM_SEARCH_MODE: { + mha = ff.spec_inc_multihead_self_attention( + att_norm, + llama_config.hidden_size, + llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + NULL, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case TREE_VERIFY_MODE: { + mha = ff.inc_multihead_self_attention_verify( + att_norm, + llama_config.hidden_size, + llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + nullptr, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case INC_DECODING_MODE: { + mha = ff.inc_multihead_self_attention( + att_norm, + llama_config.hidden_size, + llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + llama_config.hidden_size / llama_config.num_attention_heads, + 0.0f, /*dropout*/ + false, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + nullptr, /*kernel_initializer*/ + true, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + default: { + assert(false); + } + } + + // step 2: SILU activaion + Tensor token_ff_norm[2] = {nullptr, nullptr}; + ff.residual_rms_norm( + token, + mha, + token_ff_norm, + llama_config.rms_norm_eps, + llama_config.hidden_size, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_ffn_norm").c_str()); + token = token_ff_norm[0]; + Tensor ff_norm = token_ff_norm[1]; + + Tensor w1 = + ff.dense(ff_norm, + llama_config.intermediate_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_feed_forward_w1") + .c_str()); + + Tensor w3 = + ff.dense(ff_norm, + llama_config.intermediate_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_feed_forward_w3") + .c_str()); + + Tensor multi = ff.sigmoid_silu_multi(w1, w3); + + w2 = + ff.dense(multi, + llama_config.hidden_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_feed_forward_w2") + .c_str()); + } + // final normalization and linear + Tensor final_rms_norm_output[2] = {nullptr, nullptr}; + ff.residual_rms_norm(token, + w2, + final_rms_norm_output, + llama_config.rms_norm_eps, + llama_config.hidden_size, + DT_NONE, + "norm"); + + Tensor dense = ff.dense(final_rms_norm_output[1], + llama_config.vocab_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + "output"); + + Tensor output; + if (mode == BEAM_SEARCH_MODE) { + Tensor softmax = ff.softmax(dense, -1); + // output = ff.beam_top_k(softmax, llama_config.max_beam_width, false); + // output = ff.argmax(softmax, /*beam_Search*/ true); + output = ff.arg_top_k(softmax, llama_config.max_beam_width, false, true); + // output = ff.top_k(softmax, ) + } else { + // Tensor softmax = ff.softmax(dense, -1); + if (generation_config.do_sample) { + dense = ff.scalar_truediv(dense, generation_config.temperature, false); + Tensor softmax = ff.softmax(dense, -1); + output = ff.sampling(softmax, generation_config.topp); + } else { + // output = ff.arg_top_k(dense, /*k=*/1, false); + output = ff.argmax(dense, /*beam_Search*/ false); + } + } + + FileDataLoader *fileloader = new FileDataLoader( + "", + weight_file_path, + llama_config.num_attention_heads, + llama_config.num_attention_heads, + llama_config.hidden_size, + llama_config.hidden_size / llama_config.num_attention_heads, + ff.config.tensor_parallelism_degree, + use_full_precision); + + InferenceManager *im = InferenceManager::get_inference_manager(); + im->register_model_weights_loader(&ff, fileloader); +} + +}; // namespace FlexFlow diff --git a/inference/models/llama.h b/inference/models/llama.h new file mode 100644 index 0000000000..ba1f0236f9 --- /dev/null +++ b/inference/models/llama.h @@ -0,0 +1,89 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#pragma once + +// #include "file_loader.h" +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include +#include +using json = nlohmann::json; + +namespace FlexFlow { + +class LLAMA { +public: + struct LLAMAConfig { + LLAMAConfig(std::string const &model_config_file_path) { + std::ifstream config_file(model_config_file_path); + if (config_file.is_open()) { + try { + json model_config; + config_file >> model_config; + num_hidden_layers = model_config["num_hidden_layers"]; + vocab_size = model_config["vocab_size"]; + num_attention_heads = model_config["num_attention_heads"]; + hidden_size = model_config["hidden_size"]; + rms_norm_eps = model_config["rms_norm_eps"]; + intermediate_size = model_config["intermediate_size"]; + } catch (json::exception const &e) { + std::cerr << "Error parsing LLAMA config from JSON file: " << e.what() + << std::endl; + assert(false); + } + } else { + std::cerr << "Error opening JSON file " << model_config_file_path + << std::endl; + assert(false); + } + // max_seq_len = BatchConfig::MAX_SEQ_LENGTH; + // max_num_tokens = BatchConfig::MAX_NUM_TOKENS; + max_beam_width = BeamSearchBatchConfig::MAX_BEAM_WIDTH; + max_beam_depth = BeamSearchBatchConfig::MAX_BEAM_DEPTH; + } + + void print() const { + std::cout << "LLAMA Config:" << std::endl; + std::cout << "\tnum_hidden_layers: " << num_hidden_layers << std::endl; + std::cout << "\tvocab_size: " << vocab_size << std::endl; + std::cout << "\tnum_attention_heads: " << num_attention_heads + << std::endl; + std::cout << "\thidden_size: " << hidden_size << std::endl; + std::cout << "\trms_norm_eps: " << rms_norm_eps << std::endl; + std::cout << "\tintermediate_size: " << intermediate_size << std::endl; + + // std::cout << "\tmax_seq_len: " << max_seq_len << std::endl; + // std::cout << "\tmax_num_tokens: " << max_num_tokens << std::endl; + std::cout << "\tmax_beam_width: " << max_beam_width << std::endl; + std::cout << "\tmax_beam_depth: " << max_beam_depth << std::endl; + } + + // int max_seq_len, max_num_tokens; + int max_beam_width, max_beam_depth; + int num_hidden_layers, vocab_size, num_attention_heads, hidden_size, + intermediate_size; + float rms_norm_eps; + }; + + static void create_llama_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generation_config, + bool use_full_precision = false); +}; + +}; // namespace FlexFlow diff --git a/inference/models/mpt.cc b/inference/models/mpt.cc new file mode 100644 index 0000000000..70e2b5e9c5 --- /dev/null +++ b/inference/models/mpt.cc @@ -0,0 +1,264 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "mpt.h" + +namespace FlexFlow { + +using namespace Legion; +using json = nlohmann::json; + +void MPT::create_mpt_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generationConfig, + bool use_full_precision) { + MPTConfig mpt_config(model_config_file_path); + mpt_config.print(); + + if (ff.config.tensor_parallelism_degree > mpt_config.n_heads || + mpt_config.n_heads % ff.config.tensor_parallelism_degree != 0) { + assert(false && "The number of attention heads is smaller, or it is not " + "divisible by the tensor parallelism degree"); + } + + std::unordered_map weights_layers; + + //------------------------------ build the model -------------------------- + Tensor input; + { + int const token_dims[] = { + (mode == TREE_VERIFY_MODE || mode == BEAM_SEARCH_MODE) + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(), + 1}; + input = ff.create_tensor<2>(token_dims, DT_INT32); + } + + Initializer *embed_init = new UniformInitializer(std::rand(), 0, 0); + std::vector axes = {0}; + + Tensor hidden_states = ff.embedding(input, + mpt_config.vocab_size, + mpt_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "transformer_wte"); + + Tensor intermediate_output = nullptr, layernorm_output = nullptr; + Tensor res_ln_outputs[2] = {nullptr, nullptr}; + + for (int i = 0; i < mpt_config.n_layers; i++) { + ff.set_transformer_layer_id(i); + + if (i == 0) { + layernorm_output = ff.layer_norm( + hidden_states, + axes, + true, + 1e-05, + false, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_norm_1").c_str()); + } else { + ff.residual_layer_norm( + intermediate_output, + hidden_states, + nullptr, + res_ln_outputs, + false, + axes, + true, + 1e-05, + false, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_norm_1").c_str()); + hidden_states = res_ln_outputs[0]; + layernorm_output = res_ln_outputs[1]; + } + + Tensor attn_outputs; + switch (mode) { + case BEAM_SEARCH_MODE: { + attn_outputs = ff.spec_inc_multihead_self_attention( + layernorm_output, + mpt_config.hidden_size, + mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + 0.0f, + false, + false, + false, + DT_NONE, /*data_type*/ + NULL, + false, + /*scaling query*/ true, + /*scaling factor*/ + pow((mpt_config.hidden_size / mpt_config.n_heads), -0.5), + /*qk_prod_scaling*/ false, + /*position_bias*/ true, + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case TREE_VERIFY_MODE: { + attn_outputs = ff.inc_multihead_self_attention_verify( + layernorm_output, + mpt_config.hidden_size, + mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + 0.0f, + false, + false, + false, + DT_NONE, /*data_type*/ + NULL, + false, + /*scaling query*/ true, + /*scaling factor*/ + pow((mpt_config.hidden_size / mpt_config.n_heads), -0.5), + /*qk_prod_scaling*/ false, + /*position_bias*/ true, + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case INC_DECODING_MODE: { + attn_outputs = ff.inc_multihead_self_attention( + layernorm_output, + mpt_config.hidden_size, + mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + mpt_config.hidden_size / mpt_config.n_heads, + 0.0f, + false, + false, + false, + DT_NONE, /*data_type*/ + NULL, + false, + /*scaling query*/ true, + /*scaling factor*/ + pow((mpt_config.hidden_size / mpt_config.n_heads), -0.5), + /*qk_prod_scaling*/ false, + /*position_bias*/ true, + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + default: { + assert(false); + } + } + + ff.residual_layer_norm( + attn_outputs, + hidden_states, + nullptr, + res_ln_outputs, + false, + axes, + true, + 1e-05, + false, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_norm_2").c_str()); + hidden_states = res_ln_outputs[0]; + layernorm_output = res_ln_outputs[1]; + + // MLP + layernorm_output = ff.dense( + layernorm_output, + 4 * mpt_config.hidden_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_ffn_up_proj").c_str()); + layernorm_output = ff.gelu(layernorm_output); + intermediate_output = ff.dense( + layernorm_output, + mpt_config.hidden_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_ffn_down_proj").c_str()); + } + + // final + ff.residual_layer_norm(intermediate_output, + hidden_states, + nullptr, + res_ln_outputs, + false, + axes, + true, + 1e-05, + false, + DT_NONE, + "transformer_norm_f"); + Tensor all_final_norm = res_ln_outputs[1]; + + Tensor lm_head = ff.dense(all_final_norm, + mpt_config.vocab_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + "lm_head"); + + Tensor output; + if (mode == BEAM_SEARCH_MODE) { + Tensor softmax = ff.softmax(lm_head, -1); + output = ff.argmax(softmax, /*beam_Search*/ true); + } else { + output = ff.argmax(lm_head, /*beam_Search*/ false); + } + FileDataLoader *fileloader = + new FileDataLoader("", + weight_file_path, + mpt_config.n_heads, + mpt_config.n_heads, + mpt_config.hidden_size, + mpt_config.hidden_size / mpt_config.n_heads, + ff.config.tensor_parallelism_degree, + use_full_precision); + + InferenceManager *im = InferenceManager::get_inference_manager(); + im->register_model_weights_loader(&ff, fileloader); +} + +}; // namespace FlexFlow diff --git a/inference/models/mpt.h b/inference/models/mpt.h new file mode 100644 index 0000000000..08597e1d75 --- /dev/null +++ b/inference/models/mpt.h @@ -0,0 +1,76 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#pragma once + +// #include "file_loader.h" +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include +#include +using json = nlohmann::json; + +namespace FlexFlow { + +class MPT { +public: + struct MPTConfig { + MPTConfig(std::string const &model_config_file_path) { + std::ifstream config_file(model_config_file_path); + if (config_file.is_open()) { + try { + json model_config; + config_file >> model_config; + hidden_size = model_config["d_model"]; + n_heads = model_config["n_heads"]; + n_layers = model_config["n_layers"]; + vocab_size = model_config["vocab_size"]; + } catch (json::exception const &e) { + std::cerr << "Error parsing JSON file: " << e.what() << std::endl; + assert(false); + } + } else { + std::cerr << "Error opening JSON file " << model_config_file_path + << std::endl; + assert(false); + } + // max_seq_len = BatchConfig::MAX_SEQ_LENGTH; + // max_num_tokens = BatchConfig::MAX_NUM_TOKENS; + max_beam_width = BeamSearchBatchConfig::MAX_BEAM_WIDTH; + max_beam_depth = BeamSearchBatchConfig::MAX_BEAM_DEPTH; + } + + void print() const { + std::cout << "MPT Config:" << std::endl; + std::cout << "\thidden_size: " << hidden_size << std::endl; + std::cout << "\tn_heads: " << n_heads << std::endl; + std::cout << "\tn_layers: " << n_layers << std::endl; + std::cout << "\tvocab_size: " << vocab_size << std::endl; + } + + // int max_seq_len, max_num_tokens; + int max_beam_width, max_beam_depth; + int hidden_size, n_heads, n_layers, vocab_size; + }; + + static void create_mpt_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generationConfig, + bool use_full_precision = false); +}; + +}; // namespace FlexFlow diff --git a/inference/models/opt.cc b/inference/models/opt.cc new file mode 100644 index 0000000000..5677d5658e --- /dev/null +++ b/inference/models/opt.cc @@ -0,0 +1,271 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "opt.h" + +namespace FlexFlow { + +using namespace Legion; +using json = nlohmann::json; + +void OPT::create_opt_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + bool use_full_precision) { + OPTConfig opt_config(model_config_file_path); + opt_config.print(); + + if (ff.config.tensor_parallelism_degree > opt_config.num_attention_heads || + opt_config.num_attention_heads % ff.config.tensor_parallelism_degree != + 0) { + assert(false && "The number of attention heads is smaller, or it is not " + "divisible by the tensor parallelism degree"); + } + + std::unordered_map weights_layers; + + //------------------------------ build the model -------------------------- + Tensor input; + Tensor position_input; + ff.set_position_offset(2); + { + int const token_dims[] = { + (mode == TREE_VERIFY_MODE || mode == BEAM_SEARCH_MODE) + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(), + 1}; + input = ff.create_tensor<2>(token_dims, DT_INT32); + position_input = ff.create_tensor<2>(token_dims, DT_INT32); + } + + Initializer *embed_init = new UniformInitializer(std::rand(), 0, 0); + std::vector axes = {0}; + + Tensor token = ff.embedding(input, + opt_config.vocab_size, + opt_config.word_embed_proj_dim, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "embed_tokens"); + + Tensor positional_embedding = + ff.embedding(position_input, + opt_config.max_position_embeddings, + opt_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "embed_positions"); + + Tensor fc2 = nullptr, added = nullptr; + Tensor res_ln_outputs[2] = {nullptr, nullptr}; + + for (int i = 0; i < opt_config.num_hidden_layers; i++) { + // set transformer layer id + ff.set_transformer_layer_id(i); + + // 125m, 1.7B, ..., 175B applies layer norm BEFORE attention, + // 350m applies layer norm AFTER attention + // https://github.com/huggingface/transformers/blob/main/src/transformers/models/opt/modeling_opt.py#LL324C1-L325C1 + // this version is before normalization + ff.residual_layer_norm( + (i == 0) ? token : added, + (i == 0) ? positional_embedding : fc2, + nullptr, + res_ln_outputs, + false, + axes, + opt_config.layer_norm_elementwise_affine, + 1e-05, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_attention_layer_norm") + .c_str()); + Tensor residual = res_ln_outputs[0]; + Tensor hidden_states = res_ln_outputs[1]; + + Tensor mha; + switch (mode) { + case BEAM_SEARCH_MODE: { + mha = ff.spec_inc_multihead_self_attention( + hidden_states, + opt_config.hidden_size, + opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + 0.0f, /*dropout*/ + true, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + NULL, /*kernel_initializer*/ + false, /*apply_rotary_embedding*/ + true, /*scaling query*/ + pow((opt_config.hidden_size / opt_config.num_attention_heads), + -0.5), /*scaling factor*/ + false, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case TREE_VERIFY_MODE: { + mha = ff.inc_multihead_self_attention_verify( + hidden_states, + opt_config.hidden_size, + opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + 0.0f, /*dropout*/ + true, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + NULL, /*kernel_initializer*/ + false, /*apply_rotary_embedding*/ + true, /*scaling query*/ + pow((opt_config.hidden_size / opt_config.num_attention_heads), + -0.5), /*scaling factor*/ + false, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + case INC_DECODING_MODE: { + mha = ff.inc_multihead_self_attention( + hidden_states, + opt_config.hidden_size, + opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + opt_config.hidden_size / opt_config.num_attention_heads, + 0.0f, /*dropout*/ + true, /*qkv_bias*/ + false, /*final_bias*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + NULL, /*kernel_initializer*/ + false, /*apply_rotary_embedding*/ + true, /*scaling query*/ + pow((opt_config.hidden_size / opt_config.num_attention_heads), + -0.5), /*scaling factor*/ + false, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + default: { + assert(false); + } + } + + ff.add_bias_residual_layer_norm(mha, + residual, + res_ln_outputs, + axes, + opt_config.layer_norm_elementwise_affine, + 1e-05, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + + "_add_bias_residual_layer_norm") + .c_str()); + added = res_ln_outputs[0]; + Tensor final_norm = res_ln_outputs[1]; + + //--------linear fc1 fc2 ---------- + Tensor fc1 = + ff.dense(final_norm, + opt_config.ffn_dim, + AC_MODE_RELU, + true, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_fc1").c_str()); + fc2 = ff.dense(fc1, + opt_config.hidden_size, + AC_MODE_NONE, + true, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_fc2").c_str()); + } + + // final + ff.residual_layer_norm(added, + fc2, + nullptr, + res_ln_outputs, + false, + axes, + opt_config.layer_norm_elementwise_affine, + 1e-05, + true, + DT_NONE, + "final_layer_norm"); + Tensor all_final_norm = res_ln_outputs[1]; + + Tensor lm_head = ff.dense(all_final_norm, + opt_config.vocab_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + "embed_tokens_weight_lm_head"); + + Tensor output; + if (mode == BEAM_SEARCH_MODE) { + Tensor softmax = ff.softmax(lm_head, -1); + // output = ff.beam_top_k(softmax, opt_config.max_beam_width, false); + output = ff.argmax(softmax, /*beam_Search*/ true); + } else { + // output = ff.arg_top_k(lm_head, /*k=*/1, false); + output = ff.argmax(lm_head, /*beam_Search*/ false); + } + + FileDataLoader *fileloader = new FileDataLoader( + "", + weight_file_path, + opt_config.num_attention_heads, + opt_config.num_attention_heads, + opt_config.hidden_size, + opt_config.hidden_size / opt_config.num_attention_heads, + ff.config.tensor_parallelism_degree, + use_full_precision); + InferenceManager *im = InferenceManager::get_inference_manager(); + im->register_model_weights_loader(&ff, fileloader); +} + +}; // namespace FlexFlow diff --git a/inference/models/opt.h b/inference/models/opt.h new file mode 100644 index 0000000000..7c736a26d1 --- /dev/null +++ b/inference/models/opt.h @@ -0,0 +1,103 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#pragma once + +// #include "file_loader.h" +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include +#include +using json = nlohmann::json; + +namespace FlexFlow { + +class OPT { +public: + struct OPTConfig { + OPTConfig(std::string const &model_config_file_path) { + std::ifstream config_file(model_config_file_path); + if (config_file.is_open()) { + try { + json model_config; + config_file >> model_config; + do_layer_norm_before = model_config["do_layer_norm_before"]; + dropout = model_config["dropout"]; + enable_bias = model_config["enable_bias"]; + ffn_dim = model_config["ffn_dim"]; + hidden_size = model_config["hidden_size"]; + layer_norm_elementwise_affine = + model_config["layer_norm_elementwise_affine"]; + max_position_embeddings = model_config["max_position_embeddings"]; + num_attention_heads = model_config["num_attention_heads"]; + num_hidden_layers = model_config["num_hidden_layers"]; + vocab_size = model_config["vocab_size"]; + word_embed_proj_dim = model_config["word_embed_proj_dim"]; + } catch (json::exception const &e) { + std::cerr << "Error parsing JSON file: " << e.what() << std::endl; + assert(false); + } + } else { + std::cerr << "Error opening JSON file " << model_config_file_path + << std::endl; + assert(false); + } + // max_seq_len = BatchConfig::MAX_SEQ_LENGTH; + // max_num_tokens = BatchConfig::MAX_NUM_TOKENS; + max_beam_width = BeamSearchBatchConfig::MAX_BEAM_WIDTH; + max_beam_depth = BeamSearchBatchConfig::MAX_BEAM_DEPTH; + } + + void print() const { + std::cout << "OPT Config:" << std::endl; + std::cout << "\tdo_layer_norm_before: " << do_layer_norm_before + << std::endl; + std::cout << "\tdropout: " << dropout << std::endl; + std::cout << "\tenable_bias: " << enable_bias << std::endl; + std::cout << "\tffn_dim: " << ffn_dim << std::endl; + std::cout << "\thidden_size: " << hidden_size << std::endl; + std::cout << "\tlayer_norm_elementwise_affine: " + << layer_norm_elementwise_affine << std::endl; + std::cout << "\tmax_position_embeddings: " << max_position_embeddings + << std::endl; + std::cout << "\tnum_attention_heads: " << num_attention_heads + << std::endl; + std::cout << "\tnum_hidden_layers: " << num_hidden_layers << std::endl; + std::cout << "\tvocab_size: " << vocab_size << std::endl; + std::cout << "\tword_embed_proj_dim: " << word_embed_proj_dim + << std::endl; + + // std::cout << "\tmax_seq_len: " << max_seq_len << std::endl; + // std::cout << "\tmax_num_tokens: " << max_num_tokens << std::endl; + std::cout << "\tmax_beam_width: " << max_beam_width << std::endl; + std::cout << "\tmax_beam_depth: " << max_beam_depth << std::endl; + } + + // int max_seq_len, max_num_tokens; + int max_beam_width, max_beam_depth; + bool do_layer_norm_before, enable_bias, layer_norm_elementwise_affine; + float dropout; + int ffn_dim, hidden_size, max_position_embeddings, num_attention_heads, + num_hidden_layers, vocab_size, word_embed_proj_dim; + }; + + static void create_opt_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + bool use_full_precision = false); +}; + +}; // namespace FlexFlow diff --git a/inference/models/starcoder.cc b/inference/models/starcoder.cc new file mode 100644 index 0000000000..8b0dc1098c --- /dev/null +++ b/inference/models/starcoder.cc @@ -0,0 +1,237 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "starcoder.h" + +namespace FlexFlow { + +using namespace Legion; +using json = nlohmann::json; + +void STARCODER::create_starcoder_model( + FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generationConfig, + bool use_full_precision) { + // do not apply cpu offload in beam search model. + STARCODERConfig startcoder_config(model_config_file_path); + startcoder_config.print(); + + if (ff.config.tensor_parallelism_degree > + startcoder_config.num_attention_heads || + startcoder_config.num_attention_heads % + ff.config.tensor_parallelism_degree != + 0) { + assert(false && "The number of attention heads is smaller, or it is not " + "divisible by the tensor parallelism degree"); + } + + std::unordered_map weights_layers; + std::vector axes = {0}; + + Tensor input; + Tensor position_input; + ff.set_position_offset(0); + { + // assert(startcoder_config.max_num_tokens <= BatchConfig::MAX_NUM_TOKENS); + int const token_dims[] = { + (mode == TREE_VERIFY_MODE || mode == BEAM_SEARCH_MODE) + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(), + 1}; + input = ff.create_tensor<2>(token_dims, DT_INT32); + position_input = ff.create_tensor<2>(token_dims, DT_INT32); + } + + Initializer *embed_init = new UniformInitializer(std::rand(), 0, 0); + + Tensor token = ff.embedding(input, + startcoder_config.vocab_size, + startcoder_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "transformer_wte"); + + Tensor positional_embedding = + ff.embedding(position_input, + startcoder_config.max_position_embeddings, + startcoder_config.hidden_size, + AGGR_MODE_NONE, + use_full_precision ? DT_FLOAT : DT_HALF, + NULL, + embed_init, + "transformer_wpe"); + + Tensor residual = nullptr, c_proj = nullptr; + Tensor res_ln_outputs[2] = {nullptr, nullptr}; + + for (int i = 0; i < startcoder_config.num_hidden_layers; i++) { + // set transformer layer id + ff.set_transformer_layer_id(i); + + // step 1: attention + ff.residual_layer_norm( + (i == 0) ? token : residual, + (i == 0) ? positional_embedding : c_proj, + nullptr, + res_ln_outputs, + false, + axes, + true, + startcoder_config.layer_norm_epsilon, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_ln_1").c_str()); + Tensor hidden_states = res_ln_outputs[0]; + Tensor ln_1 = res_ln_outputs[1]; + + Tensor mha; + switch (mode) { + case INC_DECODING_MODE: { + mha = ff.inc_multiquery_self_attention( + ln_1, + startcoder_config.hidden_size, + startcoder_config.num_attention_heads, + 1, + startcoder_config.hidden_size / + startcoder_config.num_attention_heads, + startcoder_config.hidden_size / + startcoder_config.num_attention_heads, + startcoder_config.dropout_p, /*dropout*/ + true, /*bias*/ + false, /*add_bias_kv*/ + false, /*add_zero_attn*/ + DT_NONE, /*data_type*/ + nullptr, /*kernel_initializer*/ + false, /*apply_rotary_embedding*/ + false, /*scaling query*/ + 1.0f, /*scaling factor*/ + true, /*qk_prod_scaling*/ + false, /*position_bias*/ + std::string("layers_" + std::to_string(i) + "_attention") + .c_str() /*name*/ + ); + break; + } + default: { + assert(false); + } + } + + ff.residual_layer_norm( + hidden_states, + mha, + nullptr, + res_ln_outputs, + false, + axes, + true, + startcoder_config.layer_norm_epsilon, + true, + DT_NONE, + std::string("layers_" + std::to_string(i) + "_ln_2").c_str()); + residual = res_ln_outputs[0]; + Tensor l2_norm = res_ln_outputs[1]; + + // mlp + Tensor c_fc = ff.dense( + l2_norm, + startcoder_config.intermediate_size, + AC_MODE_NONE, + true, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_mlp_c_fc").c_str()); + + c_fc = ff.gelu(c_fc); + + c_proj = ff.dense( + c_fc, + startcoder_config.hidden_size, + AC_MODE_NONE, + true, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + std::string("layers_" + std::to_string(i) + "_mlp_c_proj").c_str()); + } + // final normalization and linear + ff.residual_layer_norm(residual, + c_proj, + nullptr, + res_ln_outputs, + false, + axes, + true, + startcoder_config.layer_norm_epsilon, + true, + DT_NONE, + "transformer_ln_f"); + Tensor ln_f = res_ln_outputs[1]; + + Tensor lm_head = ff.dense(ln_f, + startcoder_config.vocab_size, + AC_MODE_NONE, + false, + DT_NONE, + nullptr, + nullptr, + nullptr, + REG_MODE_NONE, + 0.0f, + "lm_head"); + + Tensor output; + if (mode == BEAM_SEARCH_MODE) { + Tensor softmax = ff.softmax(lm_head, -1); + // output = ff.beam_top_k(softmax, startcoder_config.max_beam_width, false); + output = ff.argmax(softmax, /*beam_Search*/ true); + } else { + // Tensor softmax = ff.softmax(dense, -1); + if (generationConfig.do_sample) { + lm_head = ff.scalar_truediv(lm_head, generationConfig.temperature, false); + Tensor softmax = ff.softmax(lm_head, -1); + output = ff.sampling(softmax, generationConfig.topp); + } else { + // output = ff.arg_top_k(lm_head, /*k=*/1, false); + output = ff.argmax(lm_head, /*beam_Search*/ false); + } + } + + InferenceManager *im = InferenceManager::get_inference_manager(); + FileDataLoader *fileloader = new FileDataLoader( + "", + weight_file_path, + startcoder_config.num_attention_heads, + 1, + startcoder_config.hidden_size, + startcoder_config.hidden_size / startcoder_config.num_attention_heads, + ff.config.tensor_parallelism_degree, + use_full_precision); + im->register_model_weights_loader(&ff, fileloader); +} + +}; // namespace FlexFlow diff --git a/inference/models/starcoder.h b/inference/models/starcoder.h new file mode 100644 index 0000000000..0e9577d569 --- /dev/null +++ b/inference/models/starcoder.h @@ -0,0 +1,77 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#pragma once + +// #include "file_loader.h" +#include "flexflow/batch_config.h" +#include "flexflow/inference.h" +#include "flexflow/request_manager.h" +#include +#include +using json = nlohmann::json; + +namespace FlexFlow { + +class STARCODER { +public: + struct STARCODERConfig { + STARCODERConfig(std::string const &model_config_file_path) { + std::ifstream config_file(model_config_file_path); + if (config_file.is_open()) { + try { + json model_config; + config_file >> model_config; + num_hidden_layers = model_config["n_layer"]; + vocab_size = model_config["vocab_size"]; + num_attention_heads = model_config["n_head"]; + hidden_size = model_config["n_embd"]; + layer_norm_epsilon = model_config["layer_norm_epsilon"]; + intermediate_size = model_config["n_inner"]; + dropout_p = model_config["attn_pdrop"]; + max_position_embeddings = model_config["n_positions"]; + } catch (json::exception const &e) { + std::cerr << "Error parsing STARCODER config from JSON file: " + << e.what() << std::endl; + assert(false); + } + } else { + std::cerr << "Error opening JSON file " << model_config_file_path + << std::endl; + assert(false); + } + // max_seq_len = BatchConfig::MAX_SEQ_LENGTH; + // max_num_tokens = BatchConfig::MAX_NUM_TOKENS; + max_beam_width = BeamSearchBatchConfig::MAX_BEAM_WIDTH; + max_beam_depth = BeamSearchBatchConfig::MAX_BEAM_DEPTH; + } + + void print() const {} + + // int max_seq_len, max_num_tokens; + int max_beam_width, max_beam_depth; + int num_hidden_layers, vocab_size, num_attention_heads, hidden_size, + intermediate_size, max_position_embeddings; + float layer_norm_epsilon, dropout_p; + }; + + static void create_starcoder_model(FFModel &ff, + std::string const &model_config_file_path, + std::string const &weight_file_path, + InferenceMode mode, + GenerationConfig generationConfig, + bool use_full_precision = false); +}; + +}; // namespace FlexFlow diff --git a/inference/python/entrypoint/fastapi_incr.py b/inference/python/entrypoint/fastapi_incr.py new file mode 100644 index 0000000000..34f61739fb --- /dev/null +++ b/inference/python/entrypoint/fastapi_incr.py @@ -0,0 +1,162 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +Running Instructions: +- To run this FastAPI application, make sure you have FastAPI and Uvicorn installed. +- Save this script as 'fastapi_incr.py'. +- Run the application using the command: `uvicorn fastapi_incr:app --reload --port PORT_NUMBER` +- The server will start on `http://localhost:PORT_NUMBER`. Use this base URL to make API requests. +- Go to `http://localhost:PORT_NUMBER/docs` for API documentation. +""" + + +from fastapi import FastAPI, HTTPException +from pydantic import BaseModel +import flexflow.serve as ff +import uvicorn +import json, os, argparse +from types import SimpleNamespace + +# Initialize FastAPI application +app = FastAPI() + +# Define the request model +class PromptRequest(BaseModel): + prompt: str + +# Global variable to store the LLM model +llm = None + + +def get_configs(): + + # Fetch configuration file path from environment variable + config_file = os.getenv("CONFIG_FILE", "") + + # Load configs from JSON file (if specified) + if config_file: + if not os.path.isfile(config_file): + raise FileNotFoundError(f"Config file {config_file} not found.") + try: + with open(config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + +# Initialize model on startup +@app.on_event("startup") +async def startup_event(): + global llm + + # Initialize your LLM model configuration here + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + ff.init(configs_dict) + + ff_data_type = ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ) + llm.start_server() + +# API endpoint to generate response +@app.post("/generate/") +async def generate(prompt_request: PromptRequest): + if llm is None: + raise HTTPException(status_code=503, detail="LLM model is not initialized.") + + # Call the model to generate a response + full_output = llm.generate([prompt_request.prompt])[0].output_text.decode('utf-8') + + # Separate the prompt and response + split_output = full_output.split('\n', 1) + if len(split_output) > 1: + response_text = split_output[1] + else: + response_text = "" + + # Return the prompt and the response in JSON format + return { + "prompt": prompt_request.prompt, + "response": response_text + } + +# Shutdown event to stop the model server +@app.on_event("shutdown") +async def shutdown_event(): + global llm + if llm is not None: + llm.stop_server() + +# Main function to run Uvicorn server +if __name__ == "__main__": + uvicorn.run(app, host="0.0.0.0", port=8000) + +# Running within the entrypoint folder: +# uvicorn fastapi_incr:app --reload --port + +# Running within the python folder: +# uvicorn entrypoint.fastapi_incr:app --reload --port 3000 diff --git a/inference/python/entrypoint/fastapi_specinfer.py b/inference/python/entrypoint/fastapi_specinfer.py new file mode 100644 index 0000000000..416aee6dc5 --- /dev/null +++ b/inference/python/entrypoint/fastapi_specinfer.py @@ -0,0 +1,202 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +Running Instructions: +- To run this FastAPI application, make sure you have FastAPI and Uvicorn installed. +- Save this script as 'fastapi_specinfer.py'. +- Run the application using the command: `uvicorn fastapi_specinfer:app --reload --port PORT_NUMBER` +- The server will start on `http://localhost:PORT_NUMBER`. Use this base URL to make API requests. +- Go to `http://localhost:PORT_NUMBER/docs` for API documentation. +""" + + +from fastapi import FastAPI, HTTPException +from pydantic import BaseModel +import flexflow.serve as ff +import uvicorn +import json, os, argparse +from types import SimpleNamespace + +# Initialize FastAPI application +app = FastAPI() + +# Define the request model +class PromptRequest(BaseModel): + prompt: str + +# Global variable to store the LLM model +llm = None + +def get_configs(): + # Fetch configuration file path from environment variable + config_file = os.getenv("CONFIG_FILE", "") + + # Load configs from JSON file (if specified) + if config_file: + if not os.path.isfile(config_file): + raise FileNotFoundError(f"Config file {config_file} not found.") + try: + with open(config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required llm arguments + "llm_model": "meta-llama/Llama-2-7b-hf", + # optional llm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + } + ], + # "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + +# Initialize model on startup +@app.on_event("startup") +async def startup_event(): + global llm + + # Initialize your LLM model configuration here + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + ff.init(configs_dict) + + # Create the FlexFlow LLM + ff_data_type = ( + ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + ) + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + # Create the SSMs + ssms = [] + for ssm_config in configs.ssms: + ssm_config = SimpleNamespace(**ssm_config) + ff_data_type = ( + ff.DataType.DT_FLOAT if ssm_config.full_precision else ff.DataType.DT_HALF + ) + ssm = ff.SSM( + ssm_config.ssm_model, + data_type=ff_data_type, + cache_path=ssm_config.cache_path, + refresh_cache=ssm_config.refresh_cache, + output_file=configs.output_file, + ) + ssms.append(ssm) + + # Create the sampling configs + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + + # Compile the SSMs for inference and load the weights into memory + for ssm in ssms: + ssm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ) + + # Compile the LLM for inference and load the weights into memory + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ssms=ssms, + ) + + llm.start_server() + +# API endpoint to generate response +@app.post("/generate/") +async def generate(prompt_request: PromptRequest): + if llm is None: + raise HTTPException(status_code=503, detail="LLM model is not initialized.") + + # Call the model to generate a response + full_output = llm.generate([prompt_request.prompt])[0].output_text.decode('utf-8') + + # Separate the prompt and response + split_output = full_output.split('\n', 1) + if len(split_output) > 1: + response_text = split_output[1] + else: + response_text = "" + + # Return the prompt and the response in JSON format + return { + "prompt": prompt_request.prompt, + "response": response_text + } + +# Shutdown event to stop the model server +@app.on_event("shutdown") +async def shutdown_event(): + global llm + if llm is not None: + llm.stop_server() + +# Main function to run Uvicorn server +if __name__ == "__main__": + uvicorn.run(app, host="0.0.0.0", port=8000) + +# Running within the entrypoint folder: +# uvicorn fastapi_specinfer:app --reload --port + +# Running within the python folder: +# uvicorn entrypoint.fastapi_specinfer:app --reload --port 3000 diff --git a/inference/python/incr_decoding.py b/inference/python/incr_decoding.py new file mode 100644 index 0000000000..05599ea6b9 --- /dev/null +++ b/inference/python/incr_decoding.py @@ -0,0 +1,120 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace + + +def get_configs(): + parser = argparse.ArgumentParser() + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default="", + ) + args = parser.parse_args() + + # Load configs from JSON file (if specified) + if len(args.config_file) > 0: + if not os.path.isfile(args.config_file): + raise FileNotFoundError(f"Config file {args.config_file} not found.") + try: + with open(args.config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "benchmarking": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": os.environ.get("FF_CACHE_PATH", ""), + "refresh_cache": False, + "full_precision": False, + "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + +def main(): + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + + # Initialize the FlexFlow runtime. ff.init() takes a dictionary or the path to a JSON file with the configs + ff.init(configs_dict) + + # Create the FlexFlow LLM + ff_data_type = ( + ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + ) + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + # Compile the LLM for inference and load the weights into memory + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ) + + llm.start_server() + + if len(configs.prompt) > 0: + prompts = [s for s in json.load(open(configs.prompt))] + results = llm.generate(prompts) + else: + result = llm.generate("Three tips for staying healthy are: ") + + llm.stop_server() + + +if __name__ == "__main__": + print("flexflow inference example (incremental decoding)") + main() diff --git a/inference/python/spec_infer.py b/inference/python/spec_infer.py new file mode 100644 index 0000000000..a6dfa8042e --- /dev/null +++ b/inference/python/spec_infer.py @@ -0,0 +1,157 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace + + +def get_configs(): + parser = argparse.ArgumentParser() + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default="", + ) + args = parser.parse_args() + + # Load configs from JSON file (if specified) + if len(args.config_file) > 0: + if not os.path.isfile(args.config_file): + raise FileNotFoundError(f"Config file {args.config_file} not found.") + try: + with open(args.config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "benchmarking": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required llm arguments + "llm_model": "meta-llama/Llama-2-7b-hf", + # optional llm parameters + "cache_path": os.environ.get("FF_CACHE_PATH", ""), + "refresh_cache": False, + "full_precision": False, + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + } + ], + # "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + +def main(): + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + + # Initialize the FlexFlow runtime. ff.init() takes a dictionary or the path to a JSON file with the configs + ff.init(configs_dict) + + # Create the FlexFlow LLM + ff_data_type = ( + ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + ) + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + # Create the SSMs + ssms = [] + for ssm_config in configs.ssms: + ssm_config = SimpleNamespace(**ssm_config) + ff_data_type = ( + ff.DataType.DT_FLOAT if ssm_config.full_precision else ff.DataType.DT_HALF + ) + ssm = ff.SSM( + ssm_config.ssm_model, + data_type=ff_data_type, + cache_path=ssm_config.cache_path, + refresh_cache=ssm_config.refresh_cache, + output_file=configs.output_file, + ) + ssms.append(ssm) + + # Create the sampling configs + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + + # Compile the SSMs for inference and load the weights into memory + for ssm in ssms: + ssm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ) + + # Compile the LLM for inference and load the weights into memory + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ssms=ssms, + ) + + llm.start_server() + + if len(configs.prompt) > 0: + prompts = [s for s in json.load(open(configs.prompt))] + results = llm.generate(prompts) + else: + result = llm.generate("Three tips for staying healthy are: ") + + llm.stop_server() + +if __name__ == "__main__": + print("flexflow inference example (speculative inference)") + main() diff --git a/inference/python/usecases/gradio_incr.py b/inference/python/usecases/gradio_incr.py new file mode 100644 index 0000000000..2735b665bb --- /dev/null +++ b/inference/python/usecases/gradio_incr.py @@ -0,0 +1,162 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +""" +Functionality: +1. Configuration Handling: + - Parses command-line arguments to get a configuration file path. + - Loads configuration settings from a JSON file if provided, or uses default settings. + +2. FlexFlow Model Initialization: + - Initializes FlexFlow with the provided or default configurations. + - Sets up the LLM with the specified model and configurations. + - Compiles the model with generation settings and starts the FlexFlow server. + +3. Gradio Interface Setup: + - Defines a function to generate responses based on user input using FlexFlow. + - Sets up a Gradio Chat Interface to interact with the model in a conversational format. + +4. Main Execution: + - Calls the main function to initialize configurations, set up the FlexFlow LLM, and launch the Gradio interface. + - Stops the FlexFlow server after the Gradio interface is closed. + +Usage: +1. Run the script with an optional configuration file argument for custom settings. +2. Interact with the FlexFlow model through the Gradio web interface. +3. Enter text inputs to receive generated responses from the model. +4. The script will stop the FlexFlow server automatically upon closing the Gradio interface. +""" + +import gradio as gr +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace + + +def get_configs(): + parser = argparse.ArgumentParser() + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default="", + ) + args = parser.parse_args() + + # Load configs from JSON file (if specified) + if len(args.config_file) > 0: + if not os.path.isfile(args.config_file): + raise FileNotFoundError(f"Config file {args.config_file} not found.") + try: + with open(args.config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + +# def generate_response(user_input): +# result = llm.generate(user_input) +# return result.output_text.decode('utf-8') + +def generate_response(message, history): + user_input = message + results = llm.generate(user_input) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + + +def main(): + + global llm + + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + + ff.init(configs_dict) + + ff_data_type = ( + ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + ) + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64, + ) + + # # interface version 1 + # iface = gr.Interface( + # fn=generate_response, + # inputs="text", + # outputs="text" + # ) + + # interface version 2 + iface = gr.ChatInterface(fn=generate_response) + llm.start_server() + iface.launch() + llm.stop_server() + +if __name__ == "__main__": + print("flexflow inference example with gradio interface") + main() \ No newline at end of file diff --git a/inference/python/usecases/gradio_specinfer.py b/inference/python/usecases/gradio_specinfer.py new file mode 100644 index 0000000000..08cde3f00b --- /dev/null +++ b/inference/python/usecases/gradio_specinfer.py @@ -0,0 +1,205 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +""" +Functionality: +1. Configuration Handling: + - Parses command-line arguments to get a configuration file path. + - Loads configuration settings from a JSON file if provided, or uses default settings. + +2. FlexFlow Model Initialization: + - Initializes FlexFlow with the provided or default configurations. + - Sets up the LLM with the specified model and configurations. + - Compiles the model with generation settings and starts the FlexFlow server. + +3. Gradio Interface Setup: + - Defines a function to generate responses based on user input using FlexFlow. + - Sets up a Gradio Chat Interface to interact with the model in a conversational format. + +4. Main Execution: + - Calls the main function to initialize configurations, set up the FlexFlow LLM, and launch the Gradio interface. + - Stops the FlexFlow server after the Gradio interface is closed. + +Usage: +1. Run the script with an optional configuration file argument for custom settings. +2. Interact with the FlexFlow model through the Gradio web interface. +3. Enter text inputs to receive generated responses from the model. +4. The script will stop the FlexFlow server automatically upon closing the Gradio interface. +""" + +""" +TODO: fix current issue: model init is stuck at "prepare next batch init" and "prepare next batch verify" +""" + +import gradio as gr +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace + +def get_configs(): + parser = argparse.ArgumentParser() + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default="", + ) + args = parser.parse_args() + + # Load configs from JSON file (if specified) + if len(args.config_file) > 0: + if not os.path.isfile(args.config_file): + raise FileNotFoundError(f"Config file {args.config_file} not found.") + try: + with open(args.config_file) as f: + return json.load(f) + except json.JSONDecodeError as e: + print("JSON format error:") + print(e) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required llm arguments + "llm_model": "meta-llama/Llama-2-7b-hf", + # optional llm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + } + ], + # "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + +# def generate_response(user_input): +# result = llm.generate(user_input) +# return result.output_text.decode('utf-8') + +def generate_response(message, history): + user_input = message + results = llm.generate(user_input) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + +def main(): + + global llm + + configs_dict = get_configs() + configs = SimpleNamespace(**configs_dict) + + # Initialize the FlexFlow runtime. ff.init() takes a dictionary or the path to a JSON file with the configs + ff.init(configs_dict) + + # Create the FlexFlow LLM + ff_data_type = ( + ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + ) + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + + # Create the SSMs + ssms = [] + for ssm_config in configs.ssms: + ssm_config = SimpleNamespace(**ssm_config) + ff_data_type = ( + ff.DataType.DT_FLOAT if ssm_config.full_precision else ff.DataType.DT_HALF + ) + ssm = ff.SSM( + ssm_config.ssm_model, + data_type=ff_data_type, + cache_path=ssm_config.cache_path, + refresh_cache=ssm_config.refresh_cache, + output_file=configs.output_file, + ) + ssms.append(ssm) + + # Create the sampling configs + generation_config = ff.GenerationConfig( + do_sample=False, temperature=0.9, topp=0.8, topk=1 + ) + + # Compile the SSMs for inference and load the weights into memory + for ssm in ssms: + ssm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=256, + ) + + # Compile the LLM for inference and load the weights into memory + llm.compile( + generation_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=256, + ssms=ssms, + ) + + # # interface version 1 + # iface = gr.Interface( + # fn=generate_response, + # inputs="text", + # outputs="text" + # ) + + # interface version 2 + iface = gr.ChatInterface(fn=generate_response) + llm.start_server() + iface.launch() + llm.stop_server() + +if __name__ == "__main__": + print("flexflow inference example with gradio interface") + main() \ No newline at end of file diff --git a/inference/python/usecases/prompt_template_incr.py b/inference/python/usecases/prompt_template_incr.py new file mode 100644 index 0000000000..8bffe9ddad --- /dev/null +++ b/inference/python/usecases/prompt_template_incr.py @@ -0,0 +1,187 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +This script implements the usecase of prompt template upon FlexFlow. + +Functionality: +1. FlexFlowLLM Class: + - Initializes and configures FlexFlow. + - Loads configurations from a file or uses default settings. + - Compiles and starts the language model server for text generation. + - Stops the server when operations are complete. + +2. FF_LLM_wrapper Class: + - Serves as a wrapper for FlexFlow. + - Implements the necessary interface to interact with the LangChain library. + +3. Main: + - Initializes FlexFlow. + - Compiles and starts the server with specific generation configurations. + - Sets up a prompt template for generating responses to questions. + - Use LLMChain to run the model and generate response. + - Stops the FlexFlow server after generating the response. +""" + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace +from langchain.llms.base import LLM +from typing import Any, List, Mapping, Optional +from langchain.chains import LLMChain +from langchain.prompts import PromptTemplate + +class FlexFlowLLM: + def __init__(self, config_file=""): + self.configs = self.get_configs(config_file) + ff.init(self.configs) + self.llm = self.create_llm() + + def get_configs(self, config_file): + # Load configurations from a file or use default settings + if config_file and os.path.isfile(config_file): + with open(config_file) as f: + return json.load(f) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + def create_llm(self): + configs = SimpleNamespace(**self.configs) + ff_data_type = ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + return llm + + def compile_and_start(self, generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch): + self.llm.compile(generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch) + self.llm.start_server() + + def generate(self, prompt): + results = self.llm.generate(prompt) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + + def stop_server(self): + self.llm.stop_server() + + def __enter__(self): + return self.llm.__enter__() + + def __exit__(self, exc_type, exc_value, traceback): + return self.llm.__exit__(exc_type, exc_value, traceback) + +class FF_LLM_wrapper(LLM): + flexflow_llm: FlexFlowLLM + + @property + def _llm_type(self) -> str: + return "custom" + + def _call( + self, + prompt: str, + stop: Optional[List[str]] = None, + **kwargs: Any, + ) -> str: + if stop is not None: + raise ValueError("stop kwargs are not permitted.") + response = self.flexflow_llm.generate(prompt) + return response + + +if __name__ == "__main__": + # initialization + ff_llm = FlexFlowLLM() + + # compile and start server + gen_config = ff.GenerationConfig(do_sample=False, temperature=0.9, topp=0.8, topk=1) + ff_llm.compile_and_start( + gen_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64 + ) + + # the wrapper class serves as the 'Model' in LCEL + ff_llm_wrapper = FF_LLM_wrapper(flexflow_llm=ff_llm) + + # USE CASE 1: Prompt Template + template = """Question: {question} + Answer: Let's think step by step.""" + + # Build prompt template and langchain + prompt = PromptTemplate(template=template, input_variables=["question"]) + llm_chain = LLMChain(prompt=prompt, llm=ff_llm_wrapper) + + question = "Who was the US president in the year the first Pokemon game was released?" + print(llm_chain.run(question)) + + # stop the server + ff_llm.stop_server() + diff --git a/inference/python/usecases/prompt_template_specinfer.py b/inference/python/usecases/prompt_template_specinfer.py new file mode 100644 index 0000000000..dfc92e9ac2 --- /dev/null +++ b/inference/python/usecases/prompt_template_specinfer.py @@ -0,0 +1,236 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +This script implements the usecase of prompt template upon FlexFlow. + +Functionality: +1. FlexFlowLLM Class: + - Initializes and configures FlexFlow. + - Loads configurations from a file or uses default settings. + - Compiles and starts the language model server for text generation. + - Stops the server when operations are complete. + +2. FF_LLM_wrapper Class: + - Serves as a wrapper for FlexFlow. + - Implements the necessary interface to interact with the LangChain library. + +3. Main: + - Initializes FlexFlow. + - Compiles and starts the server with specific generation configurations. + - Sets up a prompt template for generating responses to questions. + - Use LLMChain to run the model and generate response. + - Stops the FlexFlow server after generating the response. +""" + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace +from langchain.llms.base import LLM +from typing import Any, List, Mapping, Optional +from langchain.chains import LLMChain +from langchain.prompts import PromptTemplate + + +class FlexFlowLLM: + def __init__(self, config_file=""): + self.configs = self.get_configs(config_file) + ff.init(self.configs) + self.llm = self.create_llm() + self.ssms = self.create_ssms() + + def get_configs(self, config_file): + # Load configurations from a file or use default settings + if config_file and os.path.isfile(config_file): + with open(config_file) as f: + return json.load(f) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required llm arguments + "llm_model": "meta-llama/Llama-2-7b-hf", + # optional llm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + } + ], + # "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + def create_llm(self): + configs = SimpleNamespace(**self.configs) + ff_data_type = ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + return llm + + def create_ssms(self): + # Create the SSMs + configs = SimpleNamespace(**self.configs) + ssms = [] + for ssm_config in configs.ssms: + ssm_config = SimpleNamespace(**ssm_config) + ff_data_type = ( + ff.DataType.DT_FLOAT if ssm_config.full_precision else ff.DataType.DT_HALF + ) + ssm = ff.SSM( + ssm_config.ssm_model, + data_type=ff_data_type, + cache_path=ssm_config.cache_path, + refresh_cache=ssm_config.refresh_cache, + output_file=configs.output_file, + ) + ssms.append(ssm) + return ssms + + def compile_and_start(self, generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch): + + # Compile the SSMs for inference and load the weights into memory + for ssm in self.ssms: + ssm.compile( + generation_config, + max_requests_per_batch, + max_seq_length, + max_tokens_per_batch, + ) + + # Compile the LLM for inference and load the weights into memory + self.llm.compile( + generation_config, + max_requests_per_batch, + max_seq_length, + max_tokens_per_batch, + ssms = self.ssms + ) + self.llm.start_server() + + def generate(self, prompt): + results = self.llm.generate(prompt) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + + def stop_server(self): + self.llm.stop_server() + + def __enter__(self): + return self.llm.__enter__() + + def __exit__(self, exc_type, exc_value, traceback): + return self.llm.__exit__(exc_type, exc_value, traceback) + +class FF_LLM_wrapper(LLM): + flexflow_llm: FlexFlowLLM + + @property + def _llm_type(self) -> str: + return "custom" + + def _call( + self, + prompt: str, + stop: Optional[List[str]] = None, + **kwargs: Any, + ) -> str: + if stop is not None: + raise ValueError("stop kwargs are not permitted.") + response = self.flexflow_llm.generate(prompt) + return response + + +if __name__ == "__main__": + # initialization + ff_llm = FlexFlowLLM() + + # compile and start server + gen_config = ff.GenerationConfig(do_sample=False, temperature=0.9, topp=0.8, topk=1) + ff_llm.compile_and_start( + gen_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64 + ) + + # the wrapper class serves as the 'Model' in LCEL + ff_llm_wrapper = FF_LLM_wrapper(flexflow_llm=ff_llm) + + # USE CASE 1: Prompt Template + template = """Question: {question} + Answer: Let's think step by step.""" + + # Build prompt template and langchain + prompt = PromptTemplate(template=template, input_variables=["question"]) + llm_chain = LLMChain(prompt=prompt, llm=ff_llm_wrapper) + + question = "Who was the US president in the year the first Pokemon game was released?" + print(llm_chain.run(question)) + + # stop the server + ff_llm.stop_server() + + diff --git a/inference/python/usecases/rag_incr.py b/inference/python/usecases/rag_incr.py new file mode 100644 index 0000000000..15e7f3d092 --- /dev/null +++ b/inference/python/usecases/rag_incr.py @@ -0,0 +1,220 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +This script implements the usecase of rag-search upon FlexFlow. + +Functionality: +1. FlexFlowLLM Class: + - Initializes and configures FlexFlow. + - Loads configurations from a file or uses default settings. + - Compiles and starts the language model server for text generation. + - Stops the server when operations are complete. + +2. FF_LLM_wrapper Class: + - Serves as a wrapper for FlexFlow. + - Implements the necessary interface to interact with the LangChain library. + +3. Main: + - Initializes FlexFlow. + - Compiles and starts the server with specific generation configurations. + - Taking in specific source information with RAG(Retrieval Augmented Generation) technique for Q&A towards specific realm/knowledgebase. + - Use LLMChain to run the model and generate response. + - Stops the FlexFlow server after generating the response. +""" + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace +from langchain.llms.base import LLM +from typing import Any, List, Mapping, Optional +from langchain.chains import LLMChain +from langchain.prompts import PromptTemplate +from langchain.document_loaders import WebBaseLoader +from langchain.text_splitter import RecursiveCharacterTextSplitter +from langchain.embeddings import OpenAIEmbeddings +from langchain.vectorstores import Chroma +from langchain.vectorstores import FAISS + +class FlexFlowLLM: + def __init__(self, config_file=""): + self.configs = self.get_configs(config_file) + ff.init(self.configs) + self.llm = self.create_llm() + + def get_configs(self, config_file): + # Load configurations from a file or use default settings + if config_file and os.path.isfile(config_file): + with open(config_file) as f: + return json.load(f) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + def create_llm(self): + configs = SimpleNamespace(**self.configs) + ff_data_type = ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + return llm + + def compile_and_start(self, generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch): + self.llm.compile(generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch) + self.llm.start_server() + + def generate(self, prompt): + results = self.llm.generate(prompt) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + + def stop_server(self): + self.llm.stop_server() + + def __enter__(self): + return self.llm.__enter__() + + def __exit__(self, exc_type, exc_value, traceback): + return self.llm.__exit__(exc_type, exc_value, traceback) + + +class FF_LLM_wrapper(LLM): + flexflow_llm: FlexFlowLLM + + @property + def _llm_type(self) -> str: + return "custom" + + def _call( + self, + prompt: str, + stop: Optional[List[str]] = None, + **kwargs: Any, + ) -> str: + if stop is not None: + raise ValueError("stop kwargs are not permitted.") + response = self.flexflow_llm.generate(prompt) + return response + + +if __name__ == "__main__": + # initialization + ff_llm = FlexFlowLLM() + + # compile and start server + gen_config = ff.GenerationConfig(do_sample=False, temperature=0.9, topp=0.8, topk=1) + ff_llm.compile_and_start( + gen_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=64 + ) + + # the wrapper class serves as the 'Model' in LCEL + ff_llm_wrapper = FF_LLM_wrapper(flexflow_llm=ff_llm) + + # USE CASE 2: Rag Search + + # Load web page content + loader = WebBaseLoader("https://lilianweng.github.io/posts/2023-06-23-agent/") + data = loader.load() + + # Split text + text_splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=0) + all_splits = text_splitter.split_documents(data) + + # Initialize embeddings + embeddings = OpenAIEmbeddings(openai_api_key=os.getenv('OPENAI_API_KEY')) # fill in openai api key + + # Create VectorStore + vectorstore = Chroma.from_documents(all_splits, embeddings) + + # Use VectorStore as a retriever + retriever = vectorstore.as_retriever() + + # Test if similarity search is working + question = "What are the approaches to Task Decomposition?" + docs = vectorstore.similarity_search(question) + max_chars_per_doc = 100 + # docs_text_list = [docs[i].page_content for i in range(len(docs))] + docs_text_list = [docs[i].page_content[:max_chars_per_doc] for i in range(len(docs))] + docs_text = ''.join(docs_text_list) + + # Using a Prompt Template + prompt_rag = PromptTemplate.from_template( + "Summarize the main themes in these retrieved docs: {docs_text}" + ) + + # Chain + llm_chain_rag = LLMChain(llm=ff_llm_wrapper, prompt=prompt_rag) + + # Run + rag_result = llm_chain_rag(docs_text) + + # Stop the server + ff_llm.stop_server() + diff --git a/inference/python/usecases/rag_specinfer.py b/inference/python/usecases/rag_specinfer.py new file mode 100644 index 0000000000..512b973955 --- /dev/null +++ b/inference/python/usecases/rag_specinfer.py @@ -0,0 +1,266 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +""" +This script implements the usecase of rag-search upon FlexFlow. + +Functionality: +1. FlexFlowLLM Class: + - Initializes and configures FlexFlow. + - Loads configurations from a file or uses default settings. + - Compiles and starts the language model server for text generation. + - Stops the server when operations are complete. + +2. FF_LLM_wrapper Class: + - Serves as a wrapper for FlexFlow. + - Implements the necessary interface to interact with the LangChain library. + +3. Main: + - Initializes FlexFlow. + - Compiles and starts the server with specific generation configurations. + - Taking in specific source information with RAG(Retrieval Augmented Generation) technique for Q&A towards specific realm/knowledgebase. + - Use LLMChain to run the model and generate response. + - Stops the FlexFlow server after generating the response. +""" + +import flexflow.serve as ff +import argparse, json, os +from types import SimpleNamespace +from langchain.llms.base import LLM +from typing import Any, List, Mapping, Optional +from langchain.chains import LLMChain +from langchain.prompts import PromptTemplate +from langchain.document_loaders import WebBaseLoader +from langchain.text_splitter import RecursiveCharacterTextSplitter +from langchain.embeddings import OpenAIEmbeddings +from langchain.vectorstores import Chroma +from langchain.vectorstores import FAISS + +class FlexFlowLLM: + def __init__(self, config_file=""): + self.configs = self.get_configs(config_file) + ff.init(self.configs) + self.llm = self.create_llm() + self.ssms = self.create_ssms() + + def get_configs(self, config_file): + # Load configurations from a file or use default settings + if config_file and os.path.isfile(config_file): + with open(config_file) as f: + return json.load(f) + else: + # Define sample configs + ff_init_configs = { + # required parameters + "num_gpus": 2, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 2, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "inference_debugging": False, + "fusion": True, + } + llm_configs = { + # required llm arguments + "llm_model": "meta-llama/Llama-2-7b-hf", + # optional llm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + } + ], + # "prompt": "", + "output_file": "", + } + # Merge dictionaries + ff_init_configs.update(llm_configs) + return ff_init_configs + + def create_llm(self): + configs = SimpleNamespace(**self.configs) + ff_data_type = ff.DataType.DT_FLOAT if configs.full_precision else ff.DataType.DT_HALF + llm = ff.LLM( + configs.llm_model, + data_type=ff_data_type, + cache_path=configs.cache_path, + refresh_cache=configs.refresh_cache, + output_file=configs.output_file, + ) + return llm + + def create_ssms(self): + # Create the SSMs + configs = SimpleNamespace(**self.configs) + ssms = [] + for ssm_config in configs.ssms: + ssm_config = SimpleNamespace(**ssm_config) + ff_data_type = ( + ff.DataType.DT_FLOAT if ssm_config.full_precision else ff.DataType.DT_HALF + ) + ssm = ff.SSM( + ssm_config.ssm_model, + data_type=ff_data_type, + cache_path=ssm_config.cache_path, + refresh_cache=ssm_config.refresh_cache, + output_file=configs.output_file, + ) + ssms.append(ssm) + return ssms + + def compile_and_start(self, generation_config, max_requests_per_batch, max_seq_length, max_tokens_per_batch): + + # Compile the SSMs for inference and load the weights into memory + for ssm in self.ssms: + ssm.compile( + generation_config, + max_requests_per_batch, + max_seq_length, + max_tokens_per_batch, + ) + + # Compile the LLM for inference and load the weights into memory + self.llm.compile( + generation_config, + max_requests_per_batch, + max_seq_length, + max_tokens_per_batch, + ssms = self.ssms + ) + # start server + self.llm.start_server() + + def generate(self, prompt): + results = self.llm.generate(prompt) + if isinstance(results, list): + result_txt = results[0].output_text.decode('utf-8') + else: + result_txt = results.output_text.decode('utf-8') + return result_txt + + def stop_server(self): + self.llm.stop_server() + + def __enter__(self): + return self.llm.__enter__() + + def __exit__(self, exc_type, exc_value, traceback): + return self.llm.__exit__(exc_type, exc_value, traceback) + +class FF_LLM_wrapper(LLM): + flexflow_llm: FlexFlowLLM + + @property + def _llm_type(self) -> str: + return "custom" + + def _call( + self, + prompt: str, + stop: Optional[List[str]] = None, + **kwargs: Any, + ) -> str: + if stop is not None: + raise ValueError("stop kwargs are not permitted.") + response = self.flexflow_llm.generate(prompt) + return response + + +if __name__ == "__main__": + # initialization + ff_llm = FlexFlowLLM() + + # compile and start server + gen_config = ff.GenerationConfig(do_sample=False, temperature=0.9, topp=0.8, topk=1) + ff_llm.compile_and_start( + gen_config, + max_requests_per_batch=1, + max_seq_length=256, + max_tokens_per_batch=200 + ) + + # the wrapper class serves as the 'Model' in LCEL + ff_llm_wrapper = FF_LLM_wrapper(flexflow_llm=ff_llm) + + # USE CASE 2: Rag Search + + # Load web page content + loader = WebBaseLoader("https://lilianweng.github.io/posts/2023-06-23-agent/") + data = loader.load() + + # Split text + text_splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=0) + all_splits = text_splitter.split_documents(data) + + # Initialize embeddings + embeddings = OpenAIEmbeddings(openai_api_key=os.getenv('OPENAI_API_KEY')) # fill in openai api key + + # Create VectorStore + vectorstore = Chroma.from_documents(all_splits, embeddings) + + # Use VectorStore as a retriever + retriever = vectorstore.as_retriever() + + # Test if similarity search is working + question = "What are the approaches to Task Decomposition?" + docs = vectorstore.similarity_search(question) + max_chars_per_doc = 50 + # docs_text_list = [docs[i].page_content for i in range(len(docs))] + docs_text_list = [docs[i].page_content[:max_chars_per_doc] for i in range(len(docs))] + docs_text = ''.join(docs_text_list) + + # Using a Prompt Template + prompt_rag = PromptTemplate.from_template( + "Summarize the main themes in these retrieved docs: {docs_text}" + ) + + # Chain + llm_chain_rag = LLMChain(llm=ff_llm_wrapper, prompt=prompt_rag) + + # Run + rag_result = llm_chain_rag(docs_text) + + # stop the server + ff_llm.stop_server() diff --git a/inference/spec_infer/CMakeLists.txt b/inference/spec_infer/CMakeLists.txt new file mode 100644 index 0000000000..1b25de8623 --- /dev/null +++ b/inference/spec_infer/CMakeLists.txt @@ -0,0 +1,37 @@ +cmake_minimum_required(VERSION 3.10) + +project(FlexFlow_SpecInfer) +set(project_target spec_infer) + + +set(CPU_SRC + ${FLEXFLOW_CPP_DRV_SRC} + spec_infer.cc + ../models/llama.cc + ../models/opt.cc + ../models/falcon.cc + ../models/mpt.cc) + +if (FF_GPU_BACKEND STREQUAL "cuda" OR FF_GPU_BACKEND STREQUAL "hip_cuda") + cuda_add_executable(${project_target} ${CPU_SRC}) + if (FF_GPU_BACKEND STREQUAL "hip_cuda") + target_compile_definitions(${project_target} PRIVATE __HIP_PLATFORM_NVIDIA__) + endif() +elseif(FF_GPU_BACKEND STREQUAL "hip_rocm") + set_source_files_properties(${CPU_SRC} PROPERTIES LANGUAGE HIP) + hip_add_executable(${project_target} ${CPU_SRC}) + if (FF_HIP_ARCH STREQUAL "") + message(FATAL_ERROR "FF_HIP_ARCH is empty!") + endif() + set_property(TARGET ${project_target} PROPERTY HIP_ARCHITECTURES "${FF_HIP_ARCH}") + target_compile_definitions(${project_target} PRIVATE __HIP_PLATFORM_AMD__) +else() + message(FATAL_ERROR "Compilation of ${project_target} for ${FF_GPU_BACKEND} backend not yet supported") +endif() + +target_include_directories(${project_target} PRIVATE ${FLEXFLOW_INCLUDE_DIRS} ${CMAKE_INSTALL_INCLUDEDIR}) +target_include_directories(${project_target} PRIVATE ${CMAKE_SOURCE_DIR}/inference) +target_link_libraries(${project_target} -Wl,--whole-archive flexflow -Wl,--no-whole-archive ${FLEXFLOW_EXT_LIBRARIES}) + +set(BIN_DEST "bin") +install(TARGETS ${project_target} DESTINATION ${BIN_DEST}) diff --git a/inference/spec_infer/Makefile b/inference/spec_infer/Makefile new file mode 100644 index 0000000000..0e4b79f51f --- /dev/null +++ b/inference/spec_infer/Makefile @@ -0,0 +1,37 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +# + +# Flags for directing the runtime makefile what to include +DEBUG ?= 0 # Include debugging symbols +MAX_DIM ?= 4 # Maximum number of dimensions +OUTPUT_LEVEL ?= LEVEL_DEBUG # Compile time logging level +USE_CUDA ?= 1 # Include CUDA support (requires CUDA) +USE_GASNET ?= 0 # Include GASNet support (requires GASNet) +USE_HDF ?= 1 # Include HDF5 support (requires HDF5) +ALT_MAPPERS ?= 0 # Include alternative mappers (not recommended) + +# Put the binary file name here +OUTFILE ?= llama_pipeline +# List all the application source files here +ifndef CUDA_HOME +CUDA_HOME = $(patsubst %/bin/nvcc,%,$(shell which nvcc | head -1)) +endif + + +ifndef FF_HOME +$(error FF_HOME variable is not defined, aborting build) +endif + +include $(FF_HOME)/FlexFlow.mk diff --git a/inference/spec_infer/spec_infer.cc b/inference/spec_infer/spec_infer.cc new file mode 100644 index 0000000000..f7edfd7696 --- /dev/null +++ b/inference/spec_infer/spec_infer.cc @@ -0,0 +1,441 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/inference.h" +#include "models/falcon.h" +#include "models/llama.h" +#include "models/mpt.h" +#include "models/opt.h" +#include +#include +#include + +using namespace FlexFlow; +using namespace Legion; +using json = nlohmann::json; + +LegionRuntime::Logger::Category log_app("llama"); + +struct FilePaths { + std::string cache_folder_path; + std::string prompt_file_path; + std::string output_file_path; +}; + +struct ModelNames { + std::string llm_model_name; + std::vector ssm_model_names; +}; + +struct ModelMeta { + ModelNames model_names; + + ModelType llm_model_type; + std::string llm_tokenizer_path; + std::string llm_weights_path; + std::string llm_model_config_path; + + int bos_token_id, eos_token_id; + + std::vector ssm_model_types; + std::vector ssm_model_config_paths; + std::vector ssm_model_weights_paths; +}; + +void parse_input_args(char **argv, + int argc, + FilePaths &paths, + ModelNames &model_names, + bool &use_full_precision, + bool &verbose, + int &max_requests_per_batch, + int &max_tokens_per_batch, + int &max_sequence_length, + int &expansion_degree) { + for (int i = 1; i < argc; i++) { + // llm model name + if (!strcmp(argv[i], "-llm-model")) { + model_names.llm_model_name = std::string(argv[++i]); + for (char &c : model_names.llm_model_name) { + c = std::tolower(c); + } + continue; + } + // ssm models names + if (!strcmp(argv[i], "-ssm-model")) { + std::string ssm_model_name = std::string(argv[++i]); + for (char &c : ssm_model_name) { + c = std::tolower(c); + } + model_names.ssm_model_names.push_back(ssm_model_name); + continue; + } + // cache folder + if (!strcmp(argv[i], "-cache-folder")) { + paths.cache_folder_path = std::string(argv[++i]); + continue; + } + // prompts + if (!strcmp(argv[i], "-prompt")) { + paths.prompt_file_path = std::string(argv[++i]); + continue; + } + // output file + if (!strcmp(argv[i], "-output-file")) { + paths.output_file_path = std::string(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--use-full-precision")) { + use_full_precision = true; + continue; + } + // verbose logging to stdout + if (!strcmp(argv[i], "--verbose")) { + verbose = true; + continue; + } + if (!strcmp(argv[i], "--max-requests-per-batch")) { + max_requests_per_batch = std::stoi(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--max-tokens-per-batch")) { + max_tokens_per_batch = std::stoi(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--max-sequence-length")) { + max_sequence_length = std::stoi(argv[++i]); + continue; + } + if (!strcmp(argv[i], "--expansion-degree")) { + expansion_degree = std::stoi(argv[++i]); + continue; + } + } + if (paths.cache_folder_path.empty()) { + char const *ff_cache_path = std::getenv("FF_CACHE_PATH"); + paths.cache_folder_path = ff_cache_path ? std::string(ff_cache_path) + : std::string("~/.cache/flexflow"); + } + // Expand ~ to the home directory if needed + wordexp_t p; + wordexp(paths.cache_folder_path.c_str(), &p, 0); + paths.cache_folder_path = p.we_wordv[0]; + wordfree(&p); +} + +void get_model_meta(FilePaths &file_paths, + ModelMeta &model_metadata, + bool use_full_precision) { + if (model_metadata.model_names.llm_model_name.empty() || + model_metadata.model_names.ssm_model_names.size() == 0) { + assert(false && "SpecInfer needs at least one LLM and one SSM for " + "speculative inference"); + } + model_metadata.llm_model_config_path = + join_path({file_paths.cache_folder_path, + "configs", + model_metadata.model_names.llm_model_name, + "config.json"}); + model_metadata.llm_tokenizer_path = + join_path({file_paths.cache_folder_path, + "tokenizers", + model_metadata.model_names.llm_model_name}); + model_metadata.llm_weights_path = + join_path({file_paths.cache_folder_path, + "weights", + model_metadata.model_names.llm_model_name, + use_full_precision ? "full-precision" : "half-precision"}); + + std::ifstream llm_config_file_handle(model_metadata.llm_model_config_path); + if (!llm_config_file_handle.good()) { + std::cout << "LLM Model config file " + << model_metadata.llm_model_config_path << " not found." + << std::endl; + assert(false); + } + json llm_model_config = json::parse(llm_config_file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + + model_metadata.llm_model_type = ModelType::UNKNOWN; + auto architectures = llm_model_config["architectures"]; + for (auto const &str : architectures) { + if (str == "LlamaForCausalLM" || str == "LLaMAForCausalLM") { + model_metadata.llm_model_type = ModelType::LLAMA; + break; + } else if (str == "OPTForCausalLM") { + model_metadata.llm_model_type = ModelType::OPT; + break; + } else if (str == "RWForCausalLM" || str == "FalconForCausalLM") { + model_metadata.llm_model_type = ModelType::FALCON; + break; + } else if (str == "MPTForCausalLM") { + model_metadata.llm_model_type = ModelType::MPT; + break; + } + } + model_metadata.bos_token_id = + llm_model_config.find("bos_token_id") == llm_model_config.end() + ? -1 + : (int)llm_model_config.at("bos_token_id"); + model_metadata.eos_token_id = + llm_model_config.find("eos_token_id") == llm_model_config.end() + ? -1 + : (int)llm_model_config.at("eos_token_id"); + + for (auto ssm_model_name : model_metadata.model_names.ssm_model_names) { + std::string ssm_config_path = join_path({file_paths.cache_folder_path, + "configs", + ssm_model_name, + "config.json"}); + std::string ssm_tokenizer_path = + join_path({file_paths.cache_folder_path, "tokenizers", ssm_model_name}); + std::string ssm_weights_path = + join_path({file_paths.cache_folder_path, + "weights", + ssm_model_name, + use_full_precision ? "full-precision" : "half-precision"}); + + std::ifstream ssm_config_file_handle(ssm_config_path); + if (!ssm_config_file_handle.good()) { + std::cout << "SSM Model config file " << ssm_config_path << " not found." + << std::endl; + assert(false); + } + json ssm_model_config = json::parse(ssm_config_file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + + ModelType ssm_model_type = ModelType::UNKNOWN; + auto architectures = ssm_model_config["architectures"]; + for (auto const &str : architectures) { + if (str == "LlamaForCausalLM" || str == "LLaMAForCausalLM") { + ssm_model_type = ModelType::LLAMA; + break; + } else if (str == "OPTForCausalLM") { + ssm_model_type = ModelType::OPT; + break; + } else if (str == "RWForCausalLM") { + ssm_model_type = ModelType::FALCON; + break; + } else if (str == "MPTForCausalLM") { + ssm_model_type = ModelType::MPT; + break; + } + } + int ssm_bos_id = + ssm_model_config.find("bos_token_id") == ssm_model_config.end() + ? -1 + : (int)ssm_model_config.at("bos_token_id"); + int ssm_eos_id = + ssm_model_config.find("eos_token_id") == ssm_model_config.end() + ? -1 + : (int)ssm_model_config.at("eos_token_id"); + if (ssm_bos_id != model_metadata.bos_token_id || + ssm_eos_id != model_metadata.eos_token_id) { + printf("Warning: bos/eos token id mismatch between LLM and one of the " + "SSMs!\n"); + } + model_metadata.ssm_model_types.push_back(ssm_model_type); + model_metadata.ssm_model_config_paths.push_back(ssm_config_path); + model_metadata.ssm_model_weights_paths.push_back(ssm_weights_path); + } + + assert(model_metadata.llm_model_type != ModelType::UNKNOWN && + "Invalid LLM model type passed (or no type was passed)."); + + for (auto mt : model_metadata.ssm_model_types) { + if (mt == ModelType::UNKNOWN) { + assert(false && "One of the SSM model types passed is invalid."); + } + } +} + +void FlexFlow::top_level_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + FFConfig ffconfig; + FilePaths file_paths; + ModelMeta model_metadata; + bool use_full_precision = false; + bool verbose = false; + int max_requests_per_batch = 16; + int max_tokens_per_batch = 256; + int max_sequence_length = 1024; + int max_spec_tree_token_num = 23; + int expansion_degree = 3; + + InputArgs const &command_args = HighLevelRuntime::get_input_args(); + char **argv = command_args.argv; + int argc = command_args.argc; + parse_input_args(argv, + argc, + file_paths, + model_metadata.model_names, + use_full_precision, + verbose, + max_requests_per_batch, + max_tokens_per_batch, + max_sequence_length, + expansion_degree); + + get_model_meta(file_paths, model_metadata, use_full_precision); + + assert(ffconfig.data_parallelism_degree * ffconfig.tensor_parallelism_degree * + ffconfig.pipeline_parallelism_degree == + ffconfig.numNodes * ffconfig.workersPerNode); + + // Create SentencePiece tokenizer or OPT tokenizer + GenerationConfig generationConfig; + InferenceManager *im = InferenceManager::get_inference_manager(); + RequestManager *rm = RequestManager::get_request_manager(); + rm->set_max_requests_per_batch(max_requests_per_batch); + rm->set_max_tokens_per_batch(max_tokens_per_batch); + rm->set_max_spec_tree_token_num(max_spec_tree_token_num); + rm->set_max_sequence_length(max_sequence_length); + rm->register_tokenizer(model_metadata.llm_model_type, + model_metadata.bos_token_id, + model_metadata.eos_token_id, + model_metadata.llm_tokenizer_path); + rm->register_output_filepath(file_paths.output_file_path); + + // first decoding step: 3 results + if (expansion_degree != -1) { + rm->push_spec_infer_tree_width(1); + rm->push_spec_infer_tree_width(1); + rm->push_spec_infer_tree_width(expansion_degree); + } + + // Create LLM model + FFModel tree_model(ffconfig, ffconfig.cpu_offload); + if (model_metadata.llm_model_type == ModelType::LLAMA) { + LLAMA::create_llama_model(tree_model, + model_metadata.llm_model_config_path, + model_metadata.llm_weights_path, + TREE_VERIFY_MODE, + generationConfig, + use_full_precision); + } else if (model_metadata.llm_model_type == ModelType::OPT) { + OPT::create_opt_model(tree_model, + model_metadata.llm_model_config_path, + model_metadata.llm_weights_path, + TREE_VERIFY_MODE, + use_full_precision); + } else if (model_metadata.llm_model_type == ModelType::FALCON) { + FALCON::create_falcon_model(tree_model, + model_metadata.llm_model_config_path, + model_metadata.llm_weights_path, + TREE_VERIFY_MODE, + use_full_precision); + } else if (model_metadata.llm_model_type == ModelType::MPT) { + MPT::create_mpt_model(tree_model, + model_metadata.llm_model_config_path, + model_metadata.llm_weights_path, + TREE_VERIFY_MODE, + generationConfig, + use_full_precision); + } else { + assert(false && "Invalid LLM model type passed (or no type was passed)."); + } + + // Create SSM models + int num_ssms = model_metadata.ssm_model_types.size(); + std::vector ssm_model_ids; + std::vector ssm_models; + FFConfig bm_config = ffconfig; + bm_config.data_parallelism_degree = bm_config.tensor_parallelism_degree = + bm_config.pipeline_parallelism_degree = 1; + for (int ssm_id = 0; ssm_id < num_ssms; ssm_id++) { + FFModel beam_model(bm_config); + ssm_models.push_back(beam_model); + } + + for (int ssm_id = 0; ssm_id < num_ssms; ssm_id++) { + FFModel &beam_model = ssm_models[ssm_id]; + if (model_metadata.ssm_model_types[ssm_id] == ModelType::LLAMA) { + LLAMA::create_llama_model(beam_model, + model_metadata.ssm_model_config_paths[ssm_id], + model_metadata.ssm_model_weights_paths[ssm_id], + BEAM_SEARCH_MODE, + generationConfig, + use_full_precision); + } else if (model_metadata.ssm_model_types[ssm_id] == ModelType::OPT) { + OPT::create_opt_model(beam_model, + model_metadata.ssm_model_config_paths[ssm_id], + model_metadata.ssm_model_weights_paths[ssm_id], + BEAM_SEARCH_MODE, + use_full_precision); + } else if (model_metadata.ssm_model_types[ssm_id] == ModelType::FALCON) { + FALCON::create_falcon_model( + beam_model, + model_metadata.ssm_model_config_paths[ssm_id], + model_metadata.ssm_model_weights_paths[ssm_id], + BEAM_SEARCH_MODE, + use_full_precision); + } else if (model_metadata.ssm_model_types[ssm_id] == ModelType::MPT) { + MPT::create_mpt_model(beam_model, + model_metadata.ssm_model_config_paths[ssm_id], + model_metadata.ssm_model_weights_paths[ssm_id], + BEAM_SEARCH_MODE, + generationConfig, + use_full_precision); + } else { + assert(false && "Invalid SSM model type passed."); + } + + rm->register_ssm_model(&beam_model); + } + + rm->start_background_server(&tree_model); + + // Register requests from prompt file + int total_num_requests = 0; + { + using json = nlohmann::json; + std::ifstream file_handle(file_paths.prompt_file_path); + assert(file_handle.good() && "Prompt file does not exist."); + json prompt_json = json::parse(file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + + std::vector prompts; + for (auto &prompt : prompt_json) { + std::string text = prompt.get(); + printf("Prompt[%d]: %s\n", total_num_requests, text.c_str()); + total_num_requests++; + prompts.push_back(text); + // tree_model.generate(text, 128 /*max_sequence_length*/); + } + tree_model.generate(prompts, 128 /*max_sequence_length*/); + } + + // terminate the request manager by stopping the background thread + rm->terminate_background_server(); + + // Execution fence + { + Future future = runtime->issue_execution_fence(ctx); + future.get_void_result(); + } + + // float* data + std::cout << "----------inference finished--------------" << std::endl; +} + +void FlexFlow::register_custom_tasks() {} diff --git a/inference/utils/compress_llama_weights.py b/inference/utils/compress_llama_weights.py new file mode 100644 index 0000000000..daaee9c9d5 --- /dev/null +++ b/inference/utils/compress_llama_weights.py @@ -0,0 +1,117 @@ +import torch +import numpy as np +from transformers import AutoModelForCausalLM +import dataclasses + +@dataclasses.dataclass +class CompressionConfig: + """Group-wise quantization.""" + num_bits: int + group_size: int + group_dim: int + symmetric: bool + enabled: bool = True + +def compress(tensor, config): + """Simulate group-wise quantization.""" + if not config.enabled: + return tensor + + group_size, num_bits, group_dim, symmetric = ( + config.group_size, config.num_bits, config.group_dim, config.symmetric) + assert num_bits <= 8 + + original_shape = tensor.shape + num_groups = (original_shape[group_dim] + group_size - 1) // group_size + new_shape = (original_shape[:group_dim] + (num_groups, group_size) + + original_shape[group_dim+1:]) + + # Pad + pad_len = (group_size - original_shape[group_dim] % group_size) % group_size + if pad_len != 0: + pad_shape = original_shape[:group_dim] + (pad_len,) + original_shape[group_dim+1:] + tensor = torch.cat([ + tensor, + torch.zeros(pad_shape, dtype=tensor.dtype, device=tensor.device)], + dim=group_dim) + data = tensor.view(new_shape) + + # Quantize + if symmetric: + B = 2 ** (num_bits - 1) - 1 + scale = B / torch.max(data.abs(), dim=group_dim + 1, keepdim=True)[0] + data = data * scale + data = data.clamp_(-B, B).round_().to(torch.int8) + return data, scale, original_shape + else: + B = 2 ** num_bits - 1 + # print('max value') + # print(B) + mn = torch.min(data, dim=group_dim + 1, keepdim=True)[0] + mx = torch.max(data, dim=group_dim + 1, keepdim=True)[0] + + scale = B / (mx - mn) + data = data - mn + data.mul_(scale) + + data = data.clamp_(0, B).round_().to(torch.uint8) + return data, mn, scale, original_shape + + +def decompress(packed_data, config): + """Simulate group-wise dequantization.""" + if not config.enabled: + return packed_data + + group_size, num_bits, group_dim, symmetric = ( + config.group_size, config.num_bits, config.group_dim, config.symmetric) + + # Dequantize + if symmetric: + data, scale, original_shape = packed_data + data = data / scale + else: + data, mn, scale, original_shape = packed_data + data = data / scale + data.add_(mn) + + # Unpad + pad_len = (group_size - original_shape[group_dim] % group_size) % group_size + if pad_len: + padded_original_shape = ( + original_shape[:group_dim] + + (original_shape[group_dim] + pad_len,) + + original_shape[group_dim+1:]) + data = data.reshape(padded_original_shape) + indices = [slice(0, x) for x in original_shape] + return data[indices].contiguous() + else: + return data.view(original_shape) + +if __name__ == "__main__": + # torch.set_default_tensor_type(torch.HalfTensor) + # torch.set_default_tensor_type(torch.cuda.HalfTensor) + model = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-2-7b-hf") + config = CompressionConfig( + num_bits=8, group_size=32, group_dim=0, symmetric=False) + for name, params in model.named_parameters(): + name = ( + name.replace(".", "_") + .replace("self_attn", "attention") + .replace("q_proj", "wq") + .replace("k_proj", "wk") + .replace("v_proj", "wv") + .replace("o_proj", "wo") + .replace("mlp", "feed_forward") + .replace("gate_proj", "w1") + .replace("down_proj", "w2") + .replace("up_proj", "w3") + .replace("input_layernorm", "attention_norm") + .replace("post_attention_layernorm", "ffn_norm") + .replace("embed_tokens", "tok_embeddings") + .replace("lm_head", "output") + .replace("model_", "") + ) + if "feed_forward" in name or "output" in name or "attention_w" in name: + data, mn, scale, original_shape = compress(params, config) + \ No newline at end of file diff --git a/inference/utils/download_hf_model.py b/inference/utils/download_hf_model.py new file mode 100644 index 0000000000..7b4f4d6fb0 --- /dev/null +++ b/inference/utils/download_hf_model.py @@ -0,0 +1,60 @@ +#!/usr/bin/env python +import flexflow.serve as ff +import argparse, os + + +def parse_args(): + parser = argparse.ArgumentParser() + parser.add_argument( + "model_names", type=str, nargs="+", help="Name of the model(s) to download" + ) + parser.add_argument( + "--cache-folder", + type=str, + help="Folder to use to store the model(s) assets in FlexFlow format", + default=os.environ.get("FF_CACHE_PATH", ""), + ) + parser.add_argument( + "--refresh-cache", + action="store_true", + help="Use this flag to force the refresh of the model(s) weights/tokenizer cache", + ) + group = parser.add_mutually_exclusive_group() + group.add_argument( + "--full-precision-only", + action="store_true", + help="Only download the full precision version of the weights", + ) + group.add_argument( + "--half-precision-only", + action="store_true", + help="Only download the half precision version of the weights", + ) + args = parser.parse_args() + return args + + +def main(args): + if args.full_precision_only: + data_types = (ff.DataType.DT_FLOAT,) + elif args.half_precision_only: + data_types = (ff.DataType.DT_HALF,) + else: + data_types = (ff.DataType.DT_FLOAT, ff.DataType.DT_HALF) + + for model_name in args.model_names: + for data_type in data_types: + llm = ff.LLM( + model_name, + data_type=data_type, + cache_path=args.cache_folder, + refresh_cache=args.refresh_cache, + ) + llm.download_hf_weights_if_needed() + llm.download_hf_tokenizer_if_needed() + llm.download_hf_config() + + +if __name__ == "__main__": + args = parse_args() + main(args) diff --git a/jupyter_notebook/README.md b/jupyter_notebook/README.md deleted file mode 100644 index 70d94f0f16..0000000000 --- a/jupyter_notebook/README.md +++ /dev/null @@ -1,89 +0,0 @@ -# Jupyter Notebook - -This directory contains Jupyter notebook support for -FlexFlow. -It allows user to run any FlexFlow Python -program (e.g., training models) on a single node using -the in-browser jupyter notebook UI. - -## Quick Start -### Pre-requisite -* Python >= 3.6 -* FlexFlow Python binding needs to be installed, please check the [installation guide](https://github.com/flexflow/FlexFlow/blob/master/INSTALL.md) -* Install Jupyter notebook - - pip install notebook - -### Install the FlexFlow IPython kernel -``` -python ./install.py --(configurations) -``` -Please refer to the [IPython Kernel Configurations](#kernel-configurations) section for the configuration details. - -If the installation is successed, the following log will be printed to the terminal. -The `flexflow_kernel_nocr` is the IPython kernel name, where `nocr` means control replication is not enabled. -The control replication can be enabled once multi-node jupyter notebook support is provided in the future. -The `FlexFlow_SM_GPU` is the display name -of the kernel, which can be modified by the configuration json file. -`FlexFlow` is the name entry in the json file, `SM` means the IPython kernel -is only for shared memory machine, and `GPU` means GPU execution is enabled. -``` -IPython kernel: flexflow_kernel_nocr(FlexFlow_SM_GPU) has been installed -``` -The installed IPython kernel can be also seen by using the following command: -``` -jupyter kernelspec list -``` - -### Create a turnel (Optional) -If you want to run the jupyter notebook server on a remote compute node instead of localhost, -you can create a turnel from localhost to the compute node. -``` -ssh -4 -t -L 8888:localhost:8002 username@login-node-hostname ssh -t -L 8002:localhost:8888 computing_node -``` - -### Start the Jupyter Notebook server -Launch jupyter notebook server on the compute node or localhost if the turnel is not created -``` -jupyter notebook --port=8888 --no-browser -``` - -### Use the Jupyter Notebook in the browser -* Open the browser, type the addredd http://localhost:8888/?token=xxx, the token will be -displayed in the terminal once the server is started. -* Once the webpage is loaded, click "New" on the right top corner, and click the kernel -just installed. It is shown as the display name of the kernel, e.g. `FlexFlow_SM_GPU`. - -### Uninstall the IPython kernel -``` -jupyter kernelspec uninstall flexflow_kernel_nocr -``` -If the IPython kernel is re-installed, the old one will be automatically uninstalled by the install.py - - -## IPython Kernel Configurations -The IPython kernel can be configured by either passing arguments to `install.py` or using a json file. -The accepted arguments can be listed with -``` -python ./install.py --help -``` - -It is always preferred to use a json file. -The `flexflow_python.json` is the template respect to the -flexflow_python. Most entries are using the following format: -``` -"cpus": { - "cmd": "--cpus", - "value": 1 -} -``` -* `cpus` is the name of the field. - -* `cmd` is used to tell how to pass the value to the field. -For example, flexflow uses `-ll:cpu` to set the number of CPUs, so the `cmd` in `flexflow_python.json` is `-ll:cpu`. - -* `value` is the value of the field. It can be set to `null`. In this case, the value is read -from the command line arguments. - -Other configuration options can be added by either appending them to the command line arguments or -using the `other_options` field of the json file. diff --git a/jupyter_notebook/flexflow_jupyter.json b/jupyter_notebook/flexflow_jupyter.json deleted file mode 100644 index 0ff79c7234..0000000000 --- a/jupyter_notebook/flexflow_jupyter.json +++ /dev/null @@ -1,67 +0,0 @@ -{ - "name": "FlexFlow", - "kernel_name": "flexflow_kernel_nocr", - "flexflow_python_prefix": null, - "exe": "flexflow_python", - "cpus": { - "cmd": "-ll:cpu", - "value": 1 - }, - "gpus": { - "cmd": "-ll:gpu", - "value": 1 - }, - "openmp": { - "cmd": "-ll:ocpu", - "value": 0 - }, - "ompthreads": { - "cmd": "-ll:othr", - "value": 0 - }, - "utility": { - "cmd": "-ll:util", - "value": 1 - }, - "sysmem": { - "cmd": "-ll:csize", - "value": null - }, - "fbmem": { - "cmd": "-ll:fsize", - "value": 4096 - }, - "zcmem": { - "cmd": "-ll:zsize", - "value": 10240 - }, - "regmem": { - "cmd": "-ll:rsize", - "value": null - }, - "not_control_replicable": { - "action": "store_true", - "cmd": "--nocr", - "value": null - }, - "nodes": { - "cmd": "-n", - "value": 1 - }, - "ranks_per_node": { - "cmd": "--npernode", - "value": 1 - }, - "launcher": { - "type": "generic", - "cmd": "--launcher", - "value": null, - "launcher_extra": null - }, - "other_options": [ - { - "cmd": "-ll:py", - "value": 1 - } - ] -} \ No newline at end of file diff --git a/jupyter_notebook/flexflow_kernel_nocr.py b/jupyter_notebook/flexflow_kernel_nocr.py deleted file mode 100644 index 203a416d70..0000000000 --- a/jupyter_notebook/flexflow_kernel_nocr.py +++ /dev/null @@ -1,59 +0,0 @@ -#!/usr/bin/env python - -# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) -# -# Licensed under the Apache License, Version 2.0 (the "License"); -# you may not use this file except in compliance with the License. -# You may obtain a copy of the License at -# -# http://www.apache.org/licenses/LICENSE-2.0 -# -# Unless required by applicable law or agreed to in writing, software -# distributed under the License is distributed on an "AS IS" BASIS, -# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. -# See the License for the specific language governing permissions and -# limitations under the License. -# - -from __future__ import print_function -from ipykernel.ipkernel import IPythonKernel -import sys - -__version__ = '0.1' - -class FlexFlowKernelNoCR(IPythonKernel): - implementation = 'flexflow_kernel_nocr' - implementation_version = __version__ - - banner = "FlexFlow IPython Kernel for SM" - language = 'python' - language_version = __version__ - language_info = {'name': 'flexflow_kernel_nocr', - 'mimetype': 'text/x-python', - 'codemirror_mode': { - 'name': 'ipython', - 'version': 3 - }, - 'pygments_lexer': 'ipython3', - 'nbconvert_exporter': 'python', - 'file_extension': '.py'} - - def __init__(self, **kwargs): - self.__stdout = None - self._set_stdout() - print("Init FlexFlow kernel for single node or multi-nodes without control replication.") - self._reset_stdout() - super().__init__(**kwargs) - - def _set_stdout(self): - assert(self.__stdout == None), "stdout should be None" - self.__stdout = sys.stdout - sys.stdout = open('/dev/stdout', 'w') - - def _reset_stdout(self): - assert(self.__stdout != None), "stdout should not be None" - sys.stdout = self.__stdout - -if __name__ == "__main__": - from ipykernel.kernelapp import IPKernelApp - IPKernelApp.launch_instance(kernel_class=FlexFlowKernelNoCR) diff --git a/jupyter_notebook/install.py b/jupyter_notebook/install.py deleted file mode 100644 index 9073620d26..0000000000 --- a/jupyter_notebook/install.py +++ /dev/null @@ -1,408 +0,0 @@ -#!/usr/bin/env python3 - -# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) -# -# Licensed under the Apache License, Version 2.0 (the "License"); -# you may not use this file except in compliance with the License. -# You may obtain a copy of the License at -# -# http://www.apache.org/licenses/LICENSE-2.0 -# -# Unless required by applicable law or agreed to in writing, software -# distributed under the License is distributed on an "AS IS" BASIS, -# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. -# See the License for the specific language governing permissions and -# limitations under the License. -# - -import json -import os -import re -import sys -import argparse -from distutils import log -import json -import inspect -import shutil - -from jupyter_client.kernelspec import KernelSpecManager, NoSuchKernel -from IPython.utils.tempdir import TemporaryDirectory - -kernel_json = {"argv": [], - "display_name": "None", - "language": "python", -} - -kernel_json_suffix_nocr = ["flexflow_kernel_nocr.py", "-f", "{connection_file}"] - - -required_cmd_dict_key = ["name", "kernel_name", "flexflow_python_prefix", "exe", "cpus", "gpus", "openmp", "ompthreads", "utility", "sysmem", "fbmem", "zcmem", "regmem", "not_control_replicable"] - -# This internal method is used to delete a kernel specified by kernel_name -def _delete_kernel(ksm, kernel_name, mute=True): - try: - spec = ksm.get_kernel_spec(kernel_name) - shutil.rmtree(spec.resource_dir) - if mute == False: - print("Find existing kernel:" + kernel_name + ", delete it before installation.") - except NoSuchKernel: - if mute == False: - print("No existing kernel:" + kernel_name + " has been installed, continue to installation.") - -# This internal method is used to install a kernel -def _install_kernel(ksm, kernel_name, kernel_json, user, prefix, mute=True): - with TemporaryDirectory() as td: - os.chmod(td, 0o755) - with open(os.path.join(td, "kernel.json"), "w") as f: - json.dump(kernel_json, f, sort_keys=True) - try: - ksm.install_kernel_spec(td, kernel_name, user=user, prefix=prefix) - if mute == False: - print("IPython kernel: " + kernel_name + "(" + kernel_json["display_name"] + ") has been installed") - except Exception as e: - if mute == False: - log.error("Failed to install the IPython kernel: " + kernel_name + "(" + kernel_json["display_name"] + ") with error: " + str(e)) - -# This method parses the json file into a dict named cmd_dict -def parse_json(flexflow_python_prefix, - cpus, - gpus, - openmp, - ompthreads, - utility, - sysmem, - fbmem, - zcmem, - regmem, - launcher, - nodes, - ranks_per_node, - not_control_replicable, - kernel_name, - filename): - with open(filename) as json_file: - cmd_dict = json.load(json_file) - for key in required_cmd_dict_key: - if key not in cmd_dict: - assert 0, "Key: " + key + " is not existed." - # Criterion - # if entry in the json file is set to null, we load it from the cmd line - args = inspect.getfullargspec(parse_json) - keys = args.args[0: len(args.args)-1] - sig = inspect.signature(parse_json) - argv_dict = locals() - for key in keys: - if key == "launcher": - if cmd_dict[key]["value"] == None and argv_dict[key] != "none": - cmd_dict[key]["value"] = argv_dict[key] - if cmd_dict[key]["launcher_extra"] == None: - cmd_dict[key]["launcher_extra"] = list() - elif key == "flexflow_python_prefix" or key == "kernel_name": - if cmd_dict[key] == None: - cmd_dict[key] = argv_dict[key] - else: - if cmd_dict[key]["value"] == None: - cmd_dict[key]["value"] = argv_dict[key] - - return cmd_dict - -# This method is used to install the kernel for jupyter notebook support for single or -# multiple nodes runs without control replication -def install_kernel_nocr(user, prefix, cmd_opts, cmd_dict, verbose, kernel_file_dir): - if verbose: - print("cmd_dict is:\n" + str(cmd_dict)) - - # setup name and argv - kernel_json["argv"] = [cmd_dict["flexflow_python_prefix"] + "/" + cmd_dict["exe"]] + kernel_json["argv"] - kernel_json["display_name"] = cmd_dict["name"] - - # launcher - if cmd_dict["launcher"]["value"] == None: - kernel_json["display_name"] += "_SM" - else: - kernel_json["display_name"] += "_DM" - nodes = cmd_dict["nodes"]["value"] - ranks_per_node = cmd_dict["ranks_per_node"]["value"] - launcher = cmd_dict["launcher"]["value"] - if cmd_dict["launcher"]["type"] == "legate": - # use legate launcher - kernel_json["argv"] += cmd_dict["launcher"]["cmd"], launcher, \ - cmd_dict["nodes"]["cmd"], str(nodes), \ - cmd_dict["ranks_per_node"]["cmd"], str(ranks_per_node) - else: - # use mpirun, srun and jsrun launcher - ranks = nodes * ranks_per_node - if launcher == "mpirun": - kernel_json["argv"] = ["mpirun", "-n", str(ranks), "--npernode", str(ranks_per_node)] + cmd_dict["launcher"]["launcher_extra"] + kernel_json["argv"] - elif launcher == "srun": - kernel_json["argv"] = ["srun", "-n", str(ranks), "--ntasks-per-node", str(ranks_per_node)] + cmd_dict["launcher"]["launcher_extra"] + kernel_json["argv"] - elif launcher == "jsrun": - kernel_json["argv"] = ["jsrun", "-n", str(ranks // ranks_per_node), "-r", "1", "-a", str(ranks_per_node)] + cmd_dict["launcher"]["launcher_extra"] + kernel_json["argv"] - else: - assert 0, "Unknown launcher" - - # let's do not enable control replication because pygion has issue with cleaning up - # disable control replication - # assert cmd_dict["not_control_replicable"]["value"] == True - # kernel_json["argv"].append(cmd_dict["not_control_replicable"]["cmd"]) - - # cpu - if cmd_dict["cpus"]["value"] > 0: - kernel_json["argv"] += cmd_dict["cpus"]["cmd"], str(cmd_dict["cpus"]["value"]) - - # gpu - if cmd_dict["gpus"]["value"] > 0: - kernel_json["display_name"] += "_GPU" - kernel_json["argv"] += cmd_dict["gpus"]["cmd"], str(cmd_dict["gpus"]["value"]) - if cmd_dict["fbmem"]["value"] > 0: - kernel_json["argv"] += cmd_dict["fbmem"]["cmd"], str(cmd_dict["fbmem"]["value"]) - if cmd_dict["zcmem"]["value"] > 0: - kernel_json["argv"] += cmd_dict["zcmem"]["cmd"], str(cmd_dict["zcmem"]["value"]) - - # openmp - if cmd_dict["openmp"]["value"] > 0: - if cmd_dict["ompthreads"]["value"] > 0: - kernel_json["argv"] += cmd_dict["openmp"]["cmd"], str(cmd_dict["openmp"]["value"]) - kernel_json["argv"] += cmd_dict["ompthreads"]["cmd"], str(cmd_dict["ompthreads"]["value"]) - else: - print( - "WARNING: ignore request for " - + str(cmd_dict["openmp"]["value"]) - + "OpenMP processors with 0 threads" - ) - - # utility - if cmd_dict["utility"]["value"] > 0: - kernel_json["argv"] += cmd_dict["utility"]["cmd"], str(cmd_dict["utility"]["value"]) - - # system memory - if cmd_dict["sysmem"]["value"] > 0: - kernel_json["argv"] += cmd_dict["sysmem"]["cmd"], str(cmd_dict["sysmem"]["value"]) - - # register memory - if cmd_dict["regmem"]["value"] > 0: - kernel_json["argv"] += cmd_dict["regmem"]["cmd"], str(cmd_dict["regmem"]["value"]) - - # other options from json - if "other_options" in cmd_dict: - other_options = cmd_dict["other_options"] - for option in other_options: - if option["value"] == None: - kernel_json["argv"].append(option["cmd"]) - else: - kernel_json["argv"] += option["cmd"], str(option["value"]) - - # other options from cmd line - for option in cmd_opts: - kernel_json["argv"].append(option) - - ksm = KernelSpecManager() - - # we need the installation dir of kernel, so first install a fake one - tmp_kernel_name = "tmp_legion_kernel" - tmp_kernel_json = {"argv": [], "display_name": "Tmp", "language": "python"} - _install_kernel(ksm, tmp_kernel_name, tmp_kernel_json, user, prefix) - spec = ksm.get_kernel_spec(tmp_kernel_name) - kernel_install_dir = os.path.dirname(spec.resource_dir) - _delete_kernel(ksm, tmp_kernel_name) - - # Now start installation - kernel_name = cmd_dict["kernel_name"] - - # add installation dir to legin_kernel_nocr.py - kernel_install_dir = os.path.join(kernel_install_dir, kernel_name) - kernel_filename = kernel_json_suffix_nocr[0] - kernel_json_suffix_nocr[0] = os.path.join(kernel_install_dir, kernel_filename) - kernel_json["argv"] += kernel_json_suffix_nocr - if verbose: - print("The kernel_json is:\n" + str(kernel_json)) - - # check if kernel is existed, if yes, then delete the old one before installation. - _delete_kernel(ksm, kernel_name, False) - - # install the kernel - _install_kernel(ksm, kernel_name, kernel_json, user, prefix, False) - - # copy legion_kernel_nocr.py into kernel dir - if kernel_file_dir == None: - file_path = os.getcwd() + "/" + kernel_filename - else: - file_path = kernel_file_dir + "/" + kernel_filename - shutil.copy(file_path, kernel_install_dir) - -def parse_args(argv=None): - parser = argparse.ArgumentParser( - description="Install Legion IPython Kernel" - ) - - parser.add_argument( - "--user", - action="store_true", - default=True, - dest="user", - help="Install the kernel in user home directory", - ) - parser.add_argument( - "--kernel-name", - default="", - dest="kernel_name", - help="Install the kernel into prefix", - ) - parser.add_argument( - "--prefix", - default=None, - dest="prefix", - help="Install the kernel into prefix", - ) - parser.add_argument( - "--json", - default="flexflow_jupyter.json", - dest="json", - help="Configuration file of flexflow_python", - ) - parser.add_argument( - "--flexflow-python-prefix", - default=None, - dest="flexflow_python_prefix", - help="The dirctory where flexflow_python is installed", - ) - parser.add_argument( - "--cpus", - type=int, - default=1, - dest="cpus", - help="Number of CPUs to use per rank", - ) - parser.add_argument( - "--gpus", - type=int, - default=1, - dest="gpus", - help="Number of GPUs to use per rank", - ) - parser.add_argument( - "--omps", - type=int, - default=0, - dest="openmp", - help="Number of OpenMP groups to use per rank", - ) - parser.add_argument( - "--ompthreads", - type=int, - default=4, - dest="ompthreads", - help="Number of threads per OpenMP group", - ) - parser.add_argument( - "--utility", - type=int, - default=1, - dest="utility", - help="Number of Utility processors per rank to request for meta-work", - ) - parser.add_argument( - "--sysmem", - type=int, - default=4000, - dest="sysmem", - help="Amount of DRAM memory per rank (in MBs)", - ) - parser.add_argument( - "--fbmem", - type=int, - default=4000, - dest="fbmem", - help="Amount of framebuffer memory per GPU (in MBs)", - ) - parser.add_argument( - "--zcmem", - type=int, - default=32, - dest="zcmem", - help="Amount of zero-copy memory per rank (in MBs)", - ) - parser.add_argument( - "--regmem", - type=int, - default=0, - dest="regmem", - help="Amount of registered CPU-side pinned memory per rank (in MBs)", - ) - parser.add_argument( - "--no-replicate", - dest="not_control_replicable", - action="store_true", - required=False, - default=True, - help="Execute this program without control replication. Most of the " - "time, this is not recommended. This option should be used for " - "debugging. The -lg:safe_ctrlrepl Legion option may be helpful " - "with discovering issues with replicated control.", - ) - parser.add_argument( - "--launcher", - dest="launcher", - choices=["mpirun", "jsrun", "srun", "none"], - default="none", - help='launcher program to use (set to "none" for local runs, or if ' - "the launch has already happened by the time legate is invoked)", - ) - parser.add_argument( - "--nodes", - type=int, - default=1, - dest="nodes", - help="Number of nodes to use", - ) - parser.add_argument( - "--ranks-per-node", - type=int, - default=1, - dest="ranks_per_node", - help="Number of ranks (processes running copies of the program) to " - "launch per node. The default (1 rank per node) will typically result " - "in the best performance.", - ) - parser.add_argument( - "--verbose", - action="store_true", - default=False, - dest="verbose", - help="Display the detailed log of installation", - ) - - args, opts = parser.parse_known_args() - return args, opts - -def driver(args, opts, kernel_file_dir=None): - cmd_dict = parse_json(flexflow_python_prefix=args.flexflow_python_prefix, - cpus=args.cpus, - gpus=args.gpus, - openmp=args.openmp, - ompthreads=args.ompthreads, - utility=args.utility, - sysmem=args.sysmem, - fbmem=args.fbmem, - zcmem=args.zcmem, - regmem=args.regmem, - launcher=args.launcher, - nodes=args.nodes, - ranks_per_node=args.ranks_per_node, - not_control_replicable=args.not_control_replicable, - kernel_name=args.kernel_name, - filename=args.json) - - if cmd_dict["not_control_replicable"]: - install_kernel_nocr(user=args.user, - prefix=args.prefix, - cmd_opts=opts, - cmd_dict=cmd_dict, - verbose=args.verbose, - kernel_file_dir=kernel_file_dir) - else: - assert 0, "Control replication is not supported yet" - -if __name__ == '__main__': - args, opts = parse_args() - driver(args, opts) diff --git a/nmt/embed.cu b/nmt/embed.cu deleted file mode 100644 index 077c5ec565..0000000000 --- a/nmt/embed.cu +++ /dev/null @@ -1,373 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "../cnn_helper.h" -#include "rnn.h" -#include "rnn_mapper.h" - -struct EmbedInitParams { - DnnHandle handle; - int batchSize, outputSize, vocabSize; -}; - -Tensor RnnModel::add_embed_node(Tensor x, - int vocab_size, - int output_size, - ParallelConfig pc, - SharedVariable params) { - assert(x.numDim == 2); - assert(x.adim[1] == LSTM_PER_NODE_LENGTH); - assert(x.pdim[1] == LSTM_PER_NODE_LENGTH); - Embed *node = new Embed(config, x, vocab_size, output_size, pc, params); - layers.push_back(node); - return node->outputs[0]; -} - -Embed::Embed(RnnConfig config, - Tensor x, - int _vocab_size, - int _output_size, - ParallelConfig pc, - SharedVariable _params) - : RnnOp(x, pc, _params), batchSize(x.adim[0]), vocabSize(_vocab_size), - outputSize(_output_size) { - Context ctx = config.lg_ctx; - HighLevelRuntime *runtime = config.lg_hlr; - assert(pc.nDims == 1); - { - Rect<1> rect(Point<1>(0), Point<1>(pc.dim[0] - 1)); - part_rect = rect; - } - IndexSpaceT<1> part_is = runtime->create_index_space(ctx, part_rect); - FieldSpace fs = config.field_space; - Rect<3, coord_t> y_rect( - Point<3>(0, 0, 0), - Point<3>(outputSize - 1, batchSize - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexSpaceT<3> y_is = runtime->create_index_space(ctx, y_rect); - LogicalRegion y_lr = runtime->create_logical_region(ctx, y_is, fs); - LogicalRegion y_grad_lr = runtime->create_logical_region(ctx, y_is, fs); - int num_par_n = part_rect.hi[0] - part_rect.lo[0] + 1; - assert(batchSize % num_par_n == 0); - int extent_n = batchSize / num_par_n; - int extent_c = outputSize; - Rect<3, coord_t> extent( - Point<3>(0, 0, 0), - Point<3>(extent_c - 1, extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - Transform<3, 1, coord_t> trans; - trans[0][0] = 0; - trans[1][0] = extent_n; - trans[2][0] = 0; - IndexPartition y_ip = runtime->create_partition_by_restriction( - ctx, y_is, part_is, trans, extent); - assert(runtime->is_index_partition_disjoint(ctx, y_ip)); - assert(runtime->is_index_partition_complete(ctx, y_ip)); - LogicalPartition y_lp = runtime->get_logical_partition(ctx, y_lr, y_ip); - LogicalPartition y_grad_lp = - runtime->get_logical_partition(ctx, y_grad_lr, y_ip); - outputs[0].region = y_lr; - outputs[0].region_grad = y_grad_lr; - outputs[0].partition = y_lp; - outputs[0].partition_grad = y_grad_lp; - outputs[0].numDim = 3; - outputs[0].adim[0] = outputSize; - outputs[0].adim[1] = batchSize; - outputs[0].adim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].pdim[0] = extent_c; - outputs[0].pdim[1] = extent_n; - outputs[0].pdim[2] = LSTM_PER_NODE_LENGTH; -} - -/* - regions[0] (I): x - regions[1] (I): w - regions[2] (O): y - */ -OpMeta *Embed::init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == 3); - assert(task->regions.size() == 3); - EmbedInitParams const *embed = (EmbedInitParams *)task->args; - Rect<2> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(rect_x.hi[0] - rect_x.lo[0] + 1 == embed->batchSize); - assert(rect_x.hi[1] - rect_x.lo[1] + 1 == LSTM_PER_NODE_LENGTH); - assert(rect_w.hi[0] - rect_w.lo[0] + 1 == - embed->vocabSize * embed->outputSize); - assert(rect_y.hi[0] - rect_y.lo[0] + 1 == embed->outputSize); - assert(rect_y.hi[1] - rect_y.lo[1] + 1 == embed->batchSize); - assert(rect_y.hi[2] - rect_y.lo[2] + 1 == LSTM_PER_NODE_LENGTH); - EmbedMeta *m = new EmbedMeta(embed->handle); - m->profiling_runtime = false; - return m; -} - -void Embed::init(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - EmbedInitParams initParams; - initParams.handle = model.dnn_handlers[paraConfig.gpu[idx]]; - initParams.batchSize = outputs[0].pdim[1]; - initParams.outputSize = outputs[0].pdim[0]; - initParams.vocabSize = vocabSize; - // batch is the first dim of input and the second dim of output - assert(inputs[0].pdim[0] == outputs[0].pdim[1]); - TaskLauncher launcher(EMBED_INIT_TASK_ID, - TaskArgument(&initParams, sizeof(initParams)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.region, READ_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(1, FID_DATA); - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(2, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - meta[idx] = f.get_result(); - } -} - -__global__ void embedForward(int const *x_ptr, - float const *embed, - float *y_ptr, - coord_t numElements, - int shift, - int outputSize) { - CUDA_KERNEL_LOOP(i, numElements) { - int idx = i >> shift; - int off = i & (outputSize - 1); - int wordIdx = x_ptr[idx]; - y_ptr[i] = embed[(wordIdx << shift) + off]; - } -} - -__global__ void embedBackward(int const *x_ptr, - float *embed, - float const *y_ptr, - coord_t numElements, - int shift, - int outputSize) { - CUDA_KERNEL_LOOP(i, numElements) { - int idx = i >> shift; - int off = i & (outputSize - 1); - int wordIdx = x_ptr[idx]; - atomicAdd(embed + (wordIdx << shift) + off, y_ptr[i]); - } -} - -/* - regions[0](I): x - regions[1](I): w - regions[2](O): y -*/ -void Embed::forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 3); - assert(task->regions.size() == 3); - EmbedMeta const *m = *((EmbedMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRO const acc_w(regions[1], FID_DATA); - AccessorWO const acc_y(regions[2], FID_DATA); - Rect<2> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - int batch_size = rect_y.hi[1] - rect_y.lo[1] + 1; - int output_size = rect_y.hi[0] - rect_y.lo[0] + 1; - int const *x_ptr = acc_x.ptr(rect_x.lo); - float const *w_ptr = acc_w.ptr(rect_w.lo); - float *y_ptr = acc_y.ptr(rect_y.lo); - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - int shift = 0; - int size = 1; - while (size < output_size) { - size = size * 2; - shift = shift + 1; - } - assert(size == output_size); - embedForward<<>>( - x_ptr, w_ptr, y_ptr, rect_y.volume(), shift, output_size); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("Embed forward time = %.2lfms\n", elapsed); - } -#endif -} - -void Embed::forward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(EMBED_FWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.region, READ_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(1, FID_DATA); - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(2, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -/* - regions[0](I): x - regions[1](I/O): w_grad - regions[2](I): y_grad -*/ -void Embed::backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 3); - assert(task->regions.size() == 3); - EmbedMeta const *m = *((EmbedMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRW const acc_w(regions[1], FID_DATA); - AccessorRO const acc_y(regions[2], FID_DATA); - Rect<2> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - int batch_size = rect_y.hi[1] - rect_y.lo[1] + 1; - int output_size = rect_y.hi[0] - rect_y.lo[0] + 1; - int const *x_ptr = acc_x.ptr(rect_x.lo); - float *w_ptr = acc_w.ptr(rect_w.lo); - float const *y_ptr = acc_y.ptr(rect_y.lo); - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - int shift = 0; - int size = 1; - while (size < output_size) { - size = size * 2; - shift = shift + 1; - } - assert(size == output_size); - embedBackward<<>>( - x_ptr, w_ptr, y_ptr, rect_y.volume(), shift, output_size); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("Embed backward time = %.2lfms\n", elapsed); - } -#endif -} - -void Embed::backward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(EMBED_BWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.gradients[paraConfig.gpu[idx]], - READ_WRITE, - EXCLUSIVE, - params.gradients[paraConfig.gpu[idx]])); - launcher.add_field(1, FID_DATA); - { - LogicalRegion y_grad = runtime->get_logical_subregion_by_color( - outputs[0].partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - y_grad, READ_ONLY, EXCLUSIVE, outputs[0].region_grad)); - launcher.add_field(2, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -void Embed::update(RnnModel const &model) {} diff --git a/nmt/linear.cu b/nmt/linear.cu deleted file mode 100644 index 48a7290bf0..0000000000 --- a/nmt/linear.cu +++ /dev/null @@ -1,618 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "../cnn_helper.h" -#include "rnn.h" -#include "rnn_mapper.h" - -struct LinearInitParams { - DnnHandle handle; - int batchSize, inputSize, outputSize; -}; - -Tensor RnnModel::add_linear_node(Tensor x, - int output_size, - ParallelConfig pc, - SharedVariable params) { - assert(x.numDim == 3); - assert(x.adim[2] == LSTM_PER_NODE_LENGTH); - assert(x.pdim[2] == LSTM_PER_NODE_LENGTH); - Linear *node = new Linear(config, x, output_size, pc, params, part_is); - layers.push_back(node); - return node->outputs[0]; -} - -Linear::Linear(RnnConfig config, - Tensor input, - int _output_size, - ParallelConfig pc, - SharedVariable _params, - IndexSpaceT<1> input_part_is) - : RnnOp(input, pc, _params), input_size(input.adim[0]), - output_size(_output_size) { - Context ctx = config.lg_ctx; - HighLevelRuntime *runtime = config.lg_hlr; - assert(pc.nDims == 2); - int num_par_n = pc.dim[1]; - int num_par_c = pc.dim[0]; - input_part_rect = runtime->get_index_space_domain(ctx, input_part_is); - { - Rect<2> rect(Point<2>(0, 0), Point<2>(num_par_c - 1, num_par_n - 1)); - part_rect = rect; - } - IndexSpaceT<2> part_is = runtime->create_index_space(ctx, part_rect); - int batch_size = input.adim[1]; - FieldSpace fs = config.field_space; - Rect<3, coord_t> y_rect( - Point<3>(0, 0, 0), - Point<3>(output_size - 1, batch_size - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexSpaceT<3> y_is = runtime->create_index_space(ctx, y_rect); - LogicalRegion y_lr = runtime->create_logical_region(ctx, y_is, fs); - LogicalRegion y_grad_lr = runtime->create_logical_region(ctx, y_is, fs); - assert(output_size % num_par_c == 0); - assert(batch_size % num_par_n == 0); - int extent_c = output_size / num_par_c; - int extent_n = batch_size / num_par_n; - Rect<3, coord_t> extent( - Point<3>(0, 0, 0), - Point<3>(extent_c - 1, extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - Transform<3, 2, coord_t> trans; - trans[0][0] = extent_c; - trans[0][1] = 0; - trans[1][0] = 0; - trans[1][1] = extent_n; - trans[2][0] = 0; - trans[2][1] = 0; - IndexPartition y_ip = runtime->create_partition_by_restriction( - ctx, y_is, part_is, trans, extent); - assert(runtime->is_index_partition_disjoint(ctx, y_ip)); - assert(runtime->is_index_partition_complete(ctx, y_ip)); - LogicalPartition y_lp = runtime->get_logical_partition(ctx, y_lr, y_ip); - LogicalPartition y_grad_lp = - runtime->get_logical_partition(ctx, y_grad_lr, y_ip); - - // Note: we only need replica's grad, so no need to create lr/lp for forward - Rect<3, coord_t> replica_rect(Point<3>(0, 0, 0), - Point<3>(input_size - 1, - batch_size - 1, - LSTM_PER_NODE_LENGTH * num_par_c - 1)); - IndexSpaceT<3> replica_is = runtime->create_index_space(ctx, replica_rect); - replica.region_grad = runtime->create_logical_region(ctx, replica_is, fs); - trans[0][0] = 0; - trans[0][1] = 0; - trans[1][0] = 0; - trans[1][1] = extent_n; - trans[2][0] = LSTM_PER_NODE_LENGTH; - trans[2][1] = 0; - Rect<3, coord_t> replica_ext( - Point<3>(0, 0, 0), - Point<3>(input_size - 1, extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexPartition replica_ip = runtime->create_partition_by_restriction( - ctx, replica_is, part_is, trans, replica_ext); - assert(runtime->is_index_partition_disjoint(ctx, replica_ip)); - assert(runtime->is_index_partition_complete(ctx, replica_ip)); - replica.partition_grad = - runtime->get_logical_partition(ctx, replica.region_grad, replica_ip); - for (int i = 0; i < num_par_c; i++) { - Transform<3, 1, coord_t> input_trans; - input_trans[0][0] = 0; - input_trans[1][0] = inputs[0].pdim[1]; - input_trans[2][0] = 0; - Rect<3, coord_t> ext(Point<3>(0, 0, LSTM_PER_NODE_LENGTH * i), - Point<3>(inputs[0].pdim[0] - 1, - inputs[0].pdim[1] - 1, - LSTM_PER_NODE_LENGTH * (i + 1) - 1)); - IndexPartition ip = runtime->create_partition_by_restriction( - ctx, replica_is, input_part_is, input_trans, ext); - assert(runtime->is_index_partition_disjoint(ctx, ip)); - replica_sub_lps[i] = - runtime->get_logical_partition(ctx, replica.region_grad, ip); - } - - outputs[0].numDim = 3; - outputs[0].adim[0] = output_size; - outputs[0].adim[1] = batch_size; - outputs[0].adim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].pdim[0] = extent_c; - outputs[0].pdim[1] = extent_n; - outputs[0].pdim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].region = y_lr; - outputs[0].partition = y_lp; - outputs[0].region_grad = y_grad_lr; - outputs[0].partition_grad = y_grad_lp; - - // Every partition reads all in_channels - trans[0][0] = 0; - trans[0][1] = 0; - trans[1][0] = 0; - trans[1][1] = extent_n; - trans[2][0] = 0; - trans[2][1] = 0; - Rect<3, coord_t> input_ext( - Point<3>(0, 0, 0), - Point<3>(input_size - 1, extent_n - 1, LSTM_PER_NODE_LENGTH)); - IndexSpaceT<3> input_is = IndexSpaceT<3>(inputs[0].region.get_index_space()); - IndexPartition input_ip = runtime->create_partition_by_restriction( - ctx, input_is, part_is, trans, input_ext); - input_lp = runtime->get_logical_partition(ctx, inputs[0].region, input_ip); -} - -/* - regions[0](I): x - regions[1](I): w - regions[2](O): y - */ -OpMeta *Linear::init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == 3); - assert(task->regions.size() == 3); - LinearInitParams const *linear = (LinearInitParams *)task->args; - Rect<3> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(rect_x.hi[0] - rect_x.lo[0] + 1 == linear->inputSize); - assert(rect_x.hi[1] - rect_x.lo[1] + 1 == linear->batchSize); - assert(rect_x.hi[2] - rect_x.lo[2] + 1 == LSTM_PER_NODE_LENGTH); - assert(rect_y.hi[0] - rect_y.lo[0] + 1 == linear->outputSize); - assert(rect_y.hi[1] - rect_y.lo[1] + 1 == linear->batchSize); - assert(rect_y.hi[2] - rect_y.lo[2] + 1 == LSTM_PER_NODE_LENGTH); - assert(rect_w.hi[0] - rect_w.lo[0] + 1 == - linear->outputSize * (linear->inputSize + 1)); - LinearMeta *m = new LinearMeta(linear->handle); - m->profiling_runtime = false; -#ifndef DISABLE_COMPUTATION - int batch_size = linear->batchSize * LSTM_PER_NODE_LENGTH; - float *dram_one_ptr = (float *)malloc(sizeof(float) * batch_size); - for (int i = 0; i < batch_size; i++) { - dram_one_ptr[i] = 1.0f; - } - checkCUDA(cudaMalloc(&m->one_ptr, sizeof(float) * batch_size)); - checkCUDA(cudaMemcpy(m->one_ptr, - dram_one_ptr, - sizeof(float) * batch_size, - cudaMemcpyHostToDevice)); -#endif - return m; -} - -void Linear::init(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - int num_par_c = part_rect.hi[0] - part_rect.lo[0] + 1; - for (PointInRectIterator<2> it(part_rect); it(); it++, idx++) { - LinearInitParams initParams; - initParams.handle = model.dnn_handlers[paraConfig.gpu[idx]]; - initParams.batchSize = outputs[0].pdim[1]; - initParams.inputSize = inputs[0].pdim[0]; - initParams.outputSize = outputs[0].pdim[0]; - TaskLauncher launcher(RNN_LINEAR_INIT_TASK_ID, - TaskArgument(&initParams, sizeof(initParams)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - // Add input - { - LogicalRegion x = runtime->get_logical_subregion_by_color(input_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.subregions[num_par_c + dp[0]], - READ_ONLY, - EXCLUSIVE, - params.region)); - launcher.add_field(1, FID_DATA); - // Add output - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(2, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - meta[idx] = f.get_result(); - } -} - -/* - regions[0] (I): x - regions[1] (I): w - regions[2] (O): y - */ -void Linear::forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 3); - assert(task->regions.size() == 3); - float alpha = 1.0f, beta = 0.0f; - LinearMeta const *m = *((LinearMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRO const acc_w(regions[1], FID_DATA); - AccessorWO const acc_y(regions[2], FID_DATA); - Rect<3> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - int input_size = rect_x.hi[0] - rect_x.lo[0] + 1; - int output_size = rect_y.hi[0] - rect_y.lo[0] + 1; - int batch_size = (rect_x.hi[1] - rect_x.lo[1] + 1) * LSTM_PER_NODE_LENGTH; - float const *x_ptr = acc_x.ptr(rect_x.lo); - float const *w_ptr = acc_w.ptr(rect_w.lo); - float const *bias_ptr = w_ptr + input_size; - float *y_ptr = acc_y.ptr(rect_y.lo); - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDA(cublasSetStream(m->handle.blas, stream)); - checkCUDA(cublasSgemm(m->handle.blas, - CUBLAS_OP_T, - CUBLAS_OP_N, - output_size, - batch_size, - input_size, - &alpha, - w_ptr, - input_size + 1, - x_ptr, - input_size, - &beta, - y_ptr, - output_size)); - checkCUDA(cublasSgemm(m->handle.blas, - CUBLAS_OP_T, - CUBLAS_OP_N, - output_size, - batch_size, - 1, - &alpha, - bias_ptr, - input_size + 1, - m->one_ptr, - 1, - &alpha, - y_ptr, - output_size)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("Linear forward time = %.2lfms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<3, float>(y_ptr, rect_y, "linear(fwd):y"); -#endif -#endif -} - -void Linear::forward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - int num_par_c = part_rect.hi[0] - part_rect.lo[0] + 1; - for (PointInRectIterator<2> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(RNN_LINEAR_FWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - // Add input - { - LogicalRegion x = runtime->get_logical_subregion_by_color(input_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.subregions[num_par_c + dp[0]], - READ_ONLY, - EXCLUSIVE, - params.region)); - launcher.add_field(1, FID_DATA); - // Add output - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(2, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -/* - regions[0](I): x - regions[1](I): w - regions[2](I): y - regions[3](O); replica_grad - regions[4](I/O): w_grad - regions[5](I): y_grad -*/ -void Linear::backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 6); - assert(task->regions.size() == 6); - float alpha = 1.0f, beta = 0.0f; - LinearMeta const *m = *((LinearMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRO const acc_w(regions[1], FID_DATA); - AccessorRO const acc_y(regions[2], FID_DATA); - AccessorWO const acc_replica_grad(regions[3], FID_DATA); - AccessorRW const acc_w_grad(regions[4], FID_DATA); - AccessorRO const acc_y_grad(regions[5], FID_DATA); - - Rect<3> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - Rect<3> rect_replica_grad = runtime->get_index_space_domain( - ctx, task->regions[3].region.get_index_space()); - Rect<1> rect_w_grad = runtime->get_index_space_domain( - ctx, task->regions[4].region.get_index_space()); - Rect<3> rect_y_grad = runtime->get_index_space_domain( - ctx, task->regions[5].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - assert(acc_replica_grad.accessor.is_dense_arbitrary(rect_replica_grad)); - assert(acc_w_grad.accessor.is_dense_arbitrary(rect_w_grad)); - assert(acc_y_grad.accessor.is_dense_arbitrary(rect_y_grad)); - int input_size = rect_x.hi[0] - rect_x.lo[0] + 1; - int output_size = rect_y.hi[0] - rect_y.lo[0] + 1; - int batch_size = (rect_x.hi[1] - rect_x.lo[1] + 1) * LSTM_PER_NODE_LENGTH; - float const *x_ptr = acc_x.ptr(rect_x.lo); - float const *w_ptr = acc_w.ptr(rect_w.lo); - float const *y_ptr = acc_y.ptr(rect_y.lo); - float *replica_grad_ptr = acc_replica_grad.ptr(rect_replica_grad.lo); - // Note that w_grad might be bigger than w - assert(rect_w_grad.contains(rect_w)); - float *w_grad_ptr = acc_w_grad.ptr(rect_w_grad.lo); - float *bias_grad_ptr = w_grad_ptr + input_size; - float const *y_grad_ptr = acc_y_grad.ptr(rect_y_grad.lo); - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDA(cublasSetStream(m->handle.blas, stream)); - // Compute weight gradient - checkCUDA(cublasSgemm(m->handle.blas, - CUBLAS_OP_N, - CUBLAS_OP_T, - input_size, - output_size, - batch_size, - &alpha, - x_ptr, - input_size, - y_grad_ptr, - output_size, - &alpha, - w_grad_ptr, - input_size + 1)); - // Compute bias gradient - checkCUDA(cublasSgemv(m->handle.blas, - CUBLAS_OP_N, - output_size, - batch_size, - &alpha, - y_grad_ptr, - output_size, - m->one_ptr, - 1, - &alpha, - bias_grad_ptr, - input_size + 1)); - // Compute data gradient - checkCUDA(cublasSgemm(m->handle.blas, - CUBLAS_OP_N, - CUBLAS_OP_N, - input_size, - batch_size, - output_size, - &alpha, - w_ptr, - input_size + 1, - y_grad_ptr, - output_size, - &beta, - replica_grad_ptr, - input_size)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("Linear backward time = %.2lfms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<1, float>(w_grad_ptr, rect_w_grad, "linear(bwd):w_grad"); -#endif -#endif -} - -/* - regions[0](O): input - regions[1..num_par_c](I): replicas -*/ -void Linear::backward2_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - float alpha = 1.0f; - LinearMeta const *m = *((LinearMeta **)task->args); - AccessorWO const acc_input(regions[0], FID_DATA); - Rect<3> rect_input = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - assert(acc_input.accessor.is_dense_arbitrary(rect_input)); - float *input_ptr = acc_input.ptr(rect_input.lo); - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDA(cublasSetStream(m->handle.blas, stream)); - for (int i = 1; i < task->regions.size(); i++) { - AccessorRO const acc_replica(regions[i], FID_DATA); - Rect<3> rect_replica = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(rect_replica.volume() == rect_input.volume()); - assert(acc_replica.accessor.is_dense_arbitrary(rect_replica)); - float const *replica_ptr = acc_replica.ptr(rect_replica.lo); - if (i == 1) { - checkCUDA(cublasScopy( - m->handle.blas, rect_input.volume(), replica_ptr, 1, input_ptr, 1)); - } else { - checkCUDA(cublasSaxpy(m->handle.blas, - rect_input.volume(), - &alpha, - replica_ptr, - 1, - input_ptr, - 1)); - } - } -#endif -} - -void Linear::backward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - int num_par_c = part_rect.hi[0] - part_rect.lo[0] + 1; - for (PointInRectIterator<2> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(RNN_LINEAR_BWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - // Add x - { - LogicalRegion x = runtime->get_logical_subregion_by_color(input_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - // Add w - launcher.add_region_requirement( - RegionRequirement(params.subregions[num_par_c + dp[0]], - READ_ONLY, - EXCLUSIVE, - params.region)); - launcher.add_field(1, FID_DATA); - // Add y - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, READ_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(2, FID_DATA); - } - // Add replica_grad - { - LogicalRegion replica_grad = - runtime->get_logical_subregion_by_color(replica.partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - replica_grad, WRITE_ONLY, EXCLUSIVE, replica.region_grad)); - launcher.add_field(3, FID_DATA); - } - // Add w_grad - launcher.add_region_requirement( - RegionRequirement(params.gradients[paraConfig.gpu[idx]], - READ_WRITE, - EXCLUSIVE, - params.gradients[paraConfig.gpu[idx]])); - launcher.add_field(4, FID_DATA); - // Add y_grad - { - LogicalRegion y_grad = runtime->get_logical_subregion_by_color( - outputs[0].partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - y_grad, READ_ONLY, EXCLUSIVE, outputs[0].region_grad)); - launcher.add_field(5, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } - - // We aggregate data from replica tensor to input tensor - idx = 0; - for (PointInRectIterator<1> it(input_part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(RNN_LINEAR_BWD2_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - LogicalRegion input = - runtime->get_logical_subregion_by_color(inputs[0].partition_grad, dp); - launcher.add_region_requirement( - RegionRequirement(input, WRITE_ONLY, EXCLUSIVE, inputs[0].region_grad)); - launcher.add_field(0, FID_DATA); - int num_par_c = part_rect.hi[0] - part_rect.lo[0] + 1; - for (int i = 0; i < num_par_c; i++) { - LogicalRegion r = - runtime->get_logical_subregion_by_color(replica_sub_lps[i], dp); - launcher.add_region_requirement( - RegionRequirement(r, READ_ONLY, EXCLUSIVE, replica.region_grad)); - launcher.add_field(i + 1, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -void Linear::update_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) {} - -void Linear::update(RnnModel const &model) {} diff --git a/nmt/lstm.cu b/nmt/lstm.cu deleted file mode 100644 index 1a405bb1a0..0000000000 --- a/nmt/lstm.cu +++ /dev/null @@ -1,652 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "../cnn_helper.h" -#include "rnn.h" -#include "rnn_mapper.h" - -struct LSTMInitParams { - DnnHandle handle; - int batchSize, inputSize, outputSize; -}; - -LSTMTensors RnnModel::add_lstm_node( - Tensor x, Tensor hx, Tensor cx, ParallelConfig pc, SharedVariable params) { - assert(x.numDim == 3); - assert(hx.numDim == 2); - assert(cx.numDim == 2); - assert(x.adim[2] == LSTM_PER_NODE_LENGTH); - assert(x.pdim[2] == LSTM_PER_NODE_LENGTH); - int batch_size = x.adim[1]; - assert(hx.adim[1] == batch_size); - assert(cx.adim[1] == batch_size); - int input_size = x.adim[0]; - int output_size = hx.adim[0]; - assert(cx.adim[0] == output_size); - LSTM *node = new LSTM( - config, x, hx, cx, batch_size, input_size, output_size, pc, params); - layers.push_back(node); - LSTMTensors output; - output.x = node->outputs[0]; - output.hx = node->outputs[1]; - output.cx = node->outputs[2]; - return output; -} - -/* - output[0]: y - output[1]: hy - output[2]: cy - */ -LSTM::LSTM(RnnConfig config, - Tensor x, - Tensor hx, - Tensor cx, - int _batch_size, - int _input_size, - int _output_size, - ParallelConfig pc, - SharedVariable _params) - : RnnOp(x, hx, cx, pc, _params), batch_size(_batch_size), - input_size(_input_size), output_size(_output_size) { - printf("LSTM node: batch(%d) input(%d) output(%d)\n", - batch_size, - input_size, - output_size); - Context ctx = config.lg_ctx; - HighLevelRuntime *runtime = config.lg_hlr; - assert(pc.nDims == 1); - { - Rect<1> rect(Point<1>(0), Point<1>(pc.dim[0] - 1)); - part_rect = rect; - } - IndexSpaceT<1> part_is = runtime->create_index_space(ctx, part_rect); - FieldSpace fs = config.field_space; - Rect<3, coord_t> y_rect( - Point<3>(0, 0, 0), - Point<3>(output_size - 1, batch_size - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexSpaceT<3> y_is = runtime->create_index_space(ctx, y_rect); - LogicalRegion y_lr = runtime->create_logical_region(ctx, y_is, fs); - LogicalRegion y_grad_lr = runtime->create_logical_region(ctx, y_is, fs); - int num_par_n = part_rect.hi[0] - part_rect.lo[0] + 1; - assert(batch_size % num_par_n == 0); - int extent_n = batch_size / num_par_n; - int extent_c = output_size; - Rect<3, coord_t> extent( - Point<3>(0, 0, 0), - Point<3>(extent_c - 1, extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - Transform<3, 1, coord_t> trans; - trans[0][0] = 0; - trans[1][0] = extent_n; - trans[2][0] = 0; - IndexPartition y_ip = runtime->create_partition_by_restriction( - ctx, y_is, part_is, trans, extent); - assert(runtime->is_index_partition_disjoint(ctx, y_ip)); - assert(runtime->is_index_partition_complete(ctx, y_ip)); - LogicalPartition y_lp = runtime->get_logical_partition(ctx, y_lr, y_ip); - LogicalPartition y_grad_lp = - runtime->get_logical_partition(ctx, y_grad_lr, y_ip); - outputs[0].region = y_lr; - outputs[0].region_grad = y_grad_lr; - outputs[0].partition = y_lp; - outputs[0].partition_grad = y_grad_lp; - outputs[0].numDim = 3; - outputs[0].adim[0] = output_size; - outputs[0].adim[1] = batch_size; - outputs[0].adim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].pdim[0] = extent_c; - outputs[0].pdim[1] = extent_n; - outputs[0].pdim[2] = LSTM_PER_NODE_LENGTH; - - Rect<2, coord_t> hy_rect(Point<2>(0, 0), - Point<2>(output_size - 1, batch_size - 1)); - IndexSpaceT<2> hy_is = runtime->create_index_space(ctx, hy_rect); - LogicalRegion hy_lr = runtime->create_logical_region(ctx, hy_is, fs); - LogicalRegion hy_grad_lr = runtime->create_logical_region(ctx, hy_is, fs); - Rect<2, coord_t> hy_ext(Point<2>(0, 0), Point<2>(extent_c - 1, extent_n - 1)); - Transform<2, 1, coord_t> hy_trans; - hy_trans[0][0] = 0; - hy_trans[1][0] = extent_n; - IndexPartition hy_ip = runtime->create_partition_by_restriction( - ctx, hy_is, part_is, hy_trans, hy_ext); - assert(runtime->is_index_partition_disjoint(ctx, hy_ip)); - assert(runtime->is_index_partition_complete(ctx, hy_ip)); - LogicalPartition hy_lp = runtime->get_logical_partition(ctx, hy_lr, hy_ip); - LogicalPartition hy_grad_lp = - runtime->get_logical_partition(ctx, hy_grad_lr, hy_ip); - outputs[1].region = hy_lr; - outputs[1].region_grad = hy_grad_lr; - outputs[1].partition = hy_lp; - outputs[1].partition_grad = hy_grad_lp; - outputs[1].numDim = 2; - outputs[1].adim[0] = output_size; - outputs[1].adim[1] = batch_size; - outputs[1].pdim[0] = extent_c; - outputs[1].pdim[1] = extent_n; - - LogicalRegion cy_lr = runtime->create_logical_region(ctx, hy_is, fs); - LogicalRegion cy_grad_lr = runtime->create_logical_region(ctx, hy_is, fs); - LogicalPartition cy_lp = runtime->get_logical_partition(ctx, cy_lr, hy_ip); - LogicalPartition cy_grad_lp = - runtime->get_logical_partition(ctx, cy_grad_lr, hy_ip); - outputs[2] = outputs[1]; - outputs[2].region = cy_lr; - outputs[2].region_grad = cy_grad_lr; - outputs[2].partition = cy_lp; - outputs[2].partition_grad = cy_grad_lp; -} - -/* - regions[0] (I): x - regions[1] (I): hx - regions[2] (I): cx - regions[3] (I): w - regions[4] (O): y - regions[5] (O): hy - regions[6] (O): cy -*/ -OpMeta *LSTM::init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - int const numLayers = 1; - int const seqLength = LSTM_PER_NODE_LENGTH; - float const dropoutRate = 0.2f; - assert(regions.size() == 7); - assert(task->regions.size() == 7); - Rect<1> para_rect = runtime->get_index_space_domain( - ctx, task->regions[3].region.get_index_space()); - LSTMInitParams const *lstm = (LSTMInitParams *)task->args; - LSTMMeta *m = new LSTMMeta(lstm->handle); -#ifndef DISABLE_COMPUTATION - checkCUDNN(cudnnCreateRNNDescriptor(&m->rnnDesc)); - checkCUDNN(cudnnCreateDropoutDescriptor(&m->dropoutDesc)); - size_t dropoutSize; - void *dropoutStates; - checkCUDNN(cudnnDropoutGetStatesSize(m->handle.dnn, &dropoutSize)); - checkCUDA(cudaMalloc(&dropoutStates, dropoutSize)); - checkCUDNN(cudnnSetDropoutDescriptor(m->dropoutDesc, - m->handle.dnn, - dropoutRate, - dropoutStates, - dropoutSize, - 10 /*seed*/)); - checkCUDNN(cudnnSetRNNDescriptor_v5(m->rnnDesc, - lstm->outputSize, - numLayers, - m->dropoutDesc, - CUDNN_LINEAR_INPUT, - CUDNN_UNIDIRECTIONAL, - CUDNN_LSTM, - CUDNN_DATA_FLOAT)); - for (int i = 0; i < seqLength; i++) { - checkCUDNN(cudnnCreateTensorDescriptor(&m->xDescs[i])); - int dims[] = {lstm->batchSize, lstm->inputSize, 1}; - int strides[] = {dims[1] * dims[2], dims[2], 1}; - checkCUDNN(cudnnSetTensorNdDescriptor( - m->xDescs[i], CUDNN_DATA_FLOAT, 3, dims, strides)); - } - size_t workSpaceSize; - checkCUDNN(cudnnGetRNNWorkspaceSize( - m->handle.dnn, m->rnnDesc, seqLength, m->xDescs, &workSpaceSize)); - // Assert that we have enough work space - assert(workSpaceSize <= m->handle.workSpaceSize); - checkCUDNN(cudnnGetRNNTrainingReserveSize( - m->handle.dnn, m->rnnDesc, seqLength, m->xDescs, &m->reserveSpaceSize)); - checkCUDA(cudaMalloc(&m->reserveSpace, m->reserveSpaceSize)); - size_t paramsSize; - checkCUDNN(cudnnGetRNNParamsSize( - m->handle.dnn, m->rnnDesc, m->xDescs[0], ¶msSize, CUDNN_DATA_FLOAT)); - assert(paramsSize == sizeof(float) * para_rect.volume()); - { - int dims[] = {(int)paramsSize, 1, 1}; - checkCUDNN(cudnnCreateFilterDescriptor(&m->wDesc)); - checkCUDNN(cudnnSetFilterNdDescriptor( - m->wDesc, CUDNN_DATA_FLOAT, CUDNN_TENSOR_NCHW, 3, dims)); - } - { - checkCUDNN(cudnnCreateTensorDescriptor(&m->hxDesc)); - checkCUDNN(cudnnCreateTensorDescriptor(&m->cxDesc)); - checkCUDNN(cudnnCreateTensorDescriptor(&m->hyDesc)); - checkCUDNN(cudnnCreateTensorDescriptor(&m->cyDesc)); - int dims[] = {numLayers, lstm->batchSize, lstm->outputSize}; - int strides[] = {dims[1] * dims[2], dims[2], 1}; - checkCUDNN(cudnnSetTensorNdDescriptor( - m->hxDesc, CUDNN_DATA_FLOAT, 3, dims, strides)); - checkCUDNN(cudnnSetTensorNdDescriptor( - m->cxDesc, CUDNN_DATA_FLOAT, 3, dims, strides)); - checkCUDNN(cudnnSetTensorNdDescriptor( - m->hyDesc, CUDNN_DATA_FLOAT, 3, dims, strides)); - checkCUDNN(cudnnSetTensorNdDescriptor( - m->cyDesc, CUDNN_DATA_FLOAT, 3, dims, strides)); - } - for (int i = 0; i < seqLength; i++) { - checkCUDNN(cudnnCreateTensorDescriptor(&m->yDescs[i])); - int dims[] = {lstm->batchSize, lstm->outputSize, 1}; - int strides[] = {dims[1] * dims[2], dims[2], 1}; - checkCUDNN(cudnnSetTensorNdDescriptor( - m->yDescs[i], CUDNN_DATA_FLOAT, 3, dims, strides)); - } - m->profiling_runtime = true; - return m; -#endif -} - -void LSTM::init(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - LSTMInitParams initParams; - initParams.handle = model.dnn_handlers[paraConfig.gpu[idx]]; - initParams.batchSize = outputs[0].pdim[1]; - initParams.inputSize = inputs[0].pdim[0]; - initParams.outputSize = outputs[0].pdim[0]; - // For now assume batch sizes equal - assert(inputs[0].pdim[1] == outputs[0].pdim[1]); - - TaskLauncher launcher(LSTM_INIT_TASK_ID, - TaskArgument(&initParams, sizeof(initParams)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - // add region requirements for x, hx, cx - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[i].region)); - launcher.add_field(i, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.region, READ_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(3, FID_DATA); - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(outputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, outputs[i].region)); - launcher.add_field(4 + i, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - meta[idx] = f.get_result(); - } -} - -/* - regions[0] (I): x - regions[1] (I): hx - regions[2] (I): cx - regions[3] (I): w - regions[4] (O): y - regions[5] (O): hy - regions[6] (O): cy -*/ -void LSTM::forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 7); - assert(task->regions.size() == 7); - LSTMMeta const *m = *((LSTMMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRO const acc_hx(regions[1], FID_DATA); - AccessorRO const acc_cx(regions[2], FID_DATA); - AccessorRO const acc_w(regions[3], FID_DATA); - AccessorWO const acc_y(regions[4], FID_DATA); - AccessorWO const acc_hy(regions[5], FID_DATA); - AccessorWO const acc_cy(regions[6], FID_DATA); - Rect<3> rect_x, rect_y; - Rect<2> rect_hx, rect_cx, rect_hy, rect_cy; - Rect<1> rect_w; - rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - rect_hx = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - rect_cx = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - rect_w = runtime->get_index_space_domain( - ctx, task->regions[3].region.get_index_space()); - rect_y = runtime->get_index_space_domain( - ctx, task->regions[4].region.get_index_space()); - rect_hy = runtime->get_index_space_domain( - ctx, task->regions[5].region.get_index_space()); - rect_cy = runtime->get_index_space_domain( - ctx, task->regions[6].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_hx.accessor.is_dense_arbitrary(rect_hx)); - assert(acc_cx.accessor.is_dense_arbitrary(rect_cx)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - assert(acc_hy.accessor.is_dense_arbitrary(rect_hy)); - assert(acc_cy.accessor.is_dense_arbitrary(rect_cy)); - assert(rect_hx == rect_cx); - assert(rect_hx == rect_hy); - assert(rect_hx == rect_cy); - float const *x_ptr = acc_x.ptr(rect_x.lo); - float const *hx_ptr = acc_hx.ptr(rect_hx.lo); - float const *cx_ptr = acc_cx.ptr(rect_cx.lo); - float const *w_ptr = acc_w.ptr(rect_w.lo); - float *y_ptr = acc_y.ptr(rect_y.lo); - float *hy_ptr = acc_hy.ptr(rect_hy.lo); - float *cy_ptr = acc_cy.ptr(rect_cy.lo); - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); - checkCUDNN(cudnnRNNForwardTraining(m->handle.dnn, - m->rnnDesc, - LSTM_PER_NODE_LENGTH /*seqLength*/, - m->xDescs, - x_ptr, - m->hxDesc, - hx_ptr, - m->cxDesc, - cx_ptr, - m->wDesc, - w_ptr, - m->yDescs, - y_ptr, - m->hyDesc, - hy_ptr, - m->cyDesc, - cy_ptr, - m->handle.workSpace, - m->handle.workSpaceSize, - m->reserveSpace, - m->reserveSpaceSize)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("LSTM forward time = %.2fms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<3, float>(y_ptr, rect_y, "lstm_fwd:y"); -#endif -#endif -} - -void LSTM::forward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(LSTM_FWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - // add region requirements for x, hx, cx - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[i].region)); - launcher.add_field(i, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.region, READ_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(3, FID_DATA); - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(outputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, outputs[i].region)); - launcher.add_field(4 + i, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -/* - regions[0] (I): x - regions[1] (I): hx - regions[2] (I): cx - regions[3] (I): w - regions[4] (I): y - regions[5] (I): hy - regions[6] (I): cy - regions[7] (O): x_grad - regions[8] (O): hx_grad - regions[9] (O): cx_grad - regions[10] (I/O): w_grad - regions[11] (I): y_grad - regions[12] (I): hy_grad - regions[13] (I): cy_grad -*/ -void LSTM::backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 14); - assert(task->regions.size() == 14); - LSTMMeta const *m = *((LSTMMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorRO const acc_hx(regions[1], FID_DATA); - AccessorRO const acc_cx(regions[2], FID_DATA); - AccessorRO const acc_w(regions[3], FID_DATA); - AccessorRO const acc_y(regions[4], FID_DATA); - AccessorRO const acc_hy(regions[5], FID_DATA); - AccessorRO const acc_cy(regions[6], FID_DATA); - AccessorWO const acc_x_grad(regions[7], FID_DATA); - AccessorWO const acc_hx_grad(regions[8], FID_DATA); - AccessorWO const acc_cx_grad(regions[9], FID_DATA); - AccessorRW const acc_w_grad(regions[10], FID_DATA); - AccessorRO const acc_y_grad(regions[11], FID_DATA); - AccessorRO const acc_hy_grad(regions[12], FID_DATA); - AccessorRO const acc_cy_grad(regions[13], FID_DATA); - - Rect<3> rect_x, rect_y, rect_x_grad, rect_y_grad; - Rect<2> rect_hx, rect_cx, rect_hy, rect_cy, rect_hx_grad, rect_cx_grad, - rect_hy_grad, rect_cy_grad; - Rect<1> rect_w, rect_w_grad; - rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - rect_hx = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - rect_cx = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - rect_w = runtime->get_index_space_domain( - ctx, task->regions[3].region.get_index_space()); - rect_y = runtime->get_index_space_domain( - ctx, task->regions[4].region.get_index_space()); - rect_hy = runtime->get_index_space_domain( - ctx, task->regions[5].region.get_index_space()); - rect_cy = runtime->get_index_space_domain( - ctx, task->regions[6].region.get_index_space()); - rect_x_grad = runtime->get_index_space_domain( - ctx, task->regions[7].region.get_index_space()); - rect_hx_grad = runtime->get_index_space_domain( - ctx, task->regions[8].region.get_index_space()); - rect_cx_grad = runtime->get_index_space_domain( - ctx, task->regions[9].region.get_index_space()); - rect_w_grad = runtime->get_index_space_domain( - ctx, task->regions[10].region.get_index_space()); - rect_y_grad = runtime->get_index_space_domain( - ctx, task->regions[11].region.get_index_space()); - rect_hy_grad = runtime->get_index_space_domain( - ctx, task->regions[12].region.get_index_space()); - rect_cy_grad = runtime->get_index_space_domain( - ctx, task->regions[13].region.get_index_space()); - - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_hx.accessor.is_dense_arbitrary(rect_hx)); - assert(acc_cx.accessor.is_dense_arbitrary(rect_cx)); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - assert(acc_hy.accessor.is_dense_arbitrary(rect_hy)); - assert(acc_cy.accessor.is_dense_arbitrary(rect_cy)); - assert(acc_x_grad.accessor.is_dense_arbitrary(rect_x_grad)); - assert(acc_hx_grad.accessor.is_dense_arbitrary(rect_hx_grad)); - assert(acc_cx_grad.accessor.is_dense_arbitrary(rect_cx_grad)); - assert(acc_w_grad.accessor.is_dense_arbitrary(rect_w_grad)); - assert(acc_y_grad.accessor.is_dense_arbitrary(rect_y_grad)); - assert(acc_hy_grad.accessor.is_dense_arbitrary(rect_hy_grad)); - assert(acc_cy_grad.accessor.is_dense_arbitrary(rect_cy_grad)); - - float const *x_ptr = acc_x.ptr(rect_x.lo); - float const *hx_ptr = acc_hx.ptr(rect_hx.lo); - float const *cx_ptr = acc_cx.ptr(rect_cx.lo); - float const *w_ptr = acc_w.ptr(rect_w.lo); - float const *y_ptr = acc_y.ptr(rect_y.lo); - float const *hy_ptr = acc_hy.ptr(rect_hy.lo); - float const *cy_ptr = acc_cy.ptr(rect_cy.lo); - float *x_grad_ptr = acc_x_grad.ptr(rect_x_grad.lo); - float *hx_grad_ptr = acc_hx_grad.ptr(rect_hx_grad.lo); - float *cx_grad_ptr = acc_cx_grad.ptr(rect_cx_grad.lo); - float *w_grad_ptr = acc_w_grad.ptr(rect_w_grad.lo); - float const *y_grad_ptr = acc_y_grad.ptr(rect_y_grad.lo); - float const *hy_grad_ptr = acc_hy_grad.ptr(rect_hy_grad.lo); - float const *cy_grad_ptr = acc_cy_grad.ptr(rect_cy_grad.lo); - - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); - checkCUDNN(cudnnRNNBackwardData(m->handle.dnn, - m->rnnDesc, - LSTM_PER_NODE_LENGTH /*seqLength*/, - m->yDescs, - y_ptr, - m->yDescs, - y_grad_ptr, - m->hyDesc, - hy_grad_ptr, - m->cyDesc, - cy_grad_ptr, - m->wDesc, - w_ptr, - m->hxDesc, - hx_ptr, - m->cxDesc, - cx_ptr, - m->xDescs, - x_grad_ptr, - m->hxDesc, - hx_grad_ptr, - m->cxDesc, - cx_grad_ptr, - m->handle.workSpace, - m->handle.workSpaceSize, - m->reserveSpace, - m->reserveSpaceSize)); - checkCUDNN(cudnnRNNBackwardWeights(m->handle.dnn, - m->rnnDesc, - LSTM_PER_NODE_LENGTH /*seqLength*/, - m->xDescs, - x_ptr, - m->hxDesc, - hx_ptr, - m->yDescs, - y_ptr, - m->handle.workSpace, - m->handle.workSpaceSize, - m->wDesc, - w_grad_ptr, - m->reserveSpace, - m->reserveSpaceSize)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("LSTM backward time = %.2fms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<1, float>(w_grad_ptr, rect_w_grad, "lstm_bwd:w_grad"); - print_tensor<3, float>(x_grad_ptr, rect_x_grad, "lstm_bwd:x_grad"); - print_tensor<2, float>(hx_grad_ptr, rect_hx_grad, "lstm_bwd:hx_grad"); - print_tensor<2, float>(cx_grad_ptr, rect_cx_grad, "lstm_bwd:cx_grad"); -#endif -#endif -} - -void LSTM::backward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - DomainPoint dp(*it); - TaskLauncher launcher(LSTM_BWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - // add region requirements for x, hx, cx - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[i].region)); - launcher.add_field(i, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.region, READ_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(3, FID_DATA); - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(outputs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, outputs[i].region)); - launcher.add_field(4 + i, FID_DATA); - } - // add region requirements for gradients - for (int i = 0; i < 3; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(inputs[i].partition_grad, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, inputs[i].region_grad)); - launcher.add_field(7 + i, FID_DATA); - } - launcher.add_region_requirement( - RegionRequirement(params.gradients[paraConfig.gpu[idx]], - READ_WRITE, - EXCLUSIVE, - params.gradients[paraConfig.gpu[idx]])); - launcher.add_field(10, FID_DATA); - for (int i = 0; i < 3; i++) { - LogicalRegion x = runtime->get_logical_subregion_by_color( - outputs[i].partition_grad, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, outputs[i].region_grad)); - launcher.add_field(11 + i, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -void LSTM::update(RnnModel const &model) {} diff --git a/nmt/nmt.cc b/nmt/nmt.cc deleted file mode 100644 index cc8c09024b..0000000000 --- a/nmt/nmt.cc +++ /dev/null @@ -1,359 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "rnn.h" -#include "rnn_mapper.h" -#include - -using namespace Legion; - -LegionRuntime::Logger::Category log_nmt("nmt"); - -void parse_input_args(char **argv, - int argc, - int &batch_size, - int &num_layers, - int &seq_length, - int &hidden_size, - int &embed_size); - -void set_global_config(GlobalConfig &global, - int num_layers, - int seq_length, - int workers_per_node, - int num_nodes); - -void top_level_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - int bs_per_worker = 64; - int num_layers = 2; - int seq_length = 20; - int hidden_size = 2048; - int embed_size = 2048; - int vocab_size = 20 * 1024; - int num_nodes = 1; - int workers_per_node = 1; - int num_parts = workers_per_node * num_nodes; - int batch_size = bs_per_worker * num_parts; - int num_iterations = 10; - { - InputArgs const &command_args = HighLevelRuntime::get_input_args(); - char **argv = command_args.argv; - int argc = command_args.argc; - parse_input_args(argv, - argc, - batch_size, - num_layers, - seq_length, - hidden_size, - embed_size); - } - GlobalConfig global; - set_global_config( - global, num_layers, seq_length, workers_per_node, num_nodes); - RnnModel model(batch_size, - num_layers, - seq_length, - hidden_size, - embed_size, - vocab_size, - num_parts, - num_nodes, - workers_per_node, - global, - ctx, - runtime); - ArgumentMap local_args; - size_t workSpaceSize = (size_t)2 * 1024 * 1024 * 1024; - Rect<1> workers_rect(Point<1>(0), Point<1>(num_nodes * workers_per_node - 1)); - int idx = 0; - for (PointInRectIterator<1> it(workers_rect); it(); it++) { - TaskLauncher launcher(CUDNN_INIT_TASK_ID, - TaskArgument(&workSpaceSize, sizeof(workSpaceSize)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(idx)); - Future f = runtime->execute_task(ctx, launcher); - model.dnn_handlers[idx++] = f.get_result(); - } - - model.init(); - double ts_start = Realm::Clock::current_time_in_microseconds(); - for (int i = 0; i < num_iterations; i++) { - model.forward(); - model.backward(); - model.update(); - } - runtime->issue_execution_fence(ctx); - TimingLauncher timer(MEASURE_MICRO_SECONDS); - Future future = runtime->issue_timing_measurement(ctx, timer); - future.get_void_result(); - double ts_end = Realm::Clock::current_time_in_microseconds(); - double run_time = 1e-6 * (ts_end - ts_start); - printf("time = %.4fs\n", run_time); -} - -int main(int argc, char **argv) { - Runtime::set_top_level_task_id(TOP_LEVEL_TASK_ID); - { - TaskVariantRegistrar registrar(TOP_LEVEL_TASK_ID, "top_level"); - registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); - // registrar.set_inner(); - Runtime::preregister_task_variant(registrar, "top_level"); - } - - // DNN_INIT_TASK - { - TaskVariantRegistrar registrar(CUDNN_INIT_TASK_ID, "cudnn_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "cudnn_init_task"); - } - // - { - TaskVariantRegistrar registrar(WORD_INIT_TASK_ID, "word_init_task(dummy)"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "word_init_task(dummy)"); - } - // Word Embedding task - { - TaskVariantRegistrar registrar(EMBED_INIT_TASK_ID, "embed_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "embed_init_task"); - } - { - TaskVariantRegistrar registrar(EMBED_FWD_TASK_ID, "embed_fwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "embed_fwd_task"); - } - { - TaskVariantRegistrar registrar(EMBED_BWD_TASK_ID, "embed_bwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "embed_bwd_task"); - } - // LSTM task - { - TaskVariantRegistrar registrar(LSTM_INIT_TASK_ID, "lstm_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "lstm_init_task"); - } - { - TaskVariantRegistrar registrar(LSTM_FWD_TASK_ID, "lstm_fwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "lstm_fwd_task"); - } - { - TaskVariantRegistrar registrar(LSTM_BWD_TASK_ID, "lstm_bwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "lstm_bwd_task"); - } - // Rnn Linear task - { - TaskVariantRegistrar registrar(RNN_LINEAR_INIT_TASK_ID, "linear_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "linear_init_task"); - } - { - TaskVariantRegistrar registrar(RNN_LINEAR_FWD_TASK_ID, "linar_fwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "linear_fwd_task"); - } - { - TaskVariantRegistrar registrar(RNN_LINEAR_BWD_TASK_ID, "linear_bwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "linear_bwd_task"); - } - { - TaskVariantRegistrar registrar(RNN_LINEAR_BWD2_TASK_ID, "linear_bwd2_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "linear_bwd2_task"); - } - // Softmax (Data Parallel Implementation) task - { - TaskVariantRegistrar registrar(RNN_SOFTMAXDP_INIT_TASK_ID, - "softmaxDP_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "softmaxDP_init_task"); - } - { - TaskVariantRegistrar registrar(RNN_SOFTMAXDP_FWD_TASK_ID, - "softmaxDP_fwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "softmaxDP_fwd_task"); - } - { - TaskVariantRegistrar registrar(RNN_SOFTMAXDP_BWD_TASK_ID, - "softmaxDP_bwd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "softmaxDP_bwd_task"); - } - // Params related tasks - { - TaskVariantRegistrar registrar(PARAMS_INIT_TASK_ID, "params_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "params_init_task"); - } - { - TaskVariantRegistrar registrar(ZERO_1D_INIT_TASK_ID, "zero_1d_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "zero_1d_init_task"); - } - { - TaskVariantRegistrar registrar(ZERO_2D_INIT_TASK_ID, "zero_2d_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "zero_2d_init_task"); - } - { - TaskVariantRegistrar registrar(ZERO_3D_INIT_TASK_ID, "zero_3d_init_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "zero_3d_init_task"); - } - { - TaskVariantRegistrar registrar(PARAMS_UPD_TASK_ID, "params_upd_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant( - registrar, "params_upd_task"); - } - // Dummy tasks - { - TaskVariantRegistrar registrar(DUMMY_TASK_ID, "dummy_task"); - registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); - registrar.set_leaf(); - Runtime::preregister_task_variant(registrar, - "dummy_task"); - } - - Runtime::add_registration_callback(update_mappers); - return Runtime::start(argc, argv); -} - -void parse_input_args(char **argv, - int argc, - int &batch_size, - int &num_layers, - int &seq_length, - int &hidden_size, - int &embed_size) { - for (int i = 1; i < argc; i++) { - if (!strcmp(argv[i], "-b")) { - batch_size = atoi(argv[++i]); - continue; - } - if (!strcmp(argv[i], "-l")) { - num_layers = atoi(argv[++i]); - continue; - } - if (!strcmp(argv[i], "-s")) { - seq_length = atoi(argv[++i]); - continue; - } - if (!strcmp(argv[i], "-h")) { - hidden_size = atoi(argv[++i]); - continue; - } - if (!strcmp(argv[i], "-e")) { - embed_size = atoi(argv[++i]); - continue; - } - } -} - -void set_global_config(GlobalConfig &global, - int num_layers, - int seq_length, - int workers_per_node, - int num_nodes) { - int num_parts = workers_per_node * num_nodes; - for (int i = 0; i * LSTM_PER_NODE_LENGTH < 2 * seq_length; i++) { - ParallelConfig pc; - pc.nDims = 1; - pc.dim[0] = num_parts; - for (int j = 0; j < num_parts; j++) { - pc.gpu[j] = i * LSTM_PER_NODE_LENGTH < seq_length ? 0 : 1; - } - // pc.gpu[j] = j; - global.embed[i] = pc; - } - for (int i = 0; i < num_layers; i++) { - for (int j = 0; j * LSTM_PER_NODE_LENGTH < 2 * seq_length; j++) { - ParallelConfig pc; - pc.nDims = 1; - pc.dim[0] = num_parts; - for (int k = 0; k < num_parts; k++) { - pc.gpu[k] = k; - } - global.lstm[i][j] = pc; - } - } - for (int i = 0; i * LSTM_PER_NODE_LENGTH < seq_length; i++) { - ParallelConfig pc; - pc.nDims = 2; - pc.dim[0] = 1; - pc.dim[1] = num_parts; - for (int j = 0; j < num_parts; j++) { - pc.gpu[j] = j; - } - global.linear[i] = pc; - } - for (int i = 0; i * LSTM_PER_NODE_LENGTH < seq_length; i++) { - ParallelConfig pc; - pc.nDims = 1; - pc.dim[0] = num_parts; - for (int j = 0; j < num_parts; j++) { - pc.gpu[j] = j; - } - global.softmax[i] = pc; - } -} diff --git a/nmt/ops.h b/nmt/ops.h deleted file mode 100644 index d6faf662a0..0000000000 --- a/nmt/ops.h +++ /dev/null @@ -1,177 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#ifndef _LEGION_CNN_OPS_H_ -#define _LEGION_CNN_OPS_H_ - -// #define DISABLE_COMPUTATION -#include "legion.h" -#include -#include -#include -#include -#include -using namespace Legion; - -template -using AccessorRO = - FieldAccessor>; -template -using AccessorRW = - FieldAccessor>; -template -using AccessorWO = - FieldAccessor>; - -#define MAX_NUM_INPUTS 6 -#define MAX_NUM_OUTPUTS 6 -#define MAX_NUM_LOCALS 3 -#define MAX_NUM_WORKERS 16 -#define MAX_NUM_PARTS 16 -#define MAX_DIM 4 -#define MAX_FILENAME 200 - -enum TaskIDs { - TOP_LEVEL_TASK_ID, - CUDNN_INIT_TASK_ID, - IMAGE_INIT_TASK_ID, - LABEL_INIT_TASK_ID, - LOAD_IMAGES_TASK_ID, - NORMALIZE_IMAGES_TASK_ID, - CONV2D_INIT_TASK_ID, - CONV2D_INIT_PARA_TASK_ID, - CONV2D_FWD_TASK_ID, - CONV2D_BWD_TASK_ID, - CONV2D_UPD_TASK_ID, - POOL2D_INIT_TASK_ID, - POOL2D_FWD_TASK_ID, - POOL2D_BWD_TASK_ID, - LINEAR_INIT_TASK_ID, - LINEAR_INIT_PARA_TASK_ID, - LINEAR_FWD_TASK_ID, - LINEAR_BWD_TASK_ID, - LINEAR_BWD2_TASK_ID, - LINEAR_UPD_TASK_ID, - FLAT_INIT_TASK_ID, - FLAT_FWD_TASK_ID, - FLAT_BWD_TASK_ID, - SOFTMAX_INIT_TASK_ID, - SOFTMAX_FWD_TASK_ID, - SOFTMAX_BWD_TASK_ID, - CONCAT_INIT_TASK_ID, - CONCAT_FWD_TASK_ID, - CONCAT_BWD_TASK_ID, - // RNN Task IDs - LSTM_INIT_TASK_ID, - LSTM_FWD_TASK_ID, - LSTM_BWD_TASK_ID, - RNN_LINEAR_INIT_TASK_ID, - RNN_LINEAR_FWD_TASK_ID, - RNN_LINEAR_BWD_TASK_ID, - RNN_LINEAR_BWD2_TASK_ID, - EMBED_INIT_TASK_ID, - EMBED_FWD_TASK_ID, - EMBED_BWD_TASK_ID, - RNN_SOFTMAXDP_INIT_TASK_ID, - RNN_SOFTMAXDP_FWD_TASK_ID, - RNN_SOFTMAXDP_BWD_TASK_ID, - PARAMS_INIT_TASK_ID, - PARAMS_UPD_TASK_ID, - WORD_INIT_TASK_ID, // DUMMY_TASK_ID: To be removed - ZERO_1D_INIT_TASK_ID, - ZERO_2D_INIT_TASK_ID, - ZERO_3D_INIT_TASK_ID, - // Dummy task ID - DUMMY_TASK_ID, -}; - -enum Pool2DType { - POOL2D_MAX, - POOL2D_AVG, -}; - -enum FieldIDs { - FID_DATA, -}; - -struct DnnHandle { -#ifndef DISABLE_COMPUTATION - cudnnHandle_t dnn; - cublasHandle_t blas; -#endif - void *workSpace; - size_t workSpaceSize; -}; - -struct Tensor { - // Tensor(int _numDim, int* _dim, LogicalRegion lr, LogicalPartition lp) - // { - // numDim = _numDim; - // for (int i = 0; i < numDim; i++) - // dim[i] = _dim[i]; - // region = lr; - // partition = lp; - // } - int numDim, adim[MAX_DIM], pdim[MAX_DIM]; - LogicalRegion region, region_grad; - LogicalPartition partition, partition_grad; -}; - -struct TensorWithGrad { - // int dim[MAX_DIM]; - LogicalRegion region, region_grad; - LogicalPartition partition, partition_grad; -}; - -class OpMeta { -public: - OpMeta(DnnHandle _handle) : handle(_handle){}; - -public: - DnnHandle handle; -}; - -// Empty base class -class CnnModel; -class DataLoader; - -class Op { -public: - Op(Tensor input); - Op(int num, Tensor *inputs); - virtual void init(CnnModel const &) = 0; - - virtual void forward(CnnModel const &) = 0; - - virtual void backward(CnnModel const &) = 0; - - virtual void update(CnnModel const &) = 0; - -public: - Tensor output; - // Op* pre_ops[MAX_NUM_INPUTS]; - Tensor inputs[MAX_NUM_INPUTS]; - LogicalPartition input_lps[MAX_NUM_INPUTS]; - TensorWithGrad locals[MAX_NUM_LOCALS]; - OpMeta *meta[MAX_NUM_WORKERS]; - // std::vector inputs, grads; -}; - -DnnHandle init_cudnn(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - -#endif // _LEGION_OPS_H_ diff --git a/nmt/rnn.cu b/nmt/rnn.cu deleted file mode 100644 index 3d59116833..0000000000 --- a/nmt/rnn.cu +++ /dev/null @@ -1,770 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "../cnn_helper.h" -#include "rnn.h" -#include "rnn_mapper.h" - -DnnHandle init_cudnn(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime) { - assert(regions.size() == 0); - assert(task->arglen == sizeof(size_t)); - size_t workSpaceSize = *(size_t const *)task->args; - DnnHandle handle; - handle.workSpaceSize = workSpaceSize; - printf("workSpaceSize = %zu\n", workSpaceSize); -#ifndef DISABLE_COMPUTATION - checkCUDA(cublasCreate(&handle.blas)); - checkCUDNN(cudnnCreate(&handle.dnn)); -#endif - checkCUDA(cudaMalloc(&handle.workSpace, workSpaceSize)); - return handle; -} - -const SharedVariable SharedVariable::NO_VARIABLE = SharedVariable(); - -RnnOp::RnnOp(Tensor input, ParallelConfig pc, SharedVariable _params) - : paraConfig(pc), params(_params) { - inputs[0] = input; -} - -RnnOp::RnnOp( - Tensor t1, Tensor t2, Tensor t3, ParallelConfig pc, SharedVariable _params) - : paraConfig(pc), params(_params) { - inputs[0] = t1; - inputs[1] = t2; - inputs[2] = t3; -} - -RnnOp::RnnOp(int n, Tensor *_inputs) { - for (int i = 0; i < n; i++) { - inputs[i] = _inputs[i]; - } -} - -RnnModel::RnnModel(int batch_size, - int numLayers, - int seqLength, - int hidden_size, - int embed_size, - int vocab_size, - int num_parts, - int num_nodes, - int num_gpus_per_node, - GlobalConfig global, - Context ctx, - Runtime *runtime) { - config.lg_ctx = ctx; - config.lg_hlr = runtime; - config.batchSize = batch_size; - config.hiddenSize = hidden_size; - config.embedSize = embed_size; - config.vocabSize = vocab_size; - config.numLayers = numLayers; - config.seqLength = seqLength; - config.numParts = num_parts; - config.numNodes = num_nodes; - config.workersPerNode = num_gpus_per_node; - config.field_space = runtime->create_field_space(ctx); - { - FieldAllocator allocator = - runtime->create_field_allocator(ctx, config.field_space); - allocator.allocate_field(sizeof(float), FID_DATA); - } - Rect<1> part_rect(Point<1>(0), Point<1>(num_parts - 1)); - part_is = runtime->create_index_space(ctx, part_rect); - assert(seqLength <= MAX_SEQ_LENGTH); - assert(numLayers <= MAX_NUM_LAYERS); - int nodes_per_layer = seqLength / LSTM_PER_NODE_LENGTH; - // Create srcs/dsts tensors - { - Rect<2> word_rect(Point<2>(0, 0), - Point<2>(batch_size - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexSpaceT<2> word_is = runtime->create_index_space(ctx, word_rect); - int extent_n = batch_size / num_parts; - Rect<2, coord_t> extent(Point<2>(0, 0), - Point<2>(extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - Transform<2, 1, coord_t> trans; - trans[0][0] = extent_n; - trans[1][0] = 0; - IndexPartition word_ip = runtime->create_partition_by_restriction( - ctx, word_is, part_is, trans, extent); - assert(runtime->is_index_partition_disjoint(ctx, word_ip)); - assert(runtime->is_index_partition_complete(ctx, word_ip)); - assert(seqLength % LSTM_PER_NODE_LENGTH == 0); - for (int i = 0; i < nodes_per_layer; i++) { - srcs[i].numDim = 2; - srcs[i].adim[0] = batch_size; - srcs[i].adim[1] = LSTM_PER_NODE_LENGTH; - srcs[i].pdim[0] = extent_n; - srcs[i].pdim[1] = LSTM_PER_NODE_LENGTH; - srcs[i].region = - runtime->create_logical_region(ctx, word_is, config.field_space); - srcs[i].partition = - runtime->get_logical_partition(ctx, srcs[i].region, word_ip); - srcs[i].region_grad = - runtime->create_logical_region(ctx, word_is, config.field_space); - srcs[i].partition_grad = - runtime->get_logical_partition(ctx, srcs[i].region_grad, word_ip); - dsts[i] = srcs[i]; - dsts[i].region = - runtime->create_logical_region(ctx, word_is, config.field_space); - dsts[i].partition = - runtime->get_logical_partition(ctx, dsts[i].region, word_ip); - dsts[i].region_grad = - runtime->create_logical_region(ctx, word_is, config.field_space); - dsts[i].partition_grad = - runtime->get_logical_partition(ctx, dsts[i].region_grad, word_ip); - } - } - // Create zeroed tensors - { - Rect<2> hx_rect(Point<2>(0, 0), Point<2>(hidden_size - 1, batch_size - 1)); - IndexSpaceT<2> hx_is = runtime->create_index_space(ctx, hx_rect); - int extent_c = hidden_size; - int extent_n = batch_size / num_parts; - Rect<2> hx_ext(Point<2>(0, 0), Point<2>(extent_c - 1, extent_n - 1)); - Transform<2, 1, coord_t> hx_trans; - hx_trans[0][0] = 0; - hx_trans[1][0] = extent_n; - IndexPartition hx_ip = runtime->create_partition_by_restriction( - ctx, hx_is, part_is, hx_trans, hx_ext); - assert(runtime->is_index_partition_disjoint(ctx, hx_ip)); - assert(runtime->is_index_partition_complete(ctx, hx_ip)); - for (int i = 0; i < numLayers; i++) { - for (int j = 0; j < 2; j++) { - Tensor t; - t.numDim = 2; - t.adim[0] = hidden_size; - t.adim[1] = batch_size; - t.pdim[0] = extent_c; - t.pdim[1] = extent_n; - t.region = - runtime->create_logical_region(ctx, hx_is, config.field_space); - t.partition = runtime->get_logical_partition(ctx, t.region, hx_ip); - t.region_grad = - runtime->create_logical_region(ctx, hx_is, config.field_space); - t.partition_grad = - runtime->get_logical_partition(ctx, t.region_grad, hx_ip); - if (j == 0) { - zero[i].hx = t; - } else { - zero[i].cx = t; - } - } - } - } - // Embedding - SharedVariable srcEmbed, dstEmbed; - { - int numParams = config.vocabSize * config.embedSize; - Rect<1> params_rect(Point<1>(0), Point<1>(numParams - 1)); - IndexSpaceT<1> params_is = runtime->create_index_space(ctx, params_rect); - srcEmbed.region = - runtime->create_logical_region(ctx, params_is, config.field_space); - dstEmbed.region = - runtime->create_logical_region(ctx, params_is, config.field_space); - for (int i = 0; i < 2 * nodes_per_layer; i++) { - ParallelConfig pc = global.embed[i]; - assert(pc.nDims == 1); - for (int j = 0; j < pc.dim[0]; j++) { - int gpuId = pc.gpu[j]; - if (i < nodes_per_layer) { - if (srcEmbed.gradients[gpuId] == LogicalRegion::NO_REGION) { - srcEmbed.gradients[gpuId] = runtime->create_logical_region( - ctx, params_is, config.field_space); - } - } else { - if (dstEmbed.gradients[gpuId] == LogicalRegion::NO_REGION) { - dstEmbed.gradients[gpuId] = runtime->create_logical_region( - ctx, params_is, config.field_space); - } - } - } - } - // Collect masterOnNode for srcEmbed/dstEmbed - for (int i = 0; i < config.numNodes; i++) { - for (int j = config.workersPerNode - 1; j >= 0; j--) { - int gpuId = i * config.workersPerNode + j; - if (srcEmbed.gradients[gpuId] != LogicalRegion::NO_REGION) { - srcEmbed.masterOnNode[i] = gpuId; - } - if (dstEmbed.gradients[gpuId] != LogicalRegion::NO_REGION) { - dstEmbed.masterOnNode[i] = gpuId; - } - } - } - } - - // Encoders/decoders - SharedVariable encoders[MAX_NUM_LAYERS], decoders[MAX_NUM_LAYERS]; - for (int i = 0; i < numLayers; i++) { - int input_size = (i == 0) ? embed_size : hidden_size; - int output_size = hidden_size; - int numParams = (input_size + 1 + output_size + 1) * output_size * 4; - Rect<1> params_rect(Point<1>(0), Point<1>(numParams - 1)); - IndexSpaceT<1> params_is = runtime->create_index_space(ctx, params_rect); - encoders[i].region = - runtime->create_logical_region(ctx, params_is, config.field_space); - decoders[i].region = - runtime->create_logical_region(ctx, params_is, config.field_space); - for (int j = 0; j < 2 * nodes_per_layer; j++) { - ParallelConfig pc = global.lstm[i][j]; - assert(pc.nDims == 1); - for (int k = 0; k < pc.dim[0]; k++) { - int gpuId = pc.gpu[k]; - if (j < nodes_per_layer) { - if (encoders[i].gradients[gpuId] == LogicalRegion::NO_REGION) { - encoders[i].gradients[gpuId] = runtime->create_logical_region( - ctx, params_is, config.field_space); - } - } else { - if (decoders[i].gradients[gpuId] == LogicalRegion::NO_REGION) { - decoders[i].gradients[gpuId] = runtime->create_logical_region( - ctx, params_is, config.field_space); - } - } - } - } - // Collect masterOnNode for encoders[i]/decoders[i] - for (int j = 0; j < config.numNodes; j++) { - for (int k = config.workersPerNode - 1; k >= 0; k--) { - int gpuId = j * config.workersPerNode + k; - if (encoders[i].gradients[gpuId] != LogicalRegion::NO_REGION) { - encoders[i].masterOnNode[j] = gpuId; - } - if (decoders[i].gradients[gpuId] != LogicalRegion::NO_REGION) { - decoders[i].masterOnNode[j] = gpuId; - } - } - } - } - SharedVariable linear; - { - int numParams = (hidden_size + 1) * vocab_size; - Rect<1> params_rect(Point<1>(0), Point<1>(numParams - 1)); - IndexSpaceT<1> params_is = runtime->create_index_space(ctx, params_rect); - linear.region = - runtime->create_logical_region(ctx, params_is, config.field_space); - linear.subregions[1] = linear.region; - // Create subregions for the shared variable linear - for (int parts = 2; parts <= MAX_NUM_PARTS; parts *= 2) { - Rect<1> rect(Point<1>(0), Point<1>(parts - 1)); - IndexSpaceT<1> is = runtime->create_index_space(ctx, rect); - IndexPartition ip = runtime->create_equal_partition(ctx, params_is, is); - LogicalPartition lp = - runtime->get_logical_partition(ctx, linear.region, ip); - int idx = 0; - for (PointInRectIterator<1> it(rect); it(); it++, idx++) { - DomainPoint dp(*it); - linear.subregions[parts + idx] = - runtime->get_logical_subregion_by_color(ctx, lp, dp); - } - } - // Compute bboxes for the shared variable linear - // Also compute masterOnNode which is the largest gradients on each node - std::map> bboxes; - for (int i = 0; i < nodes_per_layer; i++) { - ParallelConfig pc = global.linear[i]; - assert(pc.nDims == 2); - for (int j = 0; j < pc.dim[1]; j++) { - for (int k = 0; k < pc.dim[0]; k++) { - int gpuIdx = pc.gpu[j * pc.dim[0] + k]; - Rect<1> rect = runtime->get_index_space_domain( - ctx, linear.subregions[pc.dim[0] + k].get_index_space()); - if (bboxes.find(gpuIdx) == bboxes.end()) { - bboxes[gpuIdx] = rect; - } else { - bboxes[gpuIdx] = bboxes[gpuIdx].union_bbox(rect); - } - int nodeIdx = gpuIdx / config.workersPerNode; - if (linear.masterOnNode[nodeIdx] == MASTER_NOT_ASSIGNED) { - linear.masterOnNode[nodeIdx] = gpuIdx; - } else { - int masterIdx = linear.masterOnNode[nodeIdx]; - if (bboxes[gpuIdx].volume() > bboxes[masterIdx].volume()) { - linear.masterOnNode[nodeIdx] = gpuIdx; - } - } - } - } - } - // The first bbox on each node is a superset of all bboxes on that node - for (int n = 0; n < config.numNodes; n++) { - if (linear.masterOnNode[n] != MASTER_NOT_ASSIGNED) { - for (int j = 0; j < config.workersPerNode; j++) { - if (bboxes.find(n * config.workersPerNode + j) != bboxes.end()) { - Rect<1> rect = bboxes[n * config.workersPerNode + j]; - bboxes[linear.masterOnNode[n]] = - bboxes[linear.masterOnNode[n]].union_bbox(rect); - } - } - } - } - for (int i = 0; i < config.numNodes * config.workersPerNode; i++) { - if (bboxes.find(i) != bboxes.end()) { - IndexSpaceT<1> params_is = runtime->create_index_space(ctx, bboxes[i]); - linear.gradients[i] = - runtime->create_logical_region(ctx, params_is, config.field_space); - } else { - linear.gradients[i] = LogicalRegion::NO_REGION; - } - } - } - - Tensor embed[2 * MAX_SEQ_LENGTH]; - for (int i = 0; i < 2 * nodes_per_layer; i++) { - embed[i] = add_embed_node(i < nodes_per_layer ? srcs[i] - : dsts[i - nodes_per_layer], - config.vocabSize, - config.embedSize, - global.embed[i], - i < nodes_per_layer ? srcEmbed : dstEmbed); - } - for (int i = 0; i < numLayers; i++) { - // Add encoder lstm nodes - for (int j = 0; j < nodes_per_layer; j++) { - Tensor x = (i == 0) ? embed[j] : lstm[i - 1][j].x; - Tensor hx = (j == 0) ? zero[i].hx : lstm[i][j - 1].hx; - Tensor cx = (j == 0) ? zero[i].cx : lstm[i][j - 1].cx; - lstm[i][j] = add_lstm_node(x, hx, cx, global.lstm[i][j], encoders[i]); - } - // Add decoder lstm nodes - for (int j = nodes_per_layer; j < 2 * nodes_per_layer; j++) { - Tensor x = (i == 0) ? embed[j] : lstm[i - 1][j].x; - Tensor hx = lstm[i][j - 1].hx; - Tensor cx = lstm[i][j - 1].cx; - lstm[i][j] = add_lstm_node(x, hx, cx, global.lstm[i][j], decoders[i]); - } - } - // Add linear nodes - for (int j = nodes_per_layer; j < 2 * nodes_per_layer; j++) { - Tensor logit = add_linear_node(lstm[numLayers - 1][j].x, - vocab_size, - global.linear[j - nodes_per_layer], - linear); - add_softmaxDP_node( - logit, dsts[j - nodes_per_layer], global.softmax[j - nodes_per_layer]); - } - - // Add shared variables - sharedVariables.push_back(srcEmbed); - sharedVariables.push_back(dstEmbed); - for (int i = 0; i < config.numLayers; i++) { - sharedVariables.push_back(encoders[i]); - sharedVariables.push_back(decoders[i]); - } - sharedVariables.push_back(linear); -} - -void RnnModel::word_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - Rect<2> rect0 = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - int *host_ptr; - bool same = *((bool *)task->args); - checkCUDA(cudaHostAlloc(&host_ptr, - sizeof(int) * rect0.volume(), - cudaHostAllocPortable | cudaHostAllocMapped)); - for (int i = 0; i < rect0.volume(); i++) { - host_ptr[i] = same ? 1 : i % 16; - } - for (int i = 0; i < regions.size(); i++) { - AccessorWO const acc(regions[i], FID_DATA); - Rect<2> rect = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(acc.accessor.is_dense_arbitrary(rect)); - assert(rect == rect0); - int *ptr = acc.ptr(rect.lo); - checkCUDA(cudaMemcpy( - ptr, host_ptr, sizeof(int) * rect0.volume(), cudaMemcpyHostToDevice)); - } - checkCUDA(cudaFreeHost(host_ptr)); -} - -void RnnModel::init() { - Context ctx = config.lg_ctx; - Runtime *runtime = config.lg_hlr; - // Init words - Rect<1> part_rect = runtime->get_index_space_domain(ctx, part_is); - for (PointInRectIterator<1> it(part_rect); it(); it++) { - int idx = 0; - bool same = false; - TaskLauncher launcher(WORD_INIT_TASK_ID, - TaskArgument(&same, sizeof(same)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(0)); - DomainPoint dp(*it); - for (int i = 0; i * LSTM_PER_NODE_LENGTH < config.seqLength; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(srcs[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, srcs[i].region)); - launcher.add_field(idx++, FID_DATA); - } - for (int i = 0; i * LSTM_PER_NODE_LENGTH < config.seqLength; i++) { - LogicalRegion x = - runtime->get_logical_subregion_by_color(dsts[i].partition, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, dsts[i].region)); - launcher.add_field(idx++, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - f.get_void_result(); - } - // Init zero tensors - for (PointInRectIterator<1> it(part_rect); it(); it++) { - int idx = 0; - TaskLauncher launcher(ZERO_2D_INIT_TASK_ID, - TaskArgument(NULL, 0), - Predicate::TRUE_PRED, - 0, - RnnMapper::assign_to_gpu(0)); - DomainPoint dp(*it); - for (int i = 0; i < config.numLayers; i++) { - LogicalRegion hx = - runtime->get_logical_subregion_by_color(zero[i].hx.partition, dp); - launcher.add_region_requirement( - RegionRequirement(hx, WRITE_ONLY, EXCLUSIVE, zero[i].hx.region)); - launcher.add_field(idx++, FID_DATA); - } - for (int i = 0; i < config.numLayers; i++) { - LogicalRegion cx = - runtime->get_logical_subregion_by_color(zero[i].cx.partition, dp); - launcher.add_region_requirement( - RegionRequirement(cx, WRITE_ONLY, EXCLUSIVE, zero[i].cx.region)); - launcher.add_field(idx++, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - f.get_void_result(); - } - // Init hx_grad/cx_grad for the last LSTM node on each layer - int nodes_per_layer = config.seqLength / LSTM_PER_NODE_LENGTH; - for (PointInRectIterator<1> it(part_rect); it(); it++) { - int idx = 0; - TaskLauncher launcher(ZERO_2D_INIT_TASK_ID, - TaskArgument(NULL, 0), - Predicate::TRUE_PRED, - 0, - RnnMapper::assign_to_gpu(0)); - DomainPoint dp(*it); - for (int i = 0; i < config.numLayers; i++) { - LSTMTensors last_lstm = lstm[i][2 * nodes_per_layer - 1]; - // hx - LogicalRegion hx_grad = runtime->get_logical_subregion_by_color( - last_lstm.hx.partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - hx_grad, WRITE_ONLY, EXCLUSIVE, last_lstm.hx.region_grad)); - launcher.add_field(idx++, FID_DATA); - // cx - LogicalRegion cx_grad = runtime->get_logical_subregion_by_color( - last_lstm.cx.partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - cx_grad, WRITE_ONLY, EXCLUSIVE, last_lstm.cx.region_grad)); - launcher.add_field(idx++, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - f.get_void_result(); - } - // TODO: to be removed when we have attention layers - // Init y_grad for the decoder lstm nodes - for (PointInRectIterator<1> it(part_rect); it(); it++) { - int idx = 0; - TaskLauncher launcher(ZERO_3D_INIT_TASK_ID, - TaskArgument(NULL, 0), - Predicate::TRUE_PRED, - 0, - RnnMapper::assign_to_gpu(0)); - DomainPoint dp(*it); - for (int i = 0; i < nodes_per_layer; i++) { - LSTMTensors top_lstm = lstm[config.numLayers - 1][i]; - LogicalRegion y_grad = runtime->get_logical_subregion_by_color( - top_lstm.x.partition_grad, dp); - launcher.add_region_requirement(RegionRequirement( - y_grad, WRITE_ONLY, EXCLUSIVE, top_lstm.x.region_grad)); - launcher.add_field(idx++, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - f.get_void_result(); - } - // Init shared variables - for (int i = 0; i < sharedVariables.size(); i++) { - init_shared_variable(sharedVariables[i]); - } - for (size_t i = 0; i < layers.size(); i++) { - layers[i]->init(*this); - } -} - -void RnnModel::zero_3d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - for (int i = 0; i < task->regions.size(); i++) { - AccessorWO const acc_w(regions[i], FID_DATA); - Rect<3> rect_w = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - float *w_ptr = acc_w.ptr(rect_w.lo); - assign_kernel<<>>( - w_ptr, rect_w.volume(), 0.0f); - } -} - -void RnnModel::zero_2d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - for (int i = 0; i < task->regions.size(); i++) { - AccessorWO const acc_w(regions[i], FID_DATA); - Rect<2> rect_w = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - float *w_ptr = acc_w.ptr(rect_w.lo); - assign_kernel<<>>( - w_ptr, rect_w.volume(), 0.0f); - } -} - -void RnnModel::zero_1d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - for (int i = 0; i < task->regions.size(); i++) { - AccessorWO const acc_w(regions[i], FID_DATA); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - float *w_ptr = acc_w.ptr(rect_w.lo); - assign_kernel<<>>( - w_ptr, rect_w.volume(), 0.0f); - } -} - -void RnnModel::dummy_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) {} - -void RnnModel::forward() { - config.iterator++; - Context ctx = config.lg_ctx; - Runtime *runtime = config.lg_hlr; - // Step 1: launch dummy tasks to prefetch shared variables - for (size_t i = 0; i < sharedVariables.size(); i++) { - for (int n = 0; n < config.numNodes; n++) { - if (sharedVariables[i].masterOnNode[n] != MASTER_NOT_ASSIGNED) { - int gpuId = sharedVariables[i].masterOnNode[n]; - TaskLauncher launcher(DUMMY_TASK_ID, - TaskArgument(NULL, 0), - Predicate::TRUE_PRED, - 0, - RnnMapper::assign_to_gpu(gpuId)); - launcher.add_region_requirement( - RegionRequirement(sharedVariables[i].region, - READ_ONLY, - EXCLUSIVE, - sharedVariables[i].region)); - launcher.add_field(0, FID_DATA); - runtime->execute_task(ctx, launcher); - } - } - } - runtime->issue_mapping_fence(ctx); - // Step 2: zero gradients - for (size_t i = 0; i < sharedVariables.size(); i++) { - for (int j = 0; j < config.workersPerNode * config.numNodes; j++) { - if (sharedVariables[i].gradients[j] != LogicalRegion::NO_REGION) { - TaskLauncher launcher(ZERO_1D_INIT_TASK_ID, - TaskArgument(NULL, 0), - Predicate::TRUE_PRED, - 0, - RnnMapper::assign_to_gpu(j)); - LogicalRegion gradient = sharedVariables[i].gradients[j]; - launcher.add_region_requirement( - RegionRequirement(gradient, WRITE_ONLY, EXCLUSIVE, gradient)); - launcher.add_field(0, FID_DATA); - runtime->execute_task(ctx, launcher); - } - } - } - // Step 3: launch forward tasks - for (size_t i = 0; i < layers.size(); i++) { - layers[i]->forward(*this); - } -} - -void RnnModel::backward() { - for (int i = layers.size() - 1; i >= 0; i--) { - layers[i]->backward(*this); - } -} - -void RnnModel::update() { - for (int i = sharedVariables.size() - 1; i >= 0; i--) { - update_shared_variable(sharedVariables[i]); - } -} - -/* - regions[0](O): w -*/ -void RnnModel::params_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == 1); - assert(task->regions.size() == 1); - float value = *((float *)task->args); - AccessorWO const acc_w(regions[0], FID_DATA); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - float *w_ptr = acc_w.ptr(rect_w.lo); - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - curandGenerator_t genGPU; - curandCreateGenerator(&genGPU, CURAND_RNG_PSEUDO_DEFAULT); - curandSetStream(genGPU, stream); - curandSetPseudoRandomGeneratorSeed(genGPU, 1234LL); - curandGenerateUniform(genGPU, w_ptr, rect_w.volume()); - checkCUDA(cudaDeviceSynchronize()); - scale_kernel<<>>( - w_ptr, rect_w.volume(), -value, value); - // assign_kernel<<>>( - // w_ptr, rect_w.volume(), value); -} - -void RnnModel::init_shared_variable(SharedVariable params) { - Context ctx = config.lg_ctx; - Runtime *runtime = config.lg_hlr; - float value = 0.1f; - TaskLauncher launcher(PARAMS_INIT_TASK_ID, - TaskArgument(&value, sizeof(value)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(params.masterOnNode[0])); - launcher.add_region_requirement( - RegionRequirement(params.region, WRITE_ONLY, EXCLUSIVE, params.region)); - launcher.add_field(0, FID_DATA); - Future f = runtime->execute_task(ctx, launcher); - f.get_void_result(); -} - -/* - regions[0]: (I/O): w - regions[1..]: (O): w_grad - */ -void RnnModel::params_update_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == task->regions.size()); - float rate = *((float *)task->args); - AccessorRW const acc_w(regions[0], FID_DATA); - Rect<1> rect_w = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - assert(acc_w.accessor.is_dense_arbitrary(rect_w)); - for (int i = 1; i < regions.size(); i++) { - AccessorRO const acc_w_grad(regions[i], FID_DATA); - Rect<1> rect_w_grad = runtime->get_index_space_domain( - ctx, task->regions[i].region.get_index_space()); - assert(rect_w.contains(rect_w_grad)); - assert(acc_w_grad.accessor.is_dense_arbitrary(rect_w_grad)); - float *w_ptr = acc_w.ptr(rect_w_grad.lo); - float const *w_grad_ptr = acc_w_grad.ptr(rect_w_grad.lo); - apply_add_with_scale<<>>( - w_ptr, w_grad_ptr, rect_w_grad.volume(), rate); -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<1, float>(w_grad_ptr, rect_w_grad, "partial_w"); -#endif - } -#ifdef PRINT_INTERMEDIATE_RESULT - float *w_ptr = acc_w.ptr(rect_w.lo); - print_tensor<1, float>(w_ptr, rect_w, "final_w"); -#endif -} - -void RnnModel::update_shared_variable(SharedVariable params) { - Context ctx = config.lg_ctx; - Runtime *runtime = config.lg_hlr; - // for (int i = 0; i < config.workersPerNode; i++) - // if (params.gradients[i] != LogicalRegion::NO_REGION) { - // Rect<1> rect = - // runtime->get_index_space_domain(ctx, - // params.gradients[i].get_index_space()); - // printf("rect[%d]: lo(%d) hi(%d)\n", i, rect.lo[0], rect.hi[0]); - // } - float rate = 1.0f; - for (int node = 0; node < config.numNodes; node++) { - if (params.masterOnNode[node] != MASTER_NOT_ASSIGNED) { - TaskLauncher launcher( - PARAMS_UPD_TASK_ID, - TaskArgument(&rate, sizeof(rate)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(params.masterOnNode[node])); - LogicalRegion masterGrad = params.gradients[params.masterOnNode[node]]; - assert(masterGrad != LogicalRegion::NO_REGION); - launcher.add_region_requirement( - RegionRequirement(masterGrad, READ_WRITE, EXCLUSIVE, masterGrad)); - launcher.add_field(0, FID_DATA); - int cnt = 1; - for (int idx = 0; idx < config.workersPerNode; idx++) { - int gpuIdx = node * config.workersPerNode + idx; - if (gpuIdx == params.masterOnNode[node]) { - continue; - } - LogicalRegion grad = params.gradients[gpuIdx]; - if (grad == LogicalRegion::NO_REGION) { - continue; - } - launcher.add_region_requirement( - RegionRequirement(grad, READ_ONLY, EXCLUSIVE, grad)); - launcher.add_field(cnt++, FID_DATA); - } - // printf("Step 1: cnt = %d\n", cnt); - runtime->execute_task(ctx, launcher); - } - } - rate = -0.1f; - TaskLauncher launcher(PARAMS_UPD_TASK_ID, - TaskArgument(&rate, sizeof(rate)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(params.masterOnNode[0])); - launcher.add_region_requirement( - RegionRequirement(params.region, READ_WRITE, EXCLUSIVE, params.region)); - launcher.add_field(0, FID_DATA); - int cnt = 1; - for (int node = 0; node < config.numNodes; node++) { - if (params.masterOnNode[node] != MASTER_NOT_ASSIGNED) { - int gpuIdx = params.masterOnNode[node]; - LogicalRegion grad = params.gradients[gpuIdx]; - assert(grad != LogicalRegion::NO_REGION); - launcher.add_region_requirement( - RegionRequirement(grad, READ_ONLY, EXCLUSIVE, grad)); - launcher.add_field(cnt++, FID_DATA); - } - } - // printf("Step 2: cnt = %d\n", cnt); - runtime->execute_task(ctx, launcher); -} diff --git a/nmt/rnn.h b/nmt/rnn.h deleted file mode 100644 index 001e7e06e2..0000000000 --- a/nmt/rnn.h +++ /dev/null @@ -1,438 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#ifndef _LEGION_RNN_H_ -#define _LEGION_RNN_H_ - -#include "ops.h" - -#define MAX_SEQ_LENGTH 100 -#define MAX_NUM_LAYERS 4 -#define LSTM_PER_NODE_LENGTH 10 -#define MASTER_NOT_ASSIGNED -1 -// #define PRINT_INTERMEDIATE_RESULT - -struct RnnConfig { - Context lg_ctx; - HighLevelRuntime *lg_hlr; - FieldSpace field_space; - int batchSize, hiddenSize, embedSize, vocabSize; - int numLayers, seqLength, numParts; - int numNodes, workersPerNode; - int iterator; -}; - -struct SharedVariable { - static const SharedVariable NO_VARIABLE; /*empty SharedVariable handle*/ - LogicalRegion region, gradients[MAX_NUM_WORKERS]; - LogicalRegion subregions[2 * MAX_NUM_PARTS]; - int masterOnNode[MAX_NUM_WORKERS]; - SharedVariable() { - region = LogicalRegion::NO_REGION; - for (int i = 0; i < MAX_NUM_WORKERS; i++) { - gradients[i] = LogicalRegion::NO_REGION; - } - for (int i = 0; i < 2 * MAX_NUM_PARTS; i++) { - subregions[i] = LogicalRegion::NO_REGION; - } - for (int i = 0; i < MAX_NUM_WORKERS; i++) { - masterOnNode[i] = MASTER_NOT_ASSIGNED; - } - } -}; - -struct ParallelConfig { - int nDims, dim[MAX_DIM]; - int gpu[MAX_NUM_WORKERS]; -}; - -struct GlobalConfig { - ParallelConfig linear[MAX_SEQ_LENGTH]; - ParallelConfig lstm[MAX_NUM_LAYERS][2 * MAX_SEQ_LENGTH]; - ParallelConfig embed[2 * MAX_SEQ_LENGTH]; - ParallelConfig softmax[MAX_SEQ_LENGTH]; -}; - -class RnnModel; - -class RnnOp { -public: - RnnOp(Tensor input, ParallelConfig pc, SharedVariable _params); - RnnOp(Tensor t1, - Tensor t2, - Tensor t3, - ParallelConfig pc, - SharedVariable _params); - RnnOp(int num, Tensor *inputs); - virtual void init(RnnModel const &) = 0; - - virtual void forward(RnnModel const &) = 0; - - virtual void backward(RnnModel const &) = 0; - - virtual void update(RnnModel const &) = 0; - -public: - Tensor outputs[MAX_NUM_OUTPUTS]; - Tensor inputs[MAX_NUM_INPUTS]; - OpMeta *meta[MAX_NUM_WORKERS]; - ParallelConfig paraConfig; - SharedVariable params; -}; - -struct LSTMTensors { - Tensor x, hx, cx; -}; - -class RnnModel { -public: - RnnModel(int batch_size, - int numLayers, - int seqLength, - int hidden_size, - int embed_size, - int vocab_size, - int num_parts, - int num_nodes, - int num_workers_per_node, - GlobalConfig global, - Context ctx, - Runtime *runtime); - - void init(); - - void forward(); - - void backward(); - - void update(); - - void init_shared_variable(SharedVariable params); - - void update_shared_variable(SharedVariable params); - - static void word_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void zero_1d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void zero_2d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void zero_3d_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void dummy_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void params_init_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void params_update_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - LSTMTensors add_lstm_node( - Tensor x, Tensor hx, Tensor cx, ParallelConfig pc, SharedVariable params); - - Tensor add_linear_node(Tensor x, - int output_size, - ParallelConfig pc, - SharedVariable params); - - Tensor add_embed_node(Tensor x, - int vocab_size, - int output_size, - ParallelConfig pc, - SharedVariable params); - - Tensor add_softmaxDP_node(Tensor x, Tensor label, ParallelConfig pc); - -public: - RnnConfig config; - std::vector layers; - std::vector sharedVariables; - DnnHandle dnn_handlers[MAX_NUM_WORKERS]; - Tensor srcs[MAX_SEQ_LENGTH], dsts[MAX_SEQ_LENGTH]; - LSTMTensors zero[MAX_NUM_LAYERS]; - LSTMTensors lstm[MAX_NUM_LAYERS][2 * MAX_SEQ_LENGTH]; - IndexSpaceT<1> part_is; -}; - -/* - * For now, every single LSTM cell with 1 word and 1 layer is a - * LSTM operation. - */ -class LSTM : public RnnOp { -public: - LSTM(RnnConfig config, - Tensor x, - Tensor hx, - Tensor cx, - int batch_size, - int input_size, - int output_size, - ParallelConfig pc, - SharedVariable params); - - void init(RnnModel const &); - - void forward(RnnModel const &); - - void backward(RnnModel const &); - - void update(RnnModel const &); - - static OpMeta *init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void update_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - -public: - int batch_size, input_size, output_size; - Rect<1> part_rect; -}; - -class LSTMMeta : public OpMeta { -public: - LSTMMeta(DnnHandle handle) : OpMeta(handle){}; - cudnnRNNDescriptor_t rnnDesc; - cudnnDropoutDescriptor_t dropoutDesc; - cudnnTensorDescriptor_t xDescs[LSTM_PER_NODE_LENGTH], - yDescs[LSTM_PER_NODE_LENGTH], cxDesc, hxDesc, cyDesc, hyDesc; - cudnnFilterDescriptor_t wDesc; - size_t reserveSpaceSize; - void *reserveSpace; - bool profiling_runtime; -}; - -class Linear : public RnnOp { -public: - Linear(RnnConfig config, - Tensor input, - int output_channels, - ParallelConfig pc, - SharedVariable params, - IndexSpaceT<1> input_part_is); - - void init(RnnModel const &); - - void forward(RnnModel const &); - - void backward(RnnModel const &); - - void update(RnnModel const &); - - static OpMeta *init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void backward2_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void update_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - -public: - int batch_size, input_size, output_size; - Tensor replica; - // each replica_sub_lps[i] is a disjoint partition - LogicalPartition replica_sub_lps[MAX_NUM_WORKERS]; - // input_lp may be an aliased partition if num_par_c > 1 - LogicalPartition input_lp; - Rect<2> part_rect; - Rect<1> input_part_rect; -}; - -class LinearMeta : public OpMeta { -public: - LinearMeta(DnnHandle handle) : OpMeta(handle){}; - float *one_ptr; - bool profiling_runtime; -}; - -class Embed : public RnnOp { -public: - Embed(RnnConfig config, - Tensor input, - int embed_size, - int output_size, - ParallelConfig pc, - SharedVariable params); - - void init(RnnModel const &); - - void forward(RnnModel const &); - - void backward(RnnModel const &); - - void update(RnnModel const &); - - static OpMeta *init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - - static void update_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - -public: - int batchSize, outputSize, vocabSize; - Rect<1> part_rect; -}; - -class EmbedMeta : public OpMeta { -public: - EmbedMeta(DnnHandle handle) : OpMeta(handle){}; - bool profiling_runtime; -}; - -/*class Softmax : public RnnOp { -public: - Softmax(RnnConfig config, Tensor input, Tensor output, - ParallelConfig pc); - - void init(const RnnModel&); - - void forward(const RnnModel&); - - void backward(const RnnModel&); - - void update(const RnnModel&); - - static OpMeta* init_task(const Task *task, - const std::vector ®ions, - Context ctx, Runtime *runtime); - - static void forward_task(const Task *task, - const std::vector ®ions, - Context ctx, Runtime *runtime); - - static void backward_task(const Task *task, - const std::vector ®ions, - Context ctx, HighLevelRuntime *runtime); -public: - Rect<1> part_rect; -}; - -class SoftmaxMeta : public OpMeta { -public: - SoftmaxMeta(DnnHandle handle) : OpMeta(handle) {}; - size_t storage_bytes; - void* storage; - int* offsets; - bool profiling_runtime; -}; -*/ -class SoftmaxDP : public RnnOp { -public: - SoftmaxDP(RnnConfig config, Tensor logit, Tensor label, ParallelConfig pc); - - void init(RnnModel const &); - - void forward(RnnModel const &); - - void backward(RnnModel const &); - - void update(RnnModel const &); - - static OpMeta *init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime); - - static void backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - HighLevelRuntime *runtime); - -public: - Rect<1> part_rect; - Tensor label; - LogicalPartition logit_lp, logit_grad_lp; -}; - -class SoftmaxDPMeta : public OpMeta { -public: - SoftmaxDPMeta(DnnHandle handle) : OpMeta(handle){}; -#ifndef DISABLE_COMPUTATION - cudnnTensorDescriptor_t inputTensor; -#endif - int batchSize; - bool profiling_runtime; -}; - -#endif //_LEGION_RNN_H_ diff --git a/nmt/rnn_mapper.cc b/nmt/rnn_mapper.cc deleted file mode 100644 index 9a50d2b3e0..0000000000 --- a/nmt/rnn_mapper.cc +++ /dev/null @@ -1,138 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "rnn_mapper.h" -#define ASSIGN_TO_GPU_MASK 0xABCD0000 - -RnnMapper::RnnMapper(MapperRuntime *rt, - Machine machine, - Processor local, - char const *mapper_name, - std::vector *_gpus, - std::map *_proc_fbmems, - std::vector *_cpus) - : DefaultMapper(rt, machine, local, mapper_name), gpus(*_gpus), - proc_fbmems(*_proc_fbmems), cpus(*_cpus) {} - -void RnnMapper::select_task_options(const MapperContext ctx, - Task const &task, - TaskOptions &output) { - if ((task.tag & ASSIGN_TO_GPU_MASK) == ASSIGN_TO_GPU_MASK) { - output.inline_task = false; - output.stealable = false; - output.map_locally = true; - unsigned long gpuId = task.tag ^ ASSIGN_TO_GPU_MASK; - output.initial_proc = gpus[gpuId % gpus.size()]; - } else { - DefaultMapper::select_task_options(ctx, task, output); - } -} - -#ifdef DEADCODE -void RnnMapper::map_task(const MapperContext ctx, - Task const &task, - MapTaskInput const &input, - MapTaskOutput &output) { - printf("Task(%s %zx):", task.get_task_name(), task.tag); - for (size_t i = 0; i < input.valid_instances.size(); i++) { - printf(" ("); - for (size_t j = 0; j < input.valid_instances[i].size(); j++) { - printf("%zx ", input.valid_instances[i][j].get_location().id); - } - printf(")"); - } - printf("\n"); - DefaultMapper::map_task(ctx, task, input, output); -} - -void RnnMapper::select_task_sources(const MapperContext ctx, - Task const &task, - SelectTaskSrcInput const &input, - SelectTaskSrcOutput &output) { - printf("Slct(%s %zx)[%d]:", - task.get_task_name(), - task.tag, - input.region_req_index); - for (size_t i = 0; i < input.source_instances.size(); i++) { - printf(" %zx", input.source_instances[i].get_location().id); - } - DefaultMapper::select_task_sources(ctx, task, input, output); - printf(" chosen = %zx\n", output.chosen_ranking.front().get_location().id); -} -#endif - -void update_mappers(Machine machine, - Runtime *runtime, - std::set const &local_procs) { - std::vector *gpus = new std::vector(); - std::map *proc_fbmems = new std::map(); - std::vector *cpus = new std::vector(); - // std::map* proc_zcmems = new std::map(); - std::vector proc_mem_affinities; - machine.get_proc_mem_affinity(proc_mem_affinities); - Machine::ProcessorQuery proc_query(machine); - for (Machine::ProcessorQuery::iterator it = proc_query.begin(); - it != proc_query.end(); - it++) { - if (it->kind() == Processor::TOC_PROC) { - gpus->push_back(*it); - Machine::MemoryQuery fb_query(machine); - fb_query.only_kind(Memory::GPU_FB_MEM); - fb_query.best_affinity_to(*it); - assert(fb_query.count() == 1); - (*proc_fbmems)[*it] = *(fb_query.begin()); - } else if (it->kind() == Processor::LOC_PROC) { - cpus->push_back(*it); - } - } - - /* - for (unsigned idx = 0; idx < proc_mem_affinities.size(); ++idx) { - Machine::ProcessorMemoryAffinity& affinity = proc_mem_affinities[idx]; - if (affinity.p.kind() == Processor::TOC_PROC) { - if (affinity.m.kind() == Memory::GPU_FB_MEM) { - (*proc_fbmems)[affinity.p] = affinity.m; - } - else if (affinity.m.kind() == Memory::Z_COPY_MEM) { - (*proc_zcmems)[affinity.p] = affinity.m; - } - } - } - - for (std::map::iterator it = proc_fbmems->begin(); - it != proc_fbmems->end(); it++) { - gpus->push_back(it->first); - } - */ - - for (std::set::const_iterator it = local_procs.begin(); - it != local_procs.end(); - it++) { - RnnMapper *mapper = new RnnMapper(runtime->get_mapper_runtime(), - machine, - *it, - "rnn_mapper", - gpus, - proc_fbmems, - cpus); - runtime->replace_default_mapper(mapper, *it); - } -} - -MappingTagID RnnMapper::assign_to_gpu(int idx) { - assert(idx <= 0xFFFF); - return (ASSIGN_TO_GPU_MASK | idx); -} diff --git a/nmt/rnn_mapper.h b/nmt/rnn_mapper.h deleted file mode 100644 index 357eab97ba..0000000000 --- a/nmt/rnn_mapper.h +++ /dev/null @@ -1,63 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#ifndef __RNN_MAPPER_H__ -#define __RNN_MAPPER_H__ - -#include "default_mapper.h" -#include "legion.h" -#include "ops.h" - -using namespace Legion; -using namespace Legion::Mapping; - -class RnnMapper : public DefaultMapper { -public: - RnnMapper(MapperRuntime *rt, - Machine machine, - Processor local, - char const *mapper_name, - std::vector *gpus, - std::map *proc_fbmems, - std::vector *cpus); - -public: - virtual void select_task_options(const MapperContext ctx, - Task const &task, - TaskOptions &output); - // virtual void slice_task(const MapperContext ctx, - // const Task& task, - // const SliceTaskInput& input, - // SliceTaskOutput& output); - // virtual void map_task(const MapperContext ctx, - // const Task& task, - // const MapTaskInput& input, - // MapTaskOutput& output); - // virtual void select_task_sources(const MapperContext ctx, - // const Task& task, - // const SelectTaskSrcInput& input, - // SelectTaskSrcOutput& output); - static MappingTagID assign_to_gpu(int gpuIdx); - -protected: - std::vector &gpus; - std::map &proc_fbmems; - std::vector &cpus; -}; - -void update_mappers(Machine machine, - Runtime *rt, - std::set const &local_procs); -#endif diff --git a/nmt/softmax_data_parallel.cu b/nmt/softmax_data_parallel.cu deleted file mode 100644 index 9b41a332ec..0000000000 --- a/nmt/softmax_data_parallel.cu +++ /dev/null @@ -1,392 +0,0 @@ -/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) - * - * Licensed under the Apache License, Version 2.0 (the "License"); - * you may not use this file except in compliance with the License. - * You may obtain a copy of the License at - * - * http://www.apache.org/licenses/LICENSE-2.0 - * - * Unless required by applicable law or agreed to in writing, software - * distributed under the License is distributed on an "AS IS" BASIS, - * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. - * See the License for the specific language governing permissions and - * limitations under the License. - */ - -#include "../cnn_helper.h" -#include "rnn.h" -#include "rnn_mapper.h" - -struct SoftmaxDPInitParams { - DnnHandle handle; - int batchSize; - bool profiling; -}; - -Tensor RnnModel::add_softmaxDP_node(Tensor logit, - Tensor label, - ParallelConfig pc) { - assert(logit.numDim == 3); - assert(logit.adim[2] == LSTM_PER_NODE_LENGTH); - assert(logit.pdim[2] == LSTM_PER_NODE_LENGTH); - SoftmaxDP *node = new SoftmaxDP(config, logit, label, pc); - layers.push_back(node); - return node->outputs[0]; -} - -SoftmaxDP::SoftmaxDP(RnnConfig config, - Tensor logit, - Tensor _label, - ParallelConfig pc) - : RnnOp(logit, pc, SharedVariable::NO_VARIABLE), label(_label) { - Context ctx = config.lg_ctx; - Runtime *runtime = config.lg_hlr; - assert(pc.nDims == 1); - int num_par_n = pc.dim[0]; - { - Rect<1> rect(Point<1>(0), Point<1>(num_par_n - 1)); - part_rect = rect; - } - IndexSpaceT<1> part_is = runtime->create_index_space(ctx, part_rect); - int batch_size = logit.adim[1]; - int output_size = logit.adim[0]; - FieldSpace fs = config.field_space; - Rect<3, coord_t> y_rect( - Point<3>(0, 0, 0), - Point<3>(output_size - 1, batch_size - 1, LSTM_PER_NODE_LENGTH - 1)); - IndexSpaceT<3> y_is = runtime->create_index_space(ctx, y_rect); - LogicalRegion y_lr = runtime->create_logical_region(ctx, y_is, fs); - LogicalRegion y_grad_lr = runtime->create_logical_region(ctx, y_is, fs); - assert(batch_size % num_par_n == 0); - int extent_n = batch_size / num_par_n; - Rect<3, coord_t> extent( - Point<3>(0, 0, 0), - Point<3>(output_size - 1, extent_n - 1, LSTM_PER_NODE_LENGTH - 1)); - Transform<3, 1, coord_t> trans; - trans[0][0] = 0; - trans[1][0] = extent_n; - trans[2][0] = 0; - IndexPartition y_ip = runtime->create_partition_by_restriction( - ctx, y_is, part_is, trans, extent); - assert(runtime->is_index_partition_disjoint(ctx, y_ip)); - assert(runtime->is_index_partition_complete(ctx, y_ip)); - LogicalPartition y_lp = runtime->get_logical_partition(ctx, y_lr, y_ip); - LogicalPartition y_grad_lp = - runtime->get_logical_partition(ctx, y_grad_lr, y_ip); - outputs[0].numDim = 3; - outputs[0].adim[0] = output_size; - outputs[0].adim[1] = batch_size; - outputs[0].adim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].pdim[0] = output_size; - outputs[0].pdim[1] = extent_n; - outputs[0].pdim[2] = LSTM_PER_NODE_LENGTH; - outputs[0].region = y_lr; - outputs[0].partition = y_lp; - outputs[0].region_grad = y_grad_lr; - outputs[0].partition_grad = y_grad_lp; - // Every partition reads all input_channels - // Use the same partitioning as outputs - // if (inputs[0].pdim[0] == outputs[0].pdim[0] - // && inputs[0].pdim[1] == outputs[0].pdim[1]) { - // logit_lp = inputs[0].partition; - // logit_grad_lp = inputs[0].partition_grad; - //} else { - IndexSpaceT<3> logit_is(inputs[0].region.get_index_space()); - IndexPartition logit_ip = runtime->create_partition_by_restriction( - ctx, logit_is, part_is, trans, extent); - logit_lp = runtime->get_logical_partition(ctx, inputs[0].region, logit_ip); - logit_grad_lp = - runtime->get_logical_partition(ctx, inputs[0].region_grad, logit_ip); - //} -} - -/* - regions[0](I): x - regions[1](O): y -*/ -OpMeta *SoftmaxDP::init_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == 2); - assert(task->regions.size() == 2); - SoftmaxDPInitParams const *softmaxDP = (SoftmaxDPInitParams *)task->args; - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorWO const acc_y(regions[1], FID_DATA); - Rect<3> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - SoftmaxDPMeta *m = new SoftmaxDPMeta(softmaxDP->handle); - m->profiling_runtime = softmaxDP->profiling; - m->batchSize = softmaxDP->batchSize; -#ifndef DISABLE_COMPUTATION - checkCUDNN(cudnnCreateTensorDescriptor(&m->inputTensor)); - assert(rect_x == rect_y); - int input_c = rect_x.hi[0] - rect_x.lo[0] + 1; - int input_n = (rect_x.hi[1] - rect_x.lo[1] + 1) * LSTM_PER_NODE_LENGTH; - checkCUDNN(cudnnSetTensor4dDescriptor(m->inputTensor, - CUDNN_TENSOR_NCHW, - CUDNN_DATA_FLOAT, - input_n, - input_c, - 1, - 1)); -#endif - return m; -} - -void SoftmaxDP::init(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - SoftmaxDPInitParams initParams; - initParams.handle = model.dnn_handlers[paraConfig.gpu[idx]]; - initParams.batchSize = model.config.batchSize; - initParams.profiling = false; - TaskLauncher launcher(RNN_SOFTMAXDP_INIT_TASK_ID, - TaskArgument(&initParams, sizeof(initParams)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = runtime->get_logical_subregion_by_color(logit_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(1, FID_DATA); - } - Future f = runtime->execute_task(ctx, launcher); - meta[idx] = f.get_result(); - } -} - -/* - regions[0](I): x - regions[1](O): y -*/ -void SoftmaxDP::forward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 2); - assert(task->regions.size() == 2); - float alpha = 1.0f, beta = 0.0f; - SoftmaxDPMeta const *m = *((SoftmaxDPMeta **)task->args); - AccessorRO const acc_x(regions[0], FID_DATA); - AccessorWO const acc_y(regions[1], FID_DATA); - Rect<3> rect_x = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - assert(acc_x.accessor.is_dense_arbitrary(rect_x)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - float const *x_ptr = acc_x.ptr(rect_x.lo); - float *y_ptr = acc_y.ptr(rect_y.lo); - - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - cudaStream_t stream; - checkCUDA(cudaStreamCreate(&stream)); - checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); - checkCUDNN(cudnnSoftmaxForward(m->handle.dnn, - CUDNN_SOFTMAX_ACCURATE, - CUDNN_SOFTMAX_MODE_CHANNEL, - &alpha, - m->inputTensor, - x_ptr, - &beta, - m->inputTensor, - y_ptr)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("SoftmaxDP forward time = %.2fms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<3, float>(y_ptr, rect_y, "softmax"); -#endif -#endif -} - -void SoftmaxDP::forward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(RNN_SOFTMAXDP_FWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = runtime->get_logical_subregion_by_color(logit_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, READ_ONLY, EXCLUSIVE, inputs[0].region)); - launcher.add_field(0, FID_DATA); - } - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, WRITE_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(1, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -__global__ void SoftmaxLossBackprop(float *input, - int const *label, - int vocab_size, - int batch_size) { - CUDA_KERNEL_LOOP(i, batch_size) { - int label_idx = label[i]; - input[i * vocab_size + label_idx] -= 1.0f; - } -} - -/* - regions[0](O): x_grad - regions[1](I): y - regions[2](I): labels -*/ -void SoftmaxDP::backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { -#ifndef DISABLE_COMPUTATION - assert(regions.size() == 3); - assert(task->regions.size() == 3); - SoftmaxDPMeta const *m = *((SoftmaxDPMeta **)task->args); - AccessorWO const acc_x_grad(regions[0], FID_DATA); - AccessorRO const acc_y(regions[1], FID_DATA); - AccessorRO const acc_label(regions[2], FID_DATA); - Rect<3> rect_x_grad = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Rect<3> rect_y = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Rect<2> rect_label = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - assert(acc_x_grad.accessor.is_dense_arbitrary(rect_x_grad)); - assert(acc_y.accessor.is_dense_arbitrary(rect_y)); - assert(acc_label.accessor.is_dense_arbitrary(rect_label)); - float *x_grad_ptr = acc_x_grad.ptr(rect_x_grad.lo); - float const *y_ptr = acc_y.ptr(rect_y.lo); - int const *label_ptr = acc_label.ptr(rect_label.lo); - assert(rect_x_grad == rect_y); - assert(rect_y.hi[1] - rect_y.lo[1] == rect_label.hi[0] - rect_label.lo[0]); - assert(rect_y.hi[2] - rect_y.lo[2] == rect_label.hi[1] - rect_label.lo[1]); - int num_labels = rect_label.volume(); - int vocab_size = rect_y.hi[0] - rect_y.lo[0] + 1; - - cudaEvent_t t_start, t_end; - if (m->profiling_runtime) { - cudaEventCreate(&t_start); - cudaEventCreate(&t_end); - cudaEventRecord(t_start); - } - checkCUDA(cudaMemcpyAsync(x_grad_ptr, - y_ptr, - rect_x_grad.volume() * sizeof(float), - cudaMemcpyDeviceToDevice)); - SoftmaxLossBackprop<<>>( - x_grad_ptr, label_ptr, vocab_size, num_labels); - - // Accouting for batch size in SGD - float scalVal = 1.0f / static_cast(m->batchSize); - scale_kernel<<>>( - x_grad_ptr, rect_x_grad.volume(), 0.0f, scalVal); - // checkCUDA(cublasSscal(m->handle.blas, rect_x_grad.volume(), - // &scalVal, x_grad_ptr, 1)); - if (m->profiling_runtime) { - cudaEventRecord(t_end); - checkCUDA(cudaEventSynchronize(t_end)); - float elapsed = 0; - checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); - cudaEventDestroy(t_start); - cudaEventDestroy(t_end); - printf("Softmax backward time = %.2fms\n", elapsed); - } -#ifdef PRINT_INTERMEDIATE_RESULT - print_tensor<3, float>(x_grad_ptr, rect_x_grad, "softmax bwd:x_grad"); - float *host_ptr; - checkCUDA(cudaHostAlloc(&host_ptr, - sizeof(float) * rect_x_grad.volume(), - cudaHostAllocPortable | cudaHostAllocMapped)); - checkCUDA(cudaMemcpy(host_ptr, - x_grad_ptr, - sizeof(float) * rect_x_grad.volume(), - cudaMemcpyDeviceToHost)); - int idx = 0; - float loss = 0.0f; - for (PointInRectIterator<3> it(rect_x_grad); it(); it++, idx++) { - if (host_ptr[idx] < 0) { - loss += -std::log(host_ptr[idx] + 1); - } - } - printf("lost = %.4lf\n", loss); - checkCUDA(cudaFreeHost(host_ptr)); -#endif -#endif -} - -void SoftmaxDP::backward(RnnModel const &model) { - Context ctx = model.config.lg_ctx; - Runtime *runtime = model.config.lg_hlr; - int idx = 0; - for (PointInRectIterator<1> it(part_rect); it(); it++, idx++) { - OpMeta *mp = meta[idx]; - TaskLauncher launcher(RNN_SOFTMAXDP_BWD_TASK_ID, - TaskArgument(&mp, sizeof(OpMeta *)), - Predicate::TRUE_PRED, - 0 /*MapperID*/, - RnnMapper::assign_to_gpu(paraConfig.gpu[idx])); - DomainPoint dp(*it); - { - LogicalRegion x = - runtime->get_logical_subregion_by_color(logit_grad_lp, dp); - launcher.add_region_requirement( - RegionRequirement(x, WRITE_ONLY, EXCLUSIVE, inputs[0].region_grad)); - launcher.add_field(0, FID_DATA); - } - { - LogicalRegion y = - runtime->get_logical_subregion_by_color(outputs[0].partition, dp); - launcher.add_region_requirement( - RegionRequirement(y, READ_ONLY, EXCLUSIVE, outputs[0].region)); - launcher.add_field(1, FID_DATA); - } - { - LogicalRegion l = - runtime->get_logical_subregion_by_color(label.partition, dp); - launcher.add_region_requirement( - RegionRequirement(l, READ_ONLY, EXCLUSIVE, label.region)); - launcher.add_field(2, FID_DATA); - } - runtime->execute_task(ctx, launcher); - } -} - -void SoftmaxDP::update(RnnModel const &model) {} diff --git a/pyproject.toml b/pyproject.toml new file mode 100644 index 0000000000..4b8214f3fe --- /dev/null +++ b/pyproject.toml @@ -0,0 +1,10 @@ +[build-system] +requires = [ + "wheel", + "setuptools>=45", + "setuptools_scm[toml]>=6.0", + "cmake-build-extension", + "ninja", + "requests" +] +build-backend = "setuptools.build_meta" diff --git a/python/Makefile b/python/Makefile index 07beab86f3..2edee4f0d1 100644 --- a/python/Makefile +++ b/python/Makefile @@ -30,6 +30,8 @@ FF_USE_PYTHON := 1 SHARED_OBJECTS := 1 # we build the shared lib for legion # FF_PYTHON_USE_INDEX_LOADER = 1 +INSTALL_TOKENIZERS := $(shell $(FF_HOME)/scripts/install_tokenizer.sh) + ifeq ($(shell uname -s), Darwin) PYTHON_EXT := dylib else diff --git a/python/flexflow/config.py b/python/flexflow/config.py index 44d460d832..d5f2131ae8 100644 --- a/python/flexflow/config.py +++ b/python/flexflow/config.py @@ -16,35 +16,60 @@ import os # python binding -_FF_PYTHON_BINDING = 'cffi' +_FF_PYTHON_BINDING = "cffi" -if 'FF_USE_CFFI' in os.environ: - use_pybind = not int(os.environ['FF_USE_CFFI']) +if "FF_USE_CFFI" in os.environ: + use_pybind = not int(os.environ["FF_USE_CFFI"]) else: - use_pybind = False + use_pybind = False if use_pybind: - _FF_PYTHON_BINDING = 'pybind11' + _FF_PYTHON_BINDING = "pybind11" else: - _FF_PYTHON_BINDING = 'cffi' - + _FF_PYTHON_BINDING = "cffi" + + def flexflow_python_binding(): - return _FF_PYTHON_BINDING - -# build docs -_FF_BUILD_DOCS = bool(os.environ.get('READTHEDOCS') or os.environ.get("FF_BUILD_DOCS")) - -# init import -# It is used to run __init__.py in flexflow/core -# The following cases __init__.py is not needed: -# 1. build docs = True -_FF_INIT_IMPORT = _FF_BUILD_DOCS == False - -def flexflow_init_import(): - return _FF_INIT_IMPORT - + return _FF_PYTHON_BINDING + + +_FF_ALREADY_INITIALIZED = False + + +def flexflow_already_initialized(): + global _FF_ALREADY_INITIALIZED + return _FF_ALREADY_INITIALIZED + + +def set_flexflow_initialized(): + global _FF_ALREADY_INITIALIZED + if _FF_ALREADY_INITIALIZED == True: + raise RuntimeError( + "Attempting to set _FF_ALREADY_INITIALIZED=True, but _FF_ALREADY_INITIALIZED is already True" + ) + _FF_ALREADY_INITIALIZED = True + + # FlexFlow dir _FF_DIR = os.path.dirname(os.path.realpath(__file__)) + def flexflow_dir(): - return _FF_DIR + return _FF_DIR + +# Get runtime configs from the command line +def get_configs(): + import argparse,json + parser = argparse.ArgumentParser() + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) + args, unknown = parser.parse_known_args() + if args.config_file is not None: + with open(args.config_file) as f: + return json.load(f) + else: + return None diff --git a/python/flexflow/core/__init__.py b/python/flexflow/core/__init__.py index b0177be6fa..2820cf485a 100644 --- a/python/flexflow/core/__init__.py +++ b/python/flexflow/core/__init__.py @@ -20,83 +20,131 @@ import atexit import os import sys +import warnings +from typing import Optional from flexflow.config import * -from flexflow.jupyter import * -def rerun_if_needed(): - def update_ld_library_path_if_needed(path): - ld_lib_path = os.environ.get("LD_LIBRARY_PATH") or "" - if path not in ld_lib_path.split(":"): - os.environ["LD_LIBRARY_PATH"] = path + ":" + ld_lib_path - return True - return False - from distutils import sysconfig - # When installing FlexFlow with pip, the library files are installed within - # the pip package folder, instead of at /usr/local/lib - packages_dir = sysconfig.get_python_lib(plat_specific=False, standard_lib=False) - ff_lib_path = os.path.join(packages_dir, "flexflow", "lib") - # If the library exists at the ff_lib_path, rerun with the ff_lib_path in the LD_LIBRARY_PATH - rerun=False - if os.path.isdir(ff_lib_path): - rerun = update_ld_library_path_if_needed(ff_lib_path) - if rerun: - run_from_python_c = ((sys.argv or [''])[0] == '-c') - # re-running with os.execv only works with 'python -c' for python >= 3.10 - # (see https://bugs.python.org/issue23427) - if not run_from_python_c: - os.execv(sys.executable, ["python"] + sys.argv) - else: - if hasattr(sys, 'orig_argv'): - assert(len(sys.orig_argv) >= 3) - os.execv(sys.executable, ["python"] + sys.orig_argv[1:]) - else: - print(f'Error: Please export LD_LIBRARY_PATH={os.environ.get("LD_LIBRARY_PATH")} and rerun') - sys.exit(1) +# check which python binding to use +if flexflow_python_binding() == "pybind11": + # print("Using pybind11 flexflow bindings.") + from .flexflow_pybind11 import * +else: + # print("Using cffi flexflow bindings.") + from .flexflow_cffi import * -if flexflow_init_import(): - os.environ["NCCL_LAUNCH_MODE"] = "PARALLEL" - from legion_cffi import ffi, is_legion_python - from .flexflowlib import flexflow_library - - # Default python mode - if is_legion_python == False: - os.environ["REALM_DEFAULT_ARGS"] = "-ll:gpu 1" - rerun_if_needed() - print("Using Default Python") - _FF_BUILD_DOCS = bool(os.environ.get('READTHEDOCS') or os.environ.get("FF_BUILD_DOCS")) - _CPU_ONLY = bool(os.environ.get('CPU_ONLY_TEST')) - if not _FF_BUILD_DOCS and not _CPU_ONLY: - from legion_top import ( - legion_canonical_python_main, - legion_canonical_python_cleanup, - ) - import atexit, sys, os - # run from jupyter - if "ipykernel_launcher.py" in sys.argv[0]: - sys_argv = ["python", "dummy.py"] - argv_dict = load_jupyter_config() - for key, value in argv_dict.items(): - sys_argv.append(key) - sys_argv.append(str(value)) - else: - sys_argv = [ - "python", - ] + sys.argv - legion_canonical_python_main(sys_argv) - atexit.register(legion_canonical_python_cleanup) - else: - print("Using Legion Python") +ff_arg_to_sysarg = { + # General args + "num_gpus": "-ll:gpu", + "memory_per_gpu": "-ll:fsize", + "zero_copy_memory_per_node": "-ll:zsize", + "num_cpus": "-ll:cpu", + "legion_utility_processors": "-ll:util", + "profiling": "--profiling", + "benchmarking": "--benchmarking", + "inference_debugging": "--inference-debugging", + "fusion": "--fusion", + "disable_control_replication": "--disable-control-replication", + # Training args + "epochs": "--epochs", + "batch_size": "--batch-size", + "learning_rate": "--learning-rate", + "weight_decay": "--weight-decay", + "print_frequency": "--print-freq", + "dataset": "--dataset", + "budget": "--budget", + "search_budget": "--search-budget", + "alpha": "--alpha", + "search_alpha": "--search-alpha", + "simulator_workspace_size": "--simulator-workspace-size", + "import": "--import", + "import_strategy": "--import-strategy", + "export": "--export", + "export_strategy": "--export-strategy", + "only_data_parallel": "--only-data-parallel", + "enable_parameter_parallel": "--enable-parameter-parallel", + "enable_attribute_parallel": "--enable-attribute-parallel", + "allow_tensor_op_math_conversion": "--allow-tensor-op-math-conversion", + "search_overlap_backward_update": "--overlap", + "export_strategy_task_graph_file": "--taskgraph", + "include_costs_dot_graph": "--include-costs-dot-graph", + "export_strategy_computation_graph_file": "--compgraph", + "machine_model_version": "--machine-model-version", + "machine_model_file": "--machine-model-file", + "simulator_segment_size": "--simulator-segment-size", + "simulator_max_num_segments": "--simulator-max-num-segments", + "enable_propagation": "--enable-propagation", + "enable_inplace_optimizations": "--enable-inplace-optimization", + "search_num_nodes": "--search-num-nodes", + "search_num_workers": "--search-num-workers", + "base_optimize_threshold": "--base-optimize-threshold", + "python_data_loader_type": "--python-data-loader-type", + "substitution_json_path": "--substitution-json", + "perform_memory_search": "--memory-search", + # Inference args + "data_parallelism_degree": "-data-parallelism-degree", + "tensor_parallelism_degree": "-tensor-parallelism-degree", + "pipeline_parallelism_degree": "-pipeline-parallelism-degree", + "offload": "-offload", + "offload_reserve_space_size": "-offload-reserve-space-size", + "use_4bit_quantization": "--4bit-quantization", + "use_8bit_quantization": "--8bit-quantization" +} - flexflow_library.initialize() - # check which python binding to use - if flexflow_python_binding() == 'pybind11': - print("Using pybind11 flexflow bindings.") - from .flexflow_pybind11 import * - else: - print("Using cffi flexflow bindings.") - from .flexflow_cffi import * +def init_flexflow_runtime(configs_dict: Optional[dict] = None, **kwargs): + if not flexflow_already_initialized(): + os.environ["NCCL_LAUNCH_MODE"] = "PARALLEL" + from legion_cffi import is_legion_python + from .flexflowlib import flexflow_library -else: - pass \ No newline at end of file + # Default python mode + if is_legion_python == False: + # print("Using Default Python") + from legion_top import ( + legion_canonical_python_main, + legion_canonical_python_cleanup, + ) + + # Either a configs_dict dictionary, or individual key-value parameters should be passed. Not both. + if configs_dict is not None and len(kwargs.items()) > 0: + raise ValueError("Cannot pass both configs_dict and individual args") + ff_args = configs_dict if configs_dict is not None else dict(kwargs.items()) + # Check presence of mandatory parameters + if ( + "num_gpus" not in ff_args + or "memory_per_gpu" not in ff_args + or "zero_copy_memory_per_node" not in ff_args + ): + raise ValueError( + "Missing one of the following required configs: num_gpus, memory_per_gpu, zero_copy_memory_per_node" + ) + + # Remove any existing arguments to avoid interferences + sys.argv = [sys.argv[0]] + + # Pass parameters to the FlexFlow C++ runtime via command line arguments + for arg in ff_args: + if arg not in ff_arg_to_sysarg: + # warnings.warn(f"Ignoring parameter {arg}: not recognized.") + continue + else: + sys_arg = [ff_arg_to_sysarg[arg]] + if type(ff_args[arg]) == bool: + if ff_args[arg] is not True: + continue + else: + sys_arg += [str(ff_args[arg])] + sys.argv += sys_arg + + legion_canonical_python_main(sys.argv) + atexit.register(legion_canonical_python_cleanup) + else: + # print("Using FlexFlow Python") + if configs_dict is not None or len(kwargs.items()) > 0: + warnings.warn("init_flexflow_runtime are ignored when using the FlexFlow Python interpreter") + + flexflow_library.initialize() + set_flexflow_initialized() + else: + warnings.warn("Attempting to initialize FlexFlow more than once") diff --git a/python/flexflow/core/flexflow_cffi.py b/python/flexflow/core/flexflow_cffi.py index 750838d829..0ab261654e 100644 --- a/python/flexflow/core/flexflow_cffi.py +++ b/python/flexflow/core/flexflow_cffi.py @@ -15,875 +15,709 @@ from __future__ import absolute_import, division, print_function, unicode_literals -import cffi -import os -import subprocess -import logging import warnings import numpy as np from .flexflow_logger import fflogger -from flexflow.type import ActiMode, RegularizerMode, AggrMode, PoolType, DataType, LossType, CompMode, MetricsType, OpType, ParameterSyncType, enum_to_int, int_to_enum -_FF_BUILD_DOCS = bool(os.environ.get('READTHEDOCS') or os.environ.get("FF_BUILD_DOCS")) -if not _FF_BUILD_DOCS: - from .flexflowlib import ffi, flexflow_library - ffc = flexflow_library.lib +from flexflow.type import ( + ActiMode, + RegularizerMode, + AggrMode, + PoolType, + DataType, + LossType, + CompMode, + MetricsType, + InferenceMode, + ModelType, + OpType, + ParameterSyncType, + enum_to_int, + int_to_enum, +) +from flexflow.config import * +from .flexflowlib import ffi, flexflow_library + + +def ffc(): + if not flexflow_already_initialized(): + raise RuntimeError("Cannot use FlexFlow library before initializing FlexFlow") + ffc = flexflow_library.lib + if ffc is None: + raise RuntimeError("FlexFlow library is None") + return ffc + ff_tracing_id = 200 -warnings.simplefilter('always', DeprecationWarning) +warnings.simplefilter("always", DeprecationWarning) + def get_c_name(name): - if name is None: - return ffi.NULL - else: - return ffi.new("char[]", name.encode('ascii')) + if name is None: + return ffi.NULL + else: + return ffi.new("char[]", name.encode("utf-8")) + def get_datatype_size(datatype): - if (datatype == DataType.DT_FLOAT): - return 4 - elif (datatype == DataType.DT_DOUBLE): - return 8 - elif (datatype == DataType.DT_INT32): - return 4 - elif (datatype == DataType.DT_INT64): - return 8 - else: - assert 0, "unknow datatype" + str(datatype) - return 0 + if datatype == DataType.DT_HALF: + return 2 + if datatype == DataType.DT_FLOAT: + return 4 + elif datatype == DataType.DT_DOUBLE: + return 8 + elif datatype == DataType.DT_INT32: + return 4 + elif datatype == DataType.DT_INT64: + return 8 + else: + assert 0, "unknow datatype" + str(datatype) + return 0 + # ----------------------------------------------------------------------- # Op # ----------------------------------------------------------------------- class Op(object): - __slots__ = ['handle', 'idx', 'name'] - def __init__(self, handle, idx=None, name=None): - assert ffi.typeof(handle) == ffi.typeof('flexflow_op_t'), "Op handle is wrong" - self.handle = handle - self.idx = idx - self.name = name + __slots__ = ["handle", "idx", "name"] + + def __init__(self, handle, idx=None, name=None): + assert ffi.typeof(handle) == ffi.typeof("flexflow_op_t"), "Op handle is wrong" + self.handle = handle + self.idx = idx + self.name = name + + def get_number_parameters(self): + return ffc().flexflow_op_get_num_parameters(self.handle) - def get_number_parameters(self): - return ffc.flexflow_op_get_num_parameters(self.handle) + def get_parameter_by_id(self, id): + handle = ffc().flexflow_op_get_parameter_by_id(self.handle, id) + return Parameter(handle) - def get_parameter_by_id(self, id): - handle = ffc.flexflow_op_get_parameter_by_id(self.handle, id) - return Parameter(handle) + def get_number_inputs(self): + return ffc().flexflow_op_get_num_inputs(self.handle) - def get_number_inputs(self): - return ffc.flexflow_op_get_num_inputs(self.handle) + def get_input_by_id(self, id): + handle = ffc().flexflow_op_get_input_by_id(self.handle, id) + return Tensor(handle, False) - def get_input_by_id(self, id): - handle = ffc.flexflow_op_get_input_by_id(self.handle, id) - return Tensor(handle, False) + def get_number_outputs(self): + return ffc().flexflow_op_get_num_outputs(self.handle) - def get_number_outputs(self): - return ffc.flexflow_op_get_num_outputs(self.handle) + def get_output_by_id(self, id): + handle = ffc().flexflow_op_get_output_by_id(self.handle, id) + return Tensor(handle, False) - def get_output_by_id(self, id): - handle = ffc.flexflow_op_get_output_by_id(self.handle, id) - return Tensor(handle, False) + def init(self, model): + ffc().flexflow_op_init(self.handle, model.handle) - def init(self, model): - ffc.flexflow_op_init(self.handle, model.handle) + def forward(self, model): + ffc().flexflow_op_forward(self.handle, model.handle) + # return Tensor(handle) - def forward(self, model): - ffc.flexflow_op_forward(self.handle, model.handle) - #return Tensor(handle) + def _add_to_model(self, model): + ffc().flexflow_op_add_to_model(self.handle, model.handle) - def _add_to_model(self, model): - ffc.flexflow_op_add_to_model(self.handle, model.handle) + def get_output_tensor(self): + return self.get_output_by_id(0) - def get_output_tensor(self): - return self.get_output_by_id(0) # ----------------------------------------------------------------------- # Exp # ----------------------------------------------------------------------- class Exp(Op): - def __init__(self, handle, idx=None, name=None): - super(Exp, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Exp, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Sin # ----------------------------------------------------------------------- class Sin(Op): - def __init__(self, handle, idx=None, name=None): - super(Sin, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Sin, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Cos # ----------------------------------------------------------------------- class Cos(Op): - def __init__(self, handle, idx=None, name=None): - super(Cos, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Cos, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Add # ----------------------------------------------------------------------- class Add(Op): - def __init__(self, handle, idx=None, name=None): - super(Add, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Add, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Subtract # ----------------------------------------------------------------------- class Subtract(Op): - def __init__(self, handle, idx=None, name=None): - super(Subtract, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Subtract, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Multiply # ----------------------------------------------------------------------- class Multiply(Op): - def __init__(self, handle, idx=None, name=None): - super(Multiply, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Multiply, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Divide # ----------------------------------------------------------------------- class Divide(Op): - def __init__(self, handle, idx=None, name=None): - super(Divide, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Divide, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Max # ----------------------------------------------------------------------- class Max(Op): - def __init__(self, handle, idx=None, name=None): - super(Max, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Max, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Min # ----------------------------------------------------------------------- class Min(Op): - def __init__(self, handle, idx=None, name=None): - super(Min, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Min, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # ReduceSum # ----------------------------------------------------------------------- class ReduceSum(Op): - def __init__(self, handle, idx=None, name=None): - super(ReduceSum, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(ReduceSum, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Conv2D # ----------------------------------------------------------------------- class Conv2D(Op): - def __init__(self, handle, idx=None, name=None): - super(Conv2D, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Conv2D, self).__init__(handle, idx, name) + + def get_weight_tensor(self): + return self.get_parameter_by_id(0) - def get_weight_tensor(self): - return self.get_parameter_by_id(0) + def get_bias_tensor(self): + return self.get_parameter_by_id(1) - def get_bias_tensor(self): - return self.get_parameter_by_id(1) + def get_input_tensor(self): + return self.get_input_by_id(0) - def get_input_tensor(self): - return self.get_input_by_id(0) + def get_output_tensor(self): + return self.get_output_by_id(0) - def get_output_tensor(self): - return self.get_output_by_id(0) # ----------------------------------------------------------------------- # Pool2D # ----------------------------------------------------------------------- class Pool2D(Op): - def __init__(self, handle, idx=None, name=None): - super(Pool2D, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Pool2D, self).__init__(handle, idx, name) - def get_input_tensor(self): - return self.get_input_by_id(0) + def get_input_tensor(self): + return self.get_input_by_id(0) + + def get_output_tensor(self): + return self.get_output_by_id(0) - def get_output_tensor(self): - return self.get_output_by_id(0) # ----------------------------------------------------------------------- # Linear # ----------------------------------------------------------------------- class Linear(Op): - def __init__(self, handle, idx=None, name=None): - super(Linear, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Linear, self).__init__(handle, idx, name) + + def get_weight_tensor(self): + return self.get_parameter_by_id(0) - def get_weight_tensor(self): - return self.get_parameter_by_id(0) + def get_bias_tensor(self): + return self.get_parameter_by_id(1) - def get_bias_tensor(self): - return self.get_parameter_by_id(1) + def get_input_tensor(self): + return self.get_input_by_id(0) - def get_input_tensor(self): - return self.get_input_by_id(0) + def get_output_tensor(self): + return self.get_output_by_id(0) - def get_output_tensor(self): - return self.get_output_by_id(0) # ----------------------------------------------------------------------- # Flat # ----------------------------------------------------------------------- class Flat(Op): - def __init__(self, handle, idx=None, name=None): - super(Flat, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Flat, self).__init__(handle, idx, name) - def get_input_tensor(self): - return self.get_input_by_id(0) + def get_input_tensor(self): + return self.get_input_by_id(0) + + def get_output_tensor(self): + return self.get_output_by_id(0) - def get_output_tensor(self): - return self.get_output_by_id(0) # ----------------------------------------------------------------------- # Softmax # ----------------------------------------------------------------------- class Softmax(Op): - def __init__(self, handle, idx=None, name=None): - super(Softmax, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Softmax, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Embedding # ----------------------------------------------------------------------- class Embedding(Op): - def __init__(self, handle, idx=None, name=None): - super(Embedding, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Embedding, self).__init__(handle, idx, name) + + def get_weight_tensor(self): + return self.get_parameter_by_id(0) - def get_weight_tensor(self): - return self.get_parameter_by_id(0) # ----------------------------------------------------------------------- # Concat # ----------------------------------------------------------------------- class Concat(Op): - def __init__(self, handle, idx=None, name=None): - super(Concat, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Concat, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # BatchNorm # ----------------------------------------------------------------------- class BatchNorm(Op): - def __init__(self, handle, idx=None, name=None): - super(BatchNorm, self).__init__(handle, idx, name) - + def __init__(self, handle, idx=None, name=None): + super(BatchNorm, self).__init__(handle, idx, name) + + # ----------------------------------------------------------------------- # LayerNorm # ----------------------------------------------------------------------- class LayerNorm(Op): - def __init__(self, handle, idx=None, name=None): - super(LayerNorm, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(LayerNorm, self).__init__(handle, idx, name) + + def get_weight_tensor(self): + return self.get_parameter_by_id(0) - def get_weight_tensor(self): - return self.get_parameter_by_id(0) + def get_bias_tensor(self): + return self.get_parameter_by_id(1) + + +# ----------------------------------------------------------------------- +# ResidualLayerNorm +# ----------------------------------------------------------------------- +class ResidualLayerNorm(Op): + def __init__(self, handle, idx=None, name=None): + super(ResidualLayerNorm, self).__init__(handle, idx, name) + + def get_weight_tensor(self): + return self.get_parameter_by_id(1) + + def get_bias_tensor(self): + return self.get_parameter_by_id(2) + + +# ----------------------------------------------------------------------- +# AddBiasResidualLayerNorm +# ----------------------------------------------------------------------- +class AddBiasResidualLayerNorm(Op): + def __init__(self, handle, idx=None, name=None): + super(AddBiasResidualLayerNorm, self).__init__(handle, idx, name) + + def get_attn_bias_tensor(self): + return self.get_parameter_by_id(0) + + def get_weight_tensor(self): + return self.get_parameter_by_id(1) + + def get_bias_tensor(self): + return self.get_parameter_by_id(2) + + +# ----------------------------------------------------------------------- +# SigmoidSiluMulti +# ----------------------------------------------------------------------- +class SigmoidSiluMulti(Op): + def __init__(self, handle, idx=None, name=None): + super(SigmoidSiluMulti, self).__init__(handle, idx, name) - def get_bias_tensor(self): - return self.get_parameter_by_id(1) # ----------------------------------------------------------------------- # Dropout # ----------------------------------------------------------------------- class Dropout(Op): - def __init__(self, handle, idx=None, name=None): - super(Dropout, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Dropout, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # ScalarMultiply # ----------------------------------------------------------------------- class ScalarMultiply(Op): - def __init__(self, handle, idx=None, name=None): - super(ScalarMultiply, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(ScalarMultiply, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # ScalarAdd # ----------------------------------------------------------------------- class ScalarAdd(Op): - def __init__(self, handle, idx=None, name=None): - super(ScalarAdd, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(ScalarAdd, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # ScalarSub # ----------------------------------------------------------------------- class ScalarSub(Op): - def __init__(self, handle, idx=None, name=None): - super(ScalarSub, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(ScalarSub, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # ScalarTrueDiv # ----------------------------------------------------------------------- class ScalarTrueDiv(Op): - def __init__(self, handle, idx=None, name=None): - super(ScalarTrueDiv, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(ScalarTrueDiv, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Rsqrt # ----------------------------------------------------------------------- class Rsqrt(Op): - def __init__(self, handle, idx=None, name=None): - super(Rsqrt, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Rsqrt, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Pow # ----------------------------------------------------------------------- class Pow(Op): - def __init__(self, handle, idx=None, name=None): - super(Pow, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Pow, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Mean # ----------------------------------------------------------------------- class Mean(Op): - def __init__(self, handle, idx=None, name=None): - super(Mean, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Mean, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Relu # ----------------------------------------------------------------------- class Relu(Op): - def __init__(self, handle, idx=None, name=None): - super(Relu, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Relu, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Gelu # ----------------------------------------------------------------------- class Gelu(Op): - def __init__(self, handle, idx=None, name=None): - super(Gelu, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Gelu, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Sigmod # ----------------------------------------------------------------------- class Sigmoid(Op): - def __init__(self, handle, idx=None, name=None): - super(Sigmoid, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Sigmoid, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Tanh # ----------------------------------------------------------------------- class Tanh(Op): - def __init__(self, handle, idx=None, name=None): - super(Tanh, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Tanh, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Elu # ----------------------------------------------------------------------- class Elu(Op): - def __init__(self, handle, idx=None, name=None): - super(Elu, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Elu, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Batch_Norm # ----------------------------------------------------------------------- class Batch_Norm(Op): - def __init__(self, handle, idx=None, name=None): - super(Batch_Norm, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Batch_Norm, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Batch_Matmul # ----------------------------------------------------------------------- class Batch_Matmul(Op): - def __init__(self, handle, idx=None, name=None): - super(Batch_Matmul, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Batch_Matmul, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Split # ----------------------------------------------------------------------- class Split(Op): - def __init__(self, handle, idx=None, name=None): - super(Split, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Split, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Reshape # ----------------------------------------------------------------------- class Reshape(Op): - def __init__(self, handle, idx=None, name=None): - super(Reshape, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Reshape, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Gather # ----------------------------------------------------------------------- class Gather(Op): - def __init__(self, handle, idx=None, name=None): - super(Gather, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Gather, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Identity # ----------------------------------------------------------------------- class Identity(Op): - def __init__(self, handle, idx=None, name=None): - super(Identity, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Identity, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Transpose # ----------------------------------------------------------------------- class Transpose(Op): - def __init__(self, handle, idx=None, name=None): - super(Transpose, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(Transpose, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- # Reverse # ----------------------------------------------------------------------- class Reverse(Op): - def __init__(self, handle, idx=None, name=None): - super(Reverse, self).__init__(handle, idx, name) - + def __init__(self, handle, idx=None, name=None): + super(Reverse, self).__init__(handle, idx, name) + + # ----------------------------------------------------------------------- # MultiHeadAttention # ----------------------------------------------------------------------- class MultiHeadAttention(Op): - def __init__(self, handle, idx=None, name=None): - super(MultiHeadAttention, self).__init__(handle, idx, name) + def __init__(self, handle, idx=None, name=None): + super(MultiHeadAttention, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- -# flexflow_op_t handle to Op +# Incremental MultiHeadAttention # ----------------------------------------------------------------------- -def convert_op_handle_to_op(op_type, handle, idx=None, name=None): - if op_type == OpType.CONV2D: - return Conv2D(handle, idx, name) - elif op_type == OpType.POOL2D: - return Pool2D(handle, idx, name) - elif op_type == OpType.LINEAR: - return Linear(handle, idx, name) - elif op_type == OpType.EMBEDDING: - return Embedding(handle, idx, name) - elif op_type == OpType.FLAT: - return Flat(handle, idx, name) - elif op_type == OpType.CONCAT: - return Concat(handle, idx, name) - elif op_type == OpType.SOFTMAX: - return Softmax(handle, idx, name) - elif op_type == OpType.EXP: - return Exp(handle, idx, name) - elif op_type == OpType.SIN: - return Sin(handle, idx, name) - elif op_type == OpType.COS: - return Cos(handle, idx, name) - elif op_type == OpType.ADD: - return Add(handle, idx, name) - elif op_type == OpType.SUBTRACT: - return Subtract(handle, idx, name) - elif op_type == OpType.MULTIPLY: - return Multiply(handle, idx, name) - elif op_type == OpType.DIVIDE: - return Divide(handle, idx, name) - elif op_type == OpType.MAX: - return Max(handle, idx, name) - elif op_type == OpType.MIN: - return Min(handle, idx, name) - elif op_type == OpType.REDUCE_SUM: - return ReduceSum(handle, idx, name) - elif op_type == OpType.MSELOSS: - return MSELoss(handle, idx, name) - elif op_type == OpType.SCALAR_MULTIPLY: - return ScalarMultiply(handle, idx, name) - elif op_type == OpType.SCALAR_ADD: - return ScalarAdd(handle, idx, name) - elif op_type == OpType.SCALAR_SUB: - return ScalarSub(handle, idx, name) - elif op_type == OpType.SCALAR_FLOORDIV: - return ScalarFloorDiv(handle, idx, name) - elif op_type == OpType.SCALAR_TRUEDIV: - return ScalarTrueDiv(handle, idx, name) - elif op_type == OpType.GELU: - return Gelu(handle, idx, name) - elif op_type == OpType.RELU: - return Relu(handle, idx, name) - elif op_type == OpType.SIGMOID: - return Sigmoid(handle, idx, name) - elif op_type == OpType.TANH: - return Tanh(handle, idx, name) - elif op_type == OpType.ELU: - return Elu(handle, idx, name) - elif op_type == OpType.DROPOUT: - return Dropout(handle, idx, name) - elif op_type == OpType.BATCH_NORM: - return BatchNorm(handle, idx, name) - elif op_type == OpType.LAYER_NORM: - return LayerNorm(handle, idx, name) - elif op_type == OpType.BATCH_MATMUL: - return Batch_Matmul(handle, idx, name) - elif op_type == OpType.SPLIT: - return Split(handle, idx, name) - elif op_type == OpType.RESHAPE: - return Reshape(handle, idx, name) - elif op_type == OpType.IDENTITY: - return Identity(handle,idx,name) - elif op_type == OpType.TRANSPOSE: - return Transpose(handle, idx, name) - elif op_type == OpType.REVERSE: - return Reverse(handle, idx, name) - elif op_type == OpType.MULTIHEAD_ATTENTION: - return Reverse(handle, idx, name) - elif op_type == OpType.RSQRT: - return Rsqrt(handle, idx, name) - elif op_type == OpType.POW: - return Pow(handle, idx, name) - elif op_type == OpType.MEAN: - return Mean(handle, idx, name) - elif op_type == OpType.GATHER: - return Gather(handle, idx, name) - else: - assert 0, "unknown layer type {}".format(op_type) - return None +class IncMultiHeadAttention(Op): + def __init__(self, handle, idx=None, name=None): + super(IncMultiHeadAttention, self).__init__(handle, idx, name) + # ----------------------------------------------------------------------- -# FFConfig +# Speculative Incremental MultiHeadAttention # ----------------------------------------------------------------------- +class SpecIncMultiHeadSelfAttention(Op): + def __init__(self, handle, idx=None, name=None): + super(SpecIncMultiHeadSelfAttention, self).__init__(handle, idx, name) -class FFConfig(object): - __slots__ = ['handle', '_handle', 'enable_tracing'] - def __init__(self): - self.handle = ffc.flexflow_config_create() - self._handle = ffi.gc(self.handle, ffc.flexflow_config_destroy) - self.enable_tracing = False - - def parse_args(self): - ffc.flexflow_config_parse_args_default(self.handle) - - @property - def batch_size(self): - return ffc.flexflow_config_get_batch_size(self.handle) - - @property - def workers_per_node(self): - return ffc.flexflow_config_get_workers_per_node(self.handle) - - @property - def num_nodes(self): - return ffc.flexflow_config_get_num_nodes(self.handle) - - @property - def epochs(self): - return ffc.flexflow_config_get_epochs(self.handle) - - @property - def enable_control_replication(self): - return ffc.flexflow_config_get_enable_control_replication(self.handle) - - @property - def python_data_loader_type(self): - return ffc.flexflow_config_get_python_data_loader_type(self.handle) - def get_current_time(self): - return ffc.flexflow_get_current_time(self.handle) +# ----------------------------------------------------------------------- +# TreeVerify Incremental MultiHeadAttention +# ----------------------------------------------------------------------- +class TreeIncMultiHeadSelfAttention(Op): + def __init__(self, handle, idx=None, name=None): + super(TreeIncMultiHeadSelfAttention, self).__init__(handle, idx, name) + - def begin_trace(self, trace_id): - if self.enable_tracing: - ffc.flexflow_begin_trace(self.handle, trace_id) +# ----------------------------------------------------------------------- +# RMS Norm +# ----------------------------------------------------------------------- +class RMSNorm(Op): + def __init__(self, handle, idx=None, name=None): + super(RMSNorm, self).__init__(handle, idx, name) - def end_trace(self, trace_id): - if self.enable_tracing: - ffc.flexflow_end_trace(self.handle, trace_id) # ----------------------------------------------------------------------- -# Tensor +# Residual RMS Norm # ----------------------------------------------------------------------- +class ResidualRMSNorm(Op): + def __init__(self, handle, idx=None, name=None): + super(ResidualRMSNorm, self).__init__(handle, idx, name) -class Tensor(object): - __slots__ = ['p_handle', 'handle', '_handle', 'num_dims', 'dims', 'data_type', 'owner_op', 'mapped'] - def __init__(self, handle, deallocate=True, owner_op_type=None, p_handle=None): - if handle == None and ffi.typeof(p_handle) == ffi.typeof('flexflow_tensor_t*'): - self.p_handle = p_handle - self.handle = self.p_handle[0] - elif handle != None and ffi.typeof(handle) == ffi.typeof('flexflow_tensor_t'): - self.p_handle = 0 - self.handle = handle - #elif handle != None and ffi.typeof(handle) == ffi.typeof('flexflow_tensor_t'): - # self.p_handle = ffi.new('flexflow_tensor_t *') - # self.p_handle.impl = handle.impl - # self.handle = self.p_handle[0] - else: - assert 0, "Tensor handle is wrong" - self.num_dims = 0 - self.dims = 0 - self.mapped = False - self.__get_dims() - self.__get_data_type() - # if (deallocate == True): - # self._handle = ffi.gc(self.handle, ffc.flexflow_tensor_destroy) - # if (self.is_mapped() == True): - # self.mapped = True - - if owner_op_type != None: - self.__get_owner_op(owner_op_type) - assert self.owner_op != None - - def inline_map(self, ffmodel, ffconfig): - assert self.mapped == False, "Tensor is already mapped." - ffc.flexflow_tensor_inline_map(self.handle, ffmodel.handle, ffconfig.handle); - self.mapped = True - assert self.num_dims > 0, "check dims" - - def inline_unmap(self, ffmodel, ffconfig): - assert self.mapped == True, "Tensor is not inline mapped." - ffc.flexflow_tensor_inline_unmap(self.handle, ffmodel.handle, ffconfig.handle); - self.mapped = False - - def get_array(self, ffmodel, ffconfig): - assert self.mapped == True, "Tensor is not mapped." - raw_ptr = self.__get_raw_ptr(ffmodel, ffconfig, self.data_type) - raw_ptr_int = int(ffi.cast("uintptr_t", raw_ptr)) - fflogger.debug("raw_ptr: %s, %d" %( str(raw_ptr), raw_ptr_int)) - strides = None - if (self.num_dims >= 1 or self.num_dims <= 4): - shape = self.dims - else: - assert 0, "unknow num_dims" - initializer = RegionNdarray(shape, self.data_type, raw_ptr_int, strides, False) - array = np.asarray(initializer) - # print("stride", array.__array_interface__['strides']) - return array - - def get_flat_array(self, ffmodel, ffconfig): - assert self.mapped == True, "Tensor is not mapped." - raw_ptr = self.__get_raw_ptr(ffmodel, ffconfig, self.data_type) - raw_ptr_int = int(ffi.cast("uintptr_t", raw_ptr)) - fflogger.debug("raw_ptr: %s, %d" %( str(raw_ptr), raw_ptr_int)) - strides = None - if (self.num_dims >= 1 or self.num_dims <= 4): - shape_prod = np.prod(self.dims) - shape = (shape_prod,) - else: - assert 0, "unknown num_dims" - initializer = RegionNdarray(shape, self.data_type, raw_ptr_int, strides, False) - array = np.asarray(initializer) - return array - - def attach_numpy_array(self, ffmodel, ffconfig, np_array): - assert np_array.__array_interface__['strides'] == None, "numpy array strides is not None" - np_shape = np_array.shape - num_dims = len(np_shape) - assert num_dims == self.num_dims, "please check dims (%d == %d)" %(num_dims, self.num_dims) - for i in range(0, num_dims): - assert np_shape[i] == self.dims[i], "please check shape dim %d (%d == %d)" %(i, np_shape[i], self.dims[i]) - np_raw_ptr = np_array.__array_interface__['data'] - raw_ptr = ffi.cast("void*", np_raw_ptr[0]) - fflogger.debug("attach numpy array: %s, %s, %s" %( str(np_raw_ptr), str(raw_ptr), hex(np_raw_ptr[0]))) - self.__attach_raw_ptr(ffmodel, ffconfig, raw_ptr) - - def detach_numpy_array(self, ffconfig): - self.__detach_raw_ptr(ffconfig) - - def is_mapped(self): - return ffc.flexflow_tensor_is_mapped(self.handle) - - def set_tensor(self, ffmodel, np_array): - assert np_array.__array_interface__['strides'] == None, "Parameter set_weights, numpy array strides is not None" - np_shape = np_array.shape - num_dims = len(np_shape) - assert num_dims == self.num_dims, "please check dims (%d == %d)" %(num_dims, self.num_dims) - for i in range(0, num_dims): - assert np_shape[i] == self.dims[i], "please check shape dim %d (%d == %d)" %(i, np_shape[i], self.dims[i]) - c_dims = ffi.new("int[]", self.dims) - np_raw_ptr = np_array.__array_interface__['data'] - if np_array.dtype == np.float32: - assert self.data_type == DataType.DT_FLOAT, "Wrong datatype" - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_set_tensor_float(self.handle, ffmodel.handle, num_dims, c_dims, raw_ptr) - elif np_array.dtype == np.int32: - assert self.data_type == DataType.DT_INT32, "Wrong datatype" - raw_ptr = ffi.cast("int*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_set_tensor_int(self.handle, ffmodel.handle, num_dims, c_dims, raw_ptr) - else: - assert 0, "Unsupported datatype" - fflogger.debug("set tensor raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(np_shape))) - assert ret_val == True, ret_val - - def get_tensor(self, ffmodel): - shape = self.dims - if self.data_type == DataType.DT_FLOAT: - np_array = np.empty(shape, dtype=np.float32) - elif self.data_type == DataType.DT_INT32: - np_array = np.empty(shape, dtype=np.int32) - elif self.data_type == DataType.DT_INT64: - np_array = np.empty(shape, dtype=np.int64) - else: - assert 0, f"Unsupported datatype: {self.data_type}" - np_raw_ptr = np_array.__array_interface__['data'] - if np_array.dtype == np.float32: - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_float(self.handle, ffmodel.handle, raw_ptr, False) - elif np_array.dtype == np.int32: - raw_ptr = ffi.cast("int*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int(self.handle, ffmodel.handle, raw_ptr, False) - elif np_array.dtype == np.int64: - raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int64(self.handle, ffmodel.handle, raw_ptr, False) - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - assert ret_val == True - return np_array - - def get_gradients(self, ffmodel, comm_type): - shape = self.dims - if self.data_type == DataType.DT_FLOAT: - np_array = np.empty(shape, dtype=np.float32) - elif self.data_type == DataType.DT_INT32: - np_array = np.empty(shape, dtype=np.int32) - elif self.data_type == DataType.DT_INT64: - np_array = np.empty(shape, dtype=np.int64) - else: - assert 0, f"Unsupported datatype: {self.data_type}" - np_raw_ptr = np_array.__array_interface__['data'] - c_comm_type = enum_to_int(ParameterSyncType, comm_type) - if np_array.dtype == np.float32: - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_float(self.handle, ffmodel.handle, raw_ptr, True) - elif np_array.dtype == np.int32: - raw_ptr = ffi.cast("int*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int(self.handle, ffmodel.handle, raw_ptr, True) - elif np_array.dtype == np.int64: - raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int64(self.handle, ffmodel.handle, raw_ptr, True) - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - assert ret_val == True - return np_array - - def get_model_output_gradients(self, ffmodel, comm_type): - shape = self.dims - if self.data_type == DataType.DT_FLOAT: - np_array = np.empty(shape, dtype=np.float32) - elif self.data_type == DataType.DT_INT32: - np_array = np.empty(shape, dtype=np.int32) - elif self.data_type == DataType.DT_INT64: - np_array = np.empty(shape, dtype=np.int64) - else: - assert 0, f"Unsupported datatype: {self.data_type}" - np_raw_ptr = np_array.__array_interface__['data'] - c_comm_type = enum_to_int(ParameterSyncType, comm_type) - if np_array.dtype == np.float32: - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_model_get_output_tensor_float(ffmodel.handle, self.handle, raw_ptr, True) - else: - assert 0, "unknown data type" - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - assert ret_val == True - return np_array - - def get_model_output_tensor(self, ffmodel): - shape = self.dims - if self.data_type == DataType.DT_FLOAT: - np_array = np.empty(shape, dtype=np.float32) - elif self.data_type == DataType.DT_INT32: - np_array = np.empty(shape, dtype=np.int32) - elif self.data_type == DataType.DT_INT64: - np_array = np.empty(shape, dtype=np.int64) - else: - assert 0, f"Unsupported datatype: {self.data_type}" - np_raw_ptr = np_array.__array_interface__['data'] - if np_array.dtype == np.float32: - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_model_get_output_tensor_float(ffmodel.handle, self.handle, raw_ptr, False) - else: - assert 0, "unknown data type" - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - assert ret_val == True - return np_array - - def __get_raw_ptr(self, ffmodel, ffconfig, data_type): - assert data_type == self.data_type, "Tensor check data type" - if (data_type == DataType.DT_FLOAT): - return ffc.flexflow_tensor_get_raw_ptr_float(self.handle, ffmodel.handle, ffconfig.handle) - elif (data_type == DataType.DT_INT32): - return ffc.flexflow_tensor_get_raw_ptr_int32(self.handle, ffmodel.handle, ffconfig.handle) - else: - assert 0, "unknown data type" - - def __get_dims(self): - self.num_dims = ffc.flexflow_tensor_get_num_dims(self.handle) - # if (self.num_dims == 1): - # self.dims = (ffc.flexflow_tensor_get_dim(self.handle, 0),) - # elif (self.num_dims == 2): - # self.dims = (ffc.flexflow_tensor_get_dim(self.handle, 1), ffc.flexflow_tensor_get_dim(self.handle, 0)) - # elif (self.num_dims == 3): - # self.dims = (ffc.flexflow_tensor_get_dim(self.handle, 2), ffc.flexflow_tensor_get_dim(self.handle, 1), ffc.flexflow_tensor_get_dim(self.handle, 0)) - # elif (self.num_dims == 4): - # self.dims = (ffc.flexflow_tensor_get_dim(self.handle, 3), ffc.flexflow_tensor_get_dim(self.handle, 2), ffc.flexflow_tensor_get_dim(self.handle, 1), ffc.flexflow_tensor_get_dim(self.handle, 0)) - # elif (self.num_dims == 5): - # self.dims = (ffc.flexflow_tensor_get_dim(self.handle, 4), ffc.flexflow_tensor_get_dim(self.handle, 3), ffc.flexflow_tensor_get_dim(self.handle, 2), ffc.flexflow_tensor_get_dim(self.handle, 1), ffc.flexflow_tensor_get_dim(self.handle, 0)) - # else: - # assert 0, "unknown num_dims" - d = ffc.flexflow_tensor_get_dims(self.handle) - if (self.num_dims == 1): - self.dims = (d[0],) - elif (self.num_dims == 2): - self.dims = (d[1], d[0]) - elif (self.num_dims == 3): - self.dims = (d[2], d[1], d[0]) - elif (self.num_dims == 4): - self.dims = (d[3], d[2], d[1], d[0]) - elif (self.num_dims == 5): - self.dims = (d[4], d[3], d[2], d[1], d[0]) - else: - assert 0, "unknown num_dims" - - def __get_data_type(self): - dtype = ffc.flexflow_tensor_get_data_type(self.handle) - if (dtype == 40): - self.data_type = DataType.DT_BOOLEAN - elif (dtype == 41): - self.data_type = DataType.DT_INT32 - elif (dtype == 42): - self.data_type = DataType.DT_INT64 - elif (dtype == 43): - self.data_type = DataType.DT_HALF - elif (dtype == 44): - self.data_type = DataType.DT_FLOAT - elif (dtype == 45): - self.data_type = DataType.DT_DOUBLE - else: - assert 0, "unknown data type {}".format(dtype) - def __get_owner_op(self, op_type): - op_handle = ffc.flexflow_tensor_get_owner_op(self.handle) - if op_handle.impl == ffi.NULL: - self.owner_op = None - else: - self.owner_op = convert_op_handle_to_op(op_type, op_handle) +# ----------------------------------------------------------------------- +# ArgTopK +# ----------------------------------------------------------------------- +class ArgTopK(Op): + def __init__(self, handle, idx=None, name=None): + super(ArgTopK, self).__init__(handle, idx, name) + - def __attach_raw_ptr(self, ffmodel, ffconfig, raw_ptr, column_major=True): - assert self.mapped == False, "Tensor is already mapped." - ffc.flexflow_tensor_attach_raw_ptr(self.handle, ffmodel.handle, ffconfig.handle, raw_ptr, column_major) - self.mapped = True +# ----------------------------------------------------------------------- +# BeamTopK +# ----------------------------------------------------------------------- +class BeamTopK(Op): + def __init__(self, handle, idx=None, name=None): + super(BeamTopK, self).__init__(handle, idx, name) - def __detach_raw_ptr(self, ffconfig): - assert self.mapped == True, "Tensor is not mapped." - ffc.flexflow_tensor_detach_raw_ptr(self.handle, ffconfig.handle) - self.mapped = False # ----------------------------------------------------------------------- -# Parameter +# Sampling # ----------------------------------------------------------------------- +class Sampling(Op): + def __init__(self, handle, idx=None, name=None): + super(Sampling, self).__init__(handle, idx, name) -class Parameter(Tensor): - __slots__ = ['parameter_handle'] - def __init__(self, handle): - assert ffi.typeof(handle) == ffi.typeof('flexflow_tensor_t'), "Parameter handle is wrong" - self.parameter_handle = handle - super(Parameter, self).__init__(self.parameter_handle, deallocate=False) - - def set_weights(self, ffmodel, np_array): - assert np_array.__array_interface__['strides'] == None, "Parameter set_weights, numpy array strides is not None" - np_shape = np_array.shape - num_dims = len(np_shape) - assert num_dims == self.num_dims, "please check dims (%d == %d)" %(num_dims, self.num_dims) - print(np_shape, self.dims) - for i in range(0, num_dims): - assert np_shape[i] == self.dims[i], "please check shape dim %d (%d == %d)" %(i, np_shape[i], self.dims[i]) - c_dims = ffi.new("int[]", self.dims) - np_raw_ptr = np_array.__array_interface__['data'] - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - fflogger.debug("set weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(np_shape))) - ret_val = ffc.flexflow_tensor_set_tensor_float(self.parameter_handle, ffmodel.handle, num_dims, c_dims, raw_ptr) - assert ret_val == True, ret_val - - def get_weights(self, ffmodel): - shape = self.dims - np_array = np.empty(shape, dtype=np.float32) - np_raw_ptr = np_array.__array_interface__['data'] - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - ret_val = ffc.flexflow_tensor_get_tensor_float(self.parameter_handle, ffmodel.handle, raw_ptr, False) - assert ret_val == True - return np_array # ----------------------------------------------------------------------- -# FFModel +# ArgMax # ----------------------------------------------------------------------- +class ArgMax(Op): + def __init__(self, handle, idx=None, name=None): + super(ArgMax, self).__init__(handle, idx, name) + +# ----------------------------------------------------------------------- +# flexflow_op_t handle to Op +# ----------------------------------------------------------------------- +def convert_op_handle_to_op(op_type, handle, idx=None, name=None): + if op_type == OpType.CONV2D: + return Conv2D(handle, idx, name) + elif op_type == OpType.POOL2D: + return Pool2D(handle, idx, name) + elif op_type == OpType.LINEAR: + return Linear(handle, idx, name) + elif op_type == OpType.EMBEDDING: + return Embedding(handle, idx, name) + elif op_type == OpType.FLAT: + return Flat(handle, idx, name) + elif op_type == OpType.CONCAT: + return Concat(handle, idx, name) + elif op_type == OpType.SOFTMAX: + return Softmax(handle, idx, name) + elif op_type == OpType.EXP: + return Exp(handle, idx, name) + elif op_type == OpType.SIN: + return Sin(handle, idx, name) + elif op_type == OpType.COS: + return Cos(handle, idx, name) + elif op_type == OpType.ADD: + return Add(handle, idx, name) + elif op_type == OpType.SUBTRACT: + return Subtract(handle, idx, name) + elif op_type == OpType.MULTIPLY: + return Multiply(handle, idx, name) + elif op_type == OpType.DIVIDE: + return Divide(handle, idx, name) + elif op_type == OpType.MAX: + return Max(handle, idx, name) + elif op_type == OpType.MIN: + return Min(handle, idx, name) + elif op_type == OpType.REDUCE_SUM: + return ReduceSum(handle, idx, name) + elif op_type == OpType.MSELOSS: + return MSELoss(handle, idx, name) + elif op_type == OpType.SCALAR_MULTIPLY: + return ScalarMultiply(handle, idx, name) + elif op_type == OpType.SCALAR_ADD: + return ScalarAdd(handle, idx, name) + elif op_type == OpType.SCALAR_SUB: + return ScalarSub(handle, idx, name) + elif op_type == OpType.SCALAR_FLOORDIV: + return ScalarFloorDiv(handle, idx, name) + elif op_type == OpType.SCALAR_TRUEDIV: + return ScalarTrueDiv(handle, idx, name) + elif op_type == OpType.GELU: + return Gelu(handle, idx, name) + elif op_type == OpType.RELU: + return Relu(handle, idx, name) + elif op_type == OpType.SIGMOID: + return Sigmoid(handle, idx, name) + elif op_type == OpType.TANH: + return Tanh(handle, idx, name) + elif op_type == OpType.ELU: + return Elu(handle, idx, name) + elif op_type == OpType.DROPOUT: + return Dropout(handle, idx, name) + elif op_type == OpType.BATCH_NORM: + return BatchNorm(handle, idx, name) + elif op_type == OpType.LAYER_NORM: + return LayerNorm(handle, idx, name) + elif op_type == OpType.RESIDUAL_LAYERNORM: + return ResidualLayerNorm(handle, idx, name) + elif op_type == OpType.ADD_BIAS_RESIDUAL_LAYERNORM: + return AddBiasResidualLayerNorm(handle, idx, name) + elif op_type == OpType.SIGMOID_SILU_MULTI: + return SigmoidSiluMulti(handle, idx, name) + elif op_type == OpType.BATCH_MATMUL: + return Batch_Matmul(handle, idx, name) + elif op_type == OpType.SPLIT: + return Split(handle, idx, name) + elif op_type == OpType.RESHAPE: + return Reshape(handle, idx, name) + elif op_type == OpType.IDENTITY: + return Identity(handle, idx, name) + elif op_type == OpType.TRANSPOSE: + return Transpose(handle, idx, name) + elif op_type == OpType.REVERSE: + return Reverse(handle, idx, name) + elif op_type == OpType.MULTIHEAD_ATTENTION: + return MultiHeadAttention(handle, idx, name) + elif op_type == OpType.INC_MULTIHEAD_ATTENTION: + return IncMultiHeadAttention(handle, idx, name) + elif op_type == OpType.SPEC_INC_MULTIHEAD_SELF_ATTENTION: + return SpecIncMultiHeadSelfAttention(handle, idx, name) + elif op_type == OpType.TREE_INC_MULTIHEAD_SELF_ATTENTION: + return TreeIncMultiHeadSelfAttention(handle, idx, name) + elif op_type == OpType.RMS_NORM: + return RMSNorm(handle, idx, name) + elif op_type == OpType.RESIDUAL_RMS_NORM: + return ResidualRMSNorm(handle, idx, name) + elif op_type == OpType.ARG_TOPK: + return ArgTopK(handle, idx, name) + elif op_type == OpType.BEAM_TOPK: + return BeamTopK(handle, idx, name) + elif op_type == OpType.SAMPLING: + return Sampling(handle, idx, name) + elif op_type == OpType.ARGMAX: + return ArgMax(handle, idx, name) + elif op_type == OpType.RSQRT: + return Rsqrt(handle, idx, name) + elif op_type == OpType.POW: + return Pow(handle, idx, name) + elif op_type == OpType.MEAN: + return Mean(handle, idx, name) + elif op_type == OpType.GATHER: + return Gather(handle, idx, name) class FFModel(object): """ """ @@ -913,7 +747,11 @@ def get_layers(self): def add_layer(self, op_type, name): layer_id = self._nb_layers op_handle = ffc.flexflow_model_get_last_layer(self.handle) - self._layers[self._nb_layers] = convert_op_handle_to_op(op_type, op_handle, idx=layer_id, name=name) + self._layers[self._nb_layers] = + + + + (op_type, op_handle, idx=layer_id, name=name) self._nb_layers += 1 def create_tensor(self, dims, data_type, create_grad=True): @@ -2185,353 +2023,3564 @@ def set_optimizer(self, optimizer): elif optimizer == None: pass else: - assert 0, "[Model]: unknown optimizer" + assert 0, "unknown layer type {}".format(op_type) + return None - optimizer = property(fset=set_optimizer) - def print_layers(self, id=-1): - ffc.flexflow_model_print_layers(self.handle, id) +# ----------------------------------------------------------------------- +# FFConfig +# ----------------------------------------------------------------------- - def get_layer_by_id(self, layer_id): - return self._layers[layer_id] - def get_last_layer(self): - return self._layers[self._nb_layers-1] +class FFConfig(object): + __slots__ = ["handle", "_handle", "enable_tracing"] + + def __init__(self): + self.handle = ffc().flexflow_config_create() + self._handle = ffi.gc(self.handle, ffc().flexflow_config_destroy) + self.enable_tracing = False + + def parse_args(self): + ffc().flexflow_config_parse_args_default(self.handle) + + @property + def batch_size(self): + return ffc().flexflow_config_get_batch_size(self.handle) + + @property + def workers_per_node(self): + return ffc().flexflow_config_get_workers_per_node(self.handle) + + @property + def num_nodes(self): + return ffc().flexflow_config_get_num_nodes(self.handle) + + @property + def epochs(self): + return ffc().flexflow_config_get_epochs(self.handle) + + @property + def enable_control_replication(self): + return ffc().flexflow_config_get_enable_control_replication(self.handle) + + @property + def data_parallelism_degree(self): + return ffc().flexflow_config_get_data_parallelism_degree(self.handle) + + @data_parallelism_degree.setter + def data_parallelism_degree(self, value): + if type(value) is not int: + raise ValueError( + "The data parallelism degree must be specified as an integer number" + ) + elif value < 1: + raise ValueError("The data parallelism degree cannot be lower than 1") + ffc().flexflow_config_set_data_parallelism_degree(self.handle, value) + + @property + def tensor_parallelism_degree(self): + return ffc().flexflow_config_get_tensor_parallelism_degree(self.handle) + + @tensor_parallelism_degree.setter + def tensor_parallelism_degree(self, value): + if type(value) is not int: + raise ValueError( + "The tensor parallelism degree must be specified as an integer number" + ) + elif value < 1: + raise ValueError("The tensor parallelism degree cannot be lower than 1") + ffc().flexflow_config_set_tensor_parallelism_degree(self.handle, value) + + @property + def pipeline_parallelism_degree(self): + return ffc().flexflow_config_get_pipeline_parallelism_degree(self.handle) + + @pipeline_parallelism_degree.setter + def pipeline_parallelism_degree(self, value): + if type(value) is not int: + raise ValueError( + "The pipeline parallelism degree must be specified as an integer number" + ) + elif value < 1: + raise ValueError("The pipeline parallelism degree cannot be lower than 1") + ffc().flexflow_config_set_pipeline_parallelism_degree(self.handle, value) + + @property + def python_data_loader_type(self): + return ffc().flexflow_config_get_python_data_loader_type(self.handle) + + @property + def cpu_offload(self): + return ffc().flexflow_config_get_offload(self.handle) + + def get_current_time(self): + return ffc().flexflow_get_current_time(self.handle) + + def begin_trace(self, trace_id): + if self.enable_tracing: + ffc().flexflow_begin_trace(self.handle, trace_id) + + def end_trace(self, trace_id): + if self.enable_tracing: + ffc().flexflow_end_trace(self.handle, trace_id) - def get_layer_by_name(self, layer_name): - for layer_id in self._layers: - layer = self._layers[layer_id] - if layer.name == layer_name: - return layer - assert 0, f"Cannot find the layer with name {layer_name}" - return None - def get_tensor_by_id(self, id): - handle = ffc.flexflow_model_get_parameter_by_id(self.handle, id) - return Parameter(handle) +# ----------------------------------------------------------------------- +# Tensor +# ----------------------------------------------------------------------- - @property - def label_tensor(self): - handle = ffc.flexflow_model_get_label_tensor(self.handle) - return Tensor(handle, deallocate=False) - def get_perf_metrics(self): - handle = ffc.flexflow_model_get_perf_metrics(self.handle) - return PerfMetrics(handle) - - def create_data_loader(self, batch_tensor, full_array): - """Create a SingleDataloader instance. - - :param batch_tensor: a batch-sized tensor. Usually it is a input tensor of the model. - :type batch_tensor: Tensor - - :param full_array: the entire data. - :type full_array: Numpy Array - - :returns: SingleDataloader -- returns a dataloader instance. - """ +class Tensor(object): + __slots__ = [ + "p_handle", + "handle", + "_handle", + "num_dims", + "dims", + "data_type", + "owner_op", + "mapped", + ] + + def __init__(self, handle, deallocate=True, owner_op_type=None, p_handle=None): + if handle == None and ffi.typeof(p_handle) == ffi.typeof("flexflow_tensor_t*"): + self.p_handle = p_handle + self.handle = self.p_handle[0] + elif handle != None and ffi.typeof(handle) == ffi.typeof("flexflow_tensor_t"): + self.p_handle = 0 + self.handle = handle + # elif handle != None and ffi.typeof(handle) == ffi.typeof('flexflow_tensor_t'): + # self.p_handle = ffi.new('flexflow_tensor_t *') + # self.p_handle.impl = handle.impl + # self.handle = self.p_handle[0] + else: + assert 0, "Tensor handle is wrong" + self.num_dims = 0 + self.dims = 0 + self.mapped = False + self.__get_dims() + self.__get_data_type() + # if (deallocate == True): + # self._handle = ffi.gc(self.handle, ffc().flexflow_tensor_destroy) + # if (self.is_mapped() == True): + # self.mapped = True + + if owner_op_type != None: + self.__get_owner_op(owner_op_type) + assert self.owner_op != None + + def inline_map(self, ffmodel, ffconfig): + assert self.mapped == False, "Tensor is already mapped." + ffc().flexflow_tensor_inline_map(self.handle, ffmodel.handle, ffconfig.handle) + self.mapped = True + assert self.num_dims > 0, "check dims" + + def inline_unmap(self, ffmodel, ffconfig): + assert self.mapped == True, "Tensor is not inline mapped." + ffc().flexflow_tensor_inline_unmap(self.handle, ffmodel.handle, ffconfig.handle) + self.mapped = False + + def get_array(self, ffmodel, ffconfig): + assert self.mapped == True, "Tensor is not mapped." + raw_ptr = self.__get_raw_ptr(ffmodel, ffconfig, self.data_type) + raw_ptr_int = int(ffi.cast("uintptr_t", raw_ptr)) + fflogger.debug("raw_ptr: %s, %d" % (str(raw_ptr), raw_ptr_int)) + strides = None + if self.num_dims >= 1 or self.num_dims <= 4: + shape = self.dims + else: + assert 0, "unknow num_dims" + initializer = RegionNdarray(shape, self.data_type, raw_ptr_int, strides, False) + array = np.asarray(initializer) + # print("stride", array.__array_interface__['strides']) + return array + + def get_flat_array(self, ffmodel, ffconfig): + assert self.mapped == True, "Tensor is not mapped." + raw_ptr = self.__get_raw_ptr(ffmodel, ffconfig, self.data_type) + raw_ptr_int = int(ffi.cast("uintptr_t", raw_ptr)) + fflogger.debug("raw_ptr: %s, %d" % (str(raw_ptr), raw_ptr_int)) + strides = None + if self.num_dims >= 1 or self.num_dims <= 4: + shape_prod = np.prod(self.dims) + shape = (shape_prod,) + else: + assert 0, "unknown num_dims" + initializer = RegionNdarray(shape, self.data_type, raw_ptr_int, strides, False) + array = np.asarray(initializer) + return array + + def attach_numpy_array(self, ffmodel, ffconfig, np_array): + assert ( + np_array.__array_interface__["strides"] == None + ), "numpy array strides is not None" + np_shape = np_array.shape + num_dims = len(np_shape) + assert num_dims == self.num_dims, "please check dims (%d == %d)" % ( + num_dims, + self.num_dims, + ) + for i in range(0, num_dims): + assert ( + np_shape[i] == self.dims[i] + ), "please check shape dim %d (%d == %d)" % (i, np_shape[i], self.dims[i]) + np_raw_ptr = np_array.__array_interface__["data"] + raw_ptr = ffi.cast("void*", np_raw_ptr[0]) + fflogger.debug( + "attach numpy array: %s, %s, %s" + % (str(np_raw_ptr), str(raw_ptr), hex(np_raw_ptr[0])) + ) + self.__attach_raw_ptr(ffmodel, ffconfig, raw_ptr) + + def detach_numpy_array(self, ffconfig): + self.__detach_raw_ptr(ffconfig) + + def is_mapped(self): + return ffc().flexflow_tensor_is_mapped(self.handle) + + def set_tensor(self, ffmodel, np_array): + assert ( + np_array.__array_interface__["strides"] == None + ), "Parameter set_weights, numpy array strides is not None" + np_shape = np_array.shape + num_dims = len(np_shape) + assert num_dims == self.num_dims, "please check dims (%d == %d)" % ( + num_dims, + self.num_dims, + ) + for i in range(0, num_dims): + assert ( + np_shape[i] == self.dims[i] + ), "please check shape dim %d (%d == %d)" % (i, np_shape[i], self.dims[i]) + c_dims = ffi.new("int[]", self.dims) + np_raw_ptr = np_array.__array_interface__["data"] + if np_array.dtype == np.float16: + assert self.data_type == DataType.DT_HALF, "Wrong datatype" + raw_ptr = ffi.cast("half*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_set_tensor_float( + self.handle, ffmodel.handle, num_dims, c_dims, raw_ptr + ) + elif np_array.dtype == np.float32: + assert self.data_type == DataType.DT_FLOAT, "Wrong datatype" + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_set_tensor_float( + self.handle, ffmodel.handle, num_dims, c_dims, raw_ptr + ) + elif np_array.dtype == np.int32: + assert self.data_type == DataType.DT_INT32, "Wrong datatype" + raw_ptr = ffi.cast("int*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_set_tensor_int( + self.handle, ffmodel.handle, num_dims, c_dims, raw_ptr + ) + else: + assert 0, "Unsupported datatype" + fflogger.debug( + "set tensor raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(np_shape)) + ) + assert ret_val == True, ret_val + + def get_tensor(self, ffmodel): + shape = self.dims + if self.data_type == DataType.DT_HALF: + np_array = np.empty(shape, dtype=np.float16) + elif self.data_type == DataType.DT_FLOAT: + np_array = np.empty(shape, dtype=np.float32) + elif self.data_type == DataType.DT_INT32: + np_array = np.empty(shape, dtype=np.int32) + elif self.data_type == DataType.DT_INT64: + np_array = np.empty(shape, dtype=np.int64) + else: + assert 0, f"Unsupported datatype: {self.data_type}" + np_raw_ptr = np_array.__array_interface__["data"] + if np_array.dtype == np.float32: + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_float( + self.handle, ffmodel.handle, raw_ptr, False + ) + elif np_array.dtype == np.int32: + raw_ptr = ffi.cast("int*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int( + self.handle, ffmodel.handle, raw_ptr, False + ) + elif np_array.dtype == np.int64: + raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int64( + self.handle, ffmodel.handle, raw_ptr, False + ) + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + assert ret_val == True + return np_array + + def get_gradients(self, ffmodel, comm_type): + shape = self.dims + if self.data_type == DataType.DT_HALF: + np_array = np.empty(shape, dtype=np.float16) + elif self.data_type == DataType.DT_FLOAT: + np_array = np.empty(shape, dtype=np.float32) + elif self.data_type == DataType.DT_INT32: + np_array = np.empty(shape, dtype=np.int32) + elif self.data_type == DataType.DT_INT64: + np_array = np.empty(shape, dtype=np.int64) + else: + assert 0, f"Unsupported datatype: {self.data_type}" + np_raw_ptr = np_array.__array_interface__["data"] + c_comm_type = enum_to_int(ParameterSyncType, comm_type) + if np_array.dtype == np.float32: + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_float( + self.handle, ffmodel.handle, raw_ptr, True + ) + elif np_array.dtype == np.int32: + raw_ptr = ffi.cast("int*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int( + self.handle, ffmodel.handle, raw_ptr, True + ) + elif np_array.dtype == np.int64: + raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int64( + self.handle, ffmodel.handle, raw_ptr, True + ) + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + assert ret_val == True + return np_array + + def get_model_output_gradients(self, ffmodel, comm_type): + shape = self.dims + if self.data_type == DataType.DT_HALF: + np_array = np.empty(shape, dtype=np.float16) + elif self.data_type == DataType.DT_FLOAT: + np_array = np.empty(shape, dtype=np.float32) + elif self.data_type == DataType.DT_INT32: + np_array = np.empty(shape, dtype=np.int32) + elif self.data_type == DataType.DT_INT64: + np_array = np.empty(shape, dtype=np.int64) + else: + assert 0, f"Unsupported datatype: {self.data_type}" + np_raw_ptr = np_array.__array_interface__["data"] + c_comm_type = enum_to_int(ParameterSyncType, comm_type) + if np_array.dtype == np.float32: + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_model_get_output_tensor_float( + ffmodel.handle, self.handle, raw_ptr, True + ) + else: + assert 0, "unknown data type" + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + assert ret_val == True + return np_array + + def get_model_output_tensor(self, ffmodel): + shape = self.dims + if self.data_type == DataType.DT_HALF: + np_array = np.empty(shape, dtype=np.float16) + elif self.data_type == DataType.DT_FLOAT: + np_array = np.empty(shape, dtype=np.float32) + elif self.data_type == DataType.DT_INT32: + np_array = np.empty(shape, dtype=np.int32) + elif self.data_type == DataType.DT_INT64: + np_array = np.empty(shape, dtype=np.int64) + else: + assert 0, f"Unsupported datatype: {self.data_type}" + np_raw_ptr = np_array.__array_interface__["data"] + if np_array.dtype == np.float32: + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_model_get_output_tensor_float( + ffmodel.handle, self.handle, raw_ptr, False + ) + else: + assert 0, "unknown data type" + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + assert ret_val == True + return np_array + + def __get_raw_ptr(self, ffmodel, ffconfig, data_type): + assert data_type == self.data_type, "Tensor check data type" + if data_type == DataType.DT_HALF: + return ffc().flexflow_tensor_get_raw_ptr_float( + self.handle, ffmodel.handle, ffconfig.handle + ) + elif data_type == DataType.DT_FLOAT: + return ffc().flexflow_tensor_get_raw_ptr_float( + self.handle, ffmodel.handle, ffconfig.handle + ) + elif data_type == DataType.DT_INT32: + return ffc().flexflow_tensor_get_raw_ptr_int32( + self.handle, ffmodel.handle, ffconfig.handle + ) + else: + assert 0, "unknown data type" + + def __get_dims(self): + self.num_dims = ffc().flexflow_tensor_get_num_dims(self.handle) + # if (self.num_dims == 1): + # self.dims = (ffc().flexflow_tensor_get_dim(self.handle, 0),) + # elif (self.num_dims == 2): + # self.dims = (ffc().flexflow_tensor_get_dim(self.handle, 1), ffc().flexflow_tensor_get_dim(self.handle, 0)) + # elif (self.num_dims == 3): + # self.dims = (ffc().flexflow_tensor_get_dim(self.handle, 2), ffc().flexflow_tensor_get_dim(self.handle, 1), ffc().flexflow_tensor_get_dim(self.handle, 0)) + # elif (self.num_dims == 4): + # self.dims = (ffc().flexflow_tensor_get_dim(self.handle, 3), ffc().flexflow_tensor_get_dim(self.handle, 2), ffc().flexflow_tensor_get_dim(self.handle, 1), ffc().flexflow_tensor_get_dim(self.handle, 0)) + # elif (self.num_dims == 5): + # self.dims = (ffc().flexflow_tensor_get_dim(self.handle, 4), ffc().flexflow_tensor_get_dim(self.handle, 3), ffc().flexflow_tensor_get_dim(self.handle, 2), ffc().flexflow_tensor_get_dim(self.handle, 1), ffc().flexflow_tensor_get_dim(self.handle, 0)) + # else: + # assert 0, "unknown num_dims" + d = ffc().flexflow_tensor_get_dims(self.handle) + if self.num_dims == 1: + self.dims = (d[0],) + elif self.num_dims == 2: + self.dims = (d[1], d[0]) + elif self.num_dims == 3: + self.dims = (d[2], d[1], d[0]) + elif self.num_dims == 4: + self.dims = (d[3], d[2], d[1], d[0]) + elif self.num_dims == 5: + self.dims = (d[4], d[3], d[2], d[1], d[0]) + else: + assert 0, "unknown num_dims" + + def __get_data_type(self): + dtype = ffc().flexflow_tensor_get_data_type(self.handle) + if dtype == 40: + self.data_type = DataType.DT_BOOLEAN + elif dtype == 41: + self.data_type = DataType.DT_INT32 + elif dtype == 42: + self.data_type = DataType.DT_INT64 + elif dtype == 43: + self.data_type = DataType.DT_HALF + elif dtype == 44: + self.data_type = DataType.DT_FLOAT + elif dtype == 45: + self.data_type = DataType.DT_DOUBLE + else: + assert 0, "unknown data type {}".format(dtype) + + def __get_owner_op(self, op_type): + op_handle = ffc().flexflow_tensor_get_owner_op(self.handle) + if op_handle.impl == ffi.NULL: + self.owner_op = None + else: + self.owner_op = convert_op_handle_to_op(op_type, op_handle) + + def __attach_raw_ptr(self, ffmodel, ffconfig, raw_ptr, column_major=True): + assert self.mapped == False, "Tensor is already mapped." + ffc().flexflow_tensor_attach_raw_ptr( + self.handle, ffmodel.handle, ffconfig.handle, raw_ptr, column_major + ) + self.mapped = True + + def __detach_raw_ptr(self, ffconfig): + assert self.mapped == True, "Tensor is not mapped." + ffc().flexflow_tensor_detach_raw_ptr(self.handle, ffconfig.handle) + self.mapped = False - if (self._ffconfig.enable_control_replication): - assert self._ffconfig.python_data_loader_type != 1, 'To enable control replication, please set --python-data-loader-type 2' - return self.__create_data_loader_ptr(batch_tensor, full_array) - else: - if (self._ffconfig.python_data_loader_type == 1): - return self.__create_data_loader_attach(batch_tensor, full_array) - else: - return self.__create_data_loader_ptr(batch_tensor, full_array) - - def __create_data_loader_attach(self, batch_tensor, full_array): - full_array_shape = full_array.shape - num_samples = full_array_shape[0] - num_dim = len(full_array_shape) - if (full_array.dtype == "float32"): - datatype = DataType.DT_FLOAT - elif (full_array.dtype == "int32"): - datatype = DataType.DT_INT32 - elif (full_array.dtype == "int64"): - datatype = DataType.DT_INT64 - else: - assert 0, "unsupported datatype" - - if (num_dim == 2): - full_tensor = self.create_tensor([num_samples, full_array_shape[1]], datatype) - self.map_tensor(full_tensor) - elif (num_dim == 4): - full_tensor = self.create_tensor([num_samples, full_array_shape[1], full_array_shape[2], full_array_shape[3]], datatype) - self.map_tensor(full_tensor) - else: - assert 0, "unsupported dims" - full_tensor.attach_numpy_array(self._ffconfig, full_array) - dataloader = SingleDataLoader(self, batch_tensor, full_tensor, num_samples, datatype) - full_tensor.detach_numpy_array(self._ffconfig) +# ----------------------------------------------------------------------- +# Parameter +# ----------------------------------------------------------------------- - return dataloader - - def __create_data_loader_ptr(self, batch_tensor, full_array): - full_array_shape = full_array.shape - num_samples = full_array_shape[0] - if (full_array.dtype == "float32"): - datatype = DataType.DT_FLOAT - elif (full_array.dtype == "int32"): - datatype = DataType.DT_INT32 - elif (full_array.dtype == "int64"): - datatype = DataType.DT_INT64 - else: - assert 0, "unsupported datatype" - np_raw_ptr = full_array.__array_interface__['data'] - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - print("numpy array: %s, %s, %s" % (str(np_raw_ptr), str(raw_ptr), hex(np_raw_ptr[0]))) - dataloader = SingleDataLoader(self, batch_tensor, raw_ptr, num_samples, datatype) - - return dataloader - - def __get_initializer_handle(self, initializer): - if (initializer == None): - null_initializer = Initializer(None) - return null_initializer.handle - else: - return initializer.handle - def __get_op_handle(self, shared_op): - if shared_op == None: - op_handle = ffi.new('flexflow_op_t *') - op_handle.impl = ffi.NULL - op = Op(op_handle[0]) - else: - op = shared_op - return op.handle - - def get_output_tensor(self, ffmodel, data_type): - shape = self.dims - if data_type == DataType.DT_FLOAT: - np_array = np.empty(shape, dtype=np.float32) - elif self.data_type == DataType.DT_INT32: - np_array = np.empty(shape, dtype=np.int32) - elif self.data_type == DataType.DT_INT64: - np_array = np.empty(shape, dtype=np.int64) - else: - assert 0, f"Unsupported datatype: {self.data_type}" - np_raw_ptr = np_array.__array_interface__['data'] - if np_array.dtype == np.float32: - raw_ptr = ffi.cast("float*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_float(self.handle, ffmodel.handle, raw_ptr, False) - elif np_array.dtype == np.int32: - raw_ptr = ffi.cast("int*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int(self.handle, ffmodel.handle, raw_ptr, False) - elif np_array.dtype == np.int64: - raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) - ret_val = ffc.flexflow_tensor_get_tensor_int64(self.handle, ffmodel.handle, raw_ptr, False) - fflogger.debug("get weights raw_ptr: %s, %s, %s, %s" %( str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape))) - assert ret_val == True - return np_array +class Parameter(Tensor): + __slots__ = ["parameter_handle"] + + def __init__(self, handle): + assert ffi.typeof(handle) == ffi.typeof( + "flexflow_tensor_t" + ), "Parameter handle is wrong" + self.parameter_handle = handle + super(Parameter, self).__init__(self.parameter_handle, deallocate=False) + + def set_weights(self, ffmodel, np_array): + assert ( + np_array.__array_interface__["strides"] == None + ), "Parameter set_weights, numpy array strides is not None" + np_shape = np_array.shape + num_dims = len(np_shape) + assert num_dims == self.num_dims, "please check dims (%d == %d)" % ( + num_dims, + self.num_dims, + ) + print(np_shape, self.dims) + for i in range(0, num_dims): + assert ( + np_shape[i] == self.dims[i] + ), "please check shape dim %d (%d == %d)" % (i, np_shape[i], self.dims[i]) + c_dims = ffi.new("int[]", self.dims) + np_raw_ptr = np_array.__array_interface__["data"] + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + fflogger.debug( + "set weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(np_shape)) + ) + ret_val = ffc().flexflow_tensor_set_tensor_float( + self.parameter_handle, ffmodel.handle, num_dims, c_dims, raw_ptr + ) + assert ret_val == True, ret_val + + def get_weights(self, ffmodel): + shape = self.dims + np_array = np.empty(shape, dtype=np.float32) + np_raw_ptr = np_array.__array_interface__["data"] + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + ret_val = ffc().flexflow_tensor_get_tensor_float( + self.parameter_handle, ffmodel.handle, raw_ptr, False + ) + assert ret_val == True + return np_array + + +# ----------------------------------------------------------------------- +# FFModel +# ----------------------------------------------------------------------- + + +class FFModel(object): + """ """ + + __slots__ = [ + "handle", + "_handle", + "_layers", + "_nb_layers", + "_ffconfig", + "_tracing_id", + "initializers", + "attr_tensors", + ] + + def __init__(self, ffconfig): + """Constructor of FFModel. + + :param ffconfig: configurations of FlexFlow and the created model. + :type ffconfig: FFConfig + + :returns: FFModel -- the model. + """ + self.handle = ffc().flexflow_model_create(ffconfig.handle, ffconfig.cpu_offload) + self._handle = ffi.gc(self.handle, ffc().flexflow_model_destroy) + self._layers = dict() + self._nb_layers = 0 + self._ffconfig = ffconfig + global ff_tracing_id + self._tracing_id = ff_tracing_id + ff_tracing_id += 1 + self.initializers = {} + self.attr_tensors = {} + + def get_layers(self): + return self._layers + + def add_layer(self, op_type, name): + layer_id = self._nb_layers + op_handle = ffc().flexflow_model_get_last_layer(self.handle) + self._layers[self._nb_layers] = convert_op_handle_to_op( + op_type, op_handle, idx=layer_id, name=name + ) + self._nb_layers += 1 + + def create_tensor(self, dims, data_type, create_grad=True): + """Instantiate a FlexFlow tensor. + + :param x: a shape tuple/list (integers), including the batch size. + :type x: list of int + + :param data_type: the datatype of the created tensor. Options are + DT_FLOAT, DT_DOUBLE, DT_INT32, DT_INT64, DT_BOOLEAN. + :type data_type: DataType + + :param create_grad: weather the tensor creates a gradients vector. + If you don't specify anything, a gradients vector is used. + :type create_grad: bool + + :returns: Tensor -- the output tensor. + """ + c_dims = ffi.new("int[]", dims) + c_data_type = enum_to_int(DataType, data_type) + num_dims = len(dims) + handle = ffc().flexflow_tensor_create( + self.handle, num_dims, c_dims, c_data_type, create_grad + ) + return Tensor(handle) + + def map_tensor(self, tensor, parallel_op=None): + op_handle = self.__get_op_handle(parallel_op) + ffc().flexflow_tensor_map(self.handle, tensor.handle, op_handle) + + def create_constant(self, dims, value, data_type): + c_dims = ffi.new("int[]", dims) + c_data_type = enum_to_int(DataType, data_type) + num_dims = len(dims) + handle = ffc().flexflow_constant_create( + self.handle, num_dims, c_dims, value, c_data_type + ) + return Tensor(handle) + + def exp(self, x, name=None): + """Exponential activation function. + + :param x: the input Tensor. + :type x: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_exp(self.handle, x.handle, c_name) + self.add_layer(OpType.EXP, name) + return Tensor(handle, owner_op_type=OpType.EXP) + + def sin(self, x, name=None): + """Elementwise sine function. + + :param x: the input Tensor. + :type x: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_sin(self.handle, x.handle, c_name) + self.add_layer(OpType.SIN, name) + return Tensor(handle, owner_op_type=OpType.SIN) + + def cos(self, x, name=None): + """Elementwise cosine function. + + :param x: the input Tensor. + :type x: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_cos(self.handle, x.handle, c_name) + self.add_layer(OpType.COS, name) + return Tensor(handle, owner_op_type=OpType.COS) + + def add(self, x, y, inplace_a=False, name=None): + """Layer that adds two input Tensors, :attr:`output = x + y`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_add( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.ADD, name) + return Tensor(handle, owner_op_type=OpType.ADD) + + def subtract(self, x, y, inplace_a=False, name=None): + """Layer that subtracts two input Tensors, :attr:`output = x * y`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_subtract( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.SUBTRACT, name) + return Tensor(handle, owner_op_type=OpType.SUBTRACT) + + def multiply(self, x, y, inplace_a=False, name=None): + """Layer that multiplies (element-wise) two input Tensors, :attr:`output = x * y`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_multiply( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.MULTIPLY, name) + return Tensor(handle, owner_op_type=OpType.MULTIPLY) + + def divide(self, x, y, inplace_a=False, name=None): + """Layer that divides (element-wise) two input Tensors, :attr:`output = x / y`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_divide( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.DIVIDE, name) + return Tensor(handle, owner_op_type=OpType.DIVIDE) + + def max(self, x, y, inplace_a=False, name=None): + """Layer that computes the max (element-wise) two input Tensors, :attr:`output = max(x,y)`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_max( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.MAX, name) + return Tensor(handle, owner_op_type=OpType.MAX) + + def min(self, x, y, inplace_a=False, name=None): + """Layer that computes the min (element-wise) two input Tensors, :attr:`output = min(x,y)`. + + :param x: the first input Tensor. + :type x: Tensor + + :param y: the second input Tensor. + :type y: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_min( + self.handle, x.handle, y.handle, inplace_a, c_name + ) + self.add_layer(OpType.MIN, name) + return Tensor(handle, owner_op_type=OpType.MIN) + + def reduce_sum(self, input, axes, keepdims=False, name=None): + """Layer that computes the sum of the input Tensor along given axes. + + :param input: the input Tensor. + :type input: Tensor + + :param axes: the axes along which reduction is applied + :type axes: List[int] + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + c_axes = ffi.new("int[]", axes) + handle = ffc().flexflow_model_add_reduce_sum( + self.handle, input.handle, c_axes, len(axes), keepdims, c_name + ) + self.add_layer(OpType.REDUCE_SUM, name) + return Tensor(handle, owner_op_type=OpType.REDUCE_SUM) + + def rsqrt(self, input, name=None): + """Layer that computes the element-wise reciprocal square-root. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_rsqrt(self.handle, input.handle, c_name) + self.add_layer(OpType.RSQRT, name) + return Tensor(handle, owner_op_type=OpType.RSQRT) + + def pow(self, input, exponent, name=None): + """Layer that computes the element-wise power. + + :param input: the input Tensor. + :type input: Tensor + + :param exponent: exponent to raise each element in the input tensor. + :type exponent: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_pow( + self.handle, input.handle, exponent, c_name + ) + self.add_layer(OpType.POW, name) + return Tensor(handle, owner_op_type=OpType.POW) + + def mean(self, input, dims, keepdims=False, name=None): + """Layer that computes the mean of the input tensor across the given + dimensions. + + :param input: the input Tensor. + :type input: Tensor + + :param dims: dimensions to take the mean over. + :type dims: list + + :param keepdims: keeps the dimensions in :attr:`dims` as size 1 if True and + collapses the dimension if False. Default is False. + :type keepdims: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + dims = list(dims) + c_dims = ffi.new("int[]", dims) + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_mean( + self.handle, input.handle, c_dims, len(dims), keepdims, c_name + ) + self.add_layer(OpType.MEAN, name) + return Tensor(handle, owner_op_type=OpType.MEAN) + + def conv2d( + self, + input, + out_channels, + kernel_h, + kernel_w, + stride_h, + stride_w, + padding_h, + padding_w, + activation=ActiMode.AC_MODE_NONE, + groups=1, + use_bias=True, + shared_op=None, + kernel_initializer=None, + bias_initializer=None, + name=None, + ): + """This layer creates a 2D convolution kernel that is convolved with the layer :attr:`input` + to produce a tensor of :attr:`output`. + + The size of input tensor is :math:`(N, C_{in}, H, W)` and the size of output tensor + is :math:`(N, C_{out}, H_{out}, W_{out})`, which can be calculated by: + + .. math:: + C_{out} = out\_channels + + .. math:: + K_{H} = kernel\_h + + .. math:: + K_{W} = kernel\_w + + .. math:: + S_{H} = stride\_h + + .. math:: + S_{W} = stride\_w + + .. math:: + P_{H} = padding\_h + + .. math:: + P_{S} = padding\_s + + .. math:: + H_{out} = (H - K_{H} + 2 * P_{H}) / S_{H} + 1 + + .. math:: + W_{out} = (W - K_{W} + 2 * P_{W}) / S_{W} + 1 + + :param input: the input Tensor. + :type input: Tensor + + :param out\_channels: the dimensionality of the output space (i.e. the number of output filters in the convolution). + :type out\_channels: int + + :param kernel_h: the height of the 2D convolution window: :math:`K_{H}`. + :type kernel_h: int + + :param kernel_w: the width of the 2D convolution window: :math:`K_{W}`. + :type kernel_w: int + + :param stride_h: the stride of the convolution along the height: :math:`S_{H}`. + :type stride_h: int + + :param stride_w: the stride of the convolution along the width: :math:`S_{W}`. + :type stride_w: int + + :param padding_h: the amount of implicit zero-paddings along the height: :math:`P_{H}`. + :type padding_h: int + + :param padding_w: the amount of implicit zero-paddings along the width: :math:`P_{W}`. + :type padding_w: int + + :param activation: Activation function to use. Default is ActiMode.AC_MODE_NONE. + :type activation: ActiMode + + :param groups: the number of groups in this convolution + :type groups: int + + :param use_bias: whether the layer uses a bias vector. Default is True. + :type use_bias: bool + + :param shared_op: the layer whose parameters are shared with. Default is None. + :type shared_op: Op + + :param kernel_initializer: Initializer for the kernel weights matrix. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param bias_initializer: Initializer for the bias vector. If it is set to None, the ZeroInitializer is applied. + :type bias_initializer: Initializer + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + shared_op_handle = self.__get_op_handle(shared_op) + c_activation = enum_to_int(ActiMode, activation) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + bias_init_handle = self.__get_initializer_handle(bias_initializer) + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_conv2d( + self.handle, + input.handle, + out_channels, + kernel_h, + kernel_w, + stride_h, + stride_w, + padding_h, + padding_w, + c_activation, + groups, + use_bias, + shared_op_handle, + kernel_init_handle, + bias_init_handle, + c_name, + ) + self.add_layer(OpType.CONV2D, name) + return Tensor(handle, owner_op_type=OpType.CONV2D) + + def embedding( + self, + input, + num_embeddings, + embedding_dim, + aggr, + dtype=DataType.DT_FLOAT, + shared_op=None, + kernel_initializer=None, + name=None, + ): + """Layer that turns positive integers into dense vectors of fixed size + + :param input: the input Tensor. + :type input: Tensor + + :param num_embeddings: size of the vocabulary, i.e. maximum integer index + 1 + :type num_embeddings: int + + :param embedding_dim: dimension of the dense embedding. + :type embedding_dim: int + + :param aggr: aggregation mode. Options are AGGR_MODE_NONE, AGGR_MODE_SUM and AGGR_MODE_AVG. + :type aggr: AggrMode + + :param dtype: the tensor data type. Options are DT_BOOLEAN, DT_INT32, DT_INT64, DT_HALF, DT_FLOAT, DT_DOUBLE, DT_INT4, DT_INT8, DT_NONE + :type dtype: DataType + + :param shared_op: the layer whose parameters are shared with. Default is None. + :type shared_op: Op + + :param kernel_initializer: Initializer for the kernel weights matrix. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + shared_op_handle = self.__get_op_handle(shared_op) + c_aggr = enum_to_int(AggrMode, aggr) + c_dtype = enum_to_int(DataType, dtype) + if kernel_initializer is None: + kernel_initializer = GlorotUniformInitializer(42) + assert ( + (type(kernel_initializer) is GlorotUniformInitializer) + or (type(kernel_initializer) is ZeroInitializer) + or (type(kernel_initializer) is UniformInitializer) + or (type(kernel_initializer) is NormInitializer) + ), f"Unknown initializer type: {kernel_initializer}" + handle = ffc().flexflow_model_add_embedding( + self.handle, + input.handle, + num_embeddings, + embedding_dim, + c_aggr, + c_dtype, + shared_op_handle, + kernel_initializer.handle, + c_name, + ) + # NOTE: We must keep a reference to the initializer or else it will be + # immediately destructed + self.initializers[name] = kernel_initializer + self.add_layer(OpType.EMBEDDING, name) + return Tensor(handle, owner_op_type=OpType.EMBEDDING) + + def pool2d( + self, + input, + kernel_h, + kernel_w, + stride_h, + stride_w, + padding_h, + padding_w, + pool_type=PoolType.POOL_MAX, + activation=ActiMode.AC_MODE_NONE, + name=None, + ): + """Pooling operation for 2D spatial data. + + The size of input tensor is :math:`(N, C_{in}, H, W)` and the size of output tensor + is :math:`(N, C_{out}, H_{out}, W_{out})`, which can be calculated by: + + .. math:: + C_{out} = out\_channels + + .. math:: + K_{H} = kernel\_h + + .. math:: + K_{W} = kernel\_w + + .. math:: + S_{H} = stride\_h + + .. math:: + S_{W} = stride\_w + + .. math:: + P_{H} = padding\_h + + .. math:: + P_{S} = padding\_s + + .. math:: + H_{out} = (H - K_{H} + 2 * P_{H}) / S_{H} + 1 + + .. math:: + W_{out} = (W - K_{W} + 2 * P_{W}) / S_{W} + 1 + + :param input: the input Tensor. + :type input: Tensor + + :param kernel_h: the height of the 2D pooling window: :math:`K_{H}`. + :type kernel_h: int + + :param kernel_w: the width of the 2D pooling window: :math:`K_{W}`. + :type kernel_w: int + + :param stride_h: the stride of the pooling along the height: :math:`S_{H}`. + :type stride_h: int + + :param stride_w: the stride of the pooling along the width: :math:`S_{W}`. + :type stride_w: int + + :param padding_h: the amount of implicit zero-paddings along the height: :math:`P_{H}`. + :type padding_h: int + + :param padding_w: the amount of implicit zero-paddings along the width: :math:`P_{W}`. + :type padding_w: int + + :param activation: Tyoe of pooling function to use. If you don't specify anything, PoolType.POOL_MAX is applied. + :type activation: PoolType + + :param activation: Activation function to use. Default is ActiMode.AC_MODE_NONE. + :type activation: ActiMode + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + c_pool_type = enum_to_int(PoolType, pool_type) + c_activation = enum_to_int(ActiMode, activation) + handle = ffc().flexflow_model_add_pool2d( + self.handle, + input.handle, + kernel_h, + kernel_w, + stride_h, + stride_w, + padding_h, + padding_w, + c_pool_type, + c_activation, + c_name, + ) + self.add_layer(OpType.POOL2D, name) + return Tensor(handle, owner_op_type=OpType.POOL2D) + + def batch_norm(self, input, relu=True, name=None): + """Layer that normalizes its inputs. + + Batch normalization applies a transformation that maintains the mean output close to 0 and the output standard deviation close to 1. + + :param input: the list of input Tensors. + :type input: Tensor + + :param relu: whether a ReLU function is applied. Default is True. + :type relu: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_batch_norm( + self.handle, input.handle, relu, c_name + ) + self.add_layer(OpType.BATCH_NORM, name) + return Tensor(handle, owner_op_type=OpType.BATCH_NORM) + + def layer_norm( + self, input, axes, elementwise_affine=True, eps=1e-5, use_bias=True, name=None + ): + """Add a LayerNorm layer + + :param input: The input tensor + :type input: Tensor + :param axes: Indicate which axes (starting from the end) the LayerNorm should normalize over + :type axes: Union[int, List[int]] + :param elementwise_affine: Whether the LayerNorm should use the gamma weight for scaling, defaults to True + :type elementwise_affine: bool, optional + :param eps: A small float value added to the LayerNorm denominator for numerical stability, defaults to 1e-5 + :type eps: float, optional + :param use_bias: Whether to add a beta bias to the LayerNorm result, defaults to True + :type use_bias: bool, optional + :param name: Name of the operator, also used for loading weights in inference mode, defaults to None + :type name: _type_, optional + :return: The LayerNorm output tensor + :rtype: Tensor + """ + c_name = get_c_name(name) + c_axes = ffi.new("int[]", axes) + handle = ffc().flexflow_model_add_layer_norm( + self.handle, + input.handle, + len(axes), + c_axes, + elementwise_affine, + eps, + use_bias, + c_name, + ) + self.add_layer(OpType.LAYER_NORM, name) + return Tensor(handle, owner_op_type=OpType.LAYER_NORM) + + def residual_layer_norm( + self, + input, + residual1, + residual2, + use_two_residuals, + axes, + elementwise_affine=True, + eps=1e-5, + use_bias=True, + name=None, + ): + """Add a fused LayerNorm + Residual layer. This operator uses a single kernel, resulting in + better efficiency compared to using separate element-wise add and LayerNorm operators. + + :param input: The input tensor + :type input: Tensor + :param residual1: The residual tensor to add to the input before computing the LayerNorm + :type residual1: Tensor + :param residual2: An optional second residual tensor to add to the input (in addition to residual1) before computing the LayerNorm + :type residual2: Tensor + :param use_two_residuals: A boolean that should be set to True if using the second optional residual, False otherwise + :type use_two_residuals: bool + :param axes: Indicate which axes (starting from the end) the LayerNorm should normalize over + :type axes: List[int] + :param elementwise_affine: Whether the LayerNorm should use the gamma weight for scaling, defaults to True + :type elementwise_affine: bool, optional + :param eps: A small float value added to the LayerNorm denominator for numerical stability, defaults to 1e-5 + :type eps: float, optional + :param use_bias: Whether to add a beta bias to the LayerNorm result, defaults to True + :type use_bias: bool, optional + :param name: Name of the operator, also used for loading weights in inference mode, defaults to None + :type name: str, optional + :return: A tensor with the sum of the input and residual(s), and the LayerNorm output + :rtype: (Tensor, Tensor) + """ + c_name = get_c_name(name) + c_axes = ffi.new("int[]", axes) + residual2_handle = ( + residual1.handle + ) # This is intentional. Data will be ignored, and we cannot pass None + if use_two_residuals: + assert residual2 is not None + residual2_handle = residual2.handle + handles_array = ffc().flexflow_model_add_residual_layer_norm( + self.handle, + input.handle, + residual1.handle, + residual2_handle, + use_two_residuals, + len(axes), + c_axes, + elementwise_affine, + eps, + use_bias, + c_name, + ) + self.add_layer(OpType.RESIDUAL_LAYERNORM, name) + return Tensor( + handles_array[0], owner_op_type=OpType.RESIDUAL_LAYERNORM + ), Tensor(handles_array[1], owner_op_type=OpType.RESIDUAL_LAYERNORM) + + def add_bias_residual_layer_norm( + self, + input, + residual, + axes, + elementwise_affine=True, + eps=1e-5, + use_bias=True, + name=None, + ): + """Add a Attention Bias + Residual + LayerNorm layer. This operator uses a single kernel, + resulting in better efficiency compared to using separate attention bias addition + + element-wise residual addition + LayerNorm operators. + + :param input: The input tensor + :type input: Tensor + :param residual: The residual tensor + :type residual: Tensor + :param axes: Indicate which axes (starting from the end) the LayerNorm should normalize over + :type axes: Union[int, List[int]] + :param elementwise_affine: Whether the LayerNorm should use the gamma weight for scaling, defaults to True + :type elementwise_affine: bool, optional + :param eps: A small float value added to the LayerNorm denominator for numerical stability, defaults to 1e-5 + :type eps: float, optional + :param use_bias: Whether to add a beta bias to the LayerNorm result, defaults to True + :type use_bias: bool, optional + :param name: Name of the operator, also used for loading weights in inference mode, defaults to None + :type name: _type_, optional + :return: A tensor with the sum of the attention bias, input and residual(s), and the LayerNorm output + :rtype: (Tensor, Tensor) + """ + c_name = get_c_name(name) + c_axes = ffi.new("int[]", axes) + handles_array = ffc().flexflow_model_add_add_bias_residual_layer_norm( + self.handle, + input.handle, + residual.handle, + len(axes), + c_axes, + elementwise_affine, + eps, + use_bias, + c_name, + ) + self.add_layer(OpType.ADD_BIAS_RESIDUAL_LAYERNORM, name) + return Tensor( + handles_array[0], owner_op_type=OpType.ADD_BIAS_RESIDUAL_LAYERNORM + ), Tensor(handles_array[1], owner_op_type=OpType.ADD_BIAS_RESIDUAL_LAYERNORM) + + def sigmoid_silu_multi(self, input1, input2, name=None): + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_sigmoid_silu_multi( + self.handle, input1.handle, input2.handle, c_name + ) + self.add_layer(OpType.SIGMOID_SILU_MULTI, name) + return Tensor(handle, owner_op_type=OpType.SIGMOID_SILU_MULTI) + + def batch_matmul( + self, A, B, a_seq_length_dim=None, b_seq_length_dim=None, name=None + ): + """Layer that applied batched matrix multiplication onto two input Tensors, :attr:`output = x * y`. + + :param A: the first input Tensor. + :type A: Tensor + + :param B: the second input Tensor. + :type B: Tensor + + :param a_seq_length_dim: an int when set indicating the a_seq_length_dim dimention of A is a sequence_length dimension + :type a_seq_length_dim: int + + :param b_seq_length_dim: an int when set indicating the b_seq_length_dim dimention of B is a sequence_length dimension + :type b_seq_length_dim: int + + :param name: the name of the layer. Default is None. + :type name: string + + :param name: Whether to add use bias in layer normalization + :type name: bool + + :returns: Tensor -- the output tensor. + """ + if a_seq_length_dim is None: + a_seq_length_dim = -1 + if b_seq_length_dim is None: + b_seq_length_dim = -1 + handle = ffc().flexflow_model_add_batch_matmul( + self.handle, A.handle, B.handle, a_seq_length_dim, b_seq_length_dim + ) + self.add_layer(OpType.BATCH_MATMUL, name) + return Tensor(handle, owner_op_type=OpType.BATCH_MATMUL) + + def dense( + self, + input, + out_dim, + activation=ActiMode.AC_MODE_NONE, + use_bias=True, + datatype=DataType.DT_NONE, + shared_op=None, + kernel_initializer=None, + bias_initializer=None, + kernel_regularizer=None, + name=None, + ): + """Dense implements the operation: :attr:`output = activation(dot(input, kernel) + bias)` where + :attr:`activation` is the element-wise activation function passed as the activation argument, + :attr:`kernel` is a weights matrix created by the layer, and + :attr:`bias` is a bias vector created by the layer (only applicable if :attr:`use_bias` is True). + + The size of input tensor is :math:`(N, C_{in})` and the size of output tensor + is :math:`(N, C_{out})`, where :math:`C_{out} = out\_dim` + + :param input: the input Tensor. + :type input: Tensor + + :param out\_dim: dimensionality of the output space. + :type out\_dim: int + + :param activation: Activation function to use. Default is ActiMode.AC_MODE_NONE. + :type activation: ActiMode + + :param use_bias: whether the layer uses a bias vector. Default is True. + :type use_bias: bool + + :param shared_op: the layer whose parameters are shared with. Default is None. + :type shared_op: Op + + :param kernel_initializer: Initializer for the kernel weights matrix. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param bias_initializer: Initializer for the bias vector. If it is set to None, the ZeroInitializer is applied. + :type bias_initializer: Initializer + + :param kernel_regularizer: Regularizer for the kernel weights matrix + :type bias_initializer: Regularizer + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + shared_op_handle = self.__get_op_handle(shared_op) + c_activation = enum_to_int(ActiMode, activation) + c_datatype = enum_to_int(DataType, datatype) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + bias_init_handle = self.__get_initializer_handle(bias_initializer) + if kernel_regularizer: + c_kernel_reg_type = enum_to_int(RegularizerMode, kernel_regularizer.type) + kernel_reg_lambda = kernel_regularizer._lambda + else: + c_kernel_reg_type = enum_to_int( + RegularizerMode, RegularizerMode.REG_MODE_NONE + ) + kernel_reg_lambda = 0.0 + handle = ffc().flexflow_model_add_dense( + self.handle, + input.handle, + out_dim, + c_activation, + use_bias, + c_datatype, + shared_op_handle, + kernel_init_handle, + bias_init_handle, + c_kernel_reg_type, + kernel_reg_lambda, + c_name, + ) + self.add_layer(OpType.LINEAR, name) + return Tensor(handle, owner_op_type=OpType.LINEAR) + + def concat(self, tensors, axis, name=None): + """Layer that concatenates a list of inputs. + + It takes as input a list of tensors, all of the same shape except for the concatenation axis, and returns a single tensor that is the concatenation of all inputs. + + :param input: the list of input Tensors. + :type input: List of Tensors + + :param axis: the dimension along which to concatenate. + :type axis: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + assert type(tensors) is list, "tensors should be a list" + tensor_handle_list = [] + n = len(tensors) + assert n <= 256, "Please increase MAX_NUM_INPUTS" + for tensor in tensors: + tensor_handle_list.append(tensor.handle) + c_tensor_handle_list = ffi.new("flexflow_tensor_t[]", tensor_handle_list) + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_concat( + self.handle, n, c_tensor_handle_list, axis, c_name + ) + self.add_layer(OpType.CONCAT, name) + return Tensor(handle, owner_op_type=OpType.CONCAT) + + def split(self, input, sizes, axis, name=None): + """Layer that splits a :attr:`input` tensor into a list of tensors. + + :param input: the input Tensor. + :type input: Tensor + + :param sizes: either an int indicating the number of splits along axis or a Python list containing the sizes of each output tensor along axis. If a scalar, then it must evenly divide :attr:`input.dims[axis]`; otherwise the sum of sizes along the split axis must match that of the :attr:`input`. + :type sizes: int or list of int + + :param axis: the dimension along which to split. + :type axis: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: list of Tensors -- the output tensors. + """ + if type(sizes) is list: + split = sizes + else: + assert input.dims[axis] % sizes == 0, "Split dimension is not divisible" + split = [input.dims[axis] // sizes for i in range(sizes)] + n = len(split) + assert n <= 256, "Please increase MAX_NUM_OUTPUTS" + c_split = ffi.new("int[]", split) + c_outputs_handle_list = ffi.new("flexflow_tensor_t[256]") + c_name = get_c_name(name) + ffc().flexflow_model_add_split( + self.handle, input.handle, n, c_outputs_handle_list, c_split, axis, c_name + ) + output_tensor_list = [] + for i in range(n): + tensor_p_handle = ffi.new("flexflow_tensor_t*") + tensor_p_handle.impl = c_outputs_handle_list[i].impl + output_tensor_list.append( + Tensor(None, owner_op_type=OpType.SPLIT, p_handle=tensor_p_handle) + ) + self.add_layer(OpType.SPLIT, name) + del c_outputs_handle_list + return output_tensor_list + + def flat(self, input, name=None): + """Flattens the input. Does not affect the batch size. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_flat(self.handle, input.handle, c_name) + self.add_layer(OpType.FLAT, name) + return Tensor(handle, owner_op_type=OpType.FLAT) + + def softmax(self, input, axis=-1, name=None): + """Softmax activation function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_softmax( + self.handle, input.handle, axis, c_name + ) + self.add_layer(OpType.SOFTMAX, name) + return Tensor(handle, owner_op_type=OpType.SOFTMAX) + + def reshape(self, input, shape, name=None): + """Layer that reshapes inputs into the given shape. + + Given a :attr:`input` tensor, this operation returns a output tensor that has the same values as tensor in the same order, + except with a new shape given by :attr:`shape`. + + :param input: the input Tensor. + :type input: Tensor + + :param shape: A list defining the shape of the output tensor. + :type shape: list of int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + c_shape = ffi.new("int[]", shape) + handle = ffc().flexflow_model_add_reshape( + self.handle, input.handle, len(shape), c_shape, c_name + ) + self.add_layer(OpType.RESHAPE, name) + return Tensor(handle, owner_op_type=OpType.RESHAPE) + + def gather(self, input, index, dim, name=None): + """Layer that gathers values along the dim axis. + + :param input: the input tensor + :type input: Tensor + + :param index: the index tensor, which specifies the indices of elements to gather + :type index: Tensor + + :param dim: the axis along which to index + :type dim: int + + :param name: the name of the layer. Default is None + :type name: string + + :returns: Tensor -- the output tensor + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_gather( + self.handle, input.handle, index.handle, dim, c_name + ) + self.add_layer(OpType.GATHER, name) + return Tensor(handle, owner_op_type=OpType.GATHER) + + def transpose(self, input, perm, name=None): + """Transposes the :attr:`input` tensor. Permutes the dimensions according to perm + + :param input: the input Tensor. + :type input: Tensor + + :param perm: A permutation of the dimensions of a. + :type perm: List of int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + c_perm = ffi.new("int[]", perm) + handle = ffc().flexflow_model_add_transpose( + self.handle, input.handle, len(perm), c_perm, c_name + ) + self.add_layer(OpType.TRANSPOSE, name) + return Tensor(handle, owner_op_type=OpType.TRANSPOSE) + + def reverse(self, input, axis, name=None): + """Layer that reverses specific dimensions of a tensor. + + Given a :attr:`input` tensor, this operation reverses the dimension :attr:`axis`. + + :param input: the input Tensor. + :type input: Tensor + + :param axis: the dimension to reverse. + :type axis: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_reverse( + self.handle, input.handle, axis, c_name + ) + self.add_layer(OpType.REVERSE, name) + return Tensor(handle, owner_op_type=OpType.REVERSE) + + def scalar_multiply(self, input, scalar, inplace=True, name=None): + """Scalar multiplication of a tensor by an scalar. + + :param input: the input Tensor. + :type input: Tensor + + :param input: the scalar + :type scalar: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_scalar_multiply( + self.handle, input.handle, scalar, inplace, c_name + ) + self.add_layer(OpType.SCALAR_MULTIPLY, name) + return Tensor(handle, owner_op_type=OpType.SCALAR_MULTIPLY) + + def scalar_add(self, input, scalar, inplace=True, name=None): + """Scalar addition of a scalar to each entry of a tensor. + + :param input: the input Tensor. + :type input: Tensor + + :param input: the scalar + :type scalar: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_scalar_add( + self.handle, input.handle, scalar, inplace, c_name + ) + self.add_layer(OpType.SCALAR_ADD, name) + return Tensor(handle, owner_op_type=OpType.SCALAR_ADD) + + def scalar_sub(self, input, scalar, inplace=True, name=None): + """Scalar subtraction of a scalar to each entry of a tensor. + + :param input: the input Tensor. + :type input: Tensor + + :param input: the scalar + :type scalar: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_scalar_sub( + self.handle, input.handle, scalar, inplace, c_name + ) + self.add_layer(OpType.SCALAR_SUB, name) + return Tensor(handle, owner_op_type=OpType.SCALAR_SUB) + + def scalar_true_divide(self, input, scalar, inplace=True, name=None): + """Scalar regular division of a tensor by an scalar. + + :param input: the input Tensor. + :type input: Tensor + + :param input: the scalar + :type scalar: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_scalar_truediv( + self.handle, input.handle, scalar, inplace, c_name + ) + self.add_layer(OpType.SCALAR_TRUEDIV, name) + return Tensor(handle, owner_op_type=OpType.SCALAR_TRUEDIV) + + def gelu(self, input, inplace=True, name=None): + """Gaussian Error Linear Unit activation function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_gelu(self.handle, input.handle, c_name) + self.add_layer(OpType.GELU, name) + return Tensor(handle, owner_op_type=OpType.GELU) + + def relu(self, input, inplace=True, name=None): + """Rectified Linear Unit activation function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_relu( + self.handle, input.handle, inplace, c_name + ) + self.add_layer(OpType.RELU, name) + return Tensor(handle, owner_op_type=OpType.RELU) + + def identity(self, input, name=None): + """Identity function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_identity(self.handle, input.handle, c_name) + self.add_layer(OpType.IDENTITY, name) + return Tensor(handle, owner_op_type=OpType.IDENTITY) + + def sigmoid(self, input, name=None): + """Sigmoid activation function, :math:`sigmoid(x) = 1 / (1 + exp(-x))`. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_sigmoid(self.handle, input.handle, c_name) + self.add_layer(OpType.SIGMOID, name) + return Tensor(handle, owner_op_type=OpType.SIGMOID) + + def tanh(self, input, name=None): + """Hyperbolic tangent activation function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_tanh(self.handle, input.handle, c_name) + self.add_layer(OpType.TANH, name) + return Tensor(handle, owner_op_type=OpType.TANH) + + def elu(self, input, inplace=True, name=None): + """Exponential Linear Unit. activation function. + + :param input: the input Tensor. + :type input: Tensor + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_elu( + self.handle, input.handle, inplace, c_name + ) + self.add_layer(OpType.ELU, name) + return Tensor(handle, owner_op_type=OpType.ELU) + + def dropout(self, input, rate, seed, name=None): + """The Dropout layer randomly sets input units to 0 with + a frequency of :attr:`rate` at each step during training time, + which helps prevent overfitting. + Inputs not set to 0 are scaled up by 1/(1 - rate) such that the + sum over all inputs is unchanged. + + :param input: the input Tensor. + :type input: Tensor + + :param rate: Fraction of the input units to drop. + :type rate: float(0-1) + + :param seed: random seed. + :type seed: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_dropout( + self.handle, input.handle, rate, seed, c_name + ) + self.add_layer(OpType.DROPOUT, name) + return Tensor(handle, owner_op_type=OpType.DROPOUT) + + def multihead_attention( + self, + query, + key, + value, + embed_dim, + num_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + kernel_initializer=None, + name=None, + ): + """Defines the MultiHead Attention operation as described in Attention Is All You Need + which takes in the tensors :attr:`query`, :attr:`key`, and :attr:`value`, + and returns the dot-product attention between them:. + + :param query: the query Tensor. + :type query: Tensor + + :param key: the key Tensor. + :type key: Tensor + + :param value: the value Tensor. + :type value: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_heads: Number of attention heads. + :type num_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + handle = ffc().flexflow_model_add_multihead_attention( + self.handle, + query.handle, + key.handle, + value.handle, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + kernel_init_handle, + c_name, + ) + self.add_layer(OpType.MULTIHEAD_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.MULTIHEAD_ATTENTION) + + def inc_multihead_self_attention( + self, + input, + embed_dim, + num_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the MultiHead Attention operation as described in Attention Is All You Need + which takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + In inference mode, the attention is computed using incremental decoding. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_heads: Number of attention heads. + :type num_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_inc_multihead_self_attention( + self.handle, + input.handle, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.INC_MULTIHEAD_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.INC_MULTIHEAD_ATTENTION) + + def spec_inc_multihead_self_attention( + self, + input, + embed_dim, + num_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the MultiHead Attention operation as described in Attention Is All You Need + which takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + This operator only supports computing the attention in inference (beam search) mode. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_heads: Number of attention heads. + :type num_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_spec_inc_multihead_self_attention( + self.handle, + input.handle, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.SPEC_INC_MULTIHEAD_SELF_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.SPEC_INC_MULTIHEAD_SELF_ATTENTION) + + def inc_multihead_self_attention_verify( + self, + input, + embed_dim, + num_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the MultiHead Attention operation as described in Attention Is All You Need + which takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + This operator only supports computing the attention in inference (tree verify) mode. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_heads: Number of attention heads. + :type num_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_inc_multihead_self_attention_verify( + self.handle, + input.handle, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.TREE_INC_MULTIHEAD_SELF_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.TREE_INC_MULTIHEAD_SELF_ATTENTION) + + def inc_multiquery_self_attention( + self, + input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the multi-query head attention, which allows a different number of Q and KV heads, + and takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + In inference mode, the attention is computed using incremental decoding. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_q_heads: Number of query attention heads. + :type num_q_heads: int + + :param num_kv_heads: Number of key/value attention heads. + :type num_kv_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_inc_multiquery_self_attention( + self.handle, + input.handle, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.INC_MULTIHEAD_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.INC_MULTIHEAD_ATTENTION) + + def spec_inc_multiquery_self_attention( + self, + input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the multi-query head attention, which allows a different number of Q and KV heads, + and takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + This operator only supports computing the attention in inference (beam search) mode. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_q_heads: Number of query attention heads. + :type num_q_heads: int + + :param num_kv_heads: Number of key/value attention heads. + :type num_kv_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_spec_inc_multiquery_self_attention( + self.handle, + input.handle, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.SPEC_INC_MULTIHEAD_SELF_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.SPEC_INC_MULTIHEAD_SELF_ATTENTION) + + def inc_multiquery_self_attention_verify( + self, + input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim=0, + vdim=0, + dropout=0.0, + bias=True, + add_bias_kv=False, + add_zero_attn=False, + data_type=DataType.DT_NONE, + kernel_initializer=None, + apply_rotary_embedding=False, + scaling_query=False, + scaling_factor=1.0, + qk_prod_scaling=True, + position_bias=False, + name=None, + ): + """Defines the multi-query head attention, which allows a different number of Q and KV heads, + and takes in the tensors :attr:`input`, and uses it for all three of query, key and values. + This operator only supports computing the attention in inference (tree verify) mode. + + :param input: the input Tensor. + :type input: Tensor + + :param embed_dim: total dimension of the model + :type embed_dim: int + + :param num_q_heads: Number of query attention heads. + :type num_q_heads: int + + :param num_kv_heads: Number of key/value attention heads. + :type num_kv_heads: int + + :param kdim: total number of features in key. Default is 0 + :type kdim: int + + :param vdim: total number of features in value. Default is 0 + :type vdim: int + + :param dropout: a Dropout layer on attn_output_weights. Default is 0.0 + :type dropout: float(0-1) + + :param bias: Whether the dense layers use bias vectors. Default is True. + :type bias: bool + + :param add_bias_kv: add bias to the key and value sequences at dim=0. Default is False. + :type add_bias_kv: bool + + :param add_zero_attn: add a new batch of zeros to the key and value sequences at dim=1. Default is False. + :type add_zero_attn: bool + + :param data_type: the data type of the tensors. Default is DataType.DT_NONE, which means using the data type of the input tensors. + :type data_type: DataType + + :param kernel_initializer: Initializer for dense layer kernels. If it is set to None, the GlorotUniformInitializer is applied. + :type kernel_initializer: Initializer + + :param apply_rotary_embedding: Whether to apply rotary embeddings. Default is False. + :type apply_rotary_embedding: bool + + :param scaling_query: Whether to apply scaling query. Default is False. + :type scaling_query: bool + + :param scaling_factor: The scaling factor to use for scaling. Default is 1.0. + :type scaling_factor: float + + :param qk_prod_scaling: Whether to apply scaling to the QK product. Default is True. + :type qk_prod_scaling: bool + + :param position_bias: Whether to add position bias to the QK product. Default is False. + :type position_bias: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + kernel_init_handle = self.__get_initializer_handle(kernel_initializer) + c_data_type = enum_to_int(DataType, data_type) + handle = ffc().flexflow_model_add_inc_multiquery_self_attention_verify( + self.handle, + input.handle, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + c_data_type, + kernel_init_handle, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + c_name, + ) + self.add_layer(OpType.TREE_INC_MULTIHEAD_SELF_ATTENTION, name) + return Tensor(handle, owner_op_type=OpType.TREE_INC_MULTIHEAD_SELF_ATTENTION) + + def rms_norm(self, input, eps, dim, name=None): + """Defines the RMS Norm layer. + + :param input: the input Tensor. + :type input: Tensor + + :param eps: a value added to the denominator for numerical stability + :type eps: float + + :param dim: The dimension with respect to which to take the norm + :type dim: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_rms_norm( + self.handle, input.handle, eps, dim, c_name + ) + self.add_layer(OpType.RMS_NORM, name) + return Tensor(handle, owner_op_type=OpType.RMS_NORM) + + def residual_rms_norm(self, input1, input2, eps, dim, name=None): + """Defines the Residual RMS Norm layer. + + :param input: the input 1 Tensor. + :type input: Tensor + + :param input: the input 2 Tensor. + :type input: Tensor + + :param eps: a value added to the denominator for numerical stability + :type eps: float + + :param dim: The dimension with respect to which to take the norm + :type dim: int + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handles_array = ffc().flexflow_model_add_residual_rms_norm( + self.handle, input1.handle, input2.handle, eps, dim, c_name + ) + self.add_layer(OpType.RESIDUAL_RMS_NORM, name) + return Tensor(handles_array[0], owner_op_type=OpType.RESIDUAL_RMS_NORM), Tensor( + handles_array[1], owner_op_type=OpType.RESIDUAL_RMS_NORM + ) + + def arg_top_k(self, input, k, sorted, speculative_decoding, name=None): + """Defines the Arg TopK layer. + + :param input: the input Tensor. + :type input: Tensor + + :param k: the top k indices to select + :type k: int + + :param sorted: Whether the entries should be sorted + :type sorted: bool + + :param speculative_decoding: Whether you need to perform beam search + :type speculative_decoding: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_arg_top_k( + self.handle, input.handle, k, sorted, c_name + ) + self.add_layer(OpType.ARG_TOPK, name) + return Tensor(handle, owner_op_type=OpType.ARG_TOPK) + + def beam_top_k(self, input, max_beam_size, sorted, name=None): + """Defines the Beam TopK layer. + + :param input: the input Tensor. + :type input: Tensor + + :param max_beam_size: the top max_beam_size indices to select + :type max_beam_size: int + + :param sorted: Whether the entries should be sorted + :type sorted: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_beam_top_k( + self.handle, input.handle, max_beam_size, sorted, c_name + ) + self.add_layer(OpType.BEAM_TOPK, name) + return Tensor(handle, owner_op_type=OpType.BEAM_TOPK) + + def sampling(self, input, top_p, name=None): + """Defines the Sampling layer. + + :param input: the input Tensor. + :type input: Tensor + + :param top_p: The top_p parameter of the sampling + :type top_p: float + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_sampling( + self.handle, input.handle, top_p, c_name + ) + self.add_layer(OpType.SAMPLING, name) + return Tensor(handle, owner_op_type=OpType.SAMPLING) + + def argmax(self, input, beam_search, name=None): + """Defines the Sampling layer. + + :param input: the input Tensor. + :type input: Tensor + + :param beam_search: Whether you need to perform beam search + :type beam_search: bool + + :param name: the name of the layer. Default is None. + :type name: string + + :returns: Tensor -- the output tensor. + """ + c_name = get_c_name(name) + handle = ffc().flexflow_model_add_argmax( + self.handle, input.handle, beam_search, c_name + ) + self.add_layer(OpType.ARGMAX, name) + return Tensor(handle, owner_op_type=OpType.ARGMAX) + + def reset_metrics(self): + """Reset performance metrics. + + :returns: None -- no returns. + """ + ffc().flexflow_model_reset_metrics(self.handle) + + def init_layers(self): + """Initialize layers. + + :returns: None -- no returns. + """ + ffc().flexflow_model_init_layers(self.handle) + + def prefetch(self): + ffc().flexflow_model_prefetch(self.handle) + + def forward(self, seq_length=None): + """Forward propagation of all layers. + + :returns: None -- no returns. + """ + if seq_length is None: + seq_length = -1 + ffc().flexflow_model_forward(self.handle, seq_length) + + # TODO: seperate compute_metrics from backward + def backward(self, seq_length=None): + """Backward propagation of all layers. + + :returns: None -- no returns. + """ + if seq_length is None: + seq_length = -1 + ffc().flexflow_model_backward(self.handle, seq_length) + + def compute_metrics(self): + """Compute performance metrics. + + :returns: None -- no returns. + """ + ffc().flexflow_model_compute_metrics(self.handle) + + def update(self): + """Update weights and biases of all layers. + + :returns: None -- no returns. + """ + ffc().flexflow_model_update(self.handle) + + def compile(self, optimizer=None, loss_type=None, metrics=None, comp_mode=None): + """Configure the model for trainting. FlexFlow uses lazy initialization, + so the actual creating of all operations (including creating and partitioning + of weight, bias and output tensors) happen during compile. + + :param optimizer: optimizer instance. + :type optimizer: Optimizer + + :param loss_type: Enum of LossType. + Options are LOSS_CATEGORICAL_CROSSENTROPY, LOSS_SPARSE_CATEGORICAL_CROSSENTROPY, + LOSS_MEAN_SQUARED_ERROR_AVG_REDUCE and LOSS_MEAN_SQUARED_ERROR_SUM_REDUCE. + :type loss_type: LossType + + :param metrics: List of metrics to be evaluated by the model during training and testing. + Each of this is a Enum of MetricsType. Options are METRICS_ACCURACY, + METRICS_CATEGORICAL_CROSSENTROPY, METRICS_SPARSE_CATEGORICAL_CROSSENTROPY, + METRICS_MEAN_SQUARED_ERROR, METRICS_ROOT_MEAN_SQUARED_ERROR, METRICS_MEAN_ABSOLUTE_ERROR + :type metrics: MetricsType + + :param comp_mode: Enum of CompMode. + Options are COMP_MODE_TRAINING, COMP_MODE_INFERENCE + :type comp_mode: CompMode + + :returns: None -- no returns. + """ + self.optimizer = optimizer + + c_loss_type = enum_to_int(LossType, loss_type) + metrics_int = [] + for metric in metrics: + metrics_int.append(enum_to_int(MetricsType, metric)) + c_metrics = ffi.new("int[]", metrics_int) + if comp_mode == None: + comp_mode = CompMode.TRAINING + c_comp_mode = enum_to_int(CompMode, comp_mode) + ffc().flexflow_model_compile( + self.handle, c_loss_type, c_metrics, len(metrics), c_comp_mode + ) + for ff_tensor, np_tensor in self.attr_tensors.items(): + ff_tensor.set_tensor(self, np_tensor) + print("Compiled ffmodel!") + + def fit(self, x=None, y=None, batch_size=None, epochs=1): + """Trains the model for a fixed number of epochs (iterations on a dataset). + + :param x: Input data. It can be a Dataloader instance or a list of Dataloader instances. + :type x: Dataloader + + :param y: Target data (label). It can be a Dataloader instance or a list of Dataloader instances. + :type y: Dataloader + + :param batch_size: Number of samples per gradient update. It must be identical with :attr:`-b` + or :attr:`--batch-size` from the command line. + :type batch_size: int + + :param epochs: Number of epochs to train the model. + An epoch is an iteration over the entire :attr:`x` and :attr:`y` data provided. + The default value is 1. + :type epochs: int + + :returns: None -- no returns. + """ + if isinstance(x, list) == False: + dataloaders = [x] + else: + dataloaders = x + dataloaders.append(y) + + num_samples = y.num_samples + batch_size = self._ffconfig.batch_size + self._tracing_id += 1 # get a new tracing id + for epoch in range(0, epochs): + for d in dataloaders: + d.reset() + self.reset_metrics() + iterations = num_samples / batch_size + for iter in range(0, int(iterations)): + self._ffconfig.begin_trace(self._tracing_id) + for d in dataloaders: + d.next_batch(self) + self.forward() + self.zero_gradients() + self.backward() + self.update() + self._ffconfig.end_trace(self._tracing_id) + + def eval(self, x=None, y=None, batch_size=None): + """Returns the loss value & metrics values for the model in test mode. + + :param x: Input data. It can be a Dataloader instance or a list of Dataloader instances. + :type x: Dataloader + + :param y: Target data (label). It can be a Dataloader instance or a list of Dataloader instances. + :type y: Dataloader + + :param batch_size: Number of samples per gradient update. It must be identical with :attr:`-b` + or :attr:`--batch-size` from the command line. + :type batch_size: int + + :param epochs: Number of epochs to train the model. + An epoch is an iteration over the entire :attr:`x` and :attr:`y` data provided. + The default value is 1. + :type epochs: int + + :returns: None -- no returns. + """ + if isinstance(x, list) == False: + dataloaders = [x] + else: + dataloaders = x + dataloaders.append(y) + + num_samples = y.num_samples + batch_size = self._ffconfig.batch_size + for d in dataloaders: + d.reset() + self.reset_metrics() + iterations = num_samples / batch_size + self._tracing_id += 1 # get a new tracing id + for iter in range(0, int(iterations)): + for d in dataloaders: + d.next_batch(self) + self._ffconfig.begin_trace(self._tracing_id) + self.forward() + self.compute_metrics() + self._ffconfig.end_trace(self._tracing_id) + + def zero_gradients(self): + """Empty the gradients of all layers. + + :returns: None -- no returns. + """ + ffc().flexflow_model_zero_gradients(self.handle) + + def set_optimizer(self, optimizer): + if isinstance(optimizer, SGDOptimizer) == True: + ffc().flexflow_model_set_sgd_optimizer(self.handle, optimizer.handle) + elif isinstance(optimizer, AdamOptimizer) == True: + ffc().flexflow_model_set_adam_optimizer(self.handle, optimizer.handle) + elif optimizer == None: + pass + else: + assert 0, "[Model]: unknown optimizer" + + optimizer = property(fset=set_optimizer) + + def print_layers(self, id=-1): + ffc().flexflow_model_print_layers(self.handle, id) + + def get_layer_by_id(self, layer_id): + return self._layers[layer_id] + + def get_last_layer(self): + return self._layers[self._nb_layers - 1] + + def get_layer_by_name(self, layer_name): + for layer_id in self._layers: + layer = self._layers[layer_id] + if layer.name == layer_name: + return layer + assert 0, f"Cannot find the layer with name {layer_name}" + return None + + def get_tensor_by_id(self, id): + handle = ffc().flexflow_model_get_parameter_by_id(self.handle, id) + return Parameter(handle) + + @property + def label_tensor(self): + handle = ffc().flexflow_model_get_label_tensor(self.handle) + return Tensor(handle, deallocate=False) + + def get_perf_metrics(self): + handle = ffc().flexflow_model_get_perf_metrics(self.handle) + return PerfMetrics(handle) + + def set_transformer_layer_id(self, id): + ffc().flexflow_model_set_transformer_layer_id(self.handle, id) + + def create_data_loader(self, batch_tensor, full_array): + """Create a SingleDataloader instance. + + :param batch_tensor: a batch-sized tensor. Usually it is a input tensor of the model. + :type batch_tensor: Tensor + + :param full_array: the entire data. + :type full_array: Numpy Array + + :returns: SingleDataloader -- returns a dataloader instance. + """ + + if self._ffconfig.enable_control_replication: + assert ( + self._ffconfig.python_data_loader_type != 1 + ), "To enable control replication, please set --python-data-loader-type 2" + return self.__create_data_loader_ptr(batch_tensor, full_array) + else: + if self._ffconfig.python_data_loader_type == 1: + return self.__create_data_loader_attach(batch_tensor, full_array) + else: + return self.__create_data_loader_ptr(batch_tensor, full_array) + + def __create_data_loader_attach(self, batch_tensor, full_array): + full_array_shape = full_array.shape + num_samples = full_array_shape[0] + num_dim = len(full_array_shape) + if full_array.dtype == "float16": + datatype = DataType.DT_HALF + elif full_array.dtype == "float32": + datatype = DataType.DT_FLOAT + elif full_array.dtype == "int32": + datatype = DataType.DT_INT32 + elif full_array.dtype == "int64": + datatype = DataType.DT_INT64 + else: + assert 0, "unsupported datatype" + + if num_dim == 2: + full_tensor = self.create_tensor( + [num_samples, full_array_shape[1]], datatype + ) + self.map_tensor(full_tensor) + elif num_dim == 4: + full_tensor = self.create_tensor( + [ + num_samples, + full_array_shape[1], + full_array_shape[2], + full_array_shape[3], + ], + datatype, + ) + self.map_tensor(full_tensor) + else: + assert 0, "unsupported dims" + + full_tensor.attach_numpy_array(self._ffconfig, full_array) + dataloader = SingleDataLoader( + self, batch_tensor, full_tensor, num_samples, datatype + ) + full_tensor.detach_numpy_array(self._ffconfig) + + return dataloader + + def __create_data_loader_ptr(self, batch_tensor, full_array): + full_array_shape = full_array.shape + num_samples = full_array_shape[0] + if full_array.dtype == "float16": + datatype = DataType.DT_HALF + elif full_array.dtype == "float32": + datatype = DataType.DT_FLOAT + elif full_array.dtype == "int32": + datatype = DataType.DT_INT32 + elif full_array.dtype == "int64": + datatype = DataType.DT_INT64 + else: + assert 0, "unsupported datatype" + np_raw_ptr = full_array.__array_interface__["data"] + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + print( + "numpy array: %s, %s, %s" + % (str(np_raw_ptr), str(raw_ptr), hex(np_raw_ptr[0])) + ) + dataloader = SingleDataLoader( + self, batch_tensor, raw_ptr, num_samples, datatype + ) + + return dataloader + + def __get_initializer_handle(self, initializer): + if initializer == None: + null_initializer = Initializer(None) + return null_initializer.handle + else: + return initializer.handle + + def __get_op_handle(self, shared_op): + if shared_op == None: + op_handle = ffi.new("flexflow_op_t *") + op_handle.impl = ffi.NULL + op = Op(op_handle[0]) + else: + op = shared_op + return op.handle + + def get_output_tensor(self, ffmodel, data_type): + shape = self.dims + if data_type == DataType.DT_HALF: + np_array = np.empty(shape, dtype=np.float16) + elif data_type == DataType.DT_FLOAT: + np_array = np.empty(shape, dtype=np.float32) + elif self.data_type == DataType.DT_INT32: + np_array = np.empty(shape, dtype=np.int32) + elif self.data_type == DataType.DT_INT64: + np_array = np.empty(shape, dtype=np.int64) + else: + assert 0, f"Unsupported datatype: {self.data_type}" + np_raw_ptr = np_array.__array_interface__["data"] + if np_array.dtype == np.float32: + raw_ptr = ffi.cast("float*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_float( + self.handle, ffmodel.handle, raw_ptr, False + ) + elif np_array.dtype == np.int32: + raw_ptr = ffi.cast("int*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int( + self.handle, ffmodel.handle, raw_ptr, False + ) + elif np_array.dtype == np.int64: + raw_ptr = ffi.cast("int64_t*", np_raw_ptr[0]) + ret_val = ffc().flexflow_tensor_get_tensor_int64( + self.handle, ffmodel.handle, raw_ptr, False + ) + fflogger.debug( + "get weights raw_ptr: %s, %s, %s, %s" + % (str(raw_ptr), str(np_raw_ptr[0]), hex(np_raw_ptr[0]), str(shape)) + ) + assert ret_val == True + return np_array + + def generate(self, prompt_list, max_sequence_length): + assert isinstance(prompt_list, list) + c_input_texts = [get_c_name(prompt) for prompt in prompt_list] + max_num_chars = 5 * (max_sequence_length + 100) + c_output_texts = [ffi.new("char[]", max_num_chars) for prompt in prompt_list] + c_output_length_and_tokens = [ffi.new("int[]", max_sequence_length + 100) for prompt in prompt_list] + ffc().flexflow_model_generate( + self.handle, + len(prompt_list), + c_input_texts, + max_num_chars, + c_output_texts, + max_sequence_length, + c_output_length_and_tokens, + ) + #output_length = c_output_length_and_tokens[0] + #output_tokens = [] + #for i in range(output_length): + # output_tokens.append(c_output_length_and_tokens[i + 1]) + from flexflow.serve import GenerationResult + + return [GenerationResult(ffi.string(c_output_text), []) for c_output_text in c_output_texts] + + def set_position_offset(self, offset): + ffc().flexflow_model_set_position_offset(self.handle, offset) + # ----------------------------------------------------------------------- # SGDOptimizer # ----------------------------------------------------------------------- + class SGDOptimizer(object): - __slots__ = ['handle', '_handle'] - def __init__(self, ffmodel, lr=0.01, momentum=0.0, nesterov=False, weight_decay=0.0): - self.handle = ffc.flexflow_sgd_optimizer_create(ffmodel.handle, lr, momentum, nesterov, weight_decay) - self._handle = ffi.gc(self.handle, ffc.flexflow_sgd_optimizer_destroy) + __slots__ = ["handle", "_handle"] + + def __init__( + self, ffmodel, lr=0.01, momentum=0.0, nesterov=False, weight_decay=0.0 + ): + self.handle = ffc().flexflow_sgd_optimizer_create( + ffmodel.handle, lr, momentum, nesterov, weight_decay + ) + self._handle = ffi.gc(self.handle, ffc().flexflow_sgd_optimizer_destroy) + + def set_learning_rate(self, learning_rate): + ffc().flexflow_sgd_optimizer_set_lr(self.handle, learning_rate) - def set_learning_rate(self, learning_rate): - ffc.flexflow_sgd_optimizer_set_lr(self.handle, learning_rate) # ----------------------------------------------------------------------- # AdamOptimizer # ----------------------------------------------------------------------- + class AdamOptimizer(object): - __slots__ = ['handle', '_handle'] - def __init__(self, ffmodel, alpha=0.001, beta1=0.9, beta2=0.999, weight_decay=0.0, epsilon=1e-8): - self.handle = ffc.flexflow_adam_optimizer_create(ffmodel.handle, alpha, beta1, beta2, weight_decay, epsilon) - self._handle = ffi.gc(self.handle, ffc.flexflow_adam_optimizer_destroy) + __slots__ = ["handle", "_handle"] + + def __init__( + self, + ffmodel, + alpha=0.001, + beta1=0.9, + beta2=0.999, + weight_decay=0.0, + epsilon=1e-8, + ): + self.handle = ffc().flexflow_adam_optimizer_create( + ffmodel.handle, alpha, beta1, beta2, weight_decay, epsilon + ) + self._handle = ffi.gc(self.handle, ffc().flexflow_adam_optimizer_destroy) + + def set_learning_rate(self, learning_rate): + ffc().flexflow_adam_optimizer_set_lr(self.handle, learning_rate) - def set_learning_rate(self, learning_rate): - ffc.flexflow_adam_optimizer_set_lr(self.handle, learning_rate) # ----------------------------------------------------------------------- # Initializer # ----------------------------------------------------------------------- class Initializer(object): - __slots__ = ['handle', 'p_handle'] - def __init__(self, handle, p_handle=0): - self.p_handle = ffi.new('flexflow_initializer_t *') - if (handle == None): - self.p_handle.impl = ffi.NULL - else: - self.p_handle.impl = handle.impl - self.handle = self.p_handle[0] - assert ffi.typeof(self.handle) == ffi.typeof('flexflow_initializer_t'), "Initializer handle is wrong" + __slots__ = ["handle", "p_handle"] + + def __init__(self, handle, p_handle=0): + self.p_handle = ffi.new("flexflow_initializer_t *") + if handle == None: + self.p_handle.impl = ffi.NULL + else: + self.p_handle.impl = handle.impl + self.handle = self.p_handle[0] + assert ffi.typeof(self.handle) == ffi.typeof( + "flexflow_initializer_t" + ), "Initializer handle is wrong" + # ----------------------------------------------------------------------- # GlorotUniform # ----------------------------------------------------------------------- + class GlorotUniformInitializer(Initializer): - __slots__ = ['glorot_handle', '_glorot_handle'] - def __init__(self, seed): - self.glorot_handle = ffc.flexflow_glorot_uniform_initializer_create(seed) - self._glorot_handle = ffi.gc(self.glorot_handle, ffc.flexflow_glorot_uniform_initializer_destroy) - super(GlorotUniformInitializer, self).__init__(self.glorot_handle) + __slots__ = ["glorot_handle", "_glorot_handle"] + + def __init__(self, seed): + self.glorot_handle = ffc().flexflow_glorot_uniform_initializer_create(seed) + self._glorot_handle = ffi.gc( + self.glorot_handle, ffc().flexflow_glorot_uniform_initializer_destroy + ) + super(GlorotUniformInitializer, self).__init__(self.glorot_handle) + # ----------------------------------------------------------------------- # ZeroInitializer # ----------------------------------------------------------------------- + class ZeroInitializer(Initializer): - __slots__ = ['zero_handle', '_zero_handle'] - def __init__(self): - self.zero_handle = ffc.flexflow_zero_initializer_create() - self._zero_handle = ffi.gc(self.zero_handle, ffc.flexflow_zero_initializer_destroy) - super(ZeroInitializer, self).__init__(self.zero_handle) + __slots__ = ["zero_handle", "_zero_handle"] + + def __init__(self): + self.zero_handle = ffc().flexflow_zero_initializer_create() + self._zero_handle = ffi.gc( + self.zero_handle, ffc().flexflow_zero_initializer_destroy + ) + super(ZeroInitializer, self).__init__(self.zero_handle) + # ----------------------------------------------------------------------- # UniformInitializer # ----------------------------------------------------------------------- + class UniformInitializer(Initializer): - __slots__ = ['uniform_handle', '_uniform_handle'] - def __init__(self, seed, minv, maxv): - self.uniform_handle = ffc.flexflow_uniform_initializer_create(seed, minv, maxv) - self._uniform_handle = ffi.gc(self.uniform_handle, ffc.flexflow_uniform_initializer_destroy) - super(UniformInitializer, self).__init__(self.uniform_handle) + __slots__ = ["uniform_handle", "_uniform_handle"] + + def __init__(self, seed, minv, maxv): + self.uniform_handle = ffc().flexflow_uniform_initializer_create( + seed, minv, maxv + ) + self._uniform_handle = ffi.gc( + self.uniform_handle, ffc().flexflow_uniform_initializer_destroy + ) + super(UniformInitializer, self).__init__(self.uniform_handle) + # ----------------------------------------------------------------------- # NormInitializer # ----------------------------------------------------------------------- + class NormInitializer(Initializer): - __slots__ = ['norm_handle', '_norm_handle'] - def __init__(self, seed, mean, stddev): - self.norm_handle = ffc.flexflow_norm_initializer_create(seed, mean, stddev) - self._norm_handle = ffi.gc(self.norm_handle, ffc.flexflow_norm_initializer_destroy) - super(NormInitializer, self).__init__(self.norm_handle) + __slots__ = ["norm_handle", "_norm_handle"] + + def __init__(self, seed, mean, stddev): + self.norm_handle = ffc().flexflow_norm_initializer_create(seed, mean, stddev) + self._norm_handle = ffi.gc( + self.norm_handle, ffc().flexflow_norm_initializer_destroy + ) + super(NormInitializer, self).__init__(self.norm_handle) + # ----------------------------------------------------------------------- # PerfMetrics # ----------------------------------------------------------------------- + class PerfMetrics(object): - __slots__= ['handle', '_handle'] - def __init__(self, handle): - self.handle = handle - self._handle = ffi.gc(self.handle, ffc.flexflow_per_metrics_destroy) + __slots__ = ["handle", "_handle"] + + def __init__(self, handle): + self.handle = handle + self._handle = ffi.gc(self.handle, ffc().flexflow_per_metrics_destroy) + + def get_accuracy(self): + return ffc().flexflow_per_metrics_get_accuracy(self.handle) - def get_accuracy(self): - return ffc.flexflow_per_metrics_get_accuracy(self.handle) # ----------------------------------------------------------------------- # NetConfig # ----------------------------------------------------------------------- + class NetConfig(object): - def __init__(self): - self.handle = ffc.flexflow_net_config_create() - self._handle = ffi.gc(self.handle, ffc.flexflow_net_config_destroy) - cpath = ffc.flexflow_net_config_get_dataset_path(self.handle) - self.dataset_path = ffi.string(cpath) + def __init__(self): + self.handle = ffc().flexflow_net_config_create() + self._handle = ffi.gc(self.handle, ffc().flexflow_net_config_destroy) + cpath = ffc().flexflow_net_config_get_dataset_path(self.handle) + self.dataset_path = ffi.string(cpath) + # ----------------------------------------------------------------------- # DLRMConfig # ----------------------------------------------------------------------- + class DLRMConfig(object): - def __init__(self): - self.handle = ffc.flexflow_dlrm_config_create() - self._handle = ffi.gc(self.handle, ffc.flexflow_dlrm_config_destroy) + def __init__(self): + self.handle = ffc().flexflow_dlrm_config_create() + self._handle = ffi.gc(self.handle, ffc().flexflow_dlrm_config_destroy) + + cstr = ffc().flexflow_dlrm_config_get_dataset_path(self.handle) + self.dataset_path = ffi.string(cstr) + + cstr = ffc().flexflow_dlrm_config_get_arch_interaction_op(self.handle) + self.arch_interaction_op = ffi.string(cstr) + + self.sparse_feature_size = ffc().flexflow_dlrm_config_get_sparse_feature_size( + self.handle + ) + self.sigmoid_bot = ffc().flexflow_dlrm_config_get_sigmoid_bot(self.handle) + self.sigmoid_top = ffc().flexflow_dlrm_config_get_sigmoid_top(self.handle) + self.embedding_bag_size = ffc().flexflow_dlrm_config_get_embedding_bag_size( + self.handle + ) + self.loss_threshold = ffc().flexflow_dlrm_config_get_loss_threshold(self.handle) + + mlp_bot_c = ffc().flexflow_dlrm_config_get_mlp_bot(self.handle) + self.mlp_bot = [] + for i in range(0, mlp_bot_c[0]): + self.mlp_bot.append(mlp_bot_c[i + 1]) + + mlp_top_c = ffc().flexflow_dlrm_config_get_mlp_top(self.handle) + self.mlp_top = [] + for i in range(0, mlp_top_c[0]): + self.mlp_top.append(mlp_top_c[i + 1]) + + embedding_size_c = ffc().flexflow_dlrm_config_get_embedding_size(self.handle) + self.embedding_size = [] + for i in range(0, embedding_size_c[0]): + self.embedding_size.append(embedding_size_c[i + 1]) - cstr = ffc.flexflow_dlrm_config_get_dataset_path(self.handle) - self.dataset_path = ffi.string(cstr) - cstr = ffc.flexflow_dlrm_config_get_arch_interaction_op(self.handle) - self.arch_interaction_op = ffi.string(cstr) +# ----------------------------------------------------------------------- +# Single DataLoader +# ----------------------------------------------------------------------- - self.sparse_feature_size = ffc.flexflow_dlrm_config_get_sparse_feature_size(self.handle) - self.sigmoid_bot = ffc.flexflow_dlrm_config_get_sigmoid_bot(self.handle) - self.sigmoid_top = ffc.flexflow_dlrm_config_get_sigmoid_top(self.handle) - self.embedding_bag_size = ffc.flexflow_dlrm_config_get_embedding_bag_size(self.handle) - self.loss_threshold = ffc.flexflow_dlrm_config_get_loss_threshold(self.handle) - mlp_bot_c = ffc.flexflow_dlrm_config_get_mlp_bot(self.handle) - self.mlp_bot = [] - for i in range(0, mlp_bot_c[0]): - self.mlp_bot.append(mlp_bot_c[i+1]) +class SingleDataLoader(object): + __slots__ = ["handle", "_handle"] + + def __init__(self, ffmodel, input, full_input, num_samples, data_type): + assert type(ffmodel) is FFModel, "SingleDataLoader ffmodel is wrong" + assert type(input) is Tensor, "SingleDataLoader input is wrong" + if type(full_input) is Tensor: + self.init_from_tensor(ffmodel, input, full_input, num_samples, data_type) + else: + self.init_from_ptr(ffmodel, input, full_input, num_samples, data_type) + self._handle = ffi.gc(self.handle, ffc().flexflow_single_dataloader_destroy) + + def init_from_tensor(self, ffmodel, input, full_input, num_samples, data_type): + assert type(full_input) is Tensor, "SingleDataLoader full_input is wrong" + c_data_type = enum_to_int(DataType, data_type) + self.handle = ffc().flexflow_single_dataloader_create( + ffmodel.handle, input.handle, full_input.handle, num_samples, c_data_type + ) + + def init_from_ptr(self, ffmodel, input, full_input, num_samples, data_type): + # assert type(full_input) is Tensor, "SingleDataLoader full_input is wrong" + c_data_type = enum_to_int(DataType, data_type) + self.handle = ffc().flexflow_single_dataloader_create2( + ffmodel.handle, input.handle, full_input, num_samples, c_data_type + ) + + @property + def num_samples(self): + return ffc().flexflow_single_dataloader_get_num_samples(self.handle) + + @num_samples.setter + def num_samples(self, samples): + ffc().flexflow_single_dataloader_set_num_samples(self.handle, samples) + + def next_batch(self, ffmodel): + """Ask the dataloder to load the next batch to the :attr:`batch_tensor`. + + :returns: None -- no returns. + """ + ffc().flowflow_single_dataloader_next_batch(self.handle, ffmodel.handle) + + def reset(self): + """Reset the current position of the dataloder to 0. + + :returns: None -- no returns. + """ + ffc().flexflow_single_dataloader_reset(self.handle) - mlp_top_c = ffc.flexflow_dlrm_config_get_mlp_top(self.handle) - self.mlp_top = [] - for i in range(0, mlp_top_c[0]): - self.mlp_top.append(mlp_top_c[i+1]) - embedding_size_c = ffc.flexflow_dlrm_config_get_embedding_size(self.handle) - self.embedding_size = [] - for i in range(0, embedding_size_c[0]): - self.embedding_size.append(embedding_size_c[i+1]) +class RegionNdarray(object): + __slots__ = ["__array_interface__"] + + def __init__(self, shape, data_type, base_ptr, strides, read_only): + # See: https://docs.scipy.org/doc/numpy/reference/arrays.interface.html + if data_type == DataType.DT_HALF: + field_type = " str: def get_shared_library(self) -> str: libname = "libflexflow" + self.get_library_extension() - return os.path.join(libname) + + # If we installed with pip, use the full path instead of just the library name, because the library will not be in the LD_LIBRARY_PATH + candidate_package_dirs = [pkg for func in (site.getsitepackages(), site.getusersitepackages()) for pkg in ([func] if isinstance(func, str) else func)] + candidate_package_dirs += sysconfig.get_python_lib(plat_specific=False, standard_lib=False) + for packages_dir in candidate_package_dirs: + ff_lib_path = os.path.join(packages_dir, "flexflow", "lib", libname) + installed_with_pip = os.path.exists(ff_lib_path) + if installed_with_pip: + return ff_lib_path + return libname def get_c_header(self) -> str: return self._header diff --git a/python/flexflow/findpylib.py b/python/flexflow/findpylib.py index 2ac9dcbbb9..c2ce002996 100755 --- a/python/flexflow/findpylib.py +++ b/python/flexflow/findpylib.py @@ -1,4 +1,4 @@ -#!/usr/bin/env python +#!/usr/bin/env python3 """ Locate libpython associated with this Python executable. diff --git a/python/flexflow/flexflow_python b/python/flexflow/flexflow_python index 7fed992c6d..cf247b9ede 100644 --- a/python/flexflow/flexflow_python +++ b/python/flexflow/flexflow_python @@ -7,5 +7,6 @@ pylib_path="$(python "$python_packages"/flexflow/findpylib.py)" pylib_dir="$(dirname "$pylib_path")" export PATH="${python_packages}/flexflow/bin:${PATH}" export LD_LIBRARY_PATH="${python_packages}/flexflow/lib:${pylib_dir}:${PATH}" +legion_python_args=("$@" "-ll:py" "1") -legion_python "$@" \ No newline at end of file +legion_python "${legion_python_args[@]}" diff --git a/python/flexflow/jupyter.py b/python/flexflow/jupyter.py deleted file mode 100644 index e2ed529c85..0000000000 --- a/python/flexflow/jupyter.py +++ /dev/null @@ -1,37 +0,0 @@ -# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) -# -# Licensed under the Apache License, Version 2.0 (the "License"); -# you may not use this file except in compliance with the License. -# You may obtain a copy of the License at -# -# http://www.apache.org/licenses/LICENSE-2.0 -# -# Unless required by applicable law or agreed to in writing, software -# distributed under the License is distributed on an "AS IS" BASIS, -# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. -# See the License for the specific language governing permissions and -# limitations under the License. -# - -import json -from flexflow.config import flexflow_dir - -_CONFIG_FILENAME = None - -def set_jupyter_config(filename): - global _CONFIG_FILENAME - _CONFIG_FILENAME = filename - print("config file is set to:", _CONFIG_FILENAME) - -def load_jupyter_config(): - cmd_dict_key = ["cpus", "gpus", "utility", "sysmem", "fbmem", "zcmem"] - argv_dict = {} - global _CONFIG_FILENAME - if _CONFIG_FILENAME is None: - raise Exception("Sorry, jupyter configuration file is not set, please call set_jupyter_config to set the path to the configuration json file.") - with open(_CONFIG_FILENAME) as json_file: - cmd_dict = json.load(json_file) - for key in cmd_dict_key: - if key in cmd_dict and cmd_dict[key]["value"] is not None: - argv_dict[cmd_dict[key]["cmd"]] = cmd_dict[key]["value"] - return argv_dict diff --git a/python/flexflow/keras/layers/merge.py b/python/flexflow/keras/layers/merge.py index fa967422d8..be2fe0c8c9 100644 --- a/python/flexflow/keras/layers/merge.py +++ b/python/flexflow/keras/layers/merge.py @@ -101,7 +101,16 @@ def __init__(self, **kwargs): def _calculate_inout_shape(self, input_tensors): assert len(input_tensors) == 2, "check input_tensors" self.input_shape = input_tensors[0].batch_shape - self.output_shape = input_tensors[0].batch_shape + self.output_shape = list(input_tensors[0].batch_shape) + for i, d in enumerate(input_tensors[1].batch_shape): + if self.output_shape[i] != d: + if self.output_shape[i] == 1 or d == 1: + self.output_shape[i] *= d + else: + raise AssertionError( + f"Tensor with shape {input_tensors[0].batch_shape} and " + f"{input_tensors[1].batch_shape} cannot be added") + self.output_shape = tuple(self.output_shape) fflogger.debug("add output %s" %( str(self.output_shape))) def subtract(input_tensors): @@ -114,7 +123,16 @@ def __init__(self, **kwargs): def _calculate_inout_shape(self, input_tensors): assert len(input_tensors) == 2, "check input_tensors" self.input_shape = input_tensors[0].batch_shape - self.output_shape = input_tensors[0].batch_shape + self.output_shape = list(input_tensors[0].batch_shape) + for i, d in enumerate(input_tensors[1].batch_shape): + if self.output_shape[i] != d: + if self.output_shape[i] == 1 or d == 1: + self.output_shape[i] *= d + else: + raise AssertionError( + f"Tensor with shape {input_tensors[0].batch_shape} and " + f"{input_tensors[1].batch_shape} cannot be subtracted") + self.output_shape = tuple(self.output_shape) fflogger.debug("subtract output %s" %( str(self.output_shape))) def multiply(input_tensors): @@ -127,7 +145,16 @@ def __init__(self, **kwargs): def _calculate_inout_shape(self, input_tensors): assert len(input_tensors) == 2, "check input_tensors" self.input_shape = input_tensors[0].batch_shape - self.output_shape = input_tensors[0].batch_shape + self.output_shape = list(input_tensors[0].batch_shape) + for i, d in enumerate(input_tensors[1].batch_shape): + if self.output_shape[i] != d: + if self.output_shape[i] == 1 or d == 1: + self.output_shape[i] *= d + else: + raise AssertionError( + f"Tensor with shape {input_tensors[0].batch_shape} and " + f"{input_tensors[1].batch_shape} cannot be multiplied") + self.output_shape = tuple(self.output_shape) fflogger.debug("multiply output %s" %( str(self.output_shape))) class Maximum(_Merge): diff --git a/python/flexflow/serve/__init__.py b/python/flexflow/serve/__init__.py new file mode 100644 index 0000000000..5af077273d --- /dev/null +++ b/python/flexflow/serve/__init__.py @@ -0,0 +1,217 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import Optional +from ..type import * +from flexflow.core import * +from .serve import LLM, SSM, GenerationConfig, GenerationResult + + +def __check_positive_int(configs_dict: dict, key: str): + value = configs_dict.get(key, None) + if value is not None: + if type(value) is not int: + raise TypeError(f"Parameter {key} has value {value}, which is not an int!") + elif value <= 0: + raise ValueError( + f"Parameter {key} has value {value}, which is not a positive number!" + ) + + +def init( + configs_dict: Optional[dict] = None, + *, + num_gpus: Optional[int] = None, + memory_per_gpu: Optional[int] = None, + zero_copy_memory_per_node: Optional[int] = None, + num_cpus: Optional[int] = None, + legion_utility_processors: Optional[int] = None, + data_parallelism_degree: Optional[int] = None, + tensor_parallelism_degree: Optional[int] = None, + pipeline_parallelism_degree: Optional[int] = None, + offload: Optional[bool] = None, + offload_reserve_space_size: Optional[int] = None, + use_4bit_quantization: Optional[bool] = None, + use_8bit_quantization: Optional[bool] = None, + profiling: Optional[bool] = None, + benchmarking: Optional[bool] = None, + inference_debugging: Optional[bool] = None, + fusion: Optional[bool] = None, +): + """ + Configure FlexFlow Serve and start the runtime. + + The function takes, alternatively, configs_dict (a positional argument of type dictionary), + or three mandatory named parameters, plus some additional optional named parameters. When passing + a configs_dict, no named parameter should be specified, and the dictionary should have keys matching + at least the mandatory named parameters. + + The three mandatory parameters, which cannot be changed after starting the runtime, are: + - num_gpus: the number of GPUs to reserve for the runtime + - memory_per_gpu: the amount of memory (in MB) to pre-allocate on each GPU + - zero_copy_memory_per_node: the amount of zero-copy memory (in MB) to pre-allocate for each node + + The optional parameters are: + - num_cpus: the number of CPU processors to reserve for the runtime, defaults to 4 + - legion_utility_processors: number of Legion utility threads to create per process, defaults to 1 + - data_parallelism_degree: the degree of parallelization in the data parallel dimension, defaults to 1 + - tensor_parallelism_degree: the degree of parallelization in the tensor parallel dimension (using the Megatron technique), defaults to 1 + - pipeline_parallelism_degree: the degree of parallelization in the pipeline parallel dimension, defaults to 1 + - offload: whether to enable offloading of the weights to CPU, defaults to False + - offload_reserve_space_size: the space (in MB) to reserve on CPU for offloading, default to 1024^2 + - use_4bit_quantization: whether to use 4-bit quantization, defaults to False + - use_8bit_quantization: whether to use 8-bit quantization, defaults to False + - profiling: whether to enable the FlexFlow profiling mode, defaults to False + - benchmarking: whether to run benchmaking only, without loading real weights, defaults to False + - inference_debugging: whether to run inference in debugging mode, saving all inputs/outputs/weights to file, defaults to False + - fusion: whether to enable the FlexFlow operator fusion optimization, defaults to True + + The configurations are passed down to the FlexFlow runtime (implemented in C++) via command line arguments. + + + :param configs_dict: A Python dictionary to pass all configurations as a single object + :type configs_dict: dict + :param num_gpus: the number of GPUs to reserve for the runtime + :type num_gpus: int + :param memory_per_gpu: memory_per_gpu: the amount of memory (in MB) to pre-allocate on each GPU + :type memory_per_gpu: int + :param zero_copy_memory_per_node: zero_copy_memory_per_node: the amount of zero-copy memory (in MB) to pre-allocate for each node + :type zero_copy_memory_per_node: int + :param num_cpus: the number of CPU processors to reserve for the runtime, defaults to 4 + :type num_cpus: Optional[int], optional + :param legion_utility_processors: number of Legion utility threads to create per process, defaults to 1 + :type legion_utility_processors: Optional[int], optional + :param data_parallelism_degree: the degree of parallelization in the data parallel dimension, defaults to 1 + :type data_parallelism_degree: Optional[int], optional + :param tensor_parallelism_degree: the degree of parallelization in the tensor parallel dimension (using the Megatron technique), defaults to 1 + :type tensor_parallelism_degree: Optional[int], optional + :param pipeline_parallelism_degree: the degree of parallelization in the pipeline parallel dimension, defaults to 1 + :type pipeline_parallelism_degree: Optional[int], optional + :param offload: whether to enable offloading of the weights to CPU, defaults to False + :type offload: Optional[bool], optional + :param offload_reserve_space_size: the space (in MB) to reserve on CPU for offloading, default to 1024^2 + :type offload_reserve_space_size: Optional[int], optional + :param use_4bit_quantization: whether to use 4-bit quantization, defaults to False + :type use_4bit_quantization: Optional[bool], optional + :param use_8bit_quantization: whether to use 8-bit quantization, defaults to False + :type use_8bit_quantization: Optional[bool], optional + :param profiling: whether to enable the FlexFlow profiling mode, defaults to False + :type profiling: Optional[bool], optional + :param benchmarking: whether to run benchmaking only, without loading real weights, defaults to False + :type benchmarking: Optional[bool], optional + :param inference_debugging: whether to run inference in debugging mode, saving all inputs/outputs/weights to file, defaults to False + :type inference_debugging: Optional[bool], optional + :param fusion: whether to enable the FlexFlow operator fusion optimization, defaults to True + :type fusion: Optional[bool], optional + + :raises ValueError: this function will raise an exception if the user passes both a configs_dict and some named parameters + :raises TypeError: this function will raise an exception if the configs_dict is not a dictionary + :raises ValueError: this function will raise an exception if the mandatory FlexFlow initialization parameters are missing, or are not positive integers: num_gpus, memory_per_gpu, zero_copy_memory_per_node + """ + + # Check that if configs_dict is passed, no other key-value argument (after the *) is passed. + if configs_dict is not None and any( + [ + num_gpus is not None, + memory_per_gpu is not None, + zero_copy_memory_per_node is not None, + num_cpus is not None, + legion_utility_processors is not None, + data_parallelism_degree is not None, + tensor_parallelism_degree is not None, + pipeline_parallelism_degree is not None, + offload is not None, + offload_reserve_space_size is not None, + use_4bit_quantization is not None, + use_8bit_quantization is not None, + profiling is not None, + benchmarking is not None, + inference_debugging is not None, + fusion is not None, + ] + ): + raise ValueError("Cannot pass both configs_dict and individual args") + + if configs_dict is not None: + if type(configs_dict) != dict: + raise TypeError("configs_dict is not a dictionary") + else: + # Add named key-value arguments into dictionary + configs_dict = { + "num_gpus": num_gpus, + "memory_per_gpu": memory_per_gpu, + "num_cpus": num_cpus, + "zero_copy_memory_per_node": zero_copy_memory_per_node, + "legion_utility_processors": legion_utility_processors, + "data_parallelism_degree": data_parallelism_degree, + "tensor_parallelism_degree": tensor_parallelism_degree, + "pipeline_parallelism_degree": pipeline_parallelism_degree, + "offload": offload, + "offload_reserve_space_size": offload_reserve_space_size, + "use_4bit_quantization": use_4bit_quantization, + "use_8bit_quantization": use_8bit_quantization, + "profiling": profiling, + "benchmarking": benchmarking, + "inference_debugging": inference_debugging, + "fusion": fusion, + } + + # Check that mandatory configs are present + required_keys = ["num_gpus", "memory_per_gpu", "zero_copy_memory_per_node"] + for required_key in required_keys: + if configs_dict.get(required_key, None) is None: + raise ValueError( + "Missing one of the following required configs: num_gpus, memory_per_gpu, zero_copy_memory_per_node" + ) + + # Sanity check parameters + positive_int_params = required_keys + [ + "legion_utility_processors", + "data_parallelism_degree", + "tensor_parallelism_degree", + "pipeline_parallelism_degree", + "offload_reserve_space_size", + ] + for param in positive_int_params: + __check_positive_int(configs_dict, param) + + # Set default values + if configs_dict.get("num_cpus", None) is None: + configs_dict["num_cpus"] = 4 + if configs_dict.get("legion_utility_processors", None) is None: + configs_dict["legion_utility_processors"] = 8 + if configs_dict.get("data_parallelism_degree", None) is None: + configs_dict["data_parallelism_degree"] = 1 + if configs_dict.get("tensor_parallelism_degree", None) is None: + configs_dict["tensor_parallelism_degree"] = 1 + if configs_dict.get("pipeline_parallelism_degree", None) is None: + configs_dict["pipeline_parallelism_degree"] = 1 + if configs_dict.get("offload", None) is None: + configs_dict["offload"] = False + if configs_dict.get("offload_reserve_space_size", None) is None: + configs_dict["offload_reserve_space_size"] = 1024**2 + if configs_dict.get("use_4bit_quantization", None) is None: + configs_dict["use_4bit_quantization"] = False + if configs_dict.get("use_8bit_quantization", None) is None: + configs_dict["use_8bit_quantization"] = False + if configs_dict.get("profiling", None) is None: + configs_dict["profiling"] = False + if configs_dict.get("benchmarking", None) is None: + configs_dict["benchmarking"] = False + if configs_dict.get("inference_debugging", None) is None: + configs_dict["inference_debugging"] = False + if configs_dict.get("fusion", None) is None: + configs_dict["fusion"] = True + + init_flexflow_runtime(configs_dict) diff --git a/python/flexflow/serve/models/__init__.py b/python/flexflow/serve/models/__init__.py new file mode 100644 index 0000000000..7b0e632f53 --- /dev/null +++ b/python/flexflow/serve/models/__init__.py @@ -0,0 +1,19 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from .llama import FlexFlowLLAMA, LLAMAConfig +from .opt import FlexFlowOPT, OPTConfig +from .falcon import FlexFlowFalcon, FalconConfig +from .starcoder import FlexFlowSTARCODER, STARCODERConfig +from .mpt import FlexFlowMPT, MPTConfig diff --git a/python/flexflow/serve/models/base.py b/python/flexflow/serve/models/base.py new file mode 100644 index 0000000000..e7f3914037 --- /dev/null +++ b/python/flexflow/serve/models/base.py @@ -0,0 +1,36 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +class FlexFlowModel: + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + # max_tokens_per_batch=64, + weights_filepath="", + tokenizer_filepath="", + ): + self.build_model() + + def build_model(self): + assert False, "Not implemented yet" + + def convert_hf_model(model, dst_folder): + assert False, "Not implemented yet" diff --git a/python/flexflow/serve/models/falcon.py b/python/flexflow/serve/models/falcon.py new file mode 100644 index 0000000000..7a55da26ef --- /dev/null +++ b/python/flexflow/serve/models/falcon.py @@ -0,0 +1,282 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.core import * +from .base import FlexFlowModel +import random, torch + + +class FalconConfig: + def __init__(self, hf_config): + # self.max_seq_len = 256 + # self.max_num_tokens = 64 + self.max_beam_width = 1 + self.max_beam_depth = 8 + self.max_spec_tree_token_num = 20 + self.bias = hf_config.bias + self.hidden_size = hf_config.hidden_size + self.layer_norm_epsilon = hf_config.layer_norm_epsilon + self.multi_query = hf_config.multi_query + self.n_head = ( + hf_config.n_head + if "n_head" in hf_config.__dict__ + else hf_config.num_attention_heads + ) + self.n_head_kv = hf_config.n_head_kv if "n_head_kv" in hf_config.__dict__ else 1 + self.n_layer = ( + hf_config.n_layer + if "n_layer" in hf_config.__dict__ + else hf_config.num_hidden_layers + ) + self.parallel_attn = hf_config.parallel_attn + self.vocab_size = hf_config.vocab_size + # Standardized FlexFlow num heads fields below + self.num_attention_heads = self.n_head + self.num_key_value_heads = self.n_head_kv + + +class FlexFlowFalcon(FlexFlowModel): + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + max_tokens_per_batch, + weights_filepath="", + tokenizer_filepath="", + ): + self.mode = mode + self.generation_config = generation_config + self.ffconfig = ffconfig + # self.max_batch_size = max_batch_size + self.data_type = data_type + self.falcon_config = FalconConfig(hf_config) + # self.falcon_config.max_seq_length = max_seq_length + # self.falcon_config.max_num_tokens = max_tokens_per_batch + self.weights_filepath = weights_filepath + self.tokenizer_filepath = tokenizer_filepath + self.maxint = 2**31 - 1 + max_verify_tokens_per_batch = ( + max_tokens_per_batch + self.falcon_config.max_spec_tree_token_num + ) + + # Sanity checks + if self.falcon_config.hidden_size % self.falcon_config.n_head != 0: + raise ValueError( + f"Hidden size ({self.falcon_config.hidden_size}) is not divisible by n_head ({self.falcon_config.n_head})" + ) + if ( + self.falcon_config.n_head < self.ffconfig.tensor_parallelism_degree + or self.falcon_config.n_head % self.ffconfig.tensor_parallelism_degree != 0 + ): + raise ValueError( + f"Number of q attention heads ({self.falcon_config.n_head}) is smaller, or not divisible by tensor parallelism degree ({self.ffconfig.tensor_parallelism_degree})" + ) + + self.build_model( + max_tokens_per_batch + if self.mode == InferenceMode.INC_DECODING_MODE + else max_verify_tokens_per_batch + ) + + def build_model(self, max_tokens_per_batch): + ffmodel = FFModel(self.ffconfig) + + tokens_dims = [max_tokens_per_batch, 1] + input_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + + embed_init = UniformInitializer(random.randint(0, self.maxint), 0, 0) + token = ffmodel.embedding( + input_tensor, + self.falcon_config.vocab_size, + self.falcon_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="word_embeddings", + ) + axes = [ + 0, + ] + + for i in range(self.falcon_config.n_layer): + ffmodel.set_transformer_layer_id(i) + + if i == 0: + att_norm = ffmodel.layer_norm( + token, + axes, + True, + self.falcon_config.layer_norm_epsilon, + name=f"layers_{i}_input_layernorm", + ) + else: + token, att_norm = ffmodel.residual_layer_norm( + token, + mha, + mlp_output, + True, + axes, + True, + self.falcon_config.layer_norm_epsilon, + name=f"layers_{i}_input_layernorm", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + mha = ffmodel.spec_inc_multiquery_self_attention( + att_norm, + self.falcon_config.hidden_size, + self.falcon_config.n_head, + self.falcon_config.n_head_kv, + self.falcon_config.hidden_size // self.falcon_config.n_head, + self.falcon_config.hidden_size // self.falcon_config.n_head, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.TREE_VERIFY_MODE: + mha = ffmodel.inc_multiquery_self_attention_verify( + att_norm, + self.falcon_config.hidden_size, + self.falcon_config.n_head, + self.falcon_config.n_head_kv, + self.falcon_config.hidden_size // self.falcon_config.n_head, + self.falcon_config.hidden_size // self.falcon_config.n_head, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.INC_DECODING_MODE: + mha = ffmodel.inc_multiquery_self_attention( + att_norm, + self.falcon_config.hidden_size, + self.falcon_config.n_head, + self.falcon_config.n_head_kv, + self.falcon_config.hidden_size // self.falcon_config.n_head, + self.falcon_config.hidden_size // self.falcon_config.n_head, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + else: + assert False + + dense_h_to_4h = ffmodel.dense( + att_norm, + self.falcon_config.hidden_size * 4, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_mlp_dense_h_to_4h", + ) + dense_h_to_4h = ffmodel.gelu(dense_h_to_4h) + mlp_output = ffmodel.dense( + dense_h_to_4h, + self.falcon_config.hidden_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_mlp_dense_4h_to_h", + ) + + _, ln_f = ffmodel.residual_layer_norm( + token, + mha, + mlp_output, + True, + axes, + True, + self.falcon_config.layer_norm_epsilon, + name="ln_f", + ) + lm_head = ffmodel.dense( + ln_f, + self.falcon_config.vocab_size, + ActiMode.AC_MODE_NONE, + False, + name="lm_head", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + softmax = ffmodel.softmax(lm_head, -1) + # output = ffmodel.beam_top_k(softmax, self.falcon_config.max_beam_width, False) + output = ffmodel.argmax(softmax, True) + else: + if self.generation_config.do_sample: + dense = ffmodel.scalar_true_divide( + lm_head, self.generation_config.temperature, False + ) + softmax = ffmodel.softmax(dense, -1) + output = ffmodel.sampling(softmax, self.generation_config.topp) + else: + # output = ffmodel.arg_top_k(lm_head, 1, False) + output = ffmodel.argmax(lm_head, False) + + self.ffmodel = ffmodel + + def convert_hf_model(model, dst_folder): + os.makedirs(dst_folder, exist_ok=True) + n_head = ( + model.config.n_head + if "n_head" in model.config.__dict__ + else model.config.num_attention_heads + ) + for name, params in model.named_parameters(): + name = ( + name.replace(".", "_") + .replace("transformer_h_", "layers_") + .replace("transformer_", "") + .replace("self_attention_dense", "attention_wo") + ) + # Split Q,K,V attention weights + if "self_attention_query_key_value" in name: + name_q = name.replace("self_attention_query_key_value", "attention_wq") + name_k = name.replace("self_attention_query_key_value", "attention_wk") + name_v = name.replace("self_attention_query_key_value", "attention_wv") + q, k, v = torch.split( + params, + [ + model.config.hidden_size, + model.config.hidden_size // n_head, + model.config.hidden_size // n_head, + ], + 0, + ) + q.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_q)) + k.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_k)) + v.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_v)) + else: + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + # LM head weight + model.lm_head.weight.detach().cpu().numpy().tofile( + os.path.join(dst_folder, "lm_head_weight") + ) diff --git a/python/flexflow/serve/models/llama.py b/python/flexflow/serve/models/llama.py new file mode 100644 index 0000000000..6b33030f62 --- /dev/null +++ b/python/flexflow/serve/models/llama.py @@ -0,0 +1,273 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.core import * +from .base import FlexFlowModel +import random + + +class LLAMAConfig: + def __init__(self, hf_config): + # self.max_seq_len = 256 + # self.max_num_tokens = 64 + self.max_beam_width = 1 + self.max_beam_depth = 8 + self.max_spec_tree_token_num = 20 + self.num_hidden_layers = hf_config.num_hidden_layers + self.vocab_size = hf_config.vocab_size + self.hidden_size = hf_config.hidden_size + self.rms_norm_eps = hf_config.rms_norm_eps + self.intermediate_size = hf_config.intermediate_size + # Standardized FlexFlow num heads fields below + self.num_attention_heads = hf_config.num_attention_heads + self.num_key_value_heads = ( + hf_config.num_attention_heads + if hf_config.num_key_value_heads is None + else hf_config.num_key_value_heads + ) + + +class FlexFlowLLAMA(FlexFlowModel): + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + max_tokens_per_batch, + weights_filepath="", + tokenizer_filepath="", + ): + self.mode = mode + self.generation_config = generation_config + self.ffconfig = ffconfig + # self.max_batch_size = max_batch_size + self.data_type = data_type + self.llama_config = LLAMAConfig(hf_config) + # self.llama_config.max_seq_length = max_seq_length + # self.llama_config.max_num_tokens = max_tokens_per_batch + self.weights_filepath = weights_filepath + self.tokenizer_filepath = tokenizer_filepath + self.maxint = 2**31 - 1 + max_verify_tokens_per_batch = ( + max_tokens_per_batch + self.llama_config.max_spec_tree_token_num + ) + + # Sanity checks + if self.llama_config.hidden_size % self.llama_config.num_attention_heads != 0: + raise ValueError( + f"Hidden size ({self.llama_config.hidden_size}) is not divisible by number of attention heads ({self.llama_config.num_attention_heads})" + ) + + # Sanity checks + if ( + self.llama_config.num_attention_heads + < self.ffconfig.tensor_parallelism_degree + or self.llama_config.num_attention_heads + % self.ffconfig.tensor_parallelism_degree + != 0 + ): + raise ValueError( + f"Number of attention heads ({self.llama_config.num_attention_heads}) is smaller, or not divisible by tensor parallelism degree ({self.ffconfig.tensor_parallelism_degree})" + ) + + self.build_model( + max_tokens_per_batch + if self.mode == InferenceMode.INC_DECODING_MODE + else max_verify_tokens_per_batch + ) + + def build_model(self, max_tokens_per_batch): + ffmodel = FFModel(self.ffconfig) + + tokens_dims = [max_tokens_per_batch, 1] + input_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + + embed_init = UniformInitializer(random.randint(0, self.maxint), 0, 0) + token = ffmodel.embedding( + input_tensor, + self.llama_config.vocab_size, + self.llama_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="tok_embeddings", + ) + + for i in range(self.llama_config.num_hidden_layers): + ffmodel.set_transformer_layer_id(i) + + if i == 0: + attn_norm = ffmodel.rms_norm( + token, + self.llama_config.rms_norm_eps, + self.llama_config.hidden_size, + name=f"layers_{i}_attention_norm", + ) + else: + token, attn_norm = ffmodel.residual_rms_norm( + token, + w2, + self.llama_config.rms_norm_eps, + self.llama_config.hidden_size, + name=f"layers_{i}_attention_norm", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + mha = ffmodel.spec_inc_multiquery_self_attention( + attn_norm, + self.llama_config.hidden_size, + self.llama_config.num_attention_heads, + self.llama_config.num_key_value_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.TREE_VERIFY_MODE: + mha = ffmodel.inc_multiquery_self_attention_verify( + attn_norm, + self.llama_config.hidden_size, + self.llama_config.num_attention_heads, + self.llama_config.num_key_value_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.INC_DECODING_MODE: + mha = ffmodel.inc_multiquery_self_attention( + attn_norm, + self.llama_config.hidden_size, + self.llama_config.num_attention_heads, + self.llama_config.num_key_value_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + self.llama_config.hidden_size + // self.llama_config.num_attention_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + True, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + else: + assert False + + token, ff_norm = ffmodel.residual_rms_norm( + token, + mha, + self.llama_config.rms_norm_eps, + self.llama_config.hidden_size, + name=f"layers_{i}_ffn_norm", + ) + w1 = ffmodel.dense( + ff_norm, + self.llama_config.intermediate_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_feed_forward_w1", + ) + w3 = ffmodel.dense( + ff_norm, + self.llama_config.intermediate_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_feed_forward_w3", + ) + multi = ffmodel.sigmoid_silu_multi(w1, w3) + w2 = ffmodel.dense( + multi, + self.llama_config.hidden_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_feed_forward_w2", + ) + + _, token = ffmodel.residual_rms_norm( + token, + w2, + self.llama_config.rms_norm_eps, + self.llama_config.hidden_size, + name="norm", + ) + dense = ffmodel.dense( + token, + self.llama_config.vocab_size, + ActiMode.AC_MODE_NONE, + False, + name="output", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + softmax = ffmodel.softmax(dense, -1) + # output = ffmodel.beam_top_k(softmax, self.llama_config.max_beam_width, False) + output = ffmodel.argmax(softmax, True) + else: + if self.generation_config.do_sample: + dense = ffmodel.scalar_true_divide( + dense, self.generation_config.temperature, False + ) + softmax = ffmodel.softmax(dense, -1) + output = ffmodel.sampling(softmax, self.generation_config.topp) + else: + # output = ffmodel.arg_top_k(dense, 1, False) + output = ffmodel.argmax(dense, False) + + self.ffmodel = ffmodel + + def convert_hf_model(model, dst_folder): + os.makedirs(dst_folder, exist_ok=True) + for name, params in model.named_parameters(): + name = ( + name.replace(".", "_") + .replace("self_attn", "attention") + .replace("q_proj", "wq") + .replace("k_proj", "wk") + .replace("v_proj", "wv") + .replace("o_proj", "wo") + .replace("mlp", "feed_forward") + .replace("gate_proj", "w1") + .replace("down_proj", "w2") + .replace("up_proj", "w3") + .replace("input_layernorm", "attention_norm") + .replace("post_attention_layernorm", "ffn_norm") + .replace("embed_tokens", "tok_embeddings") + .replace("lm_head", "output") + .replace("model_", "") + ) + params.detach().cpu().numpy().tofile(f"{dst_folder}/{name}") diff --git a/python/flexflow/serve/models/mpt.py b/python/flexflow/serve/models/mpt.py new file mode 100644 index 0000000000..92867fd498 --- /dev/null +++ b/python/flexflow/serve/models/mpt.py @@ -0,0 +1,285 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.core import * +from .base import FlexFlowModel +import random, torch, shutil + + +class MPTConfig: + def __init__(self, hf_config): + # self.max_seq_len = 256 + # self.max_num_tokens = 64 + self.max_beam_width = 1 + self.max_beam_depth = 8 + self.max_spec_tree_token_num = 20 + self.hidden_size = hf_config.d_model + self.n_heads = hf_config.n_heads + self.n_layers = hf_config.n_layers + self.vocab_size = hf_config.vocab_size + # Standardized FlexFlow num heads fields below + self.num_attention_heads = hf_config.n_heads + self.num_key_value_heads = hf_config.n_heads + + +class FlexFlowMPT(FlexFlowModel): + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + max_tokens_per_batch, + weights_filepath="", + tokenizer_filepath="", + ): + self.mode = mode + self.generation_config = generation_config + self.ffconfig = ffconfig + # self.max_batch_size = max_batch_size + self.data_type = data_type + self.mpt_config = MPTConfig(hf_config) + # self.mpt_config.max_seq_length = max_seq_length + # self.mpt_config.max_num_tokens = max_tokens_per_batch + self.weights_filepath = weights_filepath + self.tokenizer_filepath = tokenizer_filepath + self.maxint = 2**31 - 1 + max_verify_tokens_per_batch = ( + max_tokens_per_batch + self.mpt_config.max_spec_tree_token_num + ) + + # Sanity checks + if self.mpt_config.hidden_size % self.mpt_config.n_heads != 0: + raise ValueError( + f"Hidden size ({self.mpt_config.hidden_size}) is not divisible by n_head ({self.mpt_config.n_heads})" + ) + + # Sanity checks + if ( + self.mpt_config.n_heads < self.ffconfig.tensor_parallelism_degree + or self.mpt_config.n_heads % self.ffconfig.tensor_parallelism_degree != 0 + ): + raise ValueError( + f"Number of attention heads ({self.mpt_config.n_heads}) is smaller, or not divisible by tensor parallelism degree ({self.ffconfig.tensor_parallelism_degree})" + ) + self.build_model( + max_tokens_per_batch + if self.mode == InferenceMode.INC_DECODING_MODE + else max_verify_tokens_per_batch + ) + + def build_model(self, max_tokens_per_batch): + ffmodel = FFModel(self.ffconfig) + + tokens_dims = [max_tokens_per_batch, 1] + input = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + + embed_init = UniformInitializer(random.randint(0, self.maxint), 0, 0) + hidden_states = ffmodel.embedding( + input, + self.mpt_config.vocab_size, + self.mpt_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="transformer_wte", + ) + + axes = [ + 0, + ] + + for i in range(self.mpt_config.n_layers): + ffmodel.set_transformer_layer_id(i) + + if i == 0: + layernorm_output = ffmodel.layer_norm( + hidden_states, + axes, + True, + 1e-05, + False, + name=f"layers_{i}_norm_1", + ) + else: + hidden_states, layernorm_output = ffmodel.residual_layer_norm( + intermediate_output, + hidden_states, + None, + False, + axes, + True, + 1e-05, + False, + name=f"layers_{i}_norm_1", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + attn_outputs = ffmodel.spec_inc_multihead_self_attention( + layernorm_output, + self.mpt_config.hidden_size, + self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.mpt_config.hidden_size / self.mpt_config.n_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + True, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.TREE_VERIFY_MODE: + attn_outputs = ffmodel.inc_multihead_self_attention_verify( + layernorm_output, + self.mpt_config.hidden_size, + self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.mpt_config.hidden_size / self.mpt_config.n_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + True, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.INC_DECODING_MODE: + attn_outputs = ffmodel.inc_multihead_self_attention( + layernorm_output, + self.mpt_config.hidden_size, + self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + self.mpt_config.hidden_size // self.mpt_config.n_heads, + 0.0, # dropout + False, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.mpt_config.hidden_size / self.mpt_config.n_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + True, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + else: + assert False + + hidden_states, layernorm_output = ffmodel.residual_layer_norm( + attn_outputs, + hidden_states, + None, + False, + axes, + True, + 1e-05, + False, + name=f"layers_{i}_norm_2", + ) + # mlp + layernorm_output = ffmodel.dense( + layernorm_output, + 4 * self.mpt_config.hidden_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_ffn_up_proj", + ) + layernorm_output = ffmodel.gelu(layernorm_output) + intermediate_output = ffmodel.dense( + layernorm_output, + self.mpt_config.hidden_size, + ActiMode.AC_MODE_NONE, + False, + name=f"layers_{i}_ffn_down_proj", + ) + + _, all_final_norm = ffmodel.residual_layer_norm( + intermediate_output, + hidden_states, + None, + False, + axes, + True, + 1e-05, + False, + name=f"transformer_norm_f", + ) + lm_head = ffmodel.dense( + all_final_norm, + self.mpt_config.vocab_size, + ActiMode.AC_MODE_NONE, + False, + name="lm_head", + ) + + if self.generation_config.do_sample: + dense = ffmodel.scalar_true_divide( + lm_head, self.generation_config.temperature, False + ) + softmax = ffmodel.softmax(dense, -1) + output = ffmodel.sampling(softmax, self.generation_config.topp) + else: + output = ffmodel.argmax(lm_head, False) + + self.ffmodel = ffmodel + + def convert_hf_model(model, dst_folder): + os.makedirs(dst_folder, exist_ok=True) + for name, params in model.named_parameters(): + name = name.replace("transformer.blocks.", "layers.").replace(".", "_") + if "Wqkv" in name: + name_q = name.replace("attn_Wqkv", "attention_wq") + name_k = name.replace("attn_Wqkv", "attention_wk") + name_v = name.replace("attn_Wqkv", "attention_wv") + q, k, v = torch.split( + params, + [ + model.config.d_model, + model.config.d_model, + model.config.d_model, + ], + 0, + ) + q.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_q)) + k.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_k)) + v.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_v)) + elif "out_proj" in name: + name = name.replace("attn_out_proj", "attention_wo") + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + else: + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + + shutil.copy( + os.path.join(dst_folder, "transformer_wte_weight"), + os.path.join(dst_folder, "lm_head_weight"), + ) diff --git a/python/flexflow/serve/models/opt.py b/python/flexflow/serve/models/opt.py new file mode 100644 index 0000000000..b715f5f35e --- /dev/null +++ b/python/flexflow/serve/models/opt.py @@ -0,0 +1,308 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.core import * +from .base import FlexFlowModel +import random, shutil + + +class OPTConfig: + def __init__(self, hf_config): + # self.max_seq_len = 256 + # self.max_num_tokens = 64 + self.max_beam_width = 1 + self.max_beam_depth = 8 + self.max_spec_tree_token_num = 20 + self.do_layer_norm_before = hf_config.do_layer_norm_before + self.dropout = hf_config.dropout + self.enable_bias = hf_config.enable_bias + self.ffn_dim = hf_config.ffn_dim + self.hidden_size = hf_config.hidden_size + self.layer_norm_elementwise_affine = hf_config.layer_norm_elementwise_affine + self.max_position_embeddings = hf_config.max_position_embeddings + self.num_hidden_layers = hf_config.num_hidden_layers + self.vocab_size = hf_config.vocab_size + self.word_embed_proj_dim = hf_config.word_embed_proj_dim + # Standardized FlexFlow num heads fields below + self.num_attention_heads = hf_config.num_attention_heads + self.num_key_value_heads = hf_config.num_attention_heads + + +class FlexFlowOPT(FlexFlowModel): + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + max_tokens_per_batch, + weights_filepath="", + tokenizer_filepath="", + ): + self.mode = mode + self.generation_config = generation_config + self.ffconfig = ffconfig + # self.max_batch_size = max_batch_size + self.data_type = data_type + self.opt_config = OPTConfig(hf_config) + # self.opt_config.max_seq_length = max_seq_length + # self.opt_config.max_num_tokens = max_tokens_per_batch + self.weights_filepath = weights_filepath + self.tokenizer_filepath = tokenizer_filepath + self.maxint = 2**31 - 1 + max_verify_tokens_per_batch = ( + max_tokens_per_batch + self.opt_config.max_spec_tree_token_num + ) + + # Sanity checks + if self.opt_config.hidden_size % self.opt_config.num_attention_heads != 0: + raise ValueError( + f"Hidden size ({self.opt_config.hidden_size}) is not divisible by n_head ({self.opt_config.num_attention_heads})" + ) + + # Sanity checks + if ( + self.opt_config.num_attention_heads + < self.ffconfig.tensor_parallelism_degree + or self.opt_config.num_attention_heads + % self.ffconfig.tensor_parallelism_degree + != 0 + ): + raise ValueError( + f"Number of attention heads ({self.opt_config.num_attention_heads}) is smaller, or not divisible by tensor parallelism degree ({self.ffconfig.tensor_parallelism_degree})" + ) + + self.build_model( + max_tokens_per_batch + if self.mode == InferenceMode.INC_DECODING_MODE + else max_verify_tokens_per_batch + ) + + def build_model(self, max_tokens_per_batch): + ffmodel = FFModel(self.ffconfig) + + tokens_dims = [max_tokens_per_batch, 1] + input_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + position_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + + # OPT model positional embedding start offset is 2 + ffmodel.set_position_offset(2) + embed_init = UniformInitializer(random.randint(0, self.maxint), 0, 0) + token = ffmodel.embedding( + input_tensor, + self.opt_config.vocab_size, + self.opt_config.word_embed_proj_dim, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="embed_tokens", + ) + positional_embedding = ffmodel.embedding( + position_tensor, + self.opt_config.max_position_embeddings, + self.opt_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="embed_positions", + ) + + axes = [ + 0, + ] + + for i in range(self.opt_config.num_hidden_layers): + ffmodel.set_transformer_layer_id(i) + + if self.opt_config.do_layer_norm_before: + residual, hidden_states = ffmodel.residual_layer_norm( + token if i == 0 else residual, + positional_embedding if i == 0 else fc2, + None, + False, + axes, + self.opt_config.layer_norm_elementwise_affine, + 1e-05, + name=f"layers_{i}_attention_layer_norm", + ) + else: + hidden_states = ffmodel.add(token, positional_embedding) + residual = hidden_states + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + mha = ffmodel.spec_inc_multihead_self_attention( + hidden_states, + self.opt_config.hidden_size, + self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + 0.0, # dropout + True, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.opt_config.hidden_size / self.opt_config.num_attention_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.TREE_VERIFY_MODE: + mha = ffmodel.inc_multihead_self_attention_verify( + hidden_states, + self.opt_config.hidden_size, + self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + 0.0, # dropout + True, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.opt_config.hidden_size / self.opt_config.num_attention_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + elif self.mode == InferenceMode.INC_DECODING_MODE: + mha = ffmodel.inc_multihead_self_attention( + hidden_states, + self.opt_config.hidden_size, + self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + self.opt_config.hidden_size // self.opt_config.num_attention_heads, + 0.0, # dropout + True, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + True, # scaling_query + (self.opt_config.hidden_size / self.opt_config.num_attention_heads) + ** (-0.5), # scaling_factor + False, # qk_prod_scaling + name=f"layers_{i}_attention", + ) + else: + assert False + + # This is either a before or after attention LayerNorm. In both cases, we need to compute the LN here. + residual, ff_norm = ffmodel.add_bias_residual_layer_norm( + mha, + residual, + axes, + self.opt_config.layer_norm_elementwise_affine, + 1e-05, + name=f"layers_{i}_add_bias_residual_layer_norm", + ) + + if not self.opt_config.do_layer_norm_before: + residual = ff_norm + + fc1 = ffmodel.dense( + ff_norm, + self.opt_config.ffn_dim, + ActiMode.AC_MODE_RELU, + True, + name=f"layers_{i}_fc1", + ) + fc2 = ffmodel.dense( + fc1, + self.opt_config.hidden_size, + ActiMode.AC_MODE_NONE, + True, + name=f"layers_{i}_fc2", + ) + + if not self.opt_config.do_layer_norm_before: + _, residual = ffmodel.residual_layer_norm( + residual, + fc2, + None, + False, + axes, + self.opt_config.layer_norm_elementwise_affine, + 1e-05, + name=f"layers_{i}_final_layer_norm", + ) + + _, all_final_norm = ffmodel.residual_layer_norm( + residual, + fc2, + None, + False, + axes, + self.opt_config.layer_norm_elementwise_affine, + 1e-05, + name=f"final_layer_norm", + ) + lm_head = ffmodel.dense( + all_final_norm, + self.opt_config.vocab_size, + ActiMode.AC_MODE_NONE, + False, + name="embed_tokens_weight_lm_head", + ) + + if self.mode == InferenceMode.BEAM_SEARCH_MODE: + softmax = ffmodel.softmax(lm_head, -1) + # output = ffmodel.beam_top_k(softmax, self.opt_config.max_beam_width, False) + output = ffmodel.argmax(softmax, True) + else: + if self.generation_config.do_sample: + dense = ffmodel.scalar_true_divide( + lm_head, self.generation_config.temperature, False + ) + softmax = ffmodel.softmax(dense, -1) + output = ffmodel.sampling(softmax, self.generation_config.topp) + else: + # output = ffmodel.arg_top_k(lm_head, 1, False) + output = ffmodel.argmax(lm_head, False) + + self.ffmodel = ffmodel + + def convert_hf_model(model, dst_folder): + os.makedirs(dst_folder, exist_ok=True) + for name, params in model.named_parameters(): + name = ( + name.replace(".", "_") + .replace("decoder_", "") + .replace("model_", "") + .replace("self_attn", "attention") + .replace("q_proj", "wq") + .replace("k_proj", "wk") + .replace("v_proj", "wv") + .replace("out_proj", "wo") + .replace("attention_wo_bias", "add_bias_residual_layer_norm_attn_bias") + .replace( + "_final_layer_norm", "_add_bias_residual_layer_norm" + ) # important to use the leading "_" to avoid matching the last LayerNorm + ) + params.detach().cpu().numpy().tofile(f"{dst_folder}/{name}") + # copy embedding weights + shutil.copy( + os.path.join(dst_folder, "embed_tokens_weight"), + os.path.join(dst_folder, "embed_tokens_weight_lm_head"), + ) diff --git a/python/flexflow/serve/models/starcoder.py b/python/flexflow/serve/models/starcoder.py new file mode 100644 index 0000000000..37edaa4c40 --- /dev/null +++ b/python/flexflow/serve/models/starcoder.py @@ -0,0 +1,270 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.core import * +from .base import FlexFlowModel +import random, torch + + +class STARCODERConfig: + def __init__(self, hf_config): + # self.max_seq_len = 256 + # self.max_num_tokens = 64 + self.max_beam_width = 1 + self.max_beam_depth = 8 + self.max_spec_tree_token_num = 20 + self.dropout_p = hf_config.attn_pdrop + self.hidden_size = hf_config.n_embd + self.layer_norm_epsilon = hf_config.layer_norm_epsilon + self.max_position_embeddings = hf_config.n_positions + self.num_hidden_layers = hf_config.n_layer + self.vocab_size = hf_config.vocab_size + self.intermediate_size = hf_config.n_inner + self.n_head_kv = 1 if hf_config.multi_query else hf_config.n_head + # Standardized FlexFlow num heads fields below + self.num_attention_heads = hf_config.n_head + self.num_key_value_heads = self.n_head_kv + + +class FlexFlowSTARCODER(FlexFlowModel): + def __init__( + self, + mode, + generation_config, + ffconfig, + hf_config, + data_type, + # max_batch_size=1, + # max_seq_length=256, + max_tokens_per_batch, + weights_filepath="", + tokenizer_filepath="", + ): + self.mode = mode + self.generation_config = generation_config + self.ffconfig = ffconfig + # self.max_batch_size = max_batch_size + self.data_type = data_type + self.starcoder_config = STARCODERConfig(hf_config) + # self.starcoder_config.max_seq_length = max_seq_length + # self.starcoder_config.max_num_tokens = max_tokens_per_batch + self.weights_filepath = weights_filepath + self.tokenizer_filepath = tokenizer_filepath + self.maxint = 2**31 - 1 + max_verify_tokens_per_batch = ( + max_tokens_per_batch + self.starcoder_config.max_spec_tree_token_num + ) + + # Sanity checks + if ( + self.starcoder_config.hidden_size + % self.starcoder_config.num_attention_heads + != 0 + ): + raise ValueError( + f"Hidden size ({self.starcoder_config.hidden_size}) is not divisible by n_head ({self.starcoder_config.num_attention_heads})" + ) + + # Sanity checks + if ( + self.starcoder_config.num_attention_heads + < self.ffconfig.tensor_parallelism_degree + or self.starcoder_config.num_attention_heads + % self.ffconfig.tensor_parallelism_degree + != 0 + ): + raise ValueError( + f"Number of attention heads ({self.starcoder_config.num_attention_heads}) is smaller, or not divisible by tensor parallelism degree ({self.ffconfig.tensor_parallelism_degree})" + ) + + self.build_model( + max_tokens_per_batch + if self.mode == InferenceMode.INC_DECODING_MODE + else max_verify_tokens_per_batch + ) + + def build_model(self, max_tokens_per_batch): + ffmodel = FFModel(self.ffconfig) + + tokens_dims = [max_tokens_per_batch, 1] + input_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + position_tensor = ffmodel.create_tensor(tokens_dims, DataType.DT_INT32) + + embed_init = UniformInitializer(random.randint(0, self.maxint), 0, 0) + ffmodel.set_position_offset(0) + token = ffmodel.embedding( + input_tensor, + self.starcoder_config.vocab_size, + self.starcoder_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="transformer_wte", + ) + positional_embedding = ffmodel.embedding( + position_tensor, + self.starcoder_config.max_position_embeddings, + self.starcoder_config.hidden_size, + AggrMode.AGGR_MODE_NONE, + self.data_type, + None, + embed_init, + name="transformer_wpe", + ) + + axes = [ + 0, + ] + + for i in range(self.starcoder_config.num_hidden_layers): + ffmodel.set_transformer_layer_id(i) + + hidden_states, ln_1 = ffmodel.residual_layer_norm( + token if i == 0 else residual, + positional_embedding if i == 0 else c_proj, + None, + False, + axes, + True, + self.starcoder_config.layer_norm_epsilon, + name=f"layers_{i}_ln_1", + ) + + assert self.mode == InferenceMode.INC_DECODING_MODE + mha = ffmodel.inc_multiquery_self_attention( + ln_1, + self.starcoder_config.hidden_size, + self.starcoder_config.num_attention_heads, + self.starcoder_config.n_head_kv, + self.starcoder_config.hidden_size + // self.starcoder_config.num_attention_heads, + self.starcoder_config.hidden_size + // self.starcoder_config.num_attention_heads, + 0.0, # dropout + True, # qkv_bias + False, # final_bias + False, # add_zero_attn + DataType.DT_NONE, # data_type + None, # kernel initializer + False, # apply_rotary_embedding + name=f"layers_{i}_attention", + ) + + residual, l2_norm = ffmodel.residual_layer_norm( + hidden_states, + mha, + None, + False, + residual, + axes, + True, + self.starcoder_config.layer_norm_epsilon, + name=f"layers_{i}_ln_2", + ) + + # mlp + + c_fc = ffmodel.dense( + l2_norm, + self.starcoder_config.intermediate_size, + ActiMode.AC_MODE_NONE, + True, + name=f"layers_{i}_mlp_c_fc", + ) + activation = ffmodel.gelu(c_fc, False) + c_proj = ffmodel.dense( + activation, + self.starcoder_config.hidden_size, + ActiMode.AC_MODE_NONE, + True, + name=f"layers_{i}_mlp_c_proj", + ) + + _, ln_f = ffmodel.residual_layer_norm( + residual, + c_proj, + None, + False, + axes, + True, + self.starcoder_config.layer_norm_epsilon, + name=f"transformer_ln_f", + ) + lm_head = ffmodel.dense( + ln_f, + self.starcoder_config.vocab_size, + ActiMode.AC_MODE_NONE, + False, + name="lm_head", + ) + + if self.generation_config.do_sample: + dense = ffmodel.scalar_true_divide( + lm_head, self.generation_config.temperature, False + ) + softmax = ffmodel.softmax(dense, -1) + output = ffmodel.sampling(softmax, self.generation_config.topp) + else: + output = ffmodel.argmax(lm_head, False) + + self.ffmodel = ffmodel + + def convert_hf_model(model, dst_folder): + os.makedirs(dst_folder, exist_ok=True) + for name, params in model.named_parameters(): + name = name.replace("transformer.h", "layers").replace(".", "_") + if "c_attn_weight" in name: + name_q = name.replace("attn_c_attn", "attention_wq") + name_k = name.replace("attn_c_attn", "attention_wk") + name_v = name.replace("attn_c_attn", "attention_wv") + q, k, v = torch.split( + params, + [ + model.config.hidden_size, + model.config.hidden_size // model.config.num_attention_heads, + model.config.hidden_size // model.config.num_attention_heads, + ], + 0, + ) + q.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_q)) + k.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_k)) + v.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_v)) + elif "c_attn_bias" in name: + name_q = name.replace("attn_c_attn", "attention_wq") + name_k = name.replace("attn_c_attn", "attention_wk") + name_v = name.replace("attn_c_attn", "attention_wv") + q, k, v = torch.split( + params, + [ + model.config.hidden_size, + model.config.hidden_size // model.config.num_attention_heads, + model.config.hidden_size // model.config.num_attention_heads, + ], + 0, + ) + q.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_q)) + k.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_k)) + v.detach().cpu().numpy().tofile(os.path.join(dst_folder, name_v)) + elif "c_proj_bias" in name: + name = name.replace("attn_c_proj", "attention_wo") + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + elif "c_proj_weight" in name: + name = name.replace("attn_c_proj", "attention_wo") + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + else: + params.detach().cpu().numpy().tofile(os.path.join(dst_folder, name)) + model.lm_head.weight.detach().cpu().numpy().tofile( + os.path.join(dst_folder, "lm_head_weight") + ) diff --git a/python/flexflow/serve/serve.py b/python/flexflow/serve/serve.py new file mode 100644 index 0000000000..ac622b3337 --- /dev/null +++ b/python/flexflow/serve/serve.py @@ -0,0 +1,534 @@ +# Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from flexflow.serve.models import ( + FlexFlowLLAMA, + FlexFlowOPT, + FlexFlowFalcon, + FlexFlowSTARCODER, + FlexFlowMPT, +) +from flexflow.serve.models import ( + LLAMAConfig, + OPTConfig, + FalconConfig, + STARCODERConfig, + MPTConfig, +) +from flexflow.core import * +from transformers import AutoConfig, AutoModelForCausalLM, AutoTokenizer, LlamaTokenizer +from huggingface_hub import HfApi +import sys, torch, shutil, hashlib +from typing import Union, List + + +class GenerationConfig: + """A class to store the sampling configs.""" + + def __init__( + self, + do_sample: bool = False, + temperature: float = 0.9, + topp: float = 0.8, + topk: int = 1, + ): + """Initialize the sampling configs + + :param do_sample: Whether to perform sampling, or use greedy decoding, defaults to False + :type do_sample: bool, optional + :param temperature: The temperature setting, defaults to 0.9 + :type temperature: float, optional + :param topp: The top probabilities (top-p) setting, defaults to 0.8 + :type topp: float, optional + :param topk: The top-k setting, defaults to 1 + :type topk: int, optional + """ + self.do_sample = do_sample + self.temperature = temperature + self.topp = topp + self.topk = topk + + +class GenerationResult: + """A class to store the output of a generation request.""" + + def __init__(self, text: str = None, tokens: list = None): + self.output_text = text + self.output_tokens = tokens + + +class LLM: + """This class creates a LLM (Large-Language Model) object based on a model from HuggingFace""" + + def __init__( + self, + model_name: str, + data_type: DataType = DataType.DT_HALF, + cache_path: str = "", + refresh_cache: bool = False, + output_file: str = "", + ): + """Create the LLM object + + :param model_name: The name of the HuggingFace model to use. E.g. 'meta-llama/Llama-2-7b-hf' + :type model_name: str + :param data_type: The data type to use for the tensors (e.g. DataType.DT_FLOAT for full precision, or DataType.DT_HALF for half precision), defaults to DataType.DT_HALF + :type data_type: DataType, optional + :param cache_path: Path to the folder (which will be created if it does not yet exist) to use for the FlexFlow weights/tokenizers cache, defaults to "~/.cache/flexflow" + :type tokenizer_path: str, optional + :param refresh_cache: Use this flag to force the refresh of the model's weights/tokenizer cache, defaults to False + :type refresh_cache: bool, optional + :param output_file: Path to the output file. If left blank, the output will not be written to file, defaults to "" + :type output_file: str, optional + """ + self.supported_models = { + "LlamaForCausalLM": (ModelType.LLAMA, FlexFlowLLAMA, LLAMAConfig), + "LLaMAForCausalLM": (ModelType.LLAMA, FlexFlowLLAMA, LLAMAConfig), + "OPTForCausalLM": (ModelType.OPT, FlexFlowOPT, OPTConfig), + "RWForCausalLM": (ModelType.FALCON, FlexFlowFalcon, FalconConfig), + "FalconForCausalLM": (ModelType.FALCON, FlexFlowFalcon, FalconConfig), + "GPTBigCodeForCausalLM": ( + ModelType.STARCODER, + FlexFlowSTARCODER, + STARCODERConfig, + ), + "MPTForCausalLM": (ModelType.MPT, FlexFlowMPT, MPTConfig), + } + self.hf_config = AutoConfig.from_pretrained(model_name, trust_remote_code=True) + self.model_name = self.hf_config._name_or_path + ( + self.model_type, + self.model_class, + self.config_class, + ) = self.__get_ff_model_type() + self.data_type = data_type + assert self.data_type == DataType.DT_HALF or self.data_type == DataType.DT_FLOAT + self.cache_path = cache_path if len(cache_path) > 0 else "~/.cache/flexflow" + self.refresh_cache = refresh_cache + self.output_file = output_file + self.rm = None + + def __del__(self): + # Stop the background server before deleting the object + if type(self) == LLM and self.rm is not None: + self.rm.stop_server() + + def __get_ff_model_type(self): + architectures = getattr(self.hf_config, "architectures", []) + ff_arch = None + if next(iter(architectures), None) is not None: + ff_arch = self.supported_models.get(architectures[0]) + if ff_arch is None: + print( + f"Huggingface model of type {architectures} is not yet supported by FlexFlow" + ) + sys.exit(1) + return ff_arch + + def download_hf_config(self): + """Save the HuggingFace model configs to a json file. Useful mainly to run the C++ inference code.""" + self.config_dir = os.path.join( + os.path.expanduser(self.cache_path), "configs", self.model_name.lower() + ) + self.config_path = os.path.join(self.config_dir, "config.json") + os.makedirs(self.config_dir, exist_ok=True) + print(f"Creating directory {self.config_dir} (if it doesn't exist)...") + print(f"Saving {self.model_name} configs to file {self.config_path}...") + self.hf_config.to_json_file(self.config_path) + + def __get_revision_hashes(self, model_name: str, weights: bool): + ff_revision = None + ff_revision_file = ( + os.path.join(self.weights_path, "rev_sha.txt") + if weights + else os.path.join(self.tokenizer_path, "rev_sha.txt") + ) + if os.path.exists(ff_revision_file): + ff_revision = "".join(open(ff_revision_file).read().split()) + + if os.path.exists(model_name) and os.path.isdir(model_name): + # Local model + files = os.listdir(model_name) + state = files + [ + os.path.getmtime(os.path.join(model_name, f)) for f in files + ] + latest_revision = hashlib.md5(str(state).encode("utf-8")).hexdigest() + else: + # Remote HuggingFace model + hf_api = HfApi() + latest_revision = hf_api.model_info(self.model_name).sha + return ff_revision, ff_revision_file, latest_revision + + def download_hf_weights_if_needed(self): + """Check in the folder specified by the cache_path whether the LLM's model weights are available and up to date. + If not, or if the refresh_cache parameter is set to True, download new weights. + """ + if self.data_type == DataType.DT_HALF: + torch.set_default_tensor_type(torch.HalfTensor) + elif self.data_type == DataType.DT_FLOAT: + torch.set_default_tensor_type(torch.FloatTensor) + else: + assert False, "Data type not yet supported -- cannot download weights!" + + # Use local cache, or download new version + self.weights_path = os.path.join( + os.path.expanduser(self.cache_path), + "weights", + self.model_name.lower(), + ( + "full-precision" + if self.data_type == DataType.DT_FLOAT + else "half-precision" + ), + ) + if self.refresh_cache: + print( + f"Refreshing weights in cache for model {self.model_name} at path {self.weights_path} ..." + ) + if os.path.exists(self.weights_path): + shutil.rmtree(self.weights_path) + os.makedirs(self.weights_path, exist_ok=True) + print(f"Creating directory {self.weights_path} (if it doesn't exist)...") + + ff_revision, ff_revision_file, latest_revision = self.__get_revision_hashes( + self.model_name, weights=True + ) + + # Download if needed + if ff_revision != latest_revision: + if not os.path.exists(self.model_name) or os.path.isdir(self.model_name): + # Local model + print( + f"'{self.model_name}' model weights not found in cache or outdated. Downloading from huggingface.co ..." + ) + else: + # Remote model + print( + f"'{self.model_name}' local model weights were updated! Converting new weights now..." + ) + # Download model from HuggingFace, or load it from the local folder + hf_model = AutoModelForCausalLM.from_pretrained( + self.model_name, trust_remote_code=True + ) + # Print log message to notify user download of model has finished + if not os.path.exists(self.model_name) or os.path.isdir(self.model_name): + print("Done downloading HF weights. Converting them now...") + # Convert the model to FlexFlow format + self.model_class.convert_hf_model(hf_model, self.weights_path) + # Save new revision hash to file + with open(ff_revision_file, "w+") as f: + f.write(latest_revision) + print("Done converting the weights...") + else: + print(f"Loading '{self.model_name}' model weights from the cache...") + + def download_hf_tokenizer_if_needed(self): + """Check in the folder specified by the cache_path whether the LLM's tokenizer files are available and up to date. + If not, or if the refresh_cache parameter is set to True, download new tokenizer files. + """ + print("Loading tokenizer...") + + # Use local cache, or download new version + self.tokenizer_path = os.path.join( + os.path.expanduser(self.cache_path), + "tokenizers", + self.model_name.lower(), + ) + if self.refresh_cache: + print( + f"Discarding cached tokenizer files (if they exist) for model {self.model_name}..." + ) + if os.path.exists(self.tokenizer_path): + shutil.rmtree(self.tokenizer_path) + if not os.path.exists(self.tokenizer_path): + print(f"Creating directory {self.tokenizer_path} (if it doesn't exist)...") + os.makedirs(self.tokenizer_path, exist_ok=True) + + # Get local revision SHA, check if it matches latest one on huggingface + ff_revision, ff_revision_file, latest_revision = self.__get_revision_hashes( + self.model_name, weights=False + ) + + if ff_revision != latest_revision: + if not os.path.exists(self.model_name) or os.path.isdir(self.model_name): + # Local model + print( + f"'{self.model_name}' tokenizer not found in cache or outdated. Downloading from huggingface.co ..." + ) + else: + # Remote model + print( + f"'{self.model_name}' local tokenizer was updated! Saving new tokenizer now..." + ) + # Download tokenizer from HuggingFace, or load it from the local folder + if self.model_type == ModelType.LLAMA: + hf_tokenizer = LlamaTokenizer.from_pretrained( + self.model_name, use_fast=True + ) + else: + hf_tokenizer = AutoTokenizer.from_pretrained(self.model_name) + # Print log message to notify user download of tokenizer has finished + if not os.path.exists(self.model_name) or os.path.isdir(self.model_name): + print("Done downloading tokenizer. Saving it now...") + # Save tokenizer + hf_tokenizer.save_pretrained(self.tokenizer_path) + print("Done saving HF tokenizer.") + # Save new revision hash to file + with open(ff_revision_file, "w+") as f: + f.write(latest_revision) + + else: + print(f"Loading '{self.model_name}' tokenizer from the cache...") + + def compile( + self, + generation_config: GenerationConfig = GenerationConfig(), + max_requests_per_batch: int = 1, + max_seq_length: int = 256, + max_tokens_per_batch: int = 64, + model_specific_data_parallelism_degree: int = None, + model_specific_tensor_parallelism_degree: int = None, + model_specific_pipeline_parallelism_degree: int = None, + ssms: list = [], + ): + """Compile the LLM for inference and load the weights into memory + + :param generation_config: The GenerationConfig object with the configurations to use for sampling, defaults to GenerationConfig() + :type generation_config: GenerationConfig, optional + :param max_requests_per_batch: The maximum batch size to allow, defaults to 1 + :type max_requests_per_batch: int, optional + :param max_seq_length: The maximum sequence length to allow per batch, defaults to 256 + :type max_seq_length: int, optional + :param max_tokens_per_batch: The maximum number of tokens (across requests) to allow per batch, defaults to 64 + :type max_tokens_per_batch: int, optional + :param model_specific_data_parallelism_degree: Use this parameter if you want to give the LLM a different data parallelism degree than the one used to initialize the runtime, defaults to None + :type model_specific_data_parallelism_degree: int, optional + :param model_specific_tensor_parallelism_degree: Use this parameter if you want to give the LLM a different tensor parallelism degree than the one used to initialize the runtime, defaults to None + :type model_specific_tensor_parallelism_degree: int, optional + :param model_specific_pipeline_parallelism_degree: Use this parameter if you want to give the LLM a different pipeline parallelism degree than the one used to initialize the runtime, defaults to None + :type model_specific_pipeline_parallelism_degree: int, optional + :param ssms: The SSMs to use when operating in speculative inference mode, defaults to [] + :type ssms: list, optional + """ + # self.max_requests_per_batch = max_requests_per_batch + # self.max_seq_length = max_seq_length + # self.max_tokens_per_batch = max_tokens_per_batch + self.ssms = ssms + self.generation_config = GenerationConfig() + self.ffconfig = FFConfig() + if len(ssms) > 0: + assert type(self) == LLM + mode = InferenceMode.TREE_VERIFY_MODE + elif type(self) == SSM: + mode = InferenceMode.BEAM_SEARCH_MODE + else: + assert type(self) == LLM + mode = InferenceMode.INC_DECODING_MODE + + # Apply model-specific parallelism degrees, if needed + if model_specific_data_parallelism_degree: + self.ffconfig.data_parallelism_degree = ( + model_specific_data_parallelism_degree + ) + if model_specific_tensor_parallelism_degree: + self.ffconfig.tensor_parallelism_degree = ( + model_specific_tensor_parallelism_degree + ) + if model_specific_pipeline_parallelism_degree: + self.ffconfig.pipeline_parallelism_degree = ( + model_specific_pipeline_parallelism_degree + ) + + # Create request manager and set serving configuration + self.rm = RequestManager() + self.rm.set_max_requests_per_batch(max_requests_per_batch) + self.rm.set_max_tokens_per_batch(max_tokens_per_batch) + self.rm.set_max_sequence_length(max_seq_length) + + # Instantiate the relevant model + self.model = self.model_class( + mode, + generation_config, + self.ffconfig, + self.hf_config, + self.data_type, + max_tokens_per_batch, + ) + + # Download the weights from huggingface (if needed) + self.download_hf_weights_if_needed() + + # Create file data loader, load weights into tensors + model_configs = self.config_class(self.hf_config) + + self.rm.set_max_spec_tree_token_num( + model_configs.max_spec_tree_token_num + if "max_spec_tree_token_num" + in model_configs.__dict__ + else 20 + ) + + self.fileloader = FileDataLoader( + self.weights_path, + model_configs.num_attention_heads, + model_configs.num_key_value_heads, + model_configs.hidden_size, + model_configs.hidden_size // model_configs.num_attention_heads, + self.ffconfig.tensor_parallelism_degree, + self.data_type == DataType.DT_FLOAT, + ) + + # Register weights file loader + self.im = InferenceManager() + self.im.register_model_weights_loader(self.model.ffmodel, self.fileloader) + + # Download the tokenizer from huggingface (if needed) and load them + self.download_hf_tokenizer_if_needed() + + # Create tokenizer (this must be done after we have downloaded the tokenizer + bos_token_id = ( + -1 if self.hf_config.bos_token_id is None else self.hf_config.bos_token_id + ) + eos_token_id = ( + -1 if self.hf_config.eos_token_id is None else self.hf_config.eos_token_id + ) + self.rm.register_tokenizer( + self.model_type, bos_token_id, eos_token_id, self.tokenizer_path + ) + self.rm.register_output_filepath(self.output_file) + + for ssm in self.ssms: + self.rm.register_ssm_model(ssm.model.ffmodel) + + # start background server + if (mode == InferenceMode.TREE_VERIFY_MODE) or ( + mode == InferenceMode.INC_DECODING_MODE + ): + import atexit + + atexit.register(self.rm.stop_server) + + def generate(self, prompts: Union[str, List[str]], max_length: int = 128): + """Generate tokens based on the input prompt(s) + + :param prompts: The generation prompt(s) in the form of a string, or list of strings + :type prompts: Union[str, List[str]] + :return: the generation results + :rtype: GenerationResult + """ + if type(prompts) == str: + if len(prompts) == 0: + return None + return self.model.ffmodel.generate([prompts], max_length) + elif type(prompts) == list: + if len(prompts) == 0: + return [] + return self.model.ffmodel.generate(prompts, max_length) + else: + assert False, "Please pass a non-empty string or list of strings" + + def start_server(self): + self.rm.start_server(self.model.ffmodel) + print("Background server started.") + + def stop_server(self): + self.rm.stop_server() + print("Background server stopped.") + + def __enter__(self): + # Start the server when entering the context + # self.rm.start_server(self.model.ffmodel) + return self + + def __exit__(self, exc_type, exc_value, traceback): + # Stop the server when exiting the context + # self.rm.stop_server() + if exc_type: + print(f"Exception occurred: {exc_value}") + + +class SSM(LLM): + """This class creates a SSM (Small-Speculative Model) object based on a model from HuggingFace""" + + def __init__( + self, + model_name: str, + data_type: DataType = DataType.DT_HALF, + cache_path: str = "~/.cache/flexflow", + refresh_cache: bool = False, + output_file: str = "", + ): + """Create the SSM object + + :param model_name: The name of the HuggingFace model to use. E.g. 'meta-llama/Llama-2-7b-hf' + :type model_name: str + :param data_type: The data type to use for the tensors (e.g. DataType.DT_FLOAT for full precision, or DataType.DT_HALF for half precision), defaults to DataType.DT_HALF + :type data_type: DataType, optional + :param cache_path: Path to the folder (which will be created if it does not yet exist) to use for the FlexFlow weights/tokenizers cache, defaults to "~/.cache/flexflow" + :type tokenizer_path: str, optional + :param refresh_cache: Use this flag to force the refresh of the model's weights/tokenizer cache, defaults to False + :type refresh_cache: bool, optional + :param output_file: Path to the output file. If left blank, the output will not be written to file, defaults to "" + :type output_file: str, optional + """ + super().__init__( + model_name, + data_type, + cache_path, + refresh_cache, + output_file, + ) + + def compile( + self, + generation_config: GenerationConfig = GenerationConfig(), + max_requests_per_batch: int = 16, + max_seq_length: int = 256, + max_tokens_per_batch: int = 128, + model_specific_data_parallelism_degree: int = 1, + model_specific_tensor_parallelism_degree: int = 1, + model_specific_pipeline_parallelism_degree: int = 1, + ssms: list = [], + ): + """Compile the SSM for inference and load the weights into memory + + :param mode: The SSM inference mode (InferenceMode.INC_DECODING_MODE for incremental decoding, InferenceMode.BEAM_SEARCH_MODE for beam search, or InferenceMode.TREE_VERIFY_MODE for token tree verification), defaults to InferenceMode.INC_DECODING_MODE + :type mode: InferenceMode, optional + :param generation_config: The GenerationConfig object with the configurations to use for sampling, defaults to GenerationConfig() + :type generation_config: GenerationConfig, optional + :param max_requests_per_batch: The maximum batch size to allow, defaults to 16 + :type max_requests_per_batch: int, optional + :param max_seq_length: The maximum sequence length to allow per batch, defaults to 256 + :type max_seq_length: int, optional + :param max_tokens_per_batch: The maximum number of tokens (across requests) to allow per batch, defaults to 128 + :type max_tokens_per_batch: int, optional + :param model_specific_data_parallelism_degree: Use this parameter if you want to give the SSM a different data parallelism degree than the default one, defaults to 1 + :type model_specific_data_parallelism_degree: int, optional + :param model_specific_tensor_parallelism_degree: Use this parameter if you want to give the SSM a different tensor parallelism degree than the default one, defaults to 1 + :type model_specific_tensor_parallelism_degree: int, optional + :param model_specific_pipeline_parallelism_degree: Use this parameter if you want to give the SSM a different pipeline parallelism degree than the default one, defaults to 1 + :type model_specific_pipeline_parallelism_degree: int, optional + :param ssms: The SSMs to use when operating in speculative inference mode, defaults to [] + :type ssms: list, optional + """ + super().compile( + generation_config, + max_requests_per_batch, + max_seq_length, + max_tokens_per_batch, + model_specific_data_parallelism_degree, + model_specific_tensor_parallelism_degree, + model_specific_pipeline_parallelism_degree, + ssms, + ) diff --git a/python/flexflow/torch/model.py b/python/flexflow/torch/model.py index 8ebac2146c..5d4f892ccc 100644 --- a/python/flexflow/torch/model.py +++ b/python/flexflow/torch/model.py @@ -967,7 +967,7 @@ def is_left_scalar_op(node): if len(innodes) != 2: return False return type(innodes[0]) is float or \ - type(innodes[1]) is int + type(innodes[0]) is int @staticmethod def is_elemwise_op(node): diff --git a/python/flexflow/type.py b/python/flexflow/type.py index 0412e9d0cd..994a85f57e 100644 --- a/python/flexflow/type.py +++ b/python/flexflow/type.py @@ -2,142 +2,184 @@ from enum import Enum + class ActiMode(Enum): - AC_MODE_NONE = 10 - AC_MODE_RELU = 11 - AC_MODE_SIGMOID = 12 - AC_MODE_TANH = 13 - AC_MODE_GELU = 14 + AC_MODE_NONE = 10 + AC_MODE_RELU = 11 + AC_MODE_SIGMOID = 12 + AC_MODE_TANH = 13 + AC_MODE_GELU = 14 + class RegularizerMode(Enum): - REG_MODE_NONE = 17 - REG_MODE_L1 = 18 - REG_MODE_L2 = 19 + REG_MODE_NONE = 17 + REG_MODE_L1 = 18 + REG_MODE_L2 = 19 + class AggrMode(Enum): - AGGR_MODE_NONE = 20 - AGGR_MODE_SUM = 21 - AGGR_MODE_AVG = 22 + AGGR_MODE_NONE = 20 + AGGR_MODE_SUM = 21 + AGGR_MODE_AVG = 22 + class PoolType(Enum): - POOL_MAX = 30 - POOL_AVG = 31 + POOL_MAX = 30 + POOL_AVG = 31 + class DataType(Enum): - DT_BOOLEAN = 40 - DT_INT32 = 41 - DT_INT64 = 42 - DT_HALF = 43 - DT_FLOAT = 44 - DT_DOUBLE = 45 - DT_NONE = 49 + DT_BOOLEAN = 40 + DT_INT32 = 41 + DT_INT64 = 42 + DT_HALF = 43 + DT_FLOAT = 44 + DT_DOUBLE = 45 + DT_NONE = 49 + class LossType(Enum): - LOSS_CATEGORICAL_CROSSENTROPY = 50 - LOSS_SPARSE_CATEGORICAL_CROSSENTROPY = 51 - LOSS_MEAN_SQUARED_ERROR_AVG_REDUCE = 52 - LOSS_MEAN_SQUARED_ERROR_SUM_REDUCE = 53 - LOSS_IDENTITY = 54 + LOSS_CATEGORICAL_CROSSENTROPY = 50 + LOSS_SPARSE_CATEGORICAL_CROSSENTROPY = 51 + LOSS_MEAN_SQUARED_ERROR_AVG_REDUCE = 52 + LOSS_MEAN_SQUARED_ERROR_SUM_REDUCE = 53 + LOSS_IDENTITY = 54 + class CompMode(Enum): - TRAINING = 70 - INFERENCE = 71 - + TRAINING = 70 + INFERENCE = 71 + + class ParameterSyncType(Enum): - NONE = 80 - PS = 81 - NCCL = 82 - + NONE = 80 + PS = 81 + NCCL = 82 + + class MetricsType(Enum): - METRICS_ACCURACY = 1001 - METRICS_CATEGORICAL_CROSSENTROPY = 1002 - METRICS_SPARSE_CATEGORICAL_CROSSENTROPY = 1004 - METRICS_MEAN_SQUARED_ERROR = 1008 - METRICS_ROOT_MEAN_SQUARED_ERROR = 1016 - METRICS_MEAN_ABSOLUTE_ERROR=1032 + METRICS_ACCURACY = 1001 + METRICS_CATEGORICAL_CROSSENTROPY = 1002 + METRICS_SPARSE_CATEGORICAL_CROSSENTROPY = 1004 + METRICS_MEAN_SQUARED_ERROR = 1008 + METRICS_ROOT_MEAN_SQUARED_ERROR = 1016 + METRICS_MEAN_ABSOLUTE_ERROR = 1032 + + +class InferenceMode(Enum): + INC_DECODING_MODE = 2001 + BEAM_SEARCH_MODE = 2002 + TREE_VERIFY_MODE = 2003 + + +class ModelType(Enum): + UNKNOWN = 3001 + LLAMA = 3002 + OPT = 3003 + FALCON = 3004 + STARCODER = 3005 + MPT = 3006 + class OpType(Enum): - CONV2D = 2011 - EMBEDDING = 2012 - POOL2D = 2013 - LINEAR = 2014 - SOFTMAX = 2015 - CONCAT = 2016 - FLAT = 2017 - MSELOSS = 2020 - BATCH_NORM = 2021 - RELU = 2022 - SIGMOID = 2023 - TANH = 2024 - ELU = 2025 - DROPOUT = 2026 - BATCH_MATMUL = 2027 - SPLIT = 2028 - RESHAPE = 2029 - TRANSPOSE = 2030 - REVERSE = 2031 - EXP = 2040 - ADD = 2041 - SUBTRACT = 2042 - MULTIPLY = 2043 - DIVIDE = 2044 - POW = 2045 - MEAN = 2046 - RSQRT = 2047 - SIN = 2048 - COS = 2049 - INPUT = 2050 - OUTPUT = 2051 - REDUCE_SUM = 2052 - MAX = 2053 - MIN = 2054 - MULTIHEAD_ATTENTION = 2060 - GETITEM = 2070 - GETATTR = 2080 - EXPAND = 2081 - LAYER_NORM = 2082 - FLOOR_DIVIDE = 2083 - IDENTITY = 2084 - GELU = 2085 - PERMUTE = 2086 - SCALAR_MULTIPLY = 2087 - SCALAR_FLOORDIV = 2088 - SCALAR_ADD = 2089 - SCALAR_SUB = 2090 - SCALAR_TRUEDIV = 2091 - INIT_PARAM = 2092 - FLOAT = 2100 - CONTIGUOUS = 2101 - TO = 2102 - UNSQUEEZE = 2103 - TYPE_AS = 2104 - VIEW = 2105 - GATHER = 2106 - ATTRIBUTE = 2200 + CONV2D = 2011 + EMBEDDING = 2012 + POOL2D = 2013 + LINEAR = 2014 + SOFTMAX = 2015 + CONCAT = 2016 + FLAT = 2017 + MSELOSS = 2020 + BATCH_NORM = 2021 + RELU = 2022 + SIGMOID = 2023 + TANH = 2024 + ELU = 2025 + DROPOUT = 2026 + BATCH_MATMUL = 2027 + SPLIT = 2028 + RESHAPE = 2029 + TRANSPOSE = 2030 + REVERSE = 2031 + EXP = 2040 + ADD = 2041 + SUBTRACT = 2042 + MULTIPLY = 2043 + DIVIDE = 2044 + POW = 2045 + MEAN = 2046 + RSQRT = 2047 + SIN = 2048 + COS = 2049 + INPUT = 2050 + OUTPUT = 2051 + REDUCE_SUM = 2052 + MAX = 2053 + MIN = 2054 + MULTIHEAD_ATTENTION = 2060 + INC_MULTIHEAD_ATTENTION = 2061 + SPEC_INC_MULTIHEAD_SELF_ATTENTION = 2062 + TREE_INC_MULTIHEAD_SELF_ATTENTION = 2063 + SAMPLING = 2065 + ARGMAX = 2066 + GETITEM = 2070 + GETATTR = 2080 + EXPAND = 2081 + LAYER_NORM = 2082 + FLOOR_DIVIDE = 2083 + IDENTITY = 2084 + GELU = 2085 + PERMUTE = 2086 + SCALAR_MULTIPLY = 2087 + SCALAR_FLOORDIV = 2088 + SCALAR_ADD = 2089 + SCALAR_SUB = 2090 + SCALAR_TRUEDIV = 2091 + INIT_PARAM = 2092 + FLOAT = 2100 + CONTIGUOUS = 2101 + TO = 2102 + UNSQUEEZE = 2103 + TYPE_AS = 2104 + VIEW = 2105 + GATHER = 2106 + ATTRIBUTE = 2200 + RMS_NORM = 2300 + ARG_TOPK = 2301 + BEAM_TOPK = 2302 + ADD_BIAS_RESIDUAL_LAYERNORM = 2303 + SIGMOID_SILU_MULTI = 2304 + RESIDUAL_RMS_NORM = 2305 + RESIDUAL_LAYERNORM = 2306 + + def enum_to_int(enum, enum_item): - for item in enum: - if (enum_item == item): - return item.value + for item in enum: + if enum_item == item: + return item.value + + print(enum_item) + print(enum) + assert 0, "unknown enum type " + str(enum_item) + " " + str(enum) + return -1 - print(enum_item) - print(enum) - assert 0, "unknown enum type " + str(enum_item) + " " + str(enum) - return -1 def int_to_enum(enum, value): - for item in enum: - if (item.value == value): - return item + for item in enum: + if item.value == value: + return item + + assert 0, "unknown enum value " + str(value) + " " + str(enum) + - assert 0, "unknown enum value " + str(value) + " " + str(enum) - def enum_to_str(enum, enum_item): - name = enum(enum_item).name - return name - + name = enum(enum_item).name + return name + + def str_to_enum(enum, value): - for item in enum: - if (item.name == value): - return item + for item in enum: + if item.name == value: + return item - assert 0, "unknown enum value " + value + " " + str(enum) + assert 0, "unknown enum value " + value + " " + str(enum) diff --git a/python/flexflow_cffi_build.py b/python/flexflow_cffi_build.py index c4cf8e9e09..b89fba2f06 100755 --- a/python/flexflow_cffi_build.py +++ b/python/flexflow_cffi_build.py @@ -1,4 +1,4 @@ -#!/usr/bin/env python +#!/usr/bin/env python3 # Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) # diff --git a/python/flexflow_cffi_header.py.in b/python/flexflow_cffi_header.py.in index fdd03315ee..f9f5b01b20 100644 --- a/python/flexflow_cffi_header.py.in +++ b/python/flexflow_cffi_header.py.in @@ -1,4 +1,4 @@ -#!/usr/bin/env python +#!/usr/bin/env python3 # Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) # diff --git a/python/flexflow_python_build.py b/python/flexflow_python_build.py index 0e58193ef7..45b858b113 100755 --- a/python/flexflow_python_build.py +++ b/python/flexflow_python_build.py @@ -1,4 +1,4 @@ -#!/usr/bin/env python +#!/usr/bin/env python3 # Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) # @@ -29,33 +29,54 @@ sys.exit(1) build_dir = os.path.abspath(build_dir) script_dir = os.path.abspath(os.path.dirname(__file__)) -script_path = os.path.join(build_dir, "flexflow_python") if not os.path.isdir(build_dir): print(f"Folder {build_dir} does not exist") sys.exit(1) if not os.path.isdir(script_dir): print(f"Folder {script_dir} does not exist") sys.exit(1) -script_path = os.path.abspath(script_path) +# Build flexflow_python script +flexflow_python_path = os.path.join(build_dir, "flexflow_python") +flexflow_python_path = os.path.abspath(flexflow_python_path) lines = [ '#! /usr/bin/env bash', f'BUILD_FOLDER="{build_dir}"', 'SCRIPT_DIR="$(realpath "${BASH_SOURCE[0]%/*}")"', - 'if [[ "$SCRIPT_DIR" == "$BUILD_FOLDER" ]]; then', + 'legion_python_args=("$@" "-ll:py" "1")', + 'if [[ "$SCRIPT_DIR" -ef "$BUILD_FOLDER" ]]; then', f'\tPYTHON_FOLDER="{script_dir}"', '\tPYLIB_PATH="$("$PYTHON_FOLDER"/flexflow/findpylib.py)"', '\tPYLIB_DIR="$(dirname "$PYLIB_PATH")"', '\texport LD_LIBRARY_PATH="$BUILD_FOLDER:$BUILD_FOLDER/deps/legion/lib:$PYLIB_DIR:$LD_LIBRARY_PATH"', '\texport PYTHONPATH="$PYTHON_FOLDER:$BUILD_FOLDER/deps/legion/bindings/python:$PYTHONPATH"', - '\t$BUILD_FOLDER/deps/legion/bin/legion_python "$@"', + '\t$BUILD_FOLDER/deps/legion/bin/legion_python "${legion_python_args[@]}"', 'else', - '\tlegion_python "$@"', + '\tPYLIB_PATH="$(python3 -m flexflow.findpylib)"', + '\tPYLIB_DIR="$(dirname "$PYLIB_PATH")"', + '\texport LD_LIBRARY_PATH="$PYLIB_DIR:$LD_LIBRARY_PATH"', + '\tlegion_python "${legion_python_args[@]}"', 'fi' ] - -with open(script_path, "w+") as script_file: +with open(flexflow_python_path, "w+") as flexflow_python_file: for line in lines: - script_file.write(line + "\n") + flexflow_python_file.write(line + "\n") +cur_stat = os.stat(flexflow_python_path) +os.chmod(flexflow_python_path, cur_stat.st_mode | stat.S_IEXEC) -cur_stat = os.stat(script_path) -os.chmod(script_path, cur_stat.st_mode | stat.S_IEXEC) +# Build set_python_envs.sh +python_envs_path = os.path.join(build_dir, "set_python_envs.sh") +python_envs_path = os.path.abspath(python_envs_path) +lines = [ + '#! /usr/bin/env bash', + f'BUILD_FOLDER="{build_dir}"', + f'PYTHON_FOLDER="{script_dir}"', + 'PYLIB_PATH="$("$PYTHON_FOLDER"/flexflow/findpylib.py)"', + 'PYLIB_DIR="$(dirname "$PYLIB_PATH")"', + 'export LD_LIBRARY_PATH="$BUILD_FOLDER:$BUILD_FOLDER/deps/legion/lib:$PYLIB_DIR:$LD_LIBRARY_PATH"', + 'export PYTHONPATH="$PYTHON_FOLDER:$BUILD_FOLDER/deps/legion/bindings/python:$PYTHONPATH"', +] +with open(python_envs_path, "w+") as python_envs_file: + for line in lines: + python_envs_file.write(line + "\n") +cur_stat = os.stat(python_envs_path) +os.chmod(python_envs_path, cur_stat.st_mode | stat.S_IEXEC) diff --git a/requirements.txt b/requirements.txt index 13d7c67588..1037661337 100644 --- a/requirements.txt +++ b/requirements.txt @@ -1,4 +1,3 @@ -python>=3.6 cffi>=1.11.0 numpy>=1.16.0 qualname>=0.1.0 @@ -6,3 +5,13 @@ keras_preprocessing>=1.1.2 Pillow pybind11 cmake-build-extension +ninja +requests +regex +torch>=1.13.1 +torchaudio>=0.13.1 +torchvision>=0.14.1 +onnx +transformers>=4.31.0 +sentencepiece +einops diff --git a/scripts/FC_env_setup.sh b/scripts/FC_env_setup.sh deleted file mode 100755 index ad58118761..0000000000 --- a/scripts/FC_env_setup.sh +++ /dev/null @@ -1,33 +0,0 @@ -#!/bin/bash -set -euo pipefail - -# Cd into FF_HOME -cd "${BASH_SOURCE[0]%/*}/../" - -export GASNET=${PWD}/GASNet-2019.9.0 -export LEGION=${PWD}/legion -export PROTOBUF=${PWD}/protobuf - -module unload cuda cudnn NCCL - -#cuda v10 -#module load cuda/10.0 -#module load cudnn/v7.6-cuda.10.0 -#module load NCCL/2.4.8-1-cuda.10.0 -#export CUDA=/public/apps/cuda/10.1 -#export CUDNN=/public/apps/cudnn/v7.6/cuda -#export NCCL=/public/apps/NCCL/2.4.8-1 - -#cuda v9.2 -module load cuda/9.2 -module load cudnn/v7.3-cuda.9.2 -module load NCCL/2.2.13-1-cuda.9.2 -export CUDA=/public/apps/cuda/9.2 -export CUDNN=/public/apps/cudnn/v7.3/cuda -export NCCL=/public/apps/NCCL/2.2.13-1 - -module load cmake/3.15.3/gcc.7.3.0 -module load anaconda3/2019.07 - -export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$PROTOBUF/src/.libs -export PATH=$PATH:$PROTOBUF diff --git a/scripts/FC_setup.sh b/scripts/FC_setup.sh deleted file mode 100644 index 537d0c0b83..0000000000 --- a/scripts/FC_setup.sh +++ /dev/null @@ -1,34 +0,0 @@ -#! /usr/bin/env bash -set -euo pipefail - -# Cd into FF_HOME -cd "${BASH_SOURCE[0]%/*}/../" - -git submodule update --init --recursive -./scripts/FC_env_setup.sh - -cd "$PROTOBUF" -git submodule update --init --recursive -##git checkout 6d4e7fd #still cannot get the strategy compile to use the local runtime. So need to checkout v 3.10.0 -./autogen.sh -./configure -make -j -cd .. - -cd "$GASNET" -./FC.build_script.sh -cd .. - -cd src/runtime -../../protobuf/src/protoc --cpp_out=. strategy.proto -./gen_strategy.sh 8 8 1 # for 8 gpu per node, and 8 embeddings per node, and 1 node -cd ../.. - -cd "$LEGION" -git checkout control_replication -cd ../ - - -make app=examples/DLRM/dlrm -j -cd examples/DLRM -./run_random.sh 1 \ No newline at end of file diff --git a/scripts/FC_setup.txt b/scripts/FC_setup.txt deleted file mode 100644 index 0702815343..0000000000 --- a/scripts/FC_setup.txt +++ /dev/null @@ -1,24 +0,0 @@ -git clone --recursive -git submodule update --init --recursive -source FC_env_setup.sh - -cd $PROTOBUF -git submodule update --init --recursive -##git checkout 6d4e7fd #still cannot get the strategy compile to use the local runtime. So need to checkout v 3.10.0 -./autogen.sh -./configure -make -j -cd .. - -cd $GASNET -./FC.build_script.sh -cd .. - -cd src/runtime -../../protobuf/src/protoc --cpp_out=. strategy.proto -./gen_strategy.sh 8 8 # for 8 gpu and 8 embeddings -cd ../.. - -make app=examples/DLRM/dlrm -j -cd examples/DLRM -./run_random.sh 1 diff --git a/scripts/Makefile b/scripts/Makefile deleted file mode 100644 index 7fa21fb11a..0000000000 --- a/scripts/Makefile +++ /dev/null @@ -1,2 +0,0 @@ -simulator: - nvcc simulator.cc -lcudnn -lcublas -std=c++11 -arch=compute_37 -code=sm_37 diff --git a/scripts/compile_protobuf.sh b/scripts/compile_protobuf.sh deleted file mode 100755 index bea26e6940..0000000000 --- a/scripts/compile_protobuf.sh +++ /dev/null @@ -1,6 +0,0 @@ -#!/bin/bash -set -euo pipefail - -cd src/runtime -protoc --cpp_out=. strategy.proto -cd ../.. diff --git a/scripts/install_tokenizer.sh b/scripts/install_tokenizer.sh new file mode 100755 index 0000000000..4632b7e818 --- /dev/null +++ b/scripts/install_tokenizer.sh @@ -0,0 +1,9 @@ +#! /usr/bin/env bash +set -x +set -e + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" +cd ../deps/tokenizers-cpp/example +cmake -D CMAKE_CXX_FLAGS=-fPIC +make -j diff --git a/scripts/mnist_mlp_run.sh b/scripts/mnist_mlp_run.sh index 8842790e6a..b070195d88 100755 --- a/scripts/mnist_mlp_run.sh +++ b/scripts/mnist_mlp_run.sh @@ -2,4 +2,17 @@ eval "$(conda shell.bash hook)" conda activate flexflow export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:$CONDA_PREFIX/lib -~/FlexFlow/python/flexflow_python ~/FlexFlow/examples/python/native/mnist_mlp.py -ll:py 1 -ll:gpu 1 -ll:fsize 8000 -ll:zsize 8000 + +# Path to your FlexFlow build +FLEXFLOW_DIR=/home/ubuntu/FlexFlow/build + +# Path to your UCX installation +UCX_DIR=/home/ubuntu/ucx-1.15.0/install + +export REALM_UCP_BOOTSTRAP_PLUGIN=$FLEXFLOW_DIR/deps/legion/lib/realm_ucp_bootstrap_mpi.so +export LD_LIBRARY_PATH=$FLEXFLOW_DIR/deps/legion/lib:$LD_LIBRARY_PATH +export LD_LIBRARY_PATH=$FLEXFLOW_DIR:$LD_LIBRARY_PATH +export LD_LIBRARY_PATH=$UCX_DIR/lib:$LD_LIBRARY_PATH +export LD_LIBRARY_PATH=/opt/conda/envs/flexflow/lib:$LD_LIBRARY_PATH + +mpiexec -x REALM_UCP_BOOTSTRAP_PLUGIN -x PATH -x LD_LIBRARY_PATH --hostfile ~/hostfile --mca btl_tcp_if_include ens5 -np 2 "$FLEXFLOW_DIR"/flexflow_python "$FLEXFLOW_DIR"/../examples/python/native/mnist_mlp.py -ll:py 1 -ll:gpu 1 -ll:fsize 8000 -ll:zsize 8000 diff --git a/scripts/osdi22ae/bert.sh b/scripts/osdi22ae/bert.sh deleted file mode 100755 index 18d2c3195c..0000000000 --- a/scripts/osdi22ae/bert.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running BERT with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/Transformer/transformer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 -b 8 --budget 30 - -echo "Running BERT Uno with data parallelism" -"$FF_HOME"/build/examples/cpp/Transformer/transformer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 -b 8 --budget 30 --only-data-parallel diff --git a/scripts/osdi22ae/candle_uno.sh b/scripts/osdi22ae/candle_uno.sh deleted file mode 100755 index 22458149f1..0000000000 --- a/scripts/osdi22ae/candle_uno.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running CANDLE Uno with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/candle_uno/candle_uno -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 - -echo "Running CANDLE Uno with data parallelism" -"$FF_HOME"/build/examples/cpp/candle_uno/candle_uno -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 --only-data-parallel diff --git a/scripts/osdi22ae/dlrm.sh b/scripts/osdi22ae/dlrm.sh deleted file mode 100755 index a75e78bc0a..0000000000 --- a/scripts/osdi22ae/dlrm.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running DLRM with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/DLRM/dlrm -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 - -echo "Running DLRM with data parallelism" -"$FF_HOME"/build/examples/cpp/DLRM/dlrm -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 --only-data-parallel diff --git a/scripts/osdi22ae/inception.sh b/scripts/osdi22ae/inception.sh deleted file mode 100755 index 7b6c079eab..0000000000 --- a/scripts/osdi22ae/inception.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running Inception-v3 with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/InceptionV3/inception -ll:gpu 4 -ll:fsize 11000 -ll:zsize 14000 -b 64 --budget 10 - -echo "Running Inception-v3 with data parallelism" -"$FF_HOME"/build/examples/cpp/InceptionV3/inception -ll:gpu 4 -ll:fsize 11000 -ll:zsize 14000 -b 64 --budget 10 --only-data-parallel diff --git a/scripts/osdi22ae/mlp.sh b/scripts/osdi22ae/mlp.sh deleted file mode 100755 index fa84607983..0000000000 --- a/scripts/osdi22ae/mlp.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running MLP with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/MLP_Unify/mlp_unify -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 - -echo "Running MLP with data parallelism" -"$FF_HOME"/build/examples/cpp/MLP_Unify/mlp_unify -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 --only-data-parallel diff --git a/scripts/osdi22ae/resnext-50.sh b/scripts/osdi22ae/resnext-50.sh deleted file mode 100755 index c73e079361..0000000000 --- a/scripts/osdi22ae/resnext-50.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running ResNeXt-50 with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/resnext50/resnext50 -ll:gpu 4 -ll:fsize 12000 -ll:zsize 14000 -b 16 --budget 20 - -echo "Running ResNeXt-50 with data parallelism" -"$FF_HOME"/build/examples/cpp/resnext50/resnext50 -ll:gpu 4 -ll:fsize 12000 -ll:zsize 14000 -b 16 --budget 20 --only-data-parallel diff --git a/scripts/osdi22ae/xdl.sh b/scripts/osdi22ae/xdl.sh deleted file mode 100755 index fcb5172b30..0000000000 --- a/scripts/osdi22ae/xdl.sh +++ /dev/null @@ -1,7 +0,0 @@ -#! /usr/bin/env bash - -echo "Running XDL with a parallelization strategy discovered by Unity" -"$FF_HOME"/build/examples/cpp/XDL/xdl -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 - -echo "Running XDL with data parallelism" -"$FF_HOME"/build/examples/cpp/XDL/xdl -ll:gpu 4 -ll:fsize 14000 -ll:zsize 14000 --budget 20 --only-data-parallel diff --git a/scripts/test_run.sh b/scripts/test_run.sh deleted file mode 100644 index 9ff8f71129..0000000000 --- a/scripts/test_run.sh +++ /dev/null @@ -1,38 +0,0 @@ -#! /usr/bin/env bash -set -euo pipefail - -# Cd into FF_HOME -cd "${BASH_SOURCE[0]%/*}/../" - -# git checkout dcr # We are using the dcr branch by default -git submodule update --init --recursive -./scripts/FC_env_setup.sh - -cd "$PROTOBUF" -git submodule update --init --recursive -##git checkout 6d4e7fd #still cannot get the strategy compile to use the local runtime. So need to checkout v 3.10.0 -./autogen.sh -./configure -make -j -cd .. - -cd "$GASNET" -./FC.build_script.sh -cd .. - -cd src/runtime -../../protobuf/src/protoc --cpp_out=. strategy.proto -./gen_strategy.sh 8 8 1 # for 8 gpu per node, and 8 embeddings per node, and 1 node -./gen_strategy.sh 2 1 1 # for 2 gpu per node, testing purpose -cd ../.. - -cd "$LEGION" -git checkout control_replication -cd ../ - - -make app=src/ops/tests/concat_test -j -f Makefile -cd src/ops/tests -./test_run_FF_target.sh concat_test 2 && cp output.txt output_2gpus.txt -./test_run_FF_target.sh concat_test 1 && cp output.txt output_1gpus.txt - diff --git a/setup.py b/setup.py index 4564657d46..ad48fb9367 100644 --- a/setup.py +++ b/setup.py @@ -1,44 +1,135 @@ from setuptools import setup, find_packages from pathlib import Path from cmake_build_extension import BuildExtension, CMakeExtension -import os -import subprocess +import os, subprocess, requests, re +from datetime import date datadir = Path(__file__).parent / "python/flexflow" files = [str(p.relative_to(datadir)) for p in datadir.rglob("*.py")] -# Load CMake configs from config/config.linux file +# Load CMake configs from config/config.linux file, parsing any custom settings from environment variables configs_path = os.path.join( os.path.dirname(os.path.abspath(__file__)), "config", "config.linux" ) - cmake_configure_options = subprocess.check_output([configs_path, "CMAKE_FLAGS"]).decode( "utf-8" ).strip().split() + ["-DFF_BUILD_FROM_PYPI=ON"] cuda_path = subprocess.check_output([configs_path, "CUDA_PATH"]).decode("utf-8").strip() - +# CUDA PATH should be passed to CMAKE via an environment variable os.environ["CUDA_PATH"] = cuda_path +# set up make flags to parallelize build of subcomponents that do not use ninja +os.environ["MAKEFLAGS"] = (os.environ.get("MAKEFLAGS", "")) + f" -j{max(os.cpu_count()-1, 1)}" + +def compute_version() -> str: + """This function generates the flexflow package version according to the following rules: + 1. If the python/flexflow/version.txt file exists, return the version from the file. + 2. If the version.txt file does not exist, the version will be YY.MM., + where the YY are the last two digits of the year, MM is the month number, + and is a counter that is reset at the beginning of every month, + and it is incremented every time we publish a new version on pypi (or test.pypi, + if the DEPLOY_TO_TEST_PYPI env is defined and set to true). + Using this index (instead of the day of the month) for the sub-subversion, allows + us to release more than once per day when needed. + + Warning! If the latest flexflow package version in test.pypi goes out of sync with pypi, this + script will publish the wrong version if it is used to deploy to both test.pypi and pypi without + deleting the version.txt file in-between the two uploads. + + :raises ValueError: if the python/flexflow/version.txt file exists, but contains a version in the wrong format + :raises ValueError: if the DEPLOY_TO_TEST_PYPI env is set to a value that cannot be converted to a Python boolean + :raises ValueError: if a flexflow release exists on pypi (or test.pypi) whose last two digits of the year are + larger than the last two digits of the current year (e.g., if it's year '23, + and we find a release from year '24) + :return: The version in YY.MM. format, as a string + :rtype: str + """ + # Check if the version has already been determined before, in which case we don't recompute it + version_file = os.path.join( + os.path.dirname(os.path.abspath(__file__)), "python", "flexflow", "version.txt" + ) + if os.path.isfile(version_file): + with open(version_file) as f: + version = f.read() + # Version is YY.mm. + match = re.fullmatch(r'\d+\.\d+\.\d+', version) + if not match: + raise ValueError("Version is not in the right format!") + return version + + # Get latest version of FlexFlow on pypi (default) or test.pypi (if the DEPLOY_TO_TEST_PYPI env is set to true) + deploy_to_test_pypi = os.environ.get('DEPLOY_TO_TEST_PYPI', 'false') + if deploy_to_test_pypi.lower() in ['true', 'yes', '1']: + deploy_to_test_pypi = True + pypi_url = "https://test.pypi.org/pypi/flexflow/json" + elif deploy_to_test_pypi.lower() in ['false', 'no', '0']: + deploy_to_test_pypi = False + pypi_url = "https://pypi.org/pypi/flexflow/json" + else: + raise ValueError(f'Invalid boolean value: {deploy_to_test_pypi}') + try: + pip_version = requests.get(pypi_url).json()['info']['version'] + except KeyError: + pip_version = "0.0.0" + pip_year, pip_month, pip_incremental = [int(x) for x in pip_version.split(".")] + + today = date.today() + year_two_digits = int(str(today.year)[-2:]) + + # Ensure no version from the distant past or the future :) + if pip_year > year_two_digits or (pip_year == year_two_digits and pip_month > today.month): + raise ValueError(f"A version from the distant past or future (year '{pip_year}, month {pip_month}) already exists!") + + subversion = 0 + if pip_year == year_two_digits and pip_month == today.month: + subversion = pip_incremental + 1 + + version = f"{year_two_digits}.{today.month}.{subversion}" + # Add version to file + with open(version_file, 'w+') as f: + f.write(version) + + return version + +# Create description from README +long_description = (Path(__file__).parent / "README.md").read_text() + +# Create requirements list from requirements.txt +with open(Path(__file__).parent / "requirements.txt", "r") as reqs_file: + requirements = reqs_file.read().strip().split("\n") + +# Install Rust if not yet available +try: + # Attempt to run a Rust command to check if Rust is installed + subprocess.check_output(['cargo', '--version']) +except FileNotFoundError: + print("Rust/Cargo not found, installing it...") + # Rust is not installed, so install it using rustup + try: + subprocess.run("curl https://sh.rustup.rs -sSf | sh -s -- -y", shell=True, check=True) + print("Rust and Cargo installed successfully.") + except subprocess.CalledProcessError as e: + print(f"Error: {e}") + # Add the cargo binary directory to the PATH + os.environ["PATH"] = f"{os.path.join(os.environ.get('HOME', '/root'), '.cargo', 'bin')}:{os.environ.get('PATH', '')}" + setup( name="flexflow", - version="1.0", - description="FlexFlow Python package", + version=compute_version(), + description="A distributed deep learning framework that supports flexible parallelization strategies.", + long_description=long_description, + long_description_content_type="text/markdown", url="https://github.com/flexflow/FlexFlow", + project_urls={ + "Homepage": "https://flexflow.ai/", + "Documentation": "https://flexflow.readthedocs.io/en/latest/", + }, license="Apache", packages=find_packages("python"), package_dir={"": "python"}, package_data={"flexflow": files}, zip_safe=False, - install_requires=[ - "numpy>=1.16", - "cffi>=1.11", - "qualname>=0.1", - "keras_preprocessing", - "Pillow", - "cmake-build-extension", - "pybind11", - "ninja", - ], + install_requires=requirements, scripts=['python/flexflow/flexflow_python'], ext_modules=[ CMakeExtension( @@ -50,9 +141,14 @@ cmdclass={"build_ext": BuildExtension}, classifiers=[ "Programming Language :: Python :: 3.6", + "Programming Language :: Python :: 3.7", + "Programming Language :: Python :: 3.8", + "Programming Language :: Python :: 3.9", + "Programming Language :: Python :: 3.10", + "Programming Language :: Python :: 3.11", "License :: OSI Approved :: Apache Software License", "Operating System :: POSIX :: Linux", - "Topic :: Software Development :: Libraries", + "Topic :: Scientific/Engineering :: Artificial Intelligence", ], python_requires=">=3.6", ) diff --git a/src/c/flexflow_c.cc b/src/c/flexflow_c.cc index 1d8634f224..3fcebedfba 100644 --- a/src/c/flexflow_c.cc +++ b/src/c/flexflow_c.cc @@ -16,6 +16,8 @@ #include "flexflow/flexflow_c.h" #include "flexflow/dataloader.h" #include "flexflow/mapper.h" +#include "flexflow/request_manager.h" +#include "flexflow/utils/file_loader.h" using namespace Legion; using namespace FlexFlow; @@ -55,6 +57,16 @@ class FFCObjectWrapper { FF_NEW_OPAQUE_WRAPPER(flexflow_net_config_t, NetConfig *); FF_NEW_OPAQUE_WRAPPER(flexflow_dlrm_config_t, DLRMConfig *); FF_NEW_OPAQUE_WRAPPER(flexflow_single_dataloader_t, SingleDataLoader *); + // inference + FF_NEW_OPAQUE_WRAPPER(flexflow_batch_config_t, BatchConfig *); + FF_NEW_OPAQUE_WRAPPER(flexflow_tree_verify_batch_config_t, + TreeVerifyBatchConfig *); + FF_NEW_OPAQUE_WRAPPER(flexflow_beam_search_batch_config_t, + BeamSearchBatchConfig *); + FF_NEW_OPAQUE_WRAPPER(flexflow_inference_manager_t, InferenceManager *); + FF_NEW_OPAQUE_WRAPPER(flexflow_request_manager_t, RequestManager *); + FF_NEW_OPAQUE_WRAPPER(flexflow_file_data_loader_t, FileDataLoader *); + FF_NEW_OPAQUE_WRAPPER(flexflow_generation_result_t, GenerationResult *); }; Logger ffc_log("flexflow_c"); @@ -121,18 +133,56 @@ bool flexflow_config_get_enable_control_replication(flexflow_config_t handle_) { return handle->enable_control_replication; } +int flexflow_config_get_data_parallelism_degree(flexflow_config_t handle_) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + return handle->data_parallelism_degree; +} + +int flexflow_config_get_tensor_parallelism_degree(flexflow_config_t handle_) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + return handle->tensor_parallelism_degree; +} + +int flexflow_config_get_pipeline_parallelism_degree(flexflow_config_t handle_) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + return handle->pipeline_parallelism_degree; +} + +void flexflow_config_set_data_parallelism_degree(flexflow_config_t handle_, + int value) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + handle->data_parallelism_degree = value; +} + +void flexflow_config_set_tensor_parallelism_degree(flexflow_config_t handle_, + int value) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + handle->tensor_parallelism_degree = value; +} + +void flexflow_config_set_pipeline_parallelism_degree(flexflow_config_t handle_, + int value) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + handle->pipeline_parallelism_degree = value; +} + int flexflow_config_get_python_data_loader_type(flexflow_config_t handle_) { FFConfig *handle = FFCObjectWrapper::unwrap(handle_); return handle->python_data_loader_type; } +bool flexflow_config_get_offload(flexflow_config_t handle_) { + FFConfig *handle = FFCObjectWrapper::unwrap(handle_); + return handle->cpu_offload; +} // ----------------------------------------------------------------------- // FFModel // ----------------------------------------------------------------------- -flexflow_model_t flexflow_model_create(flexflow_config_t config_) { +flexflow_model_t flexflow_model_create(flexflow_config_t config_, + bool cpu_offload) { FFConfig *config = FFCObjectWrapper::unwrap(config_); - FFModel *model = new FFModel(*config); + FFModel *model = new FFModel(*config, cpu_offload); DEBUG_PRINT("[FFModel] new %p", model); return FFCObjectWrapper::wrap(model); } @@ -461,9 +511,10 @@ flexflow_tensor_t flexflow_tensor_t flexflow_model_add_embedding(flexflow_model_t handle_, const flexflow_tensor_t input_, - int num_entires, + int num_entries, int out_dim, enum AggrMode aggr, + DataType dtype, flexflow_op_t shared_op_, flexflow_initializer_t kernel_initializer_, char const *name) { @@ -475,20 +526,21 @@ flexflow_tensor_t // TODO: update the flexflow_c and Python API to support other data types // Currently we assume it's float Tensor tensor = handle->embedding(input, - num_entires, + num_entries, out_dim, aggr, - DT_FLOAT, + dtype, shared_op, kernel_initializer, name); - DEBUG_PRINT("[Embedding] new Tensor %p, input %p, num_entires %d, out_dim " - "%d, aggr %d, shared_op %p, kernel_init %p, name %s", + DEBUG_PRINT("[Embedding] new Tensor %p, input %p, num_entries %d, out_dim " + "%d, aggr %d, dtype %d, shared_op %p, kernel_init %p, name %s", tensor, input, - num_entires, + num_entries, out_dim, aggr, + dtype, shared_op, kernel_initializer, name); @@ -566,6 +618,7 @@ flexflow_tensor_t flexflow_model_add_layer_norm(flexflow_model_t handle_, int *axes, bool elementwise_affine, float eps, + bool use_bias, char const *name) { FFModel *handle = FFCObjectWrapper::unwrap(handle_); const Tensor input = FFCObjectWrapper::unwrap(input_); @@ -573,8 +626,13 @@ flexflow_tensor_t flexflow_model_add_layer_norm(flexflow_model_t handle_, for (int i = 0; i < n; i++) { axes_vec.push_back(axes[i]); } - Tensor tensor = handle->layer_norm( - input, axes_vec, elementwise_affine, eps, input->data_type, name); + Tensor tensor = handle->layer_norm(input, + axes_vec, + elementwise_affine, + eps, + use_bias, + input->data_type, + name); DEBUG_PRINT("[LayerNorm] new Tensor %p, input %p, elementwise_affine %d, eps " "%f, name %s", tensor, @@ -585,6 +643,130 @@ flexflow_tensor_t flexflow_model_add_layer_norm(flexflow_model_t handle_, return FFCObjectWrapper::wrap(tensor); } +flexflow_tensor_t * + flexflow_model_add_residual_layer_norm(flexflow_model_t handle_, + const flexflow_tensor_t input_, + const flexflow_tensor_t residual1_, + const flexflow_tensor_t residual2_, + bool use_two_residuals, + int n, + int *axes, + bool elementwise_affine, + float eps, + bool use_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + const Tensor input = FFCObjectWrapper::unwrap(input_); + const Tensor residual1 = FFCObjectWrapper::unwrap(residual1_); + const Tensor residual2 = + use_two_residuals ? FFCObjectWrapper::unwrap(residual2_) : nullptr; + Tensor tensor_outputs[2]; + std::vector axes_vec; + for (int i = 0; i < n; i++) { + axes_vec.push_back(axes[i]); + } + if (use_two_residuals) { + assert(residual2 != nullptr); + } + handle->residual_layer_norm(input, + residual1, + residual2, + tensor_outputs, + use_two_residuals, + axes_vec, + elementwise_affine, + eps, + use_bias, + input->data_type, + name); + assert(tensor_outputs[0] != nullptr); + assert(tensor_outputs[1] != nullptr); + DEBUG_PRINT("[ResidualLayerNorm] input %p, residual1 %p, residual2 " + "%p, output0: %p, " + "output1: %p, use_two_residuals: %d, elementwise_affine %d, eps " + "%f, use_bias: %d, name %s", + input, + residual1, + residual2, + tensor_outputs[0], + tensor_outputs[1], + use_two_residuals, + elementwise_affine, + eps, + use_bias, + name); + flexflow_tensor_t *tensor_outputs_wrapped = + (flexflow_tensor_t *)calloc(2, sizeof(flexflow_tensor_t)); + tensor_outputs_wrapped[0] = FFCObjectWrapper::wrap(tensor_outputs[0]); + tensor_outputs_wrapped[1] = FFCObjectWrapper::wrap(tensor_outputs[1]); + return tensor_outputs_wrapped; +} + +flexflow_tensor_t *flexflow_model_add_add_bias_residual_layer_norm( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + const flexflow_tensor_t residual_, + int n, + int *axes, + bool elementwise_affine, + float eps, + bool use_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + const Tensor input = FFCObjectWrapper::unwrap(input_); + const Tensor residual = FFCObjectWrapper::unwrap(residual_); + Tensor tensor_outputs[2]; + std::vector axes_vec; + for (int i = 0; i < n; i++) { + axes_vec.push_back(axes[i]); + } + handle->add_bias_residual_layer_norm(input, + residual, + tensor_outputs, + axes_vec, + elementwise_affine, + eps, + use_bias, + input->data_type, + name); + assert(tensor_outputs[0] != nullptr); + assert(tensor_outputs[1] != nullptr); + DEBUG_PRINT("[AddBiasResidualLayerNorm] input %p, residual %p, output0: %p, " + "output1: %p, elementwise_affine %d, eps " + "%f, use_bias %d, name %s", + input, + residual, + tensor_outputs[0], + tensor_outputs[1], + elementwise_affine, + eps, + use_bias, + name); + flexflow_tensor_t *tensor_outputs_wrapped = + (flexflow_tensor_t *)calloc(2, sizeof(flexflow_tensor_t)); + tensor_outputs_wrapped[0] = FFCObjectWrapper::wrap(tensor_outputs[0]); + tensor_outputs_wrapped[1] = FFCObjectWrapper::wrap(tensor_outputs[1]); + return tensor_outputs_wrapped; +} + +flexflow_tensor_t + flexflow_model_add_sigmoid_silu_multi(flexflow_model_t handle_, + const flexflow_tensor_t input1_, + const flexflow_tensor_t input2_, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + const Tensor input1 = FFCObjectWrapper::unwrap(input1_); + const Tensor input2 = FFCObjectWrapper::unwrap(input2_); + Tensor tensor = + handle->sigmoid_silu_multi(input1, input2, input1->data_type, name); + DEBUG_PRINT("[SigmoidSiluMulti] new Tensor %p, input1 %p, input2 %p, name %s", + tensor, + input1, + input2, + name); + return FFCObjectWrapper::wrap(tensor); +} + flexflow_tensor_t flexflow_model_add_batch_matmul(flexflow_model_t handle_, const flexflow_tensor_t a_, const flexflow_tensor_t b_, @@ -743,7 +925,7 @@ flexflow_tensor_t flexflow_model_add_softmax(flexflow_model_t handle_, char const *name) { FFModel *handle = FFCObjectWrapper::unwrap(handle_); Tensor input = FFCObjectWrapper::unwrap(input_); - Tensor tensor = handle->softmax(input, dim, last_layer, name); + Tensor tensor = handle->softmax(input, dim, input->data_type, last_layer, name); DEBUG_PRINT( "[Softmax] new Tensor %p, input %p, name %s", tensor, input, name); return FFCObjectWrapper::wrap(tensor); @@ -985,6 +1167,7 @@ flexflow_tensor_t flexflow_model_add_multihead_attention( bias, add_bias_kv, add_zero_attn, + query->data_type, kernel_initializer, name); DEBUG_PRINT("[MultiHeadAttention] new Tensor %p, query %p, key %p, value %p, " @@ -1007,6 +1190,351 @@ flexflow_tensor_t flexflow_model_add_multihead_attention( return FFCObjectWrapper::wrap(tensor); } +flexflow_tensor_t flexflow_model_add_inc_multihead_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = handle->inc_multihead_self_attention(input, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_spec_inc_multihead_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = + handle->spec_inc_multihead_self_attention(input, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_inc_multihead_self_attention_verify( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = + handle->inc_multihead_self_attention_verify(input, + embed_dim, + num_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_inc_multiquery_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = handle->inc_multiquery_self_attention(input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_spec_inc_multiquery_self_attention( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = + handle->spec_inc_multiquery_self_attention(input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_inc_multiquery_self_attention_verify( + flexflow_model_t handle_, + const flexflow_tensor_t input_, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool bias, + bool add_bias_kv, + bool add_zero_attn, + enum DataType data_type, + flexflow_initializer_t kernel_initializer_, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Initializer *kernel_initializer = + FFCObjectWrapper::unwrap(kernel_initializer_); + Tensor tensor = + handle->inc_multiquery_self_attention_verify(input, + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + bias, + add_bias_kv, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_rms_norm(flexflow_model_t handle_, + const flexflow_tensor_t input_, + float eps, + int dim, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Tensor tensor = handle->rms_norm(input, eps, dim, input->data_type, name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t * + flexflow_model_add_residual_rms_norm(flexflow_model_t handle_, + const flexflow_tensor_t input1_, + const flexflow_tensor_t input2_, + float eps, + int dim, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input1 = FFCObjectWrapper::unwrap(input1_); + Tensor input2 = FFCObjectWrapper::unwrap(input2_); + Tensor tensor_outputs[2]; + handle->residual_rms_norm( + input1, input2, tensor_outputs, eps, dim, input1->data_type, name); + assert(tensor_outputs[0] != nullptr); + assert(tensor_outputs[1] != nullptr); + flexflow_tensor_t *tensor_outputs_wrapped = + (flexflow_tensor_t *)calloc(2, sizeof(flexflow_tensor_t)); + tensor_outputs_wrapped[0] = FFCObjectWrapper::wrap(tensor_outputs[0]); + tensor_outputs_wrapped[1] = FFCObjectWrapper::wrap(tensor_outputs[1]); + return tensor_outputs_wrapped; +} + +flexflow_tensor_t flexflow_model_add_arg_top_k(flexflow_model_t handle_, + const flexflow_tensor_t input_, + int k, + bool sorted, + bool speculative_decoding, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Tensor tensor = + handle->arg_top_k(input, k, sorted, speculative_decoding, name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_beam_top_k(flexflow_model_t handle_, + const flexflow_tensor_t input_, + int max_beam_size, + bool sorted, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Tensor tensor = handle->beam_top_k(input, max_beam_size, sorted, name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_sampling(flexflow_model_t handle_, + const flexflow_tensor_t input_, + float top_p, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Tensor tensor = handle->sampling(input, top_p, name); + return FFCObjectWrapper::wrap(tensor); +} + +flexflow_tensor_t flexflow_model_add_argmax(flexflow_model_t handle_, + const flexflow_tensor_t input_, + bool beam_search, + char const *name) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + Tensor input = FFCObjectWrapper::unwrap(input_); + Tensor tensor = handle->argmax(input, beam_search, name); + return FFCObjectWrapper::wrap(tensor); +} + void flexflow_model_set_sgd_optimizer(flexflow_model_t handle_, flexflow_sgd_optimizer_t optimizer_) { FFModel *handle = FFCObjectWrapper::unwrap(handle_); @@ -1055,6 +1583,54 @@ flexflow_perf_metrics_t return FFCObjectWrapper::wrap(perf_metrics); } +void flexflow_model_set_transformer_layer_id(flexflow_model_t handle_, int id) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_transformer_layer_id(id); +} + +void flexflow_model_generate(flexflow_model_t handle_, + int num_requests, + char const **input_texts, + int max_num_chars, + char **output_texts, + int max_seq_length, + int **output_length_and_tokens) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + std::vector prompts; + for (int i = 0; i < num_requests; i++) { + std::string const text_str(input_texts[i]); + prompts.push_back(text_str); + DEBUG_PRINT("[Model] generate[%d] %p %s %i", + i, + handle, + text_str.c_str(), + max_seq_length); + } + std::vector results = + handle->generate(prompts, max_seq_length); + // If the prompt exceeds max seq len, check that we return the prompt with no + // additional token. Otherwise, check that the output does not exceed the max + // sequence length. + for (int i = 0; i < num_requests; i++) { + assert(results[i].output_tokens.size() <= max_seq_length || + results[i].output_tokens.size() == results[i].input_tokens.size()); + output_length_and_tokens[i][0] = results[i].output_tokens.size(); + std::copy(results[i].output_tokens.begin(), + results[i].output_tokens.end(), + output_length_and_tokens[i] + 1); + std::memcpy(output_texts[i], + results[i].output_text.c_str(), + results[i].output_text.length()); + } + // return FFCObjectWrapper::wrap(&results[0]); +} + +void flexflow_model_set_position_offset(flexflow_model_t handle_, + int const offset) { + FFModel *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_position_offset(offset); +} + // ----------------------------------------------------------------------- // Tensor // ----------------------------------------------------------------------- @@ -1934,3 +2510,229 @@ void flexflow_perform_registration(void) { Runtime::perform_registration_callback(FFMapper::update_mappers, true /*global*/); } + +// ----------------------------------------------------------------------- +// BatchConfig +// ----------------------------------------------------------------------- + +flexflow_batch_config_t flexflow_batch_config_create(void) { + BatchConfig *config = new BatchConfig(); + DEBUG_PRINT("[BatchConfig] new %p", config); + return FFCObjectWrapper::wrap(config); +} + +void flexflow_batch_config_destroy(flexflow_batch_config_t handle_) { + BatchConfig *handle = FFCObjectWrapper::unwrap(handle_); + DEBUG_PRINT("[BatchConfig] delete %p", handle); + delete handle; +} + +// ----------------------------------------------------------------------- +// TreeVerifyBatchConfig +// ----------------------------------------------------------------------- + +flexflow_tree_verify_batch_config_t + flexflow_tree_verify_batch_config_create(void) { + TreeVerifyBatchConfig *config = new TreeVerifyBatchConfig(); + DEBUG_PRINT("[TreeVerifyBatchConfig] new %p", config); + return FFCObjectWrapper::wrap(config); +} + +void flexflow_tree_verify_batch_config_destroy( + flexflow_tree_verify_batch_config_t handle_) { + TreeVerifyBatchConfig *handle = FFCObjectWrapper::unwrap(handle_); + DEBUG_PRINT("[TreeVerifyBatchConfig] delete %p", handle); + delete handle; +} + +// ----------------------------------------------------------------------- +// BeamSearchBatchConfig +// ----------------------------------------------------------------------- + +flexflow_beam_search_batch_config_t + flexflow_beam_search_batch_config_create(void) { + BeamSearchBatchConfig *config = new BeamSearchBatchConfig(); + DEBUG_PRINT("[BeamSearchBatchConfig] new %p", config); + return FFCObjectWrapper::wrap(config); +} + +void flexflow_beam_search_batch_config_destroy( + flexflow_beam_search_batch_config_t handle_) { + BeamSearchBatchConfig *handle = FFCObjectWrapper::unwrap(handle_); + DEBUG_PRINT("[BeamSearchBatchConfig] delete %p", handle); + delete handle; +} + +// ----------------------------------------------------------------------- +// RequestManager +// ----------------------------------------------------------------------- + +flexflow_request_manager_t flexflow_request_manager_get_request_manager(void) { + RequestManager *rm = RequestManager::get_request_manager(); + DEBUG_PRINT("[RequestManager] get %p", rm); + return FFCObjectWrapper::wrap(rm); +} + +void flexflow_request_manager_set_max_requests_per_batch( + flexflow_request_manager_t handle_, int max_num_requests) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_max_requests_per_batch(max_num_requests); + DEBUG_PRINT("[RequestManager] set max_requests_per_batch %d", + max_num_requests); +} + +void flexflow_request_manager_set_max_tokens_per_batch( + flexflow_request_manager_t handle_, int max_num_tokens) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_max_tokens_per_batch(max_num_tokens); + DEBUG_PRINT("[RequestManager] set max_tokens_per_batch %d", max_num_tokens); +} + +void flexflow_request_manager_set_max_spec_tree_token_num( + flexflow_request_manager_t handle_, int max_num_tokens) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_max_spec_tree_token_num(max_num_tokens); + DEBUG_PRINT("[RequestManager] set max_spec_tree_token_num %d", + max_num_tokens); +} + +void flexflow_request_manager_set_max_sequence_length( + flexflow_request_manager_t handle_, int max_seq_length) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + handle->set_max_sequence_length(max_seq_length); + DEBUG_PRINT("[RequestManager] set max_sequence_length %d", max_seq_length); +} + +void flexflow_request_manager_register_tokenizer( + flexflow_request_manager_t handle_, + enum ModelType model_type, + int bos_token_id, + int eos_token_id, + char const *tokenizer_filepath) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + assert(tokenizer_filepath != nullptr && + "Cannot convert nullptr char * to std::string"); + std::string const tokenizer_filepath_str(tokenizer_filepath); + handle->register_tokenizer( + model_type, bos_token_id, eos_token_id, tokenizer_filepath_str); + DEBUG_PRINT( + "[RequestManager] register tokenizer %p %s", handle, tokenizer_filepath); +} + +void flexflow_request_manager_register_output_filepath( + flexflow_request_manager_t handle_, char const *output_filepath) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + assert(output_filepath != nullptr && + "Cannot convert nullptr char * to std::string"); + std::string const output_filepath_str(output_filepath); + handle->register_output_filepath(output_filepath_str); + DEBUG_PRINT("[RequestManager] register output filepath %p %s", + handle, + output_filepath); +} + +int flexflow_request_manager_register_ssm_model( + flexflow_request_manager_t handle_, flexflow_model_t model_handle_) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model_handle = FFCObjectWrapper::unwrap(model_handle_); + DEBUG_PRINT("[RequestManager] register ssm %p %p", handle, model_handle); + return handle->register_ssm_model(model_handle); +} + +void flexflow_request_manager_start_background_server( + flexflow_request_manager_t handle_, flexflow_model_t model_handle_) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model_handle = FFCObjectWrapper::unwrap(model_handle_); + DEBUG_PRINT( + "[RequestManager] start background server %p %p", handle, model_handle); + handle->start_background_server(model_handle); +} + +void flexflow_request_manager_terminate_background_server( + flexflow_request_manager_t handle_) { + RequestManager *handle = FFCObjectWrapper::unwrap(handle_); + DEBUG_PRINT("[RequestManager] terminate background server %p", handle); + handle->terminate_background_server(); +} + +// ----------------------------------------------------------------------- +// InferenceManager +// ----------------------------------------------------------------------- + +flexflow_inference_manager_t + flexflow_inference_manager_get_inference_manager() { + InferenceManager *im = InferenceManager::get_inference_manager(); + DEBUG_PRINT("[InferenceManager] get %p", im); + return FFCObjectWrapper::wrap(im); +} + +void flexflow_inference_manager_compile_model_and_allocate_buffer( + flexflow_inference_manager_t handle_, flexflow_model_t model_handle) { + InferenceManager *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model = FFCObjectWrapper::unwrap(model_handle); + DEBUG_PRINT("[InferenceManager] compile_model_and_allocate_buffer %p", + handle); + handle->compile_model_and_allocate_buffer(model); +} + +void flexflow_inference_manager_init_operators_inference( + flexflow_inference_manager_t handle_, flexflow_model_t model_handle) { + InferenceManager *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model = FFCObjectWrapper::unwrap(model_handle); + DEBUG_PRINT("[InferenceManager] init_operators_inference %p", handle); + handle->init_operators_inference(model); +} + +void flexflow_inference_manager_register_model_weights_loader( + flexflow_inference_manager_t handle_, + flexflow_model_t model_handle, + flexflow_file_data_loader_t loader_handle) { + InferenceManager *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model = FFCObjectWrapper::unwrap(model_handle); + FileDataLoader *loader = FFCObjectWrapper::unwrap(loader_handle); + DEBUG_PRINT("[InferenceManager] register_model_weights_loader %p %p %p", + handle, + model, + loader); + handle->register_model_weights_loader(model, loader); +} + +// ----------------------------------------------------------------------- +// FileDataLoader +// ----------------------------------------------------------------------- + +flexflow_file_data_loader_t + flexflow_file_data_loader_create(char const *weight_file_path, + int num_q_heads, + int num_kv_heads, + int hidden_dim, + int qkv_inner_dim, + int tensor_parallelism_degree, + bool use_full_precision) { + assert(weight_file_path != nullptr && + "Cannot convert nullptr char * to std::string"); + std::string const weight_file_path_str(weight_file_path); + FileDataLoader *handle = new FileDataLoader("", + weight_file_path_str, + num_q_heads, + num_kv_heads, + hidden_dim, + qkv_inner_dim, + tensor_parallelism_degree, + use_full_precision); + DEBUG_PRINT("[FileDataLoader] new %p", handle); + return FFCObjectWrapper::wrap(handle); +} + +void flexflow_file_data_loader_destroy(flexflow_file_data_loader_t handle_) { + FileDataLoader *handle = FFCObjectWrapper::unwrap(handle_); + DEBUG_PRINT("[FileDataLoader] delete %p", handle); + delete handle; +} + +void flexflow_file_data_loader_load_weights(flexflow_file_data_loader_t handle_, + flexflow_model_t model_handle_) { + FileDataLoader *handle = FFCObjectWrapper::unwrap(handle_); + FFModel *model = FFCObjectWrapper::unwrap(model_handle_); + handle->load_weights(model); +} diff --git a/src/mapper/mapper.cc b/src/mapper/mapper.cc index 643435f207..c293aecb19 100644 --- a/src/mapper/mapper.cc +++ b/src/mapper/mapper.cc @@ -283,6 +283,14 @@ void FFMapper::select_task_options(const MapperContext ctx, output.initial_proc = all_cpus[0]; return; } + if ((task.task_id == RM_PREPARE_NEXT_BATCH_TASK_ID) || + (task.task_id == RM_PREPARE_NEXT_BATCH_INIT_TASK_ID) || + (task.task_id == RM_PREPARE_NEXT_BATCH_BEAM_TASK_ID) || + (task.task_id == RM_PREPARE_NEXT_BATCH_VERIFY_TASK_ID) || + (task.task_id == RM_BACKGROUND_SERVING_TASK_ID)) { + output.initial_proc = all_cpus[0]; + return; + } if (task.task_id == TOP_LEVEL_TASK_ID) { output.initial_proc = all_cpus[0]; // control replicate top level task @@ -349,6 +357,11 @@ void FFMapper::select_task_options(const MapperContext ctx, } } + if (task.task_id == TENSOR_EQUAL_TASK_ID) { + output.initial_proc = all_cpus[0]; + return; + } + // Assert that all single tasks should be handled and returned before // So task must be an indextask if (!task.is_index_space) { @@ -474,6 +487,25 @@ void FFMapper::premap_task(const MapperContext ctx, assert(false); } +std::string humanReadableSize(size_t size, bool mb = false) { + assert(size >= 0); + char const *units[] = {"B", "KiB", "MiB", "GiB", "TiB"}; + int i = 0; + double finalSize = size; + if (mb) { + finalSize /= 1024 * 1024; + i = 2; + } else { + while (finalSize >= 1024 && i < 4) { + finalSize /= 1024; + i++; + } + } + char buffer[256]; + snprintf(buffer, sizeof(buffer), "%.2lf %s", finalSize, units[i]); + return std::string(buffer); +} + void FFMapper::map_task(const MapperContext ctx, Task const &task, MapTaskInput const &input, @@ -488,7 +520,9 @@ void FFMapper::map_task(const MapperContext ctx, output.task_priority = 0; output.postmap_task = false; if (task.target_proc.address_space() != node_id) { - assert(false); + if (enable_control_replication) { + assert(false); + } output.target_procs.push_back(task.target_proc); } else if (task.target_proc.kind() == Processor::TOC_PROC) { output.target_procs.push_back(task.target_proc); @@ -622,16 +656,19 @@ void FFMapper::map_task(const MapperContext ctx, } // Report failed to creation log_ff_mapper.error( - "FlexFlow failed allocation of size %zd bytes for " - "region requirement %d of task %s (UID %lld) in memory " IDFMT - " with kind %d for processor " IDFMT ".", - footprint, + "Out of memory! FlexFlow failed to reserve block of size %s" + " for region requirement %d of task %s (UID %lld) in %s memory (id: " + "%llx)" + " for processor id: %llx." + " Total pre-allocated memory capacity of this kind: %s.", + humanReadableSize(footprint).c_str(), idx, task.get_task_name(), task.get_unique_id(), + Legion::Mapping::Utilities::to_string(target_mem.kind()), target_mem.id, - target_mem.kind(), - task.target_proc.id); + task.target_proc.id, + humanReadableSize(target_mem.capacity(), true).c_str()); assert(false); } else { output.chosen_instances[idx].push_back(result); @@ -648,44 +685,37 @@ void FFMapper::map_task(const MapperContext ctx, } // for idx } -void FFMapper::map_replicate_task(const MapperContext ctx, - Task const &task, - MapTaskInput const &input, - MapTaskOutput const &default_output, - MapReplicateTaskOutput &output) { +void FFMapper::replicate_task(const MapperContext ctx, + Task const &task, + ReplicateTaskInput const &input, + ReplicateTaskOutput &output) { // Should only be replicated for the top-level task assert((task.get_depth() == 0) && (task.regions.size() == 0)); const Processor::Kind target_kind = task.target_proc.kind(); - VariantID chosen_variant; + VariantID vid; { std::vector variant_ids; - runtime->find_valid_variants( - ctx, task.task_id, variant_ids, task.target_proc.kind()); + runtime->find_valid_variants(ctx, task.task_id, variant_ids, target_kind); // Currently assume there is exactly one variant assert(variant_ids.size() == 1); - chosen_variant = variant_ids[0]; + output.chosen_variant = variant_ids[0]; } - std::vector const &all_procs = all_procs_by_kind(target_kind); - // Place on replicate on each node by default - output.task_mappings.resize(total_nodes, default_output); - // Assume default_output does not include any target_procs - assert(default_output.target_procs.size() == 0); - for (std::vector::const_iterator it = all_procs.begin(); - it != all_procs.end(); + output.target_processors.resize(total_nodes); + std::vector handled(total_nodes, false); + size_t count = 0; + Machine::ProcessorQuery procs(machine); + procs.only_kind(target_kind); + for (Machine::ProcessorQuery::iterator it = procs.begin(); it != procs.end(); it++) { - AddressSpace space = it->address_space(); - assert(space < output.task_mappings.size()); - // Add *it as a target_proc if we haven't found one - if (output.task_mappings[space].target_procs.size() == 0) { - output.task_mappings[space].target_procs.push_back(*it); + const AddressSpace space = it->address_space(); + if (handled[space]) { + continue; } + output.target_processors[space] = *it; + handled[space] = true; + count++; } - output.control_replication_map.resize(total_nodes); - for (int idx = 0; idx < total_nodes; idx++) { - output.task_mappings[idx].chosen_variant = chosen_variant; - output.control_replication_map[idx] = - output.task_mappings[idx].target_procs[0]; - } + assert(count == total_nodes); } void FFMapper::select_task_variant(const MapperContext ctx, @@ -921,14 +951,17 @@ void FFMapper::map_inline(const MapperContext ctx, created, &footprint)) { log_ff_mapper.error( - "FlexFlow Mapper failed allocation of size %zd bytes" - " for region requirement of inline ammping in task %s (UID %lld)" - " in memory " IDFMT "for processor " IDFMT ".", - footprint, + "Out of memory! FlexFlow failed to reserve block of size %s" + " for region requirement of inline mapping in task %s (UID %lld)" + " in %s memory (id: %llx) for processor id: %llx." + " Total pre-allocated memory capacity of this kind: %s.", + humanReadableSize(footprint).c_str(), inline_op.parent_task->get_task_name(), inline_op.parent_task->get_unique_id(), + Legion::Mapping::Utilities::to_string(target_memory.kind()), target_memory.id, - inline_op.parent_task->current_proc.id); + inline_op.parent_task->current_proc.id, + humanReadableSize(target_memory.capacity(), true).c_str()); assert(false); } else { output.chosen_instances.push_back(result); diff --git a/src/ops/add_bias_residual_layer_norm.cc b/src/ops/add_bias_residual_layer_norm.cc new file mode 100644 index 0000000000..e670380901 --- /dev/null +++ b/src/ops/add_bias_residual_layer_norm.cc @@ -0,0 +1,824 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/add_bias_residual_layer_norm.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; + +bool operator==(AddBiasResidualLayerNormParams const &lhs, + AddBiasResidualLayerNormParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.axes == rhs.axes && + lhs.elementwise_affine == rhs.elementwise_affine && + lhs.use_bias == rhs.use_bias; +} + +bool AddBiasResidualLayerNormParams::is_valid( + std::pair const &input) const { + return input.first.is_valid() && input.second.is_valid(); +} + +AddBiasResidualLayerNormParams AddBiasResidualLayerNorm::get_params() const { + AddBiasResidualLayerNormParams params; + params.layer_guid = this->layer_guid; + params.axes = this->axes; + params.elementwise_affine = this->elementwise_affine; + params.eps = this->eps; + params.use_bias = this->use_bias; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +void FFModel::add_bias_residual_layer_norm(const Tensor input, + const Tensor residual, + Tensor *outputs, + std::vector const &axes, + bool elementwise_affine, + float eps, + bool use_bias, + DataType data_type, + char const *name) { + // In PyTorch, axes must be the sizes of the last axes.size() dimensions of + // the input tensor. However, since the tensor dimensions are reversed in + // FlexFlow (batch size is the last dimension), we require that axes must be + // the sizes of the FIRST axes.size() dimensions of the input tensor. + + // Another difference is that in PyTorch, the axes vector should contain the + // sizes of the dimensions with respect to which you want to compute the + // layernorm. In FlexFlow, instead, axes should contain the INDICES of the + // dimensions in question. We do this because the size of a dimension might be + // different when splitting a tensor in model parallelism. + assert( + axes.size() <= input->num_dims && + "number of axes must be less than tensor dimensions"); // input does not + // have replica + // dimension here + for (int i = 0; i < axes.size(); i++) { + assert(axes[i] == i && "axes must be the first axes.size() dimensions"); + } + + // Check dims + assert(input->num_dims == residual->num_dims); + for (int i = 0; i < input->num_dims; i++) { + assert(input->dims[i] == residual->dims[i]); + } + + if (data_type == DT_NONE) { + data_type = input->data_type; + } + int num_weights = + 1 + (elementwise_affine ? (use_bias ? 2 : 1) + : 0); // attention bias + layernorm weights + Layer *ln = nullptr; + Tensor casted_input = + (data_type != input->data_type) + ? cast(input, data_type, "type cast for add_bias_residual_layer_norm") + : input; + Tensor casted_residual = + (data_type != residual->data_type) + ? cast(residual, + data_type, + "type cast for add_bias_residual_layer_norm") + : residual; + ln = new Layer(this, + OP_ADD_BIAS_RESIDUAL_LAYERNORM, + data_type, + name, + 2 /*inputs*/, + num_weights, + 2 /*outputs*/, + casted_input, + residual); + // added: attn_output + final attention bias + residual. To be added to the + // output of FC2 + ln->outputs[0] = create_tensor_legion_ordering( + input->num_dims, input->dims, data_type, ln, 0, false /*create_grad*/); + // layer_norm(added) + ln->outputs[1] = create_tensor_legion_ordering( + input->num_dims, input->dims, data_type, ln, 1, false /*create_grad*/); + { + int numdims = axes.size(); + int dims[numdims]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[axes[i]]; + } + // Attention bias + int attn_bias_dims[1] = {dims[0]}; + ln->weights[0] = create_weight_legion_ordering(1, + attn_bias_dims, + data_type, + ln, + false /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + if (num_weights > 1) { + assert(elementwise_affine); + ln->weights[1] = create_weight_legion_ordering(numdims, + dims, + data_type, + ln, + false /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + if (num_weights == 3) { + assert(use_bias); + ln->weights[2] = create_weight_legion_ordering(numdims, + dims, + data_type, + ln, + false /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + } + } + } + ln->add_int_property("elementwise_affine", elementwise_affine); + ln->add_int_property("use_bias", use_bias); + ln->add_int_vector_property("axes", axes); + ln->add_float_property("eps", eps); + layers.push_back(ln); + outputs[0] = ln->outputs[0]; + outputs[1] = ln->outputs[1]; +} + +Op *AddBiasResidualLayerNorm::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("elementwise_affine", value); + bool elementwise_affine = (bool)value; + layer->get_int_property("use_bias", value); + bool use_bias = (bool)value; + std::vector axes; + layer->get_int_vector_property("axes", axes); + float eps; + layer->get_float_property("eps", eps); + return new AddBiasResidualLayerNorm(model, + layer->layer_guid, + inputs[0], + inputs[1], + axes, + elementwise_affine, + use_bias, + eps, + false, // allocate_weights + layer->name); +} + +AddBiasResidualLayerNorm::AddBiasResidualLayerNorm( + FFModel &model, + AddBiasResidualLayerNormParams const ¶ms, + std::pair const &inputs, + char const *name, + bool allocate_weights) + : AddBiasResidualLayerNorm(model, + params.layer_guid, + inputs.first, + inputs.second, + params.axes, + params.elementwise_affine, + params.use_bias, + params.eps, + allocate_weights, + params.name) {} + +AddBiasResidualLayerNorm::AddBiasResidualLayerNorm( + FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + const ParallelTensor _residual, + std::vector const &_axes, + bool _elementwise_affine, + bool _use_bias, + float _eps, + bool allocate_weights, + char const *name) + : Op(model, + OP_ADD_BIAS_RESIDUAL_LAYERNORM, + _input->data_type, + name, + 2 /*inputs*/, + 1 + (_elementwise_affine ? (_use_bias ? 2 : 1) : 0) /*weights*/, + 2 /*outputs*/, + _input, + _residual), + elementwise_affine(_elementwise_affine), eps(_eps), axes(_axes), + use_bias(_use_bias) { + // overwrite layer_guid + layer_guid = _layer_guid; + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, _input->dims, _input->data_type, this, 0 /*owner_idx*/); + outputs[1] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, _input->dims, _input->data_type, this, 1 /*owner_idx*/); + assert(check_output_input_weight_parallel_dims(allocate_weights)); + + int M = 1; + for (int i = 0; i < axes.size(); i++) { + M *= inputs[0]->dims[axes[i]].size; + } + int num_replicas = 1; + for (int i = 0; i < inputs[0]->num_dims; i++) { + if (inputs[0]->dims[i].is_replica_dim) { + num_replicas *= inputs[0]->dims[i].size; + } + } + effective_num_elements = M; + effective_batch_size = (inputs[0]->get_volume() / num_replicas) / M; + if (!elementwise_affine) { + assert(numWeights == 1); // attn bias + } else { + if (!use_bias) { + assert(numWeights == 2); // attn bias + weight + } else { + assert(numWeights == 3); // attn bias + weight + bias + } + } + + if (allocate_weights) { + // always need to allocate attn bias + ParallelTensorShape attention_bias_shape = _input->get_shape(); + for (int i = 1; i < attention_bias_shape.num_dims - 1; i++) { + attention_bias_shape.dims[i].size = 1; + } + + int seed = std::rand(); + Initializer *attn_bias_initializer = + new UniformInitializer(seed, 1.0f, 1.0f); + + weights[0] = model.create_parallel_weight_legion_ordering( + attention_bias_shape.num_dims, + attention_bias_shape.dims, + _input->data_type, + NULL /*owner_op*/, + false /*create_grad*/, + attn_bias_initializer, + CHOSEN_SYNC_TYPE); + + if (numWeights > 1) { + assert(elementwise_affine); + + ParallelTensorShape beta_gamma_shape = _input->get_shape(); + for (int i = axes.size(); i < beta_gamma_shape.num_dims - 1; i++) { + beta_gamma_shape.dims[i].size = 1; + } + + // weight + Initializer *gamma_initializer = new UniformInitializer(seed, 1.0f, 1.0f); + weights[1] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, // axes.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + false /*create_grad*/, + gamma_initializer, + CHOSEN_SYNC_TYPE); + + // bias + if (numWeights == 3) { + assert(use_bias); + Initializer *beta_initializer = + new UniformInitializer(seed, 0.0f, 0.0f); + weights[2] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, //.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + false /*create_grad*/, + beta_initializer, + CHOSEN_SYNC_TYPE); + } + } + } +} + +void AddBiasResidualLayerNorm::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ADD_BIAS_RESIDUAL_LAYERNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(AddBiasResidualLayerNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // attn output + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // residual + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // added: attn_output + attn final bias + residual + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(3, FID_DATA); + // attn final bias + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[2]->region)); + launcher.add_field(6, FID_DATA); + } + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void AddBiasResidualLayerNorm::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(ADD_BIAS_RESIDUAL_LAYERNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(AddBiasResidualLayerNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + // attn output + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // residual + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // added: attn_output + attn final bias + residual + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[1]->region)); + launcher.add_field(3, FID_DATA); + // attn final bias + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[2]->region)); + launcher.add_field(6, FID_DATA); + } + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +/* + regions[0](I): attn output + regions[1](I): residual + regions[2](O): added output (attn output + final attn bias + residual) + regions[3](O): layer norm output + regions[4](I): final attn bias + regions[5](I): gamma + regions[6](I): beta +*/ +OpMeta *AddBiasResidualLayerNorm::init_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + AddBiasResidualLayerNorm *ln = (AddBiasResidualLayerNorm *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + AddBiasResidualLayerNormMeta *meta = + new AddBiasResidualLayerNormMeta(handle, ln, gpu_mem_allocator); + meta->input_type[0] = ln->inputs[0]->data_type; + meta->input_type[1] = ln->inputs[1]->data_type; + meta->weight_type[0] = ln->weights[0]->data_type; + if (ln->elementwise_affine) { + meta->weight_type[1] = ln->weights[1]->data_type; + if (ln->use_bias) { + meta->weight_type[2] = ln->weights[2]->data_type; + } + } + meta->output_type[0] = ln->outputs[0]->data_type; + meta->output_type[1] = ln->outputs[1]->data_type; + std::strcpy(meta->op_name, ln->name); + meta->layer_guid = ln->layer_guid; + return meta; +} + +void AddBiasResidualLayerNorm::forward(FFModel const &ff) { + assert(false); +} + +void AddBiasResidualLayerNorm::backward(FFModel const &ff) { + assert(false); +} + +FutureMap AddBiasResidualLayerNorm::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "AddBiasResidualLayerNorm op machine_view: " << *(MachineView + const *)mv + << std::endl; */ + IndexLauncher launcher(ADD_BIAS_RESIDUAL_LAYERNORM_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + // attn output + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // residual + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // added: attn_output + attn final bias + residual + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(3, FID_DATA); + // attn final bias + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[2]->region)); + launcher.add_field(6, FID_DATA); + } + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): attn output + regions[1](I): residual + regions[2](O): added output (attn output + final attn bias + residual) + regions[3](O): layer norm output + regions[4](I): final attn bias + regions[5](I): gamma + regions[6](I): beta +*/ +void AddBiasResidualLayerNorm::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + assert(task->regions.size() == regions.size()); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + + AddBiasResidualLayerNormMeta *m = + *((AddBiasResidualLayerNormMeta **)task->local_args); + + assert(regions.size() == + 5 + (m->elementwise_affine ? (m->use_bias ? 2 : 1) : 0)); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR residual = helperGetGenericTensorAccessorRO( + m->input_type[1], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW added_output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[1], regions[3], task->regions[3], FID_DATA, ctx, runtime); + GenericTensorAccessorR attn_bias = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[4], task->regions[4], FID_DATA, ctx, runtime); + GenericTensorAccessorR gamma, beta; + + Domain in_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain residual_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain added_out_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + Domain out_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + Domain attn_bias_domain = runtime->get_index_space_domain( + ctx, task->regions[4].region.get_index_space()); + Domain gamma_domain, beta_domain; + + assert(in_domain.get_volume() == out_domain.get_volume()); + assert(out_domain.get_volume() == added_out_domain.get_volume()); + assert(in_domain.get_volume() == residual_domain.get_volume()); + assert(in_domain == out_domain); + assert(added_out_domain == out_domain); + assert(residual_domain == in_domain); + + coord_t attn_bias_dim = + attn_bias_domain.hi()[0] - attn_bias_domain.lo()[0] + 1; + assert((in_domain.hi()[0] - in_domain.lo()[0] + 1) == attn_bias_dim); + assert((residual_domain.hi()[0] - residual_domain.lo()[0] + 1) == + attn_bias_dim); + assert((out_domain.hi()[0] - out_domain.lo()[0] + 1) == attn_bias_dim); + assert((added_out_domain.hi()[0] - added_out_domain.lo()[0] + 1) == + attn_bias_dim); + + assert(in_domain.get_volume() == + m->effective_num_elements * m->effective_batch_size); + + if (m->elementwise_affine) { + gamma = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[5], + task->regions[5], + FID_DATA, + ctx, + runtime); + gamma_domain = runtime->get_index_space_domain( + ctx, task->regions[5].region.get_index_space()); + + if (m->use_bias) { + beta = helperGetGenericTensorAccessorRO(m->weight_type[2], + regions[6], + task->regions[6], + FID_DATA, + ctx, + runtime); + beta_domain = runtime->get_index_space_domain( + ctx, task->regions[6].region.get_index_space()); + assert(gamma_domain == beta_domain); + } + + assert(gamma_domain.get_volume() == m->effective_num_elements); + int numdims = gamma_domain.get_dim(); + size_t vol = 1; + int i = 0; + while (vol < gamma_domain.get_volume()) { + int g_d = gamma_domain.hi()[i] - gamma_domain.lo()[i] + 1; + int in_d = in_domain.hi()[i] - in_domain.lo()[i] + 1; + assert(g_d == in_d); + vol *= g_d; + i++; + } + } + + AddBiasResidualLayerNorm::inference_kernel_wrapper( + m, + (int)attn_bias_dim, + (int)residual_domain.get_volume(), + input, + added_output, + output, + residual, + attn_bias, + gamma, + beta); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + weights_accessors.push_back(attn_bias); + if (m->elementwise_affine) { + weights_accessors.push_back(gamma); + if (m->use_bias) { + weights_accessors.push_back(beta); + } + } + AddBiasResidualLayerNorm::save_inference_tensors_to_file( + m, + shard_id, + bc, + {input, residual}, + weights_accessors, + {added_output, output}); + } +} + +bool AddBiasResidualLayerNorm::measure_operator_cost( + Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const { + return false; +} + +void AddBiasResidualLayerNorm::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->axes.size()); + for (size_t i = 0; i < this->axes.size(); i++) { + sez.serialize(this->axes[i]); + } + sez.serialize(this->elementwise_affine); + sez.serialize(this->eps); + sez.serialize(this->use_bias); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node AddBiasResidualLayerNorm::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 2); + size_t num_axes; + std::vector axes; + bool elementwise_affine; + bool use_bias; + float eps; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(num_axes); + for (size_t i = 0; i < num_axes; i++) { + int axis_idx; + dez.deserialize(axis_idx); + axes.push_back(axis_idx); + } + dez.deserialize(elementwise_affine); + dez.deserialize(eps); + dez.deserialize(use_bias); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + AddBiasResidualLayerNormParams params; + params.layer_guid = layer_guid; + params.axes = axes; + params.elementwise_affine = elementwise_affine; + params.eps = eps; + params.use_bias = use_bias; + strcpy(params.name, name); + return ff.get_or_create_node({inputs[0], inputs[1]}, + params); +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::AddBiasResidualLayerNormParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.layer_guid.transformer_layer_id); + hash_combine(key, params.layer_guid.model_id); + hash_combine(key, params.axes.size()); + for (int n : params.axes) { + hash_combine(key, n); + } + hash_combine(key, params.elementwise_affine); + hash_combine(key, params.use_bias); + return key; +} +}; // namespace std diff --git a/src/ops/add_bias_residual_layer_norm.cpp b/src/ops/add_bias_residual_layer_norm.cpp new file mode 100644 index 0000000000..1add43ecd9 --- /dev/null +++ b/src/ops/add_bias_residual_layer_norm.cpp @@ -0,0 +1,263 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/add_bias_residual_layer_norm.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +AddBiasResidualLayerNormMeta::AddBiasResidualLayerNormMeta( + FFHandler handle, + AddBiasResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + elementwise_affine = ln->elementwise_affine; + use_bias = ln->use_bias; + effective_batch_size = ln->effective_batch_size; + effective_num_elements = ln->effective_num_elements; + profiling = ln->profiling; + inference_debugging = ln->inference_debugging; + eps = ln->eps; + DataType data_type = ln->data_type; + size_t totalSize = effective_batch_size * data_type_size(data_type) * 3; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + mean_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + rstd_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + bias_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); +} + +AddBiasResidualLayerNormMeta::~AddBiasResidualLayerNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < min(blockDim.x, max_num_threads) / C10_WARP_SIZE) + ? shared[lid] + : 0; + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void LayerNormFusedForwardKernel(int attn_bias_dim, + int residual_volume, + int64_t effective_num_elements, + int64_t effective_batch_size, + float eps, + T const *input_ptr, + T const *attn_bias_ptr, + T const *residual_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + T *mean, + T *rstd) { + // Add attention bias and residual + CUDA_KERNEL_LOOP(i, residual_volume) { + int bias_idx = i % attn_bias_dim; + added_output_ptr[i] = + input_ptr[i] + attn_bias_ptr[bias_idx] + residual_ptr[i]; + } + + __syncthreads(); + + // LayerNorm + __shared__ float m_shared[C10_WARP_SIZE]; + __shared__ float v_shared[C10_WARP_SIZE]; + const int64_t i = blockIdx.x; + if (i >= effective_batch_size) { + return; + } + float sum1 = 0.0f; + float sum2 = 0.0f; + for (int64_t j = threadIdx.x; j < effective_num_elements; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + const int64_t index = i * effective_num_elements + j; + sum1 += static_cast(added_output_ptr[index]); + sum2 += static_cast(added_output_ptr[index]) * + static_cast(added_output_ptr[index]); + } + if (threadIdx.x < kCUDABlockReduceNumThreads) { + sum1 = BlockReduceSum( + sum1, m_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + sum2 = BlockReduceSum( + sum2, v_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + } + if (threadIdx.x == 0) { + float const scale = float(1) / static_cast(effective_num_elements); + sum1 *= scale; + sum2 = max(sum2 * scale - sum1 * sum1, float(0)); + mean[i] = static_cast(sum1); + rstd[i] = static_cast(rsqrt(sum2 + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < effective_num_elements; + j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * effective_num_elements + j; + const T_ACC gamma_v = + gamma_ptr == nullptr ? T_ACC(1) : static_cast(gamma_ptr[j]); + const T_ACC beta_v = + beta_ptr == nullptr ? T_ACC(0) : static_cast(beta_ptr[j]); + output_ptr[index] = (static_cast(added_output_ptr[index]) - + static_cast(mean[i])) * + static_cast(rstd[i]) * gamma_v + + beta_v; + } +} + +/*static*/ +template +void AddBiasResidualLayerNorm::inference_kernel( + AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + T const *input_ptr, + T const *attn_bias_ptr, + T const *residual_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + hipStream_t stream) { + + std::pair kernel1_parallelism = std::make_pair( + GET_BLOCKS(residual_volume), std::min(residual_volume, CUDA_NUM_THREADS)); + std::pair kernel2_parallelism = + std::make_pair(m->effective_batch_size, kCUDABlockReduceNumThreads); + std::pair kernel3_parallelism = + std::make_pair(m->effective_batch_size, kCUDANumThreads); + + int num_blocks = std::max({kernel1_parallelism.first, + kernel2_parallelism.first, + kernel3_parallelism.first}); + int num_threads = std::max({kernel1_parallelism.second, + kernel2_parallelism.second, + kernel3_parallelism.second}); + + hipLaunchKernelGGL(HIP_KERNEL_NAME(LayerNormFusedForwardKernel), + num_blocks, + num_threads, + 0, + stream, + attn_bias_dim, + residual_volume, + m->effective_num_elements, + m->effective_batch_size, + m->eps, + input_ptr, + attn_bias_ptr, + residual_ptr, + added_output_ptr, + output_ptr, + gamma_ptr, + beta_ptr, + static_cast(m->mean_ptr), + static_cast(m->rstd_ptr)); +} + +/*static*/ +void AddBiasResidualLayerNorm::inference_kernel_wrapper( + AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + GenericTensorAccessorR const &input, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &residual, + GenericTensorAccessorR const &attn_bias, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + if (m->input_type[0] == DT_FLOAT) { + AddBiasResidualLayerNorm::inference_kernel( + m, + attn_bias_dim, + residual_volume, + input.get_float_ptr(), + attn_bias.get_float_ptr(), + residual.get_float_ptr(), + added_output.get_float_ptr(), + output.get_float_ptr(), + gamma.get_float_ptr(), + m->use_bias ? beta.get_float_ptr() : nullptr, + stream); + } else if (m->input_type[0] == DT_HALF) { + AddBiasResidualLayerNorm::inference_kernel( + m, + attn_bias_dim, + residual_volume, + input.get_half_ptr(), + attn_bias.get_half_ptr(), + residual.get_half_ptr(), + added_output.get_half_ptr(), + output.get_half_ptr(), + gamma.get_half_ptr(), + m->use_bias ? beta.get_half_ptr() : nullptr, + stream); + } else { + assert(false && "unsupport datatype in layernorm"); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/add_bias_residual_layer_norm.cu b/src/ops/add_bias_residual_layer_norm.cu new file mode 100644 index 0000000000..ceb1a6514e --- /dev/null +++ b/src/ops/add_bias_residual_layer_norm.cu @@ -0,0 +1,300 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +AddBiasResidualLayerNormMeta::AddBiasResidualLayerNormMeta( + FFHandler handle, + AddBiasResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + elementwise_affine = ln->elementwise_affine; + use_bias = ln->use_bias; + effective_batch_size = ln->effective_batch_size; + effective_num_elements = ln->effective_num_elements; + profiling = ln->profiling; + inference_debugging = ln->inference_debugging; + eps = ln->eps; + DataType data_type = ln->data_type; + size_t totalSize = effective_batch_size * data_type_size(data_type) * 3; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + mean_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + rstd_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + bias_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); +} + +AddBiasResidualLayerNormMeta::~AddBiasResidualLayerNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < min(blockDim.x, max_num_threads) / C10_WARP_SIZE) + ? shared[lid] + : 0; + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void LayerNormFusedForwardKernel(int64_t N, + int64_t attn_bias_dim, + float eps, + T const *input_ptr, + T const *attn_bias_ptr, + T const *residual_ptr, + T *X, + T *mean, + T *rstd, + T const *gamma, + T const *beta, + T *Y) { + __shared__ float m_shared[C10_WARP_SIZE]; + __shared__ float v_shared[C10_WARP_SIZE]; + const int64_t i = blockIdx.x; + float sum1 = 0.0f; + float sum2 = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + const int64_t index = i * N + j; + const int64_t bias_idx = index % attn_bias_dim; + X[index] = input_ptr[index] + attn_bias_ptr[bias_idx] + residual_ptr[index]; + sum1 += static_cast(X[index]); + sum2 += static_cast(X[index]) * static_cast(X[index]); + } + if (threadIdx.x < kCUDABlockReduceNumThreads) { + sum1 = BlockReduceSum( + sum1, m_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + sum2 = BlockReduceSum( + sum2, v_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + } + if (threadIdx.x == 0) { + float const scale = float(1) / static_cast(N); + sum1 *= scale; + sum2 = max(sum2 * scale - sum1 * sum1, float(0)); + mean[i] = static_cast(sum1); + rstd[i] = static_cast(rsqrt(sum2 + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + const T_ACC gamma_v = + gamma == nullptr ? T_ACC(1) : static_cast(gamma[j]); + const T_ACC beta_v = + beta == nullptr ? T_ACC(0) : static_cast(beta[j]); + Y[index] = (static_cast(X[index]) - static_cast(mean[i])) * + static_cast(rstd[i]) * gamma_v + + beta_v; + } +} + +/*static*/ +template +void AddBiasResidualLayerNorm::inference_kernel( + AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + T const *input_ptr, + T const *attn_bias_ptr, + T const *residual_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + cudaStream_t stream) { + + std::pair kernel1_parallelism = + std::make_pair(m->effective_batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->effective_batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + LayerNormFusedForwardKernel + <<>>(m->effective_num_elements, + attn_bias_dim, + m->eps, + input_ptr, + attn_bias_ptr, + residual_ptr, + added_output_ptr, + static_cast(m->mean_ptr), + static_cast(m->rstd_ptr), + gamma_ptr, + beta_ptr, + output_ptr); +} + +/*static*/ +void AddBiasResidualLayerNorm::inference_kernel_wrapper( + AddBiasResidualLayerNormMeta const *m, + int attn_bias_dim, + int residual_volume, + GenericTensorAccessorR const &input, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &residual, + GenericTensorAccessorR const &attn_bias, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + if (m->input_type[0] == DT_FLOAT) { + AddBiasResidualLayerNorm::inference_kernel( + m, + attn_bias_dim, + residual_volume, + input.get_float_ptr(), + attn_bias.get_float_ptr(), + residual.get_float_ptr(), + added_output.get_float_ptr(), + output.get_float_ptr(), + m->elementwise_affine ? gamma.get_float_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_float_ptr() : nullptr, + stream); + } else if (m->input_type[0] == DT_HALF) { + AddBiasResidualLayerNorm::inference_kernel( + m, + attn_bias_dim, + residual_volume, + input.get_half_ptr(), + attn_bias.get_half_ptr(), + residual.get_half_ptr(), + added_output.get_half_ptr(), + output.get_half_ptr(), + m->elementwise_affine ? gamma.get_half_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_half_ptr() : nullptr, + stream); + } else { + assert(false && "unsupport datatype in layernorm"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[AddBiasResidualLayerNorm] forward time (CF) = %.9fms\n", elapsed); + // if (m->input_type[0] == DT_FLOAT) { + // print_tensor(input.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:input]"); + // print_tensor(attn_bias.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:attn_bias]"); + // print_tensor(residual.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:residual]"); + // print_tensor(added_output.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:added_output]"); + // print_tensor(output.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:output]"); + // print_tensor(gamma.get_float_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:gamma]"); + // print_tensor( + // beta.get_float_ptr(), 32, + // "[AddBiasResidualLayerNorm:forward:beta]"); + // } else { + // print_tensor( + // input.get_half_ptr(), 32, + // "[AddBiasResidualLayerNorm:forward:input]"); + // print_tensor(attn_bias.get_half_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:attn_bias]"); + // print_tensor(residual.get_half_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:residual]"); + // print_tensor(added_output.get_half_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:added_output]"); + // print_tensor(output.get_half_ptr(), + // 32, + // "[AddBiasResidualLayerNorm:forward:output]"); + // print_tensor( + // gamma.get_half_ptr(), 32, + // "[AddBiasResidualLayerNorm:forward:gamma]"); + // print_tensor( + // beta.get_half_ptr(), 32, + // "[AddBiasResidualLayerNorm:forward:beta]"); + // } + // print_tensor(in_ptr, 32, "[AddBiasResidualLayerNorm:forward:input]"); + // print_tensor(out_ptr, 32, + // "[AddBiasResidualLayerNorm:forward:output]"); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/aggregate.cc b/src/ops/aggregate.cc index 0ad9d91d62..5f05458e34 100644 --- a/src/ops/aggregate.cc +++ b/src/ops/aggregate.cc @@ -85,6 +85,9 @@ AggregateParams Aggregate::get_params() const { AggregateParams params; params.n = this->n; params.lambda_bal = this->lambda_bal; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -164,7 +167,54 @@ Aggregate::Aggregate(FFModel &model, AggregateParams const ¶ms, std::vector const &inputs, char const *name) - : Aggregate(model, inputs.data(), params.n, params.lambda_bal, name) {} + : Aggregate( + model, inputs.data(), params.n, params.lambda_bal, params.name) {} + +using PCG::Node; +Node Aggregate::deserialize(FFModel &ff, + Legion::Deserializer &dez, + std::vector const &inputs, + int num_inputs) { + int n; + float lambda_bal; + dez.deserialize(n); + dez.deserialize(lambda_bal); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + assert(num_inputs == n + 4); + AggregateParams params; + params.n = n; + params.lambda_bal = lambda_bal; + strcpy(params.name, name); + return ff.get_or_create_node(inputs, params); +} + +void Aggregate::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(AGGREGATE_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Aggregate)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} void Aggregate::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -194,6 +244,9 @@ OpMeta *Aggregate::init_task(Task const *task, FFHandler handle = *((FFHandler *)task->local_args); AggregateMeta *m = new AggregateMeta(handle, agg->n); m->profiling = agg->profiling; + m->inference_debugging = agg->inference_debugging; + std::strcpy(m->op_name, agg->name); + m->layer_guid = agg->layer_guid; return m; } @@ -204,7 +257,7 @@ void Aggregate::forward(FFModel const &ff) { set_argumentmap_for_forward(ff, argmap); IndexLauncher launcher(AGGREGATE_FWD_TASK_ID, parallel_is, - TaskArgument(this, sizeof(Aggregate)), + TaskArgument(nullptr, 0), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -243,14 +296,68 @@ void Aggregate::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap Aggregate::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "Aggregate op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(AGGREGATE_FWD_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // gate_preds + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // gate_assign + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // exp_preds + for (int i = 0; i < n; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_inputs[i + 4]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[i + 4]->region)); + launcher.add_field(i + 2, FID_DATA); + } + // output + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(n + 2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void Aggregate::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - int n = ((Aggregate *)task->args)->n; - - assert((int)regions.size() == n + 3); - assert((int)task->regions.size() == n + 3); + assert(regions.size() == task->regions.size()); + int n = regions.size() - 3; AggregateMeta const *m = *((AggregateMeta **)task->local_args); @@ -469,6 +576,8 @@ void Aggregate::backward_task(Task const *task, void Aggregate::serialize(Legion::Serializer &sez) const { sez.serialize(this->n); sez.serialize(this->lambda_bal); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } bool Aggregate::measure_operator_cost(Simulator *sim, diff --git a/src/ops/aggregate.cpp b/src/ops/aggregate.cpp index bc4391c426..d5ebdb0c22 100644 --- a/src/ops/aggregate.cpp +++ b/src/ops/aggregate.cpp @@ -216,8 +216,8 @@ void Aggregate::forward_kernel_wrapper(AggregateMeta const *m, checkCUDNN(miopenSetStream(m->handle.dnn, stream)); // call forward_kernel - hipMemcpy( - m->dev_exp_preds, exp_preds, n * sizeof(float *), hipMemcpyHostToDevice); + checkCUDA(hipMemcpy( + m->dev_exp_preds, exp_preds, n * sizeof(float *), hipMemcpyHostToDevice)); hipLaunchKernelGGL(agg_forward_kernel, GET_BLOCKS(batch_size * k * out_dim), @@ -256,10 +256,10 @@ void Aggregate::backward_kernel_wrapper(AggregateMeta const *m, checkCUDNN(miopenSetStream(m->handle.dnn, stream)); // call backward kernel - hipMemcpy( - m->dev_exp_preds, exp_preds, n * sizeof(float *), hipMemcpyHostToDevice); - hipMemcpy( - m->dev_exp_grads, exp_grads, n * sizeof(float *), hipMemcpyHostToDevice); + checkCUDA(hipMemcpy( + m->dev_exp_preds, exp_preds, n * sizeof(float *), hipMemcpyHostToDevice)); + checkCUDA(hipMemcpy( + m->dev_exp_grads, exp_grads, n * sizeof(float *), hipMemcpyHostToDevice)); hipLaunchKernelGGL(agg_backward_kernel, GET_BLOCKS(batch_size * k * out_dim), diff --git a/src/ops/aggregate_spec.cc b/src/ops/aggregate_spec.cc index 749d071310..1edd430881 100644 --- a/src/ops/aggregate_spec.cc +++ b/src/ops/aggregate_spec.cc @@ -84,6 +84,9 @@ AggregateSpecParams AggregateSpec::get_params() const { AggregateSpecParams params; params.n = this->n; params.lambda_bal = this->lambda_bal; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -155,6 +158,32 @@ AggregateSpec::AggregateSpec(FFModel &model, numWeights = 0; } +void AggregateSpec::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(AGG_SPEC_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(AggregateSpec)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + void AggregateSpec::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); parallel_is = outputs[0]->parallel_is; @@ -183,6 +212,9 @@ OpMeta *AggregateSpec::init_task(Task const *task, FFHandler handle = *((FFHandler *)task->local_args); AggregateSpecMeta *m = new AggregateSpecMeta(handle, agg->n); m->profiling = agg->profiling; + m->inference_debugging = agg->inference_debugging; + std::strcpy(m->op_name, agg->name); + m->layer_guid = agg->layer_guid; return m; } @@ -193,7 +225,7 @@ void AggregateSpec::forward(FFModel const &ff) { set_argumentmap_for_forward(ff, argmap); IndexLauncher launcher(AGG_SPEC_FWD_TASK_ID, parallel_is, - TaskArgument(this, sizeof(AggregateSpec)), + TaskArgument(NULL, 0), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -232,13 +264,70 @@ void AggregateSpec::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap + AggregateSpec::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "AggregateSpec op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(AGG_SPEC_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // gate_preds + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // gate_assign + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // exp_preds + for (int i = 0; i < n; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_inputs[i + 4]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[i + 4]->region)); + launcher.add_field(i + 2, FID_DATA); + } + // output + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(n + 2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void AggregateSpec::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - int n = ((AggregateSpec *)task->args)->n; + assert(regions.size() == task->regions.size()); + int n = regions.size() - 3; - assert((int)regions.size() == n + 3); assert((int)task->regions.size() == n + 3); AggregateSpecMeta const *m = *((AggregateSpecMeta **)task->local_args); diff --git a/src/ops/aggregate_spec.cpp b/src/ops/aggregate_spec.cpp index e961c3ae7b..314e20a59c 100644 --- a/src/ops/aggregate_spec.cpp +++ b/src/ops/aggregate_spec.cpp @@ -226,10 +226,10 @@ void AggregateSpec::forward_kernel_wrapper(AggregateSpecMeta const *m, checkCUDNN(miopenSetStream(m->handle.dnn, stream)); // call forward kernel - hipMemcpy(m->dev_region_ptrs, - exp_preds, - n * sizeof(float *), - hipMemcpyHostToDevice); + checkCUDA(hipMemcpy(m->dev_region_ptrs, + exp_preds, + n * sizeof(float *), + hipMemcpyHostToDevice)); hipLaunchKernelGGL(aggspec_forward_kernel, GET_BLOCKS(batch_size * k * out_dim), @@ -266,10 +266,10 @@ void AggregateSpec::backward_kernel_wrapper(AggregateSpecMeta const *m, checkCUDNN(miopenSetStream(m->handle.dnn, stream)); // call backward kernel - hipMemcpy(m->dev_region_ptrs, - exp_grads, - n * sizeof(float *), - hipMemcpyHostToDevice); + checkCUDA(hipMemcpy(m->dev_region_ptrs, + exp_grads, + n * sizeof(float *), + hipMemcpyHostToDevice)); hipLaunchKernelGGL(aggspec_backward_kernel, GET_BLOCKS(batch_size * k * out_dim), diff --git a/src/ops/arg_topk.cc b/src/ops/arg_topk.cc new file mode 100644 index 0000000000..780a77450e --- /dev/null +++ b/src/ops/arg_topk.cc @@ -0,0 +1,510 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/arg_topk.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + +namespace FlexFlow { +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +// For an input tensor, computes the top k entries in each row +// (resp. vector along the last dimension). Thus, +// values.shape = indices.shape = input.shape[:-1] + [k] +Tensor FFModel::arg_top_k(const Tensor input, + int k, + bool sorted, + bool speculative_decoding, + char const *name) { + Layer *li = new Layer(this, + OP_ARG_TOPK, + input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + speculative_decoding ? 2 : 1 /*outputs*/, + input); + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + dims[0] = k; + // li->outputs[0] = create_tensor_legion_ordering( + // numdims, dims, input->data_type, li, 0, true /*create_grad*/); + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 0, false /*create_grad*/); + if (speculative_decoding) { + li->outputs[1] = create_tensor_legion_ordering( + numdims, dims, DT_FLOAT, li, 1, false /*create_grad*/); + } + } + li->add_int_property("k", k); + li->add_int_property("sorted", sorted); + li->add_int_property("speculative_decoding", speculative_decoding); + layers.push_back(li); + // outputs[0] = li->outputs[0]; + // outputs[1] = li->outputs[1]; + return li->outputs[0]; +} + +Op *ArgTopK::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("k", value); + int k = value; + layer->get_int_property("sorted", value); + bool sorted = (bool)value; + layer->get_int_property("speculative_decoding", value); + bool speculative_decoding = (bool)value; + + return new ArgTopK(model, + layer->layer_guid, + inputs[0], + k, + sorted, + speculative_decoding, + layer->name); +} + +ArgTopKParams ArgTopK::get_params() const { + ArgTopKParams params; + params.k = this->k; + params.sorted = this->sorted; + params.speculative_decoding = this->speculative_decoding; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +bool ArgTopKParams::is_valid(ParallelTensorShape const &) const { + // topk is always valid + return true; +} + +bool operator==(ArgTopKParams const &lhs, ArgTopKParams const &rhs) { + return lhs.k == rhs.k && lhs.sorted == rhs.sorted && + lhs.speculative_decoding == rhs.speculative_decoding; +} + +ArgTopK::ArgTopK(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + int _k, + bool _sorted, + bool _speculative_decoding, + char const *name) + : Op(model, + OP_ARG_TOPK, + _input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + _speculative_decoding ? 2 : 1 /*outputs*/, + _input), + k(_k), sorted(_sorted), speculative_decoding(_speculative_decoding) { + // overwrite layer_guid + layer_guid = _layer_guid; + int numdim = inputs[0]->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = inputs[0]->dims[i]; + } + + dims[0].size = k; + assert(inputs[0]->dims[0].degree == 1); + assert(inputs[0]->dims[0].parallel_idx == -1); + + outputs[0] = model.create_parallel_tensor_legion_ordering( + numdim, dims, DT_INT32, this, 0 /*owner_idx*/); + if (_speculative_decoding) { + outputs[1] = model.create_parallel_tensor_legion_ordering( + numdim, dims, DT_FLOAT, this, 1 /*owner_idx*/); + } +} + +ArgTopK::ArgTopK(FFModel &model, + LayerID const &layer_guid, + ArgTopK const &other, + const ParallelTensor input) + : ArgTopK(model, + layer_guid, + input, + other.k, + other.sorted, + other.speculative_decoding, + other.name) {} + +ArgTopK::ArgTopK(FFModel &model, + ArgTopKParams const ¶ms, + ParallelTensor const input, + char const *name) + : ArgTopK(model, + params.layer_guid, + input, + params.k, + params.sorted, + params.speculative_decoding, + params.name) {} + +void ArgTopK::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ARG_TOPK_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ArgTopK)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + // launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + // 0 /*projection id*/, + // WRITE_ONLY, + // EXCLUSIVE, + // batch_outputs[1]->region)); + // launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void ArgTopK::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(ARG_TOPK_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ArgTopK)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + // launcher.add_region_requirement(RegionRequirement(outputs[1]->part, + // 0 /*projection id*/, + // WRITE_ONLY, + // EXCLUSIVE, + // outputs[1]->region)); + // launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *ArgTopK::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + ArgTopK *topk = (ArgTopK *)task->args; + FFHandler handle = *((FFHandler *)task->local_args); + ArgTopKMeta *m = new ArgTopKMeta(handle, topk); + m->profiling = topk->profiling; + m->inference_debugging = topk->inference_debugging; + m->sorted = topk->sorted; + m->k = topk->k; + std::strcpy(m->op_name, topk->name); + m->layer_guid = topk->layer_guid; + m->speculative_decoding = topk->speculative_decoding; + return m; +} + +void ArgTopK::forward(FFModel const &ff) { + // ArgTopK does not support forward + assert(false); +} + +FutureMap ArgTopK::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "ArgTopK op machine_view: " << *(MachineView const *)mv + << std::endl; */ + if (speculative_decoding) { + IndexLauncher launcher(ARG_TOPK_INF_SPECULATIVE_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + + launcher.add_region_requirement( + RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); + + } else { + IndexLauncher launcher(ARG_TOPK_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); + } +} + +InferenceResult + ArgTopK::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + // const ArgTopK* topk = (const ArgTopK*) task->args; + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + // Directly return for empty batch config + InferenceResult ir; + return ir; + } + ArgTopKMeta *m = *((ArgTopKMeta **)task->local_args); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW indices = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW probs; + + int batch_size = bc->num_active_tokens(); + ArgTopK::forward_kernel_wrapper( + m, input, probs, indices, batch_size, nullptr); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + ArgTopK::save_inference_tensors_to_file( + m, shard_id, bc, {input}, {}, {indices}); + } + + InferenceResult ir; + download_tensor( + indices.get_int32_ptr(), ir.token_ids, batch_size); + return ir; +} + +BeamInferenceResult ArgTopK::inference_speculative_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 3); + assert(task->regions.size() == 3); + BeamSearchBatchConfig const &bc = + Future(task->futures[0]).get_result(); + if (bc.num_active_tokens() == 0) { + // Directly return for empty batch config + BeamInferenceResult ir; + return ir; + } + ArgTopKMeta *m = *((ArgTopKMeta **)task->local_args); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW indices = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW probs = helperGetGenericTensorAccessorWO( + DT_FLOAT, regions[2], task->regions[2], FID_DATA, ctx, runtime); + + int batch_size = bc.num_active_tokens(); + ArgTopK::forward_kernel_wrapper(m, input, probs, indices, batch_size, &bc); + + BeamInferenceResult ir; + download_tensor( + indices.get_int32_ptr(), ir.token_ids, batch_size * m->k); + download_tensor(probs.get_float_ptr(), ir.probs, batch_size * m->k); + return ir; +} + +void ArgTopK::backward(FFModel const &ff) { + // ArgTopK does not support backward + assert(false); +} + +void ArgTopK::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->k); + sez.serialize(this->sorted); + sez.serialize(this->speculative_decoding); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +Node ArgTopK::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + int k; + bool sorted; + bool speculative_decoding; + dez.deserialize(k); + dez.deserialize(sorted); + dez.deserialize(speculative_decoding); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + ArgTopKParams params; + params.layer_guid = layer_guid; + params.k = k; + params.sorted = sorted; + params.speculative_decoding = speculative_decoding; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); +} + +Op *ArgTopK::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + ArgTopKParams params = get_params(); + return new ArgTopK(ff, params, inputs[0], this->name); +} + +bool ArgTopK::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::ArgTopKParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.k); + hash_combine(key, params.sorted); + hash_combine(key, params.speculative_decoding); + return key; +} +}; // namespace std diff --git a/src/ops/arg_topk.cpp b/src/ops/arg_topk.cpp new file mode 100644 index 0000000000..f431d3d4bf --- /dev/null +++ b/src/ops/arg_topk.cpp @@ -0,0 +1,534 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/arg_topk.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +enum class HeapType { kMinHeap, kMaxHeap }; +enum class PreferIndices { kLower, kHigher }; + +template +struct Entry { + int index; + T value; +}; + +template +struct LinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return data[i].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; +}; + +template +struct IndirectLinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return backing_data[data[i].index].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; + Entry *const backing_data; +}; + +template +struct StridedData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index * blockDim.x + threadIdx.x]; + } + + __device__ int get_index(int i) const { + return (*this)[i].index; + } + __device__ T get_value(int i) const { + return (*this)[i].value; + } + + Entry *const data; +}; + +// A heap of Entry that can either work as a min-heap or as a max-heap. +template + class Data, + typename T> +struct IndexedHeap { + typedef typename Data::Entry Entry; + Data const data; + __device__ IndexedHeap(Data const &d) : data(d) {} + + __device__ bool is_above(int left, int right) { + T left_value = data.get_value(left); + T right_value = data.get_value(right); + if (left_value == right_value) { + if (preferIndices == PreferIndices::kLower) { + return data.get_index(left) < data.get_index(right); + } else { + return data.get_index(left) > data.get_index(right); + } + } + if (heapType == HeapType::kMinHeap) { + return left_value < right_value; + } else { + return left_value > right_value; + } + } + + __device__ void assign(int i, Entry const &entry) { + data[i] = entry; + } + + __device__ void push_up(int i) { + int child = i; + int parent; + for (; child > 0; child = parent) { + parent = (child - 1) / 2; + if (!is_above(child, parent)) { + // Heap property satisfied. + break; + } + swap(child, parent); + } + } + + __device__ void swap(int a, int b) { + auto tmp = data[b]; + data[b] = data[a]; + data[a] = tmp; + } + + __device__ void push_root_down(int k) { + push_down(0, k); + } + + // MAX-HEAPIFY in Cormen + __device__ void push_down(int node, int k) { + while (true) { + int const left = 2 * node + 1; + int const right = left + 1; + int smallest = node; + if (left < k && is_above(left, smallest)) { + smallest = left; + } + if (right < k && is_above(right, smallest)) { + smallest = right; + } + if (smallest == node) { + break; + } + swap(smallest, node); + node = smallest; + } + } + + // BUILD-MAX-HEAPIFY in Cormen + __device__ void build(int k) { + for (int node = (k - 1) / 2; node >= 0; node--) { + push_down(node, k); + } + } + + // HEAP-EXTRACT-MAX in Cormen + __device__ void remove_root(int k) { + data[0] = data[k - 1]; + push_root_down(k - 1); + } + + // in-place HEAPSORT in Cormen + // This method destroys the heap property. + __device__ void sort(int k) { + for (int slot = k - 1; slot > 0; slot--) { + // This is like remove_root but we insert the element at the end. + swap(slot, 0); + // Heap is now an element smaller. + push_root_down(/*k=*/slot); + } + } + + __device__ void replace_root(Entry const &entry, int k) { + data[0] = entry; + push_root_down(k); + } + + __device__ Entry const &root() { + return data[0]; + } +}; + +template + class Data, + typename T> +__device__ IndexedHeap + make_indexed_heap(typename Data::Entry *data) { + return IndexedHeap{Data{data}}; +} + +// heapArgTopK walks over [input, input+length) with `step_size` stride starting +// at `start_index`. It builds a top-`k` heap that is stored in `heap_entries` +// using `Accessor` to access elements in `heap_entries`. If sorted=true, the +// elements will be sorted at the end. +template class Data = LinearData> +__device__ void heapArgTopK(T const *__restrict__ input, + int length, + int k, + Entry *__restrict__ heap_entries, + bool sorted = false, + int start_index = 0, + int step_size = 1) { + assert(k <= length); + + auto heap = + make_indexed_heap( + heap_entries); + + int heap_end_index = start_index + k * step_size; + if (heap_end_index > length) { + heap_end_index = length; + } + // Initialize the min-heap. + for (int index = start_index, slot = 0; index < heap_end_index; + index += step_size, slot++) { + heap.assign(slot, {index, input[index]}); + } + + heap.build(k); + + // Now iterate over the remaining items. + // If an item is smaller than the min element, it is not amongst the top k. + // Otherwise, replace the min element with it and push upwards. + for (int index = heap_end_index; index < length; index += step_size) { + // We prefer elements with lower indices. This is given here. + // Later elements automatically have higher indices, so can be discarded. + if (input[index] > heap.root().value) { + // This element should replace the min. + heap.replace_root({index, input[index]}, k); + } + } + + // Sort if wanted. + if (sorted) { + heap.sort(k); + } +} + +// mergeShards performs a top-k merge on `num_shards` many sorted streams that +// are sorted and stored in `entries` in a strided way: +// |s_1 1st|s_2 1st|...s_{num_shards} 1st|s_1 2nd|s_2 2nd|... +// The overall top k elements are written to `top_k_values` and their indices +// to top_k_indices. +// `top_k_heap` is used as temporary storage for the merge heap. +template +__device__ void mergeShards(int num_shards, + int k, + Entry *__restrict__ entries, + Entry *__restrict__ top_k_heap, + float *top_k_values, + int *top_k_indices, + bool speculative_decoding) { + // If k < num_shards, we can use a min-heap with k elements to get the top k + // of the sorted blocks. + // If k > num_shards, we can initialize a min-heap with the top element from + // each sorted block. + int const heap_size = k < num_shards ? k : num_shards; + + // Min-heap part. + { + auto min_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Initialize the heap as a min-heap. + for (int slot = 0; slot < heap_size; slot++) { + min_heap.assign(slot, {slot, entries[slot].value}); + } + min_heap.build(heap_size); + + // Now perform top k with the remaining shards (if num_shards > heap_size). + for (int shard = heap_size; shard < num_shards; shard++) { + auto const entry = entries[shard]; + auto const root = min_heap.root(); + if (entry.value < root.value) { + continue; + } + if (entry.value == root.value && + entry.index > entries[root.index].index) { + continue; + } + // This element should replace the min. + min_heap.replace_root({shard, entry.value}, heap_size); + } + } + + // Max-part. + { + // Turn the min-heap into a max-heap in-place. + auto max_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Heapify into a max heap. + max_heap.build(heap_size); + + // Now extract the minimum k-1 times. + // k is treated specially. + int const last_k = k - 1; + for (int rank = 0; rank < last_k; rank++) { + Entry const &max_element = max_heap.root(); + if (speculative_decoding) { + assert(top_k_values != nullptr); + top_k_values[rank] = static_cast(max_element.value); + } + int shard_index = max_element.index; + top_k_indices[rank] = entries[shard_index].index; + int next_shard_index = shard_index + num_shards; + // For rank < k-1, each top k heap still contains at least 1 element, + // so we can draw a replacement. + max_heap.replace_root({next_shard_index, entries[next_shard_index].value}, + heap_size); + } + + // rank == last_k. + Entry const &max_element = max_heap.root(); + // top_k_values[last_k] = max_element.value; + int shard_index = max_element.index; + top_k_indices[last_k] = entries[shard_index].index; + } +} + +template +__global__ void arg_topk_forward_kernel(T const *__restrict__ input, + size_t shared_memory_size, + int length, + int k, + bool sorted, + float *__restrict__ output, + int *__restrict__ indices, + bool speculative_decoding) { + __shared__ char shared_memory[48 << 10]; + int const batch_index = blockIdx.x; + T const *batch_input = input + batch_index * length; + int const thread_index = threadIdx.x; + int const thread_count = blockDim.x; + Entry *shared_entries = (Entry *)shared_memory; + heapArgTopK( + batch_input, length, k, shared_entries, true, thread_index, thread_count); + __syncthreads(); + if (thread_index == 0) { + int const offset = batch_index * k; + auto batch_output = output + offset; + auto batch_indices = indices + offset; + Entry *top_k_heap = shared_entries + thread_count * k; + mergeShards(thread_count, + k, + shared_entries, + top_k_heap, + batch_output, + batch_indices, + speculative_decoding); + } +} + +/*static*/ +template +void ArgTopK::forward_kernel(ArgTopKMeta const *m, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + size_t batch_size, + int length, + int k, + bool sorted, + BeamSearchBatchConfig const *bc, + hipStream_t stream) { + // Adopted from TensorFlow's ArgTopK implementation + // https://github.com/tensorflow/tensorflow/blob/master/tensorflow/core/kernels/topk_op_gpu.h + int num_shards = 0; + { + constexpr auto shared_memory_size = 48 << 10; + auto const heap_size = k * sizeof(Entry
); + // shared_memory_size = (num_shards + 1) * heap_size <=> + num_shards = shared_memory_size / heap_size - 1; + assert(num_shards > 0); + if (num_shards > CUDA_NUM_THREADS) { + num_shards = CUDA_NUM_THREADS; + } + } + // We are limited by the amount of shared memory we have per block. + size_t shared_memory_size = (num_shards + 1) * k * sizeof(Entry
); + // size_t num_blocks = (batch_size + num_shards - 1) / num_shards; + size_t num_blocks = batch_size; + // all requests are in the same beam stages + if (m->speculative_decoding) { + assert(bc->num_active_requests() >= 0); + + // check + int beam_size = -1; + for (int i = 1; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } else if (beam_size == -1) { + beam_size = bc->beamRequestsInfo[i].beam_size; + } else { + assert(beam_size == bc->beamRequestsInfo[i].beam_size); + } + } + + assert(num_shards >= (size_t)beam_size); + num_shards = k; + arg_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + beam_size, + sorted, + output_ptr, + indices_ptr, + m->speculative_decoding); + } else { + + assert(num_shards >= (size_t)k); + num_shards = k; + arg_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + k, + sorted, + nullptr, + indices_ptr, + false); + } +} + +/*static*/ +void ArgTopK::forward_kernel_wrapper(ArgTopKMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &probs, + // float *output_ptr, + GenericTensorAccessorW const &indices, + int batch_size, + BeamSearchBatchConfig const *bc) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + // Domain in1_domain = runtime->get_index_space_domain( + // ctx, task->regions[0].region.get_index_space()); + // Domain out1_domain = runtime->get_index_space_domain( + // ctx, task->regions[1].region.get_index_space()); + // Domain out2_domain = runtime->get_index_space_domain( + // ctx, task->regions[1].region.get_index_space()); + int numdims = input.domain.get_dim(); + assert(indices.domain.get_dim() == numdims); + + int in_cols = input.domain.hi()[0] - input.domain.lo()[0] + 1; + // int out1_cols = out1_domain.hi()[0] - out1_domain.lo()[0] + 1; + int out2_cols = indices.domain.hi()[0] - indices.domain.lo()[0] + 1; + + // assert(out1_domain == out2_domain); + for (int i = 1; i < input.domain.get_dim(); i++) { + assert(input.domain.lo()[i] == indices.domain.lo()[i]); + assert(input.domain.hi()[i] == indices.domain.hi()[i]); + } + // float const *in_ptr = helperGetTensorPointerRO( + // regions[0], task->regions[0], FID_DATA, ctx, runtime); + // float *value_ptr = helperGetTensorPointerWO( + // regions[1], task->regions[1], FID_DATA, ctx, runtime); + // int *index_ptr = helperGetTensorPointerWO( + // regions[1], task->regions[1], FID_DATA, ctx, runtime); + + int length = input.domain.hi()[0] - input.domain.lo()[0] + 1; + int k = indices.domain.hi()[0] - indices.domain.lo()[0] + + 1; /*TODO: This prints to 5*/ + // size_t batch_size = input.domain.get_volume() / length; + // assert(indices.domain.get_volume() / k == batch_size); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA((&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + if (input.data_type == DT_HALF) { + ArgTopK::forward_kernel(m, + input.get_half_ptr(), + // output_ptr, + m->speculative_decoding ? probs.get_float_ptr() + : nullptr, + indices.get_int32_ptr(), + batch_size, + length, + k, + m->sorted, + m->speculative_decoding ? bc : nullptr, + stream); + } else if (input.data_type == DT_FLOAT) { + ArgTopK::forward_kernel(m, + input.get_float_ptr(), + // output_ptr, + m->speculative_decoding ? probs.get_float_ptr() + : nullptr, + indices.get_int32_ptr(), + batch_size, + length, + k, + m->sorted, + m->speculative_decoding ? bc : nullptr, + stream); + } else { + assert(false && "Unsupported data type"); + } + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + } +} + +ArgTopKMeta::ArgTopKMeta(FFHandler handler, Op const *op) + : OpMeta(handler, op) {} + +}; // namespace FlexFlow diff --git a/src/ops/arg_topk.cu b/src/ops/arg_topk.cu new file mode 100644 index 0000000000..5b7978812c --- /dev/null +++ b/src/ops/arg_topk.cu @@ -0,0 +1,541 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/arg_topk.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +enum class HeapType { kMinHeap, kMaxHeap }; +enum class PreferIndices { kLower, kHigher }; + +template +struct Entry { + int index; + T value; +}; + +template +struct LinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return data[i].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; +}; + +template +struct IndirectLinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return backing_data[data[i].index].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; + Entry *const backing_data; +}; + +template +struct StridedData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index * blockDim.x + threadIdx.x]; + } + + __device__ int get_index(int i) const { + return (*this)[i].index; + } + __device__ T get_value(int i) const { + return (*this)[i].value; + } + + Entry *const data; +}; + +// A heap of Entry that can either work as a min-heap or as a max-heap. +template + class Data, + typename T> +struct IndexedHeap { + typedef typename Data::Entry Entry; + Data const data; + __device__ IndexedHeap(Data const &d) : data(d) {} + + __device__ bool is_above(int left, int right) { + T left_value = data.get_value(left); + T right_value = data.get_value(right); + if (left_value == right_value) { + if (preferIndices == PreferIndices::kLower) { + return data.get_index(left) < data.get_index(right); + } else { + return data.get_index(left) > data.get_index(right); + } + } + if (heapType == HeapType::kMinHeap) { + return left_value < right_value; + } else { + return left_value > right_value; + } + } + + __device__ void assign(int i, Entry const &entry) { + data[i] = entry; + } + + __device__ void push_up(int i) { + int child = i; + int parent; + for (; child > 0; child = parent) { + parent = (child - 1) / 2; + if (!is_above(child, parent)) { + // Heap property satisfied. + break; + } + swap(child, parent); + } + } + + __device__ void swap(int a, int b) { + auto tmp = data[b]; + data[b] = data[a]; + data[a] = tmp; + } + + __device__ void push_root_down(int k) { + push_down(0, k); + } + + // MAX-HEAPIFY in Cormen + __device__ void push_down(int node, int k) { + while (true) { + int const left = 2 * node + 1; + int const right = left + 1; + int smallest = node; + if (left < k && is_above(left, smallest)) { + smallest = left; + } + if (right < k && is_above(right, smallest)) { + smallest = right; + } + if (smallest == node) { + break; + } + swap(smallest, node); + node = smallest; + } + } + + // BUILD-MAX-HEAPIFY in Cormen + __device__ void build(int k) { + for (int node = (k - 1) / 2; node >= 0; node--) { + push_down(node, k); + } + } + + // HEAP-EXTRACT-MAX in Cormen + __device__ void remove_root(int k) { + data[0] = data[k - 1]; + push_root_down(k - 1); + } + + // in-place HEAPSORT in Cormen + // This method destroys the heap property. + __device__ void sort(int k) { + for (int slot = k - 1; slot > 0; slot--) { + // This is like remove_root but we insert the element at the end. + swap(slot, 0); + // Heap is now an element smaller. + push_root_down(/*k=*/slot); + } + } + + __device__ void replace_root(Entry const &entry, int k) { + data[0] = entry; + push_root_down(k); + } + + __device__ Entry const &root() { + return data[0]; + } +}; + +template + class Data, + typename T> +__device__ IndexedHeap + make_indexed_heap(typename Data::Entry *data) { + return IndexedHeap{Data{data}}; +} + +// heapArgTopK walks over [input, input+length) with `step_size` stride starting +// at `start_index`. It builds a top-`k` heap that is stored in `heap_entries` +// using `Accessor` to access elements in `heap_entries`. If sorted=true, the +// elements will be sorted at the end. +template class Data = LinearData> +__device__ void heapArgTopK(T const *__restrict__ input, + int length, + int k, + Entry *__restrict__ heap_entries, + bool sorted = false, + int start_index = 0, + int step_size = 1) { + assert(k <= length); + + auto heap = + make_indexed_heap( + heap_entries); + + int heap_end_index = start_index + k * step_size; + if (heap_end_index > length) { + heap_end_index = length; + } + // Initialize the min-heap. + for (int index = start_index, slot = 0; index < heap_end_index; + index += step_size, slot++) { + heap.assign(slot, {index, input[index]}); + } + + heap.build(k); + + // Now iterate over the remaining items. + // If an item is smaller than the min element, it is not amongst the top k. + // Otherwise, replace the min element with it and push upwards. + for (int index = heap_end_index; index < length; index += step_size) { + // We prefer elements with lower indices. This is given here. + // Later elements automatically have higher indices, so can be discarded. + if (input[index] > heap.root().value) { + // This element should replace the min. + heap.replace_root({index, input[index]}, k); + } + } + + // Sort if wanted. + if (sorted) { + heap.sort(k); + } +} + +// mergeShards performs a top-k merge on `num_shards` many sorted streams that +// are sorted and stored in `entries` in a strided way: +// |s_1 1st|s_2 1st|...s_{num_shards} 1st|s_1 2nd|s_2 2nd|... +// The overall top k elements are written to `top_k_values` and their indices +// to top_k_indices. +// `top_k_heap` is used as temporary storage for the merge heap. +template +__device__ void mergeShards(int num_shards, + int k, + Entry *__restrict__ entries, + Entry *__restrict__ top_k_heap, + float *top_k_values, + int *top_k_indices, + bool speculative_decoding) { + // If k < num_shards, we can use a min-heap with k elements to get the top k + // of the sorted blocks. + // If k > num_shards, we can initialize a min-heap with the top element from + // each sorted block. + int const heap_size = k < num_shards ? k : num_shards; + + // Min-heap part. + { + auto min_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Initialize the heap as a min-heap. + for (int slot = 0; slot < heap_size; slot++) { + min_heap.assign(slot, {slot, entries[slot].value}); + } + min_heap.build(heap_size); + + // Now perform top k with the remaining shards (if num_shards > heap_size). + for (int shard = heap_size; shard < num_shards; shard++) { + auto const entry = entries[shard]; + auto const root = min_heap.root(); + if (entry.value < root.value) { + continue; + } + if (entry.value == root.value && + entry.index > entries[root.index].index) { + continue; + } + // This element should replace the min. + min_heap.replace_root({shard, entry.value}, heap_size); + } + } + + // Max-part. + { + // Turn the min-heap into a max-heap in-place. + auto max_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Heapify into a max heap. + max_heap.build(heap_size); + + // Now extract the minimum k-1 times. + // k is treated specially. + int const last_k = k - 1; + for (int rank = 0; rank < last_k; rank++) { + Entry const &max_element = max_heap.root(); + if (speculative_decoding) { + assert(top_k_values != nullptr); + top_k_values[rank] = static_cast(max_element.value); + } + + int shard_index = max_element.index; + top_k_indices[rank] = entries[shard_index].index; + int next_shard_index = shard_index + num_shards; + // For rank < k-1, each top k heap still contains at least 1 element, + // so we can draw a replacement. + max_heap.replace_root({next_shard_index, entries[next_shard_index].value}, + heap_size); + } + + // rank == last_k. + Entry const &max_element = max_heap.root(); + // top_k_values[last_k] = max_element.value; + int shard_index = max_element.index; + top_k_indices[last_k] = entries[shard_index].index; + } +} + +template +__global__ void arg_topk_forward_kernel(T const *__restrict__ input, + size_t shared_memory_size, + int length, + int k, + bool sorted, + float *__restrict__ output, + int *__restrict__ indices, + bool speculative_decoding) { + __shared__ char shared_memory[48 << 10]; + int const batch_index = blockIdx.x; + T const *batch_input = input + batch_index * length; + int const thread_index = threadIdx.x; + int const thread_count = blockDim.x; + Entry *shared_entries = (Entry *)shared_memory; + heapArgTopK( + batch_input, length, k, shared_entries, true, thread_index, thread_count); + __syncthreads(); + if (thread_index == 0) { + int const offset = batch_index * k; + auto batch_output = output + offset; + auto batch_indices = indices + offset; + Entry *top_k_heap = shared_entries + thread_count * k; + mergeShards(thread_count, + k, + shared_entries, + top_k_heap, + batch_output, + batch_indices, + speculative_decoding); + } +} + +/*static*/ +template +void ArgTopK::forward_kernel(ArgTopKMeta const *m, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + size_t batch_size, + int length, + int k, + bool sorted, + BeamSearchBatchConfig const *bc, + cudaStream_t stream) { + // Adopted from TensorFlow's ArgTopK implementation + // https://github.com/tensorflow/tensorflow/blob/master/tensorflow/core/kernels/topk_op_gpu.h + int num_shards = 0; + { + constexpr auto shared_memory_size = 48 << 10; + auto const heap_size = k * sizeof(Entry
); + // shared_memory_size = (num_shards + 1) * heap_size <=> + num_shards = shared_memory_size / heap_size - 1; + assert(num_shards > 0); + if (num_shards > CUDA_NUM_THREADS) { + num_shards = CUDA_NUM_THREADS; + } + } + // We are limited by the amount of shared memory we have per block. + size_t shared_memory_size = (num_shards + 1) * k * sizeof(Entry
); + // size_t num_blocks = (batch_size + num_shards - 1) / num_shards; + size_t num_blocks = batch_size; + + // all requests are in the same beam stages + if (m->speculative_decoding) { + assert(bc->num_active_requests() >= 0); + + // check + // allow last request different with others + int beam_size = -1; + int num_activate_requests = bc->num_active_requests(); + int last_request_idx = + bc->requestsInfo[num_activate_requests - 1].batch_config_request_id; + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } else if (beam_size == -1) { + beam_size = bc->beamRequestsInfo[i].beam_size; + + } else if (i != last_request_idx) { + assert(beam_size == bc->beamRequestsInfo[i].beam_size); + } else if (i == last_request_idx) { + } + } + assert(num_shards >= (size_t)beam_size); + num_shards = k; + arg_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + beam_size, + sorted, + output_ptr, + indices_ptr, + m->speculative_decoding); + } else { + + assert(num_shards >= (size_t)k); + num_shards = k; + arg_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + k, + sorted, + nullptr, + indices_ptr, + false); + } +} + +/*static*/ +void ArgTopK::forward_kernel_wrapper(ArgTopKMeta const *m, + GenericTensorAccessorR const &input, + // float *output_ptr, + GenericTensorAccessorW const &probs, + GenericTensorAccessorW const &indices, + int batch_size, + BeamSearchBatchConfig const *bc) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + // Domain in1_domain = runtime->get_index_space_domain( + // ctx, task->regions[0].region.get_index_space()); + // Domain out1_domain = runtime->get_index_space_domain( + // ctx, task->regions[1].region.get_index_space()); + // Domain out2_domain = runtime->get_index_space_domain( + // ctx, task->regions[1].region.get_index_space()); + int numdims = input.domain.get_dim(); + assert(indices.domain.get_dim() == numdims); + + int in_cols = input.domain.hi()[0] - input.domain.lo()[0] + 1; + // int out1_cols = out1_domain.hi()[0] - out1_domain.lo()[0] + 1; + int out2_cols = indices.domain.hi()[0] - indices.domain.lo()[0] + 1; + + // assert(out1_domain == out2_domain); + for (int i = 1; i < input.domain.get_dim(); i++) { + assert(input.domain.lo()[i] == indices.domain.lo()[i]); + assert(input.domain.hi()[i] == indices.domain.hi()[i]); + } + // float const *in_ptr = helperGetTensorPointerRO( + // regions[0], task->regions[0], FID_DATA, ctx, runtime); + // float *value_ptr = helperGetTensorPointerWO( + // regions[1], task->regions[1], FID_DATA, ctx, runtime); + // int *index_ptr = helperGetTensorPointerWO( + // regions[1], task->regions[1], FID_DATA, ctx, runtime); + + int length = input.domain.hi()[0] - input.domain.lo()[0] + 1; + int k = indices.domain.hi()[0] - indices.domain.lo()[0] + + 1; /*TODO: This prints to 5*/ + + // batch_size = input.domain.get_volume() / length; + // assert(indices.domain.get_volume() / k == batch_size); + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + if (input.data_type == DT_HALF) { + ArgTopK::forward_kernel(m, + input.get_half_ptr(), + m->speculative_decoding ? probs.get_float_ptr() + : nullptr, + indices.get_int32_ptr(), + batch_size, + length, + k, + m->sorted, + m->speculative_decoding ? bc : nullptr, + stream); + } else if (input.data_type == DT_FLOAT) { + ArgTopK::forward_kernel(m, + input.get_float_ptr(), + m->speculative_decoding ? probs.get_float_ptr() + : nullptr, + indices.get_int32_ptr(), + batch_size, + length, + k, + m->sorted, + m->speculative_decoding ? bc : nullptr, + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[ArgTopK] forward time = %.2lfms\n", elapsed); + } +} + +ArgTopKMeta::ArgTopKMeta(FFHandler handler, Op const *op) + : OpMeta(handler, op) {} + +}; // namespace FlexFlow diff --git a/src/ops/argmax.cc b/src/ops/argmax.cc new file mode 100644 index 0000000000..a52ce1886b --- /dev/null +++ b/src/ops/argmax.cc @@ -0,0 +1,459 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/argmax.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + +namespace FlexFlow { +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +Tensor FFModel::argmax(const Tensor input, bool beam_search, char const *name) { + Layer *li = new Layer(this, + OP_ARGMAX, + input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + beam_search ? 2 : 1 /*outputs*/, + input); + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + // now just support 1 output + dims[0] = 1; + // li->outputs[0] = create_tensor_legion_ordering( + // numdims, dims, input->data_type, li, 0, true /*create_grad*/); + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 0, false /*create_grad*/); + if (beam_search) { + // parent id + li->outputs[1] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 1, false /*create_grad*/); + } + } + li->add_int_property("beam_search", beam_search); + layers.push_back(li); + // outputs[0] = li->outputs[0]; + // outputs[1] = li->outputs[1]; + return li->outputs[0]; +} + +Op *ArgMax::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("beam_search", value); + bool beam_search = (bool)value; + return new ArgMax(model, inputs[0], beam_search, layer->name); +} + +ArgMaxParams ArgMax::get_params() const { + ArgMaxParams params; + params.beam_search = this->beam_search; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +bool ArgMaxParams::is_valid(ParallelTensorShape const &) const { + return true; +} + +bool operator==(ArgMaxParams const &lhs, ArgMaxParams const &rhs) { + return lhs.beam_search == rhs.beam_search; +} + +ArgMax::ArgMax(FFModel &model, + const ParallelTensor _input, + bool _beam_search, + char const *name) + : Op(model, + OP_ARGMAX, + _input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + _beam_search ? 2 : 1 /*outputs*/, + _input), + beam_search(_beam_search) { + int numdim = inputs[0]->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = inputs[0]->dims[i]; + } + dims[0].size = 1; + assert(inputs[0]->dims[0].degree == 1); + assert(inputs[0]->dims[0].parallel_idx == -1); + // outputs[0] = model.create_parallel_tensor_legion_ordering( + // numdim, dims, _input->data_type, this, 0 /*owner_idx*/); + outputs[0] = model.create_parallel_tensor_legion_ordering( + numdim, dims, DT_INT32, this, 0 /*owner_idx*/); + if (_beam_search) { + outputs[1] = model.create_parallel_tensor_legion_ordering( + numdim, dims, DT_INT32, this, 1 /*owner_idx*/); + } +} + +ArgMax::ArgMax(FFModel &model, ArgMax const &other, const ParallelTensor input) + : ArgMax(model, input, other.beam_search, other.name) {} + +ArgMax::ArgMax(FFModel &model, + ArgMaxParams const ¶ms, + const ParallelTensor input, + char const *name) + : ArgMax(model, input, params.beam_search, params.name) {} + +void ArgMax::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ARGMAX_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ArgMax)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void ArgMax::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(ARGMAX_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ArgMax)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *ArgMax::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + ArgMax *s = (ArgMax *)task->args; + FFHandler handle = *((FFHandler *)task->local_args); + GenericTensorAccessorW acc_input = + helperGetGenericTensorAccessorRW(s->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + int length = acc_input.domain.hi()[0] - acc_input.domain.lo()[0] + 1; + int batch_size = acc_input.domain.get_volume() / length; + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + + ArgMaxMeta *m = new ArgMaxMeta(handle, + s, + input_domain, + output_domain, + acc_input, + batch_size, + length * batch_size, + gpu_mem_allocator); + m->profiling = s->profiling; + m->inference_debugging = s->inference_debugging; + m->beam_search = s->beam_search; + std::strcpy(m->op_name, s->name); + m->layer_guid = s->layer_guid; + return m; +} + +void ArgMax::forward(FFModel const &ff) { + // ArgMax does not support forward + assert(false); +} + +FutureMap ArgMax::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "ArgMax op machine_view: " << *(MachineView const *)mv + << std::endl; */ + if (beam_search) { + IndexLauncher launcher(ARGMAX_BEAM_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); + } else { + IndexLauncher launcher(ARGMAX_NORM_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); + } +} + +BeamInferenceResult + ArgMax::inference_task_beam(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 3); + assert(task->regions.size() == 3); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + // Directly return for empty batch config + BeamInferenceResult ir; + return ir; + } + ArgMaxMeta *m = *((ArgMaxMeta **)task->local_args); + + GenericTensorAccessorW input = helperGetGenericTensorAccessorRW( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW indices = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + int batch_size = bc->num_active_tokens(); + GenericTensorAccessorW parent = helperGetGenericTensorAccessorWO( + DT_INT32, regions[2], task->regions[2], FID_DATA, ctx, runtime); + ArgMax::forward_kernel_wrapper(m, input, indices, parent, batch_size); + BeamInferenceResult ir; + download_tensor( + indices.get_int32_ptr(), ir.token_ids, batch_size); + download_tensor(m->probs, ir.probs, batch_size); + download_tensor(parent.get_int32_ptr(), ir.parent_id, batch_size); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + ArgMax::save_inference_tensors_to_file( + m, shard_id, bc, {}, {}, {input, indices, parent}); + } + + return ir; +} + +InferenceResult + ArgMax::inference_task_norm(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + ArgMaxMeta *m = *((ArgMaxMeta **)task->local_args); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + // Directly return for empty batch config + InferenceResult ir; + return ir; + } + + GenericTensorAccessorW input = helperGetGenericTensorAccessorRW( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW indices = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW parent; + int batch_size = bc->num_active_tokens(); + ArgMax::forward_kernel_wrapper(m, input, indices, parent, batch_size); + InferenceResult ir; + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + ArgMax::save_inference_tensors_to_file( + m, shard_id, bc, {}, {}, {input, indices}); + } + + download_tensor( + indices.get_int32_ptr(), ir.token_ids, batch_size); + return ir; +} + +void ArgMax::backward(FFModel const &ff) { + // ArgMax does not support backward + assert(false); +} + +void ArgMax::serialize(Legion::Serializer &sez) const { + sez.serialize(this->beam_search); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +Node ArgMax::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + bool beam_search; + dez.deserialize(beam_search); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + ArgMaxParams params; + params.beam_search = beam_search; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); +} + +Op *ArgMax::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + ArgMaxParams params = get_params(); + return new ArgMax(ff, params, inputs[0], this->name); +} + +bool ArgMax::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::ArgMaxParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.beam_search); + return key; +} +}; // namespace std \ No newline at end of file diff --git a/src/ops/argmax.cpp b/src/ops/argmax.cpp new file mode 100644 index 0000000000..8a1cf0b3b0 --- /dev/null +++ b/src/ops/argmax.cpp @@ -0,0 +1,504 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/argmax.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include +#include + +namespace FlexFlow { + +using Legion::coord_t; + +enum class HeapType { kMinHeap, kMaxHeap }; +enum class PreferIndices { kLower, kHigher }; + +template +struct Entry { + int index; + T value; +}; + +template +struct LinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return data[i].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; +}; + +template +struct IndirectLinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return backing_data[data[i].index].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; + Entry *const backing_data; +}; + +template +struct StridedData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index * blockDim.x + threadIdx.x]; + } + + __device__ int get_index(int i) const { + return (*this)[i].index; + } + __device__ T get_value(int i) const { + return (*this)[i].value; + } + + Entry *const data; +}; + +// A heap of Entry that can either work as a min-heap or as a max-heap. +template + class Data, + typename T> +struct IndexedHeap { + typedef typename Data::Entry Entry; + Data const data; + __device__ IndexedHeap(Data const &d) : data(d) {} + + __device__ bool is_above(int left, int right) { + T left_value = data.get_value(left); + T right_value = data.get_value(right); + if (left_value == right_value) { + if (preferIndices == PreferIndices::kLower) { + return data.get_index(left) < data.get_index(right); + } else { + return data.get_index(left) > data.get_index(right); + } + } + if (heapType == HeapType::kMinHeap) { + return left_value < right_value; + } else { + return left_value > right_value; + } + } + + __device__ void assign(int i, Entry const &entry) { + data[i] = entry; + } + + __device__ void push_up(int i) { + int child = i; + int parent; + for (; child > 0; child = parent) { + parent = (child - 1) / 2; + if (!is_above(child, parent)) { + // Heap property satisfied. + break; + } + swap(child, parent); + } + } + + __device__ void swap(int a, int b) { + auto tmp = data[b]; + data[b] = data[a]; + data[a] = tmp; + } + + __device__ void push_root_down(int k) { + push_down(0, k); + } + + // MAX-HEAPIFY in Cormen + __device__ void push_down(int node, int k) { + while (true) { + int const left = 2 * node + 1; + int const right = left + 1; + int smallest = node; + if (left < k && is_above(left, smallest)) { + smallest = left; + } + if (right < k && is_above(right, smallest)) { + smallest = right; + } + if (smallest == node) { + break; + } + swap(smallest, node); + node = smallest; + } + } + + // BUILD-MAX-HEAPIFY in Cormen + __device__ void build(int k) { + for (int node = (k - 1) / 2; node >= 0; node--) { + push_down(node, k); + } + } + + // HEAP-EXTRACT-MAX in Cormen + __device__ void remove_root(int k) { + data[0] = data[k - 1]; + push_root_down(k - 1); + } + + // in-place HEAPSORT in Cormen + // This method destroys the heap property. + __device__ void sort(int k) { + for (int slot = k - 1; slot > 0; slot--) { + // This is like remove_root but we insert the element at the end. + swap(slot, 0); + // Heap is now an element smaller. + push_root_down(/*k=*/slot); + } + } + + __device__ void replace_root(Entry const &entry, int k) { + data[0] = entry; + push_root_down(k); + } + + __device__ Entry const &root() { + return data[0]; + } +}; + +template + class Data, + typename T> +__device__ IndexedHeap + make_indexed_heap(typename Data::Entry *data) { + return IndexedHeap{Data{data}}; +} + +// heapArgTopK walks over [input, input+length) with `step_size` stride starting +// at `start_index`. It builds a top-`k` heap that is stored in `heap_entries` +// using `Accessor` to access elements in `heap_entries`. If sorted=true, the +// elements will be sorted at the end. +template class Data = LinearData> +__device__ void heapArgTopK(T const *__restrict__ input, + int length, + int k, + Entry *__restrict__ heap_entries, + bool sorted = false, + int start_index = 0, + int step_size = 1) { + assert(k <= length); + + auto heap = + make_indexed_heap( + heap_entries); + + int heap_end_index = start_index + k * step_size; + if (heap_end_index > length) { + heap_end_index = length; + } + // Initialize the min-heap. + for (int index = start_index, slot = 0; index < heap_end_index; + index += step_size, slot++) { + heap.assign(slot, {index, input[index]}); + } + + heap.build(k); + + // Now iterate over the remaining items. + // If an item is smaller than the min element, it is not amongst the top k. + // Otherwise, replace the min element with it and push upwards. + for (int index = heap_end_index; index < length; index += step_size) { + // We prefer elements with lower indices. This is given here. + // Later elements automatically have higher indices, so can be discarded. + if (input[index] > heap.root().value) { + // This element should replace the min. + heap.replace_root({index, input[index]}, k); + } + } + + // Sort if wanted. + if (sorted) { + heap.sort(k); + } +} + +// mergeShards performs a top-k merge on `num_shards` many sorted streams that +// are sorted and stored in `entries` in a strided way: +// |s_1 1st|s_2 1st|...s_{num_shards} 1st|s_1 2nd|s_2 2nd|... +// The overall top k elements are written to `top_k_values` and their indices +// to top_k_indices. +// `top_k_heap` is used as temporary storage for the merge heap. +template +__device__ void mergeShards(int num_shards, + int k, + Entry *__restrict__ entries, + Entry *__restrict__ top_k_heap, + float *top_k_values, + int *top_k_indices) { + // If k < num_shards, we can use a min-heap with k elements to get the top k + // of the sorted blocks. + // If k > num_shards, we can initialize a min-heap with the top element from + // each sorted block. + int const heap_size = k < num_shards ? k : num_shards; + + // Min-heap part. + { + auto min_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Initialize the heap as a min-heap. + for (int slot = 0; slot < heap_size; slot++) { + min_heap.assign(slot, {slot, entries[slot].value}); + } + min_heap.build(heap_size); + + // Now perform top k with the remaining shards (if num_shards > heap_size). + for (int shard = heap_size; shard < num_shards; shard++) { + auto const entry = entries[shard]; + auto const root = min_heap.root(); + if (entry.value < root.value) { + continue; + } + if (entry.value == root.value && + entry.index > entries[root.index].index) { + continue; + } + // This element should replace the min. + min_heap.replace_root({shard, entry.value}, heap_size); + } + } + + // Max-part. + { + // Turn the min-heap into a max-heap in-place. + auto max_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Heapify into a max heap. + max_heap.build(heap_size); + + // Now extract the minimum k-1 times. + // k is treated specially. + int const last_k = k - 1; + for (int rank = 0; rank < last_k; rank++) { + Entry const &max_element = max_heap.root(); + top_k_values[rank] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[rank] = entries[shard_index].index; + int next_shard_index = shard_index + num_shards; + // For rank < k-1, each top k heap still contains at least 1 element, + // so we can draw a replacement. + max_heap.replace_root({next_shard_index, entries[next_shard_index].value}, + heap_size); + } + + // rank == last_k. + Entry const &max_element = max_heap.root(); + top_k_values[last_k] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[last_k] = entries[shard_index].index; + } +} + +template +__global__ void argmax_forward_kernel(T const *__restrict__ input, + size_t shared_memory_size, + int length, + int k, + float *__restrict__ output, + int *__restrict__ indices) { + __shared__ char shared_memory[48 << 10]; + int const batch_index = blockIdx.x; + T const *batch_input = input + batch_index * length; + int const thread_index = threadIdx.x; + int const thread_count = blockDim.x; + Entry *shared_entries = (Entry *)shared_memory; + heapArgTopK( + batch_input, length, k, shared_entries, true, thread_index, thread_count); + __syncthreads(); + if (thread_index == 0) { + int const offset = batch_index * k; + auto batch_output = output + offset; + auto batch_indices = indices + offset; + Entry *top_k_heap = shared_entries + thread_count * k; + mergeShards(thread_count, + k, + shared_entries, + top_k_heap, + batch_output, + batch_indices); + } +} + +template +__global__ void copy_result(hipcub::KeyValuePair *d_out, + int *indices, + float *prob_ptr, + int batch_size, + bool beam_search) { + CUDA_KERNEL_LOOP(i, batch_size) { + indices[i] = d_out[i].key; + if (beam_search) { + prob_ptr[i] = static_cast(d_out[i].value); + } + } +} + +/*static*/ +template +void ArgMax::forward_kernel(ArgMaxMeta const *m, + DT *input_ptr, + int *indices_ptr, + float *prob_ptr, + int *parent, + int const length, + int const batch_size, + hipStream_t stream) { + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(miopenSetStream(m->handle.dnn, stream)); + + if (m->beam_search) { + // set all parents id zero in arg top1 case. + checkCUDA(hipMemsetAsync(parent, 0, batch_size * sizeof(int), stream)); + } + int num_shards = 0; + int k = 1; + { + constexpr auto shared_memory_size = 48 << 10; + auto const heap_size = k * sizeof(Entry
); + // shared_memory_size = (num_shards + 1) * heap_size <=> + num_shards = shared_memory_size / heap_size - 1; + assert(num_shards > 0); + if (num_shards > CUDA_NUM_THREADS) { + num_shards = CUDA_NUM_THREADS; + } + } + // We are limited by the amount of shared memory we have per block. + size_t shared_memory_size = (num_shards + 1) * k * sizeof(Entry
); + // size_t num_blocks = (batch_size + num_shards - 1) / num_shards; + size_t num_blocks = batch_size; + assert(num_shards >= (size_t)k); + num_shards = k; + + hipLaunchKernelGGL(argmax_forward_kernel, + num_blocks, + num_shards, + 0, + stream, + input_ptr, + shared_memory_size, + length, + k, + prob_ptr, + indices_ptr); +} + +/*static*/ +void ArgMax::forward_kernel_wrapper(ArgMaxMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + GenericTensorAccessorW const &parent, + int batch_size) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + int length = input.domain.hi()[0] - input.domain.lo()[0] + 1; + + if (input.data_type == DT_HALF) { + ArgMax::forward_kernel(m, + input.get_half_ptr(), + indices.get_int32_ptr(), + m->probs, + m->beam_search ? parent.get_int32_ptr() + : nullptr, + length, + batch_size, + stream); + + } else if (input.data_type == DT_FLOAT) { + ArgMax::forward_kernel(m, + input.get_float_ptr(), + indices.get_int32_ptr(), + m->probs, + m->beam_search ? parent.get_int32_ptr() + : nullptr, + length, + batch_size, + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + } +} + +ArgMaxMeta::ArgMaxMeta(FFHandler handler, + Op const *op, + Legion::Domain const &input_domain, + Legion::Domain const &output_domain, + GenericTensorAccessorW input, + int batch_size, + int total_ele, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, op) { + DataType data_type = op->data_type; + size_t prob_size = batch_size; + assert(data_type == DT_FLOAT || data_type == DT_HALF); + size_t total_size = prob_size * sizeof(float); + gpu_mem_allocator.create_legion_instance(reserveInst, total_size); + probs = gpu_mem_allocator.allocate_instance(prob_size); +} +ArgMaxMeta::~ArgMaxMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +}; // namespace FlexFlow \ No newline at end of file diff --git a/src/ops/argmax.cu b/src/ops/argmax.cu new file mode 100644 index 0000000000..05c84719c1 --- /dev/null +++ b/src/ops/argmax.cu @@ -0,0 +1,212 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/argmax.h" +#include "flexflow/utils/cuda_helper.h" +#include + +namespace FlexFlow { + +__global__ void init_offset(int batch_size, + int vocab_size, + int total_eles, + int *d_offsets) { + CUDA_KERNEL_LOOP(i, total_eles) { + if (i % vocab_size == 0) { + d_offsets[i / vocab_size] = i; + } + } +} + +template +__global__ void copy_result(cub::KeyValuePair *d_out, + int *indices, + float *prob_ptr, + int batch_size, + bool beam_search) { + CUDA_KERNEL_LOOP(i, batch_size) { + indices[i] = d_out[i].key; + if (beam_search) { + prob_ptr[i] = static_cast(d_out[i].value); + } + } +} + +/*static*/ +template +void ArgMax::forward_kernel(ArgMaxMeta const *m, + DT *input_ptr, + int *indices_ptr, + float *prob_ptr, + int *parent, + int const length, + int const batch_size, + cudaStream_t stream) { + + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + DT alpha = 1.0f, beta = 0.0f; + if (m->beam_search) { + // set all parents id zero in arg top1 case. + checkCUDA(cudaMemsetAsync(parent, 0, batch_size * sizeof(int), stream)); + } + size_t temp_storage_bytes = m->temp_storage_bytes; + // use cub + checkCUDA(cub::DeviceSegmentedReduce::ArgMax( + m->d_temp_storage, + temp_storage_bytes, + input_ptr, + static_cast *>(m->d_out), + batch_size, + m->d_offsets, + m->d_offsets + 1, + stream)); + + // copy dout to incides + int parallelism = batch_size; + copy_result<<>>(static_cast *>(m->d_out), + indices_ptr, + prob_ptr, + batch_size, + m->beam_search); + // print_tensor(indices_ptr, 32, "argmax op"); +} + +/*static*/ +void ArgMax::forward_kernel_wrapper(ArgMaxMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + GenericTensorAccessorW const &parent, + int batch_size) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + int length = input.domain.hi()[0] - input.domain.lo()[0] + 1; + + if (input.data_type == DT_HALF) { + ArgMax::forward_kernel(m, + input.get_half_ptr(), + indices.get_int32_ptr(), + m->probs, + m->beam_search ? parent.get_int32_ptr() + : nullptr, + length, + batch_size, + stream); + + } else if (input.data_type == DT_FLOAT) { + ArgMax::forward_kernel(m, + input.get_float_ptr(), + indices.get_int32_ptr(), + m->probs, + m->beam_search ? parent.get_int32_ptr() + : nullptr, + length, + batch_size, + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[ArgMax] forward time = %.2lfms\n", elapsed); + } +} + +ArgMaxMeta::ArgMaxMeta(FFHandler handler, + Op const *op, + Legion::Domain const &input_domain, + Legion::Domain const &output_domain, + GenericTensorAccessorW input, + int batch_size, + int total_ele, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, op) { + DataType data_type = op->data_type; + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + size_t d_offsets_size = batch_size; + size_t prob_size = batch_size; + assert(data_type == DT_FLOAT || data_type == DT_HALF); + size_t total_size = + d_offsets_size * sizeof(int) + + (data_type == DT_FLOAT + ? sizeof(cub::KeyValuePair) * batch_size + : sizeof(cub::KeyValuePair) * batch_size) + + prob_size * sizeof(float); + gpu_mem_allocator.create_legion_instance(reserveInst, total_size); + d_offsets = gpu_mem_allocator.allocate_instance(d_offsets_size); + d_out = data_type == DT_FLOAT + ? gpu_mem_allocator.allocate_instance_untyped( + batch_size * sizeof(cub::KeyValuePair)) + : gpu_mem_allocator.allocate_instance_untyped( + batch_size * sizeof(cub::KeyValuePair)); + probs = gpu_mem_allocator.allocate_instance(prob_size); + // init offset + int parallelism = total_ele; + init_offset<<>>( + batch_size, total_ele / batch_size, total_ele, d_offsets); + + if (data_type == DT_FLOAT) { + checkCUDA(cub::DeviceSegmentedReduce::ArgMax( + d_temp_storage, + temp_storage_bytes, + input.get_float_ptr(), + static_cast *>(d_out), + batch_size, + d_offsets, + d_offsets + 1, + stream)); + + } else if (data_type == DT_HALF) { + checkCUDA(cub::DeviceSegmentedReduce::ArgMax( + d_temp_storage, + temp_storage_bytes, + input.get_half_ptr(), + static_cast *>(d_out), + batch_size, + d_offsets, + d_offsets + 1, + stream)); + } + + gpu_mem_allocator.create_legion_instance(reserveInst, temp_storage_bytes); + d_temp_storage = + gpu_mem_allocator.allocate_instance_untyped(temp_storage_bytes); +} + +ArgMaxMeta::~ArgMaxMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +}; // namespace FlexFlow \ No newline at end of file diff --git a/src/ops/attention.cc b/src/ops/attention.cc index 9c9c87bd56..97afc94341 100644 --- a/src/ops/attention.cc +++ b/src/ops/attention.cc @@ -59,8 +59,11 @@ Tensor FFModel::multihead_attention(const Tensor query, bool bias, bool add_bias_kv, bool add_zero_attn, + DataType data_type, Initializer *kernel_initializer, char const *name) { + // Currently only support float for the original attention operator + assert(data_type == DT_NONE || data_type == DT_FLOAT); Layer *li = new Layer(this, OP_MULTIHEAD_ATTENTION, DT_FLOAT, @@ -217,17 +220,12 @@ MultiHeadAttention::MultiHeadAttention(FFModel &model, dims[2].parallel_idx = -1; int seed = std::rand(); Initializer *initializer = new GlorotUniform(seed); -#ifdef USE_NCCL - ParameterSyncType comm_type = ParameterSyncType::NCCL; -#else - ParameterSyncType comm_type = ParameterSyncType::PS; -#endif weights[0] = model.create_parallel_weight<3>(dims, DT_FLOAT, NULL /*owner_op*/, true /*create_grad*/, initializer, - comm_type); + CHOSEN_SYNC_TYPE); } outputs[0] = model.create_parallel_tensor_legion_ordering( @@ -304,17 +302,12 @@ MultiHeadAttention::MultiHeadAttention(FFModel &model, dims[2].size = qParas + kParas + vParas + oParas; int seed = std::rand(); Initializer *initializer = new GlorotUniform(seed); -#ifdef USE_NCCL - ParameterSyncType comm_type = ParameterSyncType::NCCL; -#else - ParameterSyncType comm_type = ParameterSyncType::PS; -#endif weights[0] = model.create_parallel_weight<3>(dims, DT_FLOAT, NULL /*owner_op*/, true /*create_grad*/, initializer, - comm_type); + CHOSEN_SYNC_TYPE); } outputs[0] = model.create_parallel_tensor_legion_ordering( _query->num_dims, dims, DT_FLOAT, this); @@ -370,7 +363,63 @@ MultiHeadAttention::MultiHeadAttention( params.add_bias_kv, params.add_zero_attn, allocate_weights, - name) {} + params.name) {} + +void MultiHeadAttention::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(MultiHeadAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(4, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} void MultiHeadAttention::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -472,6 +521,9 @@ OpMeta * MultiHeadAttentionMeta *m = new MultiHeadAttentionMeta(handle, attn, gpu_mem, num_samples, num_heads); m->profiling = attn->profiling; + m->inference_debugging = attn->inference_debugging; + std::strcpy(m->op_name, attn->name); + m->layer_guid = attn->layer_guid; assert(acc_weight.rect.volume() * sizeof(float) == m->weightSize); return m; } @@ -523,6 +575,64 @@ void MultiHeadAttention::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap MultiHeadAttention::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "MultiHeadAttention op machine_view: " << *(MachineView const + *)mv + << std::endl; */ + int idx = 0; + IndexLauncher launcher(ATTENTION_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(4, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + /* regions[0](I): query regions[1](I): key @@ -824,7 +934,7 @@ bool MultiHeadAttention::measure_operator_cost( cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, query_ptr, query_grad_ptr, @@ -903,6 +1013,9 @@ MultiHeadAttentionParams MultiHeadAttention::get_params() const { params.bias = this->bias; params.add_bias_kv = this->add_bias_kv; params.add_zero_attn = this->add_zero_attn; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } diff --git a/src/ops/attention.cpp b/src/ops/attention.cpp index 9b6ad6cb46..ee7f87a7fb 100644 --- a/src/ops/attention.cpp +++ b/src/ops/attention.cpp @@ -56,19 +56,19 @@ void MultiHeadAttention::forward_kernel_wrapper(MultiHeadAttentionMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } MultiHeadAttention::forward_kernel( m, query_ptr, key_ptr, value_ptr, weight_ptr, output_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("MultiHeadAttention forward time = %.2fms\n", elapsed); // print_tensor<3, float>(acc_query.ptr, acc_query.rect, // "[Attention:forward:query]"); print_tensor<3, float>(acc_output.ptr, @@ -124,9 +124,9 @@ void MultiHeadAttention::backward_kernel_wrapper( hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } MultiHeadAttention::backward_kernel(m, @@ -141,12 +141,12 @@ void MultiHeadAttention::backward_kernel_wrapper( output_grad_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("MultiHeadAttention backward time = %.2fms\n", elapsed); } } diff --git a/src/ops/batch_matmul.cc b/src/ops/batch_matmul.cc index 977c5443b9..e13169f6c1 100644 --- a/src/ops/batch_matmul.cc +++ b/src/ops/batch_matmul.cc @@ -138,7 +138,7 @@ BatchMatmul::BatchMatmul( inputs.second, params.a_seq_length_dim, params.b_seq_length_dim, - name) {} + params.name) {} // return A*B BatchMatmul::BatchMatmul(FFModel &model, @@ -190,6 +190,8 @@ void BatchMatmul::serialize(Legion::Serializer &sez) const { BatchMatmulParams params = get_params(); sez.serialize(params.a_seq_length_dim); sez.serialize(params.b_seq_length_dim); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -202,10 +204,15 @@ Node BatchMatmul::deserialize(FFModel &ff, int a_seq_length_dim, b_seq_length_dim; dez.deserialize(a_seq_length_dim); dez.deserialize(b_seq_length_dim); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); BatchMatmulParams params; params.a_seq_length_dim = a_seq_length_dim; params.b_seq_length_dim = b_seq_length_dim; + strcpy(params.name, name); return ff.get_or_create_node({inputs[0], inputs[1]}, params); } @@ -274,8 +281,11 @@ OpMeta *BatchMatmul::init_task(Task const *task, FFHandler handle = *((FFHandler const *)task->local_args); BatchMatmulMeta *m = new BatchMatmulMeta(handle); m->profiling = bmm->profiling; + m->inference_debugging = bmm->inference_debugging; m->a_seq_length_dim = bmm->a_seq_length_dim; m->b_seq_length_dim = bmm->b_seq_length_dim; + std::strcpy(m->op_name, bmm->name); + m->layer_guid = bmm->layer_guid; return m; } diff --git a/src/ops/batch_norm.cc b/src/ops/batch_norm.cc index 4027313a20..03ef486e5f 100644 --- a/src/ops/batch_norm.cc +++ b/src/ops/batch_norm.cc @@ -286,7 +286,7 @@ bool BatchNorm::measure_operator_cost(Simulator *sim, cost_metrics.weights_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { + backward = [=] { backward_kernel(m, input_ptr, output_grad_ptr, diff --git a/src/ops/batch_norm.cpp b/src/ops/batch_norm.cpp index a0a2d47e24..106e5ebad2 100644 --- a/src/ops/batch_norm.cpp +++ b/src/ops/batch_norm.cpp @@ -133,9 +133,9 @@ __host__ void hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } forward_kernel(m, acc_input.ptr, @@ -143,12 +143,12 @@ __host__ void acc_scale.ptr, acc_bias.ptr /*, stream*/); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("BatchNorm forward time (BF) = %.2fms\n", elapsed); } } @@ -256,9 +256,9 @@ __host__ void hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } backward_kernel(m, acc_input.ptr, @@ -270,12 +270,12 @@ __host__ void acc_bias_grad.ptr, acc_output.rect.volume() /*, stream*/); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("BatchNorm backward time = %.2fms\n", elapsed); } } @@ -293,6 +293,7 @@ BatchNormMeta::BatchNormMeta(FFHandler handler, checkCUDNN(miopenCreateTensorDescriptor(&outputTensor)); relu = bn->relu; profiling = bn->profiling; + inference_debugging = bn->inference_debugging; mode = miopenBNSpatial; // #if HIPDNN_VERSION >= 7000 // mode = HIPDNN_BATCHNORM_SPATIAL_PERSISTENT; diff --git a/src/ops/batch_norm.cu b/src/ops/batch_norm.cu index c17244dce0..b77e9d489f 100644 --- a/src/ops/batch_norm.cu +++ b/src/ops/batch_norm.cu @@ -279,6 +279,7 @@ BatchNormMeta::BatchNormMeta(FFHandler handler, checkCUDNN(cudnnCreateTensorDescriptor(&outputTensor)); relu = bn->relu; profiling = bn->profiling; + inference_debugging = bn->inference_debugging; mode = CUDNN_BATCHNORM_SPATIAL; #if CUDNN_VERSION >= 7000 mode = CUDNN_BATCHNORM_SPATIAL_PERSISTENT; diff --git a/src/ops/beam_topk.cc b/src/ops/beam_topk.cc new file mode 100644 index 0000000000..d2054cacb0 --- /dev/null +++ b/src/ops/beam_topk.cc @@ -0,0 +1,476 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/beam_topk.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + +namespace FlexFlow { +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +// For an input tensor, computes the top k entries in each row +// (resp. vector along the last dimension). Thus, +// values.shape = indices.shape = input.shape[:-1] + [k] +Tensor FFModel::beam_top_k(const Tensor input, + int max_beam_width, + bool sorted, + char const *name) { + Layer *li = new Layer(this, + OP_BEAM_TOPK, + input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + 3 /*outputs*/, + input); + { + int numdims = input->num_dims; + + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + dims[0] = max_beam_width; + + std::cout << "beam input dimen:" << numdims << "\n"; + for (int i = 0; i < numdims; i++) { + std::cout << input->dims[i] << ", "; + } + + // beam width is dynamic + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 0, false /*create_grad*/); + li->outputs[1] = create_tensor_legion_ordering( + numdims, dims, DT_FLOAT, li, 1, false /*create_grad*/); + li->outputs[2] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 1, false /*create_grad*/); + } + li->add_int_property("sorted", sorted); + li->add_int_property("max_beam_width", max_beam_width); + layers.push_back(li); + // outputs[0] = li->outputs[0]; + // outputs[1] = li->outputs[1]; + return li->outputs[1]; +} + +Op *BeamTopK::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("sorted", value); + bool sorted = (bool)value; + layer->get_int_property("max_beam_width", value); + int max_beam_width = value; + return new BeamTopK( + model, inputs[0], layer->layer_guid, max_beam_width, sorted, layer->name); +} + +BeamTopKParams BeamTopK::get_params() const { + BeamTopKParams params; + params.layer_guid = this->layer_guid; + params.sorted = this->sorted; + params.max_beam_width = this->max_beam_width; + return params; +} + +bool BeamTopKParams::is_valid(ParallelTensorShape const &) const { + // topk is always valid + return true; +} + +bool operator==(BeamTopKParams const &lhs, BeamTopKParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.sorted == rhs.sorted && + lhs.max_beam_width == rhs.max_beam_width; +} + +BeamTopK::BeamTopK(FFModel &model, + const ParallelTensor _input, + LayerID const &_layer_guid, + int _max_beam_width, + bool _sorted, + char const *name) + : Op(model, + OP_BEAM_TOPK, + _input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + 3 /*outputs*/, + _input) { + sorted = _sorted; + max_beam_width = _max_beam_width; + layer_guid = _layer_guid; + int numdim = inputs[0]->num_dims; + assert(inputs[0]->dims[0].degree == 1); + assert(inputs[0]->dims[0].parallel_idx == -1); + // outputs[0] = model.create_parallel_tensor_legion_ordering( + // numdim, dims, _input->data_type, this, 0 /*owner_idx*/); + outputs[0] = model.create_parallel_tensor_legion_ordering( + numdim, inputs[0]->dims, DT_INT32, this, 0 /*owner_idx*/); + outputs[1] = model.create_parallel_tensor_legion_ordering( + numdim, inputs[0]->dims, DT_FLOAT, this, 1 /*owner_idx*/); + outputs[2] = model.create_parallel_tensor_legion_ordering( + numdim, inputs[0]->dims, DT_INT32, this, 2 /*owner_idx*/); +} + +BeamTopK::BeamTopK(FFModel &model, + BeamTopK const &other, + const ParallelTensor input) + : BeamTopK(model, + input, + other.layer_guid, + other.max_beam_width, + other.sorted, + other.name) {} + +BeamTopK::BeamTopK(FFModel &model, + BeamTopKParams const ¶ms, + const ParallelTensor input, + char const *name) + : BeamTopK(model, + input, + params.layer_guid, + params.max_beam_width, + params.sorted, + params.name) {} + +void BeamTopK::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(BEAM_TOPK_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(BeamTopK)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[2]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[2]->region)); + launcher.add_field(3, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void BeamTopK::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(BEAM_TOPK_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(BeamTopK)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[1]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[2]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[2]->region)); + launcher.add_field(3, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *BeamTopK::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + BeamTopK *topk = (BeamTopK *)task->args; + FFHandler handle = *((FFHandler *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + BeamTopKMeta *m = new BeamTopKMeta(handle, topk, gpu_mem_allocator); + m->profiling = topk->profiling; + m->inference_debugging = topk->inference_debugging; + std::strcpy(m->op_name, topk->name); + m->layer_guid = topk->layer_guid; + m->sorted = topk->sorted; + m->max_beam_width = topk->max_beam_width; + m->input_type[0] = topk->inputs[0]->data_type; + return m; +} + +void BeamTopK::forward(FFModel const &ff) { + assert(false); +} + +FutureMap BeamTopK::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(BEAM_TOPK_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[2]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[2]->region)); + launcher.add_field(3, FID_DATA); + + return runtime->execute_index_space(ctx, launcher); +} + +BeamInferenceResult + BeamTopK::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + assert(regions.size() == 4); + assert(task->regions.size() == 4); + + BeamTopKMeta *m = *((BeamTopKMeta **)task->local_args); + BeamSearchBatchConfig const &bc = + Future(task->futures[0]).get_result(); + + if (bc.num_tokens == 0) { + BeamInferenceResult ir; + return ir; + } + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW index = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW value = helperGetGenericTensorAccessorWO( + DT_FLOAT, regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorW parent = helperGetGenericTensorAccessorWO( + DT_INT32, regions[3], task->regions[3], FID_DATA, ctx, runtime); + + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + + int *index_ptr = index.get_int32_ptr(); + float *value_ptr = value.get_float_ptr(); + int *parent_ptr = parent.get_int32_ptr(); + + // embedding size: eg. 4096 + int length = input_domain.hi()[0] - input_domain.lo()[0] + 1; + // total token nums + size_t batch_size = bc.num_active_tokens(); + + // need meta for: how many sub requests in a main request + BeamTopK::forward_kernel_wrapper(m, + &bc, + input, + value_ptr, + index_ptr, + parent_ptr, + batch_size, + length, + m->sorted); + + BeamInferenceResult ir; + + download_tensor(index_ptr, ir.token_ids, batch_size * m->max_beam_width); + download_tensor(value_ptr, ir.probs, batch_size * m->max_beam_width); + download_tensor( + parent_ptr, ir.parent_id, batch_size * m->max_beam_width); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + BeamTopK::save_inference_tensors_to_file( + m, shard_id, &bc, {input}, {}, {index, value, parent}); + } + + return ir; +} + +void BeamTopK::backward(FFModel const &ff) { + assert(false); +} + +void BeamTopK::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->sorted); + sez.serialize(this->max_beam_width); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +Node BeamTopK::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + bool sorted; + size_t id, transformer_layer_id, deserialized_model_id; + int max_beam_width; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(sorted); + dez.deserialize(max_beam_width); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + BeamTopKParams params; + params.layer_guid = layer_guid; + params.sorted = sorted; + params.max_beam_width = max_beam_width; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); +} + +Op *BeamTopK::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + BeamTopKParams params = get_params(); + return new BeamTopK(ff, params, inputs[0], this->name); +} + +bool BeamTopK::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::BeamTopKParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.sorted); + hash_combine(key, params.max_beam_width); + return key; +} +}; // namespace std diff --git a/src/ops/beam_topk.cpp b/src/ops/beam_topk.cpp new file mode 100644 index 0000000000..18534455a0 --- /dev/null +++ b/src/ops/beam_topk.cpp @@ -0,0 +1,724 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/beam_topk.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +enum class HeapType { kMinHeap, kMaxHeap }; +enum class PreferIndices { kLower, kHigher }; + +LegionRuntime::Logger::Category log_beam_topk("BeamTopK"); + +template +struct Entry { + int index; + T value; +}; + +template +struct LinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return data[i].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; +}; + +template +struct IndirectLinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return backing_data[data[i].index].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; + Entry *const backing_data; +}; + +template +struct StridedData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index * blockDim.x + threadIdx.x]; + } + + __device__ int get_index(int i) const { + return (*this)[i].index; + } + __device__ T get_value(int i) const { + return (*this)[i].value; + } + + Entry *const data; +}; + +// A heap of Entry that can either work as a min-heap or as a max-heap. +template + class Data, + typename T> +struct IndexedHeap { + typedef typename Data::Entry Entry; + Data const data; + __device__ IndexedHeap(Data const &d) : data(d) {} + + __device__ bool is_above(int left, int right) { + T left_value = data.get_value(left); + T right_value = data.get_value(right); + if (left_value == right_value) { + if (preferIndices == PreferIndices::kLower) { + return data.get_index(left) < data.get_index(right); + } else { + return data.get_index(left) > data.get_index(right); + } + } + if (heapType == HeapType::kMinHeap) { + return left_value < right_value; + } else { + return left_value > right_value; + } + } + + __device__ void assign(int i, Entry const &entry) { + data[i] = entry; + } + + __device__ void push_up(int i) { + int child = i; + int parent; + for (; child > 0; child = parent) { + parent = (child - 1) / 2; + if (!is_above(child, parent)) { + // Heap property satisfied. + break; + } + swap(child, parent); + } + } + + __device__ void swap(int a, int b) { + auto tmp = data[b]; + data[b] = data[a]; + data[a] = tmp; + } + + __device__ void push_root_down(int k) { + push_down(0, k); + } + + // MAX-HEAPIFY in Cormen + __device__ void push_down(int node, int k) { + while (true) { + int const left = 2 * node + 1; + int const right = left + 1; + int smallest = node; + if (left < k && is_above(left, smallest)) { + smallest = left; + } + if (right < k && is_above(right, smallest)) { + smallest = right; + } + if (smallest == node) { + break; + } + swap(smallest, node); + node = smallest; + } + } + + // BUILD-MAX-HEAPIFY in Cormen + __device__ void build(int k) { + for (int node = (k - 1) / 2; node >= 0; node--) { + push_down(node, k); + } + } + + // HEAP-EXTRACT-MAX in Cormen + __device__ void remove_root(int k) { + data[0] = data[k - 1]; + push_root_down(k - 1); + } + + // in-place HEAPSORT in Cormen + // This method destroys the heap property. + __device__ void sort(int k) { + for (int slot = k - 1; slot > 0; slot--) { + // This is like remove_root but we insert the element at the end. + swap(slot, 0); + // Heap is now an element smaller. + push_root_down(/*k=*/slot); + } + } + + __device__ void replace_root(Entry const &entry, int k) { + data[0] = entry; + push_root_down(k); + } + + __device__ Entry const &root() { + return data[0]; + } +}; + +template + class Data, + typename T> +__device__ IndexedHeap + make_indexed_heap(typename Data::Entry *data) { + return IndexedHeap{Data{data}}; +} + +// heapBeamTopK walks over [input, input+length) with `step_size` stride +// starting at `start_index`. It builds a top-`k` heap that is stored in +// `heap_entries` using `Accessor` to access elements in `heap_entries`. If +// sorted=true, the elements will be sorted at the end. +template class Data = LinearData> +__device__ void heapBeamTopK(T const *__restrict__ input, + int batch_index, + int length, + int k, + Entry *__restrict__ heap_entries, + bool sorted = false, + int start_index = 0, + int step_size = 1) { + assert(k <= length); + auto heap = + make_indexed_heap( + heap_entries); + + int heap_end_index = start_index + k * step_size; + if (heap_end_index > length) { + heap_end_index = length; + } + // Initialize the min-heap. + for (int index = start_index, slot = 0; index < heap_end_index; + index += step_size, slot++) { + heap.assign(slot, {index, input[index]}); + } + + heap.build(k); + + // Now iterate over the remaining items. + // If an item is smaller than the min element, it is not amongst the top k. + // Otherwise, replace the min element with it and push upwards. + for (int index = heap_end_index; index < length; index += step_size) { + // We prefer elements with lower indices. This is given here. + // Later elements automatically have higher indices, so can be discarded. + if (input[index] > heap.root().value) { + // This element should replace the min. + heap.replace_root({index, input[index]}, k); + } + } + + // Sort if wanted. + if (sorted) { + heap.sort(k); + } + + // if(batch_index == 0){ + // printf("top elemmments: %d, value %.15f\n", start_index, + // heap.root().value); + // } +} + +template +__device__ void mergeBeamShards(int num_shards, + int batch_index, + int k, + int max_heap_size, + int request_id, + int *parent_id, + T *probs, + Entry *__restrict__ entries, + Entry *__restrict__ top_k_heap, + float *top_k_values, + int *top_k_indices, + int *top_k_parents, + bool verbose) { + // If k < num_shards, we can use a min-heap with k elements to get the top k + // of the sorted blocks. + // If k > num_shards, we can initialize a min-heap with the top element from + // each sorted block. + int const heap_size = k < num_shards ? k : num_shards; + // printf("see value: %f", entries[0].value); + // Min-heap part. + + { + auto min_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Initialize the heap as a min-heap. + for (int slot = 0; slot < heap_size; slot++) { + // int beam = (slot % max_heap_size) / k; + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((slot % max_heap_size) / k)]; + min_heap.assign(slot, {slot, (entries[slot].value * prob)}); + } + min_heap.build(heap_size); + + // Now perform top k with the remaining shards (if num_shards > heap_size). + for (int shard = heap_size; shard < num_shards; shard++) { + auto const entry = entries[shard]; + auto const root = min_heap.root(); + + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard % max_heap_size) / k)]; + if (entry.value * prob < root.value) { + continue; + } + if (entry.value * prob == root.value && + entry.index > entries[root.index].index) { + continue; + } + // This element should replace the min. + min_heap.replace_root({shard, entry.value * prob}, heap_size); + } + } + + // Max-part. + { + // Turn the min-heap into a max-heap in-place. + auto max_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Heapify into a max heap. + max_heap.build(heap_size); + + // Now extract the minimum k-1 times. + // k is treated specially. + int const last_k = k - 1; + for (int rank = 0; rank < last_k; rank++) { + Entry const &max_element = max_heap.root(); + top_k_values[rank] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[rank] = entries[shard_index].index; + top_k_parents[rank] = + parent_id[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard_index % max_heap_size) / k)]; + int next_shard_index = shard_index + num_shards; + + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((next_shard_index % max_heap_size) / k)]; + + max_heap.replace_root( + {next_shard_index, entries[next_shard_index].value * prob}, + heap_size); + } + + // rank == last_k. + Entry const &max_element = max_heap.root(); + top_k_values[last_k] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[last_k] = entries[shard_index].index; + top_k_parents[last_k] = + parent_id[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard_index % max_heap_size) / k)]; + } +} + +template +__global__ void + mergeSubRequestsKernel(int64_t N, T const *X, T const *rstd, T *Y) { + using T_ACC = T; + const int64_t i = blockIdx.x; + for (int64_t j = threadIdx.x; j < N; j += blockDim.x) { + const int64_t index = i * N + j; + Y[index] = static_cast(X[index]) * static_cast(rstd[i]); + } +} + +template +__global__ void beam_topk_forward_kernel(T const *__restrict__ input, + size_t shared_memory_size, + int length, + int k, + int max_heap_size, + int *parent_ids, + T *acc_probs, + int *gpu_block_start_index, + int *gpu_request_id, + int *tokens_per_request, + bool sorted, + float *__restrict__ output, + int *__restrict__ indices, + int *__restrict__ parents, + bool verbose) { + __shared__ char shared_memory[48 << 10]; + int const batch_index = blockIdx.x; + // T const *batch_input = input + batch_index * length; + int const thread_index = threadIdx.x; + int const thread_count = blockDim.x; + int const request_id = gpu_request_id[batch_index]; + int const token_nums = tokens_per_request[batch_index]; + Entry *shared_entries = (Entry *)shared_memory; + + int sub_request_id = thread_index / k; + // if (verbose) { + // printf("beam kernel: batch_index: %d, thread_index %d, sub_request_id %d, + // " + // "request_id %d, token_nums %d\n", + // batch_index, + // thread_index, + // sub_request_id, + // request_id, + // token_nums); + // } + + T const *batch_input = input + gpu_block_start_index[batch_index] + + (sub_request_id * token_nums * length); + + // printf("thread index %d, thread_count %d, batch_index %d\n", thread_index, + // thread_count, batch_index); + heapBeamTopK(batch_input, + batch_index, + length, + k, + shared_entries, + true, + thread_index % k, + k); + __syncthreads(); + // printf("beam thread index %d, thread_count %d, thread index %d, batch_index + // " + // "%d, k %d, parent_id %d, acc_prob: %f, sub id: %d, request_id: %d, + // offset: %d, offset2 %d, sub_request_id %d\n", thread_index, + // thread_count, + // thread_index, + // batch_index, + // k, + // parent_ids[request_id * BatchConfig::MAX_NUM_BEAMS + + // sub_request_id], acc_probs[request_id * BatchConfig::MAX_NUM_BEAMS + + // sub_request_id], sub_request_id, request_id, + // gpu_block_start_index[batch_index], + // batch_index * length, + // sub_request_id); + + if (thread_index == 0) { + // merge beam_width heaps and store the parent + // find which req it belongs to, replace the offset + // printf("merge heaps, batch index: %d, sub_request_id %d, value %f\n", + // batch_index, + // sub_request_id, + // acc_probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + // sub_request_id]); + int const offset = batch_index * k; + auto batch_output = output + offset; + auto batch_indices = indices + offset; + auto batch_parents = parents + offset; + Entry *top_k_heap = shared_entries + thread_count * k; + + // if(batch_index == 0 && verbose) { + // for(int i = 0; i < 18; i++){ + // printf("see value: %.15f\n", shared_entries[i].value); + // } + // } + + // get parent/acc based on the sub request and main request + mergeBeamShards(thread_count, + batch_index, + k, + max_heap_size, + request_id, + parent_ids, + acc_probs, + shared_entries, + top_k_heap, + batch_output, + batch_indices, + batch_parents, + verbose /*verbose prints*/); + } +} + +/*static*/ +template +void BeamTopK::forward_kernel(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted, + hipStream_t stream) { + // Adopted from TensorFlow's BeamTopK implementation + // https://github.com/tensorflow/tensorflow/blob/master/tensorflow/core/kernels/topk_op_gpu.h + + int num_shards = 0; + int max_heap_size = 0; + int max_beam_width = 0; + int req_index = 0; + + // sub request + int const *sub_requests = bc->sub_requests; + + // std::vector beam_slots = bc->beam_slots; + // assert(bc->beam_slots.size() > 0); + + int beam_num_blocks = 0; + std::vector beam_block_start_index; + std::vector request_id; + std::vector tokens_per_request; + + int block_start_index = 0; + + // a data structure for prob, parent_id, + int max_total_requests = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * bc->num_active_requests(); + int parent_ids[max_total_requests]; + DT acc_probs[max_total_requests]; + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + assert(bc->beamRequestsInfo[i].beam_size > 0); + + // int num_new_tokens = bc->num_processing_tokens[i]; + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + + // get beam size; + int beam_size = bc->beamRequestsInfo[i].beam_size; + + // initial request + log_beam_topk.debug() << "sub_requests: " << i << ", " << sub_requests[i] + << "\n"; + assert(sub_requests[i] > 0); + // process sub requests + for (int j = 0; j < sub_requests[i]; j++) { + parent_ids[req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j] = j; + // beam_slots[i].parent_id[j]; + acc_probs[req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j] = + bc->beamRequestsInfo[i].probs[j]; + log_beam_topk.debug() + << "probbbb req: " << i + << ", sub req probability : " << bc->beamRequestsInfo[i].probs[j] + << ", sub request id " << j << ", parent id " + << bc->beamRequestsInfo[i].parent_id[j] << ", data inddd" + << req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j << "\n"; + } + + // process tokens + for (int k = 0; k < num_new_tokens; k++) { + beam_block_start_index.push_back(block_start_index); + request_id.push_back(i); + tokens_per_request.push_back(num_new_tokens); + block_start_index += length; + beam_num_blocks++; + } + + max_heap_size = std::max(max_heap_size, beam_size * sub_requests[i]); + max_beam_width = std::max(max_beam_width, beam_size); + req_index += 1; + block_start_index += (sub_requests[i] - 1) * num_new_tokens * length; + } + log_beam_topk.debug() << "what index: " << block_start_index + << ", block num: " << beam_num_blocks << "\n"; + + assert(batch_size >= beam_num_blocks); + assert(bc->num_active_requests() == req_index); + + { + constexpr auto shared_memory_size = 48 << 10; + auto const heap_size = max_heap_size * sizeof(Entry
); + // shared_memory_size = (num_shards + 1) * heap_size <=> + num_shards = shared_memory_size / heap_size - 1; + assert(num_shards > 0); + if (num_shards > CUDA_NUM_THREADS) { + num_shards = CUDA_NUM_THREADS; + } + log_beam_topk.debug() << "maxheap size: " << max_heap_size << "\n"; + log_beam_topk.debug() << "maxbeam width: " << max_beam_width + << ", heap size: " << heap_size << "\n"; + } + // We are limited by the amount of shared memory we have per block. + size_t shared_memory_size = + (num_shards + 1) * max_heap_size * sizeof(Entry
); + + assert(num_shards >= (size_t)max_heap_size); + num_shards = max_heap_size; + + checkCUDA(hipMemcpy(m->parent_ids, + parent_ids, + sizeof(int) * max_total_requests, + hipMemcpyHostToDevice)); + checkCUDA(hipMemcpy(m->acc_probs, + acc_probs, + sizeof(DT) * max_total_requests, + hipMemcpyHostToDevice)); + checkCUDA(hipMemcpy(m->block_start_index, + beam_block_start_index.data(), + sizeof(int) * beam_num_blocks, + hipMemcpyHostToDevice)); + checkCUDA(hipMemcpy(m->request_id, + request_id.data(), + sizeof(int) * beam_num_blocks, + hipMemcpyHostToDevice)); + checkCUDA(hipMemcpy(m->tokens_per_request, + tokens_per_request.data(), + sizeof(int) * beam_num_blocks, + hipMemcpyHostToDevice)); + // int depth = + // bc->beamRequestsInfo[bc->tokensInfo[0].request_index].current_depth; + beam_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + max_beam_width, + max_heap_size, + m->parent_ids, + static_cast
(m->acc_probs), + m->block_start_index, + m->request_id, + m->tokens_per_request, + sorted, + output_ptr, + indices_ptr, + parent_ptr, + false /*verbose*/ // depth == 1 + ); + + // merge sub +} + +/*static*/ +void BeamTopK::forward_kernel_wrapper(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + GenericTensorAccessorR const &input, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + if (input.data_type == DT_HALF) { + BeamTopK::forward_kernel(m, + bc, + input.get_half_ptr(), + output_ptr, + indices_ptr, + parent_ptr, + batch_size, + length, + sorted, + stream); + } else if (input.data_type == DT_FLOAT) { + BeamTopK::forward_kernel(m, + bc, + input.get_float_ptr(), + output_ptr, + indices_ptr, + parent_ptr, + batch_size, + length, + sorted, + stream); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("[BeamTopK] forward time = %.2lfms\n", elapsed); + } +} + +BeamTopKMeta::BeamTopKMeta(FFHandler handler, + Op const *op, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler) { + DataType data_type = op->inputs[0]->data_type; + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + int max_requests_per_batch = BatchConfig::max_requests_per_batch(); + size_t parent_id_size = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * max_requests_per_batch; + size_t acc_probs_size = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * max_requests_per_batch; + size_t block_start_index_size = max_tokens_per_batch * max_requests_per_batch; + size_t request_id_size = max_tokens_per_batch * max_requests_per_batch; + size_t tokens_per_request_size = + max_tokens_per_batch * max_requests_per_batch; + size_t totalSize = sizeof(int) * parent_id_size + + data_type_size(data_type) * acc_probs_size + + sizeof(int) * block_start_index_size + + sizeof(int) * request_id_size + + sizeof(int) * tokens_per_request_size; + + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + parent_ids = gpu_mem_allocator.allocate_instance(parent_id_size); + if (data_type == DT_FLOAT) { + acc_probs = gpu_mem_allocator.allocate_instance(acc_probs_size); + } else if (data_type == DT_HALF) { + acc_probs = gpu_mem_allocator.allocate_instance(acc_probs_size); + } else { + assert(false); + } + + block_start_index = + gpu_mem_allocator.allocate_instance(block_start_index_size); + request_id = gpu_mem_allocator.allocate_instance(request_id_size); + tokens_per_request = + gpu_mem_allocator.allocate_instance(tokens_per_request_size); +} + +BeamTopKMeta::~BeamTopKMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +}; // namespace FlexFlow diff --git a/src/ops/beam_topk.cu b/src/ops/beam_topk.cu new file mode 100644 index 0000000000..a958786be3 --- /dev/null +++ b/src/ops/beam_topk.cu @@ -0,0 +1,766 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/beam_topk.h" +#include "flexflow/request_manager.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +enum class HeapType { kMinHeap, kMaxHeap }; +enum class PreferIndices { kLower, kHigher }; + +LegionRuntime::Logger::Category log_beam_topk("BeamTopK"); + +template +struct Entry { + int index; + T value; +}; + +template +struct LinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return data[i].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; +}; + +template +struct IndirectLinearData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index]; + } + + __device__ int get_index(int i) const { + return backing_data[data[i].index].index; + } + __device__ T get_value(int i) const { + return data[i].value; + } + + Entry *const data; + Entry *const backing_data; +}; + +template +struct StridedData { + typedef Entry Entry; + + __device__ Entry &operator[](std::size_t index) const { + return data[index * blockDim.x + threadIdx.x]; + } + + __device__ int get_index(int i) const { + return (*this)[i].index; + } + __device__ T get_value(int i) const { + return (*this)[i].value; + } + + Entry *const data; +}; + +// A heap of Entry that can either work as a min-heap or as a max-heap. +template + class Data, + typename T> +struct IndexedHeap { + typedef typename Data::Entry Entry; + Data const data; + __device__ IndexedHeap(Data const &d) : data(d) {} + + __device__ bool is_above(int left, int right) { + T left_value = data.get_value(left); + T right_value = data.get_value(right); + if (left_value == right_value) { + if (preferIndices == PreferIndices::kLower) { + return data.get_index(left) < data.get_index(right); + } else { + return data.get_index(left) > data.get_index(right); + } + } + if (heapType == HeapType::kMinHeap) { + return left_value < right_value; + } else { + return left_value > right_value; + } + } + + __device__ void assign(int i, Entry const &entry) { + data[i] = entry; + } + + __device__ void push_up(int i) { + int child = i; + int parent; + for (; child > 0; child = parent) { + parent = (child - 1) / 2; + if (!is_above(child, parent)) { + // Heap property satisfied. + break; + } + swap(child, parent); + } + } + + __device__ void swap(int a, int b) { + auto tmp = data[b]; + data[b] = data[a]; + data[a] = tmp; + } + + __device__ void push_root_down(int k) { + push_down(0, k); + } + + // MAX-HEAPIFY in Cormen + __device__ void push_down(int node, int k) { + while (true) { + int const left = 2 * node + 1; + int const right = left + 1; + int smallest = node; + if (left < k && is_above(left, smallest)) { + smallest = left; + } + if (right < k && is_above(right, smallest)) { + smallest = right; + } + if (smallest == node) { + break; + } + swap(smallest, node); + node = smallest; + } + } + + // BUILD-MAX-HEAPIFY in Cormen + __device__ void build(int k) { + for (int node = (k - 1) / 2; node >= 0; node--) { + push_down(node, k); + } + } + + // HEAP-EXTRACT-MAX in Cormen + __device__ void remove_root(int k) { + data[0] = data[k - 1]; + push_root_down(k - 1); + } + + // in-place HEAPSORT in Cormen + // This method destroys the heap property. + __device__ void sort(int k) { + for (int slot = k - 1; slot > 0; slot--) { + // This is like remove_root but we insert the element at the end. + swap(slot, 0); + // Heap is now an element smaller. + push_root_down(/*k=*/slot); + } + } + + __device__ void replace_root(Entry const &entry, int k) { + data[0] = entry; + push_root_down(k); + } + + __device__ Entry const &root() { + return data[0]; + } +}; + +template + class Data, + typename T> +__device__ IndexedHeap + make_indexed_heap(typename Data::Entry *data) { + return IndexedHeap{Data{data}}; +} + +// heapBeamTopK walks over [input, input+length) with `step_size` stride +// starting at `start_index`. It builds a top-`k` heap that is stored in +// `heap_entries` using `Accessor` to access elements in `heap_entries`. If +// sorted=true, the elements will be sorted at the end. +template class Data = LinearData> +__device__ void heapBeamTopK(T const *__restrict__ input, + int batch_index, + int length, + int k, + Entry *__restrict__ heap_entries, + bool sorted = false, + int start_index = 0, + int step_size = 1) { + assert(k <= length); + auto heap = + make_indexed_heap( + heap_entries); + + int heap_end_index = start_index + k * step_size; + if (heap_end_index > length) { + heap_end_index = length; + } + // Initialize the min-heap. + for (int index = start_index, slot = 0; index < heap_end_index; + index += step_size, slot++) { + heap.assign(slot, {index, input[index]}); + } + + heap.build(k); + + // Now iterate over the remaining items. + // If an item is smaller than the min element, it is not amongst the top k. + // Otherwise, replace the min element with it and push upwards. + for (int index = heap_end_index; index < length; index += step_size) { + // We prefer elements with lower indices. This is given here. + // Later elements automatically have higher indices, so can be discarded. + if (input[index] > heap.root().value) { + // This element should replace the min. + heap.replace_root({index, input[index]}, k); + } + } + + // Sort if wanted. + if (sorted) { + heap.sort(k); + } + + // if(batch_index == 0){ + // printf("top elemmments: %d, value %.15f\n", start_index, + // heap.root().value); + // } +} + +template +__device__ void mergeBeamShards(int num_shards, + int batch_index, + int k, + int max_heap_size, + int request_id, + int *parent_id, + T *probs, + Entry *__restrict__ entries, + Entry *__restrict__ top_k_heap, + float *top_k_values, + int *top_k_indices, + int *top_k_parents, + bool verbose) { + // If k < num_shards, we can use a min-heap with k elements to get the top k + // of the sorted blocks. + // If k > num_shards, we can initialize a min-heap with the top element from + // each sorted block. + int const heap_size = k < num_shards ? k : num_shards; + // printf("see value: %f", entries[0].value); + // Min-heap part. + + { + auto min_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Initialize the heap as a min-heap. + for (int slot = 0; slot < heap_size; slot++) { + // int beam = (slot % max_heap_size) / k; + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((slot % max_heap_size) / k)]; + min_heap.assign(slot, {slot, (entries[slot].value * prob)}); + if (verbose && batch_index == 0) { + printf("slot %d, value %.15f, prob %15f\n", + slot, + static_cast(entries[slot].value), + static_cast(prob)); + } + } + min_heap.build(heap_size); + + // Now perform top k with the remaining shards (if num_shards > heap_size). + for (int shard = heap_size; shard < num_shards; shard++) { + auto const entry = entries[shard]; + auto const root = min_heap.root(); + + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard % max_heap_size) / k)]; + if (verbose && batch_index == 0) { + printf("shard %d, index %d, value %.15f, prob %.15f\n", + shard, + entry.index, + static_cast(entry.value), + static_cast(prob)); + } + if (entry.value * prob < root.value) { + continue; + } + if (entry.value * prob == root.value && + entry.index > entries[root.index].index) { + continue; + } + // This element should replace the min. + min_heap.replace_root({shard, entry.value * prob}, heap_size); + } + } + + // Max-part. + { + // Turn the min-heap into a max-heap in-place. + auto max_heap = IndexedHeap{IndirectLinearData{top_k_heap, entries}}; + // Heapify into a max heap. + max_heap.build(heap_size); + + // Now extract the minimum k-1 times. + // k is treated specially. + int const last_k = k - 1; + for (int rank = 0; rank < last_k; rank++) { + Entry const &max_element = max_heap.root(); + top_k_values[rank] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[rank] = entries[shard_index].index; + top_k_parents[rank] = + parent_id[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard_index % max_heap_size) / k)]; + int next_shard_index = shard_index + num_shards; + + T prob = probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((next_shard_index % max_heap_size) / k)]; + // if (batch_index == 0) { + // printf("next_shard_index %d, value %.15f, prob %.15f\n", + // next_shard_index, + // entries[next_shard_index].value, + // prob); + // } + max_heap.replace_root( + {next_shard_index, entries[next_shard_index].value * prob}, + heap_size); + } + + // rank == last_k. + Entry const &max_element = max_heap.root(); + top_k_values[last_k] = __half2float(max_element.value); + int shard_index = max_element.index; + top_k_indices[last_k] = entries[shard_index].index; + top_k_parents[last_k] = + parent_id[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + ((shard_index % max_heap_size) / k)]; + } +} + +template +__global__ void + mergeSubRequestsKernel(int64_t N, T const *X, T const *rstd, T *Y) { + using T_ACC = T; + const int64_t i = blockIdx.x; + for (int64_t j = threadIdx.x; j < N; j += blockDim.x) { + const int64_t index = i * N + j; + Y[index] = static_cast(X[index]) * static_cast(rstd[i]); + } +} + +template +__global__ void beam_topk_forward_kernel(T const *__restrict__ input, + size_t shared_memory_size, + int length, + int k, + int max_heap_size, + int *parent_ids, + T *acc_probs, + int *gpu_block_start_index, + int *gpu_request_id, + int *tokens_per_request, + bool sorted, + float *__restrict__ output, + int *__restrict__ indices, + int *__restrict__ parents, + bool verbose) { + __shared__ char shared_memory[48 << 10]; + int const batch_index = blockIdx.x; + // T const *batch_input = input + batch_index * length; + int const thread_index = threadIdx.x; + int const thread_count = blockDim.x; + int const request_id = gpu_request_id[batch_index]; + int const token_nums = tokens_per_request[batch_index]; + Entry *shared_entries = (Entry *)shared_memory; + + int sub_request_id = thread_index / k; + // if (verbose) { + // printf("beam kernel: batch_index: %d, thread_index %d, sub_request_id %d, + // " + // "request_id %d, token_nums %d\n", + // batch_index, + // thread_index, + // sub_request_id, + // request_id, + // token_nums); + // } + + T const *batch_input = input + gpu_block_start_index[batch_index] + + (sub_request_id * token_nums * length); + + if (verbose && batch_index == 0) { + printf("request 0 start index: thread index %d, offset %d, batch_input %p, " + "acc index %d acc " + "prob %f, thread_count %d, request_id %d\n", + thread_index, + gpu_block_start_index[batch_index] + + (sub_request_id * token_nums * length), + batch_input, + request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + sub_request_id, + static_cast( + acc_probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + sub_request_id]), + thread_count, + request_id); + } + // printf("thread index %d, thread_count %d, batch_index %d\n", thread_index, + // thread_count, batch_index); + heapBeamTopK(batch_input, + batch_index, + length, + k, + shared_entries, + true, + thread_index % k, + k); + __syncthreads(); + // printf("beam thread index %d, thread_count %d, thread index %d, batch_index + // " + // "%d, k %d, parent_id %d, acc_prob: %f, sub id: %d, request_id: %d, + // offset: %d, offset2 %d, sub_request_id %d\n", thread_index, + // thread_count, + // thread_index, + // batch_index, + // k, + // parent_ids[request_id * BatchConfig::MAX_NUM_BEAMS + + // sub_request_id], acc_probs[request_id * BatchConfig::MAX_NUM_BEAMS + + // sub_request_id], sub_request_id, request_id, + // gpu_block_start_index[batch_index], + // batch_index * length, + // sub_request_id); + + if (thread_index == 0) { + // merge beam_width heaps and store the parent + // find which req it belongs to, replace the offset + // printf("merge heaps, batch index: %d, sub_request_id %d, value %f\n", + // batch_index, + // sub_request_id, + // acc_probs[request_id * BeamSearchBatchConfig::MAX_BEAM_WIDTH + + // sub_request_id]); + int const offset = batch_index * k; + auto batch_output = output + offset; + auto batch_indices = indices + offset; + auto batch_parents = parents + offset; + Entry *top_k_heap = shared_entries + thread_count * k; + + // if(batch_index == 0 && verbose) { + // for(int i = 0; i < 18; i++){ + // printf("see value: %.15f\n", shared_entries[i].value); + // } + // } + + // get parent/acc based on the sub request and main request + mergeBeamShards(thread_count, + batch_index, + k, + max_heap_size, + request_id, + parent_ids, + acc_probs, + shared_entries, + top_k_heap, + batch_output, + batch_indices, + batch_parents, + verbose /*verbose prints*/); + } +} + +/*static*/ +template +void BeamTopK::forward_kernel(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + DT const *input_ptr, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted, + cudaStream_t stream) { + // Adopted from TensorFlow's BeamTopK implementation + // https://github.com/tensorflow/tensorflow/blob/master/tensorflow/core/kernels/topk_op_gpu.h + + int num_shards = 0; + int max_heap_size = 0; + int max_beam_width = 0; + int req_index = 0; + + // sub request + int const *sub_requests = bc->sub_requests; + + // std::vector beam_slots = bc->beam_slots; + // assert(bc->beam_slots.size() > 0); + + int beam_num_blocks = 0; + std::vector beam_block_start_index; + std::vector request_id; + std::vector tokens_per_request; + + int block_start_index = 0; + + // a data structure for prob, parent_id, + int max_total_requests = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * bc->num_active_requests(); + int parent_ids[max_total_requests]; + DT acc_probs[max_total_requests]; + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + assert(bc->beamRequestsInfo[i].beam_size > 0); + + // int num_new_tokens = bc->num_processing_tokens[i]; + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + + // get beam size; + int beam_size = bc->beamRequestsInfo[i].beam_size; + + // initial request + assert(sub_requests[i] > 0); + // process sub requests + for (int j = 0; j < sub_requests[i]; j++) { + parent_ids[req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j] = j; + // beam_slots[i].parent_id[j]; + acc_probs[req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j] = + bc->beamRequestsInfo[i].probs[j]; + // std::cout << "probbbb req: " << i << ", sub req probability : " + // << bc->beamRequestsInfo[i].probs[j] << ", sub request id " << + // j + // << ", parent id " << bc->beamRequestsInfo[i].parent_id[j] + // << ", data inddd" + // << req_index * BeamSearchBatchConfig::MAX_BEAM_WIDTH + j + // << "\n"; + } + + // process tokens + for (int k = 0; k < num_new_tokens; k++) { + beam_block_start_index.push_back(block_start_index); + request_id.push_back(i); + tokens_per_request.push_back(num_new_tokens); + block_start_index += length; + beam_num_blocks++; + } + + max_heap_size = std::max(max_heap_size, beam_size * sub_requests[i]); + max_beam_width = std::max(max_beam_width, beam_size); + + req_index += 1; + block_start_index += (sub_requests[i] - 1) * num_new_tokens * length; + } + log_beam_topk.debug() << "what index: " << block_start_index + << ", block num: " << beam_num_blocks << "\n"; + + assert(batch_size >= beam_num_blocks); + assert(bc->num_active_requests() == req_index); + + { + constexpr auto shared_memory_size = 48 << 10; + auto const heap_size = max_heap_size * sizeof(Entry
); + // shared_memory_size = (num_shards + 1) * heap_size <=> + num_shards = shared_memory_size / heap_size - 1; + assert(num_shards > 0); + if (num_shards > CUDA_NUM_THREADS) { + num_shards = CUDA_NUM_THREADS; + } + log_beam_topk.debug() << "maxheap size: " << max_heap_size << "\n"; + log_beam_topk.debug() << "maxbeam width: " << max_beam_width + << ", heap size: " << heap_size << "\n"; + } + // We are limited by the amount of shared memory we have per block. + size_t shared_memory_size = + (num_shards + 1) * max_heap_size * sizeof(Entry
); + + assert(num_shards >= (size_t)max_heap_size); + num_shards = max_heap_size; + + checkCUDA(cudaMemcpyAsync(m->parent_ids, + parent_ids, + sizeof(int) * max_total_requests, + cudaMemcpyHostToDevice, + stream)); + checkCUDA(cudaMemcpyAsync(m->acc_probs, + acc_probs, + sizeof(DT) * max_total_requests, + cudaMemcpyHostToDevice, + stream)); + // trick, set acc_probs to 0; + checkCUDA(cudaMemsetAsync( + m->acc_probs, 1.0, max_total_requests * sizeof(DT), stream)); + checkCUDA(cudaMemcpyAsync(m->block_start_index, + beam_block_start_index.data(), + sizeof(int) * beam_num_blocks, + cudaMemcpyHostToDevice, + stream)); + checkCUDA(cudaMemcpyAsync(m->request_id, + request_id.data(), + sizeof(int) * beam_num_blocks, + cudaMemcpyHostToDevice, + stream)); + checkCUDA(cudaMemcpyAsync(m->tokens_per_request, + tokens_per_request.data(), + sizeof(int) * beam_num_blocks, + cudaMemcpyHostToDevice, + stream)); + // int depth = + // bc->beamRequestsInfo[bc->tokensInfo[0].request_index].current_depth; + beam_num_blocks = bc->num_active_tokens(); + beam_topk_forward_kernel<<>>( + input_ptr, + shared_memory_size, + length, + max_beam_width, + max_heap_size, + m->parent_ids, + static_cast
(m->acc_probs), + m->block_start_index, + m->request_id, + m->tokens_per_request, + sorted, + output_ptr, + indices_ptr, + parent_ptr, + false /*verbose*/ // depth == 1 + ); + + // merge sub +} + +/*static*/ +void BeamTopK::forward_kernel_wrapper(BeamTopKMeta const *m, + BeamSearchBatchConfig const *bc, + GenericTensorAccessorR const &input, + float *output_ptr, + int *indices_ptr, + int *parent_ptr, + int batch_size, + int length, + bool sorted) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + if (input.data_type == DT_HALF) { + BeamTopK::forward_kernel(m, + bc, + input.get_half_ptr(), + output_ptr, + indices_ptr, + parent_ptr, + batch_size, + length, + sorted, + stream); + } else if (input.data_type == DT_FLOAT) { + BeamTopK::forward_kernel(m, + bc, + input.get_float_ptr(), + output_ptr, + indices_ptr, + parent_ptr, + batch_size, + length, + sorted, + stream); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[BeamTopK] forward time = %.2lfms\n", elapsed); + } +} + +BeamTopKMeta::BeamTopKMeta(FFHandler handler, + Op const *op, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler) { + DataType data_type = op->inputs[0]->data_type; + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + int max_requests_per_batch = BatchConfig::max_requests_per_batch(); + size_t parent_id_size = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * max_requests_per_batch; + size_t acc_probs_size = + BeamSearchBatchConfig::MAX_BEAM_WIDTH * max_requests_per_batch; + size_t block_start_index_size = max_tokens_per_batch * max_requests_per_batch; + size_t request_id_size = max_tokens_per_batch * max_requests_per_batch; + size_t tokens_per_request_size = + max_tokens_per_batch * max_requests_per_batch; + size_t totalSize = sizeof(int) * parent_id_size + + data_type_size(data_type) * acc_probs_size + + sizeof(int) * block_start_index_size + + sizeof(int) * request_id_size + + sizeof(int) * tokens_per_request_size; + + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + parent_ids = gpu_mem_allocator.allocate_instance(parent_id_size); + if (data_type == DT_FLOAT) { + acc_probs = gpu_mem_allocator.allocate_instance(acc_probs_size); + } else if (data_type == DT_HALF) { + acc_probs = gpu_mem_allocator.allocate_instance(acc_probs_size); + } else { + assert(false); + } + + block_start_index = + gpu_mem_allocator.allocate_instance(block_start_index_size); + request_id = gpu_mem_allocator.allocate_instance(request_id_size); + tokens_per_request = + gpu_mem_allocator.allocate_instance(tokens_per_request_size); +} + +BeamTopKMeta::~BeamTopKMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +}; // namespace FlexFlow diff --git a/src/ops/cache.cc b/src/ops/cache.cc index 339b2cab55..691e45b559 100644 --- a/src/ops/cache.cc +++ b/src/ops/cache.cc @@ -168,6 +168,9 @@ OpMeta *Cache::init_task(Task const *task, CacheMeta *m = new CacheMeta(handle); m->cache_score = 0.0f; m->profiling = c->profiling; + m->inference_debugging = c->inference_debugging; + std::strcpy(m->op_name, c->name); + m->layer_guid = c->layer_guid; return m; } diff --git a/src/ops/cache.cpp b/src/ops/cache.cpp index 8dd1e098c2..95c5995f9e 100644 --- a/src/ops/cache.cpp +++ b/src/ops/cache.cpp @@ -43,10 +43,10 @@ void Cache::cache_forward(Task const *task, checkCUDA(hipblasSetStream(m->handle.blas, stream)); checkCUDNN(miopenSetStream(m->handle.dnn, stream)); - hipMemcpy(output_ptr, - batch_ptrs[batch_ctr], - c->inputs[0]->get_volume() * sizeof(T), - hipMemcpyHostToDevice); + checkCUDA(hipMemcpy(output_ptr, + batch_ptrs[batch_ctr], + c->inputs[0]->get_volume() * sizeof(T), + hipMemcpyHostToDevice)); } template @@ -61,10 +61,10 @@ float Cache::cache_update(Task const *task, T const *input_ptr = helperGetTensorPointerRW( regions[0], task->regions[0], FID_DATA, ctx, runtime); T *host_input = (T *)c->batch_cmp; - hipMemcpy(host_input, - input_ptr, - c->inputs[0]->get_volume() * sizeof(T), - hipMemcpyDeviceToHost); + checkCUDA(hipMemcpy(host_input, + input_ptr, + c->inputs[0]->get_volume() * sizeof(T), + hipMemcpyDeviceToHost)); float cache_score = c->score_f(&m->cache_score, host_input, c->batch_ptrs[batch_ctr], diff --git a/src/ops/cast.cc b/src/ops/cast.cc index 25f8e168b1..e514236a31 100644 --- a/src/ops/cast.cc +++ b/src/ops/cast.cc @@ -112,7 +112,7 @@ Cast::Cast(FFModel &model, CastParams const ¶ms, ParallelTensor const &input, char const *name) - : Cast(model, input, params.dtype, name) {} + : Cast(model, input, params.dtype, params.name) {} void Cast::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -146,6 +146,44 @@ void Cast::init(FFModel const &ff) { set_opmeta_from_futuremap(ff, fm); } +void Cast::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + + IndexLauncher launcher(CAST_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Cast)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + OpMeta *Cast::init_task(Task const *task, std::vector const ®ions, Context ctx, @@ -155,6 +193,8 @@ OpMeta *Cast::init_task(Task const *task, CastMeta *m = new CastMeta(handler); m->input_data_type = cast->inputs[0]->data_type; m->output_data_type = cast->outputs[0]->data_type; + std::strcpy(m->op_name, cast->name); + m->layer_guid = cast->layer_guid; return m; } @@ -186,6 +226,42 @@ void Cast::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap Cast::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(CAST_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, false), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + template void Cast::forward_task_with_1_type(Task const *task, std::vector const ®ions, @@ -333,6 +409,8 @@ bool Cast::measure_operator_cost(Simulator *sim, void Cast::serialize(Legion::Serializer &sez) const { sez.serialize(this->outputs[0]->data_type); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -344,6 +422,10 @@ Node Cast::deserialize(FFModel &ff, assert(num_inputs == 1); DataType dtype; dez.deserialize(dtype); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); return ff.get_or_create_node(inputs[0], {dtype}); } diff --git a/src/ops/concat.cc b/src/ops/concat.cc index 2c86b80cb7..d4d8e525fc 100644 --- a/src/ops/concat.cc +++ b/src/ops/concat.cc @@ -147,7 +147,7 @@ Concat::Concat(FFModel &model, ConcatParams const ¶ms, std::vector const &inputs, char const *name) - : Concat(model, inputs.size(), inputs.data(), params.axis, name) {} + : Concat(model, inputs.size(), inputs.data(), params.axis, params.name) {} void Concat::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -201,7 +201,9 @@ OpMeta *Concat::init_task(Task const *task, // Note that our internal axis index ordering is opposite to other frameworks init_meta(m, cc->legion_axis); m->profiling = cc->profiling; + m->inference_debugging = cc->inference_debugging; std::strcpy(m->op_name, cc->name); + m->layer_guid = cc->layer_guid; return m; } @@ -426,7 +428,7 @@ bool Concat::measure_operator_cost(Simulator *sim, cost_metrics.backward_time = Simulator::MAXIMUM_TASK_RUN_TIME; return true; } - backward = [&] { + backward = [=] { backward_kernel_wrapper( m, output_grad_acc, input_grad_accs, numInputs, legion_axis); }; diff --git a/src/ops/conv_2d.cc b/src/ops/conv_2d.cc index 786c3427e9..94850a178d 100644 --- a/src/ops/conv_2d.cc +++ b/src/ops/conv_2d.cc @@ -389,7 +389,7 @@ Conv2D::Conv2D(FFModel &model, params.groups, params.use_bias, allocate_weights, - name) {} + params.name) {} bool Conv2DParams::is_valid(ParallelTensorShape const &input) const { ParallelTensorShape output_shape, kernel_shape, bias_shape; @@ -592,8 +592,10 @@ OpMeta *Conv2D::init_task(Task const *task, m->relu = conv->activation == AC_MODE_RELU; m->use_bias = conv->use_bias; m->profiling = conv->profiling; + m->inference_debugging = conv->inference_debugging; m->trainableInputs[0] = conv->trainableInputs[0]; std::strcpy(m->op_name, conv->name); + m->layer_guid = conv->layer_guid; int input_w = acc_input.rect.hi[0] - acc_input.rect.lo[0] + 1; int input_h = acc_input.rect.hi[1] - acc_input.rect.lo[1] + 1; @@ -1012,6 +1014,8 @@ bool Conv2D::estimate_sync_cost(Simulator *sim, void Conv2D::serialize(Legion::Serializer &sez) const { sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); sez.serialize(this->out_channels); sez.serialize(this->kernel_h); sez.serialize(this->kernel_w); @@ -1022,6 +1026,8 @@ void Conv2D::serialize(Legion::Serializer &sez) const { sez.serialize(this->groups); sez.serialize(this->use_bias); sez.serialize(this->activation); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -1036,9 +1042,11 @@ Node Conv2D::deserialize(FFModel &ff, padding_w, groups; bool use_bias; ActiMode activation; - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); dez.deserialize(out_channels); dez.deserialize(kernel_h); dez.deserialize(kernel_w); @@ -1049,6 +1057,10 @@ Node Conv2D::deserialize(FFModel &ff, dez.deserialize(groups); dez.deserialize(use_bias); dez.deserialize(activation); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); Conv2DParams params; params.layer_guid = layer_guid; @@ -1062,6 +1074,7 @@ Node Conv2D::deserialize(FFModel &ff, params.groups = groups; params.use_bias = use_bias; params.activation = activation; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } diff --git a/src/ops/dropout.cc b/src/ops/dropout.cc index 2ebfaff539..3686c67e1e 100644 --- a/src/ops/dropout.cc +++ b/src/ops/dropout.cc @@ -118,7 +118,7 @@ Dropout::Dropout(FFModel &model, DropoutParams const ¶ms, ParallelTensor const input, char const *name) - : Dropout(model, input, params.rate, params.seed, name) {} + : Dropout(model, input, params.rate, params.seed, params.name) {} void Dropout::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -170,6 +170,8 @@ OpMeta *Dropout::init_task(Task const *task, .first(); assert(input_domain == output_domain); DropoutMeta *m = new DropoutMeta(handle, dropout, gpu_mem, output_domain); + std::strcpy(m->op_name, dropout->name); + m->layer_guid = dropout->layer_guid; return m; } @@ -276,6 +278,8 @@ void Dropout::backward_task(Task const *task, void Dropout::serialize(Legion::Serializer &sez) const { sez.serialize(this->rate); sez.serialize(this->seed); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } Node Dropout::deserialize(FFModel &ff, @@ -287,9 +291,14 @@ Node Dropout::deserialize(FFModel &ff, float rate; dez.deserialize(rate); dez.deserialize(seed); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); DropoutParams params; params.rate = rate; params.seed = seed; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } @@ -338,8 +347,9 @@ bool Dropout::measure_operator_cost(Simulator *sim, cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { - backward_kernel_wrapper(m, output_grad_acc, input_grad_acc); + backward = [=] { + backward_kernel_wrapper(m, output_grad_ptr, input_grad_ptr); + }; } diff --git a/src/ops/element_binary.cc b/src/ops/element_binary.cc index 84c3f8ba93..f080459d54 100644 --- a/src/ops/element_binary.cc +++ b/src/ops/element_binary.cc @@ -45,8 +45,11 @@ Tensor FFModel::binary(OperatorType op, assert(broadcastable(in1, in2)); if (in1->data_type < in2->data_type) { dtype = in2->data_type; - std::string str(name); - Tensor new_in1 = cast(in1, dtype, (str + "input1_pre_cast").c_str()); + std::string str; + if (name != nullptr) { + str = std::string(name) + "input1_pre_cast"; + } + Tensor new_in1 = cast(in1, dtype, str.c_str()); ele = new Layer(this, op, dtype, @@ -58,8 +61,11 @@ Tensor FFModel::binary(OperatorType op, in2); } else if (in1->data_type > in2->data_type) { dtype = in1->data_type; - std::string str(name); - Tensor new_in2 = cast(in2, dtype, (str + "input2_pre_cast").c_str()); + std::string str; + if (name != nullptr) { + str = std::string(name) + "input2_pre_cast"; + } + Tensor new_in2 = cast(in2, dtype, str.c_str()); ele = new Layer(this, op, dtype, @@ -83,8 +89,21 @@ Tensor FFModel::binary(OperatorType op, } // Assert type match after broadcast assert(ele->inputs[0]->data_type == ele->inputs[1]->data_type); + + int numdim = in1->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + if (in1->dims[i] == 1) { + dims[i] = in2->dims[i]; + } else if (in2->dims[i] == 1) { + dims[i] = in1->dims[i]; + } else { + dims[i] = in1->dims[i]; + } + } + ele->outputs[0] = create_tensor_legion_ordering( - in1->num_dims, in1->dims, ele->data_type, ele, 0, true /*create_grad*/); + in1->num_dims, dims, ele->data_type, ele, 0, true /*create_grad*/); ele->add_int_property("inplace_a", inplace_a); layers.push_back(ele); return ele->outputs[0]; @@ -97,8 +116,13 @@ Op *ElementBinary::create_operator_from_layer( long long value; layer->get_int_property("inplace_a", value); bool inplace_a = (bool)value; - return new ElementBinary( - model, layer->op_type, inputs[0], inputs[1], inplace_a, layer->name); + return new ElementBinary(model, + layer->layer_guid, + layer->op_type, + inputs[0], + inputs[1], + inplace_a, + layer->name); } Tensor FFModel::add(const Tensor in1, @@ -166,10 +190,12 @@ bool ElementBinaryParams::is_valid( bool operator==(ElementBinaryParams const &lhs, ElementBinaryParams const &rhs) { - return lhs.type == rhs.type; + return lhs.type == rhs.type && lhs.layer_guid == rhs.layer_guid && + lhs.inplace_a == rhs.inplace_a; } ElementBinary::ElementBinary(FFModel &model, + LayerID const &_layer_guid, OperatorType _op_type, const ParallelTensor in1, const ParallelTensor in2, @@ -185,6 +211,8 @@ ElementBinary::ElementBinary(FFModel &model, in1, in2), inplace_a(_inplace_a) { + // overwrite layer_guid + layer_guid = _layer_guid; numOutputs = 1; numWeights = 0; assert(in1->data_type == in2->data_type); @@ -220,10 +248,14 @@ ElementBinary::ElementBinary( FFModel &model, ElementBinaryParams const ¶ms, std::pair const &inputs, - char const *name, - bool inplace_a) - : ElementBinary( - model, params.type, inputs.first, inputs.second, inplace_a, name) {} + char const *name) + : ElementBinary(model, + params.layer_guid, + params.type, + inputs.first, + inputs.second, + params.inplace_a, + params.name) {} void ElementBinary::map_output_tensors(FFModel &ff) { if (has_inplace_output()) { @@ -263,6 +295,74 @@ void ElementBinary::do_inplace_output(void) { inplace_a = true; } +void ElementBinary::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + // Check if we have the same oprands + has_same_operands = (batch_inputs[0]->region == batch_inputs[1]->region); + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ELEMENTBINARY_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ElementBinary)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + int rid = 0; + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(rid++, FID_DATA); + if (!has_same_operands) { + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(rid++, FID_DATA); + } else { + assert(batch_inputs[0]->part == batch_inputs[1]->part); + } + if (!inplace_a) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(rid++, FID_DATA); + } else { + assert(batch_outputs[0]->part == batch_inputs[0]->part); + assert(batch_outputs[0]->region == batch_inputs[0]->region); + } + // launcher.add_region_requirement( + // RegionRequirement(input_grad_lps[0], 0/*projection id*/, + // WRITE_ONLY, EXCLUSIVE, inputs[0]->region_grad)); + // launcher.add_field(3, FID_DATA); + // if (inputs[0]->region_grad != inputs[1]->region_grad) { + // regions[4](I/O): input1_grad + // launcher.add_region_requirement( + // RegionRequirement(input_grad_lps[1], 0/*projection id*/, + // WRITE_ONLY, EXCLUSIVE, inputs[1]->region_grad)); + // launcher.add_field(4, FID_DATA); + //} + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + void ElementBinary::init(FFModel const &ff) { // Check if we have the same oprands has_same_operands = (inputs[0]->region == inputs[1]->region); @@ -330,12 +430,13 @@ OpMeta *ElementBinary::init_task(Task const *task, Runtime *runtime) { ElementBinary *eb = (ElementBinary *)task->args; FFHandler handle = *((FFHandler *)task->local_args); - ElementBinaryMeta *m = new ElementBinaryMeta(handle); + ElementBinaryMeta *m = new ElementBinaryMeta(handle, eb); for (int i = 0; i < eb->numInputs; i++) { m->trainableInputs[i] = eb->trainableInputs[i]; } m->op_type = eb->op_type; m->profiling = eb->profiling; + m->inference_debugging = eb->inference_debugging; m->inplace_a = eb->inplace_a; m->has_same_operands = eb->has_same_operands; m->broadcast_input1 = eb->broadcast_input1; @@ -343,6 +444,7 @@ OpMeta *ElementBinary::init_task(Task const *task, m->batch_size = eb->batch_size; std::strcpy(m->op_name, eb->name); + m->layer_guid = eb->layer_guid; Domain input1_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); Domain input2_domain, output_domain; @@ -447,6 +549,196 @@ void ElementBinary::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap + ElementBinary::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "ElementBinary op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(ELEMENTBINARY_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + if (inplace_a) { + assert(batch_outputs[0]->part == batch_inputs[0]->part); + assert(batch_outputs[0]->region == batch_inputs[0]->region); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + if (has_same_operands) { + // do nothing else + } else { + launcher.add_region_requirement( + RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + } + } else { + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + if (has_same_operands) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + } else { + launcher.add_region_requirement( + RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + } + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): in1 + regions[1](I): in2 + regions[2](O): output +*/ +__host__ void + ElementBinary::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + // const ElementBinary* ele = (const ElementBinary*) task->args; + ElementBinaryMeta *m = *((ElementBinaryMeta **)task->local_args); + GenericTensorAccessorR in1, in2; + GenericTensorAccessorW out; + Domain in1_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + + if (!m->has_same_operands) { + Domain in2_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + // Currently only support broadcast for add and sub + if (in1_domain != in2_domain) { + assert(m->op_type == OP_EW_SUB || m->op_type == OP_EW_ADD || + m->op_type == OP_EW_MUL); + } + } + + if (m->inplace_a) { + if (m->has_same_operands) { + assert(regions.size() == 1); + assert(task->regions.size() == 1); + out = helperGetGenericTensorAccessorRW(m->output_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = out; + in1 = out; + } else { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + out = helperGetGenericTensorAccessorRW(m->output_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = helperGetGenericTensorAccessorRO(m->input_type[1], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + in1 = out; + } + } else { + if (m->has_same_operands) { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + in1 = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = in1; + out = helperGetGenericTensorAccessorWO(m->output_type[0], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + } else { + assert(regions.size() == 3); + assert(task->regions.size() == 3); + in1 = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = helperGetGenericTensorAccessorRO(m->input_type[1], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + out = helperGetGenericTensorAccessorWO(m->output_type[0], + regions[2], + task->regions[2], + FID_DATA, + ctx, + runtime); + } + } + forward_kernel_wrapper(m, in1, in2, out); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + ElementBinary::save_inference_tensors_to_file( + m, shard_id, bc, {in1, in2}, {}, {out}); + } +} + /* regions[0](I): in1 regions[1](I): in2 @@ -459,8 +751,11 @@ __host__ void Runtime *runtime) { ElementBinary const *ele = (ElementBinary const *)task->args; ElementBinaryMeta const *m = *((ElementBinaryMeta **)task->local_args); + GenericTensorAccessorR in1, in2; + GenericTensorAccessorW out; Domain in1_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); + if (!m->has_same_operands) { Domain in2_domain = runtime->get_index_space_domain( ctx, task->regions[1].region.get_index_space()); @@ -470,53 +765,78 @@ __host__ void m->op_type == OP_EW_MUL); } } - float const *in1_ptr = NULL, *in2_ptr = NULL; - float *out_ptr = NULL; + if (m->inplace_a) { if (m->has_same_operands) { assert(regions.size() == 1); assert(task->regions.size() == 1); - out_ptr = helperGetTensorPointerRW( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - in2_ptr = out_ptr; - in1_ptr = out_ptr; + out = helperGetGenericTensorAccessorRW(m->output_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = out; + in1 = out; } else { assert(regions.size() == 2); assert(task->regions.size() == 2); - out_ptr = helperGetTensorPointerRW( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - in2_ptr = helperGetTensorPointerRO( - regions[1], task->regions[1], FID_DATA, ctx, runtime); - in1_ptr = out_ptr; + out = helperGetGenericTensorAccessorRW(m->output_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = helperGetGenericTensorAccessorRO(m->input_type[1], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + in1 = out; } } else { if (m->has_same_operands) { assert(regions.size() == 2); assert(task->regions.size() == 2); - Domain out_domain = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - // assert(out_domain == in1_domain); - in1_ptr = helperGetTensorPointerRO( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - in2_ptr = in1_ptr; - out_ptr = helperGetTensorPointerWO( - regions[1], task->regions[1], FID_DATA, ctx, runtime); + in1 = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = in1; + out = helperGetGenericTensorAccessorWO(m->output_type[0], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); } else { assert(regions.size() == 3); assert(task->regions.size() == 3); - Domain out_domain = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); - // assert(out_domain == in1_domain); - in1_ptr = helperGetTensorPointerRO( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - in2_ptr = helperGetTensorPointerRO( - regions[1], task->regions[1], FID_DATA, ctx, runtime); - out_ptr = helperGetTensorPointerWO( - regions[2], task->regions[2], FID_DATA, ctx, runtime); + in1 = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + in2 = helperGetGenericTensorAccessorRO(m->input_type[1], + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + out = helperGetGenericTensorAccessorWO(m->output_type[0], + regions[2], + task->regions[2], + FID_DATA, + ctx, + runtime); } } - forward_kernel_wrapper(m, in1_ptr, in2_ptr, out_ptr); + forward_kernel_wrapper(m, in1, in2, out); } void ElementBinary::backward(FFModel const &ff) { @@ -718,9 +1038,10 @@ bool ElementBinary::measure_operator_cost(Simulator *sim, if (!inputs[1]->get_sub_tensor(mv, sub_input2)) { return false; } - ElementBinaryMeta *m = sim->ele_binary_meta; + ElementBinaryMeta *m = new ElementBinaryMeta(sim->handler, this); m->op_type = op_type; m->profiling = this->profiling; + m->inference_debugging = this->inference_debugging; m->inplace_a = this->inplace_a; m->has_same_operands = this->has_same_operands; m->broadcast_input1 = this->broadcast_input1; @@ -734,8 +1055,12 @@ bool ElementBinary::measure_operator_cost(Simulator *sim, sim->free_all(); float *input1_ptr = (float *)sim->allocate(sub_input1.get_volume(), DT_FLOAT); assert(input1_ptr != NULL); + GenericTensorAccessorR input1_acc( + inputs[0]->data_type, input1_domain, input1_ptr); float *input2_ptr = (float *)sim->allocate(sub_input2.get_volume(), DT_FLOAT); assert(input2_ptr != NULL); + GenericTensorAccessorR input2_acc( + inputs[1]->data_type, input2_domain, input2_ptr); cost_metrics.inputs_memory += cost_metrics.total_mem_diff_from(sim->offset); float *output_ptr = NULL; @@ -745,13 +1070,15 @@ bool ElementBinary::measure_operator_cost(Simulator *sim, output_ptr = (float *)sim->allocate(sub_output.get_volume(), DT_FLOAT); } assert(output_ptr != NULL); + GenericTensorAccessorW output_acc( + outputs[0]->data_type, output_domain, output_ptr); cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); assert(m->profiling == false); std::function forward, backward; forward = [&] { - forward_kernel_wrapper(m, input1_ptr, input2_ptr, output_ptr); + forward_kernel_wrapper(m, input1_acc, input2_acc, output_acc); }; if (sim->computationMode == COMP_MODE_TRAINING) { float *input1_grad_ptr = @@ -773,7 +1100,7 @@ bool ElementBinary::measure_operator_cost(Simulator *sim, cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, output_grad_ptr, input1_ptr, @@ -800,6 +1127,7 @@ bool ElementBinary::measure_operator_cost(Simulator *sim, cost_metrics.forward_time); } + delete m; return true; } void ElementBinary::serialize(Legion::Serializer &sez) const { @@ -824,8 +1152,48 @@ Node ElementBinary::deserialize(FFModel &ff, return ff.get_or_create_node({inputs[0], inputs[1]}, params); } +void ElementBinary::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->op_type); + sez.serialize(this->inplace_a); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node ElementBinary::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 2); + OperatorType op_type; + size_t id, transformer_layer_id, deserialized_model_id; + bool inplace_a; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(op_type); + dez.deserialize(inplace_a); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + ElementBinaryParams params; + params.layer_guid = layer_guid; + params.type = op_type; + params.inplace_a = inplace_a; + strcpy(params.name, name); + return ff.get_or_create_node({inputs[0], inputs[1]}, params); +} + ElementBinaryParams ElementBinary::get_params() const { ElementBinaryParams params; + params.layer_guid = this->layer_guid; params.type = this->op_type; params.inplace_a = this->inplace_a; return params; @@ -837,7 +1205,9 @@ namespace std { size_t hash::operator()( FlexFlow::ElementBinaryParams const ¶ms) const { size_t key = 0; + hash_combine(key, params.layer_guid.id); hash_combine(key, params.type); + hash_combine(key, params.inplace_a); return key; } }; // namespace std diff --git a/src/ops/element_unary.cc b/src/ops/element_unary.cc index 46643b655b..31c0f9f8a3 100644 --- a/src/ops/element_unary.cc +++ b/src/ops/element_unary.cc @@ -27,11 +27,11 @@ Tensor FFModel::unary(OperatorType op, char const *name, float scalar) { Layer *ele = nullptr; - DataType dtype; - // FIXME: currently cast input to float if it has a lower type - if (x->data_type < DT_FLOAT) { + DataType dtype = x->data_type; + // if (x->data_type < DT_FLOAT) { + if (false) { dtype = DT_FLOAT; - std::string str(name); + std::string str = (name == nullptr) ? "" : std::string(name); Tensor new_x = cast(x, dtype, (str + "input_pre_cast").c_str()); ele = new Layer(this, op, @@ -213,7 +213,7 @@ ElementUnary::ElementUnary(FFModel &model, params.op_type, input, params.inplace, - name, + params.name, params.scalar) {} void ElementUnary::map_output_tensors(FFModel &ff) { @@ -299,6 +299,56 @@ void ElementUnary::init(FFModel const &ff) { set_opmeta_from_futuremap(ff, fm); } +void ElementUnary::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher init_launcher(ELEMENTUNARY_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ElementUnary)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + if (!inplace) { + init_launcher.add_region_requirement( + RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + init_launcher.add_field(0, FID_DATA); + init_launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + init_launcher.add_field(1, FID_DATA); + } else { + init_launcher.add_region_requirement( + RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + init_launcher.add_field(0, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, init_launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + OpMeta *ElementUnary::init_task(Task const *task, std::vector const ®ions, Context ctx, @@ -311,9 +361,11 @@ OpMeta *ElementUnary::init_task(Task const *task, // Input and output should have the same data type assert(eu->outputs[0]->data_type == eu->inputs[0]->data_type); m->profiling = eu->profiling; + m->inference_debugging = eu->inference_debugging; m->inplace = eu->inplace; m->scalar = eu->scalar; std::strcpy(m->op_name, eu->name); + m->layer_guid = eu->layer_guid; if (m->inplace) { assert(regions.size() == 1); assert(task->regions.size() == 1); @@ -369,12 +421,90 @@ void ElementUnary::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap + ElementUnary::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(ELEMENTUNARY_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + if (inplace) { + assert(batch_outputs[0]->part == batch_inputs[0]->part); + assert(batch_outputs[0]->region == batch_inputs[0]->region); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + } else { + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +void ElementUnary::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + ElementUnaryMeta const *m = *((ElementUnaryMeta **)task->local_args); + if (m->data_type == DT_HALF) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (m->data_type == DT_FLOAT) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (m->data_type == DT_DOUBLE) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (m->data_type == DT_INT32) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (m->data_type == DT_INT64) { + forward_task_with_type(task, regions, ctx, runtime); + } else { + assert(false && "Unsupported data type in Embedding forward"); + } +} + void ElementUnary::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { ElementUnaryMeta const *m = *((ElementUnaryMeta **)task->local_args); - if (m->data_type == DT_FLOAT) { + if (m->data_type == DT_HALF) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (m->data_type == DT_FLOAT) { forward_task_with_type(task, regions, ctx, runtime); } else if (m->data_type == DT_DOUBLE) { forward_task_with_type(task, regions, ctx, runtime); @@ -398,7 +528,7 @@ void ElementUnary::forward_task_with_type( Context ctx, Runtime *runtime) { // const ElementUnary* ele = (const ElementUnary*) task->args; - ElementUnaryMeta const *m = *((ElementUnaryMeta **)task->local_args); + ElementUnaryMeta *m = *((ElementUnaryMeta **)task->local_args); Domain input_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); const DT *input_ptr = NULL; @@ -423,6 +553,27 @@ void ElementUnary::forward_task_with_type( ElementUnary::forward_kernel_wrapper
( m, input_ptr, output_ptr, input_domain.get_volume()); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector input_accessors; + std::vector output_accessors; + if (m->inplace) { + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->data_type, regions[0], task->regions[0], FID_DATA, ctx, runtime); + output_accessors.push_back(output); + } else { + GenericTensorAccessorR input = helperGetGenericTensorAccessorWO( + m->data_type, regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->data_type, regions[1], task->regions[1], FID_DATA, ctx, runtime); + input_accessors.push_back(input); + output_accessors.push_back(output); + } + ElementUnary::save_inference_tensors_to_file( + m, shard_id, nullptr, input_accessors, {}, output_accessors); + } } void ElementUnary::backward(FFModel const &ff) { @@ -571,6 +722,10 @@ void ElementUnary::serialize(Legion::Serializer &sez) const { sez.serialize(this->inplace); sez.serialize(scalar); sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } bool ElementUnary::measure_operator_cost(Simulator *sim, @@ -639,7 +794,7 @@ bool ElementUnary::measure_operator_cost(Simulator *sim, cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, input_ptr, input_grad_ptr, @@ -681,15 +836,22 @@ Node ElementUnary::deserialize(FFModel &ff, dez.deserialize(op_type); dez.deserialize(inplace); dez.deserialize(scalar); - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); ElementUnaryParams params; params.op_type = op_type; params.inplace = inplace; params.scalar = scalar; params.layer_guid = layer_guid; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } diff --git a/src/ops/element_unary.cpp b/src/ops/element_unary.cpp index 38c6043297..9c1e61032a 100644 --- a/src/ops/element_unary.cpp +++ b/src/ops/element_unary.cpp @@ -45,10 +45,11 @@ void ElementUnary::init_kernel(ElementUnaryMeta *m, assert(false); } checkCUDNN(miopenSetActivationDescriptor(m->actiDesc, mode, 0.0, 0.0, 0.0)); - checkCUDNN(cudnnSetTensorDescriptorFromDomain(m->inputTensor, input_domain)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->inputTensor, input_domain, m->data_type)); // input_domain == output_domain - checkCUDNN( - cudnnSetTensorDescriptorFromDomain(m->outputTensor, output_domain)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->outputTensor, output_domain, m->data_type)); } template @@ -81,7 +82,9 @@ __global__ void elewise_unary_forward_kernel( break; } case OP_GELU: { - out[i] = (T)(in[i] * 0.5 * erfc(-in[i] * M_SQRT1_2)); + out[i] = (T)(in[i] * static_cast(0.5f) * + static_cast(erfc(static_cast( + -in[i] * static_cast(M_SQRT1_2))))); break; } case OP_RSQRT: { @@ -285,6 +288,11 @@ ElementUnaryMeta::ElementUnaryMeta(FFHandler handler) : OpMeta(handler) { checkCUDNN(miopenCreateActivationDescriptor(&actiDesc)); } +template void + ElementUnary::forward_kernel_wrapper(ElementUnaryMeta const *m, + half const *input_ptr, + half *output_ptr, + size_t num_elements); template void ElementUnary::forward_kernel_wrapper(ElementUnaryMeta const *m, float const *input_ptr, diff --git a/src/ops/element_unary.cu b/src/ops/element_unary.cu index 187e60282f..20ca34e9d7 100644 --- a/src/ops/element_unary.cu +++ b/src/ops/element_unary.cu @@ -45,10 +45,11 @@ void ElementUnary::init_kernel(ElementUnaryMeta *m, } checkCUDNN(cudnnSetActivationDescriptor( m->actiDesc, mode, CUDNN_PROPAGATE_NAN, 0.0)); - checkCUDNN(cudnnSetTensorDescriptorFromDomain(m->inputTensor, input_domain)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->inputTensor, input_domain, m->data_type)); // input_domain == output_domain - checkCUDNN( - cudnnSetTensorDescriptorFromDomain(m->outputTensor, output_domain)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->outputTensor, output_domain, m->data_type)); } template @@ -81,7 +82,9 @@ __global__ void elewise_unary_forward_kernel( break; } case OP_GELU: { - out[i] = (T)(in[i] * 0.5 * erfc(-in[i] * M_SQRT1_2)); + out[i] = (T)(in[i] * static_cast(0.5f) * + static_cast(erfc(static_cast( + -in[i] * static_cast(M_SQRT1_2))))); break; } case OP_RSQRT: { @@ -294,6 +297,11 @@ ElementUnaryMeta::ElementUnaryMeta(FFHandler handler) : OpMeta(handler) { checkCUDNN(cudnnCreateActivationDescriptor(&actiDesc)); } +template void + ElementUnary::forward_kernel_wrapper(ElementUnaryMeta const *m, + half const *input_ptr, + half *output_ptr, + size_t num_elements); template void ElementUnary::forward_kernel_wrapper(ElementUnaryMeta const *m, float const *input_ptr, @@ -314,7 +322,6 @@ template void int64_t const *input_ptr, int64_t *output_ptr, size_t num_elements); - template void ElementUnary::backward_kernel_wrapper(ElementUnaryMeta const *m, float const *input_ptr, diff --git a/src/ops/embedding.cc b/src/ops/embedding.cc index 8df6324460..e630563b63 100644 --- a/src/ops/embedding.cc +++ b/src/ops/embedding.cc @@ -243,7 +243,7 @@ Embedding::Embedding(FFModel &model, params.aggr, allocate_weights, params.data_type, - name) {} + params.name) {} Embedding::Embedding(FFModel &model, Embedding const &other, @@ -363,6 +363,45 @@ void Embedding::init(FFModel const &ff) { set_opmeta_from_futuremap(ff, fm); } +void Embedding::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(EMBED_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Embedding)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + // regions[2]: weight + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + OpMeta *Embedding::init_task(Task const *task, std::vector const ®ions, Context ctx, @@ -371,7 +410,10 @@ OpMeta *Embedding::init_task(Task const *task, FFHandler handle = *((FFHandler const *)task->local_args); EmbeddingMeta *m = new EmbeddingMeta(handle, embed); m->profiling = embed->profiling; + m->inference_debugging = embed->inference_debugging; m->aggr = embed->aggr; + std::strcpy(m->op_name, embed->name); + m->layer_guid = embed->layer_guid; return m; } @@ -413,6 +455,54 @@ void Embedding::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap Embedding::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(EMBED_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // regions[0]: input + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // regions[1]: output + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region, + MAP_TO_ZC_MEMORY)); + launcher.add_field(1, FID_DATA); + // regions[2]: weight + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + /* regions[0](I): input regions[1](O): output @@ -422,7 +512,7 @@ void Embedding::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - EmbeddingMeta const *m = *((EmbeddingMeta **)task->local_args); + EmbeddingMeta *m = *((EmbeddingMeta **)task->local_args); assert(regions.size() == 3); assert(task->regions.size() == 3); // Assert that weight and output must have the same data type @@ -469,75 +559,81 @@ void Embedding::forward_task(Task const *task, } forward_kernel_wrapper( m, input, output, kernel, in_dim, out_dim, effective_batch_size); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Embedding::save_inference_tensors_to_file( + m, shard_id, nullptr, {input}, {kernel}, {output}); + } } -#ifdef DEADCODE -template -void Embedding::forward_task_with_type( - Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { +/* + regions[0](I): input + regions[1](O): output + regions[2](I): kernel +*/ +void Embedding::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + EmbeddingMeta *m = *((EmbeddingMeta **)task->local_args); assert(regions.size() == 3); assert(task->regions.size() == 3); - // const Embedding* embed = (Embedding*) task->args; - EmbeddingMeta const *m = *((EmbeddingMeta **)task->local_args); - Domain input_domain = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - Domain output_domain = runtime->get_index_space_domain( - ctx, task->regions[1].region.get_index_space()); - Domain kernel_domain = runtime->get_index_space_domain( - ctx, task->regions[2].region.get_index_space()); + // Assert that weight and output must have the same data type + // otherwise, a cast operator should be inserted + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_active_tokens() == 0) { + return; + } + assert(m->weight_type[0] == m->output_type[0]); + assert(m->input_type[0] == DT_INT32 || m->input_type[0] == DT_INT64); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR kernel = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); if (m->aggr == AGGR_MODE_NONE) { // assert(kernel_domain.get_dim() == 2); - assert(input_domain.get_dim() + 1 == output_domain.get_dim()); - for (size_t i = 0; i < input_domain.get_dim(); i++) { - assert(input_domain.hi()[i] == output_domain.hi()[i + 1]); - assert(input_domain.lo()[i] == output_domain.lo()[i + 1]); + assert(input.domain.get_dim() + 1 == output.domain.get_dim()); + for (size_t i = 0; i < input.domain.get_dim(); i++) { + assert(input.domain.hi()[i] == output.domain.hi()[i + 1]); + assert(input.domain.lo()[i] == output.domain.lo()[i + 1]); } - assert(kernel_domain.hi()[0] - kernel_domain.lo()[0] == - output_domain.hi()[0] - output_domain.lo()[0]); + assert(kernel.domain.hi()[0] - kernel.domain.lo()[0] == + output.domain.hi()[0] - output.domain.lo()[0]); } else { // assert(kernel_domain.get_dim() == 2); - assert(input_domain.get_dim() == output_domain.get_dim()); - for (size_t i = 1; i < input_domain.get_dim(); i++) { - assert(input_domain.hi()[i] == output_domain.hi()[i]); - assert(input_domain.lo()[i] == output_domain.lo()[i]); + assert(input.domain.get_dim() == output.domain.get_dim()); + for (size_t i = 1; i < input.domain.get_dim(); i++) { + assert(input.domain.hi()[i] == output.domain.hi()[i]); + assert(input.domain.lo()[i] == output.domain.lo()[i]); } - assert(kernel_domain.hi()[0] - kernel_domain.lo()[0] == - output_domain.hi()[0] - output_domain.lo()[0]); + assert(kernel.domain.hi()[0] - kernel.domain.lo()[0] == + output.domain.hi()[0] - output.domain.lo()[0]); } - const TI *input_ptr = helperGetTensorPointerRO( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - float *output_ptr = helperGetTensorPointerWO( - regions[1], task->regions[1], FID_DATA, ctx, runtime); - float const *kernel_ptr = helperGetTensorPointerRO( - regions[2], task->regions[2], FID_DATA, ctx, runtime); int in_dim, out_dim, effective_batch_size; if (m->aggr == AGGR_MODE_NONE) { in_dim = 1; - out_dim = output_domain.hi()[0] - output_domain.lo()[0] + 1; - effective_batch_size = output_domain.get_volume() / out_dim; - assert(effective_batch_size * in_dim == input_domain.get_volume()); + out_dim = output.domain.hi()[0] - output.domain.lo()[0] + 1; + effective_batch_size = output.domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == input.domain.get_volume()); } else { - in_dim = input_domain.hi()[0] - input_domain.lo()[0] + 1; - out_dim = output_domain.hi()[0] - output_domain.lo()[0] + 1; - effective_batch_size = output_domain.get_volume() / out_dim; - assert(effective_batch_size * in_dim == input_domain.get_volume()); + in_dim = input.domain.hi()[0] - input.domain.lo()[0] + 1; + out_dim = output.domain.hi()[0] - output.domain.lo()[0] + 1; + effective_batch_size = output.domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == input.domain.get_volume()); + } + forward_kernel_wrapper( + m, input, output, kernel, in_dim, out_dim, effective_batch_size); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Embedding::save_inference_tensors_to_file( + m, shard_id, nullptr, {input}, {kernel}, {output}); } - - forward_kernel_wrapper(m, - input_ptr, - output_ptr, - kernel_ptr, - in_dim, - out_dim, - effective_batch_size, - m->aggr, - output_domain.get_volume()); } -#endif void Embedding::backward(FFModel const &ff) { ArgumentMap argmap; diff --git a/src/ops/experts.cc b/src/ops/experts.cc new file mode 100644 index 0000000000..8c66f9c7bc --- /dev/null +++ b/src/ops/experts.cc @@ -0,0 +1,1183 @@ +/* Copyright 2022 CMU + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/experts.h" +#ifdef INFERENCE_TESTS +#include "flexflow/utils/cuda_helper.h" +#endif +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +static constexpr int KERNEL_IDX = 0; +static constexpr int BIAS_IDX = 1; +#ifdef INFERENCE_TESTS +static bool DEBUG_MODE = false; +#endif + +// For now, we use one input and one output per expert +Tensor FFModel::experts(Tensor const *inputs, + int num_experts, + int experts_start_idx, + int experts_output_dim_size, + float alpha, + int experts_num_layers, + int experts_internal_dim_size, + char const *name) { + + // Check that there are three inputs: the input tensor, the indices and the + // topk_gate_preds + assert(inputs[0] != nullptr); + int num_dims = inputs[0]->num_dims; + assert(inputs[1]->num_dims == num_dims); + assert(inputs[2]->num_dims == num_dims); + int topk = inputs[1]->dims[0]; + assert(inputs[2]->dims[0] == topk); + for (int i = 1; i < num_dims; i++) { + assert(inputs[0]->dims[i] == inputs[1]->dims[i]); + assert(inputs[1]->dims[i] == inputs[2]->dims[i]); + } + + assert(inputs[1]->data_type == DT_INT32 || inputs[1]->data_type == DT_INT64); + + assert(experts_num_layers >= 1); + assert(experts_num_layers <= 2 && "Multi-layer experts not implemented yet."); + assert(experts_num_layers == 1 || experts_internal_dim_size > 0); + + // parameters for the FFN implementing the experts. We can make these + // FFModel::experts(...) function parameters if needed. + bool use_bias = true; + ActiMode activation = AC_MODE_RELU; + + Layer *e = new Layer(this, + OP_EXPERTS, + DT_FLOAT, + name, + 3 /*inputs*/, + (1 + use_bias) /*weights*/, + 1 /*outputs*/, + inputs); + { + int dims[MAX_TENSOR_DIM]; + for (int i = 1; i < num_dims; i++) { + dims[i] = inputs[0]->dims[i]; + } + dims[0] = experts_output_dim_size; + e->outputs[0] = create_tensor_legion_ordering( + num_dims, dims, DT_FLOAT, e, 0, true /*create_grad*/); + assert(e->outputs[0] != nullptr); + } + { + int nparams = (experts_num_layers == 1) + ? (inputs[0]->dims[0] * experts_output_dim_size) + : experts_internal_dim_size * + (inputs[0]->dims[0] + experts_output_dim_size); + int dims[2] = {nparams, num_experts}; + e->weights[0] = create_weight_legion_ordering( + 2, dims, DT_FLOAT, e, true /*create_grad*/, nullptr, CHOSEN_SYNC_TYPE); + } + if (use_bias) { + int nparams = (experts_num_layers == 1) + ? experts_output_dim_size + : (experts_internal_dim_size + experts_output_dim_size); + int dims[2] = {nparams, num_experts}; + e->weights[1] = create_weight_legion_ordering( + 2, dims, DT_FLOAT, e, true /*create_grad*/, nullptr, CHOSEN_SYNC_TYPE); + } + + e->add_int_property("num_experts", num_experts); + e->add_int_property("experts_start_idx", experts_start_idx); + e->add_int_property("experts_output_dim_size", experts_output_dim_size); + e->add_float_property("alpha", alpha); + e->add_int_property("experts_num_layers", experts_num_layers); + e->add_int_property("experts_internal_dim_size", experts_internal_dim_size); + e->add_int_property("use_bias", use_bias); + e->add_int_property("activation", activation); + layers.push_back(e); + + return e->outputs[0]; +} + +Op *Experts::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("num_experts", value); + int num_experts = value; + layer->get_int_property("experts_start_idx", value); + int experts_start_idx = value; + layer->get_int_property("experts_output_dim_size", value); + int experts_output_dim_size = value; + float value2; + layer->get_float_property("alpha", value2); + float alpha = value2; + layer->get_int_property("experts_num_layers", value); + int experts_num_layers = value; + layer->get_int_property("experts_internal_dim_size", value); + int experts_internal_dim_size = value; + layer->get_int_property("use_bias", value); + bool use_bias = (bool)value; + layer->get_int_property("activation", value); + ActiMode activation = (ActiMode)value; + return new Experts(model, + layer->layer_guid, + inputs.data(), + num_experts, + experts_start_idx, + experts_output_dim_size, + alpha, + experts_num_layers, + experts_internal_dim_size, + use_bias, + activation, + false /*allocate_weights*/, + layer->name); +} + +ExpertsParams Experts::get_params() const { + ExpertsParams params; + params.layer_guid = this->layer_guid; + params.num_experts = num_experts; + params.experts_start_idx = experts_start_idx; + params.experts_output_dim_size = experts_output_dim_size; + params.alpha = alpha; + params.experts_num_layers = experts_num_layers; + params.experts_internal_dim_size = experts_internal_dim_size; + params.use_bias = use_bias; + params.activation = activation; + return params; +} + +bool ExpertsParams::is_valid( + std::vector const &inputs) const { + if (inputs.size() != 3) { + printf("Number of inputs to the Experts layer is wrong\n"); + return false; + } + if (!inputs[0].is_valid()) { + printf("The first tensor passed to the Experts layer is not valid\n"); + return false; + } + if (!inputs[1].is_valid()) { + printf("The second tensor passed to the Experts layer is not valid\n"); + return false; + } + if (!inputs[2].is_valid()) { + printf("The third tensor passed to the Experts layer is not valid\n"); + return false; + } + if (inputs[0].num_dims != inputs[1].num_dims || + inputs[1].num_dims != inputs[2].num_dims) { + printf("Mismatch found between the number of dimensions of the three input " + "tensors for the Expert layer\n"); + return false; + } + if (inputs[0].data_type != DT_FLOAT) { + printf("Data type of the first input to the Experts layer is wrong!\n"); + return false; + } + if (inputs[1].data_type != DT_INT32 && inputs[1].data_type != DT_INT64) { + printf("Data type of the second input to the Experts layer is wrong!\n"); + return false; + } + if (inputs[2].data_type != DT_FLOAT) { + printf("Data type of the third input to the Experts layer is wrong!\n"); + return false; + } + if (inputs[1].dims[0] != inputs[2].dims[0]) { + printf( + "Dimension mismatch between indices and topk_gate_preds tensors passed " + "to the Experts layer.\n"); + return false; + } + for (int i = 1; i < inputs[0].num_dims; i++) { + if (inputs[0].dims[i] != inputs[1].dims[i] || + inputs[1].dims[i] != inputs[2].dims[i]) { + printf("Dimension mismatch among the input tensors passed to the Experts " + "layer.\n"); + return false; + } + } + return true; +} + +bool operator==(ExpertsParams const &lhs, ExpertsParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && + lhs.num_experts == rhs.num_experts && + lhs.experts_start_idx == rhs.experts_start_idx && + lhs.experts_output_dim_size == rhs.experts_output_dim_size && + lhs.alpha == rhs.alpha && + lhs.experts_num_layers == rhs.experts_num_layers && + lhs.experts_internal_dim_size == rhs.experts_internal_dim_size && + lhs.use_bias == rhs.use_bias && lhs.activation == rhs.activation; +} + +Experts::Experts(FFModel &model, + ExpertsParams const ¶ms, + std::vector const &inputs, + bool allocate_weights, + char const *name) + : Experts(model, + params.layer_guid, + inputs.data(), + params.num_experts, + params.experts_start_idx, + params.experts_output_dim_size, + params.alpha, + params.experts_num_layers, + params.experts_internal_dim_size, + params.use_bias, + params.activation, + allocate_weights, + params.name) {} + +Experts::Experts(FFModel &model, + LayerID const &_layer_guid, + ParallelTensor const *inputs, + int _num_experts, + int _experts_start_idx, + int _experts_output_dim_size, + float _alpha, + int _experts_num_layers, + int _experts_internal_dim_size, + bool _use_bias, + ActiMode _activation, + bool allocate_weights, + char const *name) + : Op(model, + OP_EXPERTS, + DT_FLOAT, + name, + 3 /*inputs*/, + (1 + _use_bias) /*weights*/, + 1 /*outputs*/, + inputs), + num_experts(_num_experts), experts_start_idx(_experts_start_idx), + experts_output_dim_size(_experts_output_dim_size), alpha(_alpha), + experts_num_layers(_experts_num_layers), + experts_internal_dim_size(_experts_internal_dim_size), + use_bias(_use_bias), activation(_activation) { + + // overwrite layer_guid + layer_guid = _layer_guid; + + // Check number of inputs, output, weights + assert(num_experts > 0); + assert(numInputs == 3); + assert(numOutputs == 1); + assert(numWeights == (1 + use_bias)); + + // Check input dimensions + int num_dims = inputs[0]->num_dims; + int topk = inputs[1]->dims[0].size; + assert(inputs[0] != nullptr); + assert(inputs[1]->num_dims == num_dims); + assert(inputs[2]->num_dims == num_dims); + assert(inputs[2]->dims[0].size == topk); + for (int i = 1; i < num_dims; i++) { + assert(inputs[0]->dims[i] == inputs[1]->dims[i]); + assert(inputs[1]->dims[i] == inputs[2]->dims[i]); + } + // Assume that we don't parallelize the channel dim of input + // nor the expert_assigned dim of indices + assert(inputs[0]->dims[0].degree == 1); + assert(inputs[1]->dims[0].degree == 1); + assert(inputs[2]->dims[0].degree == 1); + // check data type of indices input + assert(inputs[1]->data_type == DT_INT32 || inputs[1]->data_type == DT_INT64); + assert(experts_num_layers >= 1); + assert(experts_num_layers <= 2 && "Multi-layer experts not implemented yet."); + assert(experts_num_layers == 1 || experts_internal_dim_size > 0); + + // save the token embedding dimension (data_dim) and the effective batch size + data_dim = inputs[0]->dims[0].size; + effective_batch_size = 1; + for (int i = 1; i <= num_dims - 2; i++) { + effective_batch_size *= inputs[0]->dims[i].size; + } + num_chosen_experts = topk; + + out_dim = _experts_output_dim_size; + + // Create the parallel tensor for the output + ParallelDim out_dims[MAX_TENSOR_DIM]; + for (int i = 0; i < num_dims; i++) { + out_dims[i] = inputs[0]->dims[i]; + } + out_dims[0].size = experts_output_dim_size; + outputs[0] = model.create_parallel_tensor_legion_ordering( + num_dims, out_dims, inputs[0]->data_type, this, 0 /*owner_idx*/); + assert(outputs[0] != nullptr); + + if (allocate_weights) { + { + ParallelDim dims[3]; + int nparams = (experts_num_layers == 1) + ? (data_dim * experts_output_dim_size) + : experts_internal_dim_size * + (data_dim + experts_output_dim_size); + dims[0].size = nparams; + dims[0].degree = 1; + dims[0].parallel_idx = -1; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = num_experts; + dims[2] = inputs[0]->dims[num_dims - 2]; + dims[2].size = dims[0].degree; + Initializer *kernel_initializer = new GlorotUniform(std::rand() /*seed*/); + // assert(kernel_shape.dims[2].size == num_experts); + weights[0] = + model.create_parallel_weight_legion_ordering(3, + dims, + DT_FLOAT, + NULL /*owner_op*/, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + assert(weights[0] != nullptr); + } + if (use_bias) { + Initializer *bias_initializer = new ZeroInitializer(); + // assert(bias_shape.dims[1].size == num_experts); + ParallelDim dims[3]; + int nparams = (experts_num_layers == 1) + ? experts_output_dim_size + : (experts_internal_dim_size + experts_output_dim_size); + dims[0].size = nparams; + dims[0].degree = 1; + dims[0].parallel_idx = -1; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = num_experts; + dims[2] = inputs[0]->dims[num_dims - 2]; + dims[2].size = dims[0].degree; + weights[1] = + model.create_parallel_weight_legion_ordering(3, + dims, + DT_FLOAT, + NULL /*owner_op*/, + true /*create_grad*/, + bias_initializer, + CHOSEN_SYNC_TYPE); + assert(weights[1] != nullptr); + } + } + assert(check_output_input_weight_parallel_dims(allocate_weights)); +} + +void Experts::serialize(Legion::Serializer &sez) const { + ExpertsParams params = get_params(); + sez.serialize(params.layer_guid.id); + sez.serialize(params.layer_guid.transformer_layer_id); + sez.serialize(params.layer_guid.model_id); + sez.serialize(params.num_experts); + sez.serialize(params.experts_start_idx); + sez.serialize(params.experts_output_dim_size); + sez.serialize(params.alpha); + sez.serialize(params.experts_num_layers); + sez.serialize(params.experts_internal_dim_size); + sez.serialize(params.use_bias); + sez.serialize(params.activation); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +Node Experts::deserialize(FFModel &ff, + Legion::Deserializer &dez, + std::vector const &inputs, + int num_inputs) { + int num_experts, experts_start_idx, experts_output_dim_size, + experts_num_layers, experts_internal_dim_size; + float alpha; + ActiMode activation; + bool use_bias; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(num_experts); + dez.deserialize(experts_start_idx); + dez.deserialize(experts_output_dim_size); + dez.deserialize(alpha); + dez.deserialize(experts_num_layers); + dez.deserialize(experts_internal_dim_size); + dez.deserialize(use_bias); + dez.deserialize(activation); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + assert(num_inputs == 3); + + ExpertsParams params; + params.layer_guid = layer_guid; + params.num_experts = num_experts; + params.experts_start_idx = experts_start_idx; + params.experts_output_dim_size = experts_output_dim_size; + params.alpha = alpha; + params.experts_num_layers = experts_num_layers; + params.experts_internal_dim_size = experts_internal_dim_size; + params.use_bias = use_bias; + params.activation = activation; + strcpy(params.name, name); + + return ff.get_or_create_node(inputs, params); +} + +void Experts::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(EXPERTS_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Experts)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // expert predictions + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // expert assignment indices + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // topk_gate_preds + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void Experts::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(EXPERTS_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Experts)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + // expert predictions + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // expert assignment indices + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // topk_gate_preds + launcher.add_region_requirement(RegionRequirement(inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[2]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *Experts::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + Experts const *exp = (Experts *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + ExpertsMeta *m = new ExpertsMeta(handle, + exp->num_experts, + exp->experts_start_idx, + exp->data_dim, + exp->out_dim, + exp->experts_num_layers, + exp->experts_internal_dim_size, + exp->effective_batch_size, + exp->num_chosen_experts, + exp->alpha, + exp->use_bias, + exp->activation); + m->profiling = exp->profiling; + m->inference_debugging = exp->inference_debugging; + std::strcpy(m->op_name, exp->name); + m->layer_guid = exp->layer_guid; + return m; +} + +void Experts::forward(FFModel const &ff) { + // assert(false && "Experts is designed for inference only"); + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_forward(ff, argmap); + IndexLauncher launcher(EXPERTS_FWD_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + // expert predictions + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // expert assignment indices + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // topk_gate_preds + launcher.add_region_requirement(RegionRequirement(inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[2]->region)); + launcher.add_field(2, FID_DATA); + // expert output per token (only the chosen experts have non-zero + // contributions) + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + } + runtime->execute_index_space(ctx, launcher); +} + +FutureMap Experts::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "Experts op machine_view: " << *(MachineView const *)mv + << std::endl; */ + // int num_active_tokens = bc->num_active_tokens(); + IndexLauncher launcher(EXPERTS_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + // expert predictions + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // expert assignment indices + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // topk_gate_preds + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(2, FID_DATA); + // expert output per token (only the chosen experts have non-zero + // contributions) + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(5, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +void Experts::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == task->regions.size()); + + ExpertsMeta *m = *((ExpertsMeta **)task->local_args); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + + int num_experts = m->num_experts; + bool use_bias = m->use_bias; + assert(regions.size() - 4 == (1 + use_bias)); + + // get input, indices, topk_gate_preds, outputs + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + DT_FLOAT, regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR indices = helperGetGenericTensorAccessorRO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR topk_gate_preds = helperGetGenericTensorAccessorRO( + DT_FLOAT, regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + DT_FLOAT, regions[3], task->regions[3], FID_DATA, ctx, runtime); + + float const *input_ptr = input.get_float_ptr(); + int const *indices_ptr = indices.get_int32_ptr(); + float const *topk_gate_pred_ptr = topk_gate_preds.get_float_ptr(); + float *output_ptr = output.get_float_ptr(); + assert(input_ptr != nullptr && indices_ptr != nullptr && + topk_gate_pred_ptr != nullptr && output_ptr != nullptr); + + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain indices_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain topk_gate_pred_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + + int input_dims = input_domain.get_dim(); + int indices_dims = indices_domain.get_dim(); + int topk_gate_pred_dims = topk_gate_pred_domain.get_dim(); + int output_dims = output_domain.get_dim(); + assert(input_dims == indices_dims); + assert(indices_dims == topk_gate_pred_dims); + assert(input_dims == output_dims); + + int replica_dim = input_dims - 1; + int samples_index = input_dims - 2; + + coord_t data_dim = input_domain.hi()[0] - input_domain.lo()[0] + 1; + coord_t batch_size = + input_domain.hi()[samples_index] - input_domain.lo()[samples_index] + 1; + coord_t chosen_experts = indices_domain.hi()[0] - indices_domain.lo()[0] + 1; + coord_t out_dim = output_domain.hi()[0] - output_domain.lo()[0] + 1; + coord_t num_replicas = + input_domain.hi()[replica_dim] - input_domain.lo()[replica_dim] + 1; + assert(data_dim == m->data_dim); + assert(out_dim == m->out_dim); + assert(chosen_experts == m->num_chosen_experts); + assert(chosen_experts == + topk_gate_pred_domain.hi()[0] - topk_gate_pred_domain.lo()[0] + 1); + + for (int i = 1; i < input_dims; i++) { + int a = input_domain.hi()[i] - input_domain.lo()[i] + 1; + int b = indices_domain.hi()[i] - indices_domain.lo()[i] + 1; + int c = topk_gate_pred_domain.hi()[i] - topk_gate_pred_domain.lo()[i] + 1; + assert(a == b && b == c); + if (i >= 1 && i < samples_index) { + batch_size *= a; + } + } + assert(batch_size == m->effective_batch_size); + + assert(batch_size <= MAX_BATCH_SIZE && + "batch size exceeds MAX_BATCH_SIZE defined in experts.h"); + assert( + num_experts <= MAX_EXPERTS_PER_BLOCK && + "number of experts exceeds MAX_EXPERTS_PER_BLOCK defined in experts.h"); + + for (int j = 1; j < input_dims; j++) { + int a = input_domain.hi()[j] - input_domain.lo()[j] + 1; + int b = output_domain.hi()[j] - output_domain.lo()[j] + 1; + assert(a == b); + } + + // get weights + float const *weights_ptr = helperGetTensorPointerRO( + regions[4], task->regions[4], FID_DATA, ctx, runtime); + assert(weights_ptr != nullptr); + Domain weights_domain = runtime->get_index_space_domain( + ctx, task->regions[4].region.get_index_space()); + int weights_dims = weights_domain.get_dim(); + assert(weights_dims == 3); + int nparams_weight = + (m->experts_num_layers == 1) + ? (data_dim * out_dim) + : m->experts_internal_dim_size * (data_dim + out_dim); + assert(weights_domain.hi()[0] - weights_domain.lo()[0] + 1 == nparams_weight); + assert(weights_domain.hi()[1] - weights_domain.lo()[1] + 1 == num_experts); + assert(weights_domain.hi()[2] - weights_domain.lo()[2] + 1 == num_replicas); + + float const *bias_ptr = nullptr; + int nparams_bias = -1; + if (use_bias) { + bias_ptr = helperGetTensorPointerRO( + regions[5], task->regions[5], FID_DATA, ctx, runtime); + Domain bias_domain = runtime->get_index_space_domain( + ctx, task->regions[5].region.get_index_space()); + int bias_dims = bias_domain.get_dim(); + assert(bias_dims == 3); + nparams_bias = (m->experts_num_layers == 1) + ? out_dim + : (m->experts_internal_dim_size + out_dim); + assert(bias_domain.hi()[0] - bias_domain.lo()[0] + 1 == nparams_bias); + assert(bias_domain.hi()[1] - bias_domain.lo()[1] + 1 == num_experts); + assert(bias_domain.hi()[2] - bias_domain.lo()[2] + 1 == num_replicas); + } + +#ifdef INFERENCE_TESTS + if (DEBUG_MODE) { + std::cout << "forward_kernel_wrapper" << std::endl + << "-------------------------------" << std::endl; + std::cout << m->data_dim << std::endl; + std::cout << m->out_dim << std::endl; + std::cout << m->num_chosen_experts << std::endl; + std::cout << m->effective_batch_size << std::endl; + std::cout << m->experts_num_layers << std::endl; + std::cout << m->experts_internal_dim_size << std::endl; + std::cout << m->num_experts << std::endl; + std::cout << m->use_bias << std::endl; + + /* ----------------Input Token--------------*/ + float *cpu_input_ptr = new float[data_dim]; + checkCUDA(cudaMemcpy(cpu_input_ptr, + input_ptr, + data_dim * sizeof(float), + cudaMemcpyDeviceToHost)); + + srand(42); + float cpu_sum = 0; + for (int i = 0; i < data_dim; i++) { + // cpu_input_ptr[i] = (float)rand() / (float)RAND_MAX; + cpu_input_ptr[i] = float(i) / (float)data_dim; + cpu_sum += cpu_input_ptr[i]; + } + std::cout << "[CPU] Token 0 sum = " << cpu_sum << std::endl; + std::cout << "Total token number = " << batch_size << std::endl; + for (int i = 0; i < batch_size; i++) { + checkCUDA(cudaMemcpy((float *)(input_ptr + i * data_dim), + cpu_input_ptr, + data_dim * sizeof(float), + cudaMemcpyHostToDevice)); + } + free(cpu_input_ptr); + + /* ----------------indices--------------*/ + int *cpu_indices_ptr = new int[chosen_experts * batch_size]; + checkCUDA(cudaMemcpy(cpu_indices_ptr, + indices_ptr, + chosen_experts * batch_size * sizeof(int), + cudaMemcpyDeviceToHost)); + for (int i = 0; i < chosen_experts * 10; i++) { + if (i % 2 == 1) { + cpu_indices_ptr[i] += chosen_experts; + } + } + checkCUDA(cudaMemcpy((int *)indices_ptr, + cpu_indices_ptr, + chosen_experts * batch_size * sizeof(int), + cudaMemcpyHostToDevice)); + free(cpu_indices_ptr); + + /* ----------------coefficient--------------*/ + float *cpu_topk_gate_pred_ptr = new float[chosen_experts * batch_size]; + checkCUDA(cudaMemcpy(cpu_topk_gate_pred_ptr, + topk_gate_pred_ptr, + chosen_experts * batch_size * sizeof(float), + cudaMemcpyDeviceToHost)); + for (int i = 0; i < chosen_experts * batch_size; i++) { + if (i % 2 == 0) { + cpu_topk_gate_pred_ptr[i] = 0.5; + } else { + cpu_topk_gate_pred_ptr[i] = 0.1; + } + } + checkCUDA(cudaMemcpy((float *)topk_gate_pred_ptr, + cpu_topk_gate_pred_ptr, + chosen_experts * batch_size * sizeof(float), + cudaMemcpyHostToDevice)); + free(cpu_topk_gate_pred_ptr); + + /* ----------------Expert Weights--------------*/ + assert(m->experts_num_layers == 2 || m->experts_num_layers == 1); + size_t layer0_size = m->experts_num_layers == 1 + ? data_dim * out_dim + : data_dim * m->experts_internal_dim_size; + size_t layer1_size = m->experts_internal_dim_size * out_dim; + float *cpu_experts_0_layer0 = new float[layer0_size]; + float *cpu_experts_1_layer0 = new float[layer0_size]; + float *cpu_experts_0_layer1 = + m->experts_num_layers == 1 ? nullptr : new float[layer1_size]; + float *cpu_experts_1_layer1 = + m->experts_num_layers == 1 ? nullptr : new float[layer1_size]; + /*checkCUDA(cudaMemcpy(cpu_experts_0_layer0, + weights_ptr, + layer0_size * sizeof(float), + cudaMemcpyDeviceToHost)); + checkCUDA(cudaMemcpy(cpu_experts_1_layer0, + weights_ptr[nparams_weight], + layer0_size * sizeof(float), + cudaMemcpyDeviceToHost)); + if (m->experts_num_layers == 2) { + checkCUDA(cudaMemcpy(cpu_experts_0_layer1, + weights_ptr[layer0_size], + layer1_size * sizeof(float), + cudaMemcpyDeviceToHost)); + checkCUDA(cudaMemcpy(cpu_experts_1_layer1, + weights_ptr[nparams_weight + layer0_size], + layer1_size * sizeof(float), + cudaMemcpyDeviceToHost)); + }*/ + cpu_sum = 0; + for (int i = 0; i < layer0_size; i++) { + cpu_experts_0_layer0[i] = float(i) / float(nparams_weight); + cpu_sum += cpu_experts_0_layer0[i]; + } + if (m->experts_num_layers == 2) { + for (int i = 0; i < layer1_size; i++) { + cpu_experts_0_layer1[i] = + float(layer0_size + i) / float(nparams_weight); + cpu_sum += cpu_experts_0_layer1[i]; + } + } + std::cout << "[CPU] Experts 0 weights sum = " << cpu_sum << std::endl; + + cpu_sum = 0; + for (int i = 0; i < layer0_size; i++) { + cpu_experts_1_layer0[i] = + float(nparams_weight - i) / float(nparams_weight); + assert(cpu_experts_1_layer0[i] > 0); + cpu_sum += cpu_experts_1_layer0[i]; + } + if (m->experts_num_layers == 2) { + for (int i = 0; i < layer1_size; i++) { + cpu_experts_1_layer1[i] = + float(nparams_weight - layer0_size + i) / float(nparams_weight); + assert(cpu_experts_1_layer1[i] > 0); + cpu_sum += cpu_experts_1_layer1[i]; + } + } + std::cout << "[CPU] Experts 1 weights sum = " << cpu_sum << std::endl; + + for (int i = 0; i < num_experts; i++) { + // first layer + checkCUDA( + cudaMemcpy((float *)&weights_ptr[nparams_weight * i], + i % 2 == 0 ? cpu_experts_0_layer0 : cpu_experts_1_layer0, + layer0_size * sizeof(float), + cudaMemcpyHostToDevice)); + // second layer + if (m->experts_num_layers == 2) { + checkCUDA( + cudaMemcpy((float *)&weights_ptr[nparams_weight * i + layer0_size], + i % 2 == 0 ? cpu_experts_0_layer1 : cpu_experts_1_layer1, + layer1_size * sizeof(float), + cudaMemcpyHostToDevice)); + } + } + free(cpu_experts_0_layer0); + free(cpu_experts_1_layer0); + free(cpu_experts_0_layer1); + free(cpu_experts_1_layer1); + + /* ----------------Expert Bias--------------*/ + if (use_bias) { + size_t layer0_size = + m->experts_num_layers == 1 ? out_dim : m->experts_internal_dim_size; + size_t layer1_size = out_dim; + float *bias_experts_0_layer0 = new float[layer0_size]; + float *bias_experts_0_layer1 = + m->experts_num_layers == 1 ? nullptr : new float[layer1_size]; + + checkCUDA(cudaMemcpy(bias_experts_0_layer0, + bias_ptr, + layer0_size * sizeof(float), + cudaMemcpyDeviceToHost)); + cpu_sum = 0; + for (int i = 0; i < layer0_size; i++) { + cpu_sum += bias_experts_0_layer0[i]; + // bias_experts_1[i] = 1.0f; + } + std::cout << "[CPU] Bias expert 0 (layer 0) sum = " << cpu_sum + << std::endl; + + if (m->experts_num_layers == 2) { + checkCUDA(cudaMemcpy(bias_experts_0_layer1, + (float *)&bias_ptr[layer0_size], + layer1_size * sizeof(float), + cudaMemcpyDeviceToHost)); + cpu_sum = 0; + for (int i = 0; i < layer1_size; i++) { + cpu_sum += bias_experts_0_layer1[i]; + // bias_experts_1[i] = 1.0f; + } + std::cout << "[CPU] Bias expert 0 (layer 1) sum = " << cpu_sum + << std::endl; + } + + for (int i = 0; i < num_experts; i++) { + checkCUDA(cudaMemcpy((float *)&bias_ptr[nparams_bias * i], + bias_experts_0_layer0, + layer0_size * sizeof(float), + cudaMemcpyHostToDevice)); + if (m->experts_num_layers == 2) { + checkCUDA( + cudaMemcpy((float *)&bias_ptr[nparams_bias * i + layer0_size], + bias_experts_0_layer1, + layer1_size * sizeof(float), + cudaMemcpyHostToDevice)); + } + } + free(bias_experts_0_layer0); + free(bias_experts_0_layer1); + } + } +#endif + Experts::forward_kernel_wrapper(m, + input_ptr, + indices_ptr, + topk_gate_pred_ptr, + output_ptr, + weights_ptr, + bias_ptr, + bc->num_active_tokens(), + chosen_experts, + batch_size, + out_dim); +#ifdef INFERENCE_TESTS + if (DEBUG_MODE) { + /* ----------------Output after computation--------------*/ + float *cpu_output_ptr = new float[batch_size * out_dim]; + float cpu_sum = 0; + checkCUDA(cudaMemcpy(cpu_output_ptr, + output_ptr, + batch_size * out_dim * sizeof(float), + cudaMemcpyDeviceToHost)); + for (int j = 0; j < batch_size * out_dim; j += out_dim) { + cpu_sum = 0; + for (int i = 0; i < out_dim; i++) { + cpu_sum += cpu_output_ptr[j + i]; + } + // if ((j/out_dim) < 50) std::cout << "[CPU] output " << (j/out_dim) << " + // sum = " << cpu_sum << std::endl; + if (cpu_sum > 0.0f) { + std::cout << "[CPU] output " << (j / out_dim) << " sum = " << cpu_sum + << std::endl; + } + } + std::cout << "[CPU] output 0's 10th element = " << cpu_output_ptr[10] + << std::endl; + std::cout << "[CPU] output 0's 99th element = " << cpu_output_ptr[99] + << std::endl; + std::cout << "[CPU] output 0's 123th element = " << cpu_output_ptr[123] + << std::endl; + + /* refrence output */ + /* + * Input token sum = 391.5 + * Expert 0 weights sum = 307327.5 + * Expert 1 weights sum = 307328.47 + * ------------------ + * experts 0's reulst = 153533.1 + * experts 1's reulst = 153402.9 + * Aggreated Result = 92106.836 + * 10th element = 41.28053 + * 99th element = 59.057823 + * 123th element = 63.8517 + */ + + free(cpu_output_ptr); + } +#endif + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Experts::save_inference_tensors_to_file( + m, shard_id, bc, {input, indices, topk_gate_preds}, {}, {output}); + } +} + +void Experts::forward_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(false && "Experts is designed for inference only"); +} + +void Experts::backward(FFModel const &ff) { + assert(false && "Experts is designed for inference only"); +} + +void Experts::backward_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(false && "Experts is designed for inference only"); +} + +void Experts::print_layer(FFModel const &ff) { + return; +} + +bool Experts::measure_operator_cost(Simulator *sim, + MachineView const &c, + CostMetrics &cost_metrics) const { + // This is an inference only operator + assert(false && "Experts is designed for inference only"); + return false; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::ExpertsParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.num_experts); + hash_combine(key, params.experts_start_idx); + hash_combine(key, params.experts_output_dim_size); + hash_combine(key, params.alpha); + hash_combine(key, params.experts_num_layers); + hash_combine(key, params.experts_internal_dim_size); + hash_combine(key, params.use_bias); + hash_combine(key, params.activation); + return key; +} +}; // namespace std diff --git a/src/ops/experts.cpp b/src/ops/experts.cpp new file mode 100644 index 0000000000..c06f02a647 --- /dev/null +++ b/src/ops/experts.cpp @@ -0,0 +1,59 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/experts.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { + +/*static*/ +void Experts::forward_kernel_wrapper(ExpertsMeta const *m, + float const *input, + int const *indices, + float const *topk_gate_preds, + float *output, + float const *weights, + float const *biases, + int num_active_tokens, + int chosen_experts, + int batch_size, + int out_dim) { + // TODO: write the HIP version of the kernel after finishing the CUDA kernel + handle_unimplemented_hip_kernel(OP_EXPERTS); +} + +ExpertsMeta::ExpertsMeta(FFHandler handler, + int _num_experts, + int _experts_start_idx, + int _data_dim, + int _out_dim, + int _experts_num_layers, + int _experts_internal_dim_size, + int _effective_batch_size, + int _num_chosen_experts, + float _alpha, + bool _use_bias, + ActiMode _activation) + : OpMeta(handler), num_experts(_num_experts), + experts_start_idx(_experts_start_idx), data_dim(_data_dim), + out_dim(_out_dim), experts_num_layers(_experts_num_layers), + experts_internal_dim_size(_experts_internal_dim_size), + effective_batch_size(_effective_batch_size), + num_chosen_experts(_num_chosen_experts), alpha(_alpha), + use_bias(_use_bias), activation(_activation) {} +ExpertsMeta::~ExpertsMeta(void) {} + +}; // namespace FlexFlow diff --git a/src/ops/experts.cu b/src/ops/experts.cu new file mode 100644 index 0000000000..ce15cdff55 --- /dev/null +++ b/src/ops/experts.cu @@ -0,0 +1,1447 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/experts.h" +#include "flexflow/utils/cuda_helper.h" +#include +#include + +// Thrust-related headers +#define THRUST_IGNORE_DEPRECATED_CPP_DIALECT 1 +#include +#include +#include +#include +#include +#include +#include +#include +#include +#include + +#include +#include + +namespace FlexFlow { + +struct exceeds_expert_capacity { + int _expert_capacity; + exceeds_expert_capacity(int expert_capacity) + : _expert_capacity(expert_capacity){}; + __host__ __device__ bool operator()(int x) { + return x > _expert_capacity; + } +}; + +void experts_forward_thrust_wrapper(ExpertsMeta const *m, + int const *indices, + int num_indices, + int experts_start_idx, + int num_experts_per_block, + int expert_capacity, + int *lb_index, + int *ub_index, + int *num_valid_assignments, + int *non_zero_experts_count, + int *start_indexes, + int *gemm_batch_count, + ffStream_t stream) { + // sort the indices and coefficients by expert. Keep track of the original + // position of each index/coefficient using the original_indices array + thrust::device_ptr thrust_indices = + thrust::device_pointer_cast(indices); + thrust::device_ptr sorted_indices = + thrust::device_pointer_cast(m->sorted_indices); + thrust::copy(thrust::cuda::par.on(stream), + thrust_indices, + thrust_indices + num_indices, + sorted_indices); + + thrust::device_ptr original_indices = + thrust::device_pointer_cast(m->original_indices); + thrust::sequence(thrust::cuda::par.on(stream), + original_indices, + original_indices + num_indices); + + thrust::stable_sort_by_key(thrust::cuda::par.on(stream), + sorted_indices, + sorted_indices + num_indices, + original_indices); + + // get lower and upper bound of token->expert assignments corresponding to + // experts in the block + thrust::device_ptr lb = thrust::lower_bound(thrust::cuda::par.on(stream), + sorted_indices, + sorted_indices + num_indices, + experts_start_idx); + thrust::device_ptr ub = + thrust::upper_bound(thrust::cuda::par.on(stream), + sorted_indices, + sorted_indices + num_indices, + experts_start_idx + num_experts_per_block - 1); + // lowest index in the sorted indices array corresponding to an expert within + // the block + *lb_index = lb - sorted_indices; + // 1 + largest index in the sorted indices array corresponding to an expert + // within the block + *ub_index = ub - sorted_indices; + *num_valid_assignments = (*ub_index) - (*lb_index); + if ((*num_valid_assignments) == 0) { + return; + } + + thrust::device_ptr non_zero_expert_labels = + thrust::device_pointer_cast(m->non_zero_expert_labels); + // non_zero_expert_labels: a list of global labels of the experts in this + // block receiving nonzero tokens + thrust::device_ptr non_zero_expert_labels_end = thrust::unique_copy( + thrust::cuda::par.on(stream), lb, ub, non_zero_expert_labels); + // number of experts in this block receiving at least one token + *non_zero_experts_count = non_zero_expert_labels_end - non_zero_expert_labels; + + using namespace thrust::placeholders; + // convert global labels to local labelling (e.g. expert 65->index 65-64=1 in + // block containing experts 64-96) by substracting the experts_start_idx, + // inplace. + thrust::for_each(thrust::cuda::par.on(stream), + non_zero_expert_labels, + non_zero_expert_labels + (*non_zero_experts_count), + _1 -= experts_start_idx); + + thrust::device_ptr temp_sequence = + thrust::device_pointer_cast(m->temp_sequence); + thrust::sequence(thrust::cuda::par.on(stream), + temp_sequence, + temp_sequence + (*non_zero_experts_count)); + + // create "exp_local_label_to_index", a mapping from local expert label to its + // non-zero expert index (i.e. expert with index i is the i-th expert in the + // block to receive at least 1 token) + thrust::device_ptr exp_local_label_to_index = + thrust::device_pointer_cast(m->exp_local_label_to_index); + thrust::scatter(thrust::cuda::par.on(stream), + temp_sequence, + temp_sequence + (*non_zero_experts_count), + non_zero_expert_labels, + exp_local_label_to_index); + + // get local start index (within lower/upper bound) for each expert receiving + // non-zero tokens + thrust::device_ptr expert_start_indexes = + thrust::device_pointer_cast(m->expert_start_indexes); + thrust::sequence(thrust::cuda::par.on(stream), + expert_start_indexes, + expert_start_indexes + (*num_valid_assignments)); + *start_indexes = (thrust::unique_by_key_copy(thrust::cuda::par.on(stream), + lb, + ub, + expert_start_indexes, + temp_sequence, + expert_start_indexes)) + .first - + temp_sequence; + assert((*start_indexes) == (*non_zero_experts_count)); + + // append ub_index + expert_start_indexes[(*start_indexes)] = (*ub_index) - (*lb_index); + + // get number of token assignment to each expert + thrust::device_ptr num_assignments_per_expert = + thrust::device_pointer_cast(m->num_assignments_per_expert); + thrust::transform(thrust::cuda::par.on(stream), + expert_start_indexes + 1, + expert_start_indexes + (*non_zero_experts_count) + 1, + expert_start_indexes, + num_assignments_per_expert, + thrust::minus()); + + // build destination_start_index array, telling us the first slot that belongs + // to each expert in the destination array (after factoring in expert + // capacity) + thrust::device_ptr destination_start_indices = + thrust::device_pointer_cast(m->destination_start_indices); + thrust::replace_copy_if(thrust::cuda::par.on(stream), + num_assignments_per_expert, + num_assignments_per_expert + + (*non_zero_experts_count), + destination_start_indices, + exceeds_expert_capacity(expert_capacity), + expert_capacity); + + *gemm_batch_count = + thrust::reduce(thrust::cuda::par.on(stream), + destination_start_indices, + destination_start_indices + (*non_zero_experts_count)); + + thrust::exclusive_scan(thrust::cuda::par.on(stream), + destination_start_indices, + destination_start_indices + (*non_zero_experts_count), + destination_start_indices, + 0); +} + +__global__ void experts_forward_prepare_kernel( + int num_valid_assignments, + int expert_capacity, + int lb_index, + int experts_start_idx, + int num_experts_per_block, + int num_chosen_experts, + int data_dim, + int out_dim, + int experts_num_layers, + int experts_internal_dim_size, + bool use_bias, + int *sorted_indices, + int *expert_start_indexes, + int *exp_local_label_to_index, + int *destination_start_indices, + int *original_indices, + float const *input, // @In: Tokens' values (in_dim, batch_size) + float *output, + float const **token_idx_array, // @Out: Barray for GemmBatchedEx + float const *weights, // @In: Experts' weights + float const *biases, // @In: Experts' biases + float const **weight_idx_array1, // @Out: Aarray for GemmBatchedEx + float const **weight_idx_array2, + float const **bias_idx_array1, // @Out: Experts' bias + float const **bias_idx_array2, + float const *coefficients, // @In: topk_gate_predss coefficients tensor + // (num_chosen_experts, batch_size) + float const **coefficient_idx_array, // @Out: Barray for Aggregation + float **output_idx_array) { + + CUDA_KERNEL_LOOP(i, num_valid_assignments) { + int global_expert_label = sorted_indices[lb_index + i]; + assert(global_expert_label >= experts_start_idx && + global_expert_label < experts_start_idx + num_experts_per_block); + int local_expert_label = global_expert_label - experts_start_idx; + int expert_index = exp_local_label_to_index[local_expert_label]; + int within_expert_offset = i - expert_start_indexes[expert_index]; + int weight_params_count = + experts_num_layers == 1 + ? data_dim * out_dim + : experts_internal_dim_size * (data_dim + out_dim); + if (within_expert_offset < expert_capacity) { + int rev_idx = original_indices[i + lb_index]; + int token_idx = (rev_idx / num_chosen_experts); + + token_idx_array[destination_start_indices[expert_index] + + within_expert_offset] = &input[token_idx * data_dim]; + weight_idx_array1[destination_start_indices[expert_index] + + within_expert_offset] = + &weights[local_expert_label * weight_params_count]; + if (experts_num_layers == 2) { + weight_idx_array2[destination_start_indices[expert_index] + + within_expert_offset] = + &weights[local_expert_label * weight_params_count + + (data_dim * experts_internal_dim_size)]; + } + if (use_bias) { + int bias_params_count = (experts_num_layers == 1) + ? out_dim + : (experts_internal_dim_size + out_dim); + bias_idx_array1[destination_start_indices[expert_index] + + within_expert_offset] = + &biases[local_expert_label * bias_params_count]; + if (experts_num_layers == 2) { + bias_idx_array2[destination_start_indices[expert_index] + + within_expert_offset] = + &biases[local_expert_label * bias_params_count + + experts_internal_dim_size]; + } + } + coefficient_idx_array[destination_start_indices[expert_index] + + within_expert_offset] = &coefficients[rev_idx]; + output_idx_array[destination_start_indices[expert_index] + + within_expert_offset] = &output[token_idx * out_dim]; + } + } +} + +bool use_activation(ActiMode mode) { + switch (mode) { + case AC_MODE_RELU: + case AC_MODE_SIGMOID: + case AC_MODE_TANH: + return true; + case AC_MODE_NONE: + return false; + default: + assert(0); + break; + } + return false; +} + +void experts_forward_GemmBatched_kernel(ExpertsMeta const *m, + void const **weights_ptr1, + void const **weights_ptr2, + void const **input_ptr, + void **results_ptr1, + void **results_ptr2, + void const **bias_ptr1, + void const **bias_ptr2, + ActiMode activation, + int in_dim, + int out_dim, + int experts_num_layers, + int experts_internal_dim_size, + int num_tokens, + int num_chosen_experts, + int gemm_batch_count, + ffStream_t stream) { + + checkCUDA(cublasSetStream(m->handle.blas, stream)); + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + + float alpha = 1.0f, beta = 0.0f; + + // cudaDataType_t input_type = ff_to_cuda_datatype(m->input_type); + // cudaDataType_t weight_type = ff_to_cuda_datatype(m->weight_type); + // cudaDataType_t output_type = ff_to_cuda_datatype(m->output_type); + cudaDataType_t input_type = CUDA_R_32F; + cudaDataType_t weight_type = CUDA_R_32F; + cudaDataType_t output_type = CUDA_R_32F; + + cublasComputeType_t compute_type = CUBLAS_COMPUTE_32F; + + int m_ = out_dim; + int n = 1; + int k = in_dim; + void const **A = weights_ptr1; + void const **B = input_ptr; + void **C = results_ptr1; + int lda = in_dim; + int ldb = in_dim; + int ldc = out_dim; + if (experts_num_layers == 2) { + m_ = ldc = experts_internal_dim_size; + } + checkCUDA(cublasGemmBatchedEx( + m->handle.blas, + CUBLAS_OP_T, // Tranpose Weight, shape (in_dim, out_dim) => (out_dim, + // in_dim) + CUBLAS_OP_N, // Input_token, shape (in_dim, 1) + m_, // num_row of (A, C) = out_dim + n, // num_col of (B, C) = 1 + k, // num_col of A and num_rows of B = in_dim + &alpha, + A, // Aarray (num_tokens * chosen_experts, in_dim, out_dim) + weight_type, + lda, // Leading Dimension of weight before transpose + B, // Barray (num_tokens * chosen_experts, in_dim, 1) + input_type, + ldb, // Leading Dimension of input_token + &beta, + C, // Carray (num_tokens * chosen_experts, out_dim, 1) + output_type, + ldc, // Leading Dimension of output + gemm_batch_count, // Total submatrixes + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + + if (m->use_bias) { + m_ = out_dim; + n = 1; + k = 1; + A = bias_ptr1; + B = (void const **)m->one_ptr_array; + C = results_ptr1; + lda = out_dim; + ldb = 1; + ldc = out_dim; + if (experts_num_layers == 2) { + m_ = lda = ldc = experts_internal_dim_size; + } + alpha = 1.0f, beta = 0.0f; + checkCUDA(cublasGemmBatchedEx( + m->handle.blas, + CUBLAS_OP_N, // Bias, shape (out_dim, 1) + CUBLAS_OP_N, // Coefficient, shape (1, 1) + m_, // num_row of (A, C) = out_dim + n, // num_col of (B, C) = 1 + k, // num_col of A and num_rows of B = 1 + &alpha, + A, // bias tensor (out_dim, 1) + weight_type, + lda, // Leading Dimension of bias tensor + B, // all-one tensor (1, 1) + CUDA_R_32F, + ldb, // Leading Dimension of all-one tensor + &alpha, + C, // Carray (num_tokens * chosen_experts, out_dim, 1) + output_type, + ldc, // Leading Dimension of output + gemm_batch_count, // Total submatrixs + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + + if (use_activation(activation)) { + alpha = 1.0f, beta = 0.0f; + checkCUDNN(cudnnActivationForward(m->handle.dnn, + m->actiDesc, + &alpha, + m->resultTensorDesc1, + m->batch_outputs1[0], + &beta, + m->resultTensorDesc1, + m->batch_outputs1[0])); + } + + if (experts_num_layers == 2) { + m_ = out_dim; + n = 1; + k = experts_internal_dim_size; + A = weights_ptr2; + B = (void const **)results_ptr1; + C = results_ptr2; + lda = experts_internal_dim_size; + ldb = experts_internal_dim_size; + ldc = out_dim; + alpha = 1.0f, beta = 0.0f; + checkCUDA(cublasGemmBatchedEx( + m->handle.blas, + CUBLAS_OP_T, // Tranpose Weight, shape (in_dim, out_dim) => (out_dim, + // in_dim) + CUBLAS_OP_N, // Input_token, shape (in_dim, 1) + m_, // num_row of (A, C) = out_dim + n, // num_col of (B, C) = 1 + k, // num_col of A and num_rows of B = in_dim + &alpha, + A, // Aarray (num_tokens * chosen_experts, in_dim, out_dim) + weight_type, + lda, // Leading Dimension of weight before transpose + B, // Barray (num_tokens * chosen_experts, in_dim, 1) + input_type, + ldb, // Leading Dimension of input_token + &beta, + C, // Carray (num_tokens * chosen_experts, out_dim, 1) + output_type, + ldc, // Leading Dimension of output + gemm_batch_count, // Total submatrixes + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + + if (m->use_bias) { + m_ = out_dim; + n = 1; + k = 1; + A = bias_ptr2; + B = (void const **)m->one_ptr_array; + C = results_ptr2; + lda = out_dim; + ldb = 1; + ldc = out_dim; + alpha = 1.0f, beta = 0.0f; + checkCUDA(cublasGemmBatchedEx( + m->handle.blas, + CUBLAS_OP_N, // Bias, shape (out_dim, 1) + CUBLAS_OP_N, // Coefficient, shape (1, 1) + m_, // num_row of (A, C) = out_dim + n, // num_col of (B, C) = 1 + k, // num_col of A and num_rows of B = 1 + &alpha, + A, // bias tensor (out_dim, 1) + weight_type, + lda, // Leading Dimension of bias tensor + B, // all-one tensor (1, 1) + CUDA_R_32F, + ldb, // Leading Dimension of all-one tensor + &alpha, + C, // Carray (num_tokens * chosen_experts, out_dim, 1) + output_type, + ldc, // Leading Dimension of output + gemm_batch_count, // Total submatrixs + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + + if (use_activation(activation)) { + alpha = 1.0f, beta = 0.0f; + checkCUDNN(cudnnActivationForward(m->handle.dnn, + m->actiDesc, + &alpha, + m->resultTensorDesc2, + m->batch_outputs2[0], + &beta, + m->resultTensorDesc2, + m->batch_outputs2[0])); + } + } +} + +__global__ void experts_forward_aggregate_kernel(int num_tokens, + int gemm_batch_count, + int out_dim, + float *output, + float **results_ptr, + float const **coefficient_ptr, + float **output_ptr) { + + CUDA_KERNEL_LOOP(i, num_tokens * out_dim) { + output[i] = 0.0f; + } + + __syncthreads(); + + CUDA_KERNEL_LOOP(i, gemm_batch_count * out_dim) { + int token_index = i / out_dim; + int emb_index = i % out_dim; + float res = + results_ptr[token_index][emb_index] * (*coefficient_ptr[token_index]); + atomicAdd(output_ptr[token_index] + emb_index, res); + } +} + +/*static*/ +void Experts::forward_kernel_wrapper(ExpertsMeta const *m, + float const *input, + int const *indices, + float const *topk_gate_preds, + float *output, + float const *weights, + float const *biases, + int num_active_tokens, + int chosen_experts, + int batch_size, + int out_dim) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + assert(num_active_tokens > 0); + assert(num_active_tokens <= m->effective_batch_size); + assert(m->effective_batch_size == batch_size); + + int num_experts_per_block = m->num_experts; + int experts_start_idx = m->experts_start_idx; + bool use_bias = m->use_bias; + ActiMode activation = m->activation; + int data_dim = m->data_dim; + int num_chosen_experts = m->num_chosen_experts; + // int num_tokens = m->effective_batch_size; + int num_tokens = num_active_tokens; + int expert_capacity = m->expert_capacity; + + assert(chosen_experts == num_chosen_experts); + // assert(num_tokens == batch_size); + assert(out_dim == m->out_dim); + + assert(weights != nullptr); + assert(use_bias == (biases != nullptr)); + + int num_indices = num_tokens * num_chosen_experts; + // values below are set by Thrust in the experts_forward_thrust_wrapper + // function + int lb_index = 0; + int ub_index = 0; + int num_valid_assignments = 0; + int non_zero_experts_count = 0; + int start_indexes = 0; + int gemm_batch_count = 0; + + experts_forward_thrust_wrapper(m, + indices, + num_indices, + experts_start_idx, + num_experts_per_block, + expert_capacity, + &lb_index, + &ub_index, + &num_valid_assignments, + &non_zero_experts_count, + &start_indexes, + &gemm_batch_count, + stream); + + // checkCUDA(cudaStreamSynchronize(stream)); + +#ifdef INFERENCE_TESTS + // Checking + // 1. check that m->sorted_indices contains indices sorted + int *indices_cpu = download_tensor(indices, num_indices); + // assert(indices_cpu != nullptr); + std::vector indices_vec(indices_cpu, indices_cpu + num_indices); + std::vector indices_vec_sorted(indices_vec.size()); + std::copy(indices_vec.begin(), indices_vec.end(), indices_vec_sorted.begin()); + std::stable_sort(indices_vec_sorted.begin(), indices_vec_sorted.end()); + + int *thrust_sorted_indices_cpu = download_tensor( + m->sorted_indices, m->num_chosen_experts * m->effective_batch_size); + // assert(thrust_sorted_indices_cpu != nullptr); + std::vector thrust_sorted_indices_vec( + thrust_sorted_indices_cpu, thrust_sorted_indices_cpu + num_indices); + for (int i = 0; i < num_indices; i++) { + if (indices_vec_sorted[i] != thrust_sorted_indices_vec[i]) { + printf("i=%i\n", i); + printf("indices: "); + std::copy(indices_vec.begin(), + indices_vec.end(), + std::ostream_iterator(std::cout, " ")); + std::cout << std::endl; + printf("indices_vec_sorted: "); + std::copy(indices_vec_sorted.begin(), + indices_vec_sorted.end(), + std::ostream_iterator(std::cout, " ")); + std::cout << std::endl; + printf("thrust_sorted_indices_vec: "); + std::copy(thrust_sorted_indices_vec.begin(), + thrust_sorted_indices_vec.end(), + std::ostream_iterator(std::cout, " ")); + std::cout << std::endl; + } + assert(indices_vec_sorted[i] == thrust_sorted_indices_vec[i]); + } + // 2. check that indices[m->original_indices[i]] = i + int *thrust_original_indices_cpu = download_tensor( + m->original_indices, m->num_chosen_experts * m->effective_batch_size); + // assert(thrust_original_indices_cpu != nullptr); + std::vector thrust_original_indices_vec( + thrust_original_indices_cpu, thrust_original_indices_cpu + num_indices); + for (int i = 0; i < num_indices; i++) { + assert(indices_vec[thrust_original_indices_vec[i]] == + thrust_sorted_indices_vec[i]); + } + + // 3. check that lb_index is the index of the first element greater or equal + // to expert_start_idx + // 4. check that ub_index is greater than last, or outside array + std::vector::iterator low, up; + low = std::lower_bound( + indices_vec_sorted.begin(), indices_vec_sorted.end(), experts_start_idx); + up = std::upper_bound(indices_vec_sorted.begin(), + indices_vec_sorted.end(), + experts_start_idx + num_experts_per_block - 1); + int lb_index_check = low - indices_vec_sorted.begin(), + ub_index_check = up - indices_vec_sorted.begin(); + + if (lb_index_check != lb_index || ub_index_check != ub_index) { + printf("experts_start_idx: %i, num_experts_per_block: %i, lb_index: %i, " + "lb_index_check: %i, ub_index: %i, ub_index_check: %i\n", + experts_start_idx, + num_experts_per_block, + lb_index, + lb_index_check, + ub_index, + ub_index_check); + printf("indices_vec_sorted: "); + std::copy(indices_vec_sorted.begin(), + indices_vec_sorted.end(), + std::ostream_iterator(std::cout, " ")); + std::cout << std::endl; + } + assert(lb_index_check == lb_index); + assert(ub_index_check == ub_index); + + // 5. compute num_valid_assignments manually, and check that is equal to value + // computed in thrust + int num_valid_assignments_manual = ub_index_check - lb_index_check; + assert(num_valid_assignments_manual == num_valid_assignments); + + // 6. check m->non_zero_expert_labels, *non_zero_experts_count + std::set non_zero_experts_check; + for (int i = 0; i < num_indices; i++) { + if (indices_vec_sorted[i] >= experts_start_idx && + indices_vec_sorted[i] < experts_start_idx + num_experts_per_block) { + non_zero_experts_check.insert(indices_vec_sorted[i]); + } + } + assert(non_zero_experts_count == non_zero_experts_check.size()); + // 7. check exp_local_label_to_index + int *non_zero_expert_labels_cpu = + download_tensor(m->non_zero_expert_labels, non_zero_experts_count); + // assert(non_zero_expert_labels_cpu != nullptr); + std::vector non_zero_expert_labels_vec(non_zero_expert_labels_cpu, + non_zero_expert_labels_cpu + + non_zero_experts_count); + assert(std::is_sorted(non_zero_expert_labels_vec.begin(), + non_zero_expert_labels_vec.end())); + std::vector non_zero_experts_check_vec; + for (auto el : non_zero_experts_check) { + non_zero_experts_check_vec.push_back(el - experts_start_idx); + } + assert(std::is_sorted(non_zero_experts_check_vec.begin(), + non_zero_experts_check_vec.end())); + assert(non_zero_expert_labels_vec == non_zero_experts_check_vec); + + int *exp_local_label_to_index = + download_tensor(m->exp_local_label_to_index, non_zero_experts_count); + // assert(exp_local_label_to_index != nullptr); + std::vector exp_local_label_to_index_vec(exp_local_label_to_index, + exp_local_label_to_index + + non_zero_experts_count); + int z = 0; + for (int i = 0; i < non_zero_experts_count; i++) { + if (non_zero_experts_check.find(i) != non_zero_experts_check.end()) { + assert(exp_local_label_to_index_vec[i] == z); + z++; + } + } + + // 8. Check expert_start_indexes + int *expert_start_indices_thrust = + download_tensor(m->expert_start_indexes, non_zero_experts_count + 1); + // assert(expert_start_indices_thrust != nullptr); + std::vector expert_start_indices_thrust_vec( + expert_start_indices_thrust, + expert_start_indices_thrust + non_zero_experts_count + 1); + std::vector expert_start_indices_cpu; + std::set exp_label; + + std::vector num_assignments_per_expert_cpu; + + for (int i = lb_index; i < ub_index; i++) { + assert(indices_vec_sorted[i] >= experts_start_idx && + indices_vec_sorted[i] < experts_start_idx + num_experts_per_block); + if (exp_label.find(indices_vec_sorted[i]) == exp_label.end()) { + exp_label.insert(indices_vec_sorted[i]); + expert_start_indices_cpu.push_back(i - lb_index); + + num_assignments_per_expert_cpu.push_back(1); + } else { + num_assignments_per_expert_cpu[num_assignments_per_expert_cpu.size() - + 1] += 1; + } + } + expert_start_indices_cpu.push_back(ub_index - lb_index); + assert(num_assignments_per_expert_cpu.size() == non_zero_experts_count); + /* std::cout << "indices_vec_sorted: "; + for (int i=lb_index; i(m->num_assignments_per_expert, + num_assignments_per_expert_thrust, + non_zero_experts_count)); + assert(num_assignments_per_expert_thrust != nullptr); + std::vector num_assignments_per_expert_thrust_vec( + num_assignments_per_expert_thrust, + num_assignments_per_expert_thrust + non_zero_experts_count); + assert(num_assignments_per_expert_cpu == + num_assignments_per_expert_thrust_vec); + + int *destination_start_indices_thrust = + (int *)calloc(non_zero_experts_count, sizeof(int)); + assert(destination_start_indices_thrust != nullptr); + assert(download_tensor(m->destination_start_indices, + destination_start_indices_thrust, + non_zero_experts_count)); + assert(destination_start_indices_thrust != nullptr); + std::vector destination_start_indices_thrust_vec( + destination_start_indices_thrust, + destination_start_indices_thrust + non_zero_experts_count); + std::vector destination_start_indices_cpu; + int gemm_batch_count_cpu = 0; + for (int i = 0; i < num_assignments_per_expert_cpu.size(); i++) { + if (i == 0) { + destination_start_indices_cpu.push_back(0); + } else { + destination_start_indices_cpu.push_back( + std::min(expert_capacity, num_assignments_per_expert_cpu[i - 1])); + } + } + for (int i = 0; i < num_assignments_per_expert_cpu.size(); i++) { + gemm_batch_count_cpu += + std::min(expert_capacity, num_assignments_per_expert_cpu[i]); + } + for (int i = 1; i < destination_start_indices_cpu.size(); i++) { + destination_start_indices_cpu[i] += destination_start_indices_cpu[i - 1]; + } + /* + std::cout << "destination_start_indices_cpu: "; + for (int i=0; i= non_zero_experts_count); + assert(non_zero_experts_count <= num_experts_per_block); + if (non_zero_experts_count == 0) { + assert(num_valid_assignments == 0 && gemm_batch_count == 0); + } else { + assert(num_valid_assignments > 0 && gemm_batch_count > 0); + } + assert(num_valid_assignments <= num_indices); + assert(gemm_batch_count <= num_valid_assignments); + + if (num_valid_assignments == 0) { + if (m->profiling) { + cudaEventRecord(t_end, stream); + cudaEventSynchronize(t_end); + float milliseconds = 0; + cudaEventElapsedTime(&milliseconds, t_start, t_end); + printf("forward_kernel_wrapper: %f ms\n", milliseconds); + } + return; + } + + experts_forward_prepare_kernel<<>>(num_valid_assignments, + expert_capacity, + lb_index, + experts_start_idx, + num_experts_per_block, + num_chosen_experts, + data_dim, + out_dim, + m->experts_num_layers, + m->experts_internal_dim_size, + use_bias, + m->sorted_indices, + m->expert_start_indexes, + m->exp_local_label_to_index, + m->destination_start_indices, + m->original_indices, + input, + output, + m->token_idx_array, + weights, + biases, + m->weight_idx_array1, + m->weight_idx_array2, + m->bias_idx_array1, + m->bias_idx_array2, + topk_gate_preds, + m->coefficient_idx_array, + m->output_idx_array); + + // checkCUDA(cudaStreamSynchronize(stream)); + +#ifdef INFERENCE_TESTS + std::vector token_ptrs, weight_ptrs, bias_ptrs, + coefficient_ptrs; + std::vector output_ptrs; + std::map num_t_per_exp; + for (int i = 0; i < num_indices; i++) { + int global_exp_label = indices_vec[i]; + + if (global_exp_label >= experts_start_idx && + global_exp_label < experts_start_idx + num_experts_per_block && + (num_t_per_exp.find(global_exp_label) == num_t_per_exp.end() || + num_t_per_exp[global_exp_label] < expert_capacity)) { + if (num_t_per_exp.find(global_exp_label) == num_t_per_exp.end()) { + num_t_per_exp[global_exp_label] = 1; + } else { + num_t_per_exp[global_exp_label] = num_t_per_exp[global_exp_label] + 1; + } + int token_idx = i / num_chosen_experts; + // std::cout << "Push back token_idx (" << token_idx << ") * data_dim (" + // << data_dim << "): " << token_idx*data_dim << std::endl; + + token_ptrs.push_back(&input[token_idx * data_dim]); + coefficient_ptrs.push_back(&topk_gate_preds[i]); + int local_exp_label = global_exp_label - experts_start_idx; + weight_ptrs.push_back(&weights[local_exp_label * (out_dim * data_dim)]); + output_ptrs.push_back(&output[token_idx * out_dim]); + if (use_bias) { + bias_ptrs.push_back(&biases[local_exp_label * out_dim]); + } + } + } + + int i = 0, s = 0; + for (auto it : num_t_per_exp) { + int num_t = it.second; + s += num_t; + /* if (num_assignments_per_expert_cpu[i] != num_t) { + std::cout << "num_assignments_per_expert_cpu: "; + for (int j=0; j token_ptrs_sorted(token_ptrs.size()), + weight_ptrs_sorted(weight_ptrs.size()), + bias_ptrs_sorted(bias_ptrs.size()), + coefficient_ptrs_sorted(coefficient_ptrs.size()); + std::vector output_ptrs_sorted(output_ptrs.size()); + std::copy(token_ptrs.begin(), token_ptrs.end(), token_ptrs_sorted.begin()); + std::sort(token_ptrs_sorted.begin(), token_ptrs_sorted.end()); + std::copy(weight_ptrs.begin(), weight_ptrs.end(), weight_ptrs_sorted.begin()); + std::sort(weight_ptrs_sorted.begin(), weight_ptrs_sorted.end()); + std::copy(bias_ptrs.begin(), bias_ptrs.end(), bias_ptrs_sorted.begin()); + std::sort(bias_ptrs_sorted.begin(), bias_ptrs_sorted.end()); + std::copy(coefficient_ptrs.begin(), + coefficient_ptrs.end(), + coefficient_ptrs_sorted.begin()); + std::sort(coefficient_ptrs_sorted.begin(), coefficient_ptrs_sorted.end()); + std::copy(output_ptrs.begin(), output_ptrs.end(), output_ptrs_sorted.begin()); + std::sort(output_ptrs_sorted.begin(), output_ptrs_sorted.end()); + + // Download + float const **token_idx_array_thrust = + (float const **)calloc(gemm_batch_count, sizeof(float const *)); + assert(token_idx_array_thrust); + checkCUDA(cudaMemcpy(token_idx_array_thrust, + m->token_idx_array, + sizeof(float const *) * gemm_batch_count, + cudaMemcpyDeviceToHost)); + std::vector token_idx_array_thrust_vec( + token_idx_array_thrust, token_idx_array_thrust + gemm_batch_count); + float const **weight_idx_array_thrust = + (float const **)calloc(gemm_batch_count, sizeof(float const *)); + assert(weight_idx_array_thrust); + checkCUDA(cudaMemcpy(weight_idx_array_thrust, + m->weight_idx_array1, + sizeof(float const *) * gemm_batch_count, + cudaMemcpyDeviceToHost)); + std::vector weight_idx_array_thrust_vec( + weight_idx_array_thrust, weight_idx_array_thrust + gemm_batch_count); + float const **coefficient_idx_array_thrust = + (float const **)calloc(gemm_batch_count, sizeof(float const *)); + assert(coefficient_idx_array_thrust); + checkCUDA(cudaMemcpy(coefficient_idx_array_thrust, + m->coefficient_idx_array, + sizeof(float const *) * gemm_batch_count, + cudaMemcpyDeviceToHost)); + std::vector coefficient_idx_array_thrust_vec( + coefficient_idx_array_thrust, + coefficient_idx_array_thrust + gemm_batch_count); + float const **bias_idx_array_thrust = + (float const **)calloc(gemm_batch_count, sizeof(float const *)); + assert(bias_idx_array_thrust); + if (use_bias) { + checkCUDA(cudaMemcpy(bias_idx_array_thrust, + m->bias_idx_array1, + sizeof(float const *) * gemm_batch_count, + cudaMemcpyDeviceToHost)); + } + std::vector bias_idx_array_thrust_vec( + bias_idx_array_thrust, bias_idx_array_thrust + gemm_batch_count); + float **output_idx_array_thrust = + (float **)calloc(gemm_batch_count, sizeof(float *)); + assert(output_idx_array_thrust); + checkCUDA(cudaMemcpy(output_idx_array_thrust, + m->output_idx_array, + sizeof(float *) * gemm_batch_count, + cudaMemcpyDeviceToHost)); + std::vector output_idx_array_thrust_vec( + output_idx_array_thrust, output_idx_array_thrust + gemm_batch_count); + + std::vector token_idx_array_thrust_vec_sorted( + token_idx_array_thrust_vec.size()), + weight_idx_array_thrust_vec_sorted(weight_idx_array_thrust_vec.size()), + coefficient_idx_array_thrust_vec_sorted( + coefficient_idx_array_thrust_vec.size()), + bias_idx_array_thrust_vec_sorted(bias_idx_array_thrust_vec.size()); + std::vector output_idx_array_thrust_vec_sorted( + output_idx_array_thrust_vec.size()); + std::copy(token_idx_array_thrust_vec.begin(), + token_idx_array_thrust_vec.end(), + token_idx_array_thrust_vec_sorted.begin()); + std::sort(token_idx_array_thrust_vec_sorted.begin(), + token_idx_array_thrust_vec_sorted.end()); + std::copy(weight_idx_array_thrust_vec.begin(), + weight_idx_array_thrust_vec.end(), + weight_idx_array_thrust_vec_sorted.begin()); + std::sort(weight_idx_array_thrust_vec_sorted.begin(), + weight_idx_array_thrust_vec_sorted.end()); + std::copy(coefficient_idx_array_thrust_vec.begin(), + coefficient_idx_array_thrust_vec.end(), + coefficient_idx_array_thrust_vec_sorted.begin()); + std::sort(coefficient_idx_array_thrust_vec_sorted.begin(), + coefficient_idx_array_thrust_vec_sorted.end()); + std::copy(bias_idx_array_thrust_vec.begin(), + bias_idx_array_thrust_vec.end(), + bias_idx_array_thrust_vec_sorted.begin()); + std::sort(bias_idx_array_thrust_vec_sorted.begin(), + bias_idx_array_thrust_vec_sorted.end()); + std::copy(output_idx_array_thrust_vec.begin(), + output_idx_array_thrust_vec.end(), + output_idx_array_thrust_vec_sorted.begin()); + std::sort(output_idx_array_thrust_vec_sorted.begin(), + output_idx_array_thrust_vec_sorted.end()); + + if (token_ptrs_sorted != token_idx_array_thrust_vec_sorted) { + std::cout << "token_ptrs: "; + for (int i = 0; i < token_ptrs_sorted.size(); i++) { + std::cout << token_ptrs_sorted[i] << " "; + } + std::cout << std::endl; + std::cout << "token_idx_array_thrust_vec: "; + for (int i = 0; i < token_idx_array_thrust_vec_sorted.size(); i++) { + std::cout << token_idx_array_thrust_vec_sorted[i] << " "; + } + std::cout << std::endl; + std::cout << "Input: " << input << std::endl; + std::cout << "data_dim: " << data_dim << std::endl; + std::cout << "out_dim: " << out_dim << std::endl; + std::cout << "expert_start_idx: " << experts_start_idx << std::endl; + std::cout << "indices: "; + for (int i = 0; i < indices_vec.size(); i++) { + std::cout << indices_vec[i] << " "; + } + std::cout << std::endl; + std::cout << "indices_vec_sorted: "; + for (int i = 0; i < indices_vec_sorted.size(); i++) { + std::cout << indices_vec_sorted[i] << " "; + } + std::cout << std::endl; + } + assert(token_ptrs_sorted == token_idx_array_thrust_vec_sorted); + assert(weight_ptrs_sorted == weight_idx_array_thrust_vec_sorted); + if (coefficient_ptrs_sorted != coefficient_idx_array_thrust_vec_sorted) { + std::cout << "coefficient_ptrs_sorted: "; + for (int i = 0; i < coefficient_ptrs_sorted.size(); i++) { + std::cout << coefficient_ptrs_sorted[i] << " "; + } + std::cout << std::endl; + std::cout << "coefficient_idx_array_thrust_vec_sorted: "; + for (int i = 0; i < coefficient_idx_array_thrust_vec_sorted.size(); i++) { + std::cout << coefficient_idx_array_thrust_vec_sorted[i] << " "; + } + std::cout << std::endl; + std::cout << "topk_gate_preds: " << topk_gate_preds << std::endl; + std::cout << "data_dim: " << data_dim << std::endl; + std::cout << "out_dim: " << out_dim << std::endl; + std::cout << "expert_start_idx: " << experts_start_idx << std::endl; + std::cout << "indices: "; + for (int i = 0; i < indices_vec.size(); i++) { + std::cout << indices_vec[i] << " "; + } + std::cout << std::endl; + std::cout << "indices_vec_sorted: "; + for (int i = 0; i < indices_vec_sorted.size(); i++) { + std::cout << indices_vec_sorted[i] << " "; + } + std::cout << std::endl; + } + assert(coefficient_ptrs_sorted == coefficient_idx_array_thrust_vec_sorted); + if (use_bias) { + assert(bias_ptrs_sorted == bias_idx_array_thrust_vec_sorted); + } + assert(output_ptrs_sorted == output_idx_array_thrust_vec_sorted); + + assert(token_ptrs_sorted.size() == gemm_batch_count && + weight_ptrs_sorted.size() == gemm_batch_count && + coefficient_ptrs_sorted.size() == gemm_batch_count && + (!use_bias || bias_ptrs_sorted.size() == gemm_batch_count) && + output_ptrs_sorted.size() == gemm_batch_count); + + for (int i = 0; i < token_ptrs_sorted.size(); i++) { + assert(token_ptrs_sorted[i]); + assert(weight_ptrs_sorted[i]); + assert(coefficient_ptrs_sorted[i]); + if (use_bias) { + assert(bias_ptrs_sorted[i]); + } + assert(output_ptrs_sorted[i]); + } + + free(token_idx_array_thrust); + free(weight_idx_array_thrust); + free(coefficient_idx_array_thrust); + free(bias_idx_array_thrust); + free(output_idx_array_thrust); + + checkCUDA(cudaFreeHost(indices_cpu)); + indices_vec.clear(); + indices_vec.shrink_to_fit(); + indices_vec_sorted.clear(); + indices_vec_sorted.shrink_to_fit(); + num_assignments_per_expert_cpu.clear(); + num_assignments_per_expert_cpu.shrink_to_fit(); + + token_ptrs.clear(); + token_ptrs.shrink_to_fit(); + token_ptrs_sorted.clear(); + token_ptrs_sorted.shrink_to_fit(); + weight_ptrs.clear(); + weight_ptrs.shrink_to_fit(); + weight_ptrs_sorted.clear(); + weight_ptrs_sorted.shrink_to_fit(); + bias_ptrs.clear(); + bias_ptrs.shrink_to_fit(); + bias_ptrs_sorted.clear(); + bias_ptrs_sorted.shrink_to_fit(); + coefficient_ptrs.clear(); + coefficient_ptrs.shrink_to_fit(); + output_ptrs.clear(); + output_ptrs.shrink_to_fit(); + output_ptrs_sorted.clear(); + output_ptrs_sorted.shrink_to_fit(); + + token_idx_array_thrust_vec_sorted.clear(); + token_idx_array_thrust_vec_sorted.shrink_to_fit(); + weight_idx_array_thrust_vec_sorted.clear(); + weight_idx_array_thrust_vec_sorted.shrink_to_fit(); + coefficient_idx_array_thrust_vec_sorted.clear(); + coefficient_idx_array_thrust_vec_sorted.shrink_to_fit(); + bias_idx_array_thrust_vec_sorted.clear(); + bias_idx_array_thrust_vec_sorted.shrink_to_fit(); + output_idx_array_thrust_vec_sorted.clear(); + output_idx_array_thrust_vec_sorted.shrink_to_fit(); + + // Check batch output pointers + assert(gemm_batch_count <= m->effective_batch_size); + float **dev_batch_outputs_cuda = (float **)calloc( + num_chosen_experts * m->effective_batch_size, sizeof(float *)); + assert(dev_batch_outputs_cuda); + checkCUDA( + cudaMemcpy(dev_batch_outputs_cuda, + m->dev_batch_outputs1, + sizeof(float *) * num_chosen_experts * m->effective_batch_size, + cudaMemcpyDeviceToHost)); + std::vector dev_batch_outputs_cuda_vec( + dev_batch_outputs_cuda, + dev_batch_outputs_cuda + num_chosen_experts * m->effective_batch_size); + + std::vector batch_outputs_host_vec( + m->batch_outputs1, + m->batch_outputs1 + num_chosen_experts * m->effective_batch_size); + assert(batch_outputs_host_vec == dev_batch_outputs_cuda_vec); + + /* std::cout << "dev_batch_outputs_cuda_vec[i]: "; + for (int i=0; i0) { + assert(dev_batch_outputs_cuda_vec[i] == dev_batch_outputs_cuda_vec[i-1] + + out_dim); + } + std::cout << dev_batch_outputs_cuda_vec[i] << " "; + } + std::cout << std::endl; */ + + free(dev_batch_outputs_cuda); +#endif + + experts_forward_GemmBatched_kernel(m, + (void const **)m->weight_idx_array1, + (void const **)m->weight_idx_array2, + (void const **)m->token_idx_array, + (void **)m->dev_batch_outputs1, + (void **)m->dev_batch_outputs2, + (void const **)m->bias_idx_array1, + (void const **)m->bias_idx_array2, + activation, + data_dim, + out_dim, + m->experts_num_layers, + m->experts_internal_dim_size, + num_tokens, + num_chosen_experts, + gemm_batch_count, + stream); + + // checkCUDA(cudaStreamSynchronize(stream)); + + int aggregation_parallelism = + std::max(num_tokens, gemm_batch_count) * out_dim; + experts_forward_aggregate_kernel<<>>(num_tokens, + gemm_batch_count, + out_dim, + output, + m->experts_num_layers == 1 + ? m->dev_batch_outputs1 + : m->dev_batch_outputs2, + m->coefficient_idx_array, + m->output_idx_array); + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[Experts] forward time = %.2lfms\n", elapsed); + } +} + +ExpertsMeta::ExpertsMeta(FFHandler handler, + int _num_experts, + int _experts_start_idx, + int _data_dim, + int _out_dim, + int _experts_num_layers, + int _experts_internal_dim_size, + int _effective_batch_size, + int _num_chosen_experts, + float _alpha, + bool _use_bias, + ActiMode _activation) + : OpMeta(handler), num_experts(_num_experts), + experts_start_idx(_experts_start_idx), data_dim(_data_dim), + out_dim(_out_dim), experts_num_layers(_experts_num_layers), + experts_internal_dim_size(_experts_internal_dim_size), + effective_batch_size(_effective_batch_size), + num_chosen_experts(_num_chosen_experts), alpha(_alpha), + use_bias(_use_bias), activation(_activation) { + expert_capacity = + ceil(alpha * num_chosen_experts / num_experts * effective_batch_size); + + checkCUDA( + cudaMalloc(&sorted_indices, + num_chosen_experts * effective_batch_size * sizeof(int))); + checkCUDA( + cudaMalloc(&original_indices, + num_chosen_experts * effective_batch_size * sizeof(int))); + checkCUDA(cudaMalloc(&non_zero_expert_labels, num_experts * sizeof(int))); + checkCUDA(cudaMalloc( + &temp_sequence, + std::max(num_experts, num_chosen_experts * effective_batch_size) * + sizeof(int))); + checkCUDA(cudaMalloc(&exp_local_label_to_index, num_experts * sizeof(int))); + // expert_start_indexes needs one more slot to save the upper bound index. + // Initial sequence can require more space, though. + checkCUDA(cudaMalloc( + &expert_start_indexes, + std::max(num_experts + 1, num_chosen_experts * effective_batch_size) * + sizeof(int))); + checkCUDA(cudaMalloc(&num_assignments_per_expert, num_experts * sizeof(int))); + checkCUDA(cudaMalloc(&destination_start_indices, num_experts * sizeof(int))); + + checkCUDA( + cudaMalloc(&token_idx_array, + num_chosen_experts * effective_batch_size * sizeof(float *))); + checkCUDA( + cudaMalloc(&weight_idx_array1, + num_chosen_experts * effective_batch_size * sizeof(float *))); + checkCUDA( + cudaMalloc(&bias_idx_array1, + num_chosen_experts * effective_batch_size * sizeof(float *))); + checkCUDA( + cudaMalloc(&coefficient_idx_array, + num_chosen_experts * effective_batch_size * sizeof(float *))); + checkCUDA( + cudaMalloc(&output_idx_array, + num_chosen_experts * effective_batch_size * sizeof(float *))); + batch_outputs1 = new float *[num_chosen_experts * effective_batch_size]; + int batch_outputs1_dim = + (experts_num_layers == 1) ? out_dim : experts_internal_dim_size; + checkCUDA(cudaMalloc(&batch_outputs1[0], + batch_outputs1_dim * num_chosen_experts * + effective_batch_size * sizeof(float))); + checkCUDA(cudaMemset(batch_outputs1[0], + 0, + batch_outputs1_dim * num_chosen_experts * + effective_batch_size * sizeof(float))); + for (int i = 1; i < num_chosen_experts * effective_batch_size; i++) { + batch_outputs1[i] = batch_outputs1[i - 1] + batch_outputs1_dim; + } + checkCUDA( + cudaMalloc(&dev_batch_outputs1, + num_chosen_experts * effective_batch_size * sizeof(float *))); + checkCUDA( + cudaMemcpy(dev_batch_outputs1, + batch_outputs1, + num_chosen_experts * effective_batch_size * sizeof(float *), + cudaMemcpyHostToDevice)); + if (experts_num_layers == 2) { + checkCUDA(cudaMalloc(&weight_idx_array2, + num_chosen_experts * effective_batch_size * + sizeof(float *))); + checkCUDA(cudaMalloc(&bias_idx_array2, + num_chosen_experts * effective_batch_size * + sizeof(float *))); + batch_outputs2 = new float *[num_chosen_experts * effective_batch_size]; + checkCUDA(cudaMalloc(&batch_outputs2[0], + out_dim * num_chosen_experts * effective_batch_size * + sizeof(float))); + checkCUDA(cudaMemset(batch_outputs2[0], + 0, + out_dim * num_chosen_experts * effective_batch_size * + sizeof(float))); + for (int i = 1; i < num_chosen_experts * effective_batch_size; i++) { + batch_outputs2[i] = batch_outputs2[i - 1] + out_dim; + } + checkCUDA(cudaMalloc(&dev_batch_outputs2, + num_chosen_experts * effective_batch_size * + sizeof(float *))); + checkCUDA( + cudaMemcpy(dev_batch_outputs2, + batch_outputs2, + num_chosen_experts * effective_batch_size * sizeof(float *), + cudaMemcpyHostToDevice)); + } + // Bias + float *dram_one_ptr = (float *)malloc(sizeof(float) * 1); + for (int i = 0; i < 1; i++) { + dram_one_ptr[i] = 1.0f; + } + float *fb_one_ptr; + checkCUDA(cudaMalloc(&fb_one_ptr, sizeof(float) * 1)); + checkCUDA(cudaMemcpy( + fb_one_ptr, dram_one_ptr, sizeof(float) * 1, cudaMemcpyHostToDevice)); + one_ptr = (float const *)fb_one_ptr; + free((void *)dram_one_ptr); + checkCUDA( + cudaMalloc(&one_ptr_array, + num_chosen_experts * effective_batch_size * sizeof(float *))); + for (int i = 0; i < num_chosen_experts * effective_batch_size; i++) { + checkCUDA(cudaMemcpy(&one_ptr_array[i], + &fb_one_ptr, + sizeof(float *), + cudaMemcpyHostToDevice)); + } + // Activation + checkCUDNN(cudnnCreateActivationDescriptor(&actiDesc)); + checkCUDNN(cudnnCreateTensorDescriptor(&resultTensorDesc1)); + if (experts_num_layers == 2) { + checkCUDNN(cudnnCreateTensorDescriptor(&resultTensorDesc2)); + } + if (use_activation(activation)) { + cudnnActivationMode_t mode; + switch (activation) { + case AC_MODE_RELU: + mode = CUDNN_ACTIVATION_RELU; + break; + case AC_MODE_SIGMOID: + mode = CUDNN_ACTIVATION_SIGMOID; + break; + default: + // Unsupported activation mode + assert(false); + } + checkCUDNN( + cudnnSetActivationDescriptor(actiDesc, mode, CUDNN_PROPAGATE_NAN, 0.0)); + if (experts_num_layers == 1) { + checkCUDNN( + cudnnSetTensor4dDescriptor(resultTensorDesc1, + CUDNN_TENSOR_NCHW, + // CUDNN_DATA_FLOAT, + cuda_to_cudnn_datatype(CUDA_R_32F), + num_chosen_experts * effective_batch_size, + out_dim, + 1, + 1)); + } else { + checkCUDNN( + cudnnSetTensor4dDescriptor(resultTensorDesc1, + CUDNN_TENSOR_NCHW, + // CUDNN_DATA_FLOAT, + cuda_to_cudnn_datatype(CUDA_R_32F), + num_chosen_experts * effective_batch_size, + experts_internal_dim_size, + 1, + 1)); + checkCUDNN( + cudnnSetTensor4dDescriptor(resultTensorDesc2, + CUDNN_TENSOR_NCHW, + // CUDNN_DATA_FLOAT, + cuda_to_cudnn_datatype(CUDA_R_32F), + num_chosen_experts * effective_batch_size, + out_dim, + 1, + 1)); + } + } +} +ExpertsMeta::~ExpertsMeta(void) { + + checkCUDA(cudaFree(sorted_indices)); + checkCUDA(cudaFree(original_indices)); + checkCUDA(cudaFree(non_zero_expert_labels)); + checkCUDA(cudaFree(temp_sequence)); + checkCUDA(cudaFree(exp_local_label_to_index)); + checkCUDA(cudaFree(expert_start_indexes)); + checkCUDA(cudaFree(num_assignments_per_expert)); + checkCUDA(cudaFree(destination_start_indices)); + checkCUDA(cudaFree(token_idx_array)); + checkCUDA(cudaFree(weight_idx_array1)); + checkCUDA(cudaFree(weight_idx_array2)); + checkCUDA(cudaFree(coefficient_idx_array)); + checkCUDA(cudaFree(output_idx_array)); + checkCUDA(cudaFree(dev_batch_outputs1)); + checkCUDA(cudaFree(dev_batch_outputs2)); + checkCUDA(cudaFree(bias_idx_array1)); + checkCUDA(cudaFree(bias_idx_array2)); + checkCUDA(cudaFree(batch_outputs1[0])); + checkCUDA(cudaFree(batch_outputs2[0])); + delete[] batch_outputs1; + delete[] batch_outputs2; + // Bias + checkCUDA(cudaFree((void *)one_ptr)); + checkCUDA(cudaFree((void *)one_ptr_array)); + // Activation + checkCUDNN(cudnnDestroyActivationDescriptor(actiDesc)); + checkCUDNN(cudnnDestroyTensorDescriptor(resultTensorDesc1)); + checkCUDNN(cudnnDestroyTensorDescriptor(resultTensorDesc2)); +} + +}; // namespace FlexFlow diff --git a/src/ops/flat.cc b/src/ops/flat.cc index b5490ddc99..80aedbbb31 100644 --- a/src/ops/flat.cc +++ b/src/ops/flat.cc @@ -16,6 +16,7 @@ #include "flexflow/ops/flat.h" #include "flexflow/model.h" #include "flexflow/ops/kernels/flat_kernels.h" +#include "legion/legion_utilities.h" namespace FlexFlow { @@ -317,6 +318,8 @@ Domain Flat::get_input_tensor_shape(ParallelConfig const &pc, } void Flat::serialize(Legion::Serializer &sez) const { + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); return; } @@ -357,7 +360,7 @@ bool Flat::measure_operator_cost(Simulator *sim, assert(output_grad_ptr != NULL); assert(input_grad_ptr != NULL); - backward = [&] { + backward = [=] { backward_kernel_wrapper(input_grad_ptr, output_grad_ptr, num_elements); }; } @@ -391,6 +394,10 @@ Node Flat::deserialize(FFModel &ff, ParallelTensor inputs[], int num_inputs) { assert(num_inputs == 1); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); return ff.get_or_create_node(inputs[0], {}); } diff --git a/src/ops/fused.cc b/src/ops/fused.cc index b241ff1587..a1c911db75 100644 --- a/src/ops/fused.cc +++ b/src/ops/fused.cc @@ -100,6 +100,7 @@ FusedOp::FusedOp(FFModel &model, Op *op) op_num_outputs[0] = op->numOutputs; op_op_type[0] = op->op_type; operators[0] = op; + layer_guid = op->layer_guid; // for (int i = 0; i < numInputs; i++) { // op_input_source[i] = SOURCE_INPUT; // op_input_idx[i] = i; @@ -114,7 +115,42 @@ FusedOp::FusedOp(FFModel &model, Op *op) } } -bool FusedOp::add_operator(FFModel &model, Op *op) { +bool FusedOp::use_same_regions( + ParallelTensor const source_tensor, + ParallelTensor const target_tensor, + std::unordered_map> + *pt_mapping) { + if (pt_mapping == nullptr) { + return (source_tensor->region == target_tensor->region); + } else { + assert(pt_mapping->find(source_tensor) != pt_mapping->end()); + assert(pt_mapping->find(target_tensor) != pt_mapping->end()); + std::vector const &source_mapped_tensor_vector = + (*pt_mapping)[source_tensor]; + std::vector const &target_mapped_tensor_vector = + (*pt_mapping)[target_tensor]; + assert(source_mapped_tensor_vector.size() == + target_mapped_tensor_vector.size()); + bool same_region = source_mapped_tensor_vector[0]->region == + target_mapped_tensor_vector[0]->region + ? true + : false; + // Same that the two vectors use the exact same regions + if (same_region) { + for (size_t i = 0; i < source_mapped_tensor_vector.size(); i++) { + assert(source_mapped_tensor_vector[i]->region == + target_mapped_tensor_vector[i]->region); + } + } + return same_region; + } +} + +bool FusedOp::add_operator( + FFModel &model, + Op *op, + std::unordered_map> + *pt_mapping) { // Context ctx = model.config.lg_ctx; // Runtime* runtime = model.config.lg_hlr; // Currently assume fusion optimization is performed @@ -127,8 +163,8 @@ bool FusedOp::add_operator(FFModel &model, Op *op) { // assert(model.config.find_parallel_config(my_domain.get_dim(), name, // my_config)); assert(model.config.find_parallel_config(op_domain.get_dim(), // op->name, op_config)); - // Cannot fuse parallel operators since they have different paralel_is - // in forward and backward + // Cannot fuse parallel operators (except allreduce) since they have different + // paralel_is in forward and backward assert(!op->is_parallel_op() || op->op_type == OP_ALLREDUCE); // Currently don't consider nested fusion if (op->op_type == OP_FUSED) { @@ -151,19 +187,21 @@ bool FusedOp::add_operator(FFModel &model, Op *op) { (weight_offset + op->numWeights > MAX_NUM_FUSED_TENSORS) || (output_offset + op->numOutputs > MAX_NUM_FUSED_TENSORS)) { fprintf(stderr, "Cannot fuse. Consider increase MAX_NUM_FUSED_TENSORS\n"); + assert(false); return false; } if (numOperators + 1 > MAX_NUM_FUSED_OPERATORS) { fprintf( stderr, "Reach to the fusion limit. Consider increase MAX_NUM_FUSED_OPERATORS"); + assert(false); return false; } // Set inputs for (int i = 0; i < op->numInputs; i++) { bool found = false; for (int j = 0; j < numInputs; j++) { - if (inputs[j]->region == op->inputs[i]->region) { + if (use_same_regions(inputs[j], op->inputs[i], pt_mapping)) { // This input is one of my inputs assert(!found); assert(inputs[j]->region != LogicalRegion::NO_REGION); @@ -174,7 +212,7 @@ bool FusedOp::add_operator(FFModel &model, Op *op) { } } for (int j = 0; j < numOutputs; j++) { - if ((outputs[j]->region == op->inputs[i]->region) && (!found)) { + if (use_same_regions(outputs[j], op->inputs[i], pt_mapping) && (!found)) { // This input is one of my outputs assert(!found); assert(outputs[j]->region != LogicalRegion::NO_REGION); @@ -200,6 +238,11 @@ bool FusedOp::add_operator(FFModel &model, Op *op) { for (int i = 0; i < op->numWeights; i++) { bool found = false; for (int j = 0; j < numWeights; j++) { + // pt_mapping does not apply to weights + if (pt_mapping != nullptr) { + assert(pt_mapping->find(weights[j]) == pt_mapping->end()); + assert(pt_mapping->find(op->weights[i]) == pt_mapping->end()); + } if (weights[j]->region == op->weights[i]->region) { assert(!found); assert(weights[j]->region != LogicalRegion::NO_REGION); @@ -225,7 +268,7 @@ bool FusedOp::add_operator(FFModel &model, Op *op) { for (int i = 0; i < op->numOutputs; i++) { bool found = false; for (int j = 0; j < numOutputs; j++) { - if (outputs[j]->region == op->outputs[i]->region) { + if (use_same_regions(outputs[j], op->outputs[i], pt_mapping)) { assert(!found); found = true; op_output_source[output_offset + i] = SOURCE_OUTPUT; @@ -333,6 +376,96 @@ void FusedOp::init(FFModel const &ff) { } } +void FusedOp::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + // Call init methods in individual operators + Domain domain = runtime->get_index_space_domain(ctx, parallel_is); + int ioff = 0, ooff = 0; + for (int op = 0; op < numOperators; op++) { + // prepare batch_inputs, batch_outputs for operators[op] + std::vector my_batch_inputs; + std::vector my_batch_outputs; + for (int i = 0; i < op_num_inputs[op]; i++) { + int my_off = op_input_idx[i + ioff]; + if (op_input_source[i + ioff] == SOURCE_INPUT) { + assert(my_off < batch_inputs.size()); + my_batch_inputs.push_back(batch_inputs[my_off]); + } else if (op_input_source[i + ioff] == SOURCE_OUTPUT) { + assert(my_off < batch_outputs.size()); + my_batch_inputs.push_back(batch_outputs[my_off]); + } else { + assert(false); + } + } + for (int i = 0; i < op_num_outputs[op]; i++) { + int my_off = op_output_idx[i + ooff]; + assert(op_output_source[i + ooff] == SOURCE_OUTPUT); + assert(my_off < batch_outputs.size()); + my_batch_outputs.push_back(batch_outputs[my_off]); + } + ioff += op_num_inputs[op]; + ooff += op_num_outputs[op]; + operators[op]->init_inference(ff, my_batch_inputs, my_batch_outputs, mv); + for (size_t j = 0; j < domain.get_volume(); j++) { + fused_meta[j].meta[op] = + operators[op]->inference_meta[my_batch_outputs[0]][j]; + } + } + for (size_t j = 0; j < domain.get_volume(); j++) { + fused_meta[j].numOperators = numOperators; + } + switch (domain.get_dim()) { +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + argmap.set_point(*it, \ + TaskArgument(&fused_meta[idx++], sizeof(FusedOpMeta))); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + IndexLauncher launcher(FUSEDOP_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(FusedOp)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + switch (domain.get_dim()) { +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + inference_meta[batch_outputs[0]][idx++] = fm.get_result(*it); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } +} + void FusedOp::forward(FFModel const &ff) { // Set iter_config iter_config = ff.iter_config; @@ -382,6 +515,67 @@ void FusedOp::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap FusedOp::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + // Set iter_config + iter_config = ff.iter_config; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + // bc is one of BatchConfig, TreeVerifyBatchConfig, and BeamSearchBatchConfig + // so we transfer the maximum of them + // size_t batch_config_size = + // std::max(sizeof(TreeVerifyBatchConfig), sizeof(BeamSearchBatchConfig)); + IndexLauncher launcher(FUSEDOP_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + int offset = 0; + for (int i = 0; i < numInputs; i++) { + assert(inputs[i]->part != LogicalPartition::NO_PART); + assert(inputs[i]->region != LogicalRegion::NO_REGION); + launcher.add_region_requirement(RegionRequirement(batch_inputs[i]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[i]->region)); + launcher.add_field(offset + i, FID_DATA); + } + offset += numInputs; + for (int i = 0; i < numWeights; i++) { + assert(weights[i]->region != LogicalRegion::NO_REGION); + launcher.add_region_requirement(RegionRequirement(weights[i]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[i]->region)); + launcher.add_field(offset + i, FID_DATA); + } + offset += numWeights; + for (int i = 0; i < numOutputs; i++) { + assert(outputs[i]->region != LogicalRegion::NO_REGION); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[i]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[i]->region)); + launcher.add_field(offset + i, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + void FusedOp::backward(FFModel const &ff) { // Set iter_config iter_config = ff.iter_config; diff --git a/src/ops/fused.cpp b/src/ops/fused.cpp index 9da93f0c65..6dc8ac9a1c 100644 --- a/src/ops/fused.cpp +++ b/src/ops/fused.cpp @@ -14,10 +14,14 @@ */ #include "flexflow/ops/fused.h" +#include "flexflow/accessor.h" #include "flexflow/model.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/batch_norm.h" #include "flexflow/ops/element_unary.h" #include "flexflow/ops/embedding.h" +#include "flexflow/ops/flat.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/kernels/batch_matmul_kernels.h" #include "flexflow/ops/kernels/cast_kernels.h" #include "flexflow/ops/kernels/concat_kernels.h" @@ -29,10 +33,17 @@ #include "flexflow/ops/kernels/linear_kernels.h" #include "flexflow/ops/kernels/pool_2d_kernels.h" #include "flexflow/ops/kernels/reshape_kernels.h" +#include "flexflow/ops/kernels/residual_rms_norm_kernels.h" +#include "flexflow/ops/kernels/rms_norm_kernels.h" #include "flexflow/ops/kernels/softmax_kernels.h" #include "flexflow/ops/kernels/transpose_kernels.h" #include "flexflow/parallel_ops/kernels/allreduce_kernels.h" #include "flexflow/ops/layer_norm.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/sigmoid_silu_multi.h" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/parallel_ops/kernels/allreduce_kernels.h" #include "flexflow/ops/linear.h" #include "flexflow/utils/hip_helper.h" #include @@ -42,11 +53,11 @@ namespace FlexFlow { using Legion::Context; using Legion::coord_t; using Legion::Domain; +using Legion::Future; using Legion::LogicalPartition; using Legion::LogicalRegion; +using Legion::Memory; using Legion::PhysicalRegion; -using Legion::PointInRectIterator; -using Legion::Rect; using Legion::Runtime; using Legion::Task; @@ -68,7 +79,7 @@ OpMeta *FusedOp::init_task(Task const *task, /* regions[...](I): inputs regions[...](I): weights - regions[...](I): outputs + regions[...](O): outputs */ __host__ void FusedOp::forward_task(Task const *task, std::vector const ®ions, @@ -220,13 +231,15 @@ __host__ void FusedOp::forward_task(Task const *task, out_dim * batch_size); assert(my_input_accessor[0].domain.get_volume() == in_dim * batch_size); float const *bias_ptr = nullptr; + LinearMeta *m = (LinearMeta *)metas->meta[op]; if (fused->op_num_weights[op] == 2) { assert(my_weight_accessor[1].domain.get_volume() == out_dim); - bias_ptr = my_weight_accessor[1].get_float_ptr(); + if (!m->add_bias_only_once || task->index_point.point_data[0] == 0) { + bias_ptr = my_weight_accessor[1].get_float_ptr(); + } } else { assert(fused->op_num_weights[op] == 1); } - LinearMeta *m = (LinearMeta *)metas->meta[op]; Kernels::Linear::forward_kernel_wrapper( m, my_input_accessor[0].get_float_ptr(), @@ -288,14 +301,12 @@ __host__ void FusedOp::forward_task(Task const *task, // assert(my_input_accessor[0].domain == my_input_accessor[1].domain); // assert(my_input_accessor[0].domain == my_output_accessor[0].domain); ElementBinaryMeta *m = (ElementBinaryMeta *)metas->meta[op]; - Kernels::ElementBinary::forward_kernel_wrapper( - m, - my_input_accessor[0].get_float_ptr(), - my_input_accessor[1].get_float_ptr(), - my_output_accessor[0].get_float_ptr()); + Kernels::ElementBinary::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); break; } - case OP_EMBEDDING: { assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_weights[op] == 1); @@ -411,7 +422,12 @@ __host__ void FusedOp::forward_task(Task const *task, assert(my_input_accessor[0].domain.get_volume() == my_output_accessor[0].domain.get_volume()); SoftmaxMeta *m = (SoftmaxMeta *)metas->meta[op]; - if (my_input_accessor[0].data_type == DT_FLOAT) { + if (m->input_type == DT_HALF) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr()); + } else if (m->input_type == DT_FLOAT) { Kernels::Softmax::forward_kernel_wrapper( m, my_input_accessor[0].get_float_ptr(), @@ -474,36 +490,38 @@ __host__ void FusedOp::forward_task(Task const *task, assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_outputs[op] == 1); LayerNormMeta const *m = (LayerNormMeta *)metas->meta[op]; - assert(fused->op_num_weights[op] == 2 * (int)(m->elementwise_affine)); + if (m->elementwise_affine) { + assert(fused->op_num_weights[op] == 1 + (int)(m->use_bias)); + } GenericTensorAccessorR gamma, beta; if (m->elementwise_affine) { gamma = my_weight_accessor[0]; - beta = my_weight_accessor[1]; + if (m->use_bias) { + beta = my_weight_accessor[1]; + } } LayerNorm::forward_kernel_wrapper( m, my_input_accessor[0], my_output_accessor[0], gamma, beta); break; } - case OP_CAST: { - assert(fused->op_num_inputs[op] == 1); - assert(fused->op_num_outputs[op] == 1); - CastMeta const *m = (CastMeta *)metas->meta[op]; - if (m->input_data_type == DT_INT32 && m->output_data_type == DT_INT64) { - Kernels::Cast::forward_kernel_wrapper( - m, - my_input_accessor[0].get_int32_ptr(), - my_output_accessor[0].get_int64_ptr(), - my_output_accessor[0].domain.get_volume()); - } else if (m->input_data_type == DT_INT32 && - m->output_data_type == DT_FLOAT) { - Kernels::Cast::forward_kernel_wrapper( - m, - my_input_accessor[0].get_int32_ptr(), - my_output_accessor[0].get_float_ptr(), - my_output_accessor[0].domain.get_volume()); - } else { - assert(false); - } + case OP_RESIDUAL_LAYERNORM: { + assert(false && "Operator ResidualLayerNorm does not support " + "the forward() task"); + break; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + assert(false && "Operator AddBiasResidualLayerNorm does not support " + "the forward() task"); + break; + } + case OP_RESIDUAL_RMS_NORM: { + assert(false && "Operator ResidualRMSNorm does not support " + "the forward() task"); + break; + } + case OP_SIGMOID_SILU_MULTI: { + assert(false && "Operator SigmoidSiluMulti does not support " + "the forward() task"); break; } default: { @@ -523,35 +541,29 @@ __host__ void FusedOp::forward_task(Task const *task, } /* - regions[...](I): input - regions[...](I): weight - regions[...](I): output - regions[...](I/O): input_grad - regions[...](I/O): weight_grad - regions[...](I/O): output_grad + regions[...](I): inputs + regions[...](I): weights + regions[...](O): outputs */ - -__host__ void FusedOp::backward_task(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { +__host__ void + FusedOp::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { // const FusedOp* fused = (FusedOp*) task->args; FusedOpMeta const *metas = *((FusedOpMeta **)task->local_args); FusedOp const *fused = metas->fused_op; - + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } assert(metas->numOperators == fused->numOperators); assert(regions.size() == task->regions.size()); - { - int sum = fused->numInputs + fused->numWeights + fused->numOutputs; - assert(sum * 2 == (int)regions.size()); - } + assert((int)regions.size() == + fused->numInputs + fused->numWeights + fused->numOutputs); GenericTensorAccessorR input_accessor[MAX_NUM_INPUTS]; - GenericTensorAccessorW input_grad_accessor[MAX_NUM_INPUTS]; GenericTensorAccessorR weight_accessor[MAX_NUM_WEIGHTS]; - GenericTensorAccessorW weight_grad_accessor[MAX_NUM_WEIGHTS]; - GenericTensorAccessorR output_accessor[MAX_NUM_OUTPUTS]; - GenericTensorAccessorW output_grad_accessor[MAX_NUM_OUTPUTS]; - int roff = 0; + GenericTensorAccessorW output_accessor[MAX_NUM_OUTPUTS]; assert(fused->numInputs <= MAX_NUM_INPUTS); for (int i = 0; i < fused->numInputs; i++) { input_accessor[i] = @@ -562,7 +574,7 @@ __host__ void FusedOp::backward_task(Task const *task, ctx, runtime); } - roff += fused->numInputs; + int roff = fused->numInputs; assert(fused->numWeights <= MAX_NUM_WEIGHTS); for (int i = 0; i < fused->numWeights; i++) { weight_accessor[i] = @@ -577,48 +589,13 @@ __host__ void FusedOp::backward_task(Task const *task, assert(fused->numOutputs <= MAX_NUM_OUTPUTS); for (int i = 0; i < fused->numOutputs; i++) { output_accessor[i] = - helperGetGenericTensorAccessorRO(fused->output_data_types[i], - regions[i + roff], - task->regions[i + roff], - FID_DATA, - ctx, - runtime); - } - roff += fused->numOutputs; - for (int i = 0; i < fused->numInputs; i++) { - input_grad_accessor[i] = - helperGetGenericTensorAccessorRW(fused->input_data_types[i], - regions[i + roff], - task->regions[i + roff], - FID_DATA, - ctx, - runtime); - assert(input_grad_accessor[i].domain == input_accessor[i].domain); - } - roff += fused->numInputs; - for (int i = 0; i < fused->numWeights; i++) { - weight_grad_accessor[i] = - helperGetGenericTensorAccessorRW(fused->weight_data_types[i], - regions[i + roff], - task->regions[i + roff], - FID_DATA, - ctx, - runtime); - assert(weight_grad_accessor[i].domain.get_volume() == - weight_accessor[i].domain.get_volume()); - } - roff += fused->numWeights; - for (int i = 0; i < fused->numOutputs; i++) { - output_grad_accessor[i] = - helperGetGenericTensorAccessorRW(fused->output_data_types[i], + helperGetGenericTensorAccessorWO(fused->output_data_types[i], regions[i + roff], task->regions[i + roff], FID_DATA, ctx, runtime); - assert(output_grad_accessor[i].domain == output_accessor[i].domain); } - roff += fused->numOutputs; // Assert that all meta share the same dnn/blas handler int start = 0; for (start = 0; start < fused->numOperators; start++) { @@ -634,35 +611,21 @@ __host__ void FusedOp::backward_task(Task const *task, } hipStream_t stream; - checkCUDA(get_legion_stream(&stream)); + if (start < fused->numOperators) { + checkCUDA(get_legion_stream(&stream)); + } int ioff = 0, woff = 0, ooff = 0; - GenericTensorAccessorR my_input_accessor[MAX_NUM_INPUTS]; - GenericTensorAccessorR my_weight_accessor[MAX_NUM_WEIGHTS]; - GenericTensorAccessorR my_output_accessor[MAX_NUM_OUTPUTS]; - GenericTensorAccessorW my_input_grad_accessor[MAX_NUM_INPUTS]; - GenericTensorAccessorW my_weight_grad_accessor[MAX_NUM_WEIGHTS]; - GenericTensorAccessorW my_output_grad_accessor[MAX_NUM_OUTPUTS]; - // Do backpropagation in the reverse ordering for (int op = 0; op < fused->numOperators; op++) { - ioff += fused->op_num_inputs[op]; - woff += fused->op_num_weights[op]; - ooff += fused->op_num_outputs[op]; - } - - for (int op = fused->numOperators - 1; op >= 0; op--) { - ioff -= fused->op_num_inputs[op]; - woff -= fused->op_num_weights[op]; - ooff -= fused->op_num_outputs[op]; + GenericTensorAccessorR my_input_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorR my_weight_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorW my_output_accessor[MAX_NUM_OUTPUTS]; for (int i = 0; i < fused->op_num_inputs[op]; i++) { int my_off = fused->op_input_idx[i + ioff]; if (fused->op_input_source[i + ioff] == SOURCE_INPUT) { my_input_accessor[i] = input_accessor[my_off]; - my_input_grad_accessor[i] = input_grad_accessor[my_off]; } else if (fused->op_input_source[i + ioff] == SOURCE_OUTPUT) { my_input_accessor[i] = output_accessor[my_off]; - my_input_grad_accessor[i] = output_grad_accessor[my_off]; - assert(my_input_grad_accessor[i].domain == my_input_accessor[i].domain); } else { assert(false); } @@ -670,17 +633,10 @@ __host__ void FusedOp::backward_task(Task const *task, for (int i = 0; i < fused->op_num_weights[op]; i++) { assert(fused->op_weight_source[i + woff] == SOURCE_WEIGHT); my_weight_accessor[i] = weight_accessor[fused->op_weight_idx[i + woff]]; - my_weight_grad_accessor[i] = - weight_grad_accessor[fused->op_weight_idx[i + woff]]; - assert(my_weight_grad_accessor[i].domain.get_volume() == - my_weight_accessor[i].domain.get_volume()); } for (int i = 0; i < fused->op_num_outputs[op]; i++) { assert(fused->op_output_source[i + ooff] == SOURCE_OUTPUT); - my_output_accessor[i] = output_accessor[fused->op_output_idx[i + ooff]]; - my_output_grad_accessor[i] = - output_grad_accessor[fused->op_output_idx[i + ooff]]; - assert(my_output_grad_accessor[i].domain == my_output_accessor[i].domain); + my_output_accessor[i] = output_accessor[i + ooff]; } switch (fused->op_op_type[op]) { case OP_CONCAT: { @@ -688,59 +644,791 @@ __host__ void FusedOp::backward_task(Task const *task, assert(fused->op_num_outputs[op] == 1); ConcatMeta *m = (ConcatMeta *)metas->meta[op]; int num_inputs = fused->op_num_inputs[op]; - Kernels::Concat::backward_kernel_wrapper(m, - my_output_grad_accessor[0], - my_input_grad_accessor, - num_inputs, - m->legion_axis); - break; - } - case OP_CONV2D: { - assert(fused->op_num_inputs[op] == 1); - assert(fused->op_num_outputs[op] == 1); - assert(my_input_accessor[0].domain.get_dim() == 5); - assert(my_weight_accessor[0].domain.get_dim() == 5); - assert(my_output_accessor[0].domain.get_dim() == 5); - Conv2DMeta *m = (Conv2DMeta *)metas->meta[op]; - Kernels::Conv2D::backward_kernel_wrapper( - m, - my_input_accessor[0].get_float_ptr(), - my_input_grad_accessor[0].get_float_ptr(), - my_output_accessor[0].get_float_ptr(), - my_output_grad_accessor[0].get_float_ptr(), - my_weight_accessor[0].get_float_ptr(), - my_weight_grad_accessor[0].get_float_ptr(), - my_weight_grad_accessor[1].get_float_ptr()); + Kernels::Concat::forward_kernel_wrapper(m, + my_output_accessor[0], + my_input_accessor, + num_inputs, + m->legion_axis); break; } case OP_BATCHNORM: { assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_outputs[op] == 1); assert(my_input_accessor[0].domain.get_dim() == 5); + assert(my_output_accessor[0].domain.get_dim() == 5); assert(my_weight_accessor[0].domain.get_dim() == 2); assert(my_weight_accessor[1].domain.get_dim() == 2); - assert(my_output_accessor[0].domain.get_dim() == 5); BatchNormMeta *m = (BatchNormMeta *)metas->meta[op]; - BatchNorm::backward_kernel( - m, - (float const *)my_input_accessor[0].get_float_ptr(), - (float *)my_output_grad_accessor[0].get_float_ptr(), - (float const *)my_output_accessor[0].get_float_ptr(), - (float *)my_input_grad_accessor[0].get_float_ptr(), - (float const *)my_weight_accessor[0].get_float_ptr(), - (float *)my_weight_grad_accessor[0].get_float_ptr(), - (float *)my_weight_grad_accessor[1].get_float_ptr(), - my_output_accessor[0].domain.get_volume()); + BatchNorm::forward_kernel(m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr(), + my_weight_accessor[0].get_float_ptr(), + my_weight_accessor[1].get_float_ptr()); break; } - case OP_DROPOUT: { + case OP_LINEAR: { assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_outputs[op] == 1); - DropoutMeta *m = (DropoutMeta *)metas->meta[op]; - Kernels::Dropout::backward_kernel_wrapper( + Domain kernel_domain = my_weight_accessor[0].domain; + int in_dim = kernel_domain.hi()[0] - kernel_domain.lo()[0] + 1; + int out_dim = kernel_domain.hi()[1] - kernel_domain.lo()[1] + 1; + int batch_size = my_input_accessor[0].domain.get_volume() / in_dim; + assert(my_output_accessor[0].domain.get_volume() == + out_dim * batch_size); + assert(my_input_accessor[0].domain.get_volume() == in_dim * batch_size); + void const *bias_ptr = nullptr; + LinearMeta *m = (LinearMeta *)metas->meta[op]; + if (fused->op_num_weights[op] == 2) { + assert(my_weight_accessor[1].domain.get_volume() == out_dim); + if (!m->add_bias_only_once || task->index_point.point_data[0] == 0) { + bias_ptr = my_weight_accessor[1].ptr; + } + } else { + assert(fused->op_num_weights[op] == 1); + } + assert(m->input_type[0] == my_input_accessor[0].data_type); + assert(m->input_type[0] == my_output_accessor[0].data_type); + batch_size = bc->num_active_tokens(); + Kernels::Linear::forward_kernel_wrapper(m, + my_input_accessor[0].ptr, + my_output_accessor[0].ptr, + my_weight_accessor[0].ptr, + bias_ptr, + in_dim, + out_dim, + batch_size); + break; + } + case OP_BATCHMATMUL: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + Domain out_domain = my_output_accessor[0].domain; + Domain a_domain = my_input_accessor[0].domain; + Domain b_domain = my_input_accessor[1].domain; + int m = b_domain.hi()[0] - b_domain.lo()[0] + 1; + assert(m == out_domain.hi()[0] - out_domain.lo()[0] + 1); + int n = a_domain.hi()[1] - a_domain.lo()[1] + 1; + assert(n == out_domain.hi()[1] - out_domain.lo()[1] + 1); + int k = a_domain.hi()[0] - a_domain.lo()[0] + 1; + assert(k == b_domain.hi()[1] - b_domain.lo()[1] + 1); + assert(a_domain.get_dim() == b_domain.get_dim()); + assert(a_domain.get_dim() == out_domain.get_dim()); + int batch = 1; + for (int i = 2; i < a_domain.get_dim(); i++) { + int dim_size = a_domain.hi()[i] - a_domain.lo()[i] + 1; + assert(dim_size == b_domain.hi()[i] - b_domain.lo()[i] + 1); + assert(dim_size == out_domain.hi()[i] - out_domain.lo()[i] + 1); + batch *= dim_size; + } + BatchMatmulMeta *meta = (BatchMatmulMeta *)metas->meta[op]; + Kernels::BatchMatmul::forward_kernel_wrapper( + meta, + my_output_accessor[0].get_float_ptr(), + my_input_accessor[0].get_float_ptr(), + my_input_accessor[1].get_float_ptr(), + (float const *)nullptr, m, - my_output_grad_accessor[0].get_float_ptr(), - my_input_grad_accessor[0].get_float_ptr()); + n, + k, + batch, + meta->a_seq_length_dim, + meta->b_seq_length_dim, + fused->iter_config.seq_length); + break; + } + case OP_EW_ADD: + case OP_EW_SUB: + case OP_EW_MUL: + case OP_EW_DIV: + case OP_EW_MAX: + case OP_EW_MIN: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain == my_input_accessor[1].domain); + assert(my_input_accessor[0].domain == my_output_accessor[0].domain); + ElementBinaryMeta *m = (ElementBinaryMeta *)metas->meta[op]; + Kernels::ElementBinary::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); + break; + } + case OP_EMBEDDING: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 1); + EmbeddingMeta *m = (EmbeddingMeta *)metas->meta[op]; + if (m->aggr == AGGR_MODE_NONE) { + // assert(kernel_domain.get_dim() == 2); + assert(my_input_accessor[0].domain.get_dim() + 1 == + my_output_accessor[0].domain.get_dim()); + for (size_t i = 0; i < my_input_accessor[0].domain.get_dim(); i++) { + assert(my_input_accessor[0].domain.hi()[i] == + my_output_accessor[0].domain.hi()[i + 1]); + assert(my_input_accessor[0].domain.lo()[i] == + my_output_accessor[0].domain.lo()[i + 1]); + } + assert(my_weight_accessor[0].domain.hi()[0] - + my_weight_accessor[0].domain.lo()[0] == + my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0]); + } else { + assert(my_input_accessor[0].domain.get_dim() == + my_output_accessor[0].domain.get_dim()); + for (size_t i = 1; i < my_input_accessor[0].domain.get_dim(); i++) { + assert(my_input_accessor[0].domain.hi()[i] == + my_output_accessor[0].domain.hi()[i]); + assert(my_input_accessor[0].domain.lo()[i] == + my_output_accessor[0].domain.lo()[i]); + } + assert(my_weight_accessor[0].domain.hi()[0] - + my_weight_accessor[0].domain.lo()[0] == + my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0]); + } + int in_dim, out_dim, effective_batch_size; + if (m->aggr == AGGR_MODE_NONE) { + in_dim = 1; + out_dim = my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } else { + assert(m->aggr == AGGR_MODE_AVG || m->aggr == AGGR_MODE_SUM); + in_dim = my_input_accessor[0].domain.hi()[0] - + my_input_accessor[0].domain.lo()[0] + 1; + out_dim = my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } + + assert(my_input_accessor[0].data_type == DT_INT32 || + my_input_accessor[0].data_type == DT_INT64); + Kernels::Embedding::forward_kernel_wrapper(m, + my_input_accessor[0], + my_output_accessor[0], + my_weight_accessor[0], + in_dim, + out_dim, + effective_batch_size); + break; + } + case OP_GELU: + case OP_RELU: + case OP_SIGMOID: + case OP_TANH: + case OP_ELU: + case OP_SCALAR_TRUE_DIV: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain == my_output_accessor[0].domain); + ElementUnaryMeta *m = (ElementUnaryMeta *)metas->meta[op]; + if (m->data_type == DT_HALF) { + ElementUnary::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr(), + my_input_accessor[0].domain.get_volume()); + } else if (m->data_type == DT_FLOAT) { + ElementUnary::forward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr(), + my_input_accessor[0].domain.get_volume()); + } else { + assert(false && "Unsupported data type in ElementUnary forward"); + } + break; + } + case OP_RMS_NORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 1); + RMSNormMeta const *m = (RMSNormMeta *)metas->meta[op]; + Kernels::RMSNorm::forward_kernel_wrapper(m, + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0]); + break; + } + case OP_RESIDUAL_RMS_NORM: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 2); + ResidualRMSNormMeta const *m = (ResidualRMSNormMeta *)metas->meta[op]; + Kernels::ResidualRMSNorm::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_weight_accessor[0], + my_output_accessor[0], + my_output_accessor[1]); + break; + } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + IncMultiHeadSelfAttentionMeta const *m = + (IncMultiHeadSelfAttentionMeta *)metas->meta[op]; + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + IncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + TreeIncMultiHeadSelfAttentionMeta *m = + (TreeIncMultiHeadSelfAttentionMeta *)metas->meta[op]; + TreeVerifyBatchConfig const &tree_bc = + Future(task->futures[0]).get_result(); + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + TreeIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + &tree_bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + SpecIncMultiHeadSelfAttentionMeta const *m = + (SpecIncMultiHeadSelfAttentionMeta *)metas->meta[op]; + // BeamSearchBatchConfig const *beam_bc = + // (BeamSearchBatchConfig *)task->args; + BeamSearchBatchConfig const &beam_bc = + Future(task->futures[0]).get_result(); + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + SpecIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + &beam_bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_LAYERNORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + LayerNormMeta const *m = (LayerNormMeta *)metas->meta[op]; + if (m->elementwise_affine) { + assert(fused->op_num_weights[op] == 1 + (int)(m->use_bias)); + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[0]; + if (m->use_bias) { + beta = my_weight_accessor[1]; + } + } + LayerNorm::forward_kernel_wrapper( + m, my_input_accessor[0], my_output_accessor[0], gamma, beta); + break; + } + case OP_RESIDUAL_LAYERNORM: { + assert(fused->op_num_outputs[op] == 2); + ResidualLayerNormMeta const *m = + (ResidualLayerNormMeta *)metas->meta[op]; + if (m->use_two_residuals) { + assert(fused->op_num_inputs[op] == 3); + } else { + assert(fused->op_num_inputs[op] == 2); + } + if (!m->elementwise_affine) { + assert(fused->op_num_weights[op] == 0); + } else { + if (!m->use_bias) { + assert(fused->op_num_weights[op] == 1); // weight + } else { + assert(fused->op_num_weights[op] == 2); // weight + bias + } + } + GenericTensorAccessorR residual2; + if (m->use_two_residuals) { + residual2 = my_input_accessor[2]; + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[0]; + if (m->use_bias) { + beta = my_weight_accessor[1]; + } + } + ResidualLayerNorm::inference_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + residual2, + my_output_accessor[0], + my_output_accessor[1], + gamma, + beta); + break; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_outputs[op] == 2); + AddBiasResidualLayerNormMeta const *m = + (AddBiasResidualLayerNormMeta *)metas->meta[op]; + if (!m->elementwise_affine) { + assert(fused->op_num_weights[op] == 1); // attn bias + } else { + if (!m->use_bias) { + assert(fused->op_num_weights[op] == 2); // attn bias + weight + } else { + assert(fused->op_num_weights[op] == 3); // attn bias + weight + bias + } + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[1]; + if (m->use_bias) { + beta = my_weight_accessor[2]; + } + } + Domain attn_bias_domain = my_weight_accessor[0].domain; + Domain residual_domain = my_input_accessor[1].domain; + int attn_bias_dim = + attn_bias_domain.hi()[0] - attn_bias_domain.lo()[0] + 1; + int residual_volume = residual_domain.get_volume(); + AddBiasResidualLayerNorm::inference_kernel_wrapper( + m, + attn_bias_dim, + residual_volume, + my_input_accessor[0], + my_output_accessor[0], + my_output_accessor[1], + my_input_accessor[1], + my_weight_accessor[0], + gamma, + beta); + break; + } + case OP_SIGMOID_SILU_MULTI: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_outputs[op] == 1); + SigmoidSiluMultiMeta const *m = (SigmoidSiluMultiMeta *)metas->meta[op]; + SigmoidSiluMulti::inference_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); + break; + } + case OP_SOFTMAX: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_volume() == + my_output_accessor[0].domain.get_volume()); + SoftmaxMeta *m = (SoftmaxMeta *)metas->meta[op]; + if (m->input_type == DT_HALF) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr()); + } else if (m->input_type == DT_FLOAT) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr()); + } + break; + } + case OP_ALLREDUCE: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + AllReduceMeta const *m = (AllReduceMeta *)metas->meta[op]; + Kernels::AllReduce::inference_kernel_wrapper( + m, bc, my_input_accessor[0], my_output_accessor[0]); + break; + } + + case OP_CAST: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + CastMeta const *m = (CastMeta *)metas->meta[op]; + if (m->input_data_type == DT_INT32 && m->output_data_type == DT_INT64) { + Kernels::Cast::forward_kernel_wrapper( + m, + my_input_accessor[0].get_int32_ptr(), + my_output_accessor[0].get_int64_ptr(), + my_output_accessor[0].domain.get_volume()); + } else if (m->input_data_type == DT_INT32 && + m->output_data_type == DT_FLOAT) { + Kernels::Cast::forward_kernel_wrapper( + m, + my_input_accessor[0].get_int32_ptr(), + my_output_accessor[0].get_float_ptr(), + my_output_accessor[0].domain.get_volume()); + } else { + assert(false); + } + break; + } + default: { + fprintf(stderr, + "Fusion currently does not support type = %d\n", + fused->op_op_type[op]); + assert(false && "Fusion currently does not support type"); + } + } + ioff += fused->op_num_inputs[op]; + woff += fused->op_num_weights[op]; + ooff += fused->op_num_outputs[op]; + } + // for (int i = 0; i < fused->numOutputs; i++) + // print_tensor(output_ptr[i], output_domain[i].get_volume(), + // "[Fused:forward:output]"); +} + +/* + regions[...](I): input + regions[...](I): weight + regions[...](I): output + regions[...](I/O): input_grad + regions[...](I/O): weight_grad + regions[...](I/O): output_grad +*/ +__host__ void FusedOp::backward_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + // const FusedOp* fused = (FusedOp*) task->args; + FusedOpMeta const *metas = *((FusedOpMeta **)task->local_args); + FusedOp const *fused = metas->fused_op; + + assert(metas->numOperators == fused->numOperators); + assert(regions.size() == task->regions.size()); + { + int sum = fused->numInputs + fused->numWeights + fused->numOutputs; + assert(sum * 2 == (int)regions.size()); + } + GenericTensorAccessorR input_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorW input_grad_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorR weight_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorW weight_grad_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorR output_accessor[MAX_NUM_OUTPUTS]; + GenericTensorAccessorW output_grad_accessor[MAX_NUM_OUTPUTS]; + int roff = 0; + assert(fused->numInputs <= MAX_NUM_INPUTS); + for (int i = 0; i < fused->numInputs; i++) { + input_accessor[i] = + helperGetGenericTensorAccessorRO(fused->input_data_types[i], + regions[i], + task->regions[i], + FID_DATA, + ctx, + runtime); + } + roff += fused->numInputs; + assert(fused->numWeights <= MAX_NUM_WEIGHTS); + for (int i = 0; i < fused->numWeights; i++) { + weight_accessor[i] = + helperGetGenericTensorAccessorRO(fused->weight_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + } + roff += fused->numWeights; + assert(fused->numOutputs <= MAX_NUM_OUTPUTS); + for (int i = 0; i < fused->numOutputs; i++) { + output_accessor[i] = + helperGetGenericTensorAccessorRO(fused->output_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + } + roff += fused->numOutputs; + for (int i = 0; i < fused->numInputs; i++) { + input_grad_accessor[i] = + helperGetGenericTensorAccessorRW(fused->input_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + assert(input_grad_accessor[i].domain == input_accessor[i].domain); + } + roff += fused->numInputs; + for (int i = 0; i < fused->numWeights; i++) { + weight_grad_accessor[i] = + helperGetGenericTensorAccessorRW(fused->weight_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + assert(weight_grad_accessor[i].domain.get_volume() == + weight_accessor[i].domain.get_volume()); + } + roff += fused->numWeights; + for (int i = 0; i < fused->numOutputs; i++) { + output_grad_accessor[i] = + helperGetGenericTensorAccessorRW(fused->output_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + assert(output_grad_accessor[i].domain == output_accessor[i].domain); + } + roff += fused->numOutputs; + // Assert that all meta share the same dnn/blas handler + int start = 0; + for (start = 0; start < fused->numOperators; start++) { + if (metas->meta[start] != NULL) { + break; + } + } + for (int op = start + 1; op < fused->numOperators; op++) { + if (metas->meta[op] != NULL) { + assert(metas->meta[start]->handle.blas == metas->meta[op]->handle.blas); + assert(metas->meta[start]->handle.dnn == metas->meta[op]->handle.dnn); + } + } + + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + int ioff = 0, woff = 0, ooff = 0; + GenericTensorAccessorR my_input_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorR my_weight_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorR my_output_accessor[MAX_NUM_OUTPUTS]; + GenericTensorAccessorW my_input_grad_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorW my_weight_grad_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorW my_output_grad_accessor[MAX_NUM_OUTPUTS]; + // Do backpropagation in the reverse ordering + for (int op = 0; op < fused->numOperators; op++) { + ioff += fused->op_num_inputs[op]; + woff += fused->op_num_weights[op]; + ooff += fused->op_num_outputs[op]; + } + + for (int op = fused->numOperators - 1; op >= 0; op--) { + ioff -= fused->op_num_inputs[op]; + woff -= fused->op_num_weights[op]; + ooff -= fused->op_num_outputs[op]; + for (int i = 0; i < fused->op_num_inputs[op]; i++) { + int my_off = fused->op_input_idx[i + ioff]; + if (fused->op_input_source[i + ioff] == SOURCE_INPUT) { + my_input_accessor[i] = input_accessor[my_off]; + my_input_grad_accessor[i] = input_grad_accessor[my_off]; + } else if (fused->op_input_source[i + ioff] == SOURCE_OUTPUT) { + my_input_accessor[i] = output_accessor[my_off]; + my_input_grad_accessor[i] = output_grad_accessor[my_off]; + assert(my_input_grad_accessor[i].domain == my_input_accessor[i].domain); + } else { + assert(false); + } + } + for (int i = 0; i < fused->op_num_weights[op]; i++) { + assert(fused->op_weight_source[i + woff] == SOURCE_WEIGHT); + my_weight_accessor[i] = weight_accessor[fused->op_weight_idx[i + woff]]; + my_weight_grad_accessor[i] = + weight_grad_accessor[fused->op_weight_idx[i + woff]]; + assert(my_weight_grad_accessor[i].domain.get_volume() == + my_weight_accessor[i].domain.get_volume()); + } + for (int i = 0; i < fused->op_num_outputs[op]; i++) { + assert(fused->op_output_source[i + ooff] == SOURCE_OUTPUT); + my_output_accessor[i] = output_accessor[fused->op_output_idx[i + ooff]]; + my_output_grad_accessor[i] = + output_grad_accessor[fused->op_output_idx[i + ooff]]; + assert(my_output_grad_accessor[i].domain == my_output_accessor[i].domain); + } + switch (fused->op_op_type[op]) { + case OP_BATCHMATMUL: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + Domain out_domain = my_output_accessor[0].domain; + Domain a_domain = my_input_accessor[0].domain; + Domain b_domain = my_input_accessor[1].domain; + // check dims + int m = b_domain.hi()[0] - b_domain.lo()[0] + 1; + assert(m == out_domain.hi()[0] - out_domain.lo()[0] + 1); + int n = a_domain.hi()[1] - a_domain.lo()[1] + 1; + assert(n == out_domain.hi()[1] - out_domain.lo()[1] + 1); + int k = a_domain.hi()[0] - a_domain.lo()[0] + 1; + assert(k == b_domain.hi()[1] - b_domain.lo()[1] + 1); + assert(a_domain.get_dim() == b_domain.get_dim()); + assert(a_domain.get_dim() == out_domain.get_dim()); + int batch = 1; + for (int i = 2; i < a_domain.get_dim(); i++) { + int dim_size = a_domain.hi()[i] - a_domain.lo()[i] + 1; + assert(dim_size == b_domain.hi()[i] - b_domain.lo()[i] + 1); + assert(dim_size == out_domain.hi()[i] - out_domain.lo()[i] + 1); + batch *= dim_size; + } + BatchMatmulMeta *meta = (BatchMatmulMeta *)metas->meta[op]; + Kernels::BatchMatmul::backward_kernel_wrapper( + meta, + (float const *)my_output_accessor[0].get_float_ptr(), + (float const *)my_output_grad_accessor[0].get_float_ptr(), + (float const *)my_input_accessor[0].get_float_ptr(), + (float *)my_input_grad_accessor[0].get_float_ptr(), + (float const *)my_input_accessor[1].get_float_ptr(), + (float *)my_input_grad_accessor[1].get_float_ptr(), + (float *)nullptr, + m, + n, + k, + batch); + break; + } + case OP_BATCHNORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_dim() == 5); + assert(my_weight_accessor[0].domain.get_dim() == 2); + assert(my_weight_accessor[1].domain.get_dim() == 2); + assert(my_output_accessor[0].domain.get_dim() == 5); + BatchNormMeta *m = (BatchNormMeta *)metas->meta[op]; + BatchNorm::backward_kernel( + m, + (float const *)my_input_accessor[0].get_float_ptr(), + (float *)my_output_grad_accessor[0].get_float_ptr(), + (float const *)my_output_accessor[0].get_float_ptr(), + (float *)my_input_grad_accessor[0].get_float_ptr(), + (float const *)my_weight_accessor[0].get_float_ptr(), + (float *)my_weight_grad_accessor[0].get_float_ptr(), + (float *)my_weight_grad_accessor[1].get_float_ptr(), + my_output_accessor[0].domain.get_volume()); + break; + } + case OP_CONCAT: { + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + ConcatMeta *m = (ConcatMeta *)metas->meta[op]; + int num_inputs = fused->op_num_inputs[op]; + Kernels::Concat::backward_kernel_wrapper(m, + my_output_grad_accessor[0], + my_input_grad_accessor, + num_inputs, + m->legion_axis); + break; + } + case OP_CONV2D: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_dim() == 5); + assert(my_weight_accessor[0].domain.get_dim() == 5); + assert(my_output_accessor[0].domain.get_dim() == 5); + Conv2DMeta *m = (Conv2DMeta *)metas->meta[op]; + Kernels::Conv2D::backward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_input_grad_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr(), + my_output_grad_accessor[0].get_float_ptr(), + my_weight_accessor[0].get_float_ptr(), + my_weight_grad_accessor[0].get_float_ptr(), + my_weight_grad_accessor[1].get_float_ptr()); + break; + } + case OP_DROPOUT: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + DropoutMeta *m = (DropoutMeta *)metas->meta[op]; + Kernels::Dropout::backward_kernel_wrapper( + m, + my_output_grad_accessor[0].get_float_ptr(), + my_input_grad_accessor[0].get_float_ptr()); + break; + } + case OP_EW_ADD: + case OP_EW_SUB: + case OP_EW_MUL: + case OP_EW_DIV: + case OP_EW_MAX: + case OP_EW_MIN: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain == my_input_accessor[1].domain); + assert(my_input_accessor[0].domain == my_output_accessor[0].domain); + ElementBinaryMeta *m = (ElementBinaryMeta *)metas->meta[op]; + Kernels::ElementBinary::backward_kernel_wrapper( + m, + my_output_grad_accessor[0].get_float_ptr(), + my_input_accessor[0].get_float_ptr(), + my_input_accessor[1].get_float_ptr(), + my_input_grad_accessor[0].get_float_ptr(), + my_input_grad_accessor[1].get_float_ptr()); + break; + } + case OP_EMBEDDING: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 1); + EmbeddingMeta *m = (EmbeddingMeta *)metas->meta[op]; + assert(my_input_accessor[0].data_type == DT_INT64); + int in_dim, out_dim, effective_batch_size; + if (m->aggr == AGGR_MODE_NONE) { + in_dim = 1; + out_dim = my_output_grad_accessor[0].domain.hi()[0] - + my_output_grad_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_grad_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } else { + in_dim = my_input_accessor[0].domain.hi()[0] - + my_input_accessor[0].domain.lo()[0] + 1; + out_dim = my_output_grad_accessor[0].domain.hi()[0] - + my_output_grad_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_grad_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } + Kernels::Embedding::backward_kernel_wrapper(m, + my_input_accessor[0], + my_output_grad_accessor[0], + my_weight_grad_accessor[0], + in_dim, + out_dim, + effective_batch_size); break; } case OP_LINEAR: { diff --git a/src/ops/fused.cu b/src/ops/fused.cu index b78447ba41..ec114c8ea5 100644 --- a/src/ops/fused.cu +++ b/src/ops/fused.cu @@ -15,11 +15,13 @@ #include "flexflow/accessor.h" #include "flexflow/model.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/batch_norm.h" #include "flexflow/ops/element_unary.h" #include "flexflow/ops/embedding.h" #include "flexflow/ops/flat.h" #include "flexflow/ops/fused.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/kernels/batch_matmul_kernels.h" #include "flexflow/ops/kernels/cast_kernels.h" #include "flexflow/ops/kernels/concat_kernels.h" @@ -31,10 +33,17 @@ #include "flexflow/ops/kernels/linear_kernels.h" #include "flexflow/ops/kernels/pool_2d_kernels.h" #include "flexflow/ops/kernels/reshape_kernels.h" +#include "flexflow/ops/kernels/residual_rms_norm_kernels.h" +#include "flexflow/ops/kernels/rms_norm_kernels.h" #include "flexflow/ops/kernels/softmax_kernels.h" #include "flexflow/ops/kernels/transpose_kernels.h" #include "flexflow/parallel_ops/kernels/allreduce_kernels.h" #include "flexflow/ops/layer_norm.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/sigmoid_silu_multi.h" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/parallel_ops/kernels/allreduce_kernels.h" #include "flexflow/utils/cuda_helper.h" namespace FlexFlow { @@ -42,8 +51,10 @@ namespace FlexFlow { using Legion::Context; using Legion::coord_t; using Legion::Domain; +using Legion::Future; using Legion::LogicalPartition; using Legion::LogicalRegion; +using Legion::Memory; using Legion::PhysicalRegion; using Legion::Runtime; using Legion::Task; @@ -66,7 +77,7 @@ OpMeta *FusedOp::init_task(Task const *task, /* regions[...](I): inputs regions[...](I): weights - regions[...](I): outputs + regions[...](O): outputs */ __host__ void FusedOp::forward_task(Task const *task, std::vector const ®ions, @@ -164,10 +175,11 @@ __host__ void FusedOp::forward_task(Task const *task, my_weight_accessor[i] = weight_accessor[fused->op_weight_idx[i + woff]]; } for (int i = 0; i < fused->op_num_outputs[op]; i++) { + int my_off = fused->op_output_idx[i + ooff]; assert(fused->op_output_source[i + ooff] == SOURCE_OUTPUT); - // my_od[i] = output_domain[fused->op_output_idx[i + ooff]]; - // my_op[i] = output_ptr[fused->op_output_idx[i + ooff]]; - my_output_accessor[i] = output_accessor[i + ooff]; + // my_od[i] = output_domain[my_off]; + // my_op[i] = output_ptr[my_off]; + my_output_accessor[i] = output_accessor[my_off]; } switch (fused->op_op_type[op]) { case OP_CONCAT: { @@ -231,13 +243,15 @@ __host__ void FusedOp::forward_task(Task const *task, out_dim * batch_size); assert(my_input_accessor[0].domain.get_volume() == in_dim * batch_size); float const *bias_ptr = nullptr; + LinearMeta *m = (LinearMeta *)metas->meta[op]; if (fused->op_num_weights[op] == 2) { assert(my_weight_accessor[1].domain.get_volume() == out_dim); - bias_ptr = my_weight_accessor[1].get_float_ptr(); + if (!m->add_bias_only_once || task->index_point.point_data[0] == 0) { + bias_ptr = my_weight_accessor[1].get_float_ptr(); + } } else { assert(fused->op_num_weights[op] == 1); } - LinearMeta *m = (LinearMeta *)metas->meta[op]; Kernels::Linear::forward_kernel_wrapper( m, my_input_accessor[0].get_float_ptr(), @@ -299,11 +313,10 @@ __host__ void FusedOp::forward_task(Task const *task, // assert(my_input_accessor[0].domain == my_input_accessor[1].domain); // assert(my_input_accessor[0].domain == my_output_accessor[0].domain); ElementBinaryMeta *m = (ElementBinaryMeta *)metas->meta[op]; - Kernels::ElementBinary::forward_kernel_wrapper( - m, - my_input_accessor[0].get_float_ptr(), - my_input_accessor[1].get_float_ptr(), - my_output_accessor[0].get_float_ptr()); + Kernels::ElementBinary::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); break; } case OP_EMBEDDING: { @@ -416,6 +429,26 @@ __host__ void FusedOp::forward_task(Task const *task, my_input_accessor[0].domain.get_volume()); break; } + case OP_SOFTMAX: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_volume() == + my_output_accessor[0].domain.get_volume()); + SoftmaxMeta *m = (SoftmaxMeta *)metas->meta[op]; + if (m->input_type == DT_HALF) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr()); + } else if (m->input_type == DT_FLOAT) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr()); + } + break; + } case OP_RESHAPE: { assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_weights[op] == 0); @@ -500,6 +533,603 @@ __host__ void FusedOp::forward_task(Task const *task, m, my_input_accessor[0], my_output_accessor[0], gamma, beta); break; } + case OP_RESIDUAL_LAYERNORM: { + assert(false && "Operator ResidualLayerNorm does not support " + "the forward() task"); + break; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + assert(false && "Operator AddBiasResidualLayerNorm does not support " + "the forward() task"); + break; + } + case OP_SIGMOID_SILU_MULTI: { + assert(false && "Operator SigmoidSiluMulti does not support " + "the forward() task"); + break; + } + case OP_RESIDUAL_RMS_NORM: { + assert(false && "Operator ResidualRMSNorm does not support " + "the forward() task"); + break; + } + default: { + fprintf(stderr, + "Fusion currently does not support type = %d\n", + fused->op_op_type[op]); + assert(false && "Fusion currently does not support type"); + } + } + ioff += fused->op_num_inputs[op]; + woff += fused->op_num_weights[op]; + ooff += fused->op_num_outputs[op]; + } + // for (int i = 0; i < fused->numOutputs; i++) + // print_tensor(output_ptr[i], output_domain[i].get_volume(), + // "[Fused:forward:output]"); +} + +/* + regions[...](I): inputs + regions[...](I): weights + regions[...](O): outputs +*/ +__host__ void + FusedOp::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + // const FusedOp* fused = (FusedOp*) task->args; + FusedOpMeta *metas = *((FusedOpMeta **)task->local_args); + FusedOp const *fused = metas->fused_op; + // BatchConfig const *bc = (BatchConfig *)task->args; + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + // Return if no active tokens + if (bc->num_tokens == 0) { + return; + } + + assert(metas->numOperators == fused->numOperators); + assert(regions.size() == task->regions.size()); + assert((int)regions.size() == + fused->numInputs + fused->numWeights + fused->numOutputs); + // Domain input_domain[MAX_NUM_INPUTS]; + // Domain weight_domain[MAX_NUM_WEIGHTS]; + // Domain output_domain[MAX_NUM_OUTPUTS]; + GenericTensorAccessorR input_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorR weight_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorW output_accessor[MAX_NUM_OUTPUTS]; + assert(fused->numInputs <= MAX_NUM_INPUTS); + for (int i = 0; i < fused->numInputs; i++) { + // input_domain[i] = runtime->get_index_space_domain( + // ctx, task->regions[i].region.get_index_space()); + input_accessor[i] = + helperGetGenericTensorAccessorRO(fused->input_data_types[i], + regions[i], + task->regions[i], + FID_DATA, + ctx, + runtime); + } + int roff = fused->numInputs; + assert(fused->numWeights <= MAX_NUM_WEIGHTS); + for (int i = 0; i < fused->numWeights; i++) { + // weight_domain[i] = runtime->get_index_space_domain( + // ctx, task->regions[i + roff].region.get_index_space()); + weight_accessor[i] = + helperGetGenericTensorAccessorRO(fused->weight_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + } + roff += fused->numWeights; + assert(fused->numOutputs <= MAX_NUM_OUTPUTS); + for (int i = 0; i < fused->numOutputs; i++) { + // output_domain[i] = runtime->get_index_space_domain( + // ctx, task->regions[i + roff].region.get_index_space()); + output_accessor[i] = + helperGetGenericTensorAccessorWO(fused->output_data_types[i], + regions[i + roff], + task->regions[i + roff], + FID_DATA, + ctx, + runtime); + } + // Assert that all meta share the same dnn/blas handler + int start = 0; + for (start = 0; start < fused->numOperators; start++) { + if (metas->meta[start] != NULL) { + break; + } + } + for (int op = start + 1; op < fused->numOperators; op++) { + if (metas->meta[op] != NULL) { + assert(metas->meta[start]->handle.blas == metas->meta[op]->handle.blas); + assert(metas->meta[start]->handle.dnn == metas->meta[op]->handle.dnn); + } + } + + int ioff = 0, woff = 0, ooff = 0; + for (int op = 0; op < fused->numOperators; op++) { + // Domain my_id[MAX_NUM_INPUTS]; + // Domain my_wd[MAX_NUM_WEIGHTS]; + // Domain my_od[MAX_NUM_OUTPUTS]; + GenericTensorAccessorR my_input_accessor[MAX_NUM_INPUTS]; + GenericTensorAccessorR my_weight_accessor[MAX_NUM_WEIGHTS]; + GenericTensorAccessorW my_output_accessor[MAX_NUM_OUTPUTS]; + for (int i = 0; i < fused->op_num_inputs[op]; i++) { + int my_off = fused->op_input_idx[i + ioff]; + if (fused->op_input_source[i + ioff] == SOURCE_INPUT) { + // my_id[i] = input_domain[my_off]; + assert(my_off < fused->numInputs); + my_input_accessor[i] = input_accessor[my_off]; + } else if (fused->op_input_source[i + ioff] == SOURCE_OUTPUT) { + // my_id[i] = output_domain[my_off]; + assert(my_off < fused->numOutputs); + my_input_accessor[i] = output_accessor[my_off]; + } else { + assert(false); + } + } + for (int i = 0; i < fused->op_num_weights[op]; i++) { + assert(fused->op_weight_source[i + woff] == SOURCE_WEIGHT); + // my_wd[i] = weight_domain[fused->op_weight_idx[i + woff]]; + // my_wp[i] = weight_ptr[fused->op_weight_idx[i + woff]]; + assert(fused->op_weight_idx[i + woff] < fused->numWeights); + my_weight_accessor[i] = weight_accessor[fused->op_weight_idx[i + woff]]; + } + for (int i = 0; i < fused->op_num_outputs[op]; i++) { + int my_off = fused->op_output_idx[i + ooff]; + assert(fused->op_output_source[i + ooff] == SOURCE_OUTPUT); + assert(my_off < fused->numOutputs); + // my_od[i] = output_domain[fused->op_output_idx[i + ooff]]; + // my_op[i] = output_ptr[fused->op_output_idx[i + ooff]]; + my_output_accessor[i] = output_accessor[my_off]; + } + switch (fused->op_op_type[op]) { + case OP_CONCAT: { + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + ConcatMeta *m = (ConcatMeta *)metas->meta[op]; + int num_inputs = fused->op_num_inputs[op]; + Kernels::Concat::forward_kernel_wrapper(m, + my_output_accessor[0], + my_input_accessor, + num_inputs, + m->legion_axis); + break; + } + case OP_BATCHNORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_dim() == 5); + assert(my_output_accessor[0].domain.get_dim() == 5); + assert(my_weight_accessor[0].domain.get_dim() == 2); + assert(my_weight_accessor[1].domain.get_dim() == 2); + BatchNormMeta *m = (BatchNormMeta *)metas->meta[op]; + BatchNorm::forward_kernel(m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr(), + my_weight_accessor[0].get_float_ptr(), + my_weight_accessor[1].get_float_ptr()); + break; + } + case OP_LINEAR: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + Domain kernel_domain = my_weight_accessor[0].domain; + int in_dim = kernel_domain.hi()[0] - kernel_domain.lo()[0] + 1; + int out_dim = kernel_domain.hi()[1] - kernel_domain.lo()[1] + 1; + int batch_size = my_input_accessor[0].domain.get_volume() / in_dim; + assert(my_output_accessor[0].domain.get_volume() == + out_dim * batch_size); + assert(my_input_accessor[0].domain.get_volume() == in_dim * batch_size); + void const *bias_ptr = nullptr; + LinearMeta *m = (LinearMeta *)metas->meta[op]; + if (fused->op_num_weights[op] == 2) { + assert(my_weight_accessor[1].domain.get_volume() == out_dim); + if (!m->add_bias_only_once || task->index_point.point_data[0] == 0) { + bias_ptr = my_weight_accessor[1].ptr; + } + } else { + assert(fused->op_num_weights[op] == 1); + } + assert(m->input_type[0] == my_input_accessor[0].data_type); + assert(m->input_type[0] == my_output_accessor[0].data_type); + batch_size = bc->num_active_tokens(); + Kernels::Linear::forward_kernel_wrapper(m, + my_input_accessor[0].ptr, + my_output_accessor[0].ptr, + my_weight_accessor[0].ptr, + bias_ptr, + in_dim, + out_dim, + batch_size); + break; + } + case OP_BATCHMATMUL: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + Domain out_domain = my_output_accessor[0].domain; + Domain a_domain = my_input_accessor[0].domain; + Domain b_domain = my_input_accessor[1].domain; + int m = b_domain.hi()[0] - b_domain.lo()[0] + 1; + assert(m == out_domain.hi()[0] - out_domain.lo()[0] + 1); + int n = a_domain.hi()[1] - a_domain.lo()[1] + 1; + assert(n == out_domain.hi()[1] - out_domain.lo()[1] + 1); + int k = a_domain.hi()[0] - a_domain.lo()[0] + 1; + assert(k == b_domain.hi()[1] - b_domain.lo()[1] + 1); + assert(a_domain.get_dim() == b_domain.get_dim()); + assert(a_domain.get_dim() == out_domain.get_dim()); + int batch = 1; + for (int i = 2; i < a_domain.get_dim(); i++) { + int dim_size = a_domain.hi()[i] - a_domain.lo()[i] + 1; + assert(dim_size == b_domain.hi()[i] - b_domain.lo()[i] + 1); + assert(dim_size == out_domain.hi()[i] - out_domain.lo()[i] + 1); + batch *= dim_size; + } + BatchMatmulMeta *meta = (BatchMatmulMeta *)metas->meta[op]; + Kernels::BatchMatmul::forward_kernel_wrapper( + meta, + my_output_accessor[0].get_float_ptr(), + my_input_accessor[0].get_float_ptr(), + my_input_accessor[1].get_float_ptr(), + (float const *)nullptr, + m, + n, + k, + batch, + meta->a_seq_length_dim, + meta->b_seq_length_dim, + fused->iter_config.seq_length); + break; + } + case OP_EW_ADD: + case OP_EW_SUB: + case OP_EW_MUL: + case OP_EW_DIV: + case OP_EW_MAX: + case OP_EW_MIN: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain == my_input_accessor[1].domain); + assert(my_input_accessor[0].domain == my_output_accessor[0].domain); + ElementBinaryMeta *m = (ElementBinaryMeta *)metas->meta[op]; + Kernels::ElementBinary::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); + break; + } + case OP_EMBEDDING: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 1); + EmbeddingMeta *m = (EmbeddingMeta *)metas->meta[op]; + if (m->aggr == AGGR_MODE_NONE) { + // assert(kernel_domain.get_dim() == 2); + assert(my_input_accessor[0].domain.get_dim() + 1 == + my_output_accessor[0].domain.get_dim()); + for (size_t i = 0; i < my_input_accessor[0].domain.get_dim(); i++) { + assert(my_input_accessor[0].domain.hi()[i] == + my_output_accessor[0].domain.hi()[i + 1]); + assert(my_input_accessor[0].domain.lo()[i] == + my_output_accessor[0].domain.lo()[i + 1]); + } + assert(my_weight_accessor[0].domain.hi()[0] - + my_weight_accessor[0].domain.lo()[0] == + my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0]); + } else { + assert(my_input_accessor[0].domain.get_dim() == + my_output_accessor[0].domain.get_dim()); + for (size_t i = 1; i < my_input_accessor[0].domain.get_dim(); i++) { + assert(my_input_accessor[0].domain.hi()[i] == + my_output_accessor[0].domain.hi()[i]); + assert(my_input_accessor[0].domain.lo()[i] == + my_output_accessor[0].domain.lo()[i]); + } + assert(my_weight_accessor[0].domain.hi()[0] - + my_weight_accessor[0].domain.lo()[0] == + my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0]); + } + int in_dim, out_dim, effective_batch_size; + if (m->aggr == AGGR_MODE_NONE) { + in_dim = 1; + out_dim = my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } else { + assert(m->aggr == AGGR_MODE_AVG || m->aggr == AGGR_MODE_SUM); + in_dim = my_input_accessor[0].domain.hi()[0] - + my_input_accessor[0].domain.lo()[0] + 1; + out_dim = my_output_accessor[0].domain.hi()[0] - + my_output_accessor[0].domain.lo()[0] + 1; + effective_batch_size = + my_output_accessor[0].domain.get_volume() / out_dim; + assert(effective_batch_size * in_dim == + my_input_accessor[0].domain.get_volume()); + } + + assert(my_input_accessor[0].data_type == DT_INT32 || + my_input_accessor[0].data_type == DT_INT64); + Kernels::Embedding::forward_kernel_wrapper(m, + my_input_accessor[0], + my_output_accessor[0], + my_weight_accessor[0], + in_dim, + out_dim, + effective_batch_size); + break; + } + case OP_GELU: + case OP_RELU: + case OP_SIGMOID: + case OP_TANH: + case OP_ELU: + case OP_SCALAR_TRUE_DIV: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain == my_output_accessor[0].domain); + ElementUnaryMeta *m = (ElementUnaryMeta *)metas->meta[op]; + if (m->data_type == DT_HALF) { + ElementUnary::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr(), + my_input_accessor[0].domain.get_volume()); + } else if (m->data_type == DT_FLOAT) { + ElementUnary::forward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr(), + my_input_accessor[0].domain.get_volume()); + } else { + assert(false && "Unsupported data type in ElementUnary forward"); + } + break; + } + case OP_RMS_NORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 1); + RMSNormMeta const *m = (RMSNormMeta *)metas->meta[op]; + Kernels::RMSNorm::forward_kernel_wrapper(m, + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0]); + break; + } + case OP_RESIDUAL_RMS_NORM: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_weights[op] == 1); + assert(fused->op_num_outputs[op] == 2); + ResidualRMSNormMeta const *m = (ResidualRMSNormMeta *)metas->meta[op]; + Kernels::ResidualRMSNorm::forward_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_weight_accessor[0], + my_output_accessor[0], + my_output_accessor[1]); + break; + } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + IncMultiHeadSelfAttentionMeta const *m = + (IncMultiHeadSelfAttentionMeta *)metas->meta[op]; + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + IncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + TreeIncMultiHeadSelfAttentionMeta *m = + (TreeIncMultiHeadSelfAttentionMeta *)metas->meta[op]; + // TreeVerifyBatchConfig const *tree_bc = + // (TreeVerifyBatchConfig *)task->args; + TreeVerifyBatchConfig const &tree_bc = + Future(task->futures[0]).get_result(); + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + TreeIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + &tree_bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + SpecIncMultiHeadSelfAttentionMeta const *m = + (SpecIncMultiHeadSelfAttentionMeta *)metas->meta[op]; + // BeamSearchBatchConfig const *beam_bc = + // (BeamSearchBatchConfig *)task->args; + BeamSearchBatchConfig const &beam_bc = + Future(task->futures[0]).get_result(); + assert(fused->op_num_weights[op] == + (1 + (int)(*m->qkv_bias || *m->final_bias))); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + assert(fused->op_num_weights[op] == 2); + biases = my_weight_accessor[1]; + } + SpecIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, + &beam_bc, + task->index_point.point_data[0], + my_input_accessor[0], + my_weight_accessor[0], + my_output_accessor[0], + biases); + break; + } + case OP_LAYERNORM: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + LayerNormMeta const *m = (LayerNormMeta *)metas->meta[op]; + if (m->elementwise_affine) { + assert(fused->op_num_weights[op] == 1 + (int)(m->use_bias)); + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[0]; + if (m->use_bias) { + beta = my_weight_accessor[1]; + } + } + LayerNorm::forward_kernel_wrapper( + m, my_input_accessor[0], my_output_accessor[0], gamma, beta); + break; + } + case OP_RESIDUAL_LAYERNORM: { + assert(fused->op_num_outputs[op] == 2); + ResidualLayerNormMeta const *m = + (ResidualLayerNormMeta *)metas->meta[op]; + if (m->use_two_residuals) { + assert(fused->op_num_inputs[op] == 3); + } else { + assert(fused->op_num_inputs[op] == 2); + } + if (!m->elementwise_affine) { + assert(fused->op_num_weights[op] == 0); + } else { + if (!m->use_bias) { + assert(fused->op_num_weights[op] == 1); // weight + } else { + assert(fused->op_num_weights[op] == 2); // weight + bias + } + } + GenericTensorAccessorR residual2; + if (m->use_two_residuals) { + residual2 = my_input_accessor[2]; + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[0]; + if (m->use_bias) { + beta = my_weight_accessor[1]; + } + } + ResidualLayerNorm::inference_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + residual2, + my_output_accessor[0], + my_output_accessor[1], + gamma, + beta); + break; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_outputs[op] == 2); + AddBiasResidualLayerNormMeta const *m = + (AddBiasResidualLayerNormMeta *)metas->meta[op]; + if (!m->elementwise_affine) { + assert(fused->op_num_weights[op] == 1); // attn bias + } else { + if (!m->use_bias) { + assert(fused->op_num_weights[op] == 2); // attn bias + weight + } else { + assert(fused->op_num_weights[op] == 3); // attn bias + weight + bias + } + } + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = my_weight_accessor[1]; + if (m->use_bias) { + beta = my_weight_accessor[2]; + } + } + Domain attn_bias_domain = my_weight_accessor[0].domain; + Domain residual_domain = my_input_accessor[1].domain; + int attn_bias_dim = + attn_bias_domain.hi()[0] - attn_bias_domain.lo()[0] + 1; + int residual_volume = residual_domain.get_volume(); + AddBiasResidualLayerNorm::inference_kernel_wrapper( + m, + attn_bias_dim, + residual_volume, + my_input_accessor[0], + my_output_accessor[0], + my_output_accessor[1], + my_input_accessor[1], + my_weight_accessor[0], + gamma, + beta); + break; + } + case OP_SIGMOID_SILU_MULTI: { + assert(fused->op_num_inputs[op] == 2); + assert(fused->op_num_outputs[op] == 1); + SigmoidSiluMultiMeta const *m = (SigmoidSiluMultiMeta *)metas->meta[op]; + SigmoidSiluMulti::inference_kernel_wrapper(m, + my_input_accessor[0], + my_input_accessor[1], + my_output_accessor[0]); + break; + } + case OP_SOFTMAX: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_weights[op] == 0); + assert(fused->op_num_outputs[op] == 1); + assert(my_input_accessor[0].domain.get_volume() == + my_output_accessor[0].domain.get_volume()); + SoftmaxMeta *m = (SoftmaxMeta *)metas->meta[op]; + if (m->input_type == DT_HALF) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_half_ptr(), + my_output_accessor[0].get_half_ptr()); + } else if (m->input_type == DT_FLOAT) { + Kernels::Softmax::forward_kernel_wrapper( + m, + my_input_accessor[0].get_float_ptr(), + my_output_accessor[0].get_float_ptr()); + } + break; + } + case OP_ALLREDUCE: { + assert(fused->op_num_inputs[op] == 1); + assert(fused->op_num_outputs[op] == 1); + AllReduceMeta const *m = (AllReduceMeta *)metas->meta[op]; + Kernels::AllReduce::inference_kernel_wrapper( + m, bc, my_input_accessor[0], my_output_accessor[0]); + break; + } case OP_CAST: { assert(fused->op_num_inputs[op] == 1); assert(fused->op_num_outputs[op] == 1); @@ -520,7 +1150,6 @@ __host__ void FusedOp::forward_task(Task const *task, } else { assert(false); } - break; } default: { @@ -530,6 +1159,37 @@ __host__ void FusedOp::forward_task(Task const *task, assert(false && "Fusion currently does not support type"); } } + if (metas->meta[op]->inference_debugging) { + std::vector input_accessors_to_save; + std::vector weight_accessors_to_save; + std::vector output_accessors_to_save; + for (int i = 0; i < fused->op_num_inputs[op]; i++) { + int my_off = fused->op_input_idx[i + ioff]; + if (fused->op_input_source[i + ioff] == SOURCE_INPUT) { + input_accessors_to_save.push_back(input_accessor[my_off]); + } else if (fused->op_input_source[i + ioff] == SOURCE_OUTPUT) { + input_accessors_to_save.push_back(output_accessor[my_off]); + } else { + assert(false); + } + } + for (int i = 0; i < fused->op_num_weights[op]; i++) { + assert(fused->op_weight_source[i + woff] == SOURCE_WEIGHT); + weight_accessors_to_save.push_back( + weight_accessor[fused->op_weight_idx[i + woff]]); + } + for (int i = 0; i < fused->op_num_outputs[op]; i++) { + output_accessors_to_save.push_back(output_accessor[i + ooff]); + } + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + FusedOp::save_inference_tensors_to_file(metas->meta[op], + shard_id, + bc, + input_accessors_to_save, + weight_accessors_to_save, + output_accessors_to_save); + } ioff += fused->op_num_inputs[op]; woff += fused->op_num_weights[op]; ooff += fused->op_num_outputs[op]; @@ -547,7 +1207,6 @@ __host__ void FusedOp::forward_task(Task const *task, regions[...](I/O): weight_grad regions[...](I/O): output_grad */ - __host__ void FusedOp::backward_task(Task const *task, std::vector const ®ions, Context ctx, @@ -722,13 +1381,13 @@ __host__ void FusedOp::backward_task(Task const *task, } for (int i = 0; i < fused->op_num_outputs[op]; i++) { assert(fused->op_output_source[i + ooff] == SOURCE_OUTPUT); - // my_od[i] = output_domain[fused->op_output_idx[i + ooff]]; - // my_op[i] = output_ptr[fused->op_output_idx[i + ooff]]; - my_output_accessor[i] = output_accessor[fused->op_output_idx[i + ooff]]; - // my_grad_od[i] = output_grad_domain[fused->op_output_idx[i + ooff]]; - // my_grad_op[i] = output_grad_ptr[fused->op_output_idx[i + ooff]]; - my_output_grad_accessor[i] = - output_grad_accessor[fused->op_output_idx[i + ooff]]; + int my_off = fused->op_output_idx[i + ooff]; + // my_od[i] = output_domain[my_off]; + // my_op[i] = output_ptr[my_off]; + my_output_accessor[i] = output_accessor[my_off]; + // my_grad_od[i] = output_grad_domain[my_off]; + // my_grad_op[i] = output_grad_ptr[my_off]; + my_output_grad_accessor[i] = output_grad_accessor[my_off]; assert(my_output_grad_accessor[i].domain == my_output_accessor[i].domain); } switch (fused->op_op_type[op]) { diff --git a/src/ops/gather.cc b/src/ops/gather.cc index f094fe38b0..85580ed803 100644 --- a/src/ops/gather.cc +++ b/src/ops/gather.cc @@ -125,7 +125,7 @@ Gather::Gather(FFModel &model, inputs.first, inputs.second, params.legion_dim, - name) {} + params.name) {} Gather::Gather(FFModel &model, LayerID const &_layer_guid, @@ -166,6 +166,10 @@ void Gather::serialize(Legion::Serializer &sez) const { GatherParams params = get_params(); sez.serialize(params.legion_dim); sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -177,13 +181,20 @@ Node Gather::deserialize(FFModel &ff, assert(num_inputs == 2); int legion_dim; dez.deserialize(legion_dim); - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); GatherParams params; params.legion_dim = legion_dim; params.layer_guid = layer_guid; + strcpy(params.name, name); return ff.get_or_create_node({inputs[0], inputs[1]}, params); } @@ -241,6 +252,8 @@ OpMeta *Gather::init_task(Task const *task, Gather const *gather = (Gather const *)task->args; FFHandler handle = *((FFHandler const *)task->local_args); GatherMeta *m = new GatherMeta(handle, gather); + std::strcpy(m->op_name, gather->name); + m->layer_guid = gather->layer_guid; GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); GenericTensorAccessorR index = helperGetGenericTensorAccessorRO( diff --git a/src/ops/group_by.cc b/src/ops/group_by.cc index 850a5c4587..f2f402737c 100644 --- a/src/ops/group_by.cc +++ b/src/ops/group_by.cc @@ -99,6 +99,9 @@ Group_byParams Group_by::get_params() const { Group_byParams params; params.n = this->n; params.alpha = this->alpha; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -161,8 +164,62 @@ Group_by::Group_by(FFModel &model, Group_byParams const ¶ms, std::pair const &inputs, char const *name) - : Group_by( - model, inputs.first, inputs.second, params.n, params.alpha, name) {} + : Group_by(model, + inputs.first, + inputs.second, + params.n, + params.alpha, + params.name) {} + +void Group_by::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(GROUP_BY_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Group_by)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // data + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // assign + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + + // output + for (int i = 0; i < n; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[i]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[i]->region)); + launcher.add_field(i + 2, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} void Group_by::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -214,8 +271,11 @@ OpMeta *Group_by::init_task(Task const *task, Runtime *runtime) { Group_by *gb = (Group_by *)task->args; FFHandler handle = *((FFHandler *)task->local_args); - GroupByMeta *m = new GroupByMeta(handle, gb->n); + GroupByMeta *m = new GroupByMeta(handle, gb->n, gb->alpha); m->profiling = gb->profiling; + m->inference_debugging = gb->inference_debugging; + std::strcpy(m->op_name, gb->name); + m->layer_guid = gb->layer_guid; return m; } @@ -226,7 +286,7 @@ void Group_by::forward(FFModel const &ff) { set_argumentmap_for_forward(ff, argmap); IndexLauncher launcher(GROUP_BY_FWD_TASK_ID, parallel_is, - TaskArgument(this, sizeof(Group_by)), + TaskArgument(NULL, 0), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -261,64 +321,117 @@ void Group_by::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap Group_by::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + /* std::cout << "GroupBy op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(GROUP_BY_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // data + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + + // assign + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(1, FID_DATA); + + // output + for (int i = 0; i < n; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[i]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[i]->region)); + launcher.add_field(i + 2, FID_DATA); + } + + return runtime->execute_index_space(ctx, launcher); +} + void Group_by::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - // Get n, alpha - Group_by const *gb = (Group_by *)task->args; - int n = gb->n; - float alpha = gb->alpha; - - assert((int)regions.size() == n + 2); + int n = (int)regions.size() - 2; assert((int)task->regions.size() == n + 2); - GroupByMeta const *m = *((GroupByMeta **)task->local_args); + GroupByMeta *m = *((GroupByMeta **)task->local_args); // get input and assign regions. Each tensor has three dimensions: // (datapoint_dim, batch_size, replica_dim) - AccessorRO const acc_input(regions[0], FID_DATA); - AccessorRO const acc_assign(regions[1], FID_DATA); - - Rect<3> rect_input = runtime->get_index_space_domain( + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + DT_FLOAT, regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR assign = helperGetGenericTensorAccessorRO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + Domain input_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); - Rect<3> rect_assign = runtime->get_index_space_domain( + Domain assign_domain = runtime->get_index_space_domain( ctx, task->regions[1].region.get_index_space()); - coord_t input_rows = rect_input.hi[1] - rect_input.lo[1] + 1; - coord_t input_cols = rect_input.hi[0] - rect_input.lo[0] + 1; - assert(input_rows == rect_assign.hi[1] - rect_assign.lo[1] + 1); + coord_t input_rows = input_domain.hi()[1] - input_domain.lo()[1] + 1; + coord_t input_cols = input_domain.hi()[0] - input_domain.lo()[0] + 1; + assert(input_rows == assign_domain.hi()[1] - assign_domain.lo()[1] + 1); - int k = rect_assign.hi[0] - rect_assign.lo[0] + 1; + int k = assign_domain.hi()[0] - assign_domain.lo()[0] + 1; int batch_size = input_rows; int data_dim = input_cols; // Create a vector of n outputs, where n is the number of experts. // Each entry in the "outputs" vector points to the Legion tensor that will // contain the tockens dispatched to the corresponding expert + std::vector output_accessors; float *outputs[n]; - int exp_output_rows = (int)ceil(alpha * k / n * batch_size); for (int i = 0; i < n; i++) { + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + DT_FLOAT, regions[i + 2], task->regions[i + 2], FID_DATA, ctx, runtime); + output_accessors.push_back(output); Domain out_domain = runtime->get_index_space_domain( ctx, task->regions[i + 2].region.get_index_space()); - outputs[i] = helperGetTensorPointerWO( - regions[i + 2], task->regions[i + 2], FID_DATA, ctx, runtime); + outputs[i] = output.get_float_ptr(); coord_t output_rows = out_domain.hi()[1] - out_domain.lo()[1] + 1; coord_t output_cols = out_domain.hi()[0] - out_domain.lo()[0] + 1; - assert((int)output_rows == exp_output_rows); assert(output_cols == input_cols); } Group_by::forward_kernel_wrapper(m, - acc_input.ptr(rect_input), - acc_assign.ptr(rect_assign), + input.get_float_ptr(), + assign.get_int32_ptr(), outputs, n, k, - alpha, batch_size, data_dim); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Group_by::save_inference_tensors_to_file( + m, shard_id, nullptr, {input, assign}, {}, output_accessors); + } } void Group_by::backward(FFModel const &ff) { @@ -328,7 +441,7 @@ void Group_by::backward(FFModel const &ff) { set_argumentmap_for_backward(ff, argmap); IndexLauncher launcher(GROUP_BY_BWD_TASK_ID, parallel_is, - TaskArgument(this, sizeof(Group_by)), + TaskArgument(NULL, 0), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -368,13 +481,9 @@ void Group_by::backward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - // Get n, alpha GroupByMeta const *m = *((GroupByMeta **)task->local_args); - Group_by const *gb = (Group_by *)task->args; - int n = gb->n; - float alpha = gb->alpha; - assert((int)regions.size() == n + 2); + int n = (int)regions.size() - 2; assert((int)task->regions.size() == n + 2); // get input and assign regions @@ -396,7 +505,6 @@ void Group_by::backward_task(Task const *task, // get output float *output_grads[n]; - int exp_output_rows = (int)ceil(alpha * k / n * batch_size); for (int i = 0; i < n; i++) { Domain out_domain = runtime->get_index_space_domain( ctx, task->regions[i + 2].region.get_index_space()); @@ -405,7 +513,6 @@ void Group_by::backward_task(Task const *task, coord_t output_rows = out_domain.hi()[1] - out_domain.lo()[1] + 1; coord_t output_cols = out_domain.hi()[0] - out_domain.lo()[0] + 1; - assert((int)output_rows == exp_output_rows); assert(output_cols == input_cols); } @@ -415,7 +522,6 @@ void Group_by::backward_task(Task const *task, output_grads, n, k, - alpha, batch_size, data_dim); } @@ -423,6 +529,8 @@ void Group_by::backward_task(Task const *task, void Group_by::serialize(Legion::Serializer &sez) const { sez.serialize(this->n); sez.serialize(this->alpha); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } Node Group_by::deserialize(FFModel &ff, @@ -434,9 +542,14 @@ Node Group_by::deserialize(FFModel &ff, float alpha; dez.deserialize(n); dez.deserialize(alpha); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); Group_byParams params; params.n = n; params.alpha = alpha; + strcpy(params.name, name); return ff.get_or_create_node(std::make_pair(inputs[0], inputs[1]), params); } @@ -466,7 +579,7 @@ bool Group_by::measure_operator_cost(Simulator *sim, } } - GroupByMeta *m = new GroupByMeta(sim->handler, n); + GroupByMeta *m = new GroupByMeta(sim->handler, n, alpha); // allocate sim->free_all(); @@ -500,15 +613,8 @@ bool Group_by::measure_operator_cost(Simulator *sim, int data_dim = in_domain.hi()[0] - in_domain.lo()[0] + 1; forward = [&] { - forward_kernel_wrapper(m, - input_ptr, - assign_ptr, - output_ptrs, - n, - k, - alpha, - batch_size, - data_dim); + forward_kernel_wrapper( + m, input_ptr, assign_ptr, output_ptrs, n, k, batch_size, data_dim); }; inner_measure_operator_cost(sim, forward, backward, cost_metrics); diff --git a/src/ops/group_by.cpp b/src/ops/group_by.cpp index f45e9092a5..761c35f182 100644 --- a/src/ops/group_by.cpp +++ b/src/ops/group_by.cpp @@ -118,23 +118,24 @@ __global__ void } /*static*/ -void Group_by::forward_kernel_wrapper( - GroupByMeta const *m, - float const *input, - int const *exp_assign, - float **outputs, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim) { +void Group_by::forward_kernel_wrapper(GroupByMeta const *m, + float const *input, + int const *exp_assign, + float **outputs, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim) { + + float alpha = m->alpha; + // TODO: why cublas/cudnn stream is needed here? hipStream_t stream; checkCUDA(get_legion_stream(&stream)); // call forward kernel - hipMemcpy( - m->dev_region_ptrs, outputs, n * sizeof(float *), hipMemcpyHostToDevice); + checkCUDA(hipMemcpy( + m->dev_region_ptrs, outputs, n * sizeof(float *), hipMemcpyHostToDevice)); hipLaunchKernelGGL(gb_forward_kernel, GET_BLOCKS(batch_size * k * data_dim), @@ -151,25 +152,26 @@ void Group_by::forward_kernel_wrapper( data_dim); } -void Group_by::backward_kernel_wrapper( - GroupByMeta const *m, - float *input_grad, - int const *exp_assign, - float **output_grads, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim) { +void Group_by::backward_kernel_wrapper(GroupByMeta const *m, + float *input_grad, + int const *exp_assign, + float **output_grads, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim) { + + float alpha = m->alpha; + // TODO: why cublas/cudnn stream is needed here hipStream_t stream; checkCUDA(get_legion_stream(&stream)); // call forward kernel - hipMemcpy(m->dev_region_ptrs, - output_grads, - n * sizeof(float *), - hipMemcpyHostToDevice); + checkCUDA(hipMemcpy(m->dev_region_ptrs, + output_grads, + n * sizeof(float *), + hipMemcpyHostToDevice)); hipLaunchKernelGGL(gb_backward_kernel, GET_BLOCKS(batch_size * k * data_dim), @@ -186,7 +188,8 @@ void Group_by::backward_kernel_wrapper( data_dim); } -GroupByMeta::GroupByMeta(FFHandler handler, int n) : OpMeta(handler) { +GroupByMeta::GroupByMeta(FFHandler handler, int n, float _alpha) + : OpMeta(handler), alpha(_alpha) { checkCUDA(hipMalloc(&dev_region_ptrs, n * sizeof(float *))); } GroupByMeta::~GroupByMeta(void) { diff --git a/src/ops/group_by.cu b/src/ops/group_by.cu index ee0b18337c..0ed09e20b3 100644 --- a/src/ops/group_by.cu +++ b/src/ops/group_by.cu @@ -106,17 +106,18 @@ __global__ void } /*static*/ -void Group_by::forward_kernel_wrapper( - GroupByMeta const *m, - float const *input, - int const *exp_assign, - float **outputs, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim) { +void Group_by::forward_kernel_wrapper(GroupByMeta const *m, + float const *input, + int const *exp_assign, + float **outputs, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim) { // TODO: why cublas/cudnn stream is needed here? + + float alpha = m->alpha; + cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); cudaEvent_t t_start, t_end; @@ -148,16 +149,17 @@ void Group_by::forward_kernel_wrapper( } } -void Group_by::backward_kernel_wrapper( - GroupByMeta const *m, - float *input_grad, - int const *exp_assign, - float **output_grads, - int n, // num experts - int k, // chosen experts - float alpha, // factor additional memory assigned - int batch_size, - int data_dim) { +void Group_by::backward_kernel_wrapper(GroupByMeta const *m, + float *input_grad, + int const *exp_assign, + float **output_grads, + int n, // num experts + int k, // chosen experts + int batch_size, + int data_dim) { + + float alpha = m->alpha; + // TODO: why cublas/cudnn stream is needed here cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); @@ -196,7 +198,8 @@ void Group_by::backward_kernel_wrapper( } } -GroupByMeta::GroupByMeta(FFHandler handler, int n) : OpMeta(handler) { +GroupByMeta::GroupByMeta(FFHandler handler, int n, float _alpha) + : OpMeta(handler), alpha(_alpha) { checkCUDA(cudaMalloc(&dev_region_ptrs, n * sizeof(float *))); } GroupByMeta::~GroupByMeta(void) { diff --git a/src/ops/inc_multihead_self_attention.cc b/src/ops/inc_multihead_self_attention.cc new file mode 100644 index 0000000000..7aa3503770 --- /dev/null +++ b/src/ops/inc_multihead_self_attention.cc @@ -0,0 +1,965 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/model.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +LegionRuntime::Logger::Category log_inc_mha("IncrementalMHA"); + +bool IncMultiHeadSelfAttentionParams::is_valid( + ParallelTensorShape const &input) const { + bool is_valid = input.is_valid(); + return is_valid; +} + +Tensor FFModel::inc_multihead_self_attention(const Tensor input, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + return inc_multiquery_self_attention(input, + embed_dim, + num_heads, + num_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); +} + +Tensor FFModel::inc_multiquery_self_attention(const Tensor input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + if (data_type == DT_NONE) { + data_type = input->data_type; + } + DataType quantization_type = cpu_offload ? config.quantization_type : DT_NONE; + bool offload = cpu_offload; + Layer *li = nullptr; + int weight_num = (qkv_bias || final_bias) ? 2 : 1; + if (data_type != input->data_type) { + Tensor casted_input = cast(input, data_type, "type cast for IncMHA"); + li = new Layer(this, + OP_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + casted_input); + } else { + li = new Layer(this, + OP_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + input); + } + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + dims[0] = embed_dim; + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, data_type, li, 0, true /*create_grad*/); + } + // Compute weight size + int qProjSize = kdim, kProjSize = kdim, vProjSize = kdim, + oProjSize = embed_dim; + int qSize = input->dims[0], kSize = input->dims[0], vSize = input->dims[0]; + int qParas = qProjSize * qSize; + int kParas = kProjSize * kSize; + int vParas = vProjSize * vSize; + int oParas = oProjSize * (vProjSize > 0 ? vProjSize : vSize); + + // allocate num_q_heads for key, value for replication + int weight_size = qParas * num_q_heads + kParas * num_q_heads + + vParas * num_q_heads + oParas * num_q_heads; + int one_head_size = qParas + kParas + vParas + oParas; + + { + // compress the weight size if quantization. + if (quantization_type != DT_NONE) { + one_head_size = get_quantization_to_byte_size( + data_type, quantization_type, one_head_size); + } + int dims[1] = {weight_size}; + li->weights[0] = create_weight_legion_ordering( + 1, + dims, + quantization_type == DT_NONE ? data_type : quantization_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + if (qkv_bias || final_bias) { + // q, k, v, o + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + int dims[1] = {(qkv_bias ? qkv_bias_size : 0) + + (final_bias ? oProjSize : 0)}; + li->weights[1] = create_weight_legion_ordering(1, + dims, + data_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + li->data_type = data_type; + li->add_int_property("embed_dim", embed_dim); + li->add_int_property("num_q_heads", num_q_heads); + li->add_int_property("num_kv_heads", num_kv_heads); + li->add_int_property("kdim", kdim); + li->add_int_property("vdim", vdim); + li->add_int_property("qkv_bias", qkv_bias); + li->add_int_property("final_bias", final_bias); + li->add_int_property("add_zero_attn", add_zero_attn); + li->add_float_property("dropout", dropout); + li->add_int_property("apply_rotary_embedding", apply_rotary_embedding); + li->add_int_property("scaling_query", scaling_query); + li->add_float_property("scaling_factor", scaling_factor); + li->add_int_property("qk_prod_scaling", qk_prod_scaling); + li->add_int_property("position_bias", position_bias); + li->add_int_property("quantization_type", quantization_type); + li->add_int_property("offload", offload); + li->add_int_property("tensor_parallelism_degree", + config.tensor_parallelism_degree); + layers.push_back(li); + + return li->outputs[0]; +} + +Op *IncMultiHeadSelfAttention::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("embed_dim", value); + int embed_dim = value; + layer->get_int_property("num_q_heads", value); + int num_q_heads = value; + layer->get_int_property("num_kv_heads", value); + int num_kv_heads = value; + layer->get_int_property("kdim", value); + int kdim = value; + layer->get_int_property("vdim", value); + int vdim = value; + float dropout; + layer->get_float_property("dropout", dropout); + layer->get_int_property("qkv_bias", value); + bool qkv_bias = (bool)value; + layer->get_int_property("final_bias", value); + bool final_bias = (bool)value; + layer->get_int_property("add_zero_attn", value); + bool add_zero_attn = (bool)value; + layer->get_int_property("apply_rotary_embedding", value); + bool apply_rotary_embedding = (bool)value; + layer->get_int_property("scaling_query", value); + bool scaling_query = (bool)value; + float scaling_factor; + layer->get_float_property("scaling_factor", scaling_factor); + layer->get_int_property("qk_prod_scaling", value); + bool qk_prod_scaling = (bool)value; + layer->get_int_property("position_bias", value); + bool position_bias = (bool)value; + + layer->get_int_property("quantization_type", value); + DataType quantization_type = (DataType)value; + layer->get_int_property("offload", value); + bool offload = (bool)value; + layer->get_int_property("tensor_parallelism_degree", value); + int tensor_parallelism_degree = (int)value; + + return new IncMultiHeadSelfAttention(model, + layer->layer_guid, + inputs[0], + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + false /*allocate_weights*/, + quantization_type, + offload, + tensor_parallelism_degree, + layer->name); +} + +IncMultiHeadSelfAttention::IncMultiHeadSelfAttention( + FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1), /*weights*/ + 1 /*outputs*/, + _input), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias), + quantization_type(_quantization_type), offload(_offload), + tensor_parallelism_degree(_tensor_parallelism_degree) { + // overwrite layer_guid + layer_guid = _layer_guid; + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + size_t x = 1; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + x *= _input->dims[i].size; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + + if (quantization_type != DT_NONE) { + dims[1].size = get_quantization_to_byte_size( + data_type, quantization_type, (qParas + kParas + vParas + oParas)); + } + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>( + dims, + quantization_type == DT_NONE ? this->data_type : quantization_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* // Check correctness */ + /* assert(check_output_input_weight_parallel_dims()); */ +} + +IncMultiHeadSelfAttention::IncMultiHeadSelfAttention( + FFModel &model, + const ParallelTensor _input, + const ParallelTensor _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1), /*weights*/ + 1 /*outputs*/, + _input, + _weight), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias), + quantization_type(_quantization_type), offload(_offload), + tensor_parallelism_degree(_tensor_parallelism_degree) +// bias_initializer(_bias_initializer) +{ + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + // dims[2].size = this->num_q_heads * (qParas + oParas) + this->num_kv_heads + // * (kParas + vParas); + if (quantization_type != DT_NONE) { + dims[1].size = get_quantization_to_byte_size( + data_type, quantization_type, (qParas + kParas + vParas + oParas)); + } + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>( + dims, + quantization_type == DT_NONE ? this->data_type : quantization_type, + NULL /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* register_output_weight_parallel_dims(outputs[0], numdim-1, _weight, 1); */ + /* register_output_weight_parallel_dims(outputs[0], numdim-2, _weight, 2); */ + // Check correctness + /* assert(check_output_input_weight_parallel_dims()); */ +} + +IncMultiHeadSelfAttention::IncMultiHeadSelfAttention( + FFModel &model, + IncMultiHeadSelfAttention const &other, + const ParallelTensor input, + bool allocate_weights) + : IncMultiHeadSelfAttention(model, + other.layer_guid, + input, + other.oProjSize, + other.num_q_heads, + other.num_kv_heads, + other.qProjSize, + other.vProjSize, + other.dropout, + other.qkv_bias, + other.final_bias, + other.add_zero_attn, + other.apply_rotary_embedding, + other.scaling_query, + other.scaling_factor, + other.qk_prod_scaling, + other.position_bias, + allocate_weights, + other.quantization_type, + other.offload, + other.tensor_parallelism_degree, + other.name) {} + +IncMultiHeadSelfAttention::IncMultiHeadSelfAttention( + FFModel &model, + IncMultiHeadSelfAttentionParams const ¶ms, + ParallelTensor const &input, + bool allocate_weights, + char const *name) + : IncMultiHeadSelfAttention(model, + params.layer_guid, + input, + params.embed_dim, + params.num_q_heads, + params.num_kv_heads, + params.kdim, + params.vdim, + params.dropout, + params.qkv_bias, + params.final_bias, + params.add_zero_attn, + params.apply_rotary_embedding, + params.scaling_query, + params.scaling_factor, + params.qk_prod_scaling, + params.position_bias, + allocate_weights, + params.quantization_type, + params.offload, + params.tensor_parallelism_degree, + params.name) {} + +void IncMultiHeadSelfAttention::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(IncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void IncMultiHeadSelfAttention::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(IncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +/* + regions[0](I): input + regions[1](I): weight + regions[2](O): output +*/ +OpMeta *IncMultiHeadSelfAttention::init_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + IncMultiHeadSelfAttention const *attn = + (IncMultiHeadSelfAttention *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + + GenericTensorAccessorR input = + helperGetGenericTensorAccessorRO(attn->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR weight = + helperGetGenericTensorAccessorRO(attn->weights[0]->data_type, + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorW output = + helperGetGenericTensorAccessorWO(attn->outputs[0]->data_type, + regions[2], + task->regions[2], + FID_DATA, + ctx, + runtime); + + int num_samples = input.domain.hi()[2] - input.domain.lo()[2] + 1; + assert(attn->qoSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + assert(attn->kvSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + int num_q_heads = attn->num_q_heads / attn->tensor_parallelism_degree; + int num_kv_heads = + attn->num_kv_heads / attn->tensor_parallelism_degree + + (attn->num_kv_heads % attn->tensor_parallelism_degree != 0); + + assert(attn->oProjSize == output.domain.hi()[0] - output.domain.lo()[0] + 1); + + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + if (attn->offload) { + // cpu-offload enabled + // use offload_reserved_space + gpu_mem_allocator.register_reserved_work_space( + handle.offload_reserve_space, handle.offload_reserve_space_size); + } + IncMultiHeadSelfAttentionMeta *m = + new IncMultiHeadSelfAttentionMeta(handle, + attn, + weight, + gpu_mem_allocator, + num_samples, + num_q_heads, + num_kv_heads); + if (handle.offload_reserve_space == nullptr) { + // assert that we didn't over allocate memory + assert(gpu_mem_allocator.reserved_allocated_size == + gpu_mem_allocator.reserved_total_size); + } + m->profiling = attn->profiling; + m->inference_debugging = attn->inference_debugging; + std::strcpy(m->op_name, attn->name); + m->layer_guid = attn->layer_guid; + if (attn->quantization_type == DT_NONE) { + assert(weight.domain.get_volume() * data_type_size(weight.data_type) == + m->weightSize); + } + + return m; +} + +void IncMultiHeadSelfAttention::forward(FFModel const &ff) { + // IncMultiHeadSelfAttention doesn't support forward + assert(false); +} + +FutureMap IncMultiHeadSelfAttention::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + int idx = 0; + // log_inc_mha.debug("BatchConfig, num_tokens: %d, num_requests: %d", + // bc->num_tokens, + // bc->num_active_requests()); + IndexLauncher launcher(INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + + if (qkv_bias || final_bias) { + launcher.add_region_requirement( + RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(idx++, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input + regions[3](I): weight + regions[4](O): output +*/ +void IncMultiHeadSelfAttention::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + assert(task->regions.size() == regions.size()); + + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + log_inc_mha.debug("BatchConfig, num_tokens: %d, num_requests: %d", + bc->num_tokens, + bc->num_active_requests()); + if (bc->num_tokens == 0) { + return; + } + + IncMultiHeadSelfAttentionMeta *m = + *((IncMultiHeadSelfAttentionMeta **)task->local_args); + + assert(((*m->qkv_bias || *m->final_bias) ? regions.size() == 4 + : regions.size() == 3)); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + biases = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + Domain bias_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + assert(bias_domain.get_dim() == 4); + } + + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain weight_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + + assert(input_domain.get_dim() == 4); + assert(weight_domain.get_dim() == 2); + assert(output_domain.get_dim() == 4); + + assert(task->index_point.get_dim() == 1); + + IncMultiHeadSelfAttention::inference_kernel_wrapper( + m, bc, task->index_point.point_data[0], input, weight, output, biases); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + weights_accessors.push_back(weight); + if (*m->qkv_bias || *m->final_bias) { + weights_accessors.push_back(biases); + } + IncMultiHeadSelfAttention::save_inference_tensors_to_file( + m, shard_id, bc, {input}, weights_accessors, {output}); + } +} + +void IncMultiHeadSelfAttention::backward(FFModel const &ff) { + // IncMultiHeadSelfAttention does not support backward + assert(false); +} + +bool IncMultiHeadSelfAttention::get_int_parameter(PMParameter para, + int *value) const { + switch (para) { + case PM_NUM_HEADS: + *value = num_q_heads; + return true; + default: + return Op::get_int_parameter(para, value); + } +} + +bool IncMultiHeadSelfAttention::measure_operator_cost( + Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const { + return false; +} + +bool operator==(IncMultiHeadSelfAttentionParams const &lhs, + IncMultiHeadSelfAttentionParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.embed_dim == rhs.embed_dim && + lhs.num_q_heads == rhs.num_q_heads && lhs.kdim == rhs.kdim && + lhs.vdim == rhs.vdim && lhs.dropout == rhs.dropout && + lhs.qkv_bias == rhs.qkv_bias && lhs.final_bias == rhs.final_bias && + lhs.add_zero_attn == rhs.add_zero_attn && + lhs.apply_rotary_embedding == rhs.apply_rotary_embedding && + lhs.scaling_query == rhs.scaling_query && + lhs.scaling_factor == rhs.scaling_factor && + lhs.qk_prod_scaling == rhs.qk_prod_scaling && + lhs.position_bias == rhs.position_bias; +} + +IncMultiHeadSelfAttentionParams IncMultiHeadSelfAttention::get_params() const { + IncMultiHeadSelfAttentionParams params; + params.layer_guid = this->layer_guid; + params.embed_dim = this->oProjSize; + params.num_q_heads = this->num_q_heads; + params.kdim = this->kProjSize; + params.vdim = this->vProjSize; + params.dropout = this->dropout; + params.qkv_bias = this->qkv_bias; + params.final_bias = this->final_bias; + params.add_zero_attn = this->add_zero_attn; + params.apply_rotary_embedding = this->apply_rotary_embedding; + params.scaling_query = this->scaling_query; + params.scaling_factor = this->scaling_factor; + params.qk_prod_scaling = this->qk_prod_scaling; + params.position_bias = this->position_bias, + params.tensor_parallelism_degree = this->tensor_parallelism_degree, + params.quantization_type = this->quantization_type; + params.offload = this->offload; + params.num_kv_heads = this->num_kv_heads; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + + return params; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::IncMultiHeadSelfAttentionParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.embed_dim); + hash_combine(key, params.num_q_heads); + hash_combine(key, params.num_kv_heads); + hash_combine(key, params.kdim); + hash_combine(key, params.vdim); + hash_combine(key, params.dropout); + hash_combine(key, params.qkv_bias); + hash_combine(key, params.final_bias); + hash_combine(key, params.add_zero_attn); + hash_combine(key, params.apply_rotary_embedding); + hash_combine(key, params.scaling_query); + hash_combine(key, params.scaling_factor); + hash_combine(key, params.qk_prod_scaling); + hash_combine(key, params.position_bias); + hash_combine(key, params.quantization_type); + hash_combine(key, params.offload); + hash_combine(key, params.tensor_parallelism_degree); + return key; +} +}; // namespace std diff --git a/src/ops/inc_multihead_self_attention.cpp b/src/ops/inc_multihead_self_attention.cpp new file mode 100644 index 0000000000..d60386f927 --- /dev/null +++ b/src/ops/inc_multihead_self_attention.cpp @@ -0,0 +1,1101 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/decompress_kernels.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/utils/hip_helper.h" +#include +#include + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +namespace Kernels { +namespace IncMultiHeadAttention { + +// only used by MPT model. https://arxiv.org/abs/2108.12409 +template +__global__ void apply_position_bias_qkprd(DT *input_ptr, + int num_tokens, + int num_total_tokens, + int num_heads, + int global_num_q_heads, + int shard_id) { + CUDA_KERNEL_LOOP(i, num_tokens * num_total_tokens * num_heads) { + // get head_idx, + int head_idx = i / (num_tokens * num_total_tokens) + (num_heads * shard_id); + int position_idx = (i / num_tokens) % num_total_tokens; + position_idx = position_idx + 1 - num_total_tokens; + // 8 is alibi_bias_max in + // https://huggingface.co/mosaicml/mpt-30b/blob/main/config.json + float base = (float)(head_idx + 1) * 8 / global_num_q_heads; + float slopes = 1.0 / pow(2, base); + // if(i == 0){ + // printf("see position: %d, %f, %f, %f\n", position_idx, base, slopes, + // position_idx * slopes); + // } + input_ptr[i] += static_cast
(position_idx * slopes); + } +} + +template +__global__ void apply_proj_bias_w(DT *input_ptr, + DT const *bias_ptr, + int num_tokens, + int qkv_weight_size, + int oProjSize) { + CUDA_KERNEL_LOOP(i, num_tokens * oProjSize) { + int bias_idx = qkv_weight_size + i % oProjSize; + input_ptr[i] += bias_ptr[bias_idx]; + } +} + +template +__global__ void apply_proj_bias_qkv(DT *input_ptr, + DT const *bias_ptr, + int shard_id, + int num_tokens, + int qProjSize, + int kProjSize, + int vProjSize, + int global_num_q_heads, + int num_q_heads, + bool scaling_query, + float scaling_factor, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size * QKV_WEIGHT_NUM) { + // for simplicity, assume q, k, v is in same shape + // 0->q, 1->k, 2->v + // int qkv_index = i / (num_tokens * qProjSize) % 3; + + int token_idx = i / (hidden_size * QKV_WEIGHT_NUM); + size_t in_token_idx = i - token_idx * hidden_size * 3; + int qkv_index = in_token_idx / hidden_size; + int proj_size = qkv_index == 0 ? qProjSize : kProjSize; + + int head_idx = + (in_token_idx - qkv_index * num_q_heads * proj_size) / proj_size; + int global_head_idx = head_idx + shard_id * num_q_heads; + + size_t pre_length = + qkv_index == 0 + ? 0 + : (qkv_index == 1 ? qProjSize * global_num_q_heads + : qProjSize * global_num_q_heads * KV_WEIGHT_NUM); + + size_t bias_idx = pre_length + global_head_idx * proj_size + i % proj_size; + + input_ptr[i] += bias_ptr[bias_idx]; + + if (scaling_query && qkv_index == 0) { + input_ptr[i] *= scaling_factor; + } + } +} +template +__global__ void scaling_query_kernel(DT *input_ptr, + int qProjSize, + int num_tokens, + int num_q_heads, + float scaling_factor, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + int token_idx = i / hidden_size; + input_ptr[i % hidden_size + token_idx * hidden_size * QKV_WEIGHT_NUM] *= + scaling_factor; + } +} + +template +__global__ void + apply_rotary_embedding_native(DT *input_ptr, + hipFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_q_heads, + int num_tokens, + int num_kv_heads, + int q_block_size, + int k_block_size, + int q_array_size) { + CUDA_KERNEL_LOOP( + i, + num_tokens * (qProjSize * num_q_heads + kProjSize * num_kv_heads) / 2) { + // create complex number + bool q_tensor = i < (q_array_size / 2); + int proj_size = q_tensor ? qProjSize : kProjSize; + int real_i = q_tensor ? i : i - q_array_size / 2; + + int head_idx = real_i / (num_tokens * proj_size / 2); + int idx = real_i % (num_tokens * proj_size / 2); + int real_part_index = idx * 2 + + head_idx * (q_tensor ? q_block_size : k_block_size) + + (q_tensor ? 0 : q_array_size); + + int complex_part_index = real_part_index + 1; + + complex_input[i] = {input_ptr[real_part_index], + input_ptr[complex_part_index]}; + + int token_idx = + (real_i - head_idx * (num_tokens * proj_size / 2)) / (proj_size / 2); + size_t pos = tokenInfos[token_idx].abs_depth_in_request; + int pos_i = real_i % (proj_size / 2); + float freq = pos * (1.0 / pow(10000.0, (float)2 * pos_i / proj_size)); + hipFloatComplex complex_pos = {cos(freq), sin(freq)}; + + complex_input[i] = hipCmulf(complex_input[i], complex_pos); + input_ptr[real_part_index] = complex_input[i].x; + input_ptr[complex_part_index] = complex_input[i].y; + } +} + +template +__global__ void + apply_rotary_embedding_hf(DT *input_ptr, + hipFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_tokens, + size_t q_array_size, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + // create complex number + bool q_tensor = i < (q_array_size / 2); + int proj_size = q_tensor ? qProjSize : kProjSize; + int real_i = q_tensor ? i : i - q_array_size / 2; + + int token_idx = real_i / (hidden_size / 2); + int idx = real_i % (proj_size / 2); + int head_idx = (real_i - (token_idx * (hidden_size / 2))) / (proj_size / 2); + + int real_part_index = idx + head_idx * proj_size + + token_idx * hidden_size * 3 + + hidden_size * (q_tensor ? 0 : 1); + int complex_part_index = real_part_index + (proj_size / 2); + + complex_input[i] = {input_ptr[real_part_index], + input_ptr[complex_part_index]}; + + // get the freq_cis: shape 1 * (qProjSize/2) = 1 * 64 + // apply a Cartesian coordinate transformation + // multiple with input & /copy back to q/k + + // get position of token + + // size_t pos = id_map[token_idx].token_position; + size_t pos = tokenInfos[token_idx].abs_depth_in_request; + + // float before_real = complex_input[i].x, before_complex = + int pos_i = real_i % (proj_size / 2); + float freq = pos * (1.0 / pow(10000.0, (float)2 * pos_i / proj_size)); + hipFloatComplex complex_pos = {cos(freq), sin(freq)}; + + complex_input[i] = hipCmulf(complex_input[i], complex_pos); + input_ptr[real_part_index] = complex_input[i].x; + input_ptr[complex_part_index] = complex_input[i].y; + } +} + +template +__global__ void store_kv_cache(DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + BatchConfig::PerTokenInfo const *tokenInfos, + int num_tokens, + int max_seq_len, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + int token_idx = i / hidden_size; + int offset = i % hidden_size; + size_t val_idx = token_idx * 3 * hidden_size + hidden_size + offset; + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = tokenInfos[token_idx].request_index; + int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + + // key cache + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +void compute_qkv_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + hipStream_t stream) { + + checkCUDA(hipblasSetStream(m->handle.blas, stream)); + checkCUDNN(miopenSetStream(m->handle.dnn, stream)); + DT alpha = 1.0f, beta = 0.0f; + assert(m->qSize == m->vSize && m->qSize == m->kSize); + hipblasDatatype_t hipblas_data_type = ff_to_cuda_datatype(m->output_type[0]); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = hipblas_data_type; +#else + // TODO: currently use the hipblas_data_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = hipblas_data_type; +#endif + // Compute (W^T)x matmul: einsum(ijkl,im->jmkl) + // Weights: qSize x qProjSize x 3 x num_q_heads + // Input: qSize x num_tokens + // Output >>> qProjSize x num_tokens x 3 x num_q_heads + int m_q = m->qProjSize * m->num_q_heads; + int m_k = m->kProjSize * m->num_q_heads; + int m_v = m->vProjSize * m->num_q_heads; + assert(m_q == m_k && m_k == m_v); // keep things simple for now + int n = bc->num_active_tokens(); + int k = m->qSize; + int m_ = m_q * QKV_WEIGHT_NUM; + int lda = k, ldb = k, ldc = m_; + checkCUDA(hipblasGemmEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_N, + m_, + n, + k, + &alpha, + weight_ptr, + hipblas_data_type, + lda, + input_ptr, + hipblas_data_type, + ldb, + &beta, + output_ptr, + hipblas_data_type, + ldc, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + // apply rotary emmmbedding for q and k + // step1 change the k, v to complex tensor + int num_tokens = bc->num_active_tokens(); + int parallelism = m->kProjSize * num_tokens * m->num_q_heads; + size_t q_array_size = m->qProjSize * num_tokens * m->num_q_heads; + // apply bias for q, k, v + if (*m->qkv_bias) { + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_proj_bias_qkv
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + bias_ptr, + shard_id, + num_tokens, + m->qProjSize, + m->kProjSize, + m->vProjSize, + m->global_num_q_heads, + m->num_q_heads, + *m->scaling_query, + m->scaling_factor, + m->hidden_size); + } else if (m->scaling_query) { + hipLaunchKernelGGL(HIP_KERNEL_NAME(scaling_query_kernel
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + num_tokens, + m->num_q_heads, + m->qProjSize, + m->scaling_factor, + m->hidden_size); + } + if (*m->apply_rotary_embedding) { + /*q&k*/ + parallelism = num_tokens * m->hidden_size; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_rotary_embedding_hf
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + m->complex_input, + m->token_infos, + m->qProjSize, + m->kProjSize, + num_tokens, + q_array_size, + m->hidden_size); + } +} + +template +void update_kv_cache_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + hipStream_t stream) { + int num_tokens = bc->num_active_tokens(); + if (num_tokens > 0) { + int parallelism = m->hidden_size * num_tokens; + hipLaunchKernelGGL(HIP_KERNEL_NAME(store_kv_cache
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + num_tokens, + BatchConfig::max_sequence_length(), + m->hidden_size); + } +} + +template +void pre_build_weight_kernel(IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + hipStream_t stream) { + // additional processing for weight uploading + // Note that we update weight_ptr and bias_ptr when uploading weight and + // bias + if (m->quantization_type != DT_NONE) { + // copy weight_ptr to quantized_weight_ptr, do compression and store in + // m->weight_ptr + checkCUDA(hipMemcpyAsync(m->quantized_weight_ptr, + weight.get_byte_ptr(), + m->quantized_weightSize, + hipMemcpyHostToDevice, + stream)); + + if (m->quantization_type == DT_INT4) { + int parallelism = m->qProjSize * m->qSize * m->num_q_heads / 2; + decompress_int4_attention_weights<<>>( + m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + m->qProjSize, + m->qSize, + m->num_q_heads); + } else { + assert(m->quantization_type == DT_INT8); + int parallelism = m->qProjSize * m->qSize * m->num_q_heads; + decompress_int8_attention_weights<<>>( + m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + m->qProjSize, + m->qSize, + m->num_q_heads); + } + } else { + if (data_type == DT_FLOAT) { + checkCUDA(hipMemcpyAsync(m->weight_ptr, + weight.get_float_ptr(), + m->weightSize, + hipMemcpyHostToDevice, + stream)); + } else if (data_type == DT_HALF) { + checkCUDA(hipMemcpyAsync(m->weight_ptr, + weight.get_half_ptr(), + m->weightSize, + hipMemcpyHostToDevice, + stream)); + } else { + assert(false); + } + } +} + +template +void inference_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + hipStream_t stream) { + // here because we need postion info in infernece 1 + + if (m->offload && m->biasSize > 0) { + checkCUDA(hipMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, hipMemcpyHostToDevice, stream)); + bias_ptr = static_cast
(m->bias_ptr); + } + checkCUDA(hipMemcpyAsync(m->token_infos, + &(bc->tokensInfo), + bc->num_active_tokens() * + sizeof(BatchConfig::PerTokenInfo), + hipMemcpyHostToDevice, + stream)); + // phase 1: Implement kernel to compute KQV for input tokens + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + + // phase 2: Update key/val cache + update_kv_cache_kernel
(m, bc, stream); + + // phase 3: Compute attention score + // 3 kernels for pahse 3: matmul1 - softmax - matmal2 + compute_attention_kernel( + m, bc, shard_id, output_ptr, bias_ptr, weight_ptr, stream); +} + +} // namespace IncMultiHeadAttention +} // namespace Kernels + +using namespace Kernels::IncMultiHeadAttention; + +template +__global__ void fill_entries_above_diagonal(DT *matrix, + size_t num_rows, + size_t num_cols, + size_t num_q_heads, + size_t entries_above_diagonal, + DT value) { + CUDA_KERNEL_LOOP(i, entries_above_diagonal * num_q_heads) { + size_t head_idx = i / entries_above_diagonal; + size_t entry_idx = i % entries_above_diagonal; + size_t y = (-1 + sqrt(8 * (float)entry_idx + 1)) / 2; + size_t x = entry_idx - y * (y + 1) / 2; + y += (num_cols - num_rows) + 1; + matrix[head_idx * num_rows * num_cols + num_cols * y + x] = value; + } +} + +template +void compute_attention_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *bias_ptr, + DT const *weight_ptr, + hipStream_t stream) { + checkCUDA(hipblasSetStream(m->handle.blas, stream)); + checkCUDNN(miopenSetStream(m->handle.dnn, stream)); + hipblasDatatype_t hipblas_data_type = ff_to_cuda_datatype(m->output_type[0]); + miopenDataType_t miopen_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = hipblas_data_type; +#else + // TODO: currently use the hipblas_data_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = hipblas_data_type; +#endif + // int num_requests = bc->num_active_requests(); + int num_tokens = bc->num_active_tokens(); + int tokens_previous_requests = 0; + int q_block_size = m->qProjSize; + int kt_block_size = m->kProjSize; + int kt_req_block_size = + kt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + int vt_block_size = m->vProjSize; + int vt_req_block_size = + vt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + int total_tokens = bc->requestsInfo[i].first_token_depth_in_request + + bc->requestsInfo[i].num_tokens_in_batch; + // bc->token_last_available_idx[i] + 1; + // Compute (QK^T/sqrt(d_k)) + // a flag of using this scaling alpha + int m_ = num_new_tokens; + int n = total_tokens; + int k = m->qProjSize; + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens; + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // To get A, skip over Q entries from previous requests (same head) + DT const *A = static_cast
(m->devQKVProjArray) + + tokens_previous_requests * m->qProjSize * m->num_q_heads * + QKV_WEIGHT_NUM; + // To get B, skip over K entries from previous requests (all heads + + // padding) + DT const *B = static_cast
(m->keyCache) + i * kt_req_block_size; + // To get C, skip over QK^T products from previous requests + DT *C = static_cast
(m->qk_prods); + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + // add alibi position bias to qk production + if (*m->position_bias) { + size_t parallelism = m->num_q_heads * total_tokens * num_new_tokens; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_position_bias_qkprd
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + // Fill all elements above diagonal in qk prods with -inf to force + // causal attention. + assert(num_new_tokens <= total_tokens); + size_t entries_above_diagonal = num_new_tokens * (num_new_tokens - 1) / 2; + if (entries_above_diagonal > 0) { + size_t parallelism = m->num_q_heads * entries_above_diagonal; + hipLaunchKernelGGL(HIP_KERNEL_NAME(fill_entries_above_diagonal
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens, + m->num_q_heads, + entries_above_diagonal, + static_cast
(-INFINITY)); + } + // Compute Softmax(QK^T/sqrt(d_k)) + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(miopenSet4dTensorDescriptor( + m->qk_tensor, miopen_data_type, n_param, c_param, h_param, w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax); + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(miopenSoftmaxForward_V2(m->handle.dnn, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax, + MIOPEN_SOFTMAX_ACCURATE, + MIOPEN_SOFTMAX_MODE_CHANNEL)); + // Matmul softmax(QK^T/sqrt(d_k)) by V + alpha = 1.0f, beta = 0.0f; + m_ = num_new_tokens; + n = m->vProjSize; + k = total_tokens; + lda = m_, ldb = n * m->num_q_heads, ldc = m_; + strideA = num_new_tokens * total_tokens; + strideB = vt_block_size; + strideC = num_new_tokens * m->vProjSize; + // To get A, skip over softmax(QK^T/sqrt(d_k)) entries from previous + // requests (all heads) + A = C_softmax; + // To get B, skip over V^T entries from previous requests (all heads + + // padding) + B = static_cast
(m->valueCache) + i * vt_req_block_size; + // To get C, skip over softmax(QK^T/sqrt(d_k))V products from previous + // requests + C = static_cast
(m->attn_heads) + + tokens_previous_requests * m->num_q_heads * m->vProjSize; + + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_N, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + // Project to output, save result directly on output tensor + alpha = 1.0f, beta = 0.0f; + m_ = m->oProjSize; + k = m->vProjSize * m->num_q_heads; + n = num_new_tokens; + lda = k, ldb = n, ldc = m_; + A = weight_ptr + m->qSize * (m->qProjSize * m->num_q_heads + + m->kProjSize * m->num_q_heads + + m->vProjSize * m->num_q_heads); + B = C; + C = static_cast
(output_ptr) + tokens_previous_requests * m->oProjSize; + + checkCUDA(hipblasGemmEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + B, + hipblas_data_type, + ldb, + &beta, + C, + hipblas_data_type, + ldc, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + tokens_previous_requests += num_new_tokens; + } + + if (*m->final_bias && shard_id == 0) { + int parallelism = m->oProjSize * num_tokens; + int qkv_weight_size = m->qProjSize * m->global_num_q_heads + + m->kProjSize * m->global_num_q_heads + + m->vProjSize * m->global_num_q_heads; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_proj_bias_w
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + bias_ptr, + num_tokens, + qkv_weight_size, + m->oProjSize); + } + + assert(tokens_previous_requests == num_tokens); +} + +/*static*/ +void IncMultiHeadSelfAttention::inference_kernel_wrapper( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + // assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::IncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_half_ptr(), + m->offload ? static_cast(m->weight_ptr) : weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::IncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_float_ptr(), + m->offload ? static_cast(m->weight_ptr) + : weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("IncMultiHeadSelfAttention forward time = %.2fms\n", elapsed); + // print_tensor<3, float>(acc_query.ptr, acc_query.rect, + // "[Attention:forward:query]"); print_tensor<3, float>(acc_output.ptr, + // acc_output.rect, "[Attention:forward:output]"); + } +} + +IncMultiHeadSelfAttentionMeta::IncMultiHeadSelfAttentionMeta( + FFHandler handler, + IncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + INC_DECODING_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + attn->quantization_type, + attn->offload) {} + +IncMultiHeadSelfAttentionMeta::IncMultiHeadSelfAttentionMeta( + FFHandler handler, + InferenceMode infer_mode, + Op const *attn, + int _qSize, + int _kSize, + int _vSize, + int _qProjSize, + int _kProjSize, + int _vProjSize, + int _oProjSize, + bool _apply_rotary_embedding, + bool _qkv_bias, + bool _scaling_query, + bool _qk_prod_scaling, + bool _position_bias, + bool _final_bias, + float _scaling_factor, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _global_num_q_heads, + int _global_num_kv_heads, + int _num_q_heads, + int _num_kv_heads, + DataType _quantization_type, + bool _offload) + : OpMeta(handler, attn), weight_ptr(nullptr), bias_ptr(nullptr) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(miopenSetStream(handler.dnn, stream)); + checkCUDNN(miopenCreateTensorDescriptor(&qk_tensor)); + qSize = _qSize; + kSize = _kSize; + vSize = _vSize; + // assume dimensions match for now + assert(qSize == kSize); + assert(kSize == vSize); + qProjSize = _qProjSize; + kProjSize = _kProjSize; + assert(qProjSize == kProjSize); // required for attention QK^T matmul + vProjSize = _vProjSize; + oProjSize = _oProjSize; + size_t size_of_dt = data_type_size(attn->data_type); + quantization_type = _quantization_type; + offload = _offload; + + global_num_q_heads = _global_num_q_heads; + global_num_kv_heads = _global_num_kv_heads; + num_q_heads = _num_q_heads; + num_kv_heads = _num_kv_heads; + hidden_size = num_q_heads * qProjSize; + + weightSize = + ((qSize * qProjSize + oProjSize * (vProjSize > 0 ? vProjSize : vSize)) * + num_q_heads + + (kSize * kProjSize + vSize * vProjSize) * num_q_heads) * + size_of_dt; + if (quantization_type != DT_NONE) { + quantized_weightSize = get_quantization_to_byte_size( + attn->data_type, quantization_type, weightSize); + } + // biasSize = _bias ? oProjSize * size_of_dt * 4 : 0; + + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + int final_bias_size = oProjSize; + biasSize = + (_qkv_bias ? qkv_bias_size : 0) + (final_bias ? final_bias_size : 0); + + // has_load_weights = (bool *)calloc(1, sizeof(bool)); + //*has_load_weights = false; + apply_rotary_embedding = (bool *)calloc(1, sizeof(bool)); + *apply_rotary_embedding = _apply_rotary_embedding; + qkv_bias = (bool *)calloc(1, sizeof(bool)); + *qkv_bias = _qkv_bias; + scaling_query = (bool *)calloc(1, sizeof(bool)); + *scaling_query = _scaling_query; + scaling_factor = _scaling_factor; + qk_prod_scaling = (bool *)calloc(1, sizeof(bool)); + *qk_prod_scaling = _qk_prod_scaling; + position_bias = (bool *)calloc(1, sizeof(bool)); + *position_bias = _position_bias; + final_bias = (bool *)calloc(1, sizeof(bool)); + *final_bias = _final_bias; + + // allocate weight and bias in the reserve space for cpu offloading + if (offload) { + weight_ptr = gpu_mem_allocator.allocate_reserved_untyped(weightSize); + bias_ptr = gpu_mem_allocator.allocate_reserved_untyped(biasSize); + } + + // allocate memory for the seqArray and reserve space + { + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + size_t qkv_max_proj_size = max_tokens_per_batch * (qProjSize * num_q_heads + + kProjSize * num_q_heads + + vProjSize * num_q_heads); + size_t key_cache_size = 0, value_cache_size = 0; + switch (infer_mode) { + case INC_DECODING_MODE: + case TREE_VERIFY_MODE: { + key_cache_size = num_q_heads * kProjSize * + BatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length(); + value_cache_size = num_q_heads * vProjSize * + BatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length(); + break; + } + case BEAM_SEARCH_MODE: { + key_cache_size = num_q_heads * kProjSize * + BeamSearchBatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length() * + BeamSearchBatchConfig::MAX_BEAM_WIDTH; + value_cache_size = num_q_heads * vProjSize * + BeamSearchBatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length() * + BeamSearchBatchConfig::MAX_BEAM_WIDTH; + break; + } + default: + assert(false && "Unkown inference mode"); + } + size_t tokeninfo_size = max_tokens_per_batch; + size_t qk_prod_size = + max_tokens_per_batch * BatchConfig::max_sequence_length() * num_q_heads; + size_t attn_heads_size = max_tokens_per_batch * num_q_heads * vProjSize; + size_t complex_size = (max_tokens_per_batch * (qProjSize * num_q_heads + + kProjSize * num_q_heads)) / + 2; + size_t totalSize = + (qkv_max_proj_size + key_cache_size + value_cache_size + + 2 * qk_prod_size + attn_heads_size) * + size_of_dt + + tokeninfo_size * sizeof(BatchConfig::PerTokenInfo) + + complex_size * sizeof(hipFloatComplex); // more components will + // be added here later + if (offload) { + // assert that we have enough reserved work space left + size_t totalSharedSize = + infer_mode == TREE_VERIFY_MODE + ? totalSize - + (key_cache_size + value_cache_size + qkv_max_proj_size) * + size_of_dt + : totalSize - (key_cache_size + value_cache_size) * size_of_dt; + + size_t instance_size = + size_of_dt * + (infer_mode == TREE_VERIFY_MODE + ? key_cache_size + value_cache_size + qkv_max_proj_size + : key_cache_size + value_cache_size); + + if (quantization_type != DT_NONE) { + totalSharedSize += quantized_weightSize; + } + assert(gpu_mem_allocator.reserved_total_size - + gpu_mem_allocator.reserved_allocated_size >= + totalSharedSize); + gpu_mem_allocator.create_legion_instance(reserveInst, instance_size); + } else { + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + } + + // in tree_verify, enable devQKVProjArray; + if (!offload || infer_mode == TREE_VERIFY_MODE) { + devQKVProjArray = gpu_mem_allocator.allocate_instance_untyped( + qkv_max_proj_size * size_of_dt); + } else { + devQKVProjArray = gpu_mem_allocator.allocate_reserved_untyped( + qkv_max_proj_size * size_of_dt); + // offset += qkv_max_proj_size * size_of_dt; + } + + // use key value cache in all mode. + keyCache = gpu_mem_allocator.allocate_instance_untyped(key_cache_size * + size_of_dt); + valueCache = gpu_mem_allocator.allocate_instance_untyped(value_cache_size * + size_of_dt); + + if (offload) { + token_infos = + gpu_mem_allocator.allocate_reserved( + tokeninfo_size); + // offset += sizeof(BatchConfig::PerTokenInfo) * tokeninfo_size; + qk_prods = gpu_mem_allocator.allocate_reserved_untyped(qk_prod_size * + size_of_dt); + // offset += qk_prod_size * size_of_dt; + qk_prods_softmax = gpu_mem_allocator.allocate_reserved_untyped( + qk_prod_size * size_of_dt); + // offset += qk_prod_size * size_of_dt; + attn_heads = gpu_mem_allocator.allocate_reserved_untyped(attn_heads_size * + size_of_dt); + // offset += attn_heads_size * size_of_dt; + complex_input = + gpu_mem_allocator.allocate_reserved(complex_size); + // offset += complex_size * sizeof(hipFloatComplex); + } else { + token_infos = + gpu_mem_allocator.allocate_instance( + tokeninfo_size); + qk_prods = gpu_mem_allocator.allocate_instance_untyped(qk_prod_size * + size_of_dt); + qk_prods_softmax = gpu_mem_allocator.allocate_instance_untyped( + qk_prod_size * size_of_dt); + attn_heads = gpu_mem_allocator.allocate_instance_untyped(attn_heads_size * + size_of_dt); + complex_input = + gpu_mem_allocator.allocate_instance(complex_size); + } + + // allocate more size for quantization data + if (quantization_type != DT_NONE) { + assert(offload); + quantized_weight_ptr = + gpu_mem_allocator.allocate_reserved(quantized_weightSize); + } + if (!offload) { + assert(gpu_mem_allocator.reserved_total_size == + gpu_mem_allocator.reserved_allocated_size); + } + } + checkCUDA(hipStreamSynchronize(stream)); +} + +IncMultiHeadSelfAttentionMeta::~IncMultiHeadSelfAttentionMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template void Kernels::IncMultiHeadAttention::pre_build_weight_kernel( + IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + hipStream_t stream); + +template void Kernels::IncMultiHeadAttention::pre_build_weight_kernel( + IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + hipStream_t stream); + +}; // namespace FlexFlow diff --git a/src/ops/inc_multihead_self_attention.cu b/src/ops/inc_multihead_self_attention.cu new file mode 100644 index 0000000000..a0d31bb6ef --- /dev/null +++ b/src/ops/inc_multihead_self_attention.cu @@ -0,0 +1,1535 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "cuComplex.h" +#endif +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/inc_multihead_self_attention.h" +#include "flexflow/ops/kernels/decompress_kernels.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +#define WARP_SIZE 32 + +namespace Kernels { +namespace IncMultiHeadAttention { + +// gridDim = num_heads +// blockDim = num_tokens/num_request * head_size +// QKV tensor layout: |QKV| * num_new_tokens. |Q=K=V=head_size * num_heads| +// one thread process one head_size +template +__global__ void compute_attention_kernel_generation_kernel( + DT const *query, + DT const *key_cache, + DT const *value_cache, + DT *output_ptr, + float const scale, + int max_seq_length, + int per_head_size, + int hidden_size, + BatchConfig::PerRequestInfo *request_infos) { + + // q, k + using Q_vec = typename VEC_K::Type; + using K_vec = typename VEC_K::Type; + using V_vec = typename VEC_V
::Type; + using Out_sum = typename Vec_fp32_::Type; + + constexpr int WARPS_PER_BLOCK = THREADS_PER_BLOCK / WARP_SIZE; + + // eg. if head_size = 128, thread_per_key = 4, with float32 precision + // then K_VEC_SIZE = 1, QK_VEC_SIZE = 4 + // K_ELTS_PER_THREAD = 128 / 4 = 32 + // K_VECS_PER_THREAD = 32 / 1 = 32 + constexpr int K_VEC_SIZE = sizeof(K_vec) / sizeof(DT); + // constexpr int QK_VEC_SIZE = 16 / sizeof(DT); + // // constexpr int QK_VEC_SIZE = sizeof(Qk_vec_k) / sizeof(DT); + constexpr int K_ELTS_PER_THREAD = Dh / THREADS_PER_KEY; + constexpr int K_VECS_PER_THREAD = K_ELTS_PER_THREAD / K_VEC_SIZE; + // constexpr int QK_ELTS_IN_16B = 16 / sizeof(DT); + + // thread id + int const tidx = threadIdx.x; + // head id + int const head_idx = blockIdx.x; + // request idx + int const request_idx = blockIdx.y; + + int const batch_config_request_id = + request_infos[request_idx].batch_config_request_id; + + int const first_step = 0; + + int const tlength = + request_infos[batch_config_request_id].first_token_depth_in_request + + request_infos[batch_config_request_id].num_tokens_in_batch; + + // shared memory objects + extern __shared__ char smem_[]; + + float *qk_smem = reinterpret_cast(smem_); + float *out_smem = reinterpret_cast(smem_); + + float qk_max = -FLT_MAX; + + // first WARPS_PER_BLOCK for store qk_max, second WARPS_PER_BLOCK for sum + __shared__ float red_smem[WARPS_PER_BLOCK * 2]; + + const DT *q_ptr = query + request_idx * hidden_size * QKV_WEIGHT_NUM + + head_idx * per_head_size; + __shared__ Q_vec q_vecs[THREADS_PER_KEY][K_VECS_PER_THREAD]; + // DT const *q_ptr = + // query + request_idx * Dh * QKV_WEIGHT_NUM + head_idx * per_head_size; + + // q tensor in this thread + // if THREADS_PER_KEY is 4, first thread load 0, 4, 8, 12..., total + // K_VECS_PER_THREAD elements + // QK_vec_k: 32->1, 64->2, 128->4... head_size + // K_vec_k: 4->1, 2->2, 1->4 threads_per_key + + // the start offset of the element eg. (0, 1, 2, 3) * K_VEC_SIZE + int ki = tidx % THREADS_PER_KEY * K_VEC_SIZE; + int ki_o = tidx % THREADS_PER_KEY; + // the first key's offset for this thread + // ko = 0, 0, 0, 0, 1, 1, 1, 1, .... + int ko = tidx / THREADS_PER_KEY; + // load q tensor + Q_vec q_vec[K_VECS_PER_THREAD]; +#pragma unroll + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + q_vecs[ki_o][ii] = *reinterpret_cast( + q_ptr + ki + ii * THREADS_PER_KEY * K_VEC_SIZE); + } + __syncthreads(); + // first iter = 128 / 4 = 32 + // K_VECS_PER_THREAD = 32 + // K_PER_ITER how many keys in this loop + // The number of timesteps loaded per iteration. + constexpr int K_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_KEY; + // // The number of keys per warp. + constexpr int K_PER_WARP = WARP_SIZE / THREADS_PER_KEY; + + DT const *k_cache_batch = + key_cache + batch_config_request_id * max_seq_length * hidden_size + ki; + + int ti_end = + div_up(tlength - first_step, K_PER_WARP) * K_PER_WARP + first_step; + // get k, perform qk proj + + for (int ti = ko; ti < ti_end; ti += K_PER_ITER) { + K_vec k[K_VECS_PER_THREAD]; + int const ti_circ = ti % max_seq_length; +#pragma unroll + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + int jj = ii * THREADS_PER_KEY * K_VEC_SIZE; + if (ti < tlength) { + k[ii] = *reinterpret_cast(k_cache_batch + + ti_circ * hidden_size + + head_idx * per_head_size + jj); + } + // Compute dot product. + // This includes a reduction across the threads in the same thread group. + } + float qk = scale * Qk_dot::dot(q_vecs[ki_o], k); + // // todo add positional embedding to the qk production + // // Store the product to shared memory. There's one qk value per + // timestep. + // // Update the max. + if (ti < tlength && tidx % THREADS_PER_KEY == 0) { + // todo add alobi here + bool const mask = ti_circ >= tlength; + if (mask) { + assert(false); + } + qk_max = mask ? qk_max : fmaxf(qk_max, qk); + qk_smem[ti - first_step] = mask ? 0.f : qk; + } + } + + __syncthreads(); + +#pragma unroll + for (int mask = WARP_SIZE / 2; mask >= THREADS_PER_KEY; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Decompose the thread index into warp and lane. + int const warp = tidx / WARP_SIZE; + int const lane = tidx % WARP_SIZE; + + // The warp leader writes the max to shared memory. + if (lane == 0) { + red_smem[warp] = qk_max; + } + + // Make sure the products are in shared memory. + __syncthreads(); + + // The warps finalize the reduction. + qk_max = lane < WARPS_PER_BLOCK ? red_smem[lane] : -FLT_MAX; +#pragma unroll + for (int mask = WARPS_PER_BLOCK / 2; mask >= 1; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Broadcast to all the threads in the warp. + qk_max = __shfl_sync(uint32_t(-1), qk_max, 0); + + float exp_sum = 0.f; + for (int ti = first_step + tidx; ti < tlength; ti += THREADS_PER_BLOCK) { + float logit = __expf(qk_smem[ti - first_step] - qk_max); + exp_sum += logit; + qk_smem[ti - first_step] = logit; + } + + // Compute the sum. + exp_sum = block_sum(&red_smem[WARPS_PER_BLOCK], exp_sum); + + // softmax + float inv_sum = __fdividef(1.f, exp_sum + 1.e-6); + for (int ti = first_step + tidx; ti < tlength; ti += THREADS_PER_BLOCK) { + qk_smem[ti - first_step] *= inv_sum; + } + + __syncthreads(); + // if (blockIdx.y == 0 && blockIdx.x == 0 && tidx == 0) { + // printf("softmax %.10f\n", qk_smem[0]); + // } + + // value projection + constexpr int V_VEC_SIZE = 16 / sizeof(DT); + // A vector of V elements for the current timestep. + // using V_vec_k = typename V_vec_k_::Type; + // using V_vec_acum = typename V_vec_acum_fp32_::Type; + + // The value computed by this thread. + int vo = tidx / THREADS_PER_VALUE; + // The hidden dimensions computed by this particular thread. + int vi = tidx % THREADS_PER_VALUE * V_VEC_SIZE; + constexpr int V_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_VALUE; + + Out_sum out; + zero(out); + + // The base pointer for the value in the cache buffer. + DT const *v_cache_batch = + value_cache + batch_config_request_id * max_seq_length * hidden_size + vi; + + if (Dh == Dh_MAX || vi < Dh) { + for (int ti = first_step + vo; ti < tlength; ti += V_PER_ITER) { + // Load the values from the cache. + int const ti_circ = ti % max_seq_length; + + V_vec v = *reinterpret_cast( + v_cache_batch + ti_circ * hidden_size + head_idx * per_head_size); + float logit = qk_smem[ti - first_step]; + out = FlexFlow::fma(logit, cast_to_float(v), out); + } + } + + // // Make sure we can start writing to shared memory. + __syncthreads(); + + // Run the final reduction amongst the different groups computing different + // partial outputs. + if (Dh == Dh_MAX || vi < Dh) { +#pragma unroll + for (int active_groups = V_PER_ITER; active_groups >= 2; + active_groups /= 2) { + + // The midpoint in the number of active groups. + int midpoint = active_groups / 2; + + // The upper part of active threads store to shared memory. + if (vo >= midpoint && vo < active_groups && (Dh == Dh_MAX || vi < Dh)) { + *reinterpret_cast(out_smem + (vo - midpoint) * Dh + vi) = + out; + } + __syncthreads(); + + // The bottom warps update their values. + if (vo < midpoint && (Dh == Dh_MAX || vi < Dh)) { + out = add(*reinterpret_cast(out_smem + vo * Dh + vi), + out); + } + __syncthreads(); + } + } + + // Output the final values. + if (vo == 0 && (Dh == Dh_MAX || vi < Dh)) { + convert_from_float( + *reinterpret_cast(output_ptr + request_idx * hidden_size + + head_idx * per_head_size + vi), + out); + } +} + +// only used by MPT model. https://arxiv.org/abs/2108.12409 +template +__global__ void apply_position_bias_qkprd(DT *input_ptr, + int num_tokens, + int num_total_tokens, + int num_heads, + int global_num_q_heads, + int shard_id) { + CUDA_KERNEL_LOOP(i, num_tokens * num_total_tokens * num_heads) { + // get head_idx, + int head_idx = i / (num_tokens * num_total_tokens) + (num_heads * shard_id); + int position_idx = (i / num_tokens) % num_total_tokens; + position_idx = position_idx + 1 - num_total_tokens; + // 8 is alibi_bias_max in + // https://huggingface.co/mosaicml/mpt-30b/blob/main/config.json + float base = (float)(head_idx + 1) * 8 / global_num_q_heads; + float slopes = 1.0 / pow(2, base); + // if(i == 0){ + // printf("see position: %d, %f, %f, %f\n", position_idx, base, slopes, + // position_idx * slopes); + // } + input_ptr[i] += static_cast
(position_idx * slopes); + } +} + +template +__global__ void apply_proj_bias_w(DT *input_ptr, + DT const *bias_ptr, + int num_tokens, + int qkv_weight_size, + int oProjSize) { + CUDA_KERNEL_LOOP(i, num_tokens * oProjSize) { + int bias_idx = qkv_weight_size + i % oProjSize; + input_ptr[i] += bias_ptr[bias_idx]; + } +} + +template +__global__ void apply_proj_bias_qkv(DT *input_ptr, + DT const *bias_ptr, + int shard_id, + int num_tokens, + int qProjSize, + int kProjSize, + int vProjSize, + int global_num_q_heads, + int num_q_heads, + bool scaling_query, + float scaling_factor, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size * QKV_WEIGHT_NUM) { + // for simplicity, assume q, k, v is in same shape + // 0->q, 1->k, 2->v + // int qkv_index = i / (num_tokens * qProjSize) % 3; + + int token_idx = i / (hidden_size * QKV_WEIGHT_NUM); + size_t in_token_idx = i - token_idx * hidden_size * QKV_WEIGHT_NUM; + + int qkv_index = in_token_idx / hidden_size; + + int proj_size = qkv_index == 0 ? qProjSize : kProjSize; + + int head_idx = + (in_token_idx - qkv_index * num_q_heads * proj_size) / proj_size; + int global_head_idx = head_idx + shard_id * num_q_heads; + + size_t pre_length = + qkv_index == 0 + ? 0 + : (qkv_index == 1 ? qProjSize * global_num_q_heads + : qProjSize * global_num_q_heads * KV_WEIGHT_NUM); + + size_t bias_idx = pre_length + global_head_idx * proj_size + i % proj_size; + + input_ptr[i] += bias_ptr[bias_idx]; + + if (scaling_query && qkv_index == 0) { + input_ptr[i] *= scaling_factor; + } + } +} + +template +__global__ void scaling_query_kernel(DT *input_ptr, + int qProjSize, + int num_tokens, + int num_q_heads, + float scaling_factor, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + int token_idx = i / hidden_size; + input_ptr[i % hidden_size + token_idx * hidden_size * QKV_WEIGHT_NUM] *= + scaling_factor; + } +} + +template +__global__ void + apply_rotary_embedding_native(DT *input_ptr, + cuFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_q_heads, + int num_tokens, + int num_kv_heads, + int q_block_size, + int k_block_size, + int q_array_size) { + CUDA_KERNEL_LOOP( + i, + num_tokens * (qProjSize * num_q_heads + kProjSize * num_kv_heads) / 2) { + // create complex number + bool q_tensor = i < (q_array_size / 2); + int proj_size = q_tensor ? qProjSize : kProjSize; + int real_i = q_tensor ? i : i - q_array_size / 2; + + int head_idx = real_i / (num_tokens * proj_size / 2); + int idx = real_i % (num_tokens * proj_size / 2); + int real_part_index = idx * 2 + + head_idx * (q_tensor ? q_block_size : k_block_size) + + (q_tensor ? 0 : q_array_size); + + int complex_part_index = real_part_index + 1; + + complex_input[i] = {input_ptr[real_part_index], + input_ptr[complex_part_index]}; + + int token_idx = + (real_i - head_idx * (num_tokens * proj_size / 2)) / (proj_size / 2); + size_t pos = tokenInfos[token_idx].abs_depth_in_request; + + // float before_real = complex_input[i].x, before_complex = + // complex_input[i].y; + + int pos_i = real_i % (proj_size / 2); + float freq = pos * (1.0 / pow(10000.0, (float)2 * pos_i / proj_size)); + cuFloatComplex complex_pos = {cos(freq), sin(freq)}; + + complex_input[i] = cuCmulf(complex_input[i], complex_pos); + input_ptr[real_part_index] = complex_input[i].x; + input_ptr[complex_part_index] = complex_input[i].y; + } +} + +template +__global__ void + apply_rotary_embedding_hf(DT *input_ptr, + cuFloatComplex *complex_input, + BatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int num_tokens, + size_t q_array_size, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + // create complex number + bool q_tensor = i < (q_array_size / 2); + int proj_size = q_tensor ? qProjSize : kProjSize; + int real_i = q_tensor ? i : i - q_array_size / 2; + + int token_idx = real_i / (hidden_size / 2); + int idx = real_i % (proj_size / 2); + int head_idx = (real_i - (token_idx * (hidden_size / 2))) / (proj_size / 2); + + int real_part_index = idx + head_idx * proj_size + + token_idx * hidden_size * QKV_WEIGHT_NUM + + hidden_size * (q_tensor ? 0 : 1); + int complex_part_index = real_part_index + (proj_size / 2); + + complex_input[i] = {input_ptr[real_part_index], + input_ptr[complex_part_index]}; + + // get the freq_cis: shape 1 * (qProjSize/2) = 1 * 64 + // apply a Cartesian coordinate transformation + // multiple with input & /copy back to q/k + + // get position of token + + // size_t pos = id_map[token_idx].token_position; + size_t pos = tokenInfos[token_idx].abs_depth_in_request; + + // float before_real = complex_input[i].x, before_complex = + int pos_i = real_i % (proj_size / 2); + float freq = pos * (1.0 / pow(10000.0, (float)2 * pos_i / proj_size)); + cuFloatComplex complex_pos = {cos(freq), sin(freq)}; + + complex_input[i] = cuCmulf(complex_input[i], complex_pos); + input_ptr[real_part_index] = complex_input[i].x; + input_ptr[complex_part_index] = complex_input[i].y; + } +} + +template +void compute_qkv_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + cudaStream_t stream) { + + checkCUDA(cublasSetStream(m->handle.blas, stream)); + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + assert(m->qSize == m->vSize && m->qSize == m->kSize); + cudaDataType_t cublas_data_type = ff_to_cuda_datatype(m->output_type[0]); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; +#else + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } +#endif + + // Step 1: Compute QKV projections + { + DT alpha = 1.0f, beta = 0.0f; + // after transpositions + int m_q = m->qProjSize * m->num_q_heads; + int m_k = m->kProjSize * m->num_q_heads; + int m_v = m->vProjSize * m->num_q_heads; + assert(m_q == m_k && m_k == m_v); // keep things simple for now + int n = bc->num_active_tokens(); + int k = m->qSize; + int m_ = m_q * QKV_WEIGHT_NUM; + // before transpositions + int lda = k, ldb = k, ldc = m_; + // matrix A: QKV weights + // matrix A's layout: [qSize (hidden_dim), qProjSize, num_heads, 3] + // matrix B: input + // matrix B's layout: [qSize (hidden_dim), num_new_tokens] + // matrix C: devQKVProjArray + // matrix B's layout: [qProjSize, num_heads, 3, num_new_tokens] + checkCUDA(cublasGemmEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + weight_ptr, + cublas_data_type, + lda, + input_ptr, + cublas_data_type, + ldb, + &beta, + output_ptr, + cublas_data_type, + ldc, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + + int num_tokens = bc->num_active_tokens(); + int parallelism = m->kProjSize * num_tokens * m->num_q_heads; + size_t q_array_size = m->qProjSize * num_tokens * m->num_q_heads; + + // Step 2: apply bias for QKV, or scale the query + if (*m->qkv_bias) { + apply_proj_bias_qkv<<>>(output_ptr, + bias_ptr, + shard_id, + num_tokens, + m->qProjSize, + m->kProjSize, + m->vProjSize, + m->global_num_q_heads, + m->num_q_heads, + *m->scaling_query, + m->scaling_factor, + m->hidden_size); + } else if (m->scaling_query) { + scaling_query_kernel<<>>(output_ptr, + num_tokens, + m->num_q_heads, + m->qProjSize, + m->scaling_factor, + m->hidden_size); + } + + // Step 3: apply rotary embedding if needed + if (*m->apply_rotary_embedding) { + /*q&k*/ + parallelism = num_tokens * m->hidden_size; + apply_rotary_embedding_hf<<>>(output_ptr, + m->complex_input, + m->token_infos, + m->qProjSize, + m->kProjSize, + num_tokens, + q_array_size, + m->hidden_size); + } +} + +template +void update_kv_cache_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + cudaStream_t stream) { + int num_tokens = bc->num_active_tokens(); + if (num_tokens > 0) { + int parallelism = m->hidden_size * num_tokens; + store_kv_cache<<>>(static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + num_tokens, + BatchConfig::max_sequence_length(), + m->hidden_size); + } +} + +template +void compute_o_prod_bias(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *weight_ptr, + DT const *bias_ptr, + int num_tokens, + cudaStream_t stream) { + cudaDataType_t cublas_data_type = ff_to_cuda_datatype(m->output_type[0]); + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if CUDA_VERSION >= 11000 + // TODO: currently set the default to CUBLAS_COMPUTE_16F for best performance + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; +#else + cudaDataType_t compute_type = cublas_data_type; +#endif + // Project to output, save result directly on output tensor + { + DT alpha = 1.0f, beta = 0.0f; + // after transpositions + int m_ = m->oProjSize; + int k = m->vProjSize * m->num_q_heads; + int n = num_tokens; + // before transpositions + int lda = k, ldb = k, ldc = m_; + // matrix A: output projection weight + // matrix A's layout: [vProjSize * num_heads, oProjSize] + DT const *A = weight_ptr + m->qSize * (m->qProjSize * m->num_q_heads + + m->kProjSize * m->num_q_heads + + m->vProjSize * m->num_q_heads); + // matrix B: attn heads + // matrix B's layout: [vProjSize * num_heads, num_new_tokens] + DT const *B = static_cast
(m->attn_heads); + // matrix B: output + // matrix B's layout: [oProjSize, num_new_tokens] + DT *C = static_cast
(output_ptr); + + checkCUDA(cublasGemmEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + B, + cublas_data_type, + ldb, + &beta, + C, + cublas_data_type, + ldc, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + // Add final output bias + if (*m->final_bias && shard_id == 0) { + int parallelism = m->oProjSize * num_tokens; + int qkv_weight_size = m->qProjSize * m->global_num_q_heads + + m->kProjSize * m->global_num_q_heads + + m->vProjSize * m->global_num_q_heads; + apply_proj_bias_w<<>>( + output_ptr, bias_ptr, num_tokens, qkv_weight_size, m->oProjSize); + } +} + +#define LAUNCH_ATTENTION_SCORE_KERNEL( \ + DT, Dh, Dh_MAX, THDS_PER_KEY, THREADS_PER_VALUE, THDS_PER_BLOCK, stream) \ + smem_sz = smem_size_in_bytes
(m->qProjSize, \ + BatchConfig::max_sequence_length(), \ + THREADS_PER_VALUE, \ + THDS_PER_BLOCK); \ + compute_attention_kernel_generation_kernel \ + <<>>( \ + static_cast
(m->devQKVProjArray), \ + static_cast
(m->keyCache), \ + static_cast
(m->valueCache), \ + output_ptr, \ + scale, \ + BatchConfig::max_sequence_length(), \ + m->qProjSize, \ + m->hidden_size, \ + m->request_infos) + +template +void compute_attention_kernel_generation(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + DT *output_ptr, + cudaStream_t stream) { + dim3 grid(m->num_q_heads, bc->num_generation_tokens); + int const per_head_size = m->qProjSize; + float scale = (*m->qk_prod_scaling) ? 1.0f / sqrt(m->kProjSize) : 1.0f; + size_t smem_sz; + if (per_head_size == 64) { + constexpr int THREADS_PER_VALUE_64 = threads_per_value_t::value; + LAUNCH_ATTENTION_SCORE_KERNEL( + DT, 64, 64, 4, THREADS_PER_VALUE_64, 128, stream); + } else if (per_head_size == 128) { + constexpr int THREADS_PER_VALUE_128 = threads_per_value_t::value; + LAUNCH_ATTENTION_SCORE_KERNEL( + DT, 128, 128, 4, THREADS_PER_VALUE_128, 128, stream); + } else { + assert(false && "a unsupported head size"); + } +} + +template +void pre_build_weight_kernel(IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + cudaStream_t stream) { + // additional processing for weight uploading + // Note that we update weight_ptr and bias_ptr when uploading weight and + // bias + if (m->quantization_type != DT_NONE) { + // copy weight_ptr to quantized_weight_ptr, do compression and store in + // m->weight_ptr + cudaMemcpyAsync(m->quantized_weight_ptr, + weight.get_byte_ptr(), + m->quantized_weightSize, + cudaMemcpyHostToDevice, + stream); + + if (m->quantization_type == DT_INT4) { + int parallelism = m->qProjSize * m->qSize * m->num_q_heads / 2; + decompress_int4_attention_weights<<>>( + m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + m->qProjSize, + m->qSize, + m->num_q_heads); + } else { + assert(m->quantization_type == DT_INT8); + int parallelism = m->qProjSize * m->qSize * m->num_q_heads; + decompress_int8_attention_weights<<>>( + m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + m->qProjSize, + m->qSize, + m->num_q_heads); + } + } else { + if (data_type == DT_FLOAT) { + cudaMemcpyAsync(m->weight_ptr, + weight.get_float_ptr(), + m->weightSize, + cudaMemcpyHostToDevice, + stream); + } else if (data_type == DT_HALF) { + cudaMemcpyAsync(m->weight_ptr, + weight.get_half_ptr(), + m->weightSize, + cudaMemcpyHostToDevice, + stream); + } else { + assert(false); + } + } +} + +template +void inference_kernel(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + cudaStream_t stream) { + + if (m->offload && m->biasSize > 0) { + cudaMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, cudaMemcpyHostToDevice, stream); + bias_ptr = static_cast
(m->bias_ptr); + } + + // phase 1: Implement kernel to compute KQV for input tokens + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + update_kv_cache_kernel
(m, bc, stream); + + if (bc->num_generation_tokens > 0) { + // phase 3: Compute attention score for generation tokens + compute_attention_kernel_generation
( + m, bc, static_cast
(m->attn_heads), stream); + } + + if (bc->num_tokens > bc->num_generation_tokens) { + // phase 4: Compute attention score for prompt tokens; + compute_attention_kernel_prompt( + m, bc, shard_id, bias_ptr, weight_ptr, stream); + } + + // compute output production and bias together for all tokens + int num_tokens = bc->num_active_tokens(); + compute_o_prod_bias( + m, bc, shard_id, output_ptr, weight_ptr, bias_ptr, num_tokens, stream); +} + +} // namespace IncMultiHeadAttention +} // namespace Kernels + +using namespace Kernels::IncMultiHeadAttention; + +template +__global__ void store_kv_cache(DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + BatchConfig::PerTokenInfo const *tokenInfos, + int num_tokens, + int max_seq_len, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + int token_idx = i / hidden_size; + int offset = i % hidden_size; + + size_t val_idx = + token_idx * QKV_WEIGHT_NUM * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + int const req_id = tokenInfos[token_idx].request_index; + int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + + // key cache + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +__global__ void fill_entries_above_diagonal(DT *matrix, + size_t num_rows, + size_t num_cols, + size_t num_q_heads, + size_t entries_above_diagonal, + DT value) { + CUDA_KERNEL_LOOP(i, entries_above_diagonal * num_q_heads) { + size_t head_idx = i / entries_above_diagonal; + size_t entry_idx = i % entries_above_diagonal; + size_t y = (-1 + sqrt(8 * (float)entry_idx + 1)) / 2; + size_t x = entry_idx - y * (y + 1) / 2; + y += (num_cols - num_rows) + 1; + matrix[head_idx * num_rows * num_cols + num_cols * y + x] = value; + } +} + +template +void compute_attention_kernel_prompt(IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + DT const *bias_ptr, + DT const *weight_ptr, + cudaStream_t stream) { + checkCUDA(cublasSetStream(m->handle.blas, stream)); + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + cudaDataType_t cublas_data_type = ff_to_cuda_datatype(m->output_type[0]); + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; +#else + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } +#endif + // int num_requests = bc->num_active_requests(); + int num_tokens = bc->num_active_tokens(); + int tokens_previous_requests = 0; + int q_block_size = m->qProjSize; + int kt_block_size = m->kProjSize; + int kt_req_block_size = + kt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + int vt_block_size = m->vProjSize; + int vt_req_block_size = + vt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i] || (!bc->requestsInfo[i].prompt_phase)) { + continue; + } + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + int total_tokens = bc->requestsInfo[i].first_token_depth_in_request + + bc->requestsInfo[i].num_tokens_in_batch; + // Step 1: compute query-key product QK.T/sqrt(d_k) + { + // Scale by sqrt(d_k) as per the original attention paper + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // after transpositions + int m_ = num_new_tokens; + int n = total_tokens; + int k = m->qProjSize; + // before transpositions + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + // N.B. strides are applied before transpose operations + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens; + + // matrix A: devQKVProjArray + // matrix A's layout: [qProjSize, num_heads, 3, num_new_tokens] + // To get query projection, skip over Q entries from previous requests + DT const *A = static_cast
(m->devQKVProjArray) + + bc->requestsInfo[i].first_token_offset_in_batch * + m->qProjSize * m->num_q_heads * QKV_WEIGHT_NUM; + // matrix B: key cache + // matrix B's layout: [kProjSize * num_heads, total_tokens] + // To get B, skip over K entries from previous requests (all heads + + // padding) + DT const *B = static_cast
(m->keyCache) + i * kt_req_block_size; + // matrix C: qk_prods + // matrix C's layout: [num_new_tokens, total_tokens, num_heads] + // To get C, skip over QK.T products from previous requests + DT *C = static_cast
(m->qk_prods); + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + // Step 2: Add alibi position bias to qk production + // matrix C: qk_prods + // matrix C's layout: [num_new_tokens, total_tokens, num_heads] + // To get C, skip over QK.T products from previous requests + DT *C = static_cast
(m->qk_prods); + if (*m->position_bias) { + size_t parallelism = m->num_q_heads * total_tokens * num_new_tokens; + apply_position_bias_qkprd<<>>(C, + num_new_tokens, + total_tokens, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + + // Step 3: Apply causal mask. Fill all elements above diagonal in qk prods + // with -inf to force causal attention. + assert(num_new_tokens <= total_tokens); + size_t entries_above_diagonal = num_new_tokens * (num_new_tokens - 1) / 2; + if (entries_above_diagonal > 0) { + size_t parallelism = m->num_q_heads * entries_above_diagonal; + fill_entries_above_diagonal<<>>(C, + num_new_tokens, + total_tokens, + m->num_q_heads, + entries_above_diagonal, + static_cast
(-INFINITY)); + } + + // Step 4: Compute Softmax(QK.T/sqrt(d_k)) + { + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(cudnnSetTensor4dDescriptor(m->qk_tensor, + CUDNN_TENSOR_NCHW, + cudnn_data_type, + n_param, + c_param, + h_param, + w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax); + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(cudnnSoftmaxForward(m->handle.dnn, + CUDNN_SOFTMAX_ACCURATE, + CUDNN_SOFTMAX_MODE_CHANNEL, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax)); + } + // Step 5: Matmul softmax(QK.T/sqrt(d_k)) by V. Implemented as V @ + // softmax(QK.T/sqrt(d_k)).T + { + DT alpha = 1.0f, beta = 0.0f; + // after transpositions + int m_ = m->vProjSize; + int n = num_new_tokens; + int k = total_tokens; + // before transpositions + int lda = m_ * m->num_q_heads, ldb = n, ldc = m_ * m->num_q_heads; + // N.B. strides are applied before transpose operations + int strideA = vt_block_size; + int strideB = num_new_tokens * total_tokens; + int strideC = m->vProjSize; + // matrix A: value cache + // matrix A's layout: [vProjSize, num_heads, total_tokens] + // To get A, skip over V.T entries from previous requests (all heads + + // padding) + DT *A = static_cast
(m->valueCache) + i * vt_req_block_size; + // matrix B: qk_prods_softmax + // matrix B's layout: [num_new_tokens, total_tokens, num_heads] + // To get B, skip over softmax(QK.T/sqrt(d_k)) entries from previous + // requests (all heads) + DT *B = static_cast
(m->qk_prods_softmax); + ; + // matrix C: attn heads + // matrix C's layout: [vProjSize, num_heads, num_new_tokens] + // To get C, skip over softmax(QK.T/sqrt(d_k))V products from previous + // requests + // store the result attn heads, also skip the genration tokens + DT *C = static_cast
(m->attn_heads) + + (bc->requestsInfo[i].first_token_offset_in_batch) * + m->num_q_heads * m->vProjSize; + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_N, + CUBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + } + tokens_previous_requests += num_new_tokens; + } + if (tokens_previous_requests != (num_tokens - bc->num_generation_tokens)) { + bc->print(); + printf("tokens_previous_requests: %i\n", tokens_previous_requests); + printf("num_tokens: %i\n", num_tokens); + printf("bc->num_generation_tokens: %i\n", bc->num_generation_tokens); + } + assert(tokens_previous_requests == (num_tokens - bc->num_generation_tokens)); +} + +/*static*/ +void IncMultiHeadSelfAttention::inference_kernel_wrapper( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + // assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::IncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_half_ptr(), + m->offload ? static_cast(m->weight_ptr) : weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::IncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_float_ptr(), + m->offload ? static_cast(m->weight_ptr) + : weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("IncMultiHeadSelfAttention forward time = %.9fms\n", elapsed); + } +} + +IncMultiHeadSelfAttentionMeta::IncMultiHeadSelfAttentionMeta( + FFHandler handler, + IncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + INC_DECODING_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + attn->quantization_type, + attn->offload) {} + +IncMultiHeadSelfAttentionMeta::IncMultiHeadSelfAttentionMeta( + FFHandler handler, + InferenceMode infer_mode, + Op const *attn, + int _qSize, + int _kSize, + int _vSize, + int _qProjSize, + int _kProjSize, + int _vProjSize, + int _oProjSize, + bool _apply_rotary_embedding, + bool _qkv_bias, + bool _scaling_query, + bool _qk_prod_scaling, + bool _position_bias, + bool _final_bias, + float _scaling_factor, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _global_num_q_heads, + int _global_num_kv_heads, + int _num_q_heads, + int _num_kv_heads, + DataType _quantization_type, + bool _offload) + : OpMeta(handler, attn), weight_ptr(nullptr), bias_ptr(nullptr) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(cudnnSetStream(handler.dnn, stream)); + checkCUDNN(cudnnCreateTensorDescriptor(&qk_tensor)); + qSize = _qSize; + kSize = _kSize; + vSize = _vSize; + // assume dimensions match for now + assert(qSize == kSize); + assert(kSize == vSize); + qProjSize = _qProjSize; + kProjSize = _kProjSize; + assert(qProjSize == kProjSize); // required for attention QK.T matmul + vProjSize = _vProjSize; + oProjSize = _oProjSize; + size_t size_of_dt = data_type_size(attn->data_type); + quantization_type = _quantization_type; + offload = _offload; + + global_num_q_heads = _global_num_q_heads; + global_num_kv_heads = _global_num_kv_heads; + num_q_heads = _num_q_heads; + num_kv_heads = _num_kv_heads; + hidden_size = num_q_heads * qProjSize; + + weightSize = + ((qSize * qProjSize + oProjSize * (vProjSize > 0 ? vProjSize : vSize)) * + num_q_heads + + (kSize * kProjSize + vSize * vProjSize) * num_q_heads) * + size_of_dt; + if (quantization_type != DT_NONE) { + quantized_weightSize = get_quantization_to_byte_size( + attn->data_type, quantization_type, weightSize); + } + // biasSize = _bias ? oProjSize * size_of_dt * 4 : 0; + + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + int final_bias_size = oProjSize; + biasSize = + (_qkv_bias ? qkv_bias_size : 0) + (final_bias ? final_bias_size : 0); + + // has_load_weights = (bool *)calloc(1, sizeof(bool)); + //*has_load_weights = false; + apply_rotary_embedding = (bool *)calloc(1, sizeof(bool)); + *apply_rotary_embedding = _apply_rotary_embedding; + qkv_bias = (bool *)calloc(1, sizeof(bool)); + *qkv_bias = _qkv_bias; + scaling_query = (bool *)calloc(1, sizeof(bool)); + *scaling_query = _scaling_query; + scaling_factor = _scaling_factor; + qk_prod_scaling = (bool *)calloc(1, sizeof(bool)); + *qk_prod_scaling = _qk_prod_scaling; + position_bias = (bool *)calloc(1, sizeof(bool)); + *position_bias = _position_bias; + final_bias = (bool *)calloc(1, sizeof(bool)); + *final_bias = _final_bias; + + // allocate weight and bias in the reserve space for cpu offloading + if (offload) { + weight_ptr = gpu_mem_allocator.allocate_reserved_untyped(weightSize); + bias_ptr = gpu_mem_allocator.allocate_reserved_untyped(biasSize); + } + + // allocate memory for the seqArray and reserve space + { + int max_tokens_per_batch = infer_mode == TREE_VERIFY_MODE + ? BatchConfig::max_verify_tokens_per_batch() + : BatchConfig::max_tokens_per_batch(); + size_t qkv_max_proj_size = max_tokens_per_batch * (qProjSize * num_q_heads + + kProjSize * num_q_heads + + vProjSize * num_q_heads); + size_t key_cache_size = 0, value_cache_size = 0; + switch (infer_mode) { + case INC_DECODING_MODE: { + key_cache_size = num_q_heads * kProjSize * + BatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length(); + value_cache_size = num_q_heads * vProjSize * + BatchConfig::max_requests_per_batch() * + BatchConfig::max_sequence_length(); + break; + } + case BEAM_SEARCH_MODE: + case TREE_VERIFY_MODE: { + // a K-ary tree max node is (k^n - 1) / 2 + key_cache_size = num_q_heads * kProjSize * + BeamSearchBatchConfig::max_requests_per_batch() * + (BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num()); + value_cache_size = num_q_heads * vProjSize * + BeamSearchBatchConfig::max_requests_per_batch() * + (BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num()); + break; + } + default: + assert(false && "Unkown inference mode"); + } + size_t requestinfo_size = BatchConfig::max_requests_per_batch(); + // size_t tokeninfo_size = max_tokens_per_batch; + size_t qk_prod_size = + max_tokens_per_batch * BatchConfig::max_sequence_length() * num_q_heads; + size_t attn_heads_size = max_tokens_per_batch * num_q_heads * vProjSize; + size_t complex_size = (max_tokens_per_batch * (qProjSize * num_q_heads + + kProjSize * num_q_heads)) / + 2; + size_t totalSize = + (qkv_max_proj_size + key_cache_size + value_cache_size + + 2 * qk_prod_size + attn_heads_size) * + size_of_dt + + complex_size * sizeof(cuFloatComplex); // more components will + // be added here later + if (offload) { + // assert that we have enough reserved work space left + size_t totalSharedSize = + infer_mode == TREE_VERIFY_MODE + ? totalSize - + (key_cache_size + value_cache_size + qkv_max_proj_size) * + size_of_dt + : totalSize - (key_cache_size + value_cache_size) * size_of_dt; + + size_t instance_size = + size_of_dt * + (infer_mode == TREE_VERIFY_MODE + ? key_cache_size + value_cache_size + qkv_max_proj_size + : key_cache_size + value_cache_size); + + if (quantization_type != DT_NONE) { + totalSharedSize += quantized_weightSize; + } + assert(gpu_mem_allocator.reserved_total_size - + gpu_mem_allocator.reserved_allocated_size >= + totalSharedSize); + gpu_mem_allocator.create_legion_instance(reserveInst, instance_size); + } else { + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + } + + // in tree_verify, enable devQKVProjArray; + if (!offload || infer_mode == TREE_VERIFY_MODE) { + devQKVProjArray = gpu_mem_allocator.allocate_instance_untyped( + qkv_max_proj_size * size_of_dt); + } else { + devQKVProjArray = gpu_mem_allocator.allocate_reserved_untyped( + qkv_max_proj_size * size_of_dt); + // offset += qkv_max_proj_size * size_of_dt; + } + + // use key value cache in all mode. + keyCache = gpu_mem_allocator.allocate_instance_untyped(key_cache_size * + size_of_dt); + valueCache = gpu_mem_allocator.allocate_instance_untyped(value_cache_size * + size_of_dt); + + token_infos = + static_cast(handler.batch_config_metadata); + request_infos = reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo)); + + if (offload) { + // token_infos = + // gpu_mem_allocator.allocate_reserved( + // tokeninfo_size); + // offset += sizeof(BatchConfig::PerTokenInfo) * tokeninfo_size; + qk_prods = gpu_mem_allocator.allocate_reserved_untyped(qk_prod_size * + size_of_dt); + // offset += qk_prod_size * size_of_dt; + qk_prods_softmax = gpu_mem_allocator.allocate_reserved_untyped( + qk_prod_size * size_of_dt); + // offset += qk_prod_size * size_of_dt; + attn_heads = gpu_mem_allocator.allocate_reserved_untyped(attn_heads_size * + size_of_dt); + // offset += attn_heads_size * size_of_dt; + complex_input = + gpu_mem_allocator.allocate_reserved(complex_size); + // offset += complex_size * sizeof(cuFloatComplex); + // request_infos = + // gpu_mem_allocator.allocate_reserved( + // requestinfo_size); + } else { + // token_infos = + // gpu_mem_allocator.allocate_instance( + // tokeninfo_size); + qk_prods = gpu_mem_allocator.allocate_instance_untyped(qk_prod_size * + size_of_dt); + qk_prods_softmax = gpu_mem_allocator.allocate_instance_untyped( + qk_prod_size * size_of_dt); + attn_heads = gpu_mem_allocator.allocate_instance_untyped(attn_heads_size * + size_of_dt); + complex_input = + gpu_mem_allocator.allocate_instance(complex_size); + // request_infos = + // gpu_mem_allocator.allocate_instance( + // requestinfo_size); + } + + // allocate more size for quantization data + if (quantization_type != DT_NONE) { + assert(offload); + quantized_weight_ptr = + gpu_mem_allocator.allocate_reserved(quantized_weightSize); + } + if (!offload) { + assert(gpu_mem_allocator.reserved_total_size == + gpu_mem_allocator.reserved_allocated_size); + } + } + cudaStreamSynchronize(stream); +} + +IncMultiHeadSelfAttentionMeta::~IncMultiHeadSelfAttentionMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template void Kernels::IncMultiHeadAttention::pre_build_weight_kernel( + IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + cudaStream_t stream); + +template void Kernels::IncMultiHeadAttention::pre_build_weight_kernel( + IncMultiHeadSelfAttentionMeta const *m, + GenericTensorAccessorR const weight, + DataType data_type, + cudaStream_t stream); + +template void Kernels::IncMultiHeadAttention::compute_o_prod_bias( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + float *output_ptr, + float const *weight_ptr, + float const *bias_ptr, + int num_tokens, + cudaStream_t stream); + +template void Kernels::IncMultiHeadAttention::compute_o_prod_bias( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + int shard_id, + half *output_ptr, + half const *weight_ptr, + half const *bias_ptr, + int num_tokens, + cudaStream_t stream); + +template void + Kernels::IncMultiHeadAttention::compute_attention_kernel_generation( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + float *output_ptr, + cudaStream_t stream); + +template void + Kernels::IncMultiHeadAttention::compute_attention_kernel_generation( + IncMultiHeadSelfAttentionMeta const *m, + BatchConfig const *bc, + half *output_ptr, + cudaStream_t stream); +}; // namespace FlexFlow diff --git a/src/ops/kernels/batch_matmul.cpp b/src/ops/kernels/batch_matmul.cpp index 34468d28a1..7145af2108 100644 --- a/src/ops/kernels/batch_matmul.cpp +++ b/src/ops/kernels/batch_matmul.cpp @@ -41,9 +41,9 @@ void forward_kernel_wrapper(BatchMatmulMeta const *meta, hipEvent_t t_start, t_end; if (meta->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel(meta, o_ptr, @@ -59,12 +59,12 @@ void forward_kernel_wrapper(BatchMatmulMeta const *meta, b_seq_length_dim, seq_length); if (meta->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("BatchMatmul forward time = %.2lfms\n", elapsed); } } @@ -86,9 +86,9 @@ void backward_kernel_wrapper(BatchMatmulMeta const *meta, hipEvent_t t_start, t_end; if (meta->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel(meta, o_ptr, @@ -104,12 +104,12 @@ void backward_kernel_wrapper(BatchMatmulMeta const *meta, batch, stream); if (meta->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("BatchMatmul backward time = %.2lfms\n", elapsed); } } diff --git a/src/ops/kernels/cast_kernels.cpp b/src/ops/kernels/cast_kernels.cpp index f47bd0ed92..16b9b4cec0 100644 --- a/src/ops/kernels/cast_kernels.cpp +++ b/src/ops/kernels/cast_kernels.cpp @@ -34,19 +34,19 @@ void forward_kernel_wrapper(CastMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel(input_ptr, output_ptr, volume, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("[%s] forward time (CF) = %.2fms\n", "Cast", elapsed); // print_tensor(input_ptr, 32, "[Cast:forward:input]"); // print_tensor(output_ptr, 32, "[Cast:forward:output]"); diff --git a/src/ops/kernels/concat_kernels.cpp b/src/ops/kernels/concat_kernels.cpp index 5f6e04abc9..bf5d46b9cc 100644 --- a/src/ops/kernels/concat_kernels.cpp +++ b/src/ops/kernels/concat_kernels.cpp @@ -40,13 +40,13 @@ void forward_kernel_wrapper(ConcatMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel(output, inputs, num_inputs, axis, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); // print_tensor<4, float>(output - output_blk_size, output_rect, // "[Concat:forward:output]"); printf("output_blk_size=%zu\n", @@ -56,8 +56,8 @@ void forward_kernel_wrapper(ConcatMeta const *m, float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); printf("[%s] forward time = %.4f ms\n", m->op_name, elapsed); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); } } @@ -71,19 +71,19 @@ void backward_kernel_wrapper(ConcatMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel(output_grad, input_grads, num_inputs, axis, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); printf("[%s] forward time = %.4f ms\n", m->op_name, elapsed); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); } } diff --git a/src/ops/kernels/conv_2d_kernels.cpp b/src/ops/kernels/conv_2d_kernels.cpp index b4ec1545c3..7d2fa20c49 100644 --- a/src/ops/kernels/conv_2d_kernels.cpp +++ b/src/ops/kernels/conv_2d_kernels.cpp @@ -174,15 +174,15 @@ void forward_kernel_wrapper(Conv2DMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel( m, input_ptr, output_ptr, filter_ptr, bias_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); print_tensor(input_ptr, 16, "[Conv2D:forward:input]"); print_tensor(filter_ptr, 16, "[Conv2D:forward:kernel]"); @@ -190,8 +190,8 @@ void forward_kernel_wrapper(Conv2DMeta const *m, print_tensor(output_ptr, 16, "[Conv2D:forward:output]"); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("%s [Conv2D] forward time (CF) = %.2fms\n", m->op_name, elapsed); } } @@ -209,9 +209,9 @@ void backward_kernel_wrapper(Conv2DMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel(m, @@ -224,12 +224,12 @@ void backward_kernel_wrapper(Conv2DMeta const *m, bias_grad_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("%s [Conv2D] backward time = %.2fms\n", m->op_name, elapsed); // print_tensor<4, float>(acc_output_grad.ptr, acc_output_grad.rect, // "[Conv2D:backward:output_grad]"); print_tensor<4, diff --git a/src/ops/kernels/decompress_kernels.cpp b/src/ops/kernels/decompress_kernels.cpp new file mode 100644 index 0000000000..22bf93d449 --- /dev/null +++ b/src/ops/kernels/decompress_kernels.cpp @@ -0,0 +1,90 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#include "flexflow/ops/kernels/decompress_kernels.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +namespace Kernels { + +template +__global__ void decompress_int4_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize) {} + +template +__global__ void decompress_int8_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize) {} + +template +__global__ void decompress_int4_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads) {} + +template +__global__ void decompress_int8_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads) {} + +template __global__ void decompress_int4_general_weights( + char const *input_weight_ptr, float *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int4_general_weights( + char const *input_weight_ptr, half *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int8_general_weights( + char const *input_weight_ptr, float *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int8_general_weights( + char const *input_weight_ptr, half *weight_ptr, int in_dim, int valueSize); +template __global__ void + decompress_int4_attention_weights(char *input_weight_ptr, + float *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int4_attention_weights(char *input_weight_ptr, + half *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int8_attention_weights(char *input_weight_ptr, + float *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int8_attention_weights(char *input_weight_ptr, + half *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +} // namespace Kernels +}; // namespace FlexFlow \ No newline at end of file diff --git a/src/ops/kernels/decompress_kernels.cu b/src/ops/kernels/decompress_kernels.cu new file mode 100644 index 0000000000..2e02ce1eec --- /dev/null +++ b/src/ops/kernels/decompress_kernels.cu @@ -0,0 +1,261 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/decompress_kernels.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +namespace Kernels { + +template +__global__ void decompress_int4_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize) { + // eg. in dim = 3072, out dim = 768 + CUDA_KERNEL_LOOP(i, valueSize / 2) { + size_t real_idx_first = i * 2; + size_t real_idx_second = i * 2 + 1; + size_t group_idx = + (real_idx_first / (in_dim * INT4_NUM_OF_ELEMENTS_PER_GROUP)) * in_dim + + real_idx_first % in_dim; + size_t idx = i; + size_t offset_idx = (valueSize / 2) + group_idx * sizeof(DT); + size_t scale_idx = offset_idx + sizeof(DT) * (valueSize / 32); + + weight_ptr[real_idx_first] = + static_cast
((input_weight_ptr[idx] >> 4) & 0xF) / + (*(DT *)(input_weight_ptr + scale_idx)) + + (*(DT *)(input_weight_ptr + offset_idx)); + weight_ptr[real_idx_second] = + static_cast
(input_weight_ptr[idx] & 0xF) / + (*(DT *)(input_weight_ptr + scale_idx + sizeof(DT))) + + (*(DT *)(input_weight_ptr + offset_idx + sizeof(DT))); + } +} + +template +__global__ void decompress_int8_general_weights(char const *input_weight_ptr, + DT *weight_ptr, + int in_dim, + int valueSize) { + CUDA_KERNEL_LOOP(i, valueSize) { + size_t idx = i; + size_t group_idx = + (idx / (in_dim * INT4_NUM_OF_ELEMENTS_PER_GROUP)) * in_dim + + idx % in_dim; + size_t offset_idx = valueSize + group_idx * sizeof(DT); + size_t scale_idx = offset_idx + sizeof(DT) * (valueSize / 32); + weight_ptr[idx] = static_cast
(input_weight_ptr[idx] & 0xFF) / + (*(DT *)(input_weight_ptr + scale_idx)) + + (*(DT *)(input_weight_ptr + offset_idx)); + } +} + +template +__global__ void decompress_int4_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads) { + // TODO this is because in top level function we assume q,k,v in same size + CUDA_KERNEL_LOOP(i, qProjSize * num_heads * qSize / 2) { + int q_block_size = (qProjSize * qSize) / 2; + int real_q_block_size = q_block_size * 2; + size_t qkvo_block_size = q_block_size * 4; + size_t real_qkvo_block_size = qkvo_block_size * 2; + + int group_idx = (i * 2 / (INT4_NUM_OF_ELEMENTS_PER_GROUP * qSize)) * qSize + + (i * 2) % qSize; + // i * 2 / (INT4_NUM_OF_ELEMENTS_PER_GROUP); + int head_idx = i / q_block_size; + int data_idx = i % q_block_size; + + size_t idx_q = head_idx * qkvo_block_size + data_idx; + size_t idx_k = idx_q + q_block_size; + size_t idx_v = idx_k + q_block_size; + size_t idx_o = idx_v + q_block_size; + + size_t real_idx_q_first = head_idx * real_qkvo_block_size + data_idx * 2; + size_t real_idx_q_second = real_idx_q_first + 1; + size_t real_idx_k_first = + head_idx * real_qkvo_block_size + real_q_block_size + data_idx * 2; + size_t real_idx_k_second = real_idx_k_first + 1; + size_t real_idx_v_first = + head_idx * real_qkvo_block_size + real_q_block_size * 2 + data_idx * 2; + size_t real_idx_v_second = real_idx_v_first + 1; + size_t real_idx_o_first = + head_idx * real_qkvo_block_size + real_q_block_size * 3 + data_idx * 2; + size_t real_idx_o_second = real_idx_o_first + 1; + + size_t meta_offset = num_heads * qkvo_block_size; + size_t one_meta_size = sizeof(DT) * (qProjSize * num_heads * qSize / 32); + size_t q_offset_idx = meta_offset + group_idx * sizeof(DT); + size_t q_scaling_idx = q_offset_idx + one_meta_size; + + size_t k_offset_idx = q_scaling_idx + one_meta_size; + size_t k_scaling_idx = k_offset_idx + one_meta_size; + + size_t v_offset_idx = k_scaling_idx + one_meta_size; + size_t v_scaling_idx = v_offset_idx + one_meta_size; + + size_t o_offset_idx = v_scaling_idx + one_meta_size; + size_t o_scaling_idx = o_offset_idx + one_meta_size; + + weight_ptr[real_idx_q_first] = + static_cast
((input_weight_ptr[idx_q] >> 4) & 0xF) / + (*(DT *)(input_weight_ptr + q_scaling_idx)) + + (*(DT *)(input_weight_ptr + q_offset_idx)); + weight_ptr[real_idx_q_second] = + static_cast
((input_weight_ptr[idx_q] & 0xF)) / + (*(DT *)(input_weight_ptr + q_scaling_idx + sizeof(DT))) + + (*(DT *)(input_weight_ptr + q_offset_idx + sizeof(DT))); + weight_ptr[real_idx_k_first] = + static_cast
((input_weight_ptr[idx_k] >> 4) & 0xF) / + (*(DT *)(input_weight_ptr + k_scaling_idx)) + + (*(DT *)(input_weight_ptr + k_offset_idx)); + weight_ptr[real_idx_k_second] = + static_cast
((input_weight_ptr[idx_k] & 0xF)) / + (*(DT *)(input_weight_ptr + k_scaling_idx + sizeof(DT))) + + (*(DT *)(input_weight_ptr + k_offset_idx + sizeof(DT))); + weight_ptr[real_idx_v_first] = + static_cast
((input_weight_ptr[idx_v] >> 4) & 0xF) / + (*(DT *)(input_weight_ptr + v_scaling_idx)) + + (*(DT *)(input_weight_ptr + v_offset_idx)); + weight_ptr[real_idx_v_second] = + static_cast
((input_weight_ptr[idx_v] & 0xF)) / + (*(DT *)(input_weight_ptr + v_scaling_idx + sizeof(DT))) + + (*(DT *)(input_weight_ptr + v_offset_idx + sizeof(DT))); + weight_ptr[real_idx_o_first] = + static_cast
((input_weight_ptr[idx_o] >> 4) & 0xF) / + (*(DT *)(input_weight_ptr + o_scaling_idx)) + + (*(DT *)(input_weight_ptr + o_offset_idx)); + weight_ptr[real_idx_o_second] = + static_cast
((input_weight_ptr[idx_o] & 0xF)) / + (*(DT *)(input_weight_ptr + o_scaling_idx + sizeof(DT))) + + (*(DT *)(input_weight_ptr + o_offset_idx + sizeof(DT))); + } +} + +template +__global__ void decompress_int8_attention_weights(char *input_weight_ptr, + DT *weight_ptr, + int qProjSize, + int qSize, + int num_heads) { + // TODO this is because in top level function we assume q,k,v in same size + CUDA_KERNEL_LOOP(i, qProjSize * num_heads * qSize) { + int q_block_size = qProjSize * qSize; + size_t qkvo_block_size = q_block_size * 4; + + int group_idx = + (i / (INT4_NUM_OF_ELEMENTS_PER_GROUP * qSize)) * qSize + i % qSize; + // i * 2 / (INT4_NUM_OF_ELEMENTS_PER_GROUP); + int head_idx = i / q_block_size; + int data_idx = i % q_block_size; + + size_t idx_q = head_idx * qkvo_block_size + data_idx; + size_t idx_k = idx_q + q_block_size; + size_t idx_v = idx_k + q_block_size; + size_t idx_o = idx_v + q_block_size; + + size_t meta_offset = num_heads * qkvo_block_size; + size_t one_meta_size = sizeof(DT) * (qProjSize * num_heads * qSize / 32); + size_t q_offset_idx = meta_offset + group_idx * sizeof(DT); + size_t q_scaling_idx = q_offset_idx + one_meta_size; + + size_t k_offset_idx = q_scaling_idx + one_meta_size; + size_t k_scaling_idx = k_offset_idx + one_meta_size; + + size_t v_offset_idx = k_scaling_idx + one_meta_size; + size_t v_scaling_idx = v_offset_idx + one_meta_size; + + size_t o_offset_idx = v_scaling_idx + one_meta_size; + size_t o_scaling_idx = o_offset_idx + one_meta_size; + + weight_ptr[idx_q] = static_cast
(input_weight_ptr[idx_q] & 0xFF) / + (*(DT *)(input_weight_ptr + q_scaling_idx)) + + (*(DT *)(input_weight_ptr + q_offset_idx)); + weight_ptr[idx_k] = static_cast
(input_weight_ptr[idx_k] & 0xFF) / + (*(DT *)(input_weight_ptr + k_scaling_idx)) + + (*(DT *)(input_weight_ptr + k_offset_idx)); + weight_ptr[idx_v] = static_cast
(input_weight_ptr[idx_v] & 0xFF) / + (*(DT *)(input_weight_ptr + v_scaling_idx)) + + (*(DT *)(input_weight_ptr + v_offset_idx)); + weight_ptr[idx_o] = static_cast
(input_weight_ptr[idx_o] & 0xFF) / + (*(DT *)(input_weight_ptr + o_scaling_idx)) + + (*(DT *)(input_weight_ptr + o_offset_idx)); + } +} + +template __global__ void decompress_int4_general_weights( + char const *input_weight_ptr, float *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int4_general_weights( + char const *input_weight_ptr, half *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int8_general_weights( + char const *input_weight_ptr, float *weight_ptr, int in_dim, int valueSize); +template __global__ void decompress_int8_general_weights( + char const *input_weight_ptr, half *weight_ptr, int in_dim, int valueSize); +template __global__ void + decompress_int4_attention_weights(char *input_weight_ptr, + float *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int4_attention_weights(char *input_weight_ptr, + half *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int8_attention_weights(char *input_weight_ptr, + float *weight_ptr, + int qProjSize, + int qSize, + int num_heads); + +template __global__ void + decompress_int8_attention_weights(char *input_weight_ptr, + half *weight_ptr, + int qProjSize, + int qSize, + int num_heads); +// template +// void decompress_weight_bias(T1 *input_weight_ptr, +// T2 *weight_ptr, +// T2 *params, +// int group_size, +// int tensor_size) { + +// // convert to DT, scaling, add offset; +// cudaStream_t stream; +// checkCUDA(get_legion_stream(&stream)); +// int parallelism = tensor_size; +// decompress_kernel<<>>( +// input_weight_ptr, weight_ptr, params, group_size); +// } +} // namespace Kernels +}; // namespace FlexFlow diff --git a/src/ops/kernels/dropout_kernels.cpp b/src/ops/kernels/dropout_kernels.cpp index c0d5748464..48e15564ee 100644 --- a/src/ops/kernels/dropout_kernels.cpp +++ b/src/ops/kernels/dropout_kernels.cpp @@ -30,6 +30,7 @@ DropoutMeta::DropoutMeta(FFHandler handler, Domain const &output_domain) : OpMeta(handler) { profiling = dropout->profiling; + inference_debugging = dropout->inference_debugging; rate = dropout->rate; seed = dropout->seed; input_type[0] = dropout->data_type; diff --git a/src/ops/kernels/dropout_kernels.cu b/src/ops/kernels/dropout_kernels.cu index c5b1a384df..9d4dce52f6 100644 --- a/src/ops/kernels/dropout_kernels.cu +++ b/src/ops/kernels/dropout_kernels.cu @@ -29,10 +29,12 @@ DropoutMeta::DropoutMeta(FFHandler handler, Domain const &output_domain) : OpMeta(handler) { profiling = dropout->profiling; + inference_debugging = dropout->inference_debugging; rate = dropout->rate; seed = dropout->seed; input_type[0] = dropout->data_type; output_type[0] = dropout->data_type; + checkCUDNN(cudnnCreateTensorDescriptor(&inputTensor)); checkCUDNN(cudnnCreateTensorDescriptor(&outputTensor)); checkCUDNN(cudnnCreateDropoutDescriptor(&dropoutDesc)); diff --git a/src/ops/kernels/element_binary_kernels.cpp b/src/ops/kernels/element_binary_kernels.cpp index 325edba6d0..3ae1e76cb6 100644 --- a/src/ops/kernels/element_binary_kernels.cpp +++ b/src/ops/kernels/element_binary_kernels.cpp @@ -22,7 +22,8 @@ namespace FlexFlow { using Legion::coord_t; using Legion::Domain; -ElementBinaryMeta::ElementBinaryMeta(FFHandler handler) : OpMeta(handler) { +ElementBinaryMeta::ElementBinaryMeta(FFHandler handler, Op const *op) + : OpMeta(handler, op) { checkCUDNN(miopenCreateTensorDescriptor(&input1Tensor)); checkCUDNN(miopenCreateTensorDescriptor(&input2Tensor)); checkCUDNN(miopenCreateTensorDescriptor(&outputTensor)); @@ -67,26 +68,29 @@ void init_kernel(ElementBinaryMeta *m, /*static*/ void forward_kernel_wrapper(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr) { + GenericTensorAccessorR const &in1, + GenericTensorAccessorR const &in2, + GenericTensorAccessorW const &out) { hipStream_t stream; checkCUDA(get_legion_stream(&stream)); hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } - Internal::forward_kernel(m, in1_ptr, in2_ptr, out_ptr, stream); + // print_tensor(in1_ptr, in1_domain.get_volume(), "input1:"); + // print_tensor(in2_ptr, in2_domain.get_volume(), "input2:"); + Internal::forward_kernel( + m, in1.get_float_ptr(), in2.get_float_ptr(), out.get_float_ptr(), stream); // print_tensor(out_ptr, in1_domain.get_volume(), "output:"); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); char const *opName; switch (m->op_type) { case OP_EW_ADD: @@ -119,9 +123,9 @@ void backward_kernel_wrapper(ElementBinaryMeta const *m, checkCUDA(get_legion_stream(&stream)); hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel( @@ -130,12 +134,12 @@ void backward_kernel_wrapper(ElementBinaryMeta const *m, // CUDA_NUM_THREADS>>>( out_grad_domain.get_volume(), alpha, alpha, // ele->op_type, out_grad_ptr, in1_ptr, in2_ptr, in1_grad_ptr, in2_grad_ptr); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); char const *opName; switch (m->op_type) { case OP_EW_ADD: @@ -250,10 +254,11 @@ __global__ void elewise_binary_backward_kernel(coord_t volume, } /*static*/ +template void forward_kernel(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr, + DT const *in1_ptr, + DT const *in2_ptr, + DT *out_ptr, hipStream_t stream) { checkCUDA(hipblasSetStream(m->handle.blas, stream)); checkCUDNN(miopenSetStream(m->handle.dnn, stream)); diff --git a/src/ops/kernels/element_binary_kernels.cu b/src/ops/kernels/element_binary_kernels.cu index cfa9f18279..42b31a664a 100644 --- a/src/ops/kernels/element_binary_kernels.cu +++ b/src/ops/kernels/element_binary_kernels.cu @@ -21,7 +21,8 @@ namespace FlexFlow { using Legion::coord_t; using Legion::Domain; -ElementBinaryMeta::ElementBinaryMeta(FFHandler handler) : OpMeta(handler) { +ElementBinaryMeta::ElementBinaryMeta(FFHandler handler, Op const *op) + : OpMeta(handler, op) { checkCUDNN(cudnnCreateTensorDescriptor(&input1Tensor)); checkCUDNN(cudnnCreateTensorDescriptor(&input2Tensor)); checkCUDNN(cudnnCreateTensorDescriptor(&outputTensor)); @@ -29,6 +30,7 @@ ElementBinaryMeta::ElementBinaryMeta(FFHandler handler) : OpMeta(handler) { checkCUDNN(cudnnCreateReduceTensorDescriptor(&reduceAddDesc)); op_type = OP_NOOP; profiling = false; + inference_debugging = false; inplace_a = false; has_same_operands = false; broadcast_input1 = false; @@ -61,27 +63,28 @@ void init_kernel(ElementBinaryMeta *m, default: assert(false); } + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(m->output_type[0]); checkCUDNN(cudnnSetOpTensorDescriptor( m->opDesc, mode, CUDNN_DATA_FLOAT, CUDNN_PROPAGATE_NAN)); checkCUDNN(cudnnSetReduceTensorDescriptor(m->reduceAddDesc, CUDNN_REDUCE_TENSOR_ADD, - CUDNN_DATA_FLOAT, + cudnn_data_type, CUDNN_PROPAGATE_NAN, CUDNN_REDUCE_TENSOR_NO_INDICES, CUDNN_32BIT_INDICES)); - checkCUDNN( - cudnnSetTensorDescriptorFromDomain(m->input1Tensor, input1_domain)); - checkCUDNN( - cudnnSetTensorDescriptorFromDomain(m->input2Tensor, input2_domain)); - checkCUDNN( - cudnnSetTensorDescriptorFromDomain(m->outputTensor, output_domain)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->input1Tensor, input1_domain, m->input_type[0])); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->input2Tensor, input2_domain, m->input_type[1])); + checkCUDNN(cudnnSetTensorDescriptorFromDomain( + m->outputTensor, output_domain, m->output_type[0])); } /*static*/ void forward_kernel_wrapper(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr) { + GenericTensorAccessorR const &in1, + GenericTensorAccessorR const &in2, + GenericTensorAccessorW const &out) { cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); @@ -91,7 +94,20 @@ void forward_kernel_wrapper(ElementBinaryMeta const *m, cudaEventCreate(&t_end); cudaEventRecord(t_start, stream); } - Internal::forward_kernel(m, in1_ptr, in2_ptr, out_ptr, stream); + assert(in1.data_type == in2.data_type); + assert(out.data_type == in1.data_type); + if (out.data_type == DT_HALF) { + Internal::forward_kernel( + m, in1.get_half_ptr(), in2.get_half_ptr(), out.get_half_ptr(), stream); + } else if (out.data_type == DT_FLOAT) { + Internal::forward_kernel(m, + in1.get_float_ptr(), + in2.get_float_ptr(), + out.get_float_ptr(), + stream); + } else { + assert(false && "Unsupported data type"); + } if (m->profiling) { cudaEventRecord(t_end, stream); checkCUDA(cudaEventSynchronize(t_end)); @@ -122,7 +138,7 @@ void forward_kernel_wrapper(ElementBinaryMeta const *m, default: assert(false); } - printf("[%s] forward time (CF) = %.2fms\n", opName, elapsed); + printf("[%s] forward time (CF) = %.9fms\n", opName, elapsed); // print_tensor(in1_ptr, 32, "[EWB:forward:input1]"); // print_tensor(in2_ptr, 32, "[EWB:forward:input2]"); // print_tensor(out_ptr, 32, "[EWB:forward:output]"); @@ -292,10 +308,11 @@ __global__ void elewise_binary_backward_kernel(coord_t volume, } /*static*/ +template void forward_kernel(ElementBinaryMeta const *m, - float const *in1_ptr, - float const *in2_ptr, - float *out_ptr, + DT const *in1_ptr, + DT const *in2_ptr, + DT *out_ptr, cudaStream_t stream) { checkCUDA(cublasSetStream(m->handle.blas, stream)); checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); diff --git a/src/ops/kernels/embedding_kernels.cu b/src/ops/kernels/embedding_kernels.cu index 65f3089409..22d8161ff1 100644 --- a/src/ops/kernels/embedding_kernels.cu +++ b/src/ops/kernels/embedding_kernels.cu @@ -60,7 +60,7 @@ void forward_kernel_wrapper(EmbeddingMeta const *m, m->aggr, output.domain.get_volume(), stream); - } else if (weight.data_type == DT_HALF) { + } else if (weight.data_type == DT_DOUBLE) { Internal::forward_kernel(input.get_int32_ptr(), output.get_double_ptr(), weight.get_double_ptr(), diff --git a/src/ops/kernels/linear_kernels.cpp b/src/ops/kernels/linear_kernels.cpp index 8066ddc812..072eb5e96b 100644 --- a/src/ops/kernels/linear_kernels.cpp +++ b/src/ops/kernels/linear_kernels.cpp @@ -19,7 +19,12 @@ namespace FlexFlow { -LinearMeta::LinearMeta(FFHandler handler, int batch_size) : OpMeta(handler) { +LinearMeta::LinearMeta(FFHandler handler, + int batch_size, + Linear const *li, + MemoryAllocator gpu_mem_allocator, + int weightSize) + : OpMeta(handler, li) { // Allocate an all-one's vector float *dram_one_ptr = (float *)malloc(sizeof(float) * batch_size); for (int i = 0; i < batch_size; i++) { @@ -31,11 +36,12 @@ LinearMeta::LinearMeta(FFHandler handler, int batch_size) : OpMeta(handler) { dram_one_ptr, sizeof(float) * batch_size, hipMemcpyHostToDevice)); - one_ptr = (float const *)fb_one_ptr; + one_ptr = (void *)fb_one_ptr; // Allocate descriptors checkCUDNN(miopenCreateActivationDescriptor(&actiDesc)); checkCUDNN(miopenCreateTensorDescriptor(&outputTensor)); } +LinearMeta::~LinearMeta(void) {} namespace Kernels { namespace Linear { @@ -55,7 +61,7 @@ bool use_activation(ActiMode mode) { return false; } -void Linear::init_kernel(LinearMeta *m, int batch_size, int channel) { +void init_kernel(LinearMeta *m, int batch_size, int channel) { if (use_activation(m->activation)) { miopenActivationMode_t mode; switch (m->activation) { @@ -70,12 +76,13 @@ void Linear::init_kernel(LinearMeta *m, int batch_size, int channel) { assert(false); } checkCUDNN(miopenSetActivationDescriptor(m->actiDesc, mode, 0.0, 0.0, 0.0)); - checkCUDNN(miopenSet4dTensorDescriptor(m->outputTensor, - ff_to_cudnn_datatype(m->output_type), - batch_size, - channel, - 1, - 1)); + checkCUDNN( + miopenSet4dTensorDescriptor(m->outputTensor, + ff_to_cudnn_datatype(m->output_type[0]), + batch_size, + channel, + 1, + 1)); } } @@ -92,27 +99,40 @@ void forward_kernel_wrapper(LinearMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + if (m->input_type[0] == DT_FLOAT) { + Internal::forward_kernel(m, + input_ptr, + output_ptr, + weight_ptr, + bias_ptr, + in_dim, + out_dim, + batch_size, + stream); + } else if (m->input_type[0] == DT_HALF) { + Internal::forward_kernel(m, + input_ptr, + output_ptr, + weight_ptr, + bias_ptr, + in_dim, + out_dim, + batch_size, + stream); } - Internal::forward_kernel(m, - input_ptr, - output_ptr, - weight_ptr, - bias_ptr, - in_dim, - out_dim, - batch_size, - stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("%s [Linear] forward time = %.2lfms\n", m->op_name, elapsed); // print_tensor(acc_input.ptr, acc_input.rect.volume(), // "[Linear:forward:input]"); print_tensor(acc_kernel.ptr, @@ -139,29 +159,45 @@ void backward_kernel_wrapper(LinearMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } - Internal::backward_kernel(m, - input_ptr, - input_grad_ptr, - output_ptr, - output_grad_ptr, - kernel_ptr, - kernel_grad_ptr, - bias_grad_ptr, - in_dim, - out_dim, - batch_size, - stream); + if (m->input_type[0] == DT_FLOAT) { + Internal::backward_kernel(m, + input_ptr, + input_grad_ptr, + output_ptr, + output_grad_ptr, + kernel_ptr, + kernel_grad_ptr, + bias_grad_ptr, + in_dim, + out_dim, + batch_size, + stream); + } else if (m->input_type[0] == DT_HALF) { + Internal::backward_kernel(m, + input_ptr, + input_grad_ptr, + output_ptr, + output_grad_ptr, + kernel_ptr, + kernel_grad_ptr, + bias_grad_ptr, + in_dim, + out_dim, + batch_size, + stream); + } + if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("%s Linear backward time = %.2lfms\n", m->op_name, elapsed); // print_tensor(acc_output_grad.ptr, acc_output_grad.rect.volume(), // "[Linear:backward:output_grad]"); @@ -189,7 +225,7 @@ Parameter* Linear::get_parameter(int index) */ namespace Internal { - +template void forward_kernel(LinearMeta const *m, void const *input_ptr, void *output_ptr, @@ -201,15 +237,16 @@ void forward_kernel(LinearMeta const *m, hipStream_t stream) { checkCUDA(hipblasSetStream(m->handle.blas, stream)); checkCUDNN(miopenSetStream(m->handle.dnn, stream)); - float alpha = 1.0f, beta = 0.0f; - hipblasDatatype_t input_type = ff_to_cuda_datatype(m->input_type); - hipblasDatatype_t weight_type = ff_to_cuda_datatype(m->weight_type); - hipblasDatatype_t output_type = ff_to_cuda_datatype(m->output_type); -#if CUDA_VERSION >= 11000 - // TODO: currently set the default to CUBLAS_COMPUTE_16F for best performance - cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + DT alpha = 1.0f, beta = 0.0f; + hipblasDatatype_t input_type = ff_to_cuda_datatype(m->input_type[0]); + hipblasDatatype_t weight_type = ff_to_cuda_datatype(m->weight_type[0]); + hipblasDatatype_t output_type = ff_to_cuda_datatype(m->output_type[0]); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = output_type; #else - hipblasDatatype_t compute_type = HIPBLAS_R_32F; + // TODO: currently use the output_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = output_type; #endif checkCUDA(hipblasGemmEx(m->handle.blas, HIPBLAS_OP_T, @@ -242,8 +279,8 @@ void forward_kernel(LinearMeta const *m, bias_ptr, weight_type, 1, - m->one_ptr, - HIPBLAS_R_32F, + static_cast
(m->one_ptr), + weight_type, 1, &alpha, output_ptr, @@ -281,6 +318,7 @@ void forward_kernel(LinearMeta const *m, } } +template void backward_kernel(LinearMeta const *m, void const *input_ptr, void *input_grad_ptr, @@ -296,23 +334,24 @@ void backward_kernel(LinearMeta const *m, checkCUDA(hipblasSetStream(m->handle.blas, stream)); checkCUDNN(miopenSetStream(m->handle.dnn, stream)); - float alpha = 1.0f; - hipblasDatatype_t input_type = ff_to_cuda_datatype(m->input_type); - hipblasDatatype_t weight_type = ff_to_cuda_datatype(m->weight_type); - hipblasDatatype_t output_type = ff_to_cuda_datatype(m->output_type); -#if CUDA_VERSION >= 11000 - // TODO: currently set the default to CUBLAS_COMPUTE_16F for best performance - cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + DT alpha = 1.0f; + hipblasDatatype_t input_type = ff_to_cuda_datatype(m->input_type[0]); + hipblasDatatype_t weight_type = ff_to_cuda_datatype(m->weight_type[0]); + hipblasDatatype_t output_type = ff_to_cuda_datatype(m->output_type[0]); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = output_type; #else - hipblasDatatype_t compute_type = HIPBLAS_R_32F; + // TODO: currently use output_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = output_type; #endif int output_size = out_dim * batch_size; if (m->activation == AC_MODE_RELU) { relu_backward_kernel( - m->output_type, output_grad_ptr, output_ptr, output_size, stream); + m->output_type[0], output_grad_ptr, output_ptr, output_size, stream); } else if (m->activation == AC_MODE_SIGMOID) { sigmoid_backward_kernel( - m->output_type, output_grad_ptr, output_ptr, output_size, stream); + m->output_type[0], output_grad_ptr, output_ptr, output_size, stream); } else { // TODO: only support relu and sigmoid for now assert(m->activation == AC_MODE_NONE); diff --git a/src/ops/kernels/linear_kernels.cu b/src/ops/kernels/linear_kernels.cu index 3f408c7cb0..c30c9f71c1 100644 --- a/src/ops/kernels/linear_kernels.cu +++ b/src/ops/kernels/linear_kernels.cu @@ -13,29 +13,64 @@ * limitations under the License. */ +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/decompress_kernels.h" #include "flexflow/ops/kernels/linear_kernels.h" #include "flexflow/utils/cuda_helper.h" namespace FlexFlow { -LinearMeta::LinearMeta(FFHandler handler, int batch_size) : OpMeta(handler) { +LinearMeta::LinearMeta(FFHandler handler, + int batch_size, + Linear const *li, + MemoryAllocator gpu_mem_allocator, + int weightSize) + : OpMeta(handler, li), weight_ptr(nullptr) { + DataType data_type = li->data_type; + // allocate weight and bias in the reserve space for cpu offloading + if (li->offload) { + weight_ptr = gpu_mem_allocator.allocate_reserved_untyped( + weightSize * data_type_size(data_type)); + if (li->quantization_type != DT_NONE) { + quantized_weightSize = get_quantization_to_byte_size( + data_type, li->quantization_type, weightSize); + quantized_weight_ptr = + gpu_mem_allocator.allocate_reserved(quantized_weightSize); + } + } // Allocate an all-one's vector - float *dram_one_ptr = (float *)malloc(sizeof(float) * batch_size); - for (int i = 0; i < batch_size; i++) { - dram_one_ptr[i] = 1.0f; + gpu_mem_allocator.create_legion_instance( + reserveInst, data_type_size(data_type) * batch_size); + one_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * batch_size); + int parallelism = batch_size; + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + if (data_type == DT_FLOAT) { + Kernels::Linear::Internal:: + build_one_ptr<<>>((float *)one_ptr, batch_size); + } else if (data_type == DT_HALF) { + Kernels::Linear::Internal:: + build_one_ptr<<>>((half *)one_ptr, batch_size); } - float *fb_one_ptr; - checkCUDA(cudaMalloc(&fb_one_ptr, sizeof(float) * batch_size)); - checkCUDA(cudaMemcpy(fb_one_ptr, - dram_one_ptr, - sizeof(float) * batch_size, - cudaMemcpyHostToDevice)); - one_ptr = (float const *)fb_one_ptr; + // Allocate descriptors checkCUDNN(cudnnCreateActivationDescriptor(&actiDesc)); checkCUDNN(cudnnCreateTensorDescriptor(&outputTensor)); } +LinearMeta::~LinearMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + namespace Kernels { namespace Linear { @@ -70,13 +105,14 @@ void init_kernel(LinearMeta *m, int batch_size, int channel) { } checkCUDNN(cudnnSetActivationDescriptor( m->actiDesc, mode, CUDNN_PROPAGATE_NAN, 0.0)); - checkCUDNN(cudnnSetTensor4dDescriptor(m->outputTensor, - CUDNN_TENSOR_NCHW, - ff_to_cudnn_datatype(m->output_type), - batch_size, - channel, - 1, - 1)); + checkCUDNN( + cudnnSetTensor4dDescriptor(m->outputTensor, + CUDNN_TENSOR_NCHW, + ff_to_cudnn_datatype(m->output_type[0]), + batch_size, + channel, + 1, + 1)); } } @@ -90,22 +126,33 @@ void forward_kernel_wrapper(LinearMeta const *m, int batch_size) { cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); - cudaEvent_t t_start, t_end; if (m->profiling) { cudaEventCreate(&t_start); cudaEventCreate(&t_end); cudaEventRecord(t_start, stream); } - Internal::forward_kernel(m, - input_ptr, - output_ptr, - weight_ptr, - bias_ptr, - in_dim, - out_dim, - batch_size, - stream); + if (m->input_type[0] == DT_FLOAT) { + Internal::forward_kernel(m, + input_ptr, + output_ptr, + weight_ptr, + bias_ptr, + in_dim, + out_dim, + batch_size, + stream); + } else if (m->input_type[0] == DT_HALF) { + Internal::forward_kernel(m, + input_ptr, + output_ptr, + weight_ptr, + bias_ptr, + in_dim, + out_dim, + batch_size, + stream); + } if (m->profiling) { cudaEventRecord(t_end, stream); @@ -143,18 +190,34 @@ void backward_kernel_wrapper(LinearMeta const *m, cudaEventCreate(&t_end); cudaEventRecord(t_start, stream); } - Internal::backward_kernel(m, - input_ptr, - input_grad_ptr, - output_ptr, - output_grad_ptr, - kernel_ptr, - kernel_grad_ptr, - bias_grad_ptr, - in_dim, - out_dim, - batch_size, - stream); + if (m->input_type[0] == DT_FLOAT) { + Internal::backward_kernel(m, + input_ptr, + input_grad_ptr, + output_ptr, + output_grad_ptr, + kernel_ptr, + kernel_grad_ptr, + bias_grad_ptr, + in_dim, + out_dim, + batch_size, + stream); + } else if (m->input_type[0] == DT_HALF) { + Internal::backward_kernel(m, + input_ptr, + input_grad_ptr, + output_ptr, + output_grad_ptr, + kernel_ptr, + kernel_grad_ptr, + bias_grad_ptr, + in_dim, + out_dim, + batch_size, + stream); + } + if (m->profiling) { cudaEventRecord(t_end, stream); checkCUDA(cudaEventSynchronize(t_end)); @@ -189,6 +252,19 @@ Parameter* Linear::get_parameter(int index) */ namespace Internal { +template +__global__ void AddBiasWithReLU(DT *output_ptr, + DT const *bias_ptr, + int out_dim, + int batch_size) { + CUDA_KERNEL_LOOP(i, out_dim * batch_size) { + int bias_idx = i % out_dim; + DT value = output_ptr[i] + bias_ptr[bias_idx]; + output_ptr[i] = ((float)value > 0.0f) ? value : (DT)0.0f; + } +} + +template void forward_kernel(LinearMeta const *m, void const *input_ptr, void *output_ptr, @@ -198,17 +274,65 @@ void forward_kernel(LinearMeta const *m, int out_dim, int batch_size, ffStream_t stream) { + // additional processing for uploading weights + if (m->offload) { + // Note that we update weight_ptr when uploading weight + if (m->quantization_type != DT_NONE) { + cudaMemcpyAsync(m->quantized_weight_ptr, + weight_ptr, + m->quantized_weightSize, + cudaMemcpyHostToDevice, + stream); + if (m->quantization_type == DT_INT4) { + int parallelism = in_dim * out_dim / 2; + decompress_int4_general_weights
+ <<>>(m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + in_dim, + in_dim * out_dim); + } else { + assert(m->quantization_type == DT_INT8); + int parallelism = in_dim * out_dim; + decompress_int8_general_weights
+ <<>>(m->quantized_weight_ptr, + static_cast
(m->weight_ptr), + in_dim, + in_dim * out_dim); + } + + } else { + cudaMemcpyAsync(m->weight_ptr, + weight_ptr, + in_dim * out_dim * sizeof(DT), + cudaMemcpyHostToDevice, + stream); + } + } checkCUDA(cublasSetStream(m->handle.blas, stream)); checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); - float alpha = 1.0f, beta = 0.0f; - cudaDataType_t input_type = ff_to_cuda_datatype(m->input_type); - cudaDataType_t weight_type = ff_to_cuda_datatype(m->weight_type); - cudaDataType_t output_type = ff_to_cuda_datatype(m->output_type); -#if CUDA_VERSION >= 11000 - // TODO: currently set the default to CUBLAS_COMPUTE_16F for best performance - cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + DT alpha = 1.0f, beta = 0.0f; + cudaDataType_t input_type = ff_to_cuda_datatype(m->input_type[0]); + cudaDataType_t weight_type = m->offload + ? ff_to_cuda_datatype(m->weight_ptr_type) + : ff_to_cuda_datatype(m->weight_type[0]); + cudaDataType_t output_type = ff_to_cuda_datatype(m->output_type[0]); + assert(input_type == weight_type && weight_type == output_type); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; #else - cudaDataType_t compute_type = CUDA_R_32F; + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } #endif checkCUDA(cublasGemmEx(m->handle.blas, CUBLAS_OP_T, @@ -217,7 +341,7 @@ void forward_kernel(LinearMeta const *m, batch_size, in_dim, &alpha, - weight_ptr, + m->offload ? m->weight_ptr : weight_ptr, weight_type, in_dim, input_ptr, @@ -231,6 +355,16 @@ void forward_kernel(LinearMeta const *m, CUBLAS_GEMM_DEFAULT_TENSOR_OP)); // use_bias = True if (bias_ptr != NULL) { + // fuse bias and relu + if (m->activation == AC_MODE_RELU) { + int parallelism = out_dim * batch_size; + AddBiasWithReLU<<>>( + static_cast
(output_ptr), + static_cast
(bias_ptr), + out_dim, + batch_size); + return; + } checkCUDA(cublasGemmEx(m->handle.blas, CUBLAS_OP_T, CUBLAS_OP_N, @@ -241,8 +375,8 @@ void forward_kernel(LinearMeta const *m, bias_ptr, weight_type, 1, - m->one_ptr, - CUDA_R_32F, + static_cast
(m->one_ptr), + weight_type, 1, &alpha, output_ptr, @@ -273,6 +407,7 @@ void forward_kernel(LinearMeta const *m, } } +template void backward_kernel(LinearMeta const *m, void const *input_ptr, void *input_grad_ptr, @@ -288,23 +423,29 @@ void backward_kernel(LinearMeta const *m, checkCUDA(cublasSetStream(m->handle.blas, stream)); checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); - float alpha = 1.0f; - cudaDataType_t input_type = ff_to_cuda_datatype(m->input_type); - cudaDataType_t weight_type = ff_to_cuda_datatype(m->weight_type); - cudaDataType_t output_type = ff_to_cuda_datatype(m->output_type); -#if CUDA_VERSION >= 11000 - // TODO: currently set the default to CUBLAS_COMPUTE_16F for best performance - cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + DT alpha = 1.0f; + float sgeam_alpha = 1.0f; + cudaDataType_t input_type = ff_to_cuda_datatype(m->input_type[0]); + cudaDataType_t weight_type = ff_to_cuda_datatype(m->weight_type[0]); + cudaDataType_t output_type = ff_to_cuda_datatype(m->output_type[0]); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; #else - cudaDataType_t compute_type = CUDA_R_32F; + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } #endif int output_size = out_dim * batch_size; if (m->activation == AC_MODE_RELU) { relu_backward_kernel( - m->output_type, output_grad_ptr, output_ptr, output_size, stream); + m->output_type[0], output_grad_ptr, output_ptr, output_size, stream); } else if (m->activation == AC_MODE_SIGMOID) { sigmoid_backward_kernel( - m->output_type, output_grad_ptr, output_ptr, output_size, stream); + m->output_type[0], output_grad_ptr, output_ptr, output_size, stream); } else { // TODO: only support relu and sigmoid for now assert(m->activation == AC_MODE_NONE); @@ -338,7 +479,7 @@ void backward_kernel(LinearMeta const *m, CUBLAS_OP_N, in_dim, out_dim, - &alpha, + &sgeam_alpha, (float *)kernel_grad_ptr, in_dim, &(m->kernel_reg_lambda), @@ -361,7 +502,7 @@ void backward_kernel(LinearMeta const *m, out_dim, batch_size, &alpha, - m->one_ptr, + static_cast
(m->one_ptr), CUDA_R_32F, 1, output_grad_ptr, @@ -399,6 +540,13 @@ void backward_kernel(LinearMeta const *m, } } +template +__global__ void build_one_ptr(DT *one_ptr, int batch_size) { + CUDA_KERNEL_LOOP(i, batch_size) { + one_ptr[i] = static_cast
(1.0f); + } +} + } // namespace Internal } // namespace Linear } // namespace Kernels diff --git a/src/ops/kernels/pool_2d_kernels.cpp b/src/ops/kernels/pool_2d_kernels.cpp index f302969559..8af85612ca 100644 --- a/src/ops/kernels/pool_2d_kernels.cpp +++ b/src/ops/kernels/pool_2d_kernels.cpp @@ -75,21 +75,21 @@ void forward_kernel_wrapper(Pool2DMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel(m, input_ptr, output_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); // print_tensor<4, float>(acc_input.ptr, acc_input.rect, // "[Pool2D:forward:input]"); print_tensor<4, float>(acc_output.ptr, // acc_output.rect, "[Pool2D:forward:output]"); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("%s [Pool2D] forward time = %.2fms\n", m->op_name, elapsed); } } @@ -104,19 +104,19 @@ void backward_kernel_wrapper(Pool2DMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel( m, input_ptr, input_grad_ptr, output_ptr, output_grad_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); printf("Pool2D backward time = %.2fms\n", elapsed); } } diff --git a/src/ops/kernels/residual_rms_norm_kernels.cpp b/src/ops/kernels/residual_rms_norm_kernels.cpp new file mode 100644 index 0000000000..6906556452 --- /dev/null +++ b/src/ops/kernels/residual_rms_norm_kernels.cpp @@ -0,0 +1,227 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/kernels/residual_rms_norm_kernels.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/residual_rms_norm.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +ResidualRMSNormMeta::ResidualRMSNormMeta(FFHandler handler, + ResidualRMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, rms) { + eps = rms->eps; + alpha = 1.0f; + beta = 0.0f; + + in_dim = rms->data_dim; + batch_size = rms->effective_batch_size; + num_elements = in_dim * batch_size; + + DataType data_type = rms->weights[0]->data_type; + size_t rms_ptr_size = batch_size; + size_t norm_ptr_size = num_elements; + size_t totalSize = (rms_ptr_size + norm_ptr_size) * data_type_size(data_type); + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + rms_ptr = gpu_mem_allocator.allocate_instance_untyped( + rms_ptr_size * data_type_size(data_type)); + norm_ptr = gpu_mem_allocator.allocate_instance_untyped( + norm_ptr_size * data_type_size(data_type)); +} +ResidualRMSNormMeta::~ResidualRMSNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +namespace Kernels { +namespace ResidualRMSNorm { + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (min(blockDim.x, max_num_threads) / C10_WARP_SIZE)) + ? shared[lid] + : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void ResidualRMSNormFusedForwardKernel(int64_t N, + float eps, + T const *X1, + T const *X2, + T *X_out, + T *rms, + T *Y, + T const *weights, + T *output) { + __shared__ float v_shared[C10_WARP_SIZE]; + int64_t const i = blockIdx.x; + float sum = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + int64_t const index = i * N + j; + X_out[index] = X1[index] + X2[index]; + sum += + (static_cast(X_out[index]) * static_cast(X_out[index])); + } + sum = BlockReduceSum( + sum, + v_shared, + min(blockDim.x, + kCUDABlockReduceNumThreads)); // use BlockReduceSum() to sum X_ij^2 + + if (threadIdx.x == 0) { + rms[i] = static_cast(rsqrt((sum / static_cast(N)) + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + Y[index] = static_cast(X_out[index]) * static_cast(rms[i]); + output[index] = Y[index] * weights[index % N]; + } +} + +template +void forward_kernel(ResidualRMSNormMeta const *m, + T const *input1_ptr, + T const *input2_ptr, + T const *weight_ptr, + T *residual_output_ptr, + T *output_ptr, + hipStream_t stream) { + std::pair kernel1_parallelism = + std::make_pair(m->batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + hipLaunchKernelGGL(HIP_KERNEL_NAME(ResidualRMSNormFusedForwardKernel), + num_blocks, + num_threads, + 0, + stream, + m->in_dim, + m->eps, + input1_ptr, + input2_ptr, + residual_output_ptr, + static_cast(m->rms_ptr), + static_cast(m->norm_ptr), + weight_ptr, + output_ptr); +} + +void forward_kernel_wrapper(ResidualRMSNormMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &residual_output, + GenericTensorAccessorW const &output) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + assert(input1.data_type == input2.data_type); + assert(output.data_type == input1.data_type); + assert(weight.data_type == output.data_type); + assert(residual_output.data_type == output.data_type); + + if (output.data_type == DT_HALF) { + forward_kernel(m, + input1.get_half_ptr(), + input2.get_half_ptr(), + weight.get_half_ptr(), + residual_output.get_half_ptr(), + output.get_half_ptr(), + stream); + } else if (output.data_type == DT_FLOAT) { + forward_kernel(m, + input1.get_float_ptr(), + input2.get_float_ptr(), + weight.get_float_ptr(), + residual_output.get_float_ptr(), + output.get_float_ptr(), + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("[ResidualRMSNorm] forward time (CF) = %.2fms\n", elapsed); + } +} + +} // namespace ResidualRMSNorm +} // namespace Kernels +} // namespace FlexFlow diff --git a/src/ops/kernels/residual_rms_norm_kernels.cu b/src/ops/kernels/residual_rms_norm_kernels.cu new file mode 100644 index 0000000000..17ac14449b --- /dev/null +++ b/src/ops/kernels/residual_rms_norm_kernels.cu @@ -0,0 +1,224 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/residual_rms_norm_kernels.h" +#include "flexflow/ops/residual_rms_norm.h" +#include "flexflow/utils/cuda_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +ResidualRMSNormMeta::ResidualRMSNormMeta(FFHandler handler, + ResidualRMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, rms) { + eps = rms->eps; + alpha = 1.0f; + beta = 0.0f; + + in_dim = rms->data_dim; + batch_size = rms->effective_batch_size; + num_elements = in_dim * batch_size; + + DataType data_type = rms->weights[0]->data_type; + size_t rms_ptr_size = batch_size; + size_t norm_ptr_size = num_elements; + size_t totalSize = (rms_ptr_size + norm_ptr_size) * data_type_size(data_type); + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + rms_ptr = gpu_mem_allocator.allocate_instance_untyped( + rms_ptr_size * data_type_size(data_type)); + norm_ptr = gpu_mem_allocator.allocate_instance_untyped( + norm_ptr_size * data_type_size(data_type)); +} +ResidualRMSNormMeta::~ResidualRMSNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +namespace Kernels { +namespace ResidualRMSNorm { + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (min(blockDim.x, max_num_threads) / C10_WARP_SIZE)) + ? shared[lid] + : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void ResidualRMSNormFusedForwardKernel(int64_t N, + float eps, + T const *X1, + T const *X2, + T *X_out, + T *rms, + T *Y, + T const *weights, + T *output) { + __shared__ float v_shared[C10_WARP_SIZE]; + int64_t const i = blockIdx.x; + float sum = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + int64_t const index = i * N + j; + X_out[index] = X1[index] + X2[index]; + sum += + (static_cast(X_out[index]) * static_cast(X_out[index])); + } + sum = BlockReduceSum( + sum, + v_shared, + min(blockDim.x, + kCUDABlockReduceNumThreads)); // use BlockReduceSum() to sum X_ij^2 + + if (threadIdx.x == 0) { + rms[i] = static_cast(rsqrt((sum / static_cast(N)) + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + Y[index] = static_cast(X_out[index]) * static_cast(rms[i]); + output[index] = Y[index] * weights[index % N]; + } +} + +template +void forward_kernel(ResidualRMSNormMeta const *m, + T const *input1_ptr, + T const *input2_ptr, + T const *weight_ptr, + T *residual_output_ptr, + T *output_ptr, + cudaStream_t stream) { + + std::pair kernel1_parallelism = + std::make_pair(m->batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + ResidualRMSNormFusedForwardKernel + <<>>(m->in_dim, + m->eps, + input1_ptr, + input2_ptr, + residual_output_ptr, + static_cast(m->rms_ptr), + static_cast(m->norm_ptr), + weight_ptr, + output_ptr); +} + +void forward_kernel_wrapper(ResidualRMSNormMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &residual_output, + GenericTensorAccessorW const &output) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + assert(input1.data_type == input2.data_type); + assert(output.data_type == input1.data_type); + assert(weight.data_type == output.data_type); + assert(residual_output.data_type == output.data_type); + if (output.data_type == DT_HALF) { + forward_kernel(m, + input1.get_half_ptr(), + input2.get_half_ptr(), + weight.get_half_ptr(), + residual_output.get_half_ptr(), + output.get_half_ptr(), + stream); + } else if (output.data_type == DT_FLOAT) { + forward_kernel(m, + input1.get_float_ptr(), + input2.get_float_ptr(), + weight.get_float_ptr(), + residual_output.get_float_ptr(), + output.get_float_ptr(), + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[ResidualRMSNorm] forward time (CF) = %.2fms\n", elapsed); + } +} + +} // namespace ResidualRMSNorm +} // namespace Kernels +} // namespace FlexFlow diff --git a/src/ops/kernels/rms_norm_kernels.cpp b/src/ops/kernels/rms_norm_kernels.cpp new file mode 100644 index 0000000000..24ab7051e6 --- /dev/null +++ b/src/ops/kernels/rms_norm_kernels.cpp @@ -0,0 +1,209 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/kernels/rms_norm_kernels.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +RMSNormMeta::RMSNormMeta(FFHandler handler, + RMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, rms) { + eps = rms->eps; + alpha = 1.0f; + beta = 0.0f; + + in_dim = rms->data_dim; + batch_size = rms->effective_batch_size; + num_elements = in_dim * batch_size; + + DataType data_type = rms->weights[0]->data_type; + size_t rms_ptr_size = batch_size; + size_t norm_ptr_size = num_elements; + size_t totalSize = (rms_ptr_size + norm_ptr_size) * data_type_size(data_type); + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + rms_ptr = gpu_mem_allocator.allocate_instance_untyped( + rms_ptr_size * data_type_size(data_type)); + norm_ptr = gpu_mem_allocator.allocate_instance_untyped( + norm_ptr_size * data_type_size(data_type)); +} +RMSNormMeta::~RMSNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +namespace Kernels { +namespace RMSNorm { + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (min(blockDim.x, max_num_threads) / C10_WARP_SIZE)) + ? shared[lid] + : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void RMSNormFusedForwardKernel(int64_t N, + float eps, + T const *X, + T *rms, + T *Y, + T const *weights, + T *output) { + __shared__ float v_shared[C10_WARP_SIZE]; + int64_t const i = blockIdx.x; + float sum = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + int64_t const index = i * N + j; + sum += (static_cast(X[index]) * static_cast(X[index])); + } + sum = BlockReduceSum( + sum, + v_shared, + min(blockDim.x, + kCUDABlockReduceNumThreads)); // use BlockReduceSum() to sum X_ij^2 + + if (threadIdx.x == 0) { + rms[i] = static_cast(rsqrt((sum / static_cast(N)) + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + Y[index] = static_cast(X[index]) * static_cast(rms[i]); + output[index] = Y[index] * weights[index % N]; + } +} + +template +void forward_kernel(RMSNormMeta const *m, + T const *input_ptr, + T const *weight_ptr, + T *output_ptr, + hipStream_t stream) { + std::pair kernel1_parallelism = + std::make_pair(m->batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + hipLaunchKernelGGL(HIP_KERNEL_NAME(RMSNormFusedForwardKernel), + num_blocks, + num_threads, + 0, + stream, + m->in_dim, + m->eps, + input_ptr, + static_cast(m->rms_ptr), + static_cast(m->norm_ptr), + weight_ptr, + output_ptr); +} + +void forward_kernel_wrapper(RMSNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + assert(output.data_type == input.data_type); + assert(weight.data_type == output.data_type); + if (output.data_type == DT_HALF) { + forward_kernel(m, + input.get_half_ptr(), + weight.get_half_ptr(), + output.get_half_ptr(), + stream); + } else if (output.data_type == DT_FLOAT) { + forward_kernel(m, + input.get_float_ptr(), + weight.get_float_ptr(), + output.get_float_ptr(), + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + } +} + +} // namespace RMSNorm +} // namespace Kernels +} // namespace FlexFlow diff --git a/src/ops/kernels/rms_norm_kernels.cu b/src/ops/kernels/rms_norm_kernels.cu new file mode 100644 index 0000000000..7c9f4a9f98 --- /dev/null +++ b/src/ops/kernels/rms_norm_kernels.cu @@ -0,0 +1,266 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/rms_norm_kernels.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/utils/cuda_helper.h" +#include + +namespace FlexFlow { +// declare Legion names +using Legion::coord_t; + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +RMSNormMeta::RMSNormMeta(FFHandler handler, + RMSNorm const *rms, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, rms) { + eps = rms->eps; + alpha = 1.0f; + beta = 0.0f; + + in_dim = rms->data_dim; + batch_size = rms->effective_batch_size; + num_elements = in_dim * batch_size; + + DataType data_type = rms->weights[0]->data_type; + size_t rms_ptr_size = batch_size; + size_t norm_ptr_size = num_elements; + size_t totalSize = (rms_ptr_size + norm_ptr_size) * data_type_size(data_type); + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + rms_ptr = gpu_mem_allocator.allocate_instance_untyped( + rms_ptr_size * data_type_size(data_type)); + norm_ptr = gpu_mem_allocator.allocate_instance_untyped( + norm_ptr_size * data_type_size(data_type)); +} +RMSNormMeta::~RMSNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +namespace Kernels { +namespace RMSNorm { + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (blockDim.x / C10_WARP_SIZE)) ? shared[lid] : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (min(blockDim.x, max_num_threads) / C10_WARP_SIZE)) + ? shared[lid] + : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +#ifdef DEADCODE +template +__global__ void + RowwiseRootMeanSquareKernel(long long N, float eps, T const *X, T *rms) { + __shared__ float v_shared[C10_WARP_SIZE]; + long long const i = blockIdx.x; + float sum = 0.0f; + for (long long j = threadIdx.x; j < N; j += blockDim.x) { + long long const index = i * N + j; + sum += (static_cast(X[index]) * static_cast(X[index])); + } + sum = BlockReduceSum(sum, + v_shared); // use BlockReduceSum() to sum X_ij^2 + + if (threadIdx.x == 0) { + rms[i] = static_cast(rsqrt((sum / static_cast(N)) + eps)); + } +} + +template +__global__ void NormKernel(int64_t N, T const *X, T const *rstd, T *Y) { + using T_ACC = T; + const int64_t i = blockIdx.x; + for (int64_t j = threadIdx.x; j < N; j += blockDim.x) { + const int64_t index = i * N + j; + Y[index] = static_cast(X[index]) * static_cast(rstd[i]); + } +} + +template +__global__ void elewise_apply_weights(int64_t batch_size, + int64_t in_dim, + T const *norm, + T const *weights, + T *output) { + CUDA_KERNEL_LOOP(i, batch_size * in_dim) { + output[i] = norm[i] * weights[i % in_dim]; + } +} +#endif + +template +__global__ void RMSNormFusedForwardKernel(int64_t N, + float eps, + T const *X, + T *rms, + T *Y, + T const *weights, + T *output) { + __shared__ float v_shared[C10_WARP_SIZE]; + int64_t const i = blockIdx.x; + float sum = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + int64_t const index = i * N + j; + sum += (static_cast(X[index]) * static_cast(X[index])); + } + sum = BlockReduceSum( + sum, + v_shared, + min(blockDim.x, + kCUDABlockReduceNumThreads)); // use BlockReduceSum() to sum X_ij^2 + + if (threadIdx.x == 0) { + rms[i] = static_cast(rsqrt((sum / static_cast(N)) + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + Y[index] = static_cast(X[index]) * static_cast(rms[i]); + output[index] = Y[index] * weights[index % N]; + } +} + +template +void forward_kernel(RMSNormMeta const *m, + T const *input_ptr, + T const *weight_ptr, + T *output_ptr, + cudaStream_t stream) { + + std::pair kernel1_parallelism = + std::make_pair(m->batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + RMSNormFusedForwardKernel + <<>>(m->in_dim, + m->eps, + input_ptr, + static_cast(m->rms_ptr), + static_cast(m->norm_ptr), + weight_ptr, + output_ptr); +} + +void forward_kernel_wrapper(RMSNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + assert(output.data_type == input.data_type); + assert(weight.data_type == output.data_type); + if (output.data_type == DT_HALF) { + forward_kernel(m, + input.get_half_ptr(), + weight.get_half_ptr(), + output.get_half_ptr(), + stream); + } else if (output.data_type == DT_FLOAT) { + forward_kernel(m, + input.get_float_ptr(), + weight.get_float_ptr(), + output.get_float_ptr(), + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[RMSNorm] forward time (CF) = %.2fms\n", elapsed); + } +} + +} // namespace RMSNorm +} // namespace Kernels +} // namespace FlexFlow diff --git a/src/ops/kernels/softmax.cpp b/src/ops/kernels/softmax.cpp index 6df6351bb0..c4b3394181 100644 --- a/src/ops/kernels/softmax.cpp +++ b/src/ops/kernels/softmax.cpp @@ -27,64 +27,69 @@ SoftmaxMeta::SoftmaxMeta(FFHandler handler, Domain const &input_domain) : OpMeta(handler) { checkCUDNN(miopenCreateTensorDescriptor(&inputTensor)); - // checkCUDNN(cudnnSetTensorDescriptorFromDomain(inputTensor, input_domain)); checkCUDNN( cudnnSetTensorDescriptorFromDomain4SoftMax(inputTensor, input_domain)); + checkCUDNN(miopenCreateTensorDescriptor(&outputTensor)); + checkCUDNN( + cudnnSetTensorDescriptorFromDomain4SoftMax(outputTensor, input_domain)); dim = softmax->dim; last_layer = softmax->last_layer; profiling = softmax->profiling; + inference_debugging = softmax->inference_debugging; std::strcpy(op_name, softmax->name); } namespace Kernels { namespace Softmax { +template void forward_kernel_wrapper(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr) { + DT const *input_ptr, + DT *output_ptr) { hipStream_t stream; checkCUDA(get_legion_stream(&stream)); hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::forward_kernel(m, input_ptr, output_ptr, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); // print_tensor(acc_input.ptr, acc_input.rect.volume(), // "[Softmax:forward:input]"); print_tensor(acc_output.ptr, // acc_output.rect.volume(), "[Softmax:forward:output]"); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); log_measure.debug( "%s [Softmax] forward time = %.2fms\n", m->op_name, elapsed); } } +template void backward_kernel_wrapper(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements) { hipStream_t stream; checkCUDA(get_legion_stream(&stream)); hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } Internal::backward_kernel( m, input_grad_ptr, output_grad_ptr, output_ptr, num_elements, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); // print_tensor(acc_output_grad.ptr, acc_output_grad.rect.volume(), // "[Softmax:backward:output_grad]"); @@ -92,17 +97,33 @@ void backward_kernel_wrapper(SoftmaxMeta const *m, // "[Softmax:backward:input_grad]"); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); log_measure.debug("Softmax backward time = %.2fms\n", elapsed); } } -namespace Internal { +template void forward_kernel_wrapper(SoftmaxMeta const *m, + float const *input_ptr, + float *output_ptr); +template void forward_kernel_wrapper(SoftmaxMeta const *m, + half const *input_ptr, + half *output_ptr); + +template void backward_kernel_wrapper(SoftmaxMeta const *m, + float *input_grad_ptr, + float const *output_grad_ptr, + size_t num_elements); +template void backward_kernel_wrapper(SoftmaxMeta const *m, + half *input_grad_ptr, + half const *output_grad_ptr, + size_t num_elements); +namespace Internal { +template void forward_kernel(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr, + DT const *input_ptr, + DT *output_ptr, hipStream_t stream) { checkCUDNN(miopenSetStream(m->handle.dnn, stream)); @@ -112,22 +133,23 @@ void forward_kernel(SoftmaxMeta const *m, m->inputTensor, input_ptr, &beta, - m->inputTensor, + m->outputTensor, output_ptr, MIOPEN_SOFTMAX_ACCURATE, MIOPEN_SOFTMAX_MODE_CHANNEL)); } +template void backward_kernel(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements, hipStream_t stream) { if (m->last_layer) { checkCUDA(hipMemcpyAsync(input_grad_ptr, output_grad_ptr, - num_elements * sizeof(float), + num_elements * sizeof(DT), hipMemcpyDeviceToDevice, stream)); } else { diff --git a/src/ops/kernels/softmax.cu b/src/ops/kernels/softmax.cu index e163c9a0c7..2d180c1f49 100644 --- a/src/ops/kernels/softmax.cu +++ b/src/ops/kernels/softmax.cu @@ -28,21 +28,25 @@ SoftmaxMeta::SoftmaxMeta(FFHandler handler, checkCUDNN(cudnnCreateTensorDescriptor(&inputTensor)); checkCUDNN(cudnnSetTensorDescriptorFromDomain4SoftMax( inputTensor, input_domain, softmax->data_type)); + checkCUDNN(cudnnCreateTensorDescriptor(&outputTensor)); + checkCUDNN(cudnnSetTensorDescriptorFromDomain4SoftMax( + outputTensor, input_domain, softmax->data_type)); dim = softmax->dim; last_layer = softmax->last_layer; profiling = softmax->profiling; + inference_debugging = softmax->inference_debugging; std::strcpy(op_name, softmax->name); } namespace Kernels { namespace Softmax { +template void forward_kernel_wrapper(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr) { + DT const *input_ptr, + DT *output_ptr) { cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); - cudaEvent_t t_start, t_end; if (m->profiling) { cudaEventCreate(&t_start); @@ -65,10 +69,11 @@ void forward_kernel_wrapper(SoftmaxMeta const *m, } } +template void backward_kernel_wrapper(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements) { cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); @@ -96,11 +101,26 @@ void backward_kernel_wrapper(SoftmaxMeta const *m, } } -namespace Internal { +template void forward_kernel_wrapper(SoftmaxMeta const *m, + float const *input_ptr, + float *output_ptr); +template void forward_kernel_wrapper(SoftmaxMeta const *m, + half const *input_ptr, + half *output_ptr); +template void backward_kernel_wrapper(SoftmaxMeta const *m, + float *input_grad_ptr, + float const *output_grad_ptr, + size_t num_elements); +template void backward_kernel_wrapper(SoftmaxMeta const *m, + half *input_grad_ptr, + half const *output_grad_ptr, + size_t num_elements); +namespace Internal { +template void forward_kernel(SoftmaxMeta const *m, - float const *input_ptr, - float *output_ptr, + DT const *input_ptr, + DT *output_ptr, cudaStream_t stream) { checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); @@ -112,21 +132,22 @@ void forward_kernel(SoftmaxMeta const *m, m->inputTensor, input_ptr, &beta, - m->inputTensor, + m->outputTensor, output_ptr)); } +template void backward_kernel(SoftmaxMeta const *m, - float *input_grad_ptr, - float const *output_grad_ptr, - float const *output_ptr, + DT *input_grad_ptr, + DT const *output_grad_ptr, + DT const *output_ptr, size_t num_elements, cudaStream_t stream) { if (m->last_layer) { checkCUDA(cudaMemcpyAsync(input_grad_ptr, output_grad_ptr, - num_elements * sizeof(float), + num_elements * sizeof(DT), cudaMemcpyDeviceToDevice, stream)); } else { diff --git a/src/ops/layer_norm.cc b/src/ops/layer_norm.cc index ccbd7c2dd6..a89a9cd0fe 100644 --- a/src/ops/layer_norm.cc +++ b/src/ops/layer_norm.cc @@ -41,7 +41,8 @@ using Legion::TaskLauncher; bool operator==(LayerNormParams const &lhs, LayerNormParams const &rhs) { return lhs.layer_guid == rhs.layer_guid && lhs.axes == rhs.axes && - lhs.elementwise_affine == rhs.elementwise_affine; + lhs.elementwise_affine == rhs.elementwise_affine && + lhs.use_bias == rhs.use_bias; } bool LayerNormParams::is_valid(ParallelTensorShape const &input) const { @@ -54,6 +55,10 @@ LayerNormParams LayerNorm::get_params() const { params.axes = this->axes; params.elementwise_affine = this->elementwise_affine; params.eps = this->eps; + params.use_bias = this->use_bias; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -61,6 +66,7 @@ Tensor FFModel::layer_norm(const Tensor input, std::vector const &axes, bool elementwise_affine, float eps, + bool use_bias, DataType data_type, char const *name) { // In PyTorch, axes must be the sizes of the last axes.size() dimensions of @@ -97,7 +103,7 @@ Tensor FFModel::layer_norm(const Tensor input, if (data_type == DT_NONE) { data_type = input->data_type; } - int num_weights = elementwise_affine ? 2 : 0; + int num_weights = elementwise_affine ? (use_bias ? 2 : 1) : 0; Layer *ln = nullptr; if (data_type != input->data_type) { Tensor casted_input = cast(input, data_type, "type cast for layer_norm"); @@ -139,15 +145,18 @@ Tensor FFModel::layer_norm(const Tensor input, true /*create_grad*/, nullptr, CHOSEN_SYNC_TYPE); - ln->weights[1] = create_weight_legion_ordering(numdims, - dims, - input->data_type, - ln, - true /*create_grad*/, - nullptr, - CHOSEN_SYNC_TYPE); + if (num_weights == 2) { + ln->weights[1] = create_weight_legion_ordering(numdims, + dims, + input->data_type, + ln, + true /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + } } ln->add_int_property("elementwise_affine", elementwise_affine); + ln->add_int_property("use_bias", use_bias); ln->add_int_vector_property("axes", axes); ln->add_float_property("eps", eps); layers.push_back(ln); @@ -161,6 +170,8 @@ Op *LayerNorm::create_operator_from_layer( long long value; layer->get_int_property("elementwise_affine", value); bool elementwise_affine = (bool)value; + layer->get_int_property("use_bias", value); + bool use_bias = (bool)value; std::vector axes; layer->get_int_vector_property("axes", axes); float eps; @@ -170,6 +181,7 @@ Op *LayerNorm::create_operator_from_layer( inputs[0], axes, elementwise_affine, + use_bias, eps, false, // allocate_weights layer->name); @@ -185,15 +197,17 @@ LayerNorm::LayerNorm(FFModel &model, input, params.axes, params.elementwise_affine, + params.use_bias, params.eps, allocate_weights, - name) {} + params.name) {} LayerNorm::LayerNorm(FFModel &model, LayerID const &_layer_guid, const ParallelTensor _input, std::vector const &_axes, bool _elementwise_affine, + bool _use_bias, float _eps, bool allocate_weights, char const *name) @@ -202,10 +216,11 @@ LayerNorm::LayerNorm(FFModel &model, _input->data_type, name, 1 /*inputs*/, - _elementwise_affine ? 2 : 0 /*weights*/, + _elementwise_affine ? (_use_bias ? 2 : 1) : 0 /*weights*/, 1 /*outputs*/, _input), - elementwise_affine(_elementwise_affine), eps(_eps), axes(_axes) { + elementwise_affine(_elementwise_affine), eps(_eps), axes(_axes), + use_bias(_use_bias) { // overwrite layer_guid layer_guid = _layer_guid; outputs[0] = model.create_parallel_tensor_legion_ordering( @@ -216,15 +231,22 @@ LayerNorm::LayerNorm(FFModel &model, for (int i = 0; i < axes.size(); i++) { M *= inputs[0]->dims[axes[i]].size; } + int num_replicas = 1; + for (int i = 0; i < inputs[0]->num_dims; i++) { + if (inputs[0]->dims[i].is_replica_dim) { + num_replicas *= inputs[0]->dims[i].size; + } + } effective_num_elements = M; - effective_batch_size = inputs[0]->get_volume() / M; - assert(elementwise_affine == (numWeights == 2)); + effective_batch_size = (inputs[0]->get_volume() / num_replicas) / M; + assert(use_bias == (numWeights == 2)); if (numWeights > 0 && allocate_weights) { - ParallelDim dims[axes.size() + 1]; - int num_dims = axes.size(); - for (int i = 0; i < num_dims; i++) { - dims[i] = inputs[0]->dims[i]; + assert(elementwise_affine); + ParallelTensorShape beta_gamma_shape = _input->get_shape(); + for (int i = axes.size(); i < beta_gamma_shape.num_dims - 1; i++) { + beta_gamma_shape.dims[i].size = 1; } + assert(numInputs == 1); dims[num_dims].degree = inputs[0]->dims[inputs[0]->num_dims - 1].degree; dims[num_dims].size = dims[num_dims].degree; @@ -234,25 +256,82 @@ LayerNorm::LayerNorm(FFModel &model, num_dims += 1; int seed = std::rand(); - Initializer *gamma_initializer = new UniformInitializer(seed, 0.0f, 1.0f); - Initializer *beta_initializer = new UniformInitializer(seed, 0.0f, 1.0f); - weights[0] = - model.create_parallel_weight_legion_ordering(num_dims, - dims, - _input->data_type, - NULL /*owner_op*/, - true /*create_grad*/, - gamma_initializer, - CHOSEN_SYNC_TYPE); - weights[1] = - model.create_parallel_weight_legion_ordering(num_dims, - dims, - _input->data_type, - NULL /*owner_op*/, - true /*create_grad*/, - beta_initializer, - CHOSEN_SYNC_TYPE); + Initializer *gamma_initializer = new UniformInitializer(seed, 1.0f, 1.0f); + weights[0] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, // axes.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + true /*create_grad*/, + gamma_initializer, + CHOSEN_SYNC_TYPE); + if (numWeights == 2) { + assert(use_bias); + Initializer *beta_initializer = new UniformInitializer(seed, 0.0f, 0.0f); + weights[1] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, //.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + true /*create_grad*/, + beta_initializer, + CHOSEN_SYNC_TYPE); + } + } +} + +void LayerNorm::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(LAYERNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(LayerNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(1, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(3, FID_DATA); + } } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); } void LayerNorm::init(FFModel const &ff) { @@ -289,12 +368,14 @@ void LayerNorm::init(FFModel const &ff) { EXCLUSIVE, weights[0]->region)); launcher.add_field(2, FID_DATA); - launcher.add_region_requirement(RegionRequirement(weights[1]->part, - 0 /*projection id*/, - READ_ONLY, - EXCLUSIVE, - weights[1]->region)); - launcher.add_field(3, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(3, FID_DATA); + } } FutureMap fm = runtime->execute_index_space(ctx, launcher); fm.wait_all_results(); @@ -307,7 +388,14 @@ OpMeta *LayerNorm::init_task(Task const *task, Runtime *runtime) { LayerNorm *ln = (LayerNorm *)task->args; FFHandler handle = *((FFHandler const *)task->local_args); - LayerNormMeta *meta = new LayerNormMeta(handle, ln); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + LayerNormMeta *meta = new LayerNormMeta(handle, ln, gpu_mem_allocator); + std::strcpy(meta->op_name, ln->name); + meta->layer_guid = ln->layer_guid; meta->input_type[0] = ln->inputs[0]->data_type; meta->output_type[0] = ln->outputs[0]->data_type; return meta; @@ -341,20 +429,166 @@ void LayerNorm::forward(FFModel const &ff) { if (elementwise_affine) { launcher.add_region_requirement(RegionRequirement(weights[0]->part, 0 /*projection id*/, - READ_WRITE, + READ_ONLY, EXCLUSIVE, weights[0]->region)); - launcher.add_field(2, FID_DATA); - launcher.add_region_requirement(RegionRequirement(weights[1]->part, - 0 /*projection id*/, - READ_WRITE, - EXCLUSIVE, - weights[1]->region)); + if (use_bias) { + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + } + launcher.add_field(3, FID_DATA); } runtime->execute_index_space(ctx, launcher); } +FutureMap LayerNorm::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "LayerNorm op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(LAYERNORM_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(3, FID_DATA); + } + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input + regions[1](O): output + regions[2](I/O): gamma + regions[3](I/O): beta +*/ +void LayerNorm::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + + LayerNormMeta *m = *((LayerNormMeta **)task->local_args); + assert(task->regions.size() == regions.size()); + float const *in_ptr = NULL; + float *out_ptr = NULL, *gamma_ptr = NULL, *beta_ptr = NULL; + GenericTensorAccessorR in, gamma, beta; + GenericTensorAccessorW out; + + Domain in_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + // in_ptr = helperGetTensorPointerRO( + // regions[0], task->regions[0], FID_DATA, ctx, runtime); + in = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + Domain out_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + // out_ptr = helperGetTensorPointerWO( + // regions[1], task->regions[1], FID_DATA, ctx, runtime); + out = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + assert(in_domain == out_domain); + assert(in_domain.get_volume() == + m->effective_num_elements * m->effective_batch_size); + if (m->elementwise_affine) { + assert(m->use_bias == (regions.size() == 4)); + Domain gamma_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + gamma = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + if (m->use_bias) { + Domain beta_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + beta = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + assert(gamma_domain == beta_domain); + } + + assert(gamma_domain.get_volume() == m->effective_num_elements); + int numdims = gamma_domain.get_dim(); + size_t vol = 1; + int i = 0; + while (vol < gamma_domain.get_volume()) { + int g_d = gamma_domain.hi()[i] - gamma_domain.lo()[i] + 1; + int in_d = in_domain.hi()[i] - in_domain.lo()[i] + 1; + assert(g_d == in_d); + vol *= g_d; + i++; + } + } else { + assert(regions.size() == 2); + } + + LayerNorm::forward_kernel_wrapper(m, in, out, gamma, beta); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + if (m->elementwise_affine) { + weights_accessors.push_back(gamma); + if (m->use_bias) { + weights_accessors.push_back(beta); + } + } + LayerNorm::save_inference_tensors_to_file( + m, shard_id, bc, {in}, weights_accessors, {out}); + } +} + /* regions[0](I): input regions[1](O): output @@ -369,8 +603,8 @@ void LayerNorm::forward_task(Task const *task, assert(task->regions.size() == regions.size()); float const *in_ptr = NULL; float *out_ptr = NULL, *gamma_ptr = NULL, *beta_ptr = NULL; - GenericTensorAccessorR in; - GenericTensorAccessorW out, gamma, beta; + GenericTensorAccessorR in, gamma, beta; + GenericTensorAccessorW out; Domain in_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); @@ -389,26 +623,33 @@ void LayerNorm::forward_task(Task const *task, // m->effective_num_elements * m->effective_batch_size); if (m->elementwise_affine) { - assert(regions.size() == 4); + assert(m->use_bias == (regions.size() == 4)); Domain gamma_domain = runtime->get_index_space_domain( ctx, task->regions[2].region.get_index_space()); - // gamma_ptr = helperGetTensorPointerRW( - // regions[2], task->regions[2], FID_DATA, ctx, runtime); - gamma = helperGetGenericTensorAccessorRW( + gamma = helperGetGenericTensorAccessorRO( m->input_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); - Domain beta_domain = runtime->get_index_space_domain( - ctx, task->regions[3].region.get_index_space()); - // beta_ptr = helperGetTensorPointerRW( - // regions[3], task->regions[3], FID_DATA, ctx, runtime); - beta = helperGetGenericTensorAccessorRW( - m->input_type[0], regions[3], task->regions[3], FID_DATA, ctx, runtime); - assert(gamma_domain == beta_domain); + if (m->use_bias) { + Domain beta_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + beta = helperGetGenericTensorAccessorRO(m->input_type[0], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + assert(gamma_domain == beta_domain); + } + assert(gamma_domain.get_volume() == m->effective_num_elements); - int numdims = gamma_domain.get_dim() - 1; - for (int i = 0; i < numdims; i++) { + int numdims = gamma_domain.get_dim(); + size_t vol = 1; + int i = 0; + while (vol < gamma_domain.get_volume()) { int g_d = gamma_domain.hi()[i] - gamma_domain.lo()[i] + 1; int in_d = in_domain.hi()[i] - in_domain.lo()[i] + 1; assert(g_d == in_d); + vol *= g_d; + i++; } } else { assert(regions.size() == 2); @@ -466,12 +707,15 @@ void LayerNorm::backward(FFModel const &ff) { weights[0]->region_grad)); launcher.add_field(4, FID_DATA); // regions[5](I/O): beta_grad - launcher.add_region_requirement(RegionRequirement(weights[1]->part_grad, - 0 /*projection id*/, - READ_WRITE, - EXCLUSIVE, - weights[1]->region_grad)); - launcher.add_field(5, FID_DATA); + if (use_bias) { + launcher.add_region_requirement( + RegionRequirement(weights[1]->part_grad, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + weights[1]->region_grad)); + launcher.add_field(5, FID_DATA); + } } runtime->execute_index_space(ctx, launcher); } @@ -508,7 +752,7 @@ void LayerNorm::backward_task(Task const *task, // assert(in_domain.get_volume() == // m->effective_num_elements * m->effective_batch_size); if (m->elementwise_affine) { - assert(regions.size() == 6); + assert(m->use_bias == (regions.size() == 6)); Domain gamma_domain = runtime->get_index_space_domain( ctx, task->regions[3].region.get_index_space()); gamma_ptr = helperGetTensorPointerRO( @@ -517,12 +761,16 @@ void LayerNorm::backward_task(Task const *task, ctx, task->regions[4].region.get_index_space()); gamma_grad_ptr = helperGetTensorPointerRW( regions[4], task->regions[4], FID_DATA, ctx, runtime); - Domain beta_grad_domain = runtime->get_index_space_domain( - ctx, task->regions[5].region.get_index_space()); - beta_grad_ptr = helperGetTensorPointerRW( - regions[5], task->regions[5], FID_DATA, ctx, runtime); + if (m->use_bias) { + Domain beta_grad_domain = runtime->get_index_space_domain( + ctx, task->regions[5].region.get_index_space()); + beta_grad_ptr = helperGetTensorPointerRW( + regions[5], task->regions[5], FID_DATA, ctx, runtime); + assert(gamma_domain == beta_grad_domain); + } + assert(gamma_domain == gamma_grad_domain); - assert(gamma_domain == beta_grad_domain); + assert(gamma_domain.get_volume() == m->effective_num_elements); } else { assert(regions.size() == 3); @@ -549,7 +797,7 @@ bool LayerNorm::measure_operator_cost(Simulator *sim, } Domain input_domain = sub_input.get_domain(); Domain output_domain = sub_output.get_domain(); - LayerNormMeta *m = new LayerNormMeta(sim->handler, this); + LayerNormMeta *m = sim->layernorm_meta; sim->free_all(); float *in_ptr = (float *)sim->allocate(sub_input.get_volume(), DT_FLOAT); @@ -565,8 +813,9 @@ bool LayerNorm::measure_operator_cost(Simulator *sim, // FIXME please add gamma_ptr and beta_ptr after finish the implementation float *gamma_ptr = NULL, *beta_ptr = NULL; - GenericTensorAccessorR gamma_acc; - GenericTensorAccessorR beta_acc; + GenericTensorAccessorW gamma_acc; + GenericTensorAccessorW beta_acc; + bool out_of_memory = (in_ptr == NULL) || (out_ptr == NULL) || @@ -605,7 +854,7 @@ bool LayerNorm::measure_operator_cost(Simulator *sim, return true; } - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, out_grad_ptr, in_ptr, @@ -638,12 +887,17 @@ bool LayerNorm::measure_operator_cost(Simulator *sim, void LayerNorm::serialize(Legion::Serializer &sez) const { sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); sez.serialize(this->axes.size()); for (size_t i = 0; i < this->axes.size(); i++) { sez.serialize(this->axes[i]); } sez.serialize(this->elementwise_affine); sez.serialize(this->eps); + sez.serialize(this->use_bias); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -656,10 +910,13 @@ Node LayerNorm::deserialize(FFModel &ff, size_t num_axes; std::vector axes; bool elementwise_affine; + bool use_bias; float eps; - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); dez.deserialize(num_axes); for (size_t i = 0; i < num_axes; i++) { int axis_idx; @@ -668,12 +925,19 @@ Node LayerNorm::deserialize(FFModel &ff, } dez.deserialize(elementwise_affine); dez.deserialize(eps); + dez.deserialize(use_bias); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); LayerNormParams params; params.layer_guid = layer_guid; params.axes = axes; params.elementwise_affine = elementwise_affine; params.eps = eps; + params.use_bias = use_bias; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } @@ -696,6 +960,7 @@ size_t hash::operator()( hash_combine(key, n); } hash_combine(key, params.elementwise_affine); + hash_combine(key, params.use_bias); return key; } }; // namespace std diff --git a/src/ops/layer_norm.cpp b/src/ops/layer_norm.cpp index 8ea2ebba9a..1b13ba968a 100644 --- a/src/ops/layer_norm.cpp +++ b/src/ops/layer_norm.cpp @@ -25,11 +25,14 @@ constexpr int kCUDABlockReduceNumThreads = 512; constexpr int kCUDANumThreads = 256; constexpr int kColwiseReduceTileSize = 32; -LayerNormMeta::LayerNormMeta(FFHandler handle, LayerNorm const *ln) +LayerNormMeta::LayerNormMeta(FFHandler handle, + LayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) : OpMeta(handle) { elementwise_affine = ln->elementwise_affine; effective_batch_size = ln->effective_batch_size; effective_num_elements = ln->effective_num_elements; + use_bias = ln->use_bias; eps = ln->eps; // checkCUDA(hipMalloc(&mean_ptr, sizeof(float) * effective_batch_size)); // checkCUDA(hipMalloc(&rstd_ptr, sizeof(float) * effective_batch_size)); @@ -53,6 +56,8 @@ LayerNormMeta::LayerNormMeta(FFHandler handle, LayerNorm const *ln) hipMalloc(&bias_ptr, data_type_size(data_type) * effective_batch_size)); } +LayerNormMeta::~LayerNormMeta(void) {} + template __device__ __forceinline__ T WARP_SHFL_DOWN(T value, unsigned int delta, @@ -177,22 +182,20 @@ void LayerNorm::forward_kernel_wrapper(LayerNormMeta const *m, GenericTensorAccessorR const &beta) { hipStream_t stream; checkCUDA(get_legion_stream(&stream)); - // LayerNorm::forward_kernel( - // m, in_ptr, out_ptr, gamma_ptr, beta_ptr, stream); - if (m->input_type[0] == DT_FLOAT) { LayerNorm::forward_kernel(m, input.get_float_ptr(), output.get_float_ptr(), gamma.get_float_ptr(), - beta.get_float_ptr(), + m->use_bias ? beta.get_float_ptr() + : nullptr, stream); } else if (m->input_type[0] == DT_HALF) { LayerNorm::forward_kernel(m, input.get_half_ptr(), output.get_half_ptr(), gamma.get_half_ptr(), - beta.get_half_ptr(), + m->use_bias ? beta.get_half_ptr() : nullptr, stream); } else { assert(false && "unsupport datatype in layernorm"); @@ -489,6 +492,7 @@ void LayerNorm::backward_kernel(LayerNormMeta const *m, static_cast(m->db_ptr), static_cast(m->scale_ptr), static_cast(m->bias_ptr)); + int const warp_size = C10_WARP_SIZE; int const num_threads = 128; const dim3 blocks(M); @@ -566,12 +570,7 @@ void LayerNorm::backward_kernel_wrapper(LayerNormMeta const *m, stream); } -// template void LayerNorm::forward_kernel_wrapper(LayerNormMeta const -// *m, -// float const *in_ptr, -// float *out_ptr, -// float *gamma_ptr, -// float *beta_ptr); + template void LayerNorm::backward_kernel_wrapper(LayerNormMeta const *m, float const *output_grad_ptr, diff --git a/src/ops/layer_norm.cu b/src/ops/layer_norm.cu index 736d122513..a921d9af41 100644 --- a/src/ops/layer_norm.cu +++ b/src/ops/layer_norm.cu @@ -24,26 +24,39 @@ constexpr int kCUDABlockReduceNumThreads = 512; constexpr int kCUDANumThreads = 256; constexpr int kColwiseReduceTileSize = 32; -LayerNormMeta::LayerNormMeta(FFHandler handle, LayerNorm const *ln) +LayerNormMeta::LayerNormMeta(FFHandler handle, + LayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) : OpMeta(handle) { elementwise_affine = ln->elementwise_affine; + use_bias = ln->use_bias; effective_batch_size = ln->effective_batch_size; effective_num_elements = ln->effective_num_elements; profiling = ln->profiling; + inference_debugging = ln->inference_debugging; eps = ln->eps; DataType data_type = ln->data_type; - checkCUDA( - cudaMalloc(&mean_ptr, data_type_size(data_type) * effective_batch_size)); - checkCUDA( - cudaMalloc(&rstd_ptr, data_type_size(data_type) * effective_batch_size)); - checkCUDA( - cudaMalloc(&ds_ptr, data_type_size(data_type) * effective_batch_size)); - checkCUDA( - cudaMalloc(&db_ptr, data_type_size(data_type) * effective_batch_size)); - checkCUDA( - cudaMalloc(&scale_ptr, data_type_size(data_type) * effective_batch_size)); - checkCUDA( - cudaMalloc(&bias_ptr, data_type_size(data_type) * effective_batch_size)); + size_t totalSize = effective_batch_size * data_type_size(data_type) * 6; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + mean_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + rstd_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + ds_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + db_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + scale_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + bias_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); +} + +LayerNormMeta::~LayerNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } + } template @@ -77,13 +90,33 @@ __inline__ __device__ T BlockReduceSum(T val, T *shared) { shared[wid] = val; } __syncthreads(); - val = (threadIdx.x < blockDim.x / C10_WARP_SIZE) ? shared[lid] : 0; + val = (threadIdx.x < (blockDim.x / C10_WARP_SIZE)) ? shared[lid] : T(0); + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < (min(blockDim.x, max_num_threads) / C10_WARP_SIZE)) + ? shared[lid] + : T(0); if (wid == 0) { val = WarpReduceSum(val); } return val; } +#ifdef DEADCODE template __global__ void RowwiseMomentsCUDAKernel( int64_t N, float eps, T const *X, T *mean, T *rstd) { @@ -129,6 +162,56 @@ __global__ void LayerNormForwardCUDAKernel(int64_t N, beta_v; } } +#endif + +template +__global__ void LayerNormFusedForwardKernel(int64_t N, + float eps, + T const *X, + T *mean, + T *rstd, + T const *gamma, + T const *beta, + T *Y) { + __shared__ float m_shared[C10_WARP_SIZE]; + __shared__ float v_shared[C10_WARP_SIZE]; + const int64_t i = blockIdx.x; + float sum1 = 0.0f; + float sum2 = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + const int64_t index = i * N + j; + sum1 += static_cast(X[index]); + sum2 += static_cast(X[index]) * static_cast(X[index]); + } + if (threadIdx.x < kCUDABlockReduceNumThreads) { + sum1 = BlockReduceSum( + sum1, m_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + sum2 = BlockReduceSum( + sum2, v_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + } + if (threadIdx.x == 0) { + float const scale = float(1) / static_cast(N); + sum1 *= scale; + sum2 = max(sum2 * scale - sum1 * sum1, float(0)); + mean[i] = static_cast(sum1); + rstd[i] = static_cast(rsqrt(sum2 + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + const T_ACC gamma_v = + gamma == nullptr ? T_ACC(1) : static_cast(gamma[j]); + const T_ACC beta_v = + beta == nullptr ? T_ACC(0) : static_cast(beta[j]); + Y[index] = (static_cast(X[index]) - static_cast(mean[i])) * + static_cast(rstd[i]) * gamma_v + + beta_v; + } +} /*static*/ template @@ -138,22 +221,25 @@ void LayerNorm::forward_kernel(LayerNormMeta const *m, T const *gamma_ptr, T const *beta_ptr, cudaStream_t stream) { - RowwiseMomentsCUDAKernel - <<effective_batch_size, kCUDABlockReduceNumThreads, 0, stream>>>( - m->effective_num_elements, - m->eps, - in_ptr, - static_cast(m->mean_ptr), - static_cast(m->rstd_ptr)); - LayerNormForwardCUDAKernel - <<effective_batch_size, kCUDANumThreads, 0, stream>>>( - m->effective_num_elements, - in_ptr, - static_cast(m->mean_ptr), - static_cast(m->rstd_ptr), - gamma_ptr, - beta_ptr, - out_ptr); + std::pair kernel1_parallelism = + std::make_pair(m->effective_batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->effective_batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + LayerNormFusedForwardKernel + <<>>(m->effective_num_elements, + m->eps, + in_ptr, + static_cast(m->mean_ptr), + static_cast(m->rstd_ptr), + gamma_ptr, + beta_ptr, + out_ptr); } /*static*/ @@ -172,19 +258,21 @@ void LayerNorm::forward_kernel_wrapper(LayerNormMeta const *m, cudaEventRecord(t_start, stream); } if (m->input_type[0] == DT_FLOAT) { - LayerNorm::forward_kernel(m, - input.get_float_ptr(), - output.get_float_ptr(), - gamma.get_float_ptr(), - beta.get_float_ptr(), - stream); + LayerNorm::forward_kernel( + m, + input.get_float_ptr(), + output.get_float_ptr(), + m->elementwise_affine ? gamma.get_float_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_float_ptr() : nullptr, + stream); } else if (m->input_type[0] == DT_HALF) { - LayerNorm::forward_kernel(m, - input.get_half_ptr(), - output.get_half_ptr(), - gamma.get_half_ptr(), - beta.get_half_ptr(), - stream); + LayerNorm::forward_kernel( + m, + input.get_half_ptr(), + output.get_half_ptr(), + m->elementwise_affine ? gamma.get_half_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_half_ptr() : nullptr, + stream); } else { assert(false && "unsupport datatype in layernorm"); } @@ -196,7 +284,7 @@ void LayerNorm::forward_kernel_wrapper(LayerNormMeta const *m, checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); cudaEventDestroy(t_start); cudaEventDestroy(t_end); - printf("[LayerNorm] forward time (CF) = %.2fms\n", elapsed); + printf("[LayerNorm] forward time (CF) = %.9fms\n", elapsed); // print_tensor(in_ptr, 32, "[LayerNorm:forward:input]"); // print_tensor(out_ptr, 32, "[LayerNorm:forward:output]"); } @@ -550,6 +638,17 @@ void LayerNorm::backward_kernel_wrapper(LayerNormMeta const *m, beta_grad_ptr, stream); } + // }else if(m->output_type[0] == DT_HALF){ + // LayerNorm::backward_kernel(m, + // output_grad_ptr, + // input_ptr, + // input_grad_ptr, + // gamma_ptr, + // gamma_grad_ptr, + // beta_grad_ptr, + // stream); + // } + } template void diff --git a/src/ops/linear.cc b/src/ops/linear.cc index 20cc193107..9ece39bc59 100644 --- a/src/ops/linear.cc +++ b/src/ops/linear.cc @@ -1,4 +1,5 @@ #include "flexflow/ops/linear.h" +#include "flexflow/ffconst_utils.h" #include "flexflow/layer.h" #include "flexflow/model.h" #include "flexflow/ops/kernels/linear_kernels.h" @@ -12,9 +13,12 @@ using Legion::ArgumentMap; using Legion::Context; using Legion::coord_t; using Legion::Domain; +using Legion::Future; using Legion::FutureMap; using Legion::IndexLauncher; using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; using Legion::PhysicalRegion; using Legion::Predicate; using Legion::Rect; @@ -40,14 +44,33 @@ Tensor FFModel::dense(const Tensor input, RegularizerMode kernel_reg_type, float kernel_reg_lambda, char const *name) { - Layer *li = new Layer(this, - OP_LINEAR, - data_type, - name, - 1 /*inputs*/, - use_bias ? 2 : 1 /*weights*/, - 1 /*outputs*/, - input); + if (data_type == DT_NONE) { + data_type = input->data_type; + } + DataType quantization_type = cpu_offload ? config.quantization_type : DT_NONE; + bool offload = cpu_offload; + Layer *li = nullptr; + if (data_type != input->data_type) { + Tensor casted_input = cast(input, data_type, "type cast for dense"); + li = new Layer(this, + OP_LINEAR, + data_type, + name, + 1 /*inputs*/, + use_bias ? 2 : 1 /*weights*/, + 1 /*outputs*/, + casted_input); + } else { + li = new Layer(this, + OP_LINEAR, + data_type, + name, + 1 /*inputs*/, + use_bias ? 2 : 1 /*weights*/, + 1 /*outputs*/, + input); + } + { int numdims = input->num_dims; int dims[MAX_TENSOR_DIM]; @@ -60,14 +83,18 @@ Tensor FFModel::dense(const Tensor input, } { int dims[2] = {input->dims[0], outDim}; - li->weights[KERNEL_IDX] = - create_weight_legion_ordering(2, - dims, - data_type, - li, - true /*create_grad*/, - kernel_initializer, - CHOSEN_SYNC_TYPE); + if (quantization_type != DT_NONE) { + dims[0] = + get_quantization_to_byte_size(data_type, quantization_type, dims[0]); + } + li->weights[KERNEL_IDX] = create_weight_legion_ordering( + 2, + dims, + quantization_type == DT_NONE ? data_type : quantization_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); } if (use_bias) { int dims[1] = {outDim}; @@ -84,6 +111,8 @@ Tensor FFModel::dense(const Tensor input, li->add_int_property("activation", activation); li->add_int_property("kernel_reg_type", kernel_reg_type); li->add_float_property("kernel_reg_lambda", kernel_reg_lambda); + li->add_int_property("quantization_type", quantization_type); + li->add_int_property("offload", offload); layers.push_back(li); return li->outputs[0]; } @@ -103,6 +132,10 @@ Op *Linear::create_operator_from_layer( RegularizerMode kernel_reg_type = (RegularizerMode)value; float kernel_reg_lambda; layer->get_float_property("kernel_reg_lambda", kernel_reg_lambda); + layer->get_int_property("quantization_type", value); + DataType quantization_type = (DataType)value; + layer->get_int_property("offload", value); + bool offload = (bool)value; return new Linear(model, layer->layer_guid, inputs[0], @@ -112,6 +145,8 @@ Op *Linear::create_operator_from_layer( kernel_reg_lambda, use_bias, layer->data_type, + quantization_type, + offload, false /*allocate_weights*/, layer->name); } @@ -133,6 +168,8 @@ Linear::Linear(FFModel &model, other.kernel_reg_lambda, other.use_bias, other.data_type, + other.quantization_type, + other.offload, allocate_weights, other.name) {} @@ -150,8 +187,10 @@ Linear::Linear(FFModel &model, params.kernel_reg_lambda, params.use_bias, params.data_type, + params.quantization_type, + params.offload, allocate_weights, - name) {} + params.name) {} Linear::Linear(FFModel &model, LayerID const &_layer_guid, @@ -162,6 +201,8 @@ Linear::Linear(FFModel &model, float _kernel_reg_lambda, bool _use_bias, DataType _data_type, + DataType _quantization_type, + bool _offload, bool allocate_weights, char const *name) : Op(model, @@ -175,6 +216,7 @@ Linear::Linear(FFModel &model, _input), out_channels(out_dim), activation(_activation), use_bias(_use_bias), kernel_reg_type(_kernel_reg_type), kernel_reg_lambda(_kernel_reg_lambda), + quantization_type(_quantization_type), offload(_offload), replica(ParallelTensorBase::NO_TENSOR) { // overwrite layer_guid layer_guid = _layer_guid; @@ -189,6 +231,22 @@ Linear::Linear(FFModel &model, LinearParams params = this->get_params(); params.construct_mappings(*this->parallel_dims_mapping, input_shape); params.solve_dims(input_shape, output_shape, kernel_shape, bias_shape); + kernel_shape.dims[0].size = this->in_channels; + bias_shape.dims[0].degree = _input->dims[_input->num_dims - 1].degree; + bias_shape.dims[0].parallel_idx = + _input->dims[_input->num_dims - 1].parallel_idx; + bias_shape.dims[1].size = bias_shape.dims[1].degree = 1; + bias_shape.dims[1].parallel_idx = -1; + bias_shape.dims[bias_shape.num_dims - 1].size = + bias_shape.dims[bias_shape.num_dims - 1].degree = 1; + for (int i = 0; i < input_shape.num_dims - 1; i++) { + if (_input->dims[i].degree > 1) { + bias_shape.dims[bias_shape.num_dims - 1].size *= _input->dims[i].degree; + bias_shape.dims[bias_shape.num_dims - 1].degree *= _input->dims[i].degree; + bias_shape.dims[bias_shape.num_dims - 1].parallel_idx = + _input->dims[i].parallel_idx; + } + } kernel_shape.dims[0].size = this->in_channels; bias_shape.dims[0].degree = _input->dims[_input->num_dims - 1].degree; @@ -209,15 +267,18 @@ Linear::Linear(FFModel &model, if (allocate_weights) { Initializer *kernel_initializer = new GlorotUniform(std::rand() /*seed*/); - - weights[KERNEL_IDX] = - model.create_parallel_weight_legion_ordering(kernel_shape.num_dims, - kernel_shape.dims, - _data_type, - NULL /*owner_op*/, - true /*create_grad*/, - kernel_initializer, - CHOSEN_SYNC_TYPE); + if (quantization_type != DT_NONE) { + kernel_shape.dims[0].size = get_quantization_to_byte_size( + data_type, quantization_type, kernel_shape.dims[0].size); + } + weights[KERNEL_IDX] = model.create_parallel_weight_legion_ordering( + kernel_shape.num_dims, + kernel_shape.dims, + quantization_type == DT_NONE ? _data_type : quantization_type, + NULL /*owner_op*/, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); if (use_bias) { Initializer *bias_initializer = new ZeroInitializer(); @@ -230,6 +291,7 @@ Linear::Linear(FFModel &model, true /*create_grad*/, bias_initializer, CHOSEN_SYNC_TYPE); + add_bias_only_once = _input->dims[0].degree > 1; } } @@ -259,18 +321,24 @@ void Linear::init(FFModel const &ff) { // RegionRequirement(input_lps[0], 0/*projection id*/, // READ_ONLY, EXCLUSIVE, inputs[0]->region)); // launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); launcher.add_region_requirement(RegionRequirement(outputs[0]->part, 0 /*projection id*/, WRITE_ONLY, EXCLUSIVE, outputs[0]->region)); - launcher.add_field(0, FID_DATA); + launcher.add_field(1, FID_DATA); launcher.add_region_requirement(RegionRequirement(weights[0]->part, 0 /*projection id*/, READ_ONLY, EXCLUSIVE, weights[0]->region)); - launcher.add_field(1, FID_DATA); + launcher.add_field(2, FID_DATA); // launcher.add_region_requirement( // RegionRequirement(weights[1]->part, 0/*projection id*/, // READ_ONLY, EXCLUSIVE, weights[1]->region)); @@ -287,6 +355,67 @@ void Linear::init(FFModel const &ff) { set_opmeta_from_futuremap(ff, fm); } +void Linear::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + // assert(check_output_input_weight_same_machine_view()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(LINEAR_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Linear)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // launcher.add_region_requirement( + // RegionRequirement(input_lps[0], 0/*projection id*/, + // READ_ONLY, EXCLUSIVE, inputs[0]->region)); + // launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(2, FID_DATA); + // launcher.add_region_requirement( + // RegionRequirement(weights[1]->part, 0/*projection id*/, + // READ_ONLY, EXCLUSIVE, weights[1]->region)); + // launcher.add_field(3, FID_DATA); + if (ff.config.computationMode == COMP_MODE_TRAINING) { + // Add inputs[0].region_grad to avoid Legion warning + // launcher.add_region_requirement( + // RegionRequirement(input_grad_lps[0], 0/*projection id*/, + // WRITE_ONLY, EXCLUSIVE, inputs[0].region_grad)); + // launcher.add_field(2, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + /* regions[0](O): output regions[1](I): kernel @@ -296,12 +425,37 @@ OpMeta *Linear::init_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - Domain out_domain = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - switch (out_domain.get_dim()) { + Linear const *linear = (Linear *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + GenericTensorAccessorW output = + helperGetGenericTensorAccessorWO(linear->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + switch (output.domain.get_dim()) { #define DIMFUNC(DIM) \ case DIM: \ - return init_task_with_dim(task, regions, ctx, runtime); + if (output.data_type == DT_HALF) { \ + if (linear->quantization_type != DT_NONE) { \ + return init_task_with_dim( \ + task, regions, ctx, runtime); \ + } else { \ + return init_task_with_dim( \ + task, regions, ctx, runtime); \ + } \ + } else if (output.data_type == DT_FLOAT) { \ + if (linear->quantization_type != DT_NONE) { \ + return init_task_with_dim( \ + task, regions, ctx, runtime); \ + } else { \ + return init_task_with_dim( \ + task, regions, ctx, runtime); \ + } \ + } else { \ + assert(false && "Unsupported data type"); \ + } LEGION_FOREACH_N(DIMFUNC) #undef DIMFUNC default: @@ -310,7 +464,7 @@ OpMeta *Linear::init_task(Task const *task, return NULL; } -template +template OpMeta *Linear::init_task_with_dim(Task const *task, std::vector const ®ions, Context ctx, @@ -321,39 +475,54 @@ OpMeta *Linear::init_task_with_dim(Task const *task, FFHandler handle = *((FFHandler const *)task->local_args); // TensorAccessorR acc_input( // regions[0], task->regions[0], FID_DATA, ctx, runtime); - TensorAccessorW acc_output(regions[0], - task->regions[0], - FID_DATA, - ctx, - runtime, - false /*readOutput*/); - TensorAccessorW acc_kernel(regions[1], - task->regions[1], - FID_DATA, - ctx, - runtime, - false /*readOutput*/); + TensorAccessorR acc_input( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + TensorAccessorW acc_output(regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime, + false /*readOutput*/); + TensorAccessorR acc_kernel( + regions[2], task->regions[2], FID_DATA, ctx, runtime); + // TensorAccessorR acc_bias( // regions[3], task->regions[3], FID_DATA, ctx, runtime); - // int in_dim = acc_input.rect.hi[0] - acc_input.rect.lo[0] + 1; - int in_dim = acc_kernel.rect.hi[0] - acc_kernel.rect.lo[0] + 1; + int in_dim = acc_input.rect.hi[0] - acc_input.rect.lo[0] + 1; + // int in_dim = acc_kernel.rect.hi[0] - acc_kernel.rect.lo[0] + 1; int out_dim = acc_output.rect.hi[0] - acc_output.rect.lo[0] + 1; int batch_size = acc_output.rect.volume() / out_dim; - printf("init linear (input): in_dim(%d) out_dim(%d) batch_size(%d)\n", - in_dim, - out_dim, - batch_size); - LinearMeta *m = new LinearMeta(handle, batch_size); + // printf("init linear (input): in_dim(%d) out_dim(%d) batch_size(%d)\n", + // in_dim, + // out_dim, + // batch_size); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + if (linear->offload) { + // cpu-offload enabled + // use offload_reserved_space + gpu_mem_allocator.register_reserved_work_space( + handle.offload_reserve_space, handle.offload_reserve_space_size); + } + + LinearMeta *m = new LinearMeta( + handle, batch_size, linear, gpu_mem_allocator, in_dim * out_dim); m->activation = linear->activation; m->kernel_reg_type = linear->kernel_reg_type; m->kernel_reg_lambda = linear->kernel_reg_lambda; m->use_bias = linear->use_bias; + m->add_bias_only_once = linear->add_bias_only_once; m->profiling = linear->profiling; + m->inference_debugging = linear->inference_debugging; m->trainableInputs[0] = linear->trainableInputs[0]; - m->input_type = linear->inputs[0]->data_type; - m->weight_type = linear->weights[0]->data_type; - m->output_type = linear->outputs[0]->data_type; + m->weight_ptr_type = m->input_type[0]; + m->quantization_type = linear->quantization_type; + m->offload = linear->offload; std::strcpy(m->op_name, linear->name); + m->layer_guid = linear->layer_guid; init_kernel(m, batch_size, out_dim); @@ -402,16 +571,154 @@ void Linear::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap Linear::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "Linear op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(LINEAR_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(2, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(3, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +void Linear::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + LinearMeta *m = *((LinearMeta **)task->local_args); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + assert(regions.size() == (3 + static_cast(m->use_bias))); + assert(task->regions.size() == (3 + static_cast(m->use_bias))); + if (m->quantization_type == DT_NONE) { + assert(m->input_type[0] == m->weight_type[0]); + } + assert(m->input_type[0] == m->output_type[0]); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + int in_dim = input.domain.hi()[0] - input.domain.lo()[0] + 1; + int out_dim = output.domain.hi()[0] - output.domain.lo()[0] + 1; + + int batch_size = bc->num_active_tokens(); + GenericTensorAccessorR bias; + if (m->use_bias && + !(m->add_bias_only_once && task->index_point.point_data[0] != 0)) { + bias = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + assert(bias.domain.get_volume() == static_cast(out_dim)); + } + forward_kernel_wrapper(m, + input.ptr, + output.ptr, + weight.ptr, + bias.ptr, + in_dim, + out_dim, + batch_size); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + weights_accessors.push_back(weight); + if (m->use_bias && + !(m->add_bias_only_once && task->index_point.point_data[0] != 0)) { + weights_accessors.push_back(bias); + } + Linear::save_inference_tensors_to_file( + m, shard_id, bc, {input}, weights_accessors, {output}); + } +} + void Linear::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - Domain in_domain = runtime->get_index_space_domain( + Domain input_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); - switch (in_domain.get_dim()) { + LinearMeta const *m = *((LinearMeta **)task->local_args); + if (m->quantization_type == DT_NONE) { + assert(m->input_type[0] == m->weight_type[0]); + } + assert(m->input_type[0] == m->output_type[0]); + switch (input_domain.get_dim()) { #define DIMFUNC(DIM) \ case DIM: \ - return forward_task_with_dim(task, regions, ctx, runtime); + if (m->output_type[0] == DT_HALF) { \ + if (m->quantization_type != DT_NONE) { \ + return forward_task_with_dim( \ + task, regions, ctx, runtime); \ + } else { \ + return forward_task_with_dim( \ + task, regions, ctx, runtime); \ + } \ + } else if (m->output_type[0] == DT_FLOAT) { \ + if (m->quantization_type != DT_NONE) { \ + return forward_task_with_dim( \ + task, regions, ctx, runtime); \ + } else { \ + return forward_task_with_dim( \ + task, regions, ctx, runtime); \ + } \ + } else { \ + assert(false && "Unsupported data type"); \ + } LEGION_FOREACH_N(DIMFUNC) #undef DIMFUNC default: @@ -425,7 +732,7 @@ void Linear::forward_task(Task const *task, regions[2](I): kernel regions[3](I): bias */ -template +template void Linear::forward_task_with_dim(Task const *task, std::vector const ®ions, Context ctx, @@ -435,25 +742,26 @@ void Linear::forward_task_with_dim(Task const *task, assert(regions.size() == (3 + static_cast(m->use_bias))); assert(task->regions.size() == (3 + static_cast(m->use_bias))); - TensorAccessorR acc_input( + TensorAccessorR acc_input( regions[0], task->regions[0], FID_DATA, ctx, runtime); - TensorAccessorW acc_output(regions[1], - task->regions[1], - FID_DATA, - ctx, - runtime, - false /*readOutput*/); - TensorAccessorR acc_kernel( + TensorAccessorW acc_output(regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime, + false /*readOutput*/); + TensorAccessorR acc_kernel( regions[2], task->regions[2], FID_DATA, ctx, runtime); int in_dim = acc_input.rect.hi[0] - acc_input.rect.lo[0] + 1; int out_dim = acc_output.rect.hi[0] - acc_output.rect.lo[0] + 1; int batch_size = acc_output.rect.volume() / out_dim; assert(acc_output.rect.volume() == static_cast(out_dim * batch_size)); - // assert(acc_input.rect.volume() == static_cast(in_dim * batch_size)); - assert(acc_kernel.rect.volume() == static_cast(in_dim * out_dim)); - float const *acc_bias_ptr = NULL; - if (m->use_bias) { - TensorAccessorR acc_bias( + assert(acc_input.rect.volume() == static_cast(in_dim * batch_size)); + // assert(acc_kernel.rect.volume() == static_cast(in_dim * out_dim)); + DT const *acc_bias_ptr = nullptr; + if (m->use_bias && + !(m->add_bias_only_once && task->index_point.point_data[0] != 0)) { + TensorAccessorR acc_bias( regions[3], task->regions[3], FID_DATA, ctx, runtime); assert(acc_bias.rect.volume() == static_cast(out_dim)); acc_bias_ptr = acc_bias.ptr; @@ -551,10 +859,21 @@ void Linear::backward_task(Task const *task, Runtime *runtime) { Domain in_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); + LinearMeta const *m = *((LinearMeta **)task->local_args); + if (m->quantization_type == DT_NONE) { + assert(m->input_type[0] == m->weight_type[0]); + } + assert(m->input_type[0] == m->output_type[0]); switch (in_domain.get_dim()) { #define DIMFUNC(DIM) \ case DIM: \ - return backward_task_with_dim(task, regions, ctx, runtime); + if (m->output_type[0] == DT_HALF) { \ + return backward_task_with_dim(task, regions, ctx, runtime); \ + } else if (m->output_type[0] == DT_FLOAT) { \ + return backward_task_with_dim(task, regions, ctx, runtime); \ + } else { \ + assert(false && "Unsupported data type"); \ + } LEGION_FOREACH_N(DIMFUNC) #undef DIMFUNC default: @@ -571,7 +890,7 @@ void Linear::backward_task(Task const *task, regions[5](I/O): filter_grad regions[6](I/O): bias_grad */ -template +template void Linear::backward_task_with_dim(Task const *task, std::vector const ®ions, Context ctx, @@ -583,9 +902,9 @@ void Linear::backward_task_with_dim(Task const *task, assert(task->regions.size() == (5 + static_cast(m->trainableInputs[0]) + static_cast(m->use_bias))); - float *input_grad = NULL; + DT *input_grad = nullptr; size_t rid = 0; - TensorAccessorR acc_input( + TensorAccessorR acc_input( regions[rid], task->regions[rid], FID_DATA, ctx, runtime); rid++; if (m->trainableInputs[0]) { @@ -593,39 +912,39 @@ void Linear::backward_task_with_dim(Task const *task, ctx, task->regions[rid].region.get_index_space()); if (domain.get_dim() == NDIM + 1) { assert(domain.get_volume() == acc_input.rect.volume()); - input_grad = helperGetTensorPointerWO( + input_grad = helperGetTensorPointerWO
( regions[rid], task->regions[rid], FID_DATA, ctx, runtime); } else { - TensorAccessorW acc_replica_grad(regions[rid], - task->regions[rid], - FID_DATA, - ctx, - runtime, - true /*readOutput*/); + TensorAccessorW acc_replica_grad(regions[rid], + task->regions[rid], + FID_DATA, + ctx, + runtime, + true /*readOutput*/); assert(acc_replica_grad.rect.volume() == acc_input.rect.volume()); input_grad = acc_replica_grad.ptr; } rid++; } - TensorAccessorR acc_output( + TensorAccessorR acc_output( regions[rid], task->regions[rid], FID_DATA, ctx, runtime); rid++; - TensorAccessorW acc_output_grad(regions[rid], - task->regions[rid], - FID_DATA, - ctx, - runtime, - true /*readOutput*/); + TensorAccessorW acc_output_grad(regions[rid], + task->regions[rid], + FID_DATA, + ctx, + runtime, + true /*readOutput*/); rid++; - TensorAccessorR acc_kernel( + TensorAccessorR acc_kernel( regions[rid], task->regions[rid], FID_DATA, ctx, runtime); rid++; - TensorAccessorW acc_kernel_grad(regions[rid], - task->regions[rid], - FID_DATA, - ctx, - runtime, - true /*readOutput*/); + TensorAccessorW acc_kernel_grad(regions[rid], + task->regions[rid], + FID_DATA, + ctx, + runtime, + true /*readOutput*/); rid++; // make sure the sizes match int in_dim = acc_input.rect.hi[0] - acc_input.rect.lo[0] + 1; @@ -637,17 +956,17 @@ void Linear::backward_task_with_dim(Task const *task, assert(acc_kernel.rect.volume() == static_cast(in_dim * out_dim)); assert(acc_kernel_grad.rect.volume() == static_cast(in_dim * out_dim)); - float *acc_bias_grad_ptr = NULL; + DT *acc_bias_grad_ptr = nullptr; if (m->use_bias) { - TensorAccessorW acc_bias_grad(regions[rid], - task->regions[rid], - FID_DATA, - ctx, - runtime, - true /*readOutput*/); + TensorAccessorW acc_bias_grad(regions[rid], + task->regions[rid], + FID_DATA, + ctx, + runtime, + true /*readOutput*/); rid++; assert(acc_bias_grad.rect.volume() == static_cast(out_dim)); - acc_bias_grad_ptr = static_cast(acc_bias_grad.ptr); + acc_bias_grad_ptr = static_cast
(acc_bias_grad.ptr); } assert(rid == regions.size()); @@ -823,9 +1142,9 @@ bool Linear::measure_operator_cost(Simulator *sim, m->activation = activation; m->kernel_reg_type = kernel_reg_type; m->kernel_reg_lambda = kernel_reg_lambda; - m->input_type = inputs[0]->data_type; - m->weight_type = this->data_type; - m->output_type = outputs[0]->data_type; + m->input_type[0] = inputs[0]->data_type; + m->weight_type[0] = this->data_type; + m->output_type[0] = outputs[0]->data_type; assert(m->profiling == false); init_kernel(m, output_n, output_c); @@ -891,7 +1210,7 @@ bool Linear::measure_operator_cost(Simulator *sim, cost_metrics.backward_time = Simulator::MAXIMUM_TASK_RUN_TIME; return true; } - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, input_ptr, input_grad_ptr, @@ -941,12 +1260,18 @@ bool operator==(LinearParams const &lhs, LinearParams const &rhs) { void Linear::serialize(Legion::Serializer &sez) const { sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); sez.serialize(this->out_channels); sez.serialize(this->activation); sez.serialize(this->kernel_reg_type); sez.serialize(this->kernel_reg_lambda); sez.serialize(this->use_bias); sez.serialize(this->data_type); + sez.serialize(this->quantization_type); + sez.serialize(this->offload); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } /* static */ @@ -962,15 +1287,25 @@ Node Linear::deserialize(FFModel &ff, float kernel_reg_lambda; bool use_bias; DataType data_type; - size_t id; + DataType quantization_type; + bool offload; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); dez.deserialize(out_channels); dez.deserialize(activation); dez.deserialize(kernel_reg_type); dez.deserialize(kernel_reg_lambda); dez.deserialize(use_bias); dez.deserialize(data_type); + dez.deserialize(quantization_type); + dez.deserialize(offload); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); LinearParams params; params.activation = activation; @@ -980,6 +1315,9 @@ Node Linear::deserialize(FFModel &ff, params.use_bias = use_bias; params.data_type = data_type; params.layer_guid = layer_guid; + params.quantization_type = quantization_type; + params.offload = offload; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } @@ -992,6 +1330,11 @@ LinearParams Linear::get_params() const { params.activation = this->activation; params.kernel_reg_type = this->kernel_reg_type; params.kernel_reg_lambda = this->kernel_reg_lambda; + params.quantization_type = this->quantization_type; + params.offload = this->offload; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -1015,6 +1358,11 @@ bool LinearParams::is_valid(ParallelTensorShape const &input_shape) const { return is_valid; } +/** @brief A wrapper around the main version of the solve_dims function. + * + * It takes a the input tensor as a parameter, instead of the input's + * ParallelTensorShape. + */ void LinearParams::solve_dims(const ParallelTensor input, ParallelDim output_dims[MAX_TENSOR_DIM], int *output_ndims, @@ -1031,6 +1379,13 @@ void LinearParams::solve_dims(const ParallelTensor input, bias_ndims); } +/** @brief A wrapper around the main version of the solve_dims function. + * + * For each of the output, weights, and bias tensors, it takes a + * ParallelTensorShape argument, instead of a pointer to an integer variable to + * record the number of dimensions, plus a ParallelDim array to record all the + * information regarding each dimension. + */ void LinearParams::solve_dims(ParallelTensorShape const &input_shape, ParallelTensorShape &output_shape, ParallelTensorShape &kernel_shape, @@ -1057,11 +1412,14 @@ void LinearParams::solve_dims(ParallelTensorShape const &input_shape, std::vector mapping; this->construct_mappings(mapping, input_shape); + // sets the is_replica_dim field to true for the dimensions that are used to + // record the number of replicas this->mark_replica_dims(input_shape, output_dims, kernel_dims, bias_dims); solve_parallel_dim_mappings( mapping, {input_shape.dims}, {kernel_dims, bias_dims}, {output_dims}); + // sets the dimension sizes of the output, weights, and bias tensors this->calculate_nonreplica_dim_sizes(input_shape, output_dims, output_ndims, @@ -1071,6 +1429,34 @@ void LinearParams::solve_dims(ParallelTensorShape const &input_shape, bias_ndims); } +/** @brief Create a map between each of a tensor's dimension name and its + * corresponding index + * + * The tensor dimension names are defined as follows. For the input tensor, the + * first dimension is called INPUT_CHANNEL, and generally corresponds to number + * of floats needed to store a single element from the input dataset. For + * example, when each element in the dataset is a flattened MNIST image, the + * INPUT_CHANNEL dimension will have a size of 28x28=784. The second to last and + * last dimensions in the input tensor are, respectively, the INPUT_SAMPLE and + * INPUT_REPLICA dimensions. The size of the INPUT_SAMPLE dimension generally + * corresponds to the batch size used for training. The size of the + * INPUT_REPLICA tells us how many replicas of the tensors have been created. + * The dimensions of the output tensor are named analogously: the first + * dimension is OUTPUT_CHANNEL, the second to last is OUTPUT_SAMPLE, and the + * last one is OUTPUT_REPLICA. Both the input and output tensor may have + * additional dimensions, without a name, between {INPUT,OUTPUT}_CHANNEL and + * {INPUT,OUTPUT}_SAMPLE. For instance, when the input data comes in textual + * form, it is common to have an additional dimension representing the sequence + * length. When it comes to the weights, the dimensions are named simply as + * KERNEL_CHANNEL_IN (first dimension of a weight's tensor), KERNEL_CHANNEL_OUT + * (second dimension) and BIAS_CHANNEL_OUT (first dimension of the bias tensor) + * + * @param[in] input_shape A ParallelTensorShape object representing the shape + * of the ParallelTensor used for the input to the operator + * @return dimension_names A map from each LinearParams::NamedDimensions to the + * index corresponding to that dimension in the input, weight, (bias), or output + * tensor. + */ std::unordered_map LinearParams::get_dimension_names( ParallelTensorShape const &input_shape) const { @@ -1087,6 +1473,43 @@ std::unordered_map {BIAS_CHANNEL_OUT, 0}}; } +/** @brief Sets the size field of ParallelDim objects passed as arguments to + * the expected (non-replica) dimensions of the output, weights, and bias + * tensors. In addition, it sets the output_ndims, kernel_ndims and bias_ndims + * variables to the number of dimensions (including the replica dimensions) of, + * respectively, the ouput, weights, and bias tensors. + * + * The number of dimensions, and dimension sizes of the output, weights, and + * bias dimensions are set as follows. The number of dimensions of all three + * tensors are copied from the dimensions of the input tensor. The replica + * dimensions are not subtracted or otherwise excluded. The size of the output + * tensor dimensions are also copied from the input tensor, with the exception + * of the last dimension (replica dimension), which is not set, and the first + * dimension, whose size is set equal to the out_channels member of the + * LinearParams struct, which in turn is set by the outDim parameter of the + * FModel::dense function. When it comes to the size of the weights dimensions, + * the first dimension is set to have size equal to the quotient of the size of + * the INPUT_CHANNEL dimension of the input (first dimension) and the degree + * (number of partitions) of the same input dimension. The second dimension of + * the the weights tensor is set equal to out_channels, just like the first + * dimension of the output tensor. Finally, the size of the first dimension of + * the bias tensor is also set equal to the value of out_channels. + * + * @param[in] input_shape A required argument recording the dimensions of + * the input tensor + * @param[out] output_dims An array of ParallelDim objects representing the + * dimensions of the output tensor + * @param[out] output_ndims The number of dimensions (including the replica + * dimension(s)) of the output tensor + * @param[out] kernel_dims An array of ParallelDim objects representing the + * dimensions of the weights tensor + * @param[out] kernel_ndims The number of dimensions (including the replica + * dimension(s)) of the weights tensor + * @param[out] bias_dims An array of ParallelDim objects representing the + * dimensions of the bias tensor + * @param[out] bias_ndims The number of dimensions (including the replica + * dimension(s)) of the bias tensor + */ void LinearParams::calculate_nonreplica_dim_sizes( ParallelTensorShape const &input_shape, ParallelDim output_dims[MAX_TENSOR_DIM], @@ -1119,6 +1542,20 @@ void LinearParams::calculate_nonreplica_dim_sizes( } } +/** @brief Switch the is_replica_dim field to true in each ParallelDim of + * the output, weight and bias tensor, if the corresponding dimension + * is used to keep track of the number of replicas + * + * @param[in] input_shape A required argument recording the dimensions of + * the input tensor + * @param[out] output_dims An array of ParallelDim objects representing the + * dimensions of the output tensor + * @param[out] kernel_dims An array of ParallelDim objects representing the + * dimensions of the weights tensor + * @param[out] bias_dims An array of ParallelDim objects representing the + * dimensions of the bias tensor + * + */ void LinearParams::mark_replica_dims( ParallelTensorShape const &input_shape, ParallelDim output_dims[MAX_TENSOR_DIM], @@ -1195,6 +1632,8 @@ size_t hash::operator()( hash_combine(key, params.activation); hash_combine(key, params.kernel_reg_type); hash_combine(key, params.kernel_reg_lambda); + hash_combine(key, params.quantization_type); + hash_combine(key, params.offload); return key; } }; // namespace std diff --git a/src/ops/noop.cc b/src/ops/noop.cc index 94fff30553..da2d4922e3 100644 --- a/src/ops/noop.cc +++ b/src/ops/noop.cc @@ -24,6 +24,7 @@ using Legion::coord_t; using Legion::Domain; using Legion::FutureMap; using Legion::IndexLauncher; +using Legion::IndexSpace; using Legion::InlineLauncher; using Legion::LogicalPartition; using Legion::LogicalRegion; @@ -94,8 +95,93 @@ OpMeta *NoOp::init_task(Task const *task, return m; } +void NoOp::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + parallel_is = batch_outputs[0]->parallel_is; + assert(parallel_is != IndexSpace::NO_SPACE); + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + if (op_type == OP_INPUT && batch_outputs[0]->initializer != nullptr) { + ConstantInitializer *initializer = + (ConstantInitializer *)batch_outputs[0]->initializer; + Runtime *runtime = ff.config.lg_hlr; + Context ctx = ff.config.lg_ctx; + ArgumentMap argmap; + IndexLauncher launcher( + CONSTANT_INIT_TASK_ID, + parallel_is, + TaskArgument(initializer, sizeof(ConstantInitializer)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + runtime->execute_index_space(ctx, launcher); + } else if (op_type == OP_INPUT) { + // For OP_INPUT, initialize tensor to zero + assert(batch_outputs[0]->region != LogicalRegion::NO_REGION); + if (batch_outputs[0]->part == LogicalPartition::NO_PART) { + return; + } + ConstantInitializer *initializer = NULL; + if (batch_outputs[0]->data_type == DT_FLOAT) { + initializer = new ConstantInitializer(0.0f); + } else if (batch_outputs[0]->data_type == DT_INT64) { + initializer = new ConstantInitializer((int64_t)0); + } else if (batch_outputs[0]->data_type == DT_INT32) { + initializer = new ConstantInitializer((int)0); + } + Runtime *runtime = ff.config.lg_hlr; + Context ctx = ff.config.lg_ctx; + ArgumentMap argmap; + IndexLauncher launcher( + CONSTANT_INIT_TASK_ID, + parallel_is, + TaskArgument(initializer, sizeof(ConstantInitializer)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + runtime->execute_index_space(ctx, launcher); + } else if (op_type == OP_WEIGHT) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(NOOP_INIT_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); + } +} + void NoOp::init(FFModel const &ff) { parallel_is = outputs[0]->parallel_is; + assert(parallel_is != IndexSpace::NO_SPACE); if (op_type == OP_INPUT && outputs[0]->initializer != nullptr) { ConstantInitializer *initializer = (ConstantInitializer *)outputs[0]->initializer; @@ -172,6 +258,15 @@ void NoOp::init(FFModel const &ff) { void NoOp::forward(FFModel const &ff) {} +FutureMap NoOp::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + FutureMap empty; + return empty; +} + void NoOp::backward(FFModel const &ff) {} bool NoOp::measure_operator_cost(Simulator *sim, diff --git a/src/ops/pool_2d.cc b/src/ops/pool_2d.cc index f56a60641d..4621ab5909 100644 --- a/src/ops/pool_2d.cc +++ b/src/ops/pool_2d.cc @@ -269,7 +269,7 @@ Pool2D::Pool2D(FFModel &model, params.padding_w, params.pool_type, params.activation, - name) {} + params.name) {} void Pool2D::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -317,7 +317,9 @@ OpMeta *Pool2D::init_task(Task const *task, FFHandler handle = *((FFHandler const *)task->local_args); Pool2DMeta *m = new Pool2DMeta(handle); m->profiling = pool->profiling; + m->inference_debugging = pool->inference_debugging; std::strcpy(m->op_name, pool->name); + m->layer_guid = pool->layer_guid; TensorAccessorR acc_input( regions[0], task->regions[0], FID_DATA, ctx, runtime); TensorAccessorW acc_output(regions[1], @@ -519,6 +521,8 @@ void Pool2D::serialize(Legion::Serializer &sez) const { sez.serialize(this->padding_w); sez.serialize(this->pool_type); sez.serialize(this->activation); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } bool Pool2D::measure_operator_cost(Simulator *sim, @@ -655,6 +659,10 @@ Node Pool2D::deserialize(FFModel &ff, dez.deserialize(padding_w); dez.deserialize(pool_type); dez.deserialize(activation); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); Pool2DParams params; params.kernel_h = kernel_h; @@ -665,6 +673,7 @@ Node Pool2D::deserialize(FFModel &ff, params.padding_w = padding_w; params.pool_type = pool_type; params.activation = activation; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } diff --git a/src/ops/reduce.cc b/src/ops/reduce.cc index 5761281686..454a35caf4 100644 --- a/src/ops/reduce.cc +++ b/src/ops/reduce.cc @@ -41,6 +41,9 @@ ReduceParams Reduce::get_params() const { } params.keepdims = keepdims; params.layer_guid = this->layer_guid; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -110,9 +113,12 @@ Reduce::Reduce(FFModel &model, ReduceParams const ¶ms, const ParallelTensor input, char const *name) - : Reduce( - model, params.layer_guid, input, params.axes, params.keepdims, name) { -} + : Reduce(model, + params.layer_guid, + input, + params.axes, + params.keepdims, + params.name) {} Reduce::Reduce(FFModel &model, LayerID const &_layer_guid, @@ -210,6 +216,8 @@ OpMeta *Reduce::init_task(Task const *task, GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( DT_FLOAT, regions[1], task->regions[1], FID_DATA, ctx, runtime); ReduceMeta *m = new ReduceMeta(handle, rd, input.domain); + std::strcpy(m->op_name, rd->name); + m->layer_guid = rd->layer_guid; return m; } @@ -344,7 +352,7 @@ bool Reduce::measure_operator_cost(Simulator *sim, GenericTensorAccessorR output_grad_acc( outputs[0]->data_type, sub_output.get_domain(), output_grad_ptr); - backward = [&] { + backward = [=] { backward_kernel_wrapper(m, output_grad_acc, input_grad_acc); }; } @@ -374,6 +382,10 @@ void Reduce::serialize(Legion::Serializer &sez) const { } sez.serialize(params.keepdims); sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -392,9 +404,15 @@ Node Reduce::deserialize(FFModel &ff, axes.push_back(dim_idx); } dez.deserialize(keepdims); - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); return ff.get_or_create_node(inputs[0], {axes, keepdims, layer_guid}); } diff --git a/src/ops/reshape.cc b/src/ops/reshape.cc index 07797bd223..a50d85785a 100644 --- a/src/ops/reshape.cc +++ b/src/ops/reshape.cc @@ -208,7 +208,7 @@ Reshape::Reshape(FFModel &model, ReshapeParams const ¶ms, const ParallelTensor input, char const *name) - : Reshape(model, params.layer_guid, input, params.shape, name) {} + : Reshape(model, params.layer_guid, input, params.shape, params.name) {} void Reshape::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -249,6 +249,8 @@ OpMeta *Reshape::init_task(Task const *task, Reshape const *reshape = (Reshape *)task->args; FFHandler handle = *((FFHandler const *)task->local_args); ReshapeMeta *m = new ReshapeMeta(handle); + std::strcpy(m->op_name, reshape->name); + m->layer_guid = reshape->layer_guid; m->data_type = reshape->outputs[0]->data_type; return m; } @@ -362,6 +364,9 @@ ReshapeParams Reshape::get_params() const { ReshapeParams params; params.shape = shape_vec; params.layer_guid = this->layer_guid; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -478,6 +483,10 @@ void Reshape::serialize(Legion::Serializer &sez) const { sez.serialize(this->shape_array[i]); } sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -495,13 +504,20 @@ Node Reshape::deserialize(FFModel &ff, dez.deserialize(value); shape.push_back(value); } - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); ReshapeParams params; params.shape = shape; params.layer_guid = layer_guid; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } diff --git a/src/ops/residual_layer_norm.cc b/src/ops/residual_layer_norm.cc new file mode 100644 index 0000000000..ed9252c309 --- /dev/null +++ b/src/ops/residual_layer_norm.cc @@ -0,0 +1,861 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; + +bool operator==(ResidualLayerNormParams const &lhs, + ResidualLayerNormParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.axes == rhs.axes && + lhs.elementwise_affine == rhs.elementwise_affine && + lhs.use_bias == rhs.use_bias && + lhs.use_two_residuals == rhs.use_two_residuals; +} + +bool ResidualLayerNormParams::is_valid( + std::tuple const &input) const { + return std::get<0>(input).is_valid() && std::get<1>(input).is_valid() && + (!use_two_residuals || std::get<2>(input).is_valid()); +} + +ResidualLayerNormParams ResidualLayerNorm::get_params() const { + ResidualLayerNormParams params; + params.layer_guid = this->layer_guid; + params.axes = this->axes; + params.elementwise_affine = this->elementwise_affine; + params.eps = this->eps; + params.use_bias = this->use_bias; + params.use_two_residuals = this->use_two_residuals; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +void FFModel::residual_layer_norm(const Tensor input, + const Tensor residual1, + const Tensor residual2, + Tensor *outputs, + bool use_two_residuals, + std::vector const &axes, + bool elementwise_affine, + float eps, + bool use_bias, + DataType data_type, + char const *name) { + // In PyTorch, axes must be the sizes of the last axes.size() dimensions of + // the input tensor. However, since the tensor dimensions are reversed in + // FlexFlow (batch size is the last dimension), we require that axes must be + // the sizes of the FIRST axes.size() dimensions of the input tensor. + + // Another difference is that in PyTorch, the axes vector should contain the + // sizes of the dimensions with respect to which you want to compute the + // layernorm. In FlexFlow, instead, axes should contain the INDICES of the + // dimensions in question. We do this because the size of a dimension might be + // different when splitting a tensor in model parallelism. + assert( + axes.size() <= input->num_dims && + "number of axes must be less than tensor dimensions"); // input does not + // have replica + // dimension here + for (int i = 0; i < axes.size(); i++) { + assert(axes[i] == i && "axes must be the first axes.size() dimensions"); + } + + // Check dims + assert(input->num_dims == residual1->num_dims); + if (use_two_residuals) { + assert(residual2 != nullptr); + assert(input->num_dims == residual2->num_dims); + } + for (int i = 0; i < input->num_dims; i++) { + assert(input->dims[i] == residual1->dims[i]); + if (use_two_residuals) { + assert(input->dims[i] == residual2->dims[i]); + } + } + + if (data_type == DT_NONE) { + data_type = input->data_type; + } + + int num_weights = elementwise_affine ? (use_bias ? 2 : 1) : 0; + Layer *ln = nullptr; + Tensor casted_input = + (data_type != input->data_type) + ? cast(input, data_type, "type cast for residual_layer_norm") + : input; + Tensor casted_residual1 = + (data_type != residual1->data_type) + ? cast(residual1, data_type, "type cast for residual1_layer_norm") + : residual1; + Tensor casted_residual2 = nullptr; + if (use_two_residuals) { + casted_residual2 = + (data_type != residual2->data_type) + ? cast(residual2, data_type, "type cast for residual2_layer_norm") + : residual2; + } + ln = new Layer(this, + OP_RESIDUAL_LAYERNORM, + data_type, + name, + 2 + use_two_residuals /*inputs*/, + num_weights, + 2 /*outputs*/, + casted_input, + casted_residual1, + casted_residual2); + ln->outputs[0] = create_tensor_legion_ordering( + input->num_dims, input->dims, data_type, ln, 0, false /*create_grad*/); + ln->outputs[1] = create_tensor_legion_ordering( + input->num_dims, input->dims, data_type, ln, 1, false /*create_grad*/); + { + int numdims = axes.size(); + int dims[numdims]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[axes[i]]; + } + if (num_weights >= 1) { + assert(elementwise_affine); + ln->weights[0] = create_weight_legion_ordering(numdims, + dims, + data_type, + ln, + false /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + if (num_weights == 2) { + assert(use_bias); + ln->weights[1] = create_weight_legion_ordering(numdims, + dims, + data_type, + ln, + false /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + } + } + } + ln->add_int_property("elementwise_affine", elementwise_affine); + ln->add_int_property("use_bias", use_bias); + ln->add_int_vector_property("axes", axes); + ln->add_float_property("eps", eps); + ln->add_int_property("use_two_residuals", use_two_residuals); + layers.push_back(ln); + outputs[0] = ln->outputs[0]; + outputs[1] = ln->outputs[1]; +} + +Op *ResidualLayerNorm::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("elementwise_affine", value); + bool elementwise_affine = (bool)value; + layer->get_int_property("use_bias", value); + bool use_bias = (bool)value; + std::vector axes; + layer->get_int_vector_property("axes", axes); + float eps; + layer->get_float_property("eps", eps); + layer->get_int_property("use_two_residuals", value); + bool use_two_residuals = (bool)value; + return new ResidualLayerNorm(model, + layer->layer_guid, + inputs[0], + inputs[1], + use_two_residuals ? inputs[2] : nullptr, + use_two_residuals, + axes, + elementwise_affine, + use_bias, + eps, + false, // allocate_weights + layer->name); +} + +ResidualLayerNorm::ResidualLayerNorm( + FFModel &model, + ResidualLayerNormParams const ¶ms, + std::tuple const &inputs, + bool allocate_weights, + char const *name) + : ResidualLayerNorm(model, + params.layer_guid, + std::get<0>(inputs), + std::get<1>(inputs), + params.use_two_residuals ? std::get<2>(inputs) + : nullptr, + params.use_two_residuals, + params.axes, + params.elementwise_affine, + params.use_bias, + params.eps, + allocate_weights, + params.name) {} + +ResidualLayerNorm::ResidualLayerNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + const ParallelTensor _residual1, + const ParallelTensor _residual2, + bool _use_two_residuals, + std::vector const &_axes, + bool _elementwise_affine, + bool _use_bias, + float _eps, + bool allocate_weights, + char const *name) + : Op(model, + OP_RESIDUAL_LAYERNORM, + _input->data_type, + name, + 2 + _use_two_residuals /*inputs*/, + _elementwise_affine ? (_use_bias ? 2 : 1) : 0 /*weights*/, + 2 /*outputs*/, + _input, + _residual1, + _use_two_residuals ? _residual2 : nullptr), + elementwise_affine(_elementwise_affine), eps(_eps), axes(_axes), + use_bias(_use_bias), use_two_residuals(_use_two_residuals) { + // overwrite layer_guid + layer_guid = _layer_guid; + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, _input->dims, _input->data_type, this, 0 /*owner_idx*/); + outputs[1] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, _input->dims, _input->data_type, this, 1 /*owner_idx*/); + assert(check_output_input_weight_parallel_dims(allocate_weights)); + + int M = 1; + for (int i = 0; i < axes.size(); i++) { + M *= inputs[0]->dims[axes[i]].size; + } + int num_replicas = 1; + for (int i = 0; i < inputs[0]->num_dims; i++) { + if (inputs[0]->dims[i].is_replica_dim) { + num_replicas *= inputs[0]->dims[i].size; + } + } + effective_num_elements = M; + effective_batch_size = (inputs[0]->get_volume() / num_replicas) / M; + if (!elementwise_affine) { + assert(numWeights == 0); + } else { + if (!use_bias) { + assert(numWeights == 1); // weight + } else { + assert(numWeights == 2); // weight + bias + } + } + + if (allocate_weights) { + int seed = std::rand(); + if (numWeights >= 1) { + assert(elementwise_affine); + + ParallelTensorShape beta_gamma_shape = _input->get_shape(); + for (int i = axes.size(); i < beta_gamma_shape.num_dims - 1; i++) { + beta_gamma_shape.dims[i].size = 1; + } + + // weight + Initializer *gamma_initializer = new UniformInitializer(seed, 1.0f, 1.0f); + weights[0] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, // axes.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + false /*create_grad*/, + gamma_initializer, + CHOSEN_SYNC_TYPE); + + // bias + if (numWeights == 2) { + assert(use_bias); + Initializer *beta_initializer = + new UniformInitializer(seed, 0.0f, 0.0f); + weights[1] = model.create_parallel_weight_legion_ordering( + beta_gamma_shape.num_dims, //.size(), + beta_gamma_shape.dims, + _input->data_type, + NULL /*owner_op*/, + false /*create_grad*/, + beta_initializer, + CHOSEN_SYNC_TYPE); + } + } + } +} + +void ResidualLayerNorm::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(RESIDUAL_LAYERNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ResidualLayerNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + int field_id = 0; + // input + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual1 + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual2 + if (use_two_residuals) { + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(field_id++, FID_DATA); + } + // added: input + residual(s) + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + // weights + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(field_id++, FID_DATA); + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(field_id++, FID_DATA); + } + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void ResidualLayerNorm::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(ADD_BIAS_RESIDUAL_LAYERNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ResidualLayerNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + int field_id = 0; + // input + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual1 + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual2 + if (use_two_residuals) { + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + } + // added: input + residual(s) + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + // weights + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(field_id++, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(field_id++, FID_DATA); + } + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *ResidualLayerNorm::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + ResidualLayerNorm *ln = (ResidualLayerNorm *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + ResidualLayerNormMeta *meta = + new ResidualLayerNormMeta(handle, ln, gpu_mem_allocator); + std::strcpy(meta->op_name, ln->name); + meta->layer_guid = ln->layer_guid; + meta->input_type[0] = ln->inputs[0]->data_type; + meta->input_type[1] = ln->inputs[1]->data_type; + if (ln->use_two_residuals) { + meta->input_type[2] = ln->inputs[2]->data_type; + } + if (ln->elementwise_affine) { + meta->weight_type[0] = ln->weights[0]->data_type; + if (ln->use_bias) { + meta->weight_type[1] = ln->weights[1]->data_type; + } + } + meta->output_type[0] = ln->outputs[0]->data_type; + meta->output_type[1] = ln->outputs[1]->data_type; + return meta; +} + +void ResidualLayerNorm::forward(FFModel const &ff) { + assert(false); +} + +void ResidualLayerNorm::backward(FFModel const &ff) { + assert(false); +} + +Op *ResidualLayerNorm::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + ResidualLayerNormParams params = get_params(); + return new ResidualLayerNorm( + ff, + params, + {inputs[0], inputs[1], params.use_two_residuals ? inputs[2] : nullptr}, + true, + this->name); +} + +FutureMap ResidualLayerNorm::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(RESIDUAL_LAYERNORM_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + int field_id = 0; + // input + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual1 + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + // residual2 + if (use_two_residuals) { + launcher.add_region_requirement(RegionRequirement(batch_inputs[2]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[2]->region)); + launcher.add_field(field_id++, FID_DATA); + } + // added: input + residual(s) + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(field_id++, FID_DATA); + // layer norm output + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(field_id++, FID_DATA); + if (elementwise_affine) { + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(field_id++, FID_DATA); + + if (use_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(field_id++, FID_DATA); + } + } + return runtime->execute_index_space(ctx, launcher); +} + +void ResidualLayerNorm::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + assert(task->regions.size() == regions.size()); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + + ResidualLayerNormMeta *m = *((ResidualLayerNormMeta **)task->local_args); + + assert(regions.size() == + 4 + m->use_two_residuals + + (m->elementwise_affine ? (m->use_bias ? 2 : 1) : 0)); + + int region_idx = 0, task_region_idx = 0; + GenericTensorAccessorR input = + helperGetGenericTensorAccessorRO(m->input_type[0], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR residual1 = + helperGetGenericTensorAccessorRO(m->input_type[1], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR residual2; + if (m->use_two_residuals) { + residual2 = + helperGetGenericTensorAccessorRO(m->input_type[2], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + } + GenericTensorAccessorW added_output = + helperGetGenericTensorAccessorWO(m->output_type[0], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorW output = + helperGetGenericTensorAccessorWO(m->output_type[1], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR gamma, beta; + if (m->elementwise_affine) { + gamma = helperGetGenericTensorAccessorRO(m->weight_type[0], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + if (m->use_bias) { + beta = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[region_idx++], + task->regions[task_region_idx++], + FID_DATA, + ctx, + runtime); + } + } + + task_region_idx = 0; + Domain in_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + Domain residual1_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + Domain residual2_domain; + if (m->use_two_residuals) { + residual2_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + assert(in_domain.get_volume() == residual2_domain.get_volume()); + assert(residual2_domain == in_domain); + } + Domain added_out_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + Domain out_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + Domain gamma_domain, beta_domain; + if (m->elementwise_affine) { + gamma_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + assert(gamma_domain.get_volume() == m->effective_num_elements); + int numdims = gamma_domain.get_dim(); + size_t vol = 1; + int i = 0; + while (vol < gamma_domain.get_volume()) { + int g_d = gamma_domain.hi()[i] - gamma_domain.lo()[i] + 1; + int in_d = in_domain.hi()[i] - in_domain.lo()[i] + 1; + assert(g_d == in_d); + vol *= g_d; + i++; + } + if (m->use_bias) { + beta_domain = runtime->get_index_space_domain( + ctx, task->regions[task_region_idx++].region.get_index_space()); + assert(gamma_domain == beta_domain); + } + } + assert(in_domain.get_volume() == out_domain.get_volume()); + assert(out_domain.get_volume() == added_out_domain.get_volume()); + assert(in_domain.get_volume() == residual1_domain.get_volume()); + assert(in_domain == out_domain); + assert(added_out_domain == out_domain); + assert(residual1_domain == in_domain); + assert(in_domain.get_volume() == + m->effective_num_elements * m->effective_batch_size); + + ResidualLayerNorm::inference_kernel_wrapper( + m, input, residual1, residual2, added_output, output, gamma, beta); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector input_accessors; + input_accessors.push_back(input); + input_accessors.push_back(residual1); + if (m->use_two_residuals) { + input_accessors.push_back(residual2); + } + std::vector weights_accessors; + if (m->elementwise_affine) { + weights_accessors.push_back(gamma); + if (m->use_bias) { + weights_accessors.push_back(beta); + } + } + ResidualLayerNorm::save_inference_tensors_to_file(m, + shard_id, + bc, + input_accessors, + weights_accessors, + {added_output, output}); + } +} + +bool ResidualLayerNorm::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +void ResidualLayerNorm::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->axes.size()); + for (size_t i = 0; i < this->axes.size(); i++) { + sez.serialize(this->axes[i]); + } + sez.serialize(this->elementwise_affine); + sez.serialize(this->eps); + sez.serialize(this->use_bias); + sez.serialize(this->use_two_residuals); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node ResidualLayerNorm::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + size_t num_axes; + std::vector axes; + bool elementwise_affine; + bool use_bias; + bool use_two_residuals; + float eps; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(num_axes); + for (size_t i = 0; i < num_axes; i++) { + int axis_idx; + dez.deserialize(axis_idx); + axes.push_back(axis_idx); + } + dez.deserialize(elementwise_affine); + dez.deserialize(eps); + dez.deserialize(use_bias); + dez.deserialize(use_two_residuals); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + if (use_two_residuals) { + assert(num_inputs == 3); + } else { + assert(num_inputs == 2); + } + + ResidualLayerNormParams params; + params.layer_guid = layer_guid; + params.axes = axes; + params.elementwise_affine = elementwise_affine; + params.eps = eps; + params.use_bias = use_bias; + params.use_two_residuals = use_two_residuals; + strcpy(params.name, name); + if (use_two_residuals) { + return ff.get_or_create_node( + {inputs[0], inputs[1], inputs[2]}, params); + } else { + return ff.get_or_create_node( + {inputs[0], inputs[1], inputs[1]}, params); + } +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::ResidualLayerNormParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.layer_guid.transformer_layer_id); + hash_combine(key, params.layer_guid.model_id); + hash_combine(key, params.axes.size()); + for (int n : params.axes) { + hash_combine(key, n); + } + hash_combine(key, params.elementwise_affine); + hash_combine(key, params.use_bias); + hash_combine(key, params.use_two_residuals); + return key; +} +}; // namespace std diff --git a/src/ops/residual_layer_norm.cpp b/src/ops/residual_layer_norm.cpp new file mode 100644 index 0000000000..f1b7a537b0 --- /dev/null +++ b/src/ops/residual_layer_norm.cpp @@ -0,0 +1,248 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +ResidualLayerNormMeta::ResidualLayerNormMeta(FFHandler handle, + ResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + elementwise_affine = ln->elementwise_affine; + use_bias = ln->use_bias; + use_two_residuals = ln->use_two_residuals; + effective_batch_size = ln->effective_batch_size; + effective_num_elements = ln->effective_num_elements; + profiling = ln->profiling; + inference_debugging = ln->inference_debugging; + eps = ln->eps; + DataType data_type = ln->data_type; + size_t totalSize = effective_batch_size * data_type_size(data_type) * 3; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + mean_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + rstd_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + bias_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); +} + +ResidualLayerNormMeta::~ResidualLayerNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < min(blockDim.x, max_num_threads) / C10_WARP_SIZE) + ? shared[lid] + : 0; + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void ResidualLayerNormKernel(int64_t N, + float eps, + T const *input_ptr, + T const *residual1_ptr, + T const *residual2_ptr, + T *X, + T *mean, + T *rstd, + T const *gamma, + T const *beta, + T *Y) { + __shared__ float m_shared[C10_WARP_SIZE]; + __shared__ float v_shared[C10_WARP_SIZE]; + const int64_t i = blockIdx.x; + float sum1 = 0.0f; + float sum2 = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + const int64_t index = i * N + j; + const T residual2_val = (residual2_ptr == nullptr) + ? T(0) + : static_cast(residual2_ptr[index]); + X[index] = input_ptr[index] + residual1_ptr[index] + residual2_val; + sum1 += static_cast(X[index]); + sum2 += static_cast(X[index]) * static_cast(X[index]); + } + if (threadIdx.x < kCUDABlockReduceNumThreads) { + sum1 = BlockReduceSum( + sum1, m_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + sum2 = BlockReduceSum( + sum2, v_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + } + if (threadIdx.x == 0) { + float const scale = float(1) / static_cast(N); + sum1 *= scale; + sum2 = max(sum2 * scale - sum1 * sum1, float(0)); + mean[i] = static_cast(sum1); + rstd[i] = static_cast(rsqrt(sum2 + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + const T_ACC gamma_v = + gamma == nullptr ? T_ACC(1) : static_cast(gamma[j]); + const T_ACC beta_v = + beta == nullptr ? T_ACC(0) : static_cast(beta[j]); + Y[index] = (static_cast(X[index]) - static_cast(mean[i])) * + static_cast(rstd[i]) * gamma_v + + beta_v; + } +} + +/*static*/ +template +void ResidualLayerNorm::inference_kernel(ResidualLayerNormMeta const *m, + T const *input_ptr, + T const *residual1_ptr, + T const *residual2_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + hipStream_t stream) { + + std::pair kernel1_parallelism = + std::make_pair(m->effective_batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->effective_batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + hipLaunchKernelGGL(HIP_KERNEL_NAME(ResidualLayerNormKernel), + num_blocks, + num_threads, + 0, + stream, + m->effective_num_elements, + m->eps, + input_ptr, + residual1_ptr, + residual2_ptr, + added_output_ptr, + static_cast(m->mean_ptr), + static_cast(m->rstd_ptr), + gamma_ptr, + beta_ptr, + output_ptr); +} + +/*static*/ +void ResidualLayerNorm::inference_kernel_wrapper( + ResidualLayerNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &residual1, + GenericTensorAccessorR const &residual2, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + if (m->input_type[0] == DT_FLOAT) { + ResidualLayerNorm::inference_kernel( + m, + input.get_float_ptr(), + residual1.get_float_ptr(), + residual2.get_float_ptr(), + added_output.get_float_ptr(), + output.get_float_ptr(), + m->elementwise_affine ? gamma.get_float_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_float_ptr() : nullptr, + stream); + } else if (m->input_type[0] == DT_HALF) { + ResidualLayerNorm::inference_kernel( + m, + input.get_half_ptr(), + residual1.get_half_ptr(), + residual2.get_half_ptr(), + added_output.get_half_ptr(), + output.get_half_ptr(), + m->elementwise_affine ? gamma.get_half_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_half_ptr() : nullptr, + stream); + } else { + assert(false && "unsupport datatype in layernorm"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("[ResidualLayerNorm] forward time (CF) = %.9fms\n", elapsed); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/residual_layer_norm.cu b/src/ops/residual_layer_norm.cu new file mode 100644 index 0000000000..e5ebdce6ed --- /dev/null +++ b/src/ops/residual_layer_norm.cu @@ -0,0 +1,243 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +#define C10_WARP_SIZE 32 +constexpr int kCUDABlockReduceNumThreads = 512; +constexpr int kCUDANumThreads = 256; + +ResidualLayerNormMeta::ResidualLayerNormMeta(FFHandler handle, + ResidualLayerNorm const *ln, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + elementwise_affine = ln->elementwise_affine; + use_bias = ln->use_bias; + use_two_residuals = ln->use_two_residuals; + effective_batch_size = ln->effective_batch_size; + effective_num_elements = ln->effective_num_elements; + profiling = ln->profiling; + inference_debugging = ln->inference_debugging; + eps = ln->eps; + DataType data_type = ln->data_type; + size_t totalSize = effective_batch_size * data_type_size(data_type) * 3; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + mean_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + rstd_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); + bias_ptr = gpu_mem_allocator.allocate_instance_untyped( + data_type_size(data_type) * effective_batch_size); +} + +ResidualLayerNormMeta::~ResidualLayerNormMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template +__device__ __forceinline__ T WARP_SHFL_DOWN(T value, + unsigned int delta, + int width = warpSize, + unsigned int mask = 0xffffffff) { +#ifndef __HIP_PLATFORM_HCC__ + return __shfl_down_sync(mask, value, delta, width); +#else + return __shfl_down(value, delta, width); +#endif +} + +template +__inline__ __device__ T WarpReduceSum(T val) { +#pragma unroll + for (int offset = (C10_WARP_SIZE >> 1); offset > 0; offset >>= 1) { + val += WARP_SHFL_DOWN(val, offset); + } + return val; +} + +template +__inline__ __device__ T BlockReduceSum(T val, T *shared, int max_num_threads) { + int const lid = threadIdx.x % C10_WARP_SIZE; + int const wid = threadIdx.x / C10_WARP_SIZE; + val = WarpReduceSum(val); + __syncthreads(); + if (lid == 0) { + shared[wid] = val; + } + __syncthreads(); + val = (threadIdx.x < min(blockDim.x, max_num_threads) / C10_WARP_SIZE) + ? shared[lid] + : 0; + if (wid == 0) { + val = WarpReduceSum(val); + } + return val; +} + +template +__global__ void ResidualLayerNormKernel(int64_t N, + float eps, + T const *input_ptr, + T const *residual1_ptr, + T const *residual2_ptr, + T *X, + T *mean, + T *rstd, + T const *gamma, + T const *beta, + T *Y) { + __shared__ float m_shared[C10_WARP_SIZE]; + __shared__ float v_shared[C10_WARP_SIZE]; + const int64_t i = blockIdx.x; + float sum1 = 0.0f; + float sum2 = 0.0f; + for (int64_t j = threadIdx.x; j < N; + j += min(blockDim.x, kCUDABlockReduceNumThreads)) { + const int64_t index = i * N + j; + const T residual2_val = (residual2_ptr == nullptr) + ? T(0) + : static_cast(residual2_ptr[index]); + X[index] = input_ptr[index] + residual1_ptr[index] + residual2_val; + sum1 += static_cast(X[index]); + sum2 += static_cast(X[index]) * static_cast(X[index]); + } + if (threadIdx.x < kCUDABlockReduceNumThreads) { + sum1 = BlockReduceSum( + sum1, m_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + sum2 = BlockReduceSum( + sum2, v_shared, min(blockDim.x, kCUDABlockReduceNumThreads)); + } + if (threadIdx.x == 0) { + float const scale = float(1) / static_cast(N); + sum1 *= scale; + sum2 = max(sum2 * scale - sum1 * sum1, float(0)); + mean[i] = static_cast(sum1); + rstd[i] = static_cast(rsqrt(sum2 + eps)); + } + + __syncthreads(); + + using T_ACC = T; + for (int64_t j = threadIdx.x; j < N; j += min(blockDim.x, kCUDANumThreads)) { + const int64_t index = i * N + j; + const T_ACC gamma_v = + gamma == nullptr ? T_ACC(1) : static_cast(gamma[j]); + const T_ACC beta_v = + beta == nullptr ? T_ACC(0) : static_cast(beta[j]); + Y[index] = (static_cast(X[index]) - static_cast(mean[i])) * + static_cast(rstd[i]) * gamma_v + + beta_v; + } +} + +/*static*/ +template +void ResidualLayerNorm::inference_kernel(ResidualLayerNormMeta const *m, + T const *input_ptr, + T const *residual1_ptr, + T const *residual2_ptr, + T *added_output_ptr, + T *output_ptr, + T const *gamma_ptr, + T const *beta_ptr, + cudaStream_t stream) { + + std::pair kernel1_parallelism = + std::make_pair(m->effective_batch_size, kCUDABlockReduceNumThreads); + std::pair kernel2_parallelism = + std::make_pair(m->effective_batch_size, kCUDANumThreads); + + int num_blocks = + std::max(kernel1_parallelism.first, kernel2_parallelism.first); + int num_threads = + std::max(kernel1_parallelism.second, kernel2_parallelism.second); + + ResidualLayerNormKernel + <<>>(m->effective_num_elements, + m->eps, + input_ptr, + residual1_ptr, + residual2_ptr, + added_output_ptr, + static_cast(m->mean_ptr), + static_cast(m->rstd_ptr), + gamma_ptr, + beta_ptr, + output_ptr); +} + +/*static*/ +void ResidualLayerNorm::inference_kernel_wrapper( + ResidualLayerNormMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &residual1, + GenericTensorAccessorR const &residual2, + GenericTensorAccessorW &added_output, + GenericTensorAccessorW &output, + GenericTensorAccessorR const &gamma, + GenericTensorAccessorR const &beta) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + if (m->input_type[0] == DT_FLOAT) { + ResidualLayerNorm::inference_kernel( + m, + input.get_float_ptr(), + residual1.get_float_ptr(), + m->use_two_residuals ? residual2.get_float_ptr() : nullptr, + added_output.get_float_ptr(), + output.get_float_ptr(), + m->elementwise_affine ? gamma.get_float_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_float_ptr() : nullptr, + stream); + } else if (m->input_type[0] == DT_HALF) { + ResidualLayerNorm::inference_kernel( + m, + input.get_half_ptr(), + residual1.get_half_ptr(), + m->use_two_residuals ? residual2.get_half_ptr() : nullptr, + added_output.get_half_ptr(), + output.get_half_ptr(), + m->elementwise_affine ? gamma.get_half_ptr() : nullptr, + (m->elementwise_affine && m->use_bias) ? beta.get_half_ptr() : nullptr, + stream); + } else { + assert(false && "unsupport datatype in layernorm"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[ResidualLayerNorm] forward time (CF) = %.9fms\n", elapsed); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/residual_rms_norm.cc b/src/ops/residual_rms_norm.cc new file mode 100644 index 0000000000..f4f5bb72d0 --- /dev/null +++ b/src/ops/residual_rms_norm.cc @@ -0,0 +1,524 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/residual_rms_norm.h" +#include "flexflow/model.h" +#include "flexflow/ops/kernels/residual_rms_norm_kernels.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; + +using namespace FlexFlow::Kernels::ResidualRMSNorm; + +bool operator==(ResidualRMSNormParams const &lhs, + ResidualRMSNormParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.eps == rhs.eps; +} + +bool ResidualRMSNormParams::is_valid( + std::pair const &input) const { + return input.first.is_valid() && input.second.is_valid(); +} + +ResidualRMSNormParams ResidualRMSNorm::get_params() const { + ResidualRMSNormParams params; + params.layer_guid = this->layer_guid; + params.eps = this->eps; + params.dim = this->dim; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +void FFModel::residual_rms_norm(const Tensor input1, + const Tensor input2, + Tensor *outputs, + float eps, + int dim, + DataType data_type, + char const *name) { + if (data_type == DT_NONE) { + data_type = input1->data_type; + } + Tensor casted_input1 = + (data_type != input1->data_type) + ? cast(input1, data_type, "type cast for residual_rms_norm") + : input1; + Tensor casted_input2 = + (data_type != input2->data_type) + ? cast(input2, data_type, "type cast for residual_rms_norm") + : input2; + Layer *rm = new Layer(this, + OP_RESIDUAL_RMS_NORM, + data_type, + name, + 2 /*inputs*/, + 1 /*weights*/, + 2 /*outputs*/, + casted_input1, + casted_input2); + + rm->outputs[0] = create_tensor_legion_ordering( + input1->num_dims, input1->dims, data_type, rm, 0, false /*create_grad*/); + rm->outputs[1] = create_tensor_legion_ordering( + input1->num_dims, input1->dims, data_type, rm, 1, false /*create_grad*/); + + // weights + int weight_dims[1] = {dim}; + rm->weights[0] = create_weight_legion_ordering(1, + weight_dims, + data_type, + rm, + true /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + + rm->add_float_property("eps", eps); + rm->add_int_property("dim", dim); + layers.push_back(rm); + outputs[0] = rm->outputs[0]; + outputs[1] = rm->outputs[1]; +} + +Op *ResidualRMSNorm::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + float eps; + layer->get_float_property("eps", eps); + long long value; + layer->get_int_property("dim", value); + int dim = value; + + return new ResidualRMSNorm(model, + layer->layer_guid, + inputs[0], + inputs[1], + eps, + dim, + false, + layer->name); +} + +ResidualRMSNorm::ResidualRMSNorm( + FFModel &model, + ResidualRMSNormParams const ¶ms, + std::pair const &inputs, + bool allocate_weights = false, + char const *name) + : ResidualRMSNorm(model, + params.layer_guid, + inputs.first, + inputs.second, + params.eps, + params.dim, + allocate_weights, + params.name) {} + +ResidualRMSNorm::ResidualRMSNorm( + FFModel &model, + ResidualRMSNorm const &other, + std::pair const &inputs, + bool allocate_weights) + : ResidualRMSNorm(model, + other.layer_guid, + inputs.first, + inputs.second, + other.eps, + other.dim, + allocate_weights, + other.name) {} +ResidualRMSNorm::ResidualRMSNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input1, + const ParallelTensor _input2, + float _eps, + int dim, + bool allocate_weights, + char const *name) + : Op(model, + OP_RESIDUAL_RMS_NORM, + _input1->data_type, + name, + 2 /*num of inputs tensor */, + 1 /*num of weights tensor */, + 2 /*num of outputs tensor */, + _input1, + _input2) { + eps = _eps; + inputs[0] = _input1; + inputs[1] = _input2; + layer_guid = _layer_guid; + int num_dims = _input1->num_dims; + this->dim = dim; + data_dim = _input1->dims[0].size; + effective_batch_size = 1; + for (int i = 1; i <= num_dims - 2; i++) { + effective_batch_size *= _input1->dims[i].size; + } + // Currently assert that all non-replica dims are not parallelized + // We only support parallelism along the replica dim now + for (int i = 0; i < _input1->num_dims - 1; i++) { + assert(_input1->dims[i].degree == 1); + } + // Check that the two inputs have the same dimensions + for (int i = 0; i < _input1->num_dims; i++) { + assert(_input2->dims[i] == _input1->dims[i]); + } + // output has the same parallel dims as input + ParallelDim output_dims[MAX_TENSOR_DIM]; + for (int i = 0; i < _input1->num_dims; i++) { + output_dims[i] = _input1->dims[i]; + } + outputs[0] = model.create_parallel_tensor_legion_ordering(_input1->num_dims, + output_dims, + _input1->data_type, + this, + 0 /*owner_idx*/); + outputs[1] = model.create_parallel_tensor_legion_ordering(_input1->num_dims, + output_dims, + _input1->data_type, + this, + 1 /*owner_idx*/); + + if (allocate_weights) { + // weights should have the shape of (data_dim, data_dim) + ParallelDim new_weight_dims[MAX_TENSOR_DIM]; + + new_weight_dims[0].size = dim; + new_weight_dims[0].degree = 1; + new_weight_dims[0].parallel_idx = -1; + new_weight_dims[1] = _input1->dims[_input1->num_dims - 1]; // replica dim + + // weights + Initializer *kernel_initializer = new GlorotUniform(std::rand() /*seed*/); + weights[0] = + model.create_parallel_weight_legion_ordering(2, + new_weight_dims, + _input1->data_type, + nullptr /*owner_op*/, + false /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } +} + +void ResidualRMSNorm::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(RESIDUAL_RMSNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ResidualRMSNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[1]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +void ResidualRMSNorm::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + + IndexLauncher launcher(RESIDUAL_RMSNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(ResidualRMSNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +OpMeta *ResidualRMSNorm::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + ResidualRMSNorm *rn = (ResidualRMSNorm *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + ResidualRMSNormMeta *meta = + new ResidualRMSNormMeta(handle, rn, gpu_mem_allocator); + std::strcpy(meta->op_name, rn->name); + meta->layer_guid = rn->layer_guid; + return meta; +} + +void ResidualRMSNorm::forward(FFModel const &ff) { + assert(false); +} + +FutureMap + ResidualRMSNorm::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(RESIDUAL_RMSNORM_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(3, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(4, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input1 + regions[1](I): input2 + regions[2](O): residual output + regions[3](O): output + regions[4](I/O): weight +*/ +void ResidualRMSNorm::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == 5); + assert(regions.size() == 5); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + ResidualRMSNormMeta *m = *((ResidualRMSNormMeta **)task->local_args); + GenericTensorAccessorR input1 = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR input2 = helperGetGenericTensorAccessorRO( + m->input_type[1], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW residual_output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[1], regions[3], task->regions[3], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[4], task->regions[4], FID_DATA, ctx, runtime); + forward_kernel_wrapper(m, input1, input2, weight, residual_output, output); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + ResidualRMSNorm::save_inference_tensors_to_file( + m, shard_id, bc, {input1, input2}, {weight}, {residual_output, output}); + } +} + +void ResidualRMSNorm::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->eps); + sez.serialize(this->dim); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node ResidualRMSNorm::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 2); + float eps; + size_t id, transformer_layer_id, deserialized_model_id; + int dim; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(eps); + dez.deserialize(dim); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + ResidualRMSNormParams params; + params.layer_guid = layer_guid; + params.eps = eps; + params.dim = dim; + strcpy(params.name, name); + return ff.get_or_create_node({inputs[0], inputs[1]}, params); +} + +void ResidualRMSNorm::backward(FFModel const &ff) { + assert(false); +} +Op *ResidualRMSNorm::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + ResidualRMSNormParams params = get_params(); + return new ResidualRMSNorm( + ff, params, {inputs[0], inputs[1]}, true, this->name); +} + +bool ResidualRMSNorm::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +} // namespace FlexFlow +namespace std { +size_t hash::operator()( + FlexFlow::ResidualRMSNormParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.eps); + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.dim); + return key; +} +}; // namespace std diff --git a/src/ops/reverse.cc b/src/ops/reverse.cc index e78962f697..04c744f774 100644 --- a/src/ops/reverse.cc +++ b/src/ops/reverse.cc @@ -282,7 +282,7 @@ bool Reverse::measure_operator_cost(Simulator *sim, cost_metrics.outputs_memory += cost_metrics.total_mem_diff_from(sim->offset); - backward = [&] { + backward = [=] { backward_kernel_wrapper(output_grad_ptr, input_grad_ptr, num_out_blks, diff --git a/src/ops/rms_norm.cc b/src/ops/rms_norm.cc new file mode 100644 index 0000000000..bf07ee6bb0 --- /dev/null +++ b/src/ops/rms_norm.cc @@ -0,0 +1,501 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/rms_norm.h" +#include "flexflow/model.h" +#include "flexflow/ops/kernels/rms_norm_kernels.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; + +using namespace FlexFlow::Kernels::RMSNorm; + +bool operator==(RMSNormParams const &lhs, RMSNormParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.eps == rhs.eps; +} + +bool RMSNormParams::is_valid(ParallelTensorShape const &input) const { + return input.is_valid(); +} + +RMSNormParams RMSNorm::get_params() const { + RMSNormParams params; + params.layer_guid = this->layer_guid; + params.eps = this->eps; + params.dim = this->dim; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +Tensor FFModel::rms_norm(const Tensor input, + float eps, + int dim, + DataType data_type, + char const *name) { + if (data_type == DT_NONE) { + data_type = input->data_type; + } + Layer *rm = nullptr; + if (data_type != input->data_type) { + Tensor casted_input = cast(input, data_type, "type cast for rms_norm"); + rm = new Layer(this, + OP_RMS_NORM, + data_type, + name, + 1 /*inputs*/, + 1 /*weights*/, + 1 /*outputs*/, + casted_input); + } else { + rm = new Layer(this, + OP_RMS_NORM, + data_type, + name, + 1 /*inputs*/, + 1 /*weights*/, + 1 /*outputs*/, + input); + } + rm->outputs[0] = create_tensor_legion_ordering( + input->num_dims, input->dims, data_type, rm, 0, true /*create_grad*/); + + // weights + int weight_dims[1] = {dim}; + rm->weights[0] = create_weight_legion_ordering(1, + weight_dims, + data_type, + rm, + true /*create_grad*/, + nullptr, + CHOSEN_SYNC_TYPE); + + rm->add_float_property("eps", eps); + rm->add_int_property("dim", dim); + layers.push_back(rm); + return rm->outputs[0]; +} + +Op *RMSNorm::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + float eps; + layer->get_float_property("eps", eps); + long long value; + layer->get_int_property("dim", value); + int dim = value; + + return new RMSNorm( + model, layer->layer_guid, inputs[0], eps, dim, false, layer->name); +} + +RMSNorm::RMSNorm(FFModel &model, + RMSNormParams const ¶ms, + ParallelTensor const input, + bool allocate_weights = false, + char const *name) + : RMSNorm(model, + params.layer_guid, + input, + params.eps, + params.dim, + allocate_weights, + params.name) {} + +RMSNorm::RMSNorm(FFModel &model, + RMSNorm const &other, + const ParallelTensor input, + bool allocate_weights) + : RMSNorm(model, + other.layer_guid, + input, + other.eps, + other.dim, + allocate_weights, + other.name) {} +RMSNorm::RMSNorm(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + float _eps, + int dim, + bool allocate_weights, + char const *name) + : Op(model, + OP_RMS_NORM, + _input->data_type, + name, + 1 /*num of inputs tensor */, + 1 /*num of weights tensor */, + 1 /*onum of utputs tensor */, + _input) { + eps = _eps; + inputs[0] = _input; + layer_guid = _layer_guid; + int num_dims = _input->num_dims; + this->dim = dim; + data_dim = _input->dims[0].size; + effective_batch_size = 1; + for (int i = 1; i <= num_dims - 2; i++) { + effective_batch_size *= _input->dims[i].size; + } + // Currently assert that all non-replica dims are not parallelized + // We only support parallelism along the replica dim now + for (int i = 0; i < _input->num_dims - 1; i++) { + assert(_input->dims[i].degree == 1); + } + // output has the same parallel dims as input + ParallelDim output_dims[MAX_TENSOR_DIM]; + for (int i = 0; i < _input->num_dims; i++) { + output_dims[i] = _input->dims[i]; + } + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, output_dims, _input->data_type, this); + if (allocate_weights) { + // weights should have the shape of (data_dim, data_dim) + ParallelDim new_weight_dims[MAX_TENSOR_DIM]; + + new_weight_dims[0].size = dim; + new_weight_dims[0].degree = 1; + new_weight_dims[0].parallel_idx = -1; + new_weight_dims[1] = _input->dims[_input->num_dims - 1]; // replica dim + + // weights + Initializer *kernel_initializer = new GlorotUniform(std::rand() /*seed*/); + weights[0] = + model.create_parallel_weight_legion_ordering(2, + new_weight_dims, + _input->data_type, + nullptr /*owner_op*/, + false /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } +} + +void RMSNorm::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(RMSNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(RMSNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(1, FID_DATA); + + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +void RMSNorm::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + + IndexLauncher launcher(RMSNORM_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(RMSNorm)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(1, FID_DATA); + + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +OpMeta *RMSNorm::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RMSNorm *rn = (RMSNorm *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + RMSNormMeta *meta = new RMSNormMeta(handle, rn, gpu_mem_allocator); + std::strcpy(meta->op_name, rn->name); + meta->layer_guid = rn->layer_guid; + return meta; +} + +void RMSNorm::forward(FFModel const &ff) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_forward(ff, argmap); + IndexLauncher launcher(RMSNORM_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + runtime->execute_index_space(ctx, launcher); +} + +FutureMap RMSNorm::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(RMSNORM_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input + regions[1](O): output + regions[2](I/O): weight +*/ +void RMSNorm::forward_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == 3); + assert(regions.size() == 3); + RMSNormMeta const *m = *((RMSNormMeta **)task->local_args); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + forward_kernel_wrapper(m, input, weight, output); +} + +/* + regions[0](I): input + regions[1](O): output + regions[2](I/O): weight +*/ +void RMSNorm::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == 3); + assert(regions.size() == 3); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + RMSNormMeta *m = *((RMSNormMeta **)task->local_args); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + forward_kernel_wrapper(m, input, weight, output); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + RMSNorm::save_inference_tensors_to_file( + m, shard_id, bc, {input}, {weight}, {output}); + } +} + +void RMSNorm::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->eps); + sez.serialize(this->dim); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node RMSNorm::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + float eps; + size_t id, transformer_layer_id, deserialized_model_id; + int dim; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(eps); + dez.deserialize(dim); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + RMSNormParams params; + params.layer_guid = layer_guid; + params.eps = eps; + params.dim = dim; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); +} + +Op *RMSNorm::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + RMSNormParams params = get_params(); + return new RMSNorm(ff, params, inputs[0], true, this->name); +} + +void RMSNorm::backward(FFModel const &ff) {} + +bool RMSNorm::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +} // namespace FlexFlow +namespace std { +size_t hash::operator()( + FlexFlow::RMSNormParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.eps); + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.dim); + return key; +} +}; // namespace std diff --git a/src/ops/sampling.cc b/src/ops/sampling.cc new file mode 100644 index 0000000000..9fc2316f9a --- /dev/null +++ b/src/ops/sampling.cc @@ -0,0 +1,374 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/sampling.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + +namespace FlexFlow { +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +// For an input tensor, computes the top k entries in each row +// (resp. vector along the last dimension). Thus, +// values.shape = indices.shape = input.shape[:-1] + [k] +Tensor FFModel::sampling(const Tensor input, float top_p, char const *name) { + Layer *li = new Layer(this, + OP_SAMPLING, + input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + 1 /*outputs*/, + input); + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + // now just support 1 output + dims[0] = 1; + // li->outputs[0] = create_tensor_legion_ordering( + // numdims, dims, input->data_type, li, 0, true /*create_grad*/); + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, DT_INT32, li, 0, false /*create_grad*/); + } + layers.push_back(li); + li->add_float_property("top_p", top_p); + // outputs[0] = li->outputs[0]; + // outputs[1] = li->outputs[1]; + return li->outputs[0]; +} + +Op *Sampling::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + float top_p; + layer->get_float_property("top_p", top_p); + return new Sampling(model, inputs[0], top_p, layer->name); +} + +SamplingParams Sampling::get_params() const { + SamplingParams params; + params.top_p = this->top_p; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +bool SamplingParams::is_valid(ParallelTensorShape const &) const { + return true; +} + +bool operator==(SamplingParams const &lhs, SamplingParams const &rhs) { + return lhs.top_p == rhs.top_p; +} + +Sampling::Sampling(FFModel &model, + const ParallelTensor _input, + float _top_p, + char const *name) + : Op(model, + OP_SAMPLING, + _input->data_type, + name, + 1 /*inputs*/, + 0 /*weights*/, + 1 /*outputs*/, + _input), + top_p(_top_p) { + int numdim = inputs[0]->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = inputs[0]->dims[i]; + } + dims[0].size = 1; + std::cout << "degree: " << inputs[0]->dims[0].degree << "\n"; + assert(inputs[0]->dims[0].degree == 1); + assert(inputs[0]->dims[0].parallel_idx == -1); + // outputs[0] = model.create_parallel_tensor_legion_ordering( + // numdim, dims, _input->data_type, this, 0 /*owner_idx*/); + outputs[0] = model.create_parallel_tensor_legion_ordering( + numdim, dims, DT_INT32, this, 0 /*owner_idx*/); +} + +Sampling::Sampling(FFModel &model, + Sampling const &other, + const ParallelTensor input) + : Sampling(model, input, other.top_p, other.name) {} + +Sampling::Sampling(FFModel &model, + SamplingParams const ¶ms, + const ParallelTensor input, + char const *name) + : Sampling(model, input, params.top_p, params.name) {} + +void Sampling::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(SAMPLING_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Sampling)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void Sampling::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(SAMPLING_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Sampling)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +OpMeta *Sampling::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + Sampling *s = (Sampling *)task->args; + FFHandler handle = *((FFHandler *)task->local_args); + GenericTensorAccessorW acc_input = + helperGetGenericTensorAccessorRW(s->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + + int length = acc_input.domain.hi()[0] - acc_input.domain.lo()[0] + 1; + int batch_size = acc_input.domain.get_volume() / length; + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + SamplingMeta *m = new SamplingMeta( + handle, s, batch_size, length * batch_size, acc_input, gpu_mem_allocator); + m->profiling = s->profiling; + m->inference_debugging = s->inference_debugging; + std::strcpy(m->op_name, s->name); + m->layer_guid = s->layer_guid; + m->top_p = s->top_p; + return m; +} + +void Sampling::forward(FFModel const &ff) { + // Sampling does not support forward + assert(false); +} + +FutureMap Sampling::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "Sampling op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(SAMPLING_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_WRITE, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + +InferenceResult + Sampling::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + // BatchConfig const *bc = (BatchConfig *)task->args; + SamplingMeta *m = *((SamplingMeta **)task->local_args); + if (bc->num_tokens == 0) { + // Directly return for empty batch config + InferenceResult ir; + return ir; + } + + GenericTensorAccessorW input = helperGetGenericTensorAccessorRW( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW indices = helperGetGenericTensorAccessorWO( + DT_INT32, regions[1], task->regions[1], FID_DATA, ctx, runtime); + + int batch_size = bc->num_active_tokens(); + Sampling::forward_kernel_wrapper(m, input, indices, batch_size); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Sampling::save_inference_tensors_to_file( + m, shard_id, bc, {}, {}, {input, indices}); + } + + InferenceResult ir; + download_tensor( + indices.get_int32_ptr(), ir.token_ids, batch_size); + return ir; +} + +void Sampling::backward(FFModel const &ff) { + // Sampling does not support backward + assert(false); +} + +void Sampling::serialize(Legion::Serializer &sez) const { + sez.serialize(this->top_p); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +Node Sampling::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + float top_p; + dez.deserialize(top_p); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + SamplingParams params; + params.top_p = top_p; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); +} + +Op *Sampling::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + SamplingParams params = get_params(); + return new Sampling(ff, params, inputs[0], this->name); +} + +bool Sampling::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::SamplingParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.top_p); + return key; +} +}; // namespace std diff --git a/src/ops/sampling.cpp b/src/ops/sampling.cpp new file mode 100644 index 0000000000..3d8f103524 --- /dev/null +++ b/src/ops/sampling.cpp @@ -0,0 +1,271 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/sampling.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include +#include + +namespace FlexFlow { + +constexpr int SamplingNumThreads = 1024; +struct BlockPrefixCallbackOp { + // Running prefix + float running_total; + // Constructor + __device__ BlockPrefixCallbackOp(float running_total) + : running_total(running_total) {} + // Callback operator to be entered by the first warp of threads in the block. + // Thread-0 is responsible for returning a value for seeding the block-wide + // scan. + __device__ float operator()(float block_aggregate) { + float old_prefix = running_total; + running_total += block_aggregate; + return old_prefix; + } +}; + +__global__ void init_idxs(int batch_size, + int vocab_size, + int total_eles, + int *idx, + int *begin_offset, + int *end_offset) { + CUDA_KERNEL_LOOP(i, total_eles) { + idx[i] = i % vocab_size; + if (i % vocab_size == 0) { + begin_offset[i / vocab_size] = i; + end_offset[i / vocab_size] = i; + } + } +} + +__global__ void + init_random_kernel(hiprandState *state, int batch_size, long rand) { + CUDA_KERNEL_LOOP(i, batch_size) { + hiprand_init(rand, i, 0, &state[i]); + } +} + +// multinominal and gather +template +__global__ void sampling_topp_kernel(int batch_size, + int const vocab_size, + hiprandState *state, + DT *sorted_logits, + int *sorted_idx, + int *indices_ptr, + float topp) { + // int const vocab_id = threadIdx.x; + int const batch_idx = blockIdx.x; + __shared__ float random_n; + __shared__ unsigned long long result_idx; + + // random num + if (threadIdx.x == 0) { + // number must < topp + random_n = hiprand_uniform(state + batch_idx) * topp; + // printf("batch idx: %d, random num%f\n", batch_idx, random_n); + } + + __syncthreads(); + + // cumsum; + typedef hipcub::BlockScan BlockScan; + __shared__ typename BlockScan::TempStorage temp_storage; + + int offset = batch_idx * vocab_size; + float prefix_sum = 0.0f; + BlockPrefixCallbackOp prefix_op(0); + result_idx = vocab_size - 1; + + for (unsigned long long j = threadIdx.x; j < vocab_size; j += blockDim.x) { + float logit = (float)(sorted_logits[offset + j]); + BlockScan(temp_storage).InclusiveSum(logit, prefix_sum, prefix_op); + prefix_sum /= topp; + if (prefix_sum >= random_n) { + atomicMin(&result_idx, j); + } + } + indices_ptr[batch_idx] = sorted_idx[offset + result_idx]; + + // if (threadIdx.x == 0) { + // printf("selected idx: %d, %d\n", blockIdx.x, result_idx); + // } +} + +/*static*/ +template +void Sampling::forward_kernel(SamplingMeta const *m, + DT *input_ptr, + int *indices_ptr, + float const top_p, + int const length, + int const batch_size, + hipStream_t stream) { + + size_t temp_storage_bytes = m->temp_storage_bytes; + // checkCUDA(hipcub::DeviceSegmentedRadixSort::SortPairsDescending( + // m->d_temp_storage, + // temp_storage_bytes, + // input_ptr, + // static_cast
(m->sorted_logits), + // m->idx, + // m->sorted_idx, + // length * batch_size, + // batch_size, + // m->begin_offset, + // m->end_offset + 1, + // 0, // begin_bit + // sizeof(DT) * 8, // end_bit = sizeof(KeyT) * 8 + // stream)); + return; + int parallelism = batch_size; + hipLaunchKernelGGL(init_random_kernel, + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + m->state, + batch_size, + rand()); + // sampling + hipLaunchKernelGGL( + HIP_KERNEL_NAME(sampling_topp_kernel), + batch_size, + SamplingNumThreads, + 0, + stream, + batch_size, + length, + m->state, + static_cast
(m->sorted_logits), + m->sorted_idx, + indices_ptr, + top_p); +} + +/*static*/ +void Sampling::forward_kernel_wrapper(SamplingMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + int batch_size) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + handle_unimplemented_hip_kernel(OP_SAMPLING); + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + } +} + +SamplingMeta::SamplingMeta(FFHandler handler, + Op const *op, + int batch_size, + int total_ele, + GenericTensorAccessorW input, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, op) { + DataType data_type = op->data_type; + + size_t begin_offset_size, end_offset_size; + begin_offset_size = end_offset_size = batch_size + 1; + size_t idx_size, sorted_idx_size, sorted_logits_size; + idx_size = sorted_idx_size = sorted_logits_size = total_ele; + size_t state_size = batch_size; + + size_t totalSize = sizeof(int) * (begin_offset_size + end_offset_size + + idx_size + sorted_idx_size) + + data_type_size(data_type) * sorted_logits_size + + sizeof(hiprandState) * state_size; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + begin_offset = gpu_mem_allocator.allocate_instance(begin_offset_size); + end_offset = gpu_mem_allocator.allocate_instance(end_offset_size); + idx = gpu_mem_allocator.allocate_instance(idx_size); + sorted_idx = gpu_mem_allocator.allocate_instance(sorted_idx_size); + sorted_logits = gpu_mem_allocator.allocate_instance_untyped( + sorted_logits_size * data_type_size(data_type)); + state = gpu_mem_allocator.allocate_instance(state_size); + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + // init offset + int parallelism = total_ele; + init_idxs<<>>(batch_size, + total_ele / batch_size, + total_ele, + idx, + begin_offset, + end_offset); + + // init sort function + // if (data_type == DT_FLOAT) { + // checkCUDA(hipcub::DeviceSegmentedRadixSort::SortPairsDescending( + // d_temp_storage, + // temp_storage_bytes, + // input.get_float_ptr(), + // input.get_float_ptr(), + // idx, + // idx, + // total_ele, + // batch_size, + // begin_offset, + // end_offset + 1, + // 0, // begin_bit + // data_type_size(data_type) * 8, // end_bit = sizeof(KeyT) * 8 + // stream)); + // } else if (data_type == DT_HALF) { + // checkCUDA(hipcub::DeviceSegmentedRadixSort::SortPairsDescending( + // d_temp_storage, + // temp_storage_bytes, + // input.get_half_ptr(), + // input.get_half_ptr(), + // idx, + // idx, + // total_ele, + // batch_size, + // begin_offset, + // end_offset + 1, + // 0, // begin_bit + // data_type_size(data_type) * 8, // end_bit = sizeof(KeyT) * 8 + // stream)); + // } else { + // assert(false && "input type in float and half"); + // } + + gpu_mem_allocator.create_legion_instance(reserveInst, temp_storage_bytes); + d_temp_storage = + gpu_mem_allocator.allocate_instance_untyped(temp_storage_bytes); +} + +SamplingMeta::~SamplingMeta(void) {} +}; // namespace FlexFlow \ No newline at end of file diff --git a/src/ops/sampling.cu b/src/ops/sampling.cu new file mode 100644 index 0000000000..461d72ec71 --- /dev/null +++ b/src/ops/sampling.cu @@ -0,0 +1,287 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "cub/cub.cuh" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/sampling.h" +#include "flexflow/utils/cuda_helper.h" +#include +#include + +namespace FlexFlow { + +constexpr int SamplingNumThreads = 1024; +struct BlockPrefixCallbackOp { + // Running prefix + float running_total; + // Constructor + __device__ BlockPrefixCallbackOp(float running_total) + : running_total(running_total) {} + // Callback operator to be entered by the first warp of threads in the block. + // Thread-0 is responsible for returning a value for seeding the block-wide + // scan. + __device__ float operator()(float block_aggregate) { + float old_prefix = running_total; + running_total += block_aggregate; + return old_prefix; + } +}; + +__global__ void init_idxs(int batch_size, + int vocab_size, + int total_eles, + int *idx, + int *begin_offset, + int *end_offset) { + CUDA_KERNEL_LOOP(i, total_eles) { + idx[i] = i % vocab_size; + if (i % vocab_size == 0) { + begin_offset[i / vocab_size] = i; + end_offset[i / vocab_size] = i; + } + } +} + +__global__ void + init_random_kernel(curandState *state, int batch_size, long rand) { + CUDA_KERNEL_LOOP(i, batch_size) { + curand_init(rand, i, 0, &state[i]); + } +} + +// multinominal and gather +template +__global__ void sampling_topp_kernel(int batch_size, + int const vocab_size, + curandState *state, + DT *sorted_logits, + int *sorted_idx, + int *indices_ptr, + float topp) { + // int const vocab_id = threadIdx.x; + int const batch_idx = blockIdx.x; + __shared__ float random_n; + __shared__ long long result_idx; + + // random num + if (threadIdx.x == 0) { + // number must < topp + random_n = curand_uniform(state + batch_idx) * topp; + // printf("batch idx: %d, random num%f\n", batch_idx, random_n); + } + + __syncthreads(); + + // cumsum; + typedef cub::BlockScan BlockScan; + __shared__ typename BlockScan::TempStorage temp_storage; + + int offset = batch_idx * vocab_size; + float prefix_sum = 0.0f; + BlockPrefixCallbackOp prefix_op(0); + result_idx = vocab_size - 1; + + for (long long j = threadIdx.x; j < vocab_size; j += blockDim.x) { + float logit = (float)(sorted_logits[offset + j]); + BlockScan(temp_storage).InclusiveSum(logit, prefix_sum, prefix_op); + prefix_sum /= topp; + if (prefix_sum >= random_n) { + atomicMin(&result_idx, j); + } + } + indices_ptr[batch_idx] = sorted_idx[offset + result_idx]; + + // if (threadIdx.x == 0) { + // printf("selected idx: %d, %d\n", blockIdx.x, result_idx); + // } +} + +/*static*/ +template +void Sampling::forward_kernel(SamplingMeta const *m, + DT *input_ptr, + int *indices_ptr, + float const top_p, + int const length, + int const batch_size, + cudaStream_t stream) { + // 1. sort + size_t temp_storage_bytes = m->temp_storage_bytes; + checkCUDA(cub::DeviceSegmentedRadixSort::SortPairsDescending( + m->d_temp_storage, + temp_storage_bytes, + input_ptr, + static_cast
(m->sorted_logits), + m->idx, + m->sorted_idx, + length * batch_size, + batch_size, + m->begin_offset, + m->end_offset + 1, + 0, // begin_bit + sizeof(DT) * 8, // end_bit = sizeof(KeyT) * 8 + stream)); + int parallelism = batch_size; + init_random_kernel<<>>(m->state, batch_size, rand()); + // sampling + sampling_topp_kernel + <<>>( + batch_size, + length, + m->state, + static_cast
(m->sorted_logits), + m->sorted_idx, + indices_ptr, + top_p); +} + +/*static*/ +void Sampling::forward_kernel_wrapper(SamplingMeta const *m, + GenericTensorAccessorW const &input, + GenericTensorAccessorW const &indices, + int batch_size) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + int length = input.domain.hi()[0] - input.domain.lo()[0] + 1; + + if (input.data_type == DT_HALF) { + Sampling::forward_kernel(m, + input.get_half_ptr(), + indices.get_int32_ptr(), + m->top_p, + length, + batch_size, + stream); + } else if (input.data_type == DT_FLOAT) { + Sampling::forward_kernel(m, + input.get_float_ptr(), + indices.get_int32_ptr(), + m->top_p, + length, + batch_size, + stream); + } else { + assert(false && "Unsupported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[Sampling] forward time = %.2lfms\n", elapsed); + } +} + +SamplingMeta::SamplingMeta(FFHandler handler, + Op const *op, + int batch_size, + int total_ele, + GenericTensorAccessorW input, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handler, op) { + DataType data_type = op->data_type; + + size_t begin_offset_size, end_offset_size; + begin_offset_size = end_offset_size = batch_size + 1; + size_t idx_size, sorted_idx_size, sorted_logits_size; + idx_size = sorted_idx_size = sorted_logits_size = total_ele; + size_t state_size = batch_size; + + size_t totalSize = sizeof(int) * (begin_offset_size + end_offset_size + + idx_size + sorted_idx_size) + + data_type_size(data_type) * sorted_logits_size + + sizeof(curandState) * state_size; + gpu_mem_allocator.create_legion_instance(reserveInst, totalSize); + begin_offset = gpu_mem_allocator.allocate_instance(begin_offset_size); + end_offset = gpu_mem_allocator.allocate_instance(end_offset_size); + idx = gpu_mem_allocator.allocate_instance(idx_size); + sorted_idx = gpu_mem_allocator.allocate_instance(sorted_idx_size); + sorted_logits = gpu_mem_allocator.allocate_instance_untyped( + sorted_logits_size * data_type_size(data_type)); + state = gpu_mem_allocator.allocate_instance(state_size); + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + // init offset + int parallelism = total_ele; + init_idxs<<>>(batch_size, + total_ele / batch_size, + total_ele, + idx, + begin_offset, + end_offset); + + // init sort function + if (data_type == DT_FLOAT) { + checkCUDA(cub::DeviceSegmentedRadixSort::SortPairsDescending( + d_temp_storage, + temp_storage_bytes, + input.get_float_ptr(), + input.get_float_ptr(), + idx, + idx, + total_ele, + batch_size, + begin_offset, + end_offset + 1, + 0, // begin_bit + data_type_size(data_type) * 8, // end_bit = sizeof(KeyT) * 8 + stream)); + } else if (data_type == DT_HALF) { + checkCUDA(cub::DeviceSegmentedRadixSort::SortPairsDescending( + d_temp_storage, + temp_storage_bytes, + input.get_half_ptr(), + input.get_half_ptr(), + idx, + idx, + total_ele, + batch_size, + begin_offset, + end_offset + 1, + 0, // begin_bit + data_type_size(data_type) * 8, // end_bit = sizeof(KeyT) * 8 + stream)); + } else { + assert(false && "input type in float and half"); + } + + gpu_mem_allocator.create_legion_instance(reserveInst, temp_storage_bytes); + d_temp_storage = + gpu_mem_allocator.allocate_instance_untyped(temp_storage_bytes); +} + +SamplingMeta::~SamplingMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} +}; // namespace FlexFlow \ No newline at end of file diff --git a/src/ops/sigmoid_silu_multi.cc b/src/ops/sigmoid_silu_multi.cc new file mode 100644 index 0000000000..3ddd6b8d6e --- /dev/null +++ b/src/ops/sigmoid_silu_multi.cc @@ -0,0 +1,411 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/sigmoid_silu_multi.h" +#include "flexflow/model.h" +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::InlineLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; + +bool operator==(SigmoidSiluMultiParams const &lhs, + SigmoidSiluMultiParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid; +} + +bool SigmoidSiluMultiParams::is_valid( + std::pair const &input) const { + return input.first.is_valid() && input.second.is_valid(); +} + +SigmoidSiluMultiParams SigmoidSiluMulti::get_params() const { + SigmoidSiluMultiParams params; + params.layer_guid = this->layer_guid; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +Tensor FFModel::sigmoid_silu_multi(const Tensor input1, + const Tensor input2, + DataType data_type, + char const *name) { + + // Check dims + assert(input1->num_dims == input2->num_dims); + for (int i = 0; i < input1->num_dims; i++) { + assert(input1->dims[i] == input2->dims[i]); + } + // Tensor Data type + if (data_type == DT_NONE) { + data_type = input1->data_type; + assert(input2->data_type == input1->data_type); + } + Tensor casted_input1 = + (data_type != input1->data_type) + ? cast(input1, data_type, "type cast for sigmoid_silu_multi") + : input1; + Tensor casted_input2 = + (data_type != input2->data_type) + ? cast(input2, data_type, "type cast for sigmoid_silu_multi") + : input2; + + // Create layer + Layer *ssm = new Layer(this, + OP_SIGMOID_SILU_MULTI, + data_type, + name, + 2 /*inputs*/, + 0 /*weights*/, + 1 /*outputs*/, + casted_input1, + casted_input2); + ssm->outputs[0] = create_tensor_legion_ordering( + input1->num_dims, input1->dims, data_type, ssm, 0, false /*create_grad*/); + layers.push_back(ssm); + return ssm->outputs[0]; +} + +Op *SigmoidSiluMulti::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + + return new SigmoidSiluMulti( + model, layer->layer_guid, inputs[0], inputs[1], layer->name); +} + +SigmoidSiluMulti::SigmoidSiluMulti( + FFModel &model, + SigmoidSiluMultiParams const ¶ms, + std::pair const &inputs, + char const *name) + : SigmoidSiluMulti( + model, params.layer_guid, inputs.first, inputs.second, params.name) {} + +SigmoidSiluMulti::SigmoidSiluMulti(FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input1, + const ParallelTensor _input2, + char const *name) + : Op(model, + OP_SIGMOID_SILU_MULTI, + _input1->data_type, + name, + 2 /*inputs*/, + 0 /*weights*/, + 1 /*outputs*/, + _input1, + _input2) { + // overwrite layer_guid + layer_guid = _layer_guid; + outputs[0] = model.create_parallel_tensor_legion_ordering(_input1->num_dims, + _input1->dims, + _input1->data_type, + this, + 0 /*owner_idx*/); +} + +void SigmoidSiluMulti::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(SIGMOID_SILU_MULTI_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(SigmoidSiluMulti)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + // input 1 + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // input 2 + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // output + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void SigmoidSiluMulti::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(SIGMOID_SILU_MULTI_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(SigmoidSiluMulti)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + // input 1 + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // input 2 + launcher.add_region_requirement(RegionRequirement(inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // output + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +/* + regions[0](I): input 1 + regions[1](I): input 2 + regions[2](O): output +*/ +OpMeta *SigmoidSiluMulti::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + SigmoidSiluMulti *ssm = (SigmoidSiluMulti *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + SigmoidSiluMultiMeta *meta = + new SigmoidSiluMultiMeta(handle, ssm, gpu_mem_allocator); + meta->input_type[0] = ssm->inputs[0]->data_type; + meta->input_type[1] = ssm->inputs[1]->data_type; + meta->output_type[0] = ssm->outputs[0]->data_type; + std::strcpy(meta->op_name, ssm->name); + meta->layer_guid = ssm->layer_guid; + return meta; +} + +void SigmoidSiluMulti::forward(FFModel const &ff) { + assert(false); +} + +void SigmoidSiluMulti::backward(FFModel const &ff) { + assert(false); +} + +FutureMap SigmoidSiluMulti::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "SigmoidSiluMulti op machine_view: " << *(MachineView + const *)mv + << std::endl; */ + IndexLauncher launcher(SIGMOID_SILU_MULTI_INF_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + // input 1 + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + // input 2 + launcher.add_region_requirement(RegionRequirement(batch_inputs[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[1]->region)); + launcher.add_field(1, FID_DATA); + // output + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input 1 + regions[1](I): input 2 + regions[2](O): output +*/ +void SigmoidSiluMulti::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + + assert(task->regions.size() == regions.size()); + assert(regions.size() == 3); + + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + + SigmoidSiluMultiMeta *m = *((SigmoidSiluMultiMeta **)task->local_args); + + GenericTensorAccessorR input1 = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR input2 = helperGetGenericTensorAccessorRO( + m->input_type[1], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + + Domain input1_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain input2_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + + assert(input1_domain.get_volume() == input2_domain.get_volume()); + assert(input1_domain.get_volume() == output_domain.get_volume()); + + assert(input1_domain == input2_domain); + assert(input1_domain == output_domain); + + SigmoidSiluMulti::inference_kernel_wrapper(m, input1, input2, output); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + SigmoidSiluMulti::save_inference_tensors_to_file( + m, shard_id, bc, {input1, input2}, {}, {output}); + } +} + +bool SigmoidSiluMulti::measure_operator_cost(Simulator *sim, + MachineView const &mv, + CostMetrics &cost_metrics) const { + return false; +} + +void SigmoidSiluMulti::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node SigmoidSiluMulti::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 2); + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + + SigmoidSiluMultiParams params; + params.layer_guid = layer_guid; + strcpy(params.name, name); + return ff.get_or_create_node({inputs[0], inputs[1]}, + params); +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::SigmoidSiluMultiParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.layer_guid.transformer_layer_id); + hash_combine(key, params.layer_guid.model_id); + return key; +} +}; // namespace std diff --git a/src/ops/sigmoid_silu_multi.cpp b/src/ops/sigmoid_silu_multi.cpp new file mode 100644 index 0000000000..7b7f30a288 --- /dev/null +++ b/src/ops/sigmoid_silu_multi.cpp @@ -0,0 +1,119 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/sigmoid_silu_multi.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { + +SigmoidSiluMultiMeta::SigmoidSiluMultiMeta(FFHandler handle, + SigmoidSiluMulti const *ssm, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + profiling = ssm->profiling; + inference_debugging = ssm->inference_debugging; +} + +SigmoidSiluMultiMeta::~SigmoidSiluMultiMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +__device__ __forceinline__ float sigmoid_float(float x) { + return 1.0 / (1.0 + expf(-x)); +} + +__device__ __forceinline__ half sigmoid_half(half x) { + return (half)1.0 / ((half)1.0 + hexp(-x)); +} + +__global__ void SigmoidSiluMultiKernelFloat(int num_elements, + float const *input1_ptr, + float const *input2_ptr, + float *output_ptr) { + CUDA_KERNEL_LOOP(i, num_elements) { + output_ptr[i] = + input1_ptr[i] * sigmoid_float(input1_ptr[i]) * input2_ptr[i]; + } +} + +__global__ void SigmoidSiluMultiKernelHalf(int num_elements, + half const *input1_ptr, + half const *input2_ptr, + half *output_ptr) { + CUDA_KERNEL_LOOP(i, num_elements) { + output_ptr[i] = input1_ptr[i] * sigmoid_half(input1_ptr[i]) * input2_ptr[i]; + } +} + +/*static*/ +void SigmoidSiluMulti::inference_kernel_wrapper( + SigmoidSiluMultiMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorW const &output) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + int num_elements = input1.domain.get_volume(); + assert(input2.domain.get_volume() == num_elements); + assert(output.domain.get_volume() == num_elements); + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + if (m->input_type[0] == DT_FLOAT) { + hipLaunchKernelGGL(HIP_KERNEL_NAME(SigmoidSiluMultiKernelFloat), + GET_BLOCKS(num_elements), + min(CUDA_NUM_THREADS, num_elements), + 0, + stream, + input1.domain.get_volume(), + input1.get_float_ptr(), + input2.get_float_ptr(), + output.get_float_ptr()); + } else if (m->input_type[0] == DT_HALF) { + hipLaunchKernelGGL(HIP_KERNEL_NAME(SigmoidSiluMultiKernelHalf), + GET_BLOCKS(num_elements), + min(CUDA_NUM_THREADS, num_elements), + 0, + stream, + input1.domain.get_volume(), + input1.get_half_ptr(), + input2.get_half_ptr(), + output.get_half_ptr()); + } else { + assert(false && "unsupport datatype in SigmoidSiluMulti"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("[SigmoidSiluMulti] forward time (CF) = %.9fms\n", elapsed); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/sigmoid_silu_multi.cu b/src/ops/sigmoid_silu_multi.cu new file mode 100644 index 0000000000..590b641b5a --- /dev/null +++ b/src/ops/sigmoid_silu_multi.cu @@ -0,0 +1,98 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/sigmoid_silu_multi.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +SigmoidSiluMultiMeta::SigmoidSiluMultiMeta(FFHandler handle, + SigmoidSiluMulti const *ssm, + MemoryAllocator &gpu_mem_allocator) + : OpMeta(handle) { + profiling = ssm->profiling; + inference_debugging = ssm->inference_debugging; +} + +SigmoidSiluMultiMeta::~SigmoidSiluMultiMeta(void) { + if (reserveInst != Realm::RegionInstance::NO_INST) { + reserveInst.destroy(); + } +} + +template +__global__ void SigmoidSiluMultiKernel(int num_elements, + T const *input1_ptr, + T const *input2_ptr, + T *output_ptr) { + CUDA_KERNEL_LOOP(i, num_elements) { + float sigmoid_val = static_cast(input1_ptr[i]); + sigmoid_val = 1.0f / (1.0f + exp(-sigmoid_val)); + output_ptr[i] = input1_ptr[i] * T(sigmoid_val) * input2_ptr[i]; + } +} + +/*static*/ +void SigmoidSiluMulti::inference_kernel_wrapper( + SigmoidSiluMultiMeta const *m, + GenericTensorAccessorR const &input1, + GenericTensorAccessorR const &input2, + GenericTensorAccessorW const &output) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + int num_elements = input1.domain.get_volume(); + assert(input2.domain.get_volume() == num_elements); + assert(output.domain.get_volume() == num_elements); + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + if (m->input_type[0] == DT_FLOAT) { + SigmoidSiluMultiKernel<<>>(input1.domain.get_volume(), + input1.get_float_ptr(), + input2.get_float_ptr(), + output.get_float_ptr()); + } else if (m->input_type[0] == DT_HALF) { + SigmoidSiluMultiKernel<<>>(input1.domain.get_volume(), + input1.get_half_ptr(), + input2.get_half_ptr(), + output.get_half_ptr()); + } else { + assert(false && "unsupport datatype in SigmoidSiluMulti"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("[SigmoidSiluMulti] forward time (CF) = %.9fms\n", elapsed); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/softmax.cc b/src/ops/softmax.cc index ab65db542e..4c2a78d165 100644 --- a/src/ops/softmax.cc +++ b/src/ops/softmax.cc @@ -17,6 +17,7 @@ #include "flexflow/model.h" #include "flexflow/ops/kernels/softmax_kernels.h" #include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" namespace FlexFlow { // declare Legion names @@ -39,7 +40,42 @@ using namespace FlexFlow::Kernels::Softmax; /* Params */ bool operator==(SoftmaxParams const &lhs, SoftmaxParams const &rhs) { - return lhs.dim == rhs.dim; + return lhs.layer_guid == rhs.layer_guid && lhs.dim == rhs.dim; +} + +void Softmax::serialize(Legion::Serializer &sez) const { + sez.serialize(this->layer_guid.id); + sez.serialize(this->layer_guid.transformer_layer_id); + sez.serialize(this->layer_guid.model_id); + sez.serialize(this->dim); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); +} + +using PCG::Node; +/*static*/ +Node Softmax::deserialize(FFModel &ff, + Legion::Deserializer &dez, + ParallelTensor inputs[], + int num_inputs) { + assert(num_inputs == 1); + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + int dim; + dez.deserialize(dim); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + SoftmaxParams params; + params.layer_guid = layer_guid; + params.dim = dim; + strcpy(params.name, name); + return ff.get_or_create_node(inputs[0], params); } bool SoftmaxParams::is_valid(ParallelTensorShape const &input) const { @@ -48,17 +84,25 @@ bool SoftmaxParams::is_valid(ParallelTensorShape const &input) const { SoftmaxParams Softmax::get_params() const { SoftmaxParams params; + params.layer_guid = this->layer_guid; params.dim = this->dim; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } -Tensor FFModel::softmax(const Tensor _input, +Tensor FFModel::softmax(Tensor const _input, int dim, + DataType data_type, bool last_layer, char const *name) { + if (data_type == DT_NONE) { + data_type = _input->data_type; + } Layer *sm = new Layer(this, OP_SOFTMAX, - DT_FLOAT, + data_type, name, 1 /*inputs*/, 0 /*weights*/, @@ -70,7 +114,7 @@ Tensor FFModel::softmax(const Tensor _input, dims[i] = _input->dims[i]; } sm->outputs[0] = create_tensor_legion_ordering( - numdims, dims, DT_FLOAT, sm, 0, true /*create_grad*/); + numdims, dims, data_type, sm, 0, true /*create_grad*/); sm->add_int_property("softmax_dim", dim); sm->add_int_property("last_layer", last_layer); @@ -88,6 +132,7 @@ Op *Softmax::create_operator_from_layer( layer->get_int_property("last_layer", value); bool last_layer = (bool)value; return new Softmax(model, + layer->layer_guid, inputs[0], (inputs[0]->num_dims - 1 - dim) % inputs[0]->num_dims, last_layer, @@ -95,7 +140,8 @@ Op *Softmax::create_operator_from_layer( } Softmax::Softmax(FFModel &model, - const ParallelTensor _input, + LayerID const &_layer_guid, + ParallelTensor const _input, int _dim, bool _last_layer, char const *name) @@ -110,19 +156,62 @@ Softmax::Softmax(FFModel &model, dim(_dim), last_layer(_last_layer) { // Currently assume we always perform softmax along the inner most dim assert(dim == 0); + layer_guid = _layer_guid; ParallelDim dims[MAX_TENSOR_DIM]; int numdim = _input->num_dims; for (int i = 0; i < numdim; i++) { dims[i] = _input->dims[numdim - 1 - i]; } - outputs[0] = model.create_parallel_tensor(numdim, dims, DT_FLOAT, this); + outputs[0] = model.create_parallel_tensor(numdim, dims, data_type, this); } Softmax::Softmax(FFModel &model, SoftmaxParams const ¶ms, - const ParallelTensor input, + ParallelTensor const input, char const *name) - : Softmax(model, input, params.dim, params.last_layer, name) {} + : Softmax(model, + params.layer_guid, + input, + params.dim, + params.last_layer, + params.name) {} + +void Softmax::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(SOFTMAX_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Softmax)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_DISCARD, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} void Softmax::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -193,10 +282,52 @@ OpMeta *Softmax::init_task(Task const *task, domain = input_domain; } SoftmaxMeta *m = new SoftmaxMeta(handle, softmax, domain); + m->input_type = softmax->inputs[0]->data_type; + m->output_type = softmax->outputs[0]->data_type; // checkCUDNN(cudnnCreateTensorDescriptor(&m->outputTensor)); + std::strcpy(m->op_name, softmax->name); + m->layer_guid = softmax->layer_guid; return m; } +FutureMap Softmax::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "Softmax op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(SOFTMAX_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void Softmax::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; @@ -229,42 +360,23 @@ void Softmax::forward_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - Domain in_domain = runtime->get_index_space_domain( - ctx, task->regions[0].region.get_index_space()); - switch (in_domain.get_dim()) { -#define DIMFUNC(DIM) \ - case DIM: \ - return forward_task_with_dim(task, regions, ctx, runtime); - LEGION_FOREACH_N(DIMFUNC) -#undef DIMFUNC - default: - assert(false); - } -} - -/* - regions[0](I): input - regions[1](O): output -*/ -template -void Softmax::forward_task_with_dim(Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { assert(regions.size() == 2); assert(task->regions.size() == 2); - // const Softmax* softmax = (Softmax*) task->args; + Domain in_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); SoftmaxMeta const *m = *((SoftmaxMeta **)task->local_args); - TensorAccessorR acc_input( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - TensorAccessorW acc_output(regions[1], - task->regions[1], - FID_DATA, - ctx, - runtime, - false /*readOutput*/); - - forward_kernel_wrapper(m, acc_input.ptr, acc_output.ptr); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->output_type, regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type, regions[1], task->regions[1], FID_DATA, ctx, runtime); + + if (m->output_type == DT_HALF) { + forward_kernel_wrapper(m, input.get_half_ptr(), output.get_half_ptr()); + } else if (m->output_type == DT_FLOAT) { + forward_kernel_wrapper(m, input.get_float_ptr(), output.get_float_ptr()); + } else { + assert(false && "Unsupported data type"); + } } void Softmax::backward(FFModel const &ff) { @@ -308,10 +420,17 @@ void Softmax::backward_task(Task const *task, Runtime *runtime) { Domain in_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); + SoftmaxMeta const *m = *((SoftmaxMeta **)task->local_args); switch (in_domain.get_dim()) { #define DIMFUNC(DIM) \ case DIM: \ - return backward_task_with_dim(task, regions, ctx, runtime); + if (m->output_type == DT_HALF) { \ + return backward_task_with_dim(task, regions, ctx, runtime); \ + } else if (m->output_type == DT_FLOAT) { \ + return backward_task_with_dim(task, regions, ctx, runtime); \ + } else { \ + assert(false && "Unsupported data type"); \ + } LEGION_FOREACH_N(DIMFUNC) #undef DIMFUNC default: @@ -326,7 +445,7 @@ void Softmax::backward_task(Task const *task, // Note that the backward task of softmax is actually a no op (i.e., input_grad // = output_grad) since the upstream cross_entropy_loss function computes // performs softmax_cross_entropy_loss to avoid intermediate zeros -template +template void Softmax::backward_task_with_dim(Task const *task, std::vector const ®ions, Context ctx, @@ -335,13 +454,13 @@ void Softmax::backward_task_with_dim(Task const *task, assert(task->regions.size() == 3); // const Softmax* softmax = (Softmax*) task->args; SoftmaxMeta const *m = *((SoftmaxMeta **)task->local_args); - TensorAccessorW acc_input_grad(regions[0], - task->regions[0], - FID_DATA, - ctx, - runtime, - true /*readOutput*/); - TensorAccessorR acc_output_grad( + TensorAccessorW acc_input_grad(regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime, + true /*readOutput*/); + TensorAccessorR acc_output_grad( regions[1], task->regions[1], FID_DATA, ctx, runtime); TensorAccessorR acc_output( regions[2], task->regions[1], FID_DATA, ctx, runtime); @@ -355,6 +474,39 @@ void Softmax::backward_task_with_dim(Task const *task, acc_input_grad.rect.volume()); } +void Softmax::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + assert(regions.size() == 2); + assert(task->regions.size() == 2); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + if (bc->num_tokens == 0) { + return; + } + Domain in_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + SoftmaxMeta *m = *((SoftmaxMeta **)task->local_args); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->output_type, regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type, regions[1], task->regions[1], FID_DATA, ctx, runtime); + if (m->output_type == DT_HALF) { + forward_kernel_wrapper(m, input.get_half_ptr(), output.get_half_ptr()); + } else if (m->output_type == DT_FLOAT) { + forward_kernel_wrapper(m, input.get_float_ptr(), output.get_float_ptr()); + } else { + assert(false && "Unsupported data type"); + } + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + Softmax::save_inference_tensors_to_file( + m, shard_id, bc, {input}, {}, {output}); + } +} + bool Softmax::get_int_parameter(PMParameter para, int *value) const { switch (para) { case PM_SOFTMAX_DIM: @@ -439,6 +591,7 @@ namespace std { size_t hash::operator()( FlexFlow::SoftmaxParams const ¶ms) const { size_t key = 0; + hash_combine(key, params.layer_guid.id); hash_combine(key, params.dim); hash_combine(key, params.last_layer); return key; diff --git a/src/ops/spec_inc_multihead_self_attention.cc b/src/ops/spec_inc_multihead_self_attention.cc new file mode 100644 index 0000000000..9c6ed0e0b6 --- /dev/null +++ b/src/ops/spec_inc_multihead_self_attention.cc @@ -0,0 +1,886 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/spec_inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/model.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +bool SpecIncMultiHeadSelfAttentionParams::is_valid( + ParallelTensorShape const &input) const { + bool is_valid = input.is_valid(); + return is_valid; +} + +Tensor + FFModel::spec_inc_multihead_self_attention(Tensor const input, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + return spec_inc_multiquery_self_attention(input, + embed_dim, + num_heads, + num_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); +} + +Tensor + FFModel::spec_inc_multiquery_self_attention(Tensor const input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + if (data_type == DT_NONE) { + data_type = input->data_type; + } + Layer *li = nullptr; + int weight_num = (qkv_bias || final_bias) ? 2 : 1; + if (data_type != input->data_type) { + Tensor casted_input = cast(input, data_type, "type cast for IncMHA"); + li = new Layer(this, + OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + casted_input); + } else { + li = new Layer(this, + OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + input); + } + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + dims[0] = embed_dim; + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, data_type, li, 0, true /*create_grad*/); + } + // Compute weight size + int qProjSize = kdim, kProjSize = kdim, vProjSize = kdim, + oProjSize = embed_dim; + int qSize = input->dims[0], kSize = input->dims[0], vSize = input->dims[0]; + int qParas = qProjSize * qSize; + int kParas = kProjSize * kSize; + int vParas = vProjSize * vSize; + int oParas = oProjSize * (vProjSize > 0 ? vProjSize : vSize); + int weight_size = qParas * num_q_heads + kParas * num_q_heads + + vParas * num_q_heads + oParas * num_q_heads; + { + int dims[1] = {weight_size}; + li->weights[0] = create_weight_legion_ordering(1, + dims, + data_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + if (qkv_bias || final_bias) { + // q, k, v, o + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + int dims[1] = {(qkv_bias ? qkv_bias_size : 0) + + (final_bias ? oProjSize : 0)}; + li->weights[1] = create_weight_legion_ordering(1, + dims, + data_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + li->data_type = data_type; + li->add_int_property("embed_dim", embed_dim); + li->add_int_property("num_q_heads", num_q_heads); + li->add_int_property("num_kv_heads", num_kv_heads); + li->add_int_property("kdim", kdim); + li->add_int_property("vdim", vdim); + li->add_int_property("qkv_bias", qkv_bias); + li->add_int_property("final_bias", final_bias); + li->add_int_property("add_zero_attn", add_zero_attn); + li->add_float_property("dropout", dropout); + li->add_int_property("apply_rotary_embedding", apply_rotary_embedding); + li->add_int_property("scaling_query", scaling_query); + li->add_float_property("scaling_factor", scaling_factor); + li->add_int_property("qk_prod_scaling", qk_prod_scaling); + li->add_int_property("position_bias", position_bias); + layers.push_back(li); + return li->outputs[0]; +} + +Op *SpecIncMultiHeadSelfAttention::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + + std::cout << "spec create operator: " << layer->name << "\n"; + long long value; + layer->get_int_property("embed_dim", value); + int embed_dim = value; + layer->get_int_property("num_q_heads", value); + int num_q_heads = value; + layer->get_int_property("num_kv_heads", value); + int num_kv_heads = value; + layer->get_int_property("kdim", value); + int kdim = value; + layer->get_int_property("vdim", value); + int vdim = value; + float dropout; + layer->get_float_property("dropout", dropout); + layer->get_int_property("qkv_bias", value); + bool qkv_bias = (bool)value; + layer->get_int_property("final_bias", value); + bool final_bias = (bool)value; + layer->get_int_property("add_zero_attn", value); + bool add_zero_attn = (bool)value; + layer->get_int_property("apply_rotary_embedding", value); + bool apply_rotary_embedding = (bool)value; + layer->get_int_property("scaling_query", value); + bool scaling_query = (bool)value; + float scaling_factor; + layer->get_float_property("scaling_factor", scaling_factor); + layer->get_int_property("qk_prod_scaling", value); + bool qk_prod_scaling = (bool)value; + layer->get_int_property("position_bias", value); + bool position_bias = (bool)value; + + return new SpecIncMultiHeadSelfAttention(model, + layer->layer_guid, + inputs[0], + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + false /*allocate_weights*/, + layer->name); +} + +SpecIncMultiHeadSelfAttention::SpecIncMultiHeadSelfAttention( + FFModel &model, + LayerID const &_layer_guid, + ParallelTensor const _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1) /*weights*/, + 1 /*outputs*/, + _input), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias) { + // overwrite layer_guid + layer_guid = _layer_guid; + + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>(dims, + this->data_type, + NULL /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* // Check correctness */ + /* assert(check_output_input_weight_parallel_dims()); */ +} + +SpecIncMultiHeadSelfAttention::SpecIncMultiHeadSelfAttention( + FFModel &model, + ParallelTensor const _input, + ParallelTensor const _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1) /*weights*/, + 1 /*outputs*/, + _input, + _weight), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias) +// bias_initializer(_bias_initializer) +{ + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + // dims[2].size = qParas + kParas + vParas + oParas; + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>(dims, + this->data_type, + NULL /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* register_output_weight_parallel_dims(outputs[0], numdim-1, _weight, 1); */ + /* register_output_weight_parallel_dims(outputs[0], numdim-2, _weight, 2); */ + // Check correctness + /* assert(check_output_input_weight_parallel_dims()); */ +} + +SpecIncMultiHeadSelfAttention::SpecIncMultiHeadSelfAttention( + FFModel &model, + SpecIncMultiHeadSelfAttention const &other, + ParallelTensor const input, + bool allocate_weights) + : SpecIncMultiHeadSelfAttention(model, + other.layer_guid, + input, + other.oProjSize, + other.num_q_heads, + other.num_kv_heads, + other.qProjSize, + other.vProjSize, + other.dropout, + other.qkv_bias, + other.final_bias, + other.add_zero_attn, + other.apply_rotary_embedding, + other.scaling_query, + other.scaling_factor, + other.qk_prod_scaling, + other.position_bias, + allocate_weights, + other.name) {} + +SpecIncMultiHeadSelfAttention::SpecIncMultiHeadSelfAttention( + FFModel &model, + SpecIncMultiHeadSelfAttentionParams const ¶ms, + ParallelTensor const &input, + bool allocate_weights, + char const *name) + : SpecIncMultiHeadSelfAttention(model, + params.layer_guid, + input, + params.embed_dim, + params.num_q_heads, + params.num_kv_heads, + params.kdim, + params.vdim, + params.dropout, + params.qkv_bias, + params.final_bias, + params.add_zero_attn, + params.apply_rotary_embedding, + params.scaling_query, + params.scaling_factor, + params.qk_prod_scaling, + params.position_bias, + allocate_weights, + params.name) {} + +void SpecIncMultiHeadSelfAttention::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher( + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(SpecIncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void SpecIncMultiHeadSelfAttention::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher( + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(SpecIncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +/* + regions[0](I): input + regions[1](I): weight + regions[2](O): output +*/ +OpMeta *SpecIncMultiHeadSelfAttention::init_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + SpecIncMultiHeadSelfAttention const *attn = + (SpecIncMultiHeadSelfAttention *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + + GenericTensorAccessorR input = + helperGetGenericTensorAccessorRO(attn->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR weight = + helperGetGenericTensorAccessorRO(attn->weights[0]->data_type, + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorW output = + helperGetGenericTensorAccessorWO(attn->outputs[0]->data_type, + regions[2], + task->regions[2], + FID_DATA, + ctx, + runtime); + + int num_samples = input.domain.hi()[2] - input.domain.lo()[2] + 1; + assert(attn->qoSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + assert(attn->kvSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + int num_q_heads = attn->num_q_heads; + int num_kv_heads = attn->num_kv_heads; + assert(attn->oProjSize == output.domain.hi()[0] - output.domain.lo()[0] + 1); + + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + // We don't do offloading for SSMs (small speculative models) + SpecIncMultiHeadSelfAttentionMeta *m = + new SpecIncMultiHeadSelfAttentionMeta(handle, + attn, + weight, + gpu_mem_allocator, + num_samples, + num_q_heads, + num_kv_heads); + // assert that we didn't over allocate memory + assert(gpu_mem_allocator.instance_allocated_size == + gpu_mem_allocator.instance_total_size); + m->profiling = attn->profiling; + m->inference_debugging = attn->inference_debugging; + std::strcpy(m->op_name, attn->name); + m->layer_guid = attn->layer_guid; + assert(weight.domain.get_volume() * data_type_size(weight.data_type) == + m->weightSize); + return m; +} + +void SpecIncMultiHeadSelfAttention::forward(FFModel const &ff) { + // SpecIncMultiHeadSelfAttention doesn't support forward + assert(false); +} + +FutureMap SpecIncMultiHeadSelfAttention::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + int idx = 0; + IndexLauncher launcher(SPEC_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + + if (qkv_bias || final_bias) { + launcher.add_region_requirement(RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region)); + launcher.add_field(idx++, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input + regions[3](I): weight + regions[4](O): output +*/ +void SpecIncMultiHeadSelfAttention::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + + BeamSearchBatchConfig const &bc = + Future(task->futures[0]).get_result(); + if (bc.num_tokens == 0) { + return; + } + + SpecIncMultiHeadSelfAttentionMeta *m = + *((SpecIncMultiHeadSelfAttentionMeta **)task->local_args); + assert(((*m->qkv_bias || *m->final_bias) ? regions.size() == 4 + : regions.size() == 3)); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + biases = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + Domain bias_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + assert(bias_domain.get_dim() == 4); + } + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain weight_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + + assert(input_domain.get_dim() == 4); + assert(weight_domain.get_dim() == 2); + assert(output_domain.get_dim() == 4); + + assert(task->index_point.get_dim() == 1); + SpecIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, &bc, task->index_point.point_data[0], input, weight, output, biases); + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + weights_accessors.push_back(weight); + if (*m->qkv_bias || *m->final_bias) { + weights_accessors.push_back(biases); + } + SpecIncMultiHeadSelfAttention::save_inference_tensors_to_file( + m, shard_id, &bc, {input}, weights_accessors, {output}); + } +} + +void SpecIncMultiHeadSelfAttention::backward(FFModel const &ff) { + // SpecIncMultiHeadSelfAttention does not support backward + assert(false); +} + +bool SpecIncMultiHeadSelfAttention::get_int_parameter(PMParameter para, + int *value) const { + switch (para) { + case PM_NUM_HEADS: + *value = num_q_heads; + return true; + default: + return Op::get_int_parameter(para, value); + } +} + +Op *SpecIncMultiHeadSelfAttention::materialize(FFModel &ff, + ParallelTensor inputs[], + int num_inputs) const { + SpecIncMultiHeadSelfAttentionParams params = get_params(); + return new SpecIncMultiHeadSelfAttention( + ff, params, inputs[0], true, this->name); +} + +bool SpecIncMultiHeadSelfAttention::measure_operator_cost( + Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const { + return false; +} + +bool operator==(SpecIncMultiHeadSelfAttentionParams const &lhs, + SpecIncMultiHeadSelfAttentionParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.embed_dim == rhs.embed_dim && + lhs.num_q_heads == rhs.num_q_heads && lhs.kdim == rhs.kdim && + lhs.vdim == rhs.vdim && lhs.dropout == rhs.dropout && + lhs.qkv_bias == rhs.qkv_bias && lhs.final_bias == rhs.final_bias && + lhs.add_zero_attn == rhs.add_zero_attn && + lhs.apply_rotary_embedding == rhs.apply_rotary_embedding && + lhs.scaling_query == rhs.scaling_query && + lhs.scaling_factor == rhs.scaling_factor && + lhs.qk_prod_scaling == rhs.qk_prod_scaling && + lhs.position_bias == rhs.position_bias; +} + +SpecIncMultiHeadSelfAttentionParams + SpecIncMultiHeadSelfAttention::get_params() const { + SpecIncMultiHeadSelfAttentionParams params; + params.layer_guid = this->layer_guid; + params.embed_dim = this->oProjSize; + params.num_q_heads = this->num_q_heads; + params.num_kv_heads = this->num_kv_heads; + params.kdim = this->kProjSize; + params.vdim = this->vProjSize; + params.dropout = this->dropout; + params.qkv_bias = this->qkv_bias; + params.final_bias = this->final_bias; + params.add_zero_attn = this->add_zero_attn; + params.apply_rotary_embedding = this->apply_rotary_embedding; + params.scaling_query = this->scaling_query; + params.scaling_factor = this->scaling_factor; + params.qk_prod_scaling = this->qk_prod_scaling; + params.position_bias = this->position_bias; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + + return params; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::SpecIncMultiHeadSelfAttentionParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.embed_dim); + hash_combine(key, params.num_q_heads); + hash_combine(key, params.num_kv_heads); + hash_combine(key, params.kdim); + hash_combine(key, params.vdim); + hash_combine(key, params.dropout); + hash_combine(key, params.qkv_bias); + hash_combine(key, params.final_bias); + hash_combine(key, params.add_zero_attn); + hash_combine(key, params.apply_rotary_embedding); + hash_combine(key, params.scaling_query); + hash_combine(key, params.scaling_factor); + hash_combine(key, params.qk_prod_scaling); + hash_combine(key, params.position_bias); + return key; +} +}; // namespace std diff --git a/src/ops/spec_inc_multihead_self_attention.cpp b/src/ops/spec_inc_multihead_self_attention.cpp new file mode 100644 index 0000000000..b1687d12a2 --- /dev/null +++ b/src/ops/spec_inc_multihead_self_attention.cpp @@ -0,0 +1,668 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/spec_inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/utils/hip_helper.h" +#include +#include + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +using namespace Kernels::IncMultiHeadAttention; + +namespace Kernels { +namespace SpecIncMultiHeadAttention { + +template +__global__ void spec_store_kv_cache( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + BatchConfig::PerTokenInfo *tokenInfos, + BatchConfig::PerRequestInfo *requestInfo, + BeamSearchBatchConfig::BeamSearchPerTokenInfo *beamTokenInfos, + BeamSearchBatchConfig::BeamSearchPerRequestInfo *beamRequestInfos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens, + int max_seq_len, + int max_beam_width, + bool is_root, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size * 2) { + int token_idx = i / (hidden_size * KV_WEIGHT_NUM); + int offset = i % hidden_size; + + size_t val_idx = + token_idx * QKV_WEIGHT_NUM * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + // above no need to be changed + // int const req_id = id_map[token_idx].request_index; + // int const tok_id = id_map[token_idx].token_position; + // int const sub_req_id = id_map[token_idx].sub_request_index; + // int const parent_id = id_map[token_idx].parent_id; + // int const beam_depth = id_map[token_idx].beam_depth; + // int const beam_width = id_map[token_idx].beam_width; + + int const req_id = tokenInfos[token_idx].request_index; + int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + int const sub_req_id = beamTokenInfos[token_idx].sub_request_index; + int const parent_id = beamRequestInfos[req_id].parent_id[sub_req_id]; + int const beam_depth = beamRequestInfos[req_id].current_depth; + int const beam_width = beamRequestInfos[req_id].beam_size; + + // new token + kCache_ptr[(req_id * max_beam_width + sub_req_id) * + (hidden_size * max_seq_len) + + tok_id * hidden_size + offset] = kVal; + vCache_ptr[(req_id * max_beam_width + sub_req_id) * + (hidden_size * max_seq_len) + + tok_id * hidden_size + offset] = vVal; + + // replica in the root iteration + if (beam_depth == 1) { + for (int i = 1; i < beam_width; i++) { + kCache_ptr[(req_id * max_beam_width + i) * (hidden_size * max_seq_len) + + tok_id * hidden_size + offset] = kVal; + vCache_ptr[(req_id * max_beam_width + i) * (hidden_size * max_seq_len) + + tok_id * hidden_size + offset] = vVal; + } + } + + // naive cache stealing + if (sub_req_id != parent_id) { + if (offset == 0 && tok_id == 0) { + printf("cache stealing!, depth %d req_id %d sub_req_id %d, parentid " + "%d, tok_id %d\n", + beam_depth, + req_id, + sub_req_id, + parent_id, + tok_id); + } + + for (int depth = 0; depth < beam_depth; depth++) { + int steal_token_idx = tok_id - beam_depth + depth; + int steal_from_idx = (req_id * max_beam_width + parent_id) * + (hidden_size * max_seq_len) + + steal_token_idx * hidden_size + offset; + int steal_to_idx = (req_id * max_beam_width + sub_req_id) * + (hidden_size * max_seq_len) + + steal_token_idx * hidden_size + offset; + kCache_ptr[steal_to_idx] = kCache_ptr[steal_from_idx]; + vCache_ptr[steal_to_idx] = vCache_ptr[steal_from_idx]; + + // if(data_idx == 0 && head_idx == 0 && k_cache && req_id == 1){ + // printf("cache stealing kernel!, steal_token_idx %d\n", + // steal_token_idx); + // } + } + } + + // parallel cache stealing not yet implemented + // logic shld be + // launch spec_store_kv_cache with parallelism * current depth + // from the i here, get depth index + // if depth index not the current one, check if we need to steal + // steal if needed + + // cache stealing theory + // identify which sub request does this token come from + // for initial token, 0 + // for other, may 0,0,1/ 0,1,2/ 1,1,1 to get which cache to be reuse and + // which to be delete copy beam_size bunch of blocks when sub_req_id == + // parent_id : like 0 -> 0, 1->1, 2->2, do nothing, just append the new k/v + } +} + +template +void update_kv_cache_kernel(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + hipStream_t stream) { + int num_tokens = bc->num_active_tokens(); + int curr_depth = bc->beamRequestsInfo[0].current_depth; + // printf("curr depth: %d\n", curr_depth); + // assert(curr_depth < 3); + if (num_tokens > 0) { + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_tokens; + hipLaunchKernelGGL(HIP_KERNEL_NAME(spec_store_kv_cache
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + m->request_infos, + m->beam_token_infos, + m->beam_request_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_tokens, + BatchConfig::max_sequence_length(), + BeamSearchBatchConfig::MAX_BEAM_WIDTH, + /*root*/ curr_depth == 0, + m->hidden_size); + } +} + +template +__global__ void spec_fill_entries_above_diagonal(DT *matrix, + size_t new_tokens, + size_t total_tokens_in_request, + size_t num_q_heads, + DT value) { + CUDA_KERNEL_LOOP(i, new_tokens * total_tokens_in_request * num_q_heads) { + // size_t head_idx = i / (new_tokens * total_tokens_in_request); + size_t src_idx = (i / new_tokens) % total_tokens_in_request; + size_t dst_idx = i % new_tokens + total_tokens_in_request - new_tokens; + // Casual Mask + if (src_idx > dst_idx) { + matrix[i] = value; + } + } +} + +template +void compute_attention_kernel(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *bias_ptr, + DT const *weight_ptr, + hipStream_t stream) { + checkCUDA(hipblasSetStream(m->handle.blas, stream)); + checkCUDNN(miopenSetStream(m->handle.dnn, stream)); + hipblasDatatype_t hipblas_data_type = ff_to_cuda_datatype(m->output_type[0]); + miopenDataType_t miopen_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = hipblas_data_type; +#else + // TODO: currently use the hipblas_data_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = hipblas_data_type; +#endif + // int num_requests = bc->num_active_requests(); + int num_tokens = bc->num_active_tokens(); + int tokens_previous_requests = 0; + int tokens_prev_requests_squares = 0; + // int qkv_block_size = + // (m->qProjSize + m->kProjSize + m->vProjSize) * num_tokens; + int q_block_size = m->qProjSize; + int kt_block_size = m->kProjSize; + int kt_req_block_size = + kt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + int vt_block_size = m->vProjSize; + int vt_req_block_size = + vt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + for (int sub_req_id = 0; sub_req_id < bc->sub_requests[i]; sub_req_id++) { + + // int num_new_tokens = bc->num_processing_tokens[i]; + // int total_tokens = bc->token_last_available_idx[i] + 1; + + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + int total_tokens = bc->requestsInfo[i].first_token_depth_in_request + + bc->requestsInfo[i].num_tokens_in_batch; + // Compute (QK^T/sqrt(d_k)) + int m_ = num_new_tokens; + int n = total_tokens; + int k = m->qProjSize; + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens; + + // a flag of using this scaling alpha + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // To get A, skip over Q entries from previous requests (same head) + DT const *A = static_cast
(m->devQKVProjArray) + + tokens_previous_requests * m->qProjSize * m->num_q_heads * + QKV_WEIGHT_NUM; + // To get B, skip over K entries from previous requests (all heads + + // padding) + DT const *B = static_cast
(m->keyCache) + + (i * bc->MAX_BEAM_WIDTH + sub_req_id) * kt_req_block_size; + + // if (i == 0 && sub_req_id == 0 && + // bc->beam_slots.at(0).current_depth == 1) { + // int offset = (float *)B - m->keyCache; + // printf("key cache offset %d\n", kt_req_block_size); + // } + // To get C, skip over QK^T products from previous requests + DT *C = static_cast
(m->qk_prods) + + m->num_q_heads * tokens_prev_requests_squares; + + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + if (*m->position_bias) { + size_t parallelism = m->num_q_heads * total_tokens * num_new_tokens; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_position_bias_qkprd
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + + // Fill all elements above diagonal in qk prods with -inf to force + // causal attention. + assert(num_new_tokens <= total_tokens); + if (num_new_tokens > 1) { + size_t parallelism = m->num_q_heads * num_new_tokens * total_tokens; + hipLaunchKernelGGL( + HIP_KERNEL_NAME(spec_fill_entries_above_diagonal
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens, + m->num_q_heads, + static_cast
(-INFINITY)); + } + // Compute Softmax(QK^T/sqrt(d_k)) + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(miopenSet4dTensorDescriptor( + m->qk_tensor, miopen_data_type, n_param, c_param, h_param, w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax) + + m->num_q_heads * tokens_prev_requests_squares; + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(miopenSoftmaxForward_V2(m->handle.dnn, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax, + MIOPEN_SOFTMAX_ACCURATE, + MIOPEN_SOFTMAX_MODE_CHANNEL)); + // Matmul softmax(QK^T/sqrt(d_k)) by V + alpha = 1.0f, beta = 0.0f; + m_ = num_new_tokens; + n = m->vProjSize; + k = total_tokens; + lda = m_, ldb = n * m->num_q_heads, ldc = m_; + strideA = num_new_tokens * total_tokens; + strideB = vt_block_size; + strideC = num_new_tokens * m->vProjSize; + // To get A, skip over softmax(QK^T/sqrt(d_k)) entries from previous + // requests (all heads) + A = C_softmax; + // To get B, skip over V^T entries from previous requests (all heads + + // padding) + B = static_cast
(m->valueCache) + + (i * bc->MAX_BEAM_WIDTH + sub_req_id) * vt_req_block_size; + // To get C, skip over softmax(QK^T/sqrt(d_k))V products from previous + // requests + C = static_cast
(m->attn_heads) + + tokens_previous_requests * m->num_q_heads * m->vProjSize; + + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_N, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + // Project to output, save result directly on output tensor + alpha = 1.0f, beta = 0.0f; + m_ = m->oProjSize; + k = m->vProjSize * m->num_q_heads; + n = num_new_tokens; + lda = k, ldb = n, ldc = m_; + A = weight_ptr + m->qSize * (m->qProjSize * m->num_q_heads + + m->kProjSize * m->num_q_heads + + m->vProjSize * m->num_q_heads); + B = C; + C = static_cast
(output_ptr) + + tokens_previous_requests * m->oProjSize; + + checkCUDA(hipblasGemmEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + B, + hipblas_data_type, + ldb, + &beta, + C, + hipblas_data_type, + ldc, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + tokens_previous_requests += num_new_tokens; + tokens_prev_requests_squares += num_new_tokens * total_tokens; + } + } + if (*m->final_bias && shard_id == 0) { + int parallelism = m->oProjSize * num_tokens; + int qkv_weight_size = m->qProjSize * m->global_num_q_heads + + m->kProjSize * m->global_num_q_heads + + m->vProjSize * m->global_num_q_heads; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_proj_bias_w
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + bias_ptr, + num_tokens, + qkv_weight_size, + m->oProjSize); + } + + assert(tokens_previous_requests == num_tokens); +} + +template +void inference_kernel(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + hipStream_t stream) { + // here because we need postion info in infernece 1 + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + checkCUDA( + hipMemcpyAsync(m->token_infos, + &(bc->tokensInfo), + max_tokens_per_batch * sizeof(BatchConfig::PerTokenInfo), + hipMemcpyHostToDevice, + stream)); + checkCUDA(hipMemcpyAsync(m->request_infos, + &(bc->requestsInfo), + bc->max_requests_per_batch() * + sizeof(BatchConfig::PerRequestInfo), + hipMemcpyHostToDevice, + stream)); + checkCUDA( + hipMemcpyAsync(m->beam_token_infos, + &(bc->beamTokenInfo), + max_tokens_per_batch * bc->MAX_BEAM_WIDTH * + sizeof(BeamSearchBatchConfig::BeamSearchPerTokenInfo), + hipMemcpyHostToDevice, + stream)); + checkCUDA(hipMemcpyAsync( + m->beam_request_infos, + &(bc->beamRequestsInfo), + bc->max_requests_per_batch() * + sizeof(BeamSearchBatchConfig::BeamSearchPerRequestInfo), + hipMemcpyHostToDevice, + stream)); + // phase 1: Implement kernel to compute KQV for input tokens + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + // phase 2: Update key/val cache + update_kv_cache_kernel
(m, bc, stream); + + // phase 3: Compute attention score + // 3 kernels for pahse 3: matmul1 - softmax - matmal2 + compute_attention_kernel( + m, bc, shard_id, output_ptr, bias_ptr, weight_ptr, stream); +} + +} // namespace SpecIncMultiHeadAttention +} // namespace Kernels + +/*static*/ +void SpecIncMultiHeadSelfAttention::inference_kernel_wrapper( + SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::SpecIncMultiHeadAttention::inference_kernel(m, + bc, + shard_id, + input.get_half_ptr(), + weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::SpecIncMultiHeadAttention::inference_kernel(m, + bc, + shard_id, + input.get_float_ptr(), + weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("SpecIncMultiHeadSelfAttention forward time = %.2fms\n", elapsed); + } +} + +SpecIncMultiHeadSelfAttentionMeta::SpecIncMultiHeadSelfAttentionMeta( + FFHandler handler, + SpecIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + BEAM_SEARCH_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + DT_NONE, + false) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(miopenSetStream(handler.dnn, stream)); + + // allocate memory for the seqArray and reserve space + { + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + size_t beam_tokeninfo_size = + max_tokens_per_batch * BeamSearchBatchConfig::MAX_BEAM_WIDTH; + size_t requestinfo_size = BeamSearchBatchConfig::max_requests_per_batch(); + size_t beam_requestinfo_size = + BeamSearchBatchConfig::max_requests_per_batch(); + size_t total_size = + requestinfo_size * sizeof(BatchConfig::PerRequestInfo) + + beam_tokeninfo_size * + sizeof(BeamSearchBatchConfig::BeamSearchPerTokenInfo) + + beam_requestinfo_size * + sizeof(BeamSearchBatchConfig:: + BeamSearchPerRequestInfo); // more components will + // be added here later + + // We always directly allocate memory for small speculative models + gpu_mem_allocator.create_legion_instance(beam_search_reserve_inst, + total_size); + beam_token_infos = + gpu_mem_allocator + .allocate_instance( + beam_tokeninfo_size); + // offset += beam_tokeninfo_size * + // sizeof(BeamSearchBatchConfig::BeamSearchPerTokenInfo); + request_infos = + gpu_mem_allocator.allocate_instance( + requestinfo_size); + // offset += requestinfo_size * sizeof(BatchConfig::PerRequestInfo); + beam_request_infos = + gpu_mem_allocator + .allocate_instance( + beam_requestinfo_size); + // offset += beam_requestinfo_size * + // sizeof(BeamSearchBatchConfig::BeamSearchPerRequestInfo); + // assert(offset == total_size); + assert(gpu_mem_allocator.instance_total_size == + gpu_mem_allocator.instance_allocated_size); + } + + checkCUDA(hipStreamSynchronize(stream)); +} + +SpecIncMultiHeadSelfAttentionMeta::~SpecIncMultiHeadSelfAttentionMeta(void) { + if (beam_search_reserve_inst != Realm::RegionInstance::NO_INST) { + beam_search_reserve_inst.destroy(); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/spec_inc_multihead_self_attention.cu b/src/ops/spec_inc_multihead_self_attention.cu new file mode 100644 index 0000000000..a00ea9c95f --- /dev/null +++ b/src/ops/spec_inc_multihead_self_attention.cu @@ -0,0 +1,891 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "cuComplex.h" +#endif +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +#define WARP_SIZE 32 + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; +using namespace Kernels::IncMultiHeadAttention; + +namespace Kernels { +namespace SpecIncMultiHeadSelfAttention { + +template +__global__ void compute_spec_inc_attention_kernel_generation_kernel( + DT const *query, + DT const *key_cache, + DT const *value_cache, + DT *output_ptr, + float const scale, + int const max_seq_length, + int per_head_size, + int hidden_size, + BatchConfig::PerRequestInfo *request_infos, + BeamSearchBatchConfig::BeamSearchPerRequestInfo *beam_request_infos, + BatchConfig::BitMask *causalMask, + bool *request_completed) { + + // q, k + using Q_vec = typename VEC_K::Type; + using K_vec = typename VEC_K::Type; + using V_vec = typename VEC_V
::Type; + using Out_sum = typename Vec_fp32_::Type; + + constexpr int WARPS_PER_BLOCK = THREADS_PER_BLOCK / WARP_SIZE; + + constexpr int K_VEC_SIZE = sizeof(K_vec) / sizeof(DT); + constexpr int K_ELTS_PER_THREAD = Dh / THREADS_PER_KEY; + constexpr int K_VECS_PER_THREAD = K_ELTS_PER_THREAD / K_VEC_SIZE; + // constexpr int QK_ELTS_IN_16B = 16 / sizeof(DT); + + // thread id + int const tidx = threadIdx.x; + // head id + int const head_idx = blockIdx.x; + // nth request idx + int const request_idx = blockIdx.y; + + // request id in batch config + int const batch_config_request_id = + request_infos[request_idx].batch_config_request_id; + + // request_idx = re + + BatchConfig::BitMask bitmask = causalMask[batch_config_request_id]; + + int const first_step = 0; + + // int const tlength = + // request_infos[batch_config_request_id].first_token_depth_in_request + + // request_infos[batch_config_request_id].num_tokens_in_batch; + + int const totalCacheSize = + bitmask.non_tree_cache_size + bitmask.tree_size + bitmask.prompt_size - 1; + + int first_token_idx = 0; + for (int r = 0; r < batch_config_request_id; r++) { + first_token_idx += request_completed[r] ? 0 : causalMask[r].this_layer_size; + } + + int const tree_branch_num = + beam_request_infos[batch_config_request_id].sub_request_num; + + // shared memory objects + extern __shared__ char smem_[]; + + float *qk_smem = reinterpret_cast(smem_); + float *out_smem = reinterpret_cast(smem_); + + float qk_max = -FLT_MAX; + + // first WARPS_PER_BLOCK for store qk_max, second WARPS_PER_BLOCK for sum + __shared__ float red_smem[WARPS_PER_BLOCK * 2]; + + const DT *q_ptr = query + first_token_idx * hidden_size * QKV_WEIGHT_NUM + + head_idx * per_head_size; + __shared__ Q_vec q_vecs[THREADS_PER_KEY][K_VECS_PER_THREAD]; + + // the start offset of the element eg. (0, 1, 2, 3) * K_VEC_SIZE + int ki = tidx % THREADS_PER_KEY * K_VEC_SIZE; + int ki_o = tidx % THREADS_PER_KEY; + // the first key's offset for this thread + // ko = 0, 0, 0, 0, 1, 1, 1, 1, .... + int ko = tidx / THREADS_PER_KEY; + // load q tensor + Q_vec q_vec[K_VECS_PER_THREAD]; + + constexpr int K_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_KEY; + // The number of keys per warp. + constexpr int K_PER_WARP = WARP_SIZE / THREADS_PER_KEY; + + DT const *k_cache_batch = + key_cache + batch_config_request_id * max_seq_length * hidden_size + ki; + + int ti_end = + div_up(totalCacheSize - first_step, K_PER_WARP) * K_PER_WARP + first_step; + + for (int qi = 0; qi < tree_branch_num; qi += 1) { +#pragma unroll + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + q_vecs[ki_o][ii] = *reinterpret_cast( + q_ptr + (hidden_size * QKV_WEIGHT_NUM * qi) + ki + + ii * THREADS_PER_KEY * K_VEC_SIZE); + } + + int const query_token = + bitmask.prompt_size + bitmask.tree_size - 1 - tree_branch_num + qi; + + __syncthreads(); + for (int ti = ko; ti < ti_end; ti += K_PER_ITER) { + K_vec k[K_VECS_PER_THREAD]; + int const ti_circ = ti % max_seq_length; + + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + int jj = ii * THREADS_PER_KEY * K_VEC_SIZE; + if (ti < totalCacheSize) { + + k[ii] = *reinterpret_cast( + k_cache_batch + ti_circ * hidden_size + head_idx * per_head_size + + jj); + } + } + float qk = scale * Qk_dot::dot(q_vecs[ki_o], k); + + if (ti < totalCacheSize && tidx % THREADS_PER_KEY == 0) { + // todo add alobi here + // bool const mask = ti_circ >= totalCacheSize; + bool const mask = (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << query_token)))); + + // if (head_idx == 0 && ti == 0 && request_idx == 15 && !mask) { + // printf("spec inc attn qkqkqk request id %d, %.10f, %d\n", + // batch_config_request_id, + // ti, + // qk, + // qi); + // } + qk_max = mask ? qk_max : fmaxf(qk_max, qk); + qk_smem[ti - first_step] = mask ? 0.f : qk; + } + } + + __syncthreads(); + +#pragma unroll + for (int mask = WARP_SIZE / 2; mask >= THREADS_PER_KEY; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Decompose the thread index into warp and lane. + int const warp = tidx / WARP_SIZE; + int const lane = tidx % WARP_SIZE; + + // The warp leader writes the max to shared memory. + if (lane == 0) { + red_smem[warp] = qk_max; + } + + // Make sure the products are in shared memory. + __syncthreads(); + + // The warps finalize the reduction. + qk_max = lane < WARPS_PER_BLOCK ? red_smem[lane] : -FLT_MAX; +#pragma unroll + for (int mask = WARPS_PER_BLOCK / 2; mask >= 1; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Broadcast to all the threads in the warp. + qk_max = __shfl_sync(uint32_t(-1), qk_max, 0); + + // if (blockIdx.y == 0 && blockIdx.x == 0 && tidx == 0) { + // printf("spec inc attn first token qk_max %.10f\n", qk_max); + // } + + float exp_sum = 0.f; + for (int ti = first_step + tidx; ti < totalCacheSize; + ti += THREADS_PER_BLOCK) { + bool const mask = (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << query_token)))); + float logit = mask ? 0.0f : __expf(qk_smem[ti - first_step] - qk_max); + exp_sum += logit; + qk_smem[ti - first_step] = mask ? 0.0f : logit; + } + + // Compute the sum. + exp_sum = block_sum(&red_smem[WARPS_PER_BLOCK], exp_sum); + + // softmax + float inv_sum = __fdividef(1.f, exp_sum + 1.e-6); + for (int ti = first_step + tidx; ti < totalCacheSize; + ti += THREADS_PER_BLOCK) { + qk_smem[ti - first_step] *= inv_sum; + } + + __syncthreads(); + + // value projection + constexpr int V_VEC_SIZE = 16 / sizeof(DT); + // A vector of V elements for the current timestep. + // using V_vec_k = typename V_vec_k_::Type; + // using V_vec_acum = typename V_vec_acum_fp32_::Type; + + // The value computed by this thread. + int vo = tidx / THREADS_PER_VALUE; + // The hidden dimensions computed by this particular thread. + int vi = tidx % THREADS_PER_VALUE * V_VEC_SIZE; + constexpr int V_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_VALUE; + + Out_sum out; + zero(out); + + // The base pointer for the value in the cache buffer. + DT const *v_cache_batch = + value_cache + batch_config_request_id * max_seq_length * hidden_size + + vi; + + if (Dh == Dh_MAX || vi < Dh) { + for (int ti = first_step + vo; ti < totalCacheSize; ti += V_PER_ITER) { + // Load the values from the cache. + int const ti_circ = ti % max_seq_length; + V_vec v = *reinterpret_cast( + v_cache_batch + ti_circ * hidden_size + head_idx * per_head_size); + + bool const mask = (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << query_token)))); + float logit = mask ? 0.0f : qk_smem[ti - first_step]; + out = FlexFlow::fma(logit, cast_to_float(v), out); + } + } + + // // Make sure we can start writing to shared memory. + __syncthreads(); + + // Run the final reduction amongst the different groups computing different + // partial outputs. + if (Dh == Dh_MAX || vi < Dh) { +#pragma unroll + for (int active_groups = V_PER_ITER; active_groups >= 2; + active_groups /= 2) { + + // The midpoint in the number of active groups. + int midpoint = active_groups / 2; + + // The upper part of active threads store to shared memory. + if (vo >= midpoint && vo < active_groups && (Dh == Dh_MAX || vi < Dh)) { + *reinterpret_cast(out_smem + (vo - midpoint) * Dh + vi) = + out; + } + __syncthreads(); + + // The bottom warps update their values. + if (vo < midpoint && (Dh == Dh_MAX || vi < Dh)) { + out = add(*reinterpret_cast(out_smem + vo * Dh + vi), + out); + } + __syncthreads(); + } + } + + // Output the final values. + if (vo == 0 && (Dh == Dh_MAX || vi < Dh)) { + convert_from_float(*reinterpret_cast( + output_ptr + (first_token_idx + qi) * hidden_size + + head_idx * per_head_size + vi), + out); + } + } +} + +template +__global__ void spec_inc_store_kv_cache( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + BatchConfig::PerTokenInfo *tokenInfos, + BatchConfig::PerRequestInfo *requestInfo, + BeamSearchBatchConfig::BeamSearchPerTokenInfo *beamTokenInfos, + BeamSearchBatchConfig::BeamSearchPerRequestInfo *beamRequestInfos, + BatchConfig::BitMask *causalMask, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens, + int max_seq_len, + bool is_root, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens * hidden_size) { + int token_idx = i / (hidden_size); + int offset = i % hidden_size; + + size_t val_idx = + token_idx * QKV_WEIGHT_NUM * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = tokenInfos[token_idx].request_index; + // int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + + int const request_token_offset = + requestInfo[req_id].first_token_offset_in_batch; + + BatchConfig::BitMask bitmask = causalMask[req_id]; + + // if prompt token -> token id + // if tree token: + + int const cache_idx = bitmask.prompt_size + bitmask.non_tree_cache_size + + bitmask.tree_size - 1 - bitmask.this_layer_size + + token_idx - request_token_offset; + + kCache_ptr[req_id * (hidden_size * max_seq_len) + (cache_idx)*hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + (cache_idx)*hidden_size + + offset] = vVal; + } +} + +template +void update_kv_cache_kernel(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + cudaStream_t stream) { + int num_tokens = bc->num_active_tokens(); + int curr_depth = bc->beamRequestsInfo[0].current_depth; + if (num_tokens > 0) { + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_tokens; + spec_inc_store_kv_cache<<>>( + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + m->request_infos, + m->beam_token_infos, + m->beam_request_infos, + m->causalMask, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_tokens, + BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num(), + /*root*/ curr_depth == 0, + m->hidden_size); + } +} + +#define LAUNCH_SPEC_INC_ATTENTION_SCORE_KERNEL( \ + DT, Dh, Dh_MAX, THDS_PER_KEY, THREADS_PER_VALUE, THDS_PER_BLOCK, stream) \ + smem_sz = smem_size_in_bytes
(m->qProjSize, \ + BatchConfig::max_sequence_length() + \ + BatchConfig::max_spec_tree_token_num(), \ + THREADS_PER_VALUE, \ + THDS_PER_BLOCK); \ + compute_spec_inc_attention_kernel_generation_kernel \ + <<>>( \ + static_cast
(m->devQKVProjArray), \ + static_cast
(m->keyCache), \ + static_cast
(m->valueCache), \ + output_ptr, \ + scale, \ + BatchConfig::max_sequence_length() + \ + BatchConfig::max_spec_tree_token_num(), \ + m->qProjSize, \ + m->hidden_size, \ + m->request_infos, \ + m->beam_request_infos, \ + m->causalMask, \ + m->request_completed) + +template +void compute_spec_inc_attention_kernel_generation( + SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + DT *output_ptr, + cudaStream_t stream) { + // one block == one head per request + // how many generation requests + dim3 grid(m->num_q_heads, bc->get_speculative_request_num()); + int const per_head_size = m->qProjSize; + float scale = (*m->qk_prod_scaling) ? 1.0f / sqrt(m->kProjSize) : 1.0f; + size_t smem_sz; + if (per_head_size == 64) { + constexpr int THREADS_PER_VALUE_64 = threads_per_value_t::value; + LAUNCH_SPEC_INC_ATTENTION_SCORE_KERNEL( + DT, 64, 64, 4, THREADS_PER_VALUE_64, 128, stream); + } else if (per_head_size == 128) { + constexpr int THREADS_PER_VALUE_128 = threads_per_value_t::value; + LAUNCH_SPEC_INC_ATTENTION_SCORE_KERNEL( + DT, 128, 128, 4, THREADS_PER_VALUE_128, 128, stream); + } else { + assert(false && "a unsupported head size"); + } +} + +template +__global__ void spec_fill_entries_above_diagonal(DT *matrix, + size_t new_tokens, + size_t total_tokens_in_request, + size_t num_q_heads, + DT value) { + CUDA_KERNEL_LOOP(i, new_tokens * total_tokens_in_request * num_q_heads) { + // size_t head_idx = i / (new_tokens * total_tokens_in_request); + size_t src_idx = (i / new_tokens) % total_tokens_in_request; + size_t dst_idx = i % new_tokens + total_tokens_in_request - new_tokens; + // Casual Mask + if (src_idx > dst_idx) { + matrix[i] = value; + } + } +} + +template +void compute_attention_kernel_prompt(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *bias_ptr, + DT const *weight_ptr, + cudaStream_t stream) { + checkCUDA(cublasSetStream(m->handle.blas, stream)); + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + cudaDataType_t cublas_data_type = ff_to_cuda_datatype(m->output_type[0]); + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; +#else + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } +#endif + // int num_requests = bc->num_active_requests(); + int num_tokens = bc->num_active_tokens(); + int tokens_previous_requests = 0; + int tokens_prev_requests_squares = 0; + // int qkv_block_size = + // (m->qProjSize + m->kProjSize + m->vProjSize) * num_tokens; + int q_block_size = m->qProjSize; + + int kt_block_size = m->kProjSize; + int kt_req_block_size = kt_block_size * m->num_q_heads * + (BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num()); + int vt_block_size = m->vProjSize; + int vt_req_block_size = vt_block_size * m->num_q_heads * + (BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num()); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i] || (!bc->requestsInfo[i].prompt_phase) || + (bc->requestsInfo[i].num_tokens_in_batch == 0)) { + continue; + } else if (tokens_previous_requests < bc->num_generation_tokens) { + tokens_previous_requests += bc->requestsInfo[i].num_tokens_in_batch; + continue; + } + + // all requests in prompt phase should only have one sub requests; + assert(bc->sub_requests[i] == 1); + // int num_new_tokens = bc->num_processing_tokens[i]; + // int total_tokens = bc->token_last_available_idx[i] + 1; + + int num_new_tokens = bc->requestsInfo[i].num_tokens_in_batch; + int total_tokens = bc->requestsInfo[i].first_token_depth_in_request + + bc->requestsInfo[i].num_tokens_in_batch; + + if (num_new_tokens <= 0) { + continue; + } + + // Compute (QK^T/sqrt(d_k)) + int m_ = num_new_tokens; + int n = total_tokens; + int k = m->qProjSize; + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens; + + // a flag of using this scaling alpha + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // To get A, skip over Q entries from previous requests (same head) + DT const *A = static_cast
(m->devQKVProjArray) + + bc->requestsInfo[i].first_token_offset_in_batch * + m->qProjSize * m->num_q_heads * QKV_WEIGHT_NUM; + // To get B, skip over K entries from previous requests (all heads + + // padding) + + // print_tensor((float*)A, 32, "A"); + DT const *B = static_cast
(m->keyCache) + i * kt_req_block_size; + + // if (i == 0 && sub_req_id == 0 && + // bc->beam_slots.at(0).current_depth == 1) { + // int offset = (float *)B - m->keyCache; + // printf("key cache offset %d\n", kt_req_block_size); + // } + // To get C, skip over QK^T products from previous requests + DT *C = static_cast
(m->qk_prods) + + m->num_q_heads * tokens_prev_requests_squares; + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + // print_tensor((float*)C, 32, "C"); + // add alibi position bias to qk production + // add alibi position bias to qk production + if (*m->position_bias) { + size_t parallelism = m->num_q_heads * total_tokens * num_new_tokens; + apply_position_bias_qkprd<<>>(C, + num_new_tokens, + total_tokens, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + // Fill all elements above diagonal in qk prods with -inf to force + // causal attention. + assert(num_new_tokens <= total_tokens); + if (num_new_tokens > 1) { + size_t parallelism = m->num_q_heads * num_new_tokens * total_tokens; + spec_fill_entries_above_diagonal<<>>(C, + num_new_tokens, + total_tokens, + m->num_q_heads, + static_cast
(-INFINITY)); + } + // Compute Softmax(QK^T/sqrt(d_k)) + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(cudnnSetTensor4dDescriptor(m->qk_tensor, + CUDNN_TENSOR_NCHW, + cudnn_data_type, + n_param, + c_param, + h_param, + w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax) + + m->num_q_heads * tokens_prev_requests_squares; + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(cudnnSoftmaxForward(m->handle.dnn, + CUDNN_SOFTMAX_ACCURATE, + CUDNN_SOFTMAX_MODE_CHANNEL, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax)); + // Matmul softmax(QK^T/sqrt(d_k)) by V + alpha = 1.0f, beta = 0.0f; + m_ = m->vProjSize; + n = num_new_tokens; + k = total_tokens; + lda = m_ * m->num_q_heads, ldb = n, ldc = m_ * m->num_q_heads; + strideA = vt_block_size; + strideB = num_new_tokens * total_tokens; + strideC = m->vProjSize; + // To get A, skip over V^T entries from previous requests (all heads + + // padding) + A = static_cast
(m->valueCache) + i * vt_req_block_size; + // To get B, skip over softmax(QK^T/sqrt(d_k)) entries from previous + // requests (all heads) + B = C_softmax; + // To get C, skip over softmax(QK^T/sqrt(d_k))V products from previous + // requests + + int token_offset = bc->requestsInfo[i].first_token_offset_in_batch; + + C = static_cast
(m->attn_heads) + + (token_offset)*m->num_q_heads * m->vProjSize; + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_N, + CUBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + + tokens_previous_requests += num_new_tokens; + tokens_prev_requests_squares += num_new_tokens * total_tokens; + } + + if (tokens_previous_requests != (num_tokens - bc->num_generation_tokens)) { + bc->print(); + printf("tokens_previous_requests: %i\n", tokens_previous_requests); + printf("num_tokens: %i\n", num_tokens); + printf("bc->num_generation_tokens: %i\n", bc->num_generation_tokens); + } + assert(tokens_previous_requests == (num_tokens - bc->num_generation_tokens)); +} + +template +void inference_kernel(SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + cudaStream_t stream) { + // phase 1: Implement kernel to compute KQV for input tokens + + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + // phase 2: Update key/val cache + update_kv_cache_kernel
(m, bc, stream); + if (bc->num_generation_tokens > 0) { + compute_spec_inc_attention_kernel_generation
( + m, bc, static_cast
(m->attn_heads), stream); + } + // phase 3: Compute attention score + // 3 kernels for pahse 3: matmul1 - softmax - matmal2 + if (bc->num_tokens > bc->num_generation_tokens) { + compute_attention_kernel_prompt( + m, bc, shard_id, output_ptr, bias_ptr, weight_ptr, stream); + } + // compute output production and bias together for all tokens + int num_tokens = bc->num_active_tokens(); + + compute_o_prod_bias( + m, bc, shard_id, output_ptr, weight_ptr, bias_ptr, num_tokens, stream); +} + +} // namespace SpecIncMultiHeadSelfAttention +} // namespace Kernels + +/*static*/ +void SpecIncMultiHeadSelfAttention::inference_kernel_wrapper( + SpecIncMultiHeadSelfAttentionMeta const *m, + BeamSearchBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::SpecIncMultiHeadSelfAttention::inference_kernel( + m, + bc, + shard_id, + input.get_half_ptr(), + weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::SpecIncMultiHeadSelfAttention::inference_kernel( + m, + bc, + shard_id, + input.get_float_ptr(), + weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + printf("SpecIncMultiHeadSelfAttention forward time = %.2fms\n", elapsed); + // print_tensor<3, float>(acc_query.ptr, acc_query.rect, + // "[Attention:forward:query]"); print_tensor<3, float>(acc_output.ptr, + // acc_output.rect, "[Attention:forward:output]"); + } +} + +SpecIncMultiHeadSelfAttentionMeta::SpecIncMultiHeadSelfAttentionMeta( + FFHandler handler, + SpecIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + BEAM_SEARCH_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + DT_NONE, + false) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(cudnnSetStream(handler.dnn, stream)); + + // allocate memory for the seqArray and reserve space + { + beam_token_infos = + reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + + sizeof(BatchConfig::requestsInfo)); + + beam_request_infos = + reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + + sizeof(BatchConfig::requestsInfo) + + sizeof(BeamSearchBatchConfig::beamTokenInfo)); + causalMask = reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + sizeof(BatchConfig::requestsInfo) + + sizeof(BeamSearchBatchConfig::beamTokenInfo) + + sizeof(BeamSearchBatchConfig::beamRequestsInfo)); + + request_completed = reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + sizeof(BatchConfig::requestsInfo) + + sizeof(BeamSearchBatchConfig::beamTokenInfo) + + sizeof(BeamSearchBatchConfig::beamRequestsInfo) + + sizeof(BatchConfig::causalMask)); + } + + cudaStreamSynchronize(stream); +} + +SpecIncMultiHeadSelfAttentionMeta::~SpecIncMultiHeadSelfAttentionMeta(void) { + if (beam_search_reserve_inst != Realm::RegionInstance::NO_INST) { + beam_search_reserve_inst.destroy(); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/split.cc b/src/ops/split.cc index 3517852942..e3745f834f 100644 --- a/src/ops/split.cc +++ b/src/ops/split.cc @@ -50,6 +50,9 @@ SplitParams Split::get_params() const { SplitParams params; params.splits = this->splits; params.legion_axis = this->legion_axis; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -137,7 +140,7 @@ Split::Split(FFModel &model, SplitParams const ¶ms, const ParallelTensor input, char const *name) - : Split(model, input, params.splits, params.legion_axis, name) {} + : Split(model, input, params.splits, params.legion_axis, params.name) {} void Split::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -170,6 +173,47 @@ void Split::init(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +void Split::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + + IndexLauncher launcher(SPLIT_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Split)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + for (int i = 0; i < numOutputs; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[i]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[i]->region)); + launcher.add_field(i + 1, FID_DATA); + } + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + OpMeta *Split::init_task(Task const *task, std::vector const ®ions, Context ctx, @@ -205,6 +249,45 @@ void Split::forward(FFModel const &ff) { } runtime->execute_index_space(ctx, launcher); } +FutureMap Split::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + + IndexLauncher launcher(SPLIT_FWD_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Split)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + for (int i = 0; i < numOutputs; i++) { + launcher.add_region_requirement( + RegionRequirement(batch_outputs[i]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[i]->region)); + launcher.add_field(i + 1, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} void calc_block_size(coord_t &num_blks, coord_t &blk_size, diff --git a/src/ops/topk.cc b/src/ops/topk.cc index 1a87c6c80c..7d30a8aff3 100644 --- a/src/ops/topk.cc +++ b/src/ops/topk.cc @@ -87,6 +87,9 @@ TopKParams TopK::get_params() const { TopKParams params; params.k = this->k; params.sorted = this->sorted; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -134,7 +137,50 @@ TopK::TopK(FFModel &model, TopKParams const ¶ms, const ParallelTensor input, char const *name) - : TopK(model, input, params.k, params.sorted, name) {} + : TopK(model, input, params.k, params.sorted, params.name) {} + +void TopK::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(TOPK_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(TopK)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} void TopK::init(FFModel const &ff) { assert(check_output_input_weight_same_parallel_is()); @@ -182,7 +228,10 @@ OpMeta *TopK::init_task(Task const *task, FFHandler handle = *((FFHandler *)task->local_args); TopKMeta *m = new TopKMeta(handle); m->profiling = topk->profiling; + m->inference_debugging = topk->inference_debugging; m->sorted = topk->sorted; + std::strcpy(m->op_name, topk->name); + m->layer_guid = topk->layer_guid; return m; } @@ -220,6 +269,49 @@ void TopK::forward(FFModel const &ff) { runtime->execute_index_space(ctx, launcher); } +FutureMap TopK::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + /* std::cout << "TopK op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(TOPK_FWD_TASK_ID, + parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[1]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[1]->region)); + launcher.add_field(2, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void TopK::forward_task(Task const *task, std::vector const ®ions, Context ctx, @@ -337,6 +429,8 @@ void TopK::backward_task(Task const *task, void TopK::serialize(Legion::Serializer &sez) const { sez.serialize(this->k); sez.serialize(this->sorted); + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } Node TopK::deserialize(FFModel &ff, @@ -348,9 +442,14 @@ Node TopK::deserialize(FFModel &ff, bool sorted; dez.deserialize(k); dez.deserialize(sorted); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); TopKParams params; params.k = k; params.sorted = sorted; + strcpy(params.name, name); return ff.get_or_create_node(inputs[0], params); } diff --git a/src/ops/topk.cpp b/src/ops/topk.cpp index 4bb32192ef..b6e898b654 100644 --- a/src/ops/topk.cpp +++ b/src/ops/topk.cpp @@ -421,9 +421,9 @@ void TopK::forward_kernel_wrapper(TopKMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } TopK::forward_kernel(m, @@ -437,12 +437,12 @@ void TopK::forward_kernel_wrapper(TopKMeta const *m, stream); if (m->profiling) { - hipEventRecord(t_end, stream); + checkCUDA(hipEventRecord(t_end, stream)); checkCUDA(hipEventSynchronize(t_end)); float elapsed = 0; checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); - hipEventDestroy(t_start); - hipEventDestroy(t_end); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); } } @@ -496,9 +496,9 @@ void TopK::backward_kernel_wrapper(TopKMeta const *m, hipEvent_t t_start, t_end; if (m->profiling) { - hipEventCreate(&t_start); - hipEventCreate(&t_end); - hipEventRecord(t_start, stream); + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); } TopK::backward_kernel(m, diff --git a/src/ops/transpose.cc b/src/ops/transpose.cc index 303948964b..7a179c4f7d 100644 --- a/src/ops/transpose.cc +++ b/src/ops/transpose.cc @@ -51,6 +51,9 @@ TransposeParams Transpose::get_params() const { for (int i = 0; i < outputs[0]->num_dims; i++) { params.perm.push_back(this->perm[i]); } + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -98,7 +101,7 @@ Transpose::Transpose(FFModel &model, TransposeParams const ¶ms, const ParallelTensor input, char const *name) - : Transpose(model, input, params.perm, name) {} + : Transpose(model, input, params.perm, params.name) {} Transpose::Transpose(FFModel &model, const ParallelTensor input, @@ -193,6 +196,9 @@ OpMeta *Transpose::init_task(Task const *task, TransposeMeta *m = new TransposeMeta(handle); transpose->init_meta(m, in_domain, out_domain); m->profiling = transpose->profiling; + m->inference_debugging = transpose->inference_debugging; + std::strcpy(m->op_name, transpose->name); + m->layer_guid = transpose->layer_guid; return m; } @@ -380,6 +386,8 @@ void Transpose::serialize(Legion::Serializer &sez) const { for (size_t i = 0; i < params.perm.size(); i++) { sez.serialize(params.perm[i]); } + sez.serialize(strlen(this->name)); + sez.serialize(this->name, strlen(this->name)); } using PCG::Node; @@ -396,6 +404,10 @@ Node Transpose::deserialize(FFModel &ff, dez.deserialize(dim_idx); perm.push_back(dim_idx); } + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); return ff.get_or_create_node(inputs[0], {perm}); } diff --git a/src/ops/tree_inc_multihead_self_attention.cc b/src/ops/tree_inc_multihead_self_attention.cc new file mode 100644 index 0000000000..d0efb01d54 --- /dev/null +++ b/src/ops/tree_inc_multihead_self_attention.cc @@ -0,0 +1,962 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/model.h" +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif +#include "flexflow/utils/hash_utils.h" +#include "legion/legion_utilities.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::ArgumentMap; +using Legion::Context; +using Legion::coord_t; +using Legion::Domain; +using Legion::Future; +using Legion::FutureMap; +using Legion::IndexLauncher; +using Legion::Machine; +using Legion::Memory; +using Legion::PhysicalRegion; +using Legion::Predicate; +using Legion::Rect; +using Legion::RegionRequirement; +using Legion::Runtime; +using Legion::Task; +using Legion::TaskArgument; +using Legion::TaskLauncher; +using PCG::Node; + +LegionRuntime::Logger::Category log_tree_verify("TreeVerifyIncMHA"); + +bool TreeIncMultiHeadSelfAttentionParams::is_valid( + ParallelTensorShape const &input) const { + bool is_valid = input.is_valid(); + return is_valid; +} + +Tensor FFModel::inc_multihead_self_attention_verify( + const Tensor input, + int embed_dim, + int num_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + return inc_multiquery_self_attention_verify(input, + embed_dim, + num_heads, + num_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + data_type, + kernel_initializer, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + name); +} + +Tensor FFModel::inc_multiquery_self_attention_verify( + const Tensor input, + int embed_dim, + int num_q_heads, + int num_kv_heads, + int kdim, + int vdim, + float dropout, + bool qkv_bias, + bool final_bias, + bool add_zero_attn, + DataType data_type, + Initializer *kernel_initializer, + bool apply_rotary_embedding, + bool scaling_query, + float scaling_factor, + bool qk_prod_scaling, + bool position_bias, + char const *name) { + if (data_type == DT_NONE) { + data_type = input->data_type; + } + DataType quantization_type = cpu_offload ? config.quantization_type : DT_NONE; + bool offload = cpu_offload; + Layer *li = nullptr; + int weight_num = (qkv_bias || final_bias) ? 2 : 1; + if (data_type != input->data_type) { + Tensor casted_input = cast(input, data_type, "type cast for IncMHA"); + li = new Layer(this, + OP_TREE_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + casted_input); + } else { + li = new Layer(this, + OP_TREE_INC_MULTIHEAD_SELF_ATTENTION, + data_type, + name, + 1 /*inputs*/, + weight_num /*weights*/, + 1 /*outputs*/, + input); + } + { + int numdims = input->num_dims; + int dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdims; i++) { + dims[i] = input->dims[i]; + } + dims[0] = embed_dim; + li->outputs[0] = create_tensor_legion_ordering( + numdims, dims, data_type, li, 0, true /*create_grad*/); + } + // Compute weight size + int qProjSize = kdim, kProjSize = kdim, vProjSize = kdim, + oProjSize = embed_dim; + int qSize = input->dims[0], kSize = input->dims[0], vSize = input->dims[0]; + int qParas = qProjSize * qSize; + int kParas = kProjSize * kSize; + int vParas = vProjSize * vSize; + int oParas = oProjSize * (vProjSize > 0 ? vProjSize : vSize); + int one_head_size = qParas + kParas + vParas + oParas; + int weight_size = qParas * num_q_heads + kParas * num_q_heads + + vParas * num_q_heads + oParas * num_q_heads; + { + // compress the weight size if quantization. + if (quantization_type != DT_NONE) { + one_head_size = get_quantization_to_byte_size( + data_type, quantization_type, one_head_size); + } + + int dims[1] = {weight_size}; + li->weights[0] = create_weight_legion_ordering( + 1, + dims, + quantization_type == DT_NONE ? data_type : quantization_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + if (qkv_bias || final_bias) { + // q, k, v, o + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + int dims[1] = {(qkv_bias ? qkv_bias_size : 0) + + (final_bias ? oProjSize : 0)}; + li->weights[1] = create_weight_legion_ordering(1, + dims, + data_type, + li, + true /*create_grad*/, + kernel_initializer, + CHOSEN_SYNC_TYPE); + } + li->data_type = data_type; + li->add_int_property("embed_dim", embed_dim); + li->add_int_property("num_q_heads", num_q_heads); + li->add_int_property("num_kv_heads", num_kv_heads); + li->add_int_property("kdim", kdim); + li->add_int_property("vdim", vdim); + li->add_int_property("qkv_bias", qkv_bias); + li->add_int_property("final_bias", final_bias); + li->add_int_property("add_zero_attn", add_zero_attn); + li->add_float_property("dropout", dropout); + li->add_int_property("apply_rotary_embedding", apply_rotary_embedding); + li->add_int_property("scaling_query", scaling_query); + li->add_float_property("scaling_factor", scaling_factor); + li->add_int_property("qk_prod_scaling", qk_prod_scaling); + li->add_int_property("position_bias", position_bias); + li->add_int_property("quantization_type", quantization_type); + li->add_int_property("offload", offload); + li->add_int_property("tensor_parallelism_degree", + config.tensor_parallelism_degree); + layers.push_back(li); + return li->outputs[0]; +} + +Op *TreeIncMultiHeadSelfAttention::create_operator_from_layer( + FFModel &model, + Layer const *layer, + std::vector const &inputs) { + long long value; + layer->get_int_property("embed_dim", value); + int embed_dim = value; + layer->get_int_property("num_q_heads", value); + int num_q_heads = value; + layer->get_int_property("num_kv_heads", value); + int num_kv_heads = value; + layer->get_int_property("kdim", value); + int kdim = value; + layer->get_int_property("vdim", value); + int vdim = value; + float dropout; + layer->get_float_property("dropout", dropout); + layer->get_int_property("qkv_bias", value); + bool qkv_bias = (bool)value; + layer->get_int_property("final_bias", value); + bool final_bias = (bool)value; + layer->get_int_property("add_zero_attn", value); + bool add_zero_attn = (bool)value; + layer->get_int_property("apply_rotary_embedding", value); + bool apply_rotary_embedding = (bool)value; + layer->get_int_property("scaling_query", value); + bool scaling_query = (bool)value; + float scaling_factor; + layer->get_float_property("scaling_factor", scaling_factor); + layer->get_int_property("qk_prod_scaling", value); + bool qk_prod_scaling = (bool)value; + layer->get_int_property("position_bias", value); + bool position_bias = (bool)value; + layer->get_int_property("quantization_type", value); + DataType quantization_type = (DataType)value; + layer->get_int_property("offload", value); + bool offload = (bool)value; + layer->get_int_property("tensor_parallelism_degree", value); + int tensor_parallelism_degree = (int)value; + return new TreeIncMultiHeadSelfAttention(model, + layer->layer_guid, + inputs[0], + embed_dim, + num_q_heads, + num_kv_heads, + kdim, + vdim, + dropout, + qkv_bias, + final_bias, + add_zero_attn, + apply_rotary_embedding, + scaling_query, + scaling_factor, + qk_prod_scaling, + position_bias, + false /*allocate_weights*/, + quantization_type, + offload, + tensor_parallelism_degree, + layer->name); +} + +TreeIncMultiHeadSelfAttention::TreeIncMultiHeadSelfAttention( + FFModel &model, + LayerID const &_layer_guid, + const ParallelTensor _input, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_TREE_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1) /*weights*/, + 1 /*outputs*/, + _input), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias), + quantization_type(_quantization_type), offload(_offload), + tensor_parallelism_degree(_tensor_parallelism_degree) { + // overwrite layer_guid + layer_guid = _layer_guid; + + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + // dims[2].size = qParas + kParas + vParas + oParas; + if (quantization_type != DT_NONE) { + dims[1].size = get_quantization_to_byte_size( + data_type, quantization_type, dims[1].size); + } + // dims[2].degree = 1; + // dims[2].parallel_idx = -1; + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>( + dims, + quantization_type == DT_NONE ? this->data_type : quantization_type, + NULL /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* // Check correctness */ + /* assert(check_output_input_weight_parallel_dims()); */ +} + +TreeIncMultiHeadSelfAttention::TreeIncMultiHeadSelfAttention( + FFModel &model, + const ParallelTensor _input, + const ParallelTensor _weight, + int _embed_dim, + int _num_q_heads, + int _num_kv_heads, + int _kdim, + int _vdim, + float _dropout, + bool _qkv_bias, + bool _final_bias, + bool _add_zero_attn, + bool _apply_rotary_embedding, + bool _scaling_query, + float _scaling_factor, + bool _qk_prod_scaling, + bool _position_bias, + bool allocate_weights, + DataType _quantization_type, + bool _offload, + int _tensor_parallelism_degree, + char const *name) + // Initializer* _bias_initializer) + : Op(model, + OP_TREE_INC_MULTIHEAD_SELF_ATTENTION, + _input->data_type, + name, + 1 /*inputs*/, + (_qkv_bias || _final_bias ? 2 : 1) /*weights*/, + 1 /*outputs*/, + _input, + _weight), + num_q_heads(_num_q_heads), num_kv_heads(_num_kv_heads), dropout(_dropout), + qkv_bias(_qkv_bias), final_bias(_final_bias), + add_zero_attn(_add_zero_attn), + apply_rotary_embedding(_apply_rotary_embedding), + qSize(_input->dims[0].size), kSize(_input->dims[0].size), + vSize(_input->dims[0].size), qProjSize(_kdim), kProjSize(_kdim), + vProjSize(_vdim), oProjSize(_embed_dim), + qoSeqLength(_input->dims[1].size), kvSeqLength(_input->dims[1].size), + scaling_query(_scaling_query), scaling_factor(_scaling_factor), + qk_prod_scaling(_qk_prod_scaling), position_bias(_position_bias), + quantization_type(_quantization_type), offload(_offload), + tensor_parallelism_degree(_tensor_parallelism_degree) +// bias_initializer(_bias_initializer) +{ + numOutputs = 1; + int numdim = _input->num_dims; + ParallelDim dims[MAX_TENSOR_DIM]; + for (int i = 0; i < numdim; i++) { + dims[i] = _input->dims[i]; + } + dims[0].size = _embed_dim; + // Currently require no parallelism along this dim + assert(dims[0].degree == 1); + if (allocate_weights) { + // Create weight tensor + int num_dims = inputs[0]->num_dims; + // Compute weight size + int qParas = this->qProjSize * this->qSize; + int kParas = this->kProjSize * this->kSize; + int vParas = this->vProjSize * this->vSize; + int oParas = + this->oProjSize * (this->vProjSize > 0 ? this->vProjSize : this->vSize); + ParallelDim dims[2]; + dims[0] = inputs[0]->dims[num_dims - 2]; + dims[0].size = dims[0].degree; + dims[1] = inputs[0]->dims[num_dims - 1]; + dims[1].size = this->num_q_heads * (qParas + oParas) + + this->num_q_heads * (kParas + vParas); + dims[1].is_replica_dim = false; + // dims[2].size = qParas + kParas + vParas + oParas; + if (quantization_type != DT_NONE) { + dims[1].size = get_quantization_to_byte_size( + data_type, quantization_type, dims[1].size); + } + int seed = std::rand(); + Initializer *initializer = new GlorotUniform(seed); + weights[0] = model.create_parallel_weight<2>( + dims, + quantization_type == DT_NONE ? this->data_type : quantization_type, + NULL /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + if (qkv_bias || final_bias) { + ParallelTensorShape bias_shape = _input->get_shape(); + int qkv_bias_size = + qProjSize * num_q_heads + (kProjSize + vProjSize) * num_q_heads; + bias_shape.dims[0].size = + (qkv_bias ? qkv_bias_size : 0) + (final_bias ? oProjSize : 0); + bias_shape.dims[1].size = bias_shape.dims[2].size = 1; + weights[1] = + model.create_parallel_weight_legion_ordering(bias_shape.num_dims, + bias_shape.dims, + this->data_type, + nullptr /*owner_op*/, + true /*create_grad*/, + initializer, + CHOSEN_SYNC_TYPE); + } + } + + outputs[0] = model.create_parallel_tensor_legion_ordering( + _input->num_dims, dims, this->data_type, this); + + /* for (int i = 0; i < numdim; i++) { */ + /* register_output_input_parallel_dims(outputs[0], i, inputs[0], i); */ + /* } */ + /* register_output_weight_parallel_dims(outputs[0], numdim-1, _weight, 1); */ + /* register_output_weight_parallel_dims(outputs[0], numdim-2, _weight, 2); */ + // Check correctness + /* assert(check_output_input_weight_parallel_dims()); */ +} + +TreeIncMultiHeadSelfAttention::TreeIncMultiHeadSelfAttention( + FFModel &model, + TreeIncMultiHeadSelfAttention const &other, + const ParallelTensor input, + bool allocate_weights) + : TreeIncMultiHeadSelfAttention(model, + other.layer_guid, + input, + other.oProjSize, + other.num_q_heads, + other.num_kv_heads, + other.qProjSize, + other.vProjSize, + other.dropout, + other.qkv_bias, + other.final_bias, + other.add_zero_attn, + other.apply_rotary_embedding, + other.scaling_query, + other.scaling_factor, + other.qk_prod_scaling, + other.position_bias, + allocate_weights, + other.quantization_type, + other.offload, + other.tensor_parallelism_degree, + other.name) {} + +TreeIncMultiHeadSelfAttention::TreeIncMultiHeadSelfAttention( + FFModel &model, + TreeIncMultiHeadSelfAttentionParams const ¶ms, + ParallelTensor const &input, + bool allocate_weights, + char const *name) + : TreeIncMultiHeadSelfAttention(model, + params.layer_guid, + input, + params.embed_dim, + params.num_q_heads, + params.num_kv_heads, + params.kdim, + params.vdim, + params.dropout, + params.qkv_bias, + params.final_bias, + params.add_zero_attn, + params.apply_rotary_embedding, + params.scaling_query, + params.scaling_factor, + params.qk_prod_scaling, + params.position_bias, + allocate_weights, + params.quantization_type, + params.offload, + params.tensor_parallelism_degree, + params.name) {} + +void TreeIncMultiHeadSelfAttention::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + size_t machine_view_hash = view->hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher( + TREE_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(TreeIncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +void TreeIncMultiHeadSelfAttention::init(FFModel const &ff) { + assert(check_output_input_weight_same_parallel_is()); + parallel_is = outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher( + TREE_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(TreeIncMultiHeadSelfAttention)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement(inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region)); + launcher.add_field(1, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(2, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +/* + regions[0](I): input + regions[1](I): weight + regions[2](O): output +*/ +OpMeta *TreeIncMultiHeadSelfAttention::init_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + TreeIncMultiHeadSelfAttention const *attn = + (TreeIncMultiHeadSelfAttention *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + + GenericTensorAccessorR input = + helperGetGenericTensorAccessorRO(attn->inputs[0]->data_type, + regions[0], + task->regions[0], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorR weight = + helperGetGenericTensorAccessorRO(attn->weights[0]->data_type, + regions[1], + task->regions[1], + FID_DATA, + ctx, + runtime); + GenericTensorAccessorW output = + helperGetGenericTensorAccessorWO(attn->outputs[0]->data_type, + regions[2], + task->regions[2], + FID_DATA, + ctx, + runtime); + + int num_samples = input.domain.hi()[2] - input.domain.lo()[2] + 1; + assert(attn->qoSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + assert(attn->kvSeqLength == input.domain.hi()[1] - input.domain.lo()[1] + 1); + // int num_q_heads = weight.domain.hi()[1] - weight.domain.lo()[1] + 1; + int num_q_heads = attn->num_q_heads / attn->tensor_parallelism_degree; + int num_kv_heads = + attn->num_kv_heads / attn->tensor_parallelism_degree + + (attn->num_kv_heads % attn->tensor_parallelism_degree != 0); + + assert(attn->oProjSize == output.domain.hi()[0] - output.domain.lo()[0] + 1); + + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + MemoryAllocator gpu_mem_allocator(gpu_mem); + if (attn->offload) { + // cpu-offload enabled + // use offload_reserved_space + gpu_mem_allocator.register_reserved_work_space( + handle.offload_reserve_space, handle.offload_reserve_space_size); + } + TreeIncMultiHeadSelfAttentionMeta *m = + new TreeIncMultiHeadSelfAttentionMeta(handle, + attn, + weight, + gpu_mem_allocator, + num_samples, + num_q_heads, + num_kv_heads); + if (!attn->offload) { + // assert that we didn't over allocate memory + assert(gpu_mem_allocator.reserved_allocated_size == + gpu_mem_allocator.reserved_total_size); + } + m->profiling = attn->profiling; + m->inference_debugging = attn->inference_debugging; + std::strcpy(m->op_name, attn->name); + m->layer_guid = attn->layer_guid; + + if (attn->quantization_type == DT_NONE) { + assert(weight.domain.get_volume() * data_type_size(weight.data_type) == + m->weightSize); + } + return m; +} + +void TreeIncMultiHeadSelfAttention::forward(FFModel const &ff) { + // TreeIncMultiHeadSelfAttention doesn't support forward + assert(false); +} + +FutureMap TreeIncMultiHeadSelfAttention::inference( + FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + MachineView const *view = mv ? mv : &batch_outputs[0]->machine_view; + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + size_t machine_view_hash = view->hash(); + int idx = 0; + IndexLauncher launcher(TREE_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(weights[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[0]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(idx++, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(idx++, FID_DATA); + if (qkv_bias || final_bias) { + launcher.add_region_requirement( + RegionRequirement(weights[1]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + weights[1]->region, + ff.cpu_offload ? MAP_TO_ZC_MEMORY : 0)); + launcher.add_field(idx++, FID_DATA); + } + return runtime->execute_index_space(ctx, launcher); +} + +/* + regions[0](I): input + regions[3](I): weight + regions[4](O): output +*/ +void TreeIncMultiHeadSelfAttention::inference_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(task->regions.size() == regions.size()); + + TreeVerifyBatchConfig const &bc = + Future(task->futures[0]).get_result(); + log_tree_verify.debug( + "TreeVerifyBatchConfig, num_tokens: %d, num_requests: %d", + bc.num_tokens, + bc.num_active_requests()); + if (bc.num_tokens == 0) { + return; + } + + TreeIncMultiHeadSelfAttentionMeta *m = + *((TreeIncMultiHeadSelfAttentionMeta **)task->local_args); + assert(((*m->qkv_bias || *m->final_bias) ? regions.size() == 4 + : regions.size() == 3)); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorR weight = helperGetGenericTensorAccessorRO( + m->weight_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[2], task->regions[2], FID_DATA, ctx, runtime); + GenericTensorAccessorR biases; + if (*m->qkv_bias || *m->final_bias) { + biases = helperGetGenericTensorAccessorRO(m->weight_type[1], + regions[3], + task->regions[3], + FID_DATA, + ctx, + runtime); + Domain bias_domain = runtime->get_index_space_domain( + ctx, task->regions[3].region.get_index_space()); + assert(bias_domain.get_dim() == 4); + } + + Domain input_domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + Domain weight_domain = runtime->get_index_space_domain( + ctx, task->regions[1].region.get_index_space()); + Domain output_domain = runtime->get_index_space_domain( + ctx, task->regions[2].region.get_index_space()); + + assert(input_domain.get_dim() == 4); + assert(weight_domain.get_dim() == 2); + assert(output_domain.get_dim() == 4); + + /* print_tensor(input.get_float_ptr(), + input_domain.get_volume(), + "[Attention:forward:query]"); */ + + assert(task->index_point.get_dim() == 1); + + TreeIncMultiHeadSelfAttention::inference_kernel_wrapper( + m, &bc, task->index_point.point_data[0], input, weight, output, biases); + + if (m->inference_debugging) { + assert(task->index_point.get_dim() == 1); + int shard_id = task->index_point.point_data[0]; + std::vector weights_accessors; + weights_accessors.push_back(weight); + if (*m->qkv_bias || *m->final_bias) { + weights_accessors.push_back(biases); + } + TreeIncMultiHeadSelfAttention::save_inference_tensors_to_file( + m, shard_id, &bc, {input}, weights_accessors, {output}); + } +} + +void TreeIncMultiHeadSelfAttention::backward(FFModel const &ff) { + // TreeIncMultiHeadSelfAttention does not support backward + assert(false); +} + +bool TreeIncMultiHeadSelfAttention::get_int_parameter(PMParameter para, + int *value) const { + switch (para) { + case PM_NUM_HEADS: + *value = num_q_heads; + return true; + default: + return Op::get_int_parameter(para, value); + } +} + +bool TreeIncMultiHeadSelfAttention::measure_operator_cost( + Simulator *sim, MachineView const &mv, CostMetrics &cost_metrics) const { + return false; +} + +bool operator==(TreeIncMultiHeadSelfAttentionParams const &lhs, + TreeIncMultiHeadSelfAttentionParams const &rhs) { + return lhs.layer_guid == rhs.layer_guid && lhs.embed_dim == rhs.embed_dim && + lhs.num_q_heads == rhs.num_q_heads && lhs.kdim == rhs.kdim && + lhs.vdim == rhs.vdim && lhs.dropout == rhs.dropout && + lhs.qkv_bias == rhs.qkv_bias && lhs.final_bias == rhs.final_bias && + lhs.add_zero_attn == rhs.add_zero_attn && + lhs.apply_rotary_embedding == rhs.apply_rotary_embedding && + lhs.scaling_query == rhs.scaling_query && + lhs.scaling_factor == rhs.scaling_factor && + lhs.qk_prod_scaling == rhs.qk_prod_scaling && + lhs.position_bias == rhs.position_bias; +} + +TreeIncMultiHeadSelfAttentionParams + TreeIncMultiHeadSelfAttention::get_params() const { + TreeIncMultiHeadSelfAttentionParams params; + params.layer_guid = this->layer_guid; + params.embed_dim = this->oProjSize; + params.num_q_heads = this->num_q_heads; + params.num_kv_heads = this->num_kv_heads; + params.kdim = this->kProjSize; + params.vdim = this->vProjSize; + params.dropout = this->dropout; + params.qkv_bias = this->qkv_bias; + params.final_bias = this->final_bias; + params.add_zero_attn = this->add_zero_attn; + params.apply_rotary_embedding = this->apply_rotary_embedding; + params.scaling_query = this->scaling_query; + params.scaling_factor = this->scaling_factor; + params.qk_prod_scaling = this->qk_prod_scaling; + params.position_bias = this->position_bias; + params.tensor_parallelism_degree = this->tensor_parallelism_degree; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } + return params; +} + +}; // namespace FlexFlow + +namespace std { +size_t hash::operator()( + FlexFlow::TreeIncMultiHeadSelfAttentionParams const ¶ms) const { + size_t key = 0; + hash_combine(key, params.layer_guid.id); + hash_combine(key, params.embed_dim); + hash_combine(key, params.num_q_heads); + hash_combine(key, params.num_kv_heads); + hash_combine(key, params.kdim); + hash_combine(key, params.vdim); + hash_combine(key, params.dropout); + hash_combine(key, params.qkv_bias); + hash_combine(key, params.final_bias); + hash_combine(key, params.add_zero_attn); + hash_combine(key, params.apply_rotary_embedding); + hash_combine(key, params.scaling_query); + hash_combine(key, params.scaling_factor); + hash_combine(key, params.qk_prod_scaling); + hash_combine(key, params.position_bias); + hash_combine(key, params.quantization_type); + hash_combine(key, params.offload); + hash_combine(key, params.tensor_parallelism_degree); + return key; +} +}; // namespace std diff --git a/src/ops/tree_inc_multihead_self_attention.cpp b/src/ops/tree_inc_multihead_self_attention.cpp new file mode 100644 index 0000000000..26291fb3b4 --- /dev/null +++ b/src/ops/tree_inc_multihead_self_attention.cpp @@ -0,0 +1,664 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/utils/hip_helper.h" +#include +#include + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +using namespace Kernels::IncMultiHeadAttention; + +namespace Kernels { +namespace TreeIncMultiHeadAttention { + +template +__global__ void commit_tokens_kernel( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + TreeVerifyBatchConfig::CommittedTokensInfo const *committedTokenInfos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens_to_commit, + int num_active_tokens_in_last_batch, + int max_seq_len, + int hidden_size) { + + CUDA_KERNEL_LOOP(i, num_tokens_to_commit * hidden_size * 2) { + + int token_pos = i / (hidden_size * KV_WEIGHT_NUM); + int token_idx_in_last_batch = committedTokenInfos[token_pos].token_index; + int offset = i % hidden_size; + assert(token_idx_in_last_batch < num_active_tokens_in_last_batch); + + size_t val_idx = + token_idx_in_last_batch * 3 * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = committedTokenInfos[token_pos].request_index; + int const tok_id = committedTokenInfos[token_pos].token_depth; + + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +void commit_tokens(TreeIncMultiHeadSelfAttentionMeta const *m, + TreeVerifyBatchConfig const *bc, + hipStream_t stream) { + int num_tokens_to_commit = bc->num_tokens_to_commit; + if (num_tokens_to_commit > 0) { + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_tokens_to_commit; + hipLaunchKernelGGL( + HIP_KERNEL_NAME(commit_tokens_kernel
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->committed_token_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_tokens_to_commit, + m->num_active_tokens, // number of active tokens in previous batch + BatchConfig::max_sequence_length(), + m->hidden_size); + } +} + +template +__global__ void update_tree_branch_kv_cache( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + TreeVerifyBatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens_in_branch, + int processed_tokens_in_batch, + int total_tokens_in_batch, + int max_seq_len, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens_in_branch * hidden_size * 2) { + int token_idx = i / (hidden_size * KV_WEIGHT_NUM); + int offset = i % hidden_size; + + token_idx += processed_tokens_in_batch; // get index in the whole batch + size_t val_idx = token_idx * 3 * hidden_size + hidden_size + offset; + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = tokenInfos[token_idx].request_index; + int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +__global__ void tree_fill_entries_above_diagonal(DT *matrix, + size_t new_tokens, + size_t total_tokens_in_request, + size_t num_q_heads, + DT value) { + CUDA_KERNEL_LOOP(i, new_tokens * total_tokens_in_request * num_q_heads) { + // size_t head_idx = i / (new_tokens * total_tokens_in_request); + size_t src_idx = (i / new_tokens) % total_tokens_in_request; + size_t dst_idx = i % new_tokens + total_tokens_in_request - new_tokens; + // Casual Mask + if (src_idx > dst_idx) { + matrix[i] = value; + } + } +} + +template +void compute_attention_kernel(TreeIncMultiHeadSelfAttentionMeta const *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *bias_ptr, + DT const *weight_ptr, + hipStream_t stream) { + checkCUDA(hipblasSetStream(m->handle.blas, stream)); + checkCUDNN(miopenSetStream(m->handle.dnn, stream)); + hipblasDatatype_t hipblas_data_type = ff_to_cuda_datatype(m->output_type[0]); + miopenDataType_t miopen_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + hipblasDatatype_t compute_type = hipblas_data_type; +#else + // TODO: currently use the hipblas_data_type + // cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + hipblasDatatype_t compute_type = hipblas_data_type; +#endif + // int num_requests = bc->num_active_requests(); + int processed_tokens_in_batch = 0; + // int qkv_block_size = + // (m->qProjSize + m->kProjSize + m->vProjSize) * bc->num_active_tokens(); + int q_block_size = m->qProjSize; + int kt_block_size = m->kProjSize; + int kt_req_block_size = + kt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + int vt_block_size = m->vProjSize; + int vt_req_block_size = + vt_block_size * m->num_q_heads * BatchConfig::max_sequence_length(); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + int last_token_idx_of_the_request = + processed_tokens_in_batch + bc->requestsInfo[i].num_tokens_in_batch - 1; + while (processed_tokens_in_batch <= last_token_idx_of_the_request) { + int num_new_tokens = 1; + int j = processed_tokens_in_batch; + while ((j + 1 <= last_token_idx_of_the_request) && + (bc->tokensInfo[j].abs_depth_in_request + 1 == + bc->tokensInfo[j + 1].abs_depth_in_request)) { + j++; + num_new_tokens++; + } + + int total_tokens_in_request = bc->tokensInfo[j].abs_depth_in_request + 1; + assert(num_new_tokens >= 1 && total_tokens_in_request >= num_new_tokens); + { + // update K-V cache + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_new_tokens; + hipLaunchKernelGGL( + HIP_KERNEL_NAME(update_tree_branch_kv_cache
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_new_tokens, // num_tokens_in_branch + processed_tokens_in_batch, // num_processed_tokens_in_batch + m->num_active_tokens, // total_tokens_in_batch + BatchConfig::max_sequence_length(), + m->hidden_size); + } + + // bc->token_last_available_idx[i] + 1; + // Compute (QK^T/sqrt(d_k)) + int m_ = num_new_tokens; + int n = total_tokens_in_request; + int k = m->qProjSize; + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens_in_request; + + // a flag of using this scaling alpha + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // To get A, skip over Q entries from previous requests (same head) + DT const *A = static_cast
(m->devQKVProjArray) + + processed_tokens_in_batch * m->qProjSize * m->num_q_heads * + QKV_WEIGHT_NUM; + // To get B, skip over K entries from previous requests (all heads + + // padding) + DT const *B = static_cast
(m->keyCache) + i * kt_req_block_size; + // To get C, skip over QK^T products from previous requests + DT *C = static_cast
(m->qk_prods); + + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + if (*m->position_bias) { + size_t parallelism = + m->num_q_heads * total_tokens_in_request * num_new_tokens; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_position_bias_qkprd
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens_in_request, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + + // Fill all elements above diagonal in qk prods with -inf to force + // causal attention. + assert(num_new_tokens <= total_tokens_in_request); + if (num_new_tokens > 1) { + size_t parallelism = + m->num_q_heads * num_new_tokens * total_tokens_in_request; + hipLaunchKernelGGL( + HIP_KERNEL_NAME(tree_fill_entries_above_diagonal
), + GET_BLOCKS(parallelism), + min((size_t)CUDA_NUM_THREADS, parallelism), + 0, + stream, + C, + num_new_tokens, + total_tokens_in_request, + m->num_q_heads, + static_cast
(-INFINITY)); + } + // Compute Softmax(QK^T/sqrt(d_k)) + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens_in_request; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(miopenSet4dTensorDescriptor( + m->qk_tensor, miopen_data_type, n_param, c_param, h_param, w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax); + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(miopenSoftmaxForward_V2(m->handle.dnn, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax, + MIOPEN_SOFTMAX_ACCURATE, + MIOPEN_SOFTMAX_MODE_CHANNEL)); + // Matmul softmax(QK^T/sqrt(d_k)) by V + alpha = 1.0f, beta = 0.0f; + m_ = num_new_tokens; + n = m->vProjSize; + k = total_tokens_in_request; + lda = m_, ldb = n * m->num_q_heads, ldc = m_; + strideA = num_new_tokens * total_tokens_in_request; + strideB = vt_block_size; + strideC = num_new_tokens * m->vProjSize; + // To get A, skip over softmax(QK^T/sqrt(d_k)) entries from previous + // requests (all heads) + A = C_softmax; + // To get B, skip over V^T entries from previous requests (all heads + + // padding) + B = static_cast
(m->valueCache) + i * vt_req_block_size; + // To get C, skip over softmax(QK^T/sqrt(d_k))V products from previous + // requests + C = static_cast
(m->attn_heads) + + processed_tokens_in_batch * m->num_q_heads * m->vProjSize; + + checkCUDA(hipblasGemmStridedBatchedEx(m->handle.blas, + HIPBLAS_OP_N, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + strideA, + B, + hipblas_data_type, + ldb, + strideB, + &beta, + C, + hipblas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + + // Project to output, save result directly on output tensor + alpha = 1.0f, beta = 0.0f; + m_ = m->oProjSize; + k = m->vProjSize * m->num_q_heads; + n = num_new_tokens; + lda = k, ldb = n, ldc = m_; + A = weight_ptr + m->qSize * (m->qProjSize * m->num_q_heads + + m->kProjSize * m->num_q_heads + + m->vProjSize * m->num_q_heads); + B = C; + C = static_cast
(output_ptr) + + processed_tokens_in_batch * m->oProjSize; + + checkCUDA(hipblasGemmEx(m->handle.blas, + HIPBLAS_OP_T, + HIPBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + hipblas_data_type, + lda, + B, + hipblas_data_type, + ldb, + &beta, + C, + hipblas_data_type, + ldc, + compute_type, + HIPBLAS_GEMM_DEFAULT)); + processed_tokens_in_batch += num_new_tokens; + } + // Before moving to the next request + // check that we have finished all tokens of the request + assert(last_token_idx_of_the_request + 1 == processed_tokens_in_batch); + } + if (*m->final_bias && shard_id == 0) { + int parallelism = m->oProjSize * processed_tokens_in_batch; + int qkv_weight_size = m->qProjSize * m->global_num_q_heads + + m->kProjSize * m->global_num_q_heads + + m->vProjSize * m->global_num_q_heads; + hipLaunchKernelGGL(HIP_KERNEL_NAME(apply_proj_bias_w
), + GET_BLOCKS(parallelism), + min(CUDA_NUM_THREADS, parallelism), + 0, + stream, + output_ptr, + bias_ptr, + processed_tokens_in_batch, + qkv_weight_size, + m->oProjSize); + } + + assert(processed_tokens_in_batch == bc->num_active_tokens()); +} + +template +void inference_kernel(TreeIncMultiHeadSelfAttentionMeta *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + hipStream_t stream) { + // additional processing for weight uploading + if (m->handle.offload_reserve_space != nullptr) { + // Note that we update weight_ptr and bias_ptr when uploading weight and + // bias + checkCUDA(hipMemcpyAsync(m->weight_ptr, + weight_ptr, + m->weightSize, + hipMemcpyHostToDevice, + stream)); + weight_ptr = static_cast
(m->weight_ptr); + if (m->biasSize > 0) { + checkCUDA(hipMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, hipMemcpyHostToDevice, stream)); + bias_ptr = static_cast
(m->bias_ptr); + } + } + // copy committed tokens info to GPU for the commit_tokens kernel + // Note that m->num_active_tokens stores the number of active + // tokens in the previous batch, which is needed for committing + // keys/values to the key-value cache + checkCUDA( + hipMemcpyAsync(m->committed_token_infos, + &(bc->committed_tokens), + bc->num_tokens_to_commit * + sizeof(TreeVerifyBatchConfig::CommittedTokensInfo), + hipMemcpyHostToDevice, + stream)); + commit_tokens
(m, bc, stream); + + // After commit we update m->num_active_tokens to be the number of active + // tokens for the current batch + m->num_active_tokens = bc->num_active_tokens(); + + // here because we need postion info in infernece 1 + if (m->offload && m->biasSize > 0) { + checkCUDA(hipMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, hipMemcpyHostToDevice, stream)); + bias_ptr = static_cast
(m->bias_ptr); + } + checkCUDA(hipMemcpyAsync(m->token_infos, + &(bc->tokensInfo), + bc->num_active_tokens() * + sizeof(TreeVerifyBatchConfig::PerTokenInfo), + hipMemcpyHostToDevice, + stream)); + // phase 1: Implement kernel to compute KQV for input tokens + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + + // phase 2: No need to update key/val cache + // IncMultiHeadSelfAttention::update_kv_cache_kernel( + // m, bc, stream); + + // phase 3: Compute attention score + // 3 kernels for pahse 3: matmul1 - softmax - matmal2 + compute_attention_kernel( + m, bc, shard_id, output_ptr, bias_ptr, weight_ptr, stream); +} + +} // namespace TreeIncMultiHeadAttention +} // namespace Kernels + +/*static*/ +void TreeIncMultiHeadSelfAttention::inference_kernel_wrapper( + TreeIncMultiHeadSelfAttentionMeta *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + hipEvent_t t_start, t_end; + if (m->profiling) { + checkCUDA(hipEventCreate(&t_start)); + checkCUDA(hipEventCreate(&t_end)); + checkCUDA(hipEventRecord(t_start, stream)); + } + + // assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::TreeIncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_half_ptr(), + m->offload ? static_cast(m->weight_ptr) : weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::TreeIncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_float_ptr(), + m->offload ? static_cast(m->weight_ptr) + : weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + checkCUDA(hipEventRecord(t_end, stream)); + checkCUDA(hipEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(hipEventElapsedTime(&elapsed, t_start, t_end)); + checkCUDA(hipEventDestroy(t_start)); + checkCUDA(hipEventDestroy(t_end)); + printf("TreeIncMultiHeadSelfAttention forward time = %.2fms\n", elapsed); + // print_tensor<3, float>(acc_query.ptr, acc_query.rect, + // "[Attention:forward:query]"); print_tensor<3, float>(acc_output.ptr, + // acc_output.rect, "[Attention:forward:output]"); + } +} + +TreeIncMultiHeadSelfAttentionMeta::TreeIncMultiHeadSelfAttentionMeta( + FFHandler handler, + TreeIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + TREE_VERIFY_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + attn->quantization_type, + attn->offload), + num_active_tokens(0) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(miopenSetStream(handler.dnn, stream)); + + // allocate memory for the seqArray and reserve space + { + int max_tokens_per_batch = BatchConfig::max_tokens_per_batch(); + size_t committed_tokeninfo_size = max_tokens_per_batch; + size_t total_size = committed_tokeninfo_size * + sizeof(TreeVerifyBatchConfig::CommittedTokensInfo); + if (offload) { + // assert that we have enough reserved work space left + assert(gpu_mem_allocator.reserved_total_size - + gpu_mem_allocator.reserved_allocated_size >= + total_size); + committed_token_infos = + gpu_mem_allocator + .allocate_reserved( + committed_tokeninfo_size); + } else { + gpu_mem_allocator.create_legion_instance(committed_token_reserve_inst, + total_size); + committed_token_infos = + gpu_mem_allocator + .allocate_instance( + committed_tokeninfo_size); + } + } + + checkCUDA(hipStreamSynchronize(stream)); +} + +TreeIncMultiHeadSelfAttentionMeta::~TreeIncMultiHeadSelfAttentionMeta(void) { + if (committed_token_reserve_inst != Realm::RegionInstance::NO_INST) { + committed_token_reserve_inst.destroy(); + } +} + +}; // namespace FlexFlow diff --git a/src/ops/tree_inc_multihead_self_attention.cu b/src/ops/tree_inc_multihead_self_attention.cu new file mode 100644 index 0000000000..50c056c816 --- /dev/null +++ b/src/ops/tree_inc_multihead_self_attention.cu @@ -0,0 +1,1089 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "cuComplex.h" +#endif +#include "flexflow/ffconst_utils.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_kernels.h" +#include "flexflow/ops/kernels/inc_multihead_self_attention_utils.cuh" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; + +#define WARP_SIZE 32 + +using namespace Kernels::IncMultiHeadAttention; + +namespace Kernels { +namespace TreeIncMultiHeadAttention { + +template +__global__ void compute_attention_kernel_fused_kernel( + DT const *query, + DT const *key_cache, + DT const *value_cache, + DT *output_ptr, + float const scale, + int const max_seq_length, + int const max_token_per_batch, + int per_head_size, + int hidden_size, + BatchConfig::PerRequestInfo *request_infos, + int num_heads, + int num_requests, + BatchConfig::BitMask *causalMask, + bool *request_completed, + int qk_smem_sz) { + + // q, k + using Q_vec = typename VEC_K::Type; + using K_vec = typename VEC_K::Type; + using V_vec = typename VEC_V
::Type; + using Out_sum = typename Vec_fp32_::Type; + + constexpr int WARPS_PER_BLOCK = THREADS_PER_BLOCK / WARP_SIZE; + + constexpr int K_VEC_SIZE = sizeof(K_vec) / sizeof(DT); + constexpr int K_ELTS_PER_THREAD = Dh / THREADS_PER_KEY; + constexpr int K_VECS_PER_THREAD = K_ELTS_PER_THREAD / K_VEC_SIZE; + // constexpr int QK_ELTS_IN_16B = 16 / sizeof(DT); + + // thread id + int const tidx = threadIdx.x; + // head id + int const head_idx = blockIdx.x; + // request idx + int const request_idx = blockIdx.y; + + int const batch_config_request_id = + request_infos[request_idx].batch_config_request_id; + + int const first_step = 0; + + int const tlength = + request_infos[batch_config_request_id].first_token_depth_in_request + + request_infos[batch_config_request_id].num_tokens_in_batch; + int const qlength = + request_infos[batch_config_request_id].num_tokens_in_batch; + + BatchConfig::BitMask bitmask = causalMask[batch_config_request_id]; + + int first_token_idx = 0; + for (int r = 0; r < batch_config_request_id; r++) { + first_token_idx += + request_completed[r] ? 0 : request_infos[r].num_tokens_in_batch; + } + + bool prompt_phase = request_infos[batch_config_request_id].prompt_phase; + int q_start = + request_infos[batch_config_request_id].first_token_depth_in_request; + + // shared memory objects + extern __shared__ char smem_[]; + + float *qk_smem = reinterpret_cast(smem_); + float *out_smem = reinterpret_cast(smem_ + qk_smem_sz); + + float qk_max = -FLT_MAX; + + // first WARPS_PER_BLOCK for store qk_max, second WARPS_PER_BLOCK for sum + __shared__ float red_smem[WARPS_PER_BLOCK * 2]; + + const DT *q_ptr = query + first_token_idx * hidden_size * QKV_WEIGHT_NUM + + head_idx * per_head_size; + __shared__ Q_vec q_vecs[THREADS_PER_KEY][K_VECS_PER_THREAD]; + + // the start offset of the element eg. (0, 1, 2, 3) * K_VEC_SIZE + int ki = tidx % THREADS_PER_KEY * K_VEC_SIZE; + int ki_o = tidx % THREADS_PER_KEY; + // the first key's offset for this thread + // ko = 0, 0, 0, 0, 1, 1, 1, 1, .... + int ko = tidx / THREADS_PER_KEY; + // load q tensor + Q_vec q_vec[K_VECS_PER_THREAD]; + + constexpr int K_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_KEY; + // The number of keys per warp. + constexpr int K_PER_WARP = WARP_SIZE / THREADS_PER_KEY; + + DT const *k_cache_batch = + key_cache + batch_config_request_id * max_seq_length * hidden_size + ki; + + int ti_end = + div_up(tlength - first_step, K_PER_WARP) * K_PER_WARP + first_step; + + for (int qi = 0; qi < qlength; qi += 1) { +#pragma unroll + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + q_vecs[ki_o][ii] = *reinterpret_cast( + q_ptr + (hidden_size * QKV_WEIGHT_NUM * qi) + ki + + ii * THREADS_PER_KEY * K_VEC_SIZE); + + // if (head_idx == 0 && request_idx == 1 && tidx == 0) { + // printf("laod q %d, %d %.10f\n", + // request_idx, + // qi,q_vecs[ki_o][ii].x); + // } + } + + __syncthreads(); + for (int ti = ko; ti < ti_end; ti += K_PER_ITER) { + K_vec k[K_VECS_PER_THREAD]; + int const ti_circ = ti % max_seq_length; + + for (int ii = 0; ii < K_VECS_PER_THREAD; ++ii) { + int jj = ii * THREADS_PER_KEY * K_VEC_SIZE; + if (ti < tlength) { + k[ii] = *reinterpret_cast( + k_cache_batch + ti_circ * hidden_size + head_idx * per_head_size + + jj); + } + } + float qk = scale * Qk_dot::dot(q_vecs[ki_o], k); + + if (ti < tlength && tidx % THREADS_PER_KEY == 0) { + bool const mask = + prompt_phase ? (qi + q_start < ti) + : (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << qi)))); + + qk_max = mask ? qk_max : fmaxf(qk_max, qk); + + // if (head_idx == 0 && !mask) { + // printf("tree attn qkqkqkqk request id %d qi%d, ti %d, %.10f, %.10f, + // %.10f, %d\n", + // request_idx, + // qi, + // ti, + // qk, + // q_vecs[ki_o][0].x, + // k[0].x, + // bitmask.non_tree_cache_size); + // } + qk_smem[ti - first_step] = mask ? 0.0f : qk; + } + } + + __syncthreads(); + +#pragma unroll + for (int mask = WARP_SIZE / 2; mask >= THREADS_PER_KEY; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Decompose the thread index into warp and lane. + int const warp = tidx / WARP_SIZE; + int const lane = tidx % WARP_SIZE; + + // The warp leader writes the max to shared memory. + if (lane == 0) { + red_smem[warp] = qk_max; + } + + // Make sure the products are in shared memory. + __syncthreads(); + + // The warps finalize the reduction. + qk_max = lane < WARPS_PER_BLOCK ? red_smem[lane] : -FLT_MAX; +#pragma unroll + for (int mask = WARPS_PER_BLOCK / 2; mask >= 1; mask /= 2) { + qk_max = fmaxf(qk_max, __shfl_xor_sync(uint32_t(-1), qk_max, mask)); + } + + // Broadcast to all the threads in the warp. + qk_max = __shfl_sync(uint32_t(-1), qk_max, 0); + + // if (head_idx == 0 && qi == 9 && tidx == 0) { + // printf("tree attn first token qk_max %f\n", qk_max); + // } + + float exp_sum = 0.f; + for (int ti = first_step + tidx; ti < tlength; ti += THREADS_PER_BLOCK) { + bool const mask = + prompt_phase ? (q_start + qi < ti) + : (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << qi)))); + float logit = mask ? 0.0f : __expf(qk_smem[ti - first_step] - qk_max); + exp_sum += logit; + qk_smem[ti - first_step] = mask ? 0.0f : logit; + } + + // Compute the sum. + exp_sum = block_sum(&red_smem[WARPS_PER_BLOCK], exp_sum); + + // softmax + float inv_sum = __fdividef(1.f, exp_sum + 1.e-6); + for (int ti = first_step + tidx; ti < tlength; ti += THREADS_PER_BLOCK) { + qk_smem[ti - first_step] *= inv_sum; + } + + __syncthreads(); + + // value projection + constexpr int V_VEC_SIZE = 16 / sizeof(DT); + // A vector of V elements for the current timestep. + // using V_vec_k = typename V_vec_k_::Type; + // using V_vec_acum = typename V_vec_acum_fp32_::Type; + + // The value computed by this thread. + int vo = tidx / THREADS_PER_VALUE; + // The hidden dimensions computed by this particular thread. + int vi = tidx % THREADS_PER_VALUE * V_VEC_SIZE; + constexpr int V_PER_ITER = THREADS_PER_BLOCK / THREADS_PER_VALUE; + + Out_sum out; + zero(out); + + // The base pointer for the value in the cache buffer. + DT const *v_cache_batch = + value_cache + batch_config_request_id * max_seq_length * hidden_size + + vi; + + if (Dh == Dh_MAX || vi < Dh) { + for (int ti = first_step + vo; ti < tlength; ti += V_PER_ITER) { + // Load the values from the cache. + int const ti_circ = ti % max_seq_length; + // int const real_cache_idx = topology.real_token_pos[sub_req_idx][ti]; + V_vec v = *reinterpret_cast( + v_cache_batch + ti_circ * hidden_size + head_idx * per_head_size); + + if (ti < tlength) { + bool const mask = + prompt_phase + ? (q_start + qi < ti) + : (ti >= bitmask.non_tree_cache_size && + (!(bitmask.mask[ti - bitmask.non_tree_cache_size] & + (1 << qi)))); + float logit = mask ? 0.0f : qk_smem[ti - first_step]; + out = FlexFlow::fma(logit, cast_to_float(v), out); + } + } + } + + // // Make sure we can start writing to shared memory. + __syncthreads(); + + // Run the final reduction amongst the different groups computing different + // partial outputs. + if (Dh == Dh_MAX || vi < Dh) { +#pragma unroll + for (int active_groups = V_PER_ITER; active_groups >= 2; + active_groups /= 2) { + + // The midpoint in the number of active groups. + int midpoint = active_groups / 2; + + // The upper part of active threads store to shared memory. + if (vo >= midpoint && vo < active_groups && (Dh == Dh_MAX || vi < Dh)) { + *reinterpret_cast(out_smem + (vo - midpoint) * Dh + vi) = + out; + } + __syncthreads(); + + // The bottom warps update their values. + if (vo < midpoint && (Dh == Dh_MAX || vi < Dh)) { + out = add(*reinterpret_cast(out_smem + vo * Dh + vi), + out); + } + __syncthreads(); + } + } + + // Output the final values. + if (vo == 0 && (Dh == Dh_MAX || vi < Dh)) { + convert_from_float(*reinterpret_cast( + output_ptr + (first_token_idx + qi) * hidden_size + + head_idx * per_head_size + vi), + out); + // if (blockIdx.y == 0 && blockIdx.x == 0 && tidx == 0 && qi == 1) { + // printf("tree attn final value, %.9f, %.9f, %.9f, %.9f, %d, %d\n", + // out.x, + // out.y, + // out.z, + // out.w, + // vi, + // (first_token_idx + qi) * hidden_size + head_idx * + // per_head_size + + // vi); + // } + } + } +} + +template +__global__ void commit_tokens_kernel( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + TreeVerifyBatchConfig::CommittedTokensInfo const *committedTokenInfos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens_to_commit, + int num_active_tokens_in_last_batch, + int max_seq_len, + int hidden_size) { + + CUDA_KERNEL_LOOP(i, num_tokens_to_commit * hidden_size) { + + int token_pos = i / (hidden_size); + int token_idx_in_last_batch = committedTokenInfos[token_pos].token_index; + int offset = i % hidden_size; + assert(token_idx_in_last_batch < num_active_tokens_in_last_batch); + + size_t val_idx = token_idx_in_last_batch * QKV_WEIGHT_NUM * hidden_size + + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = committedTokenInfos[token_pos].request_index; + int const tok_id = committedTokenInfos[token_pos].token_depth; + + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +void commit_tokens(TreeIncMultiHeadSelfAttentionMeta const *m, + TreeVerifyBatchConfig const *bc, + cudaStream_t stream) { + int num_tokens_to_commit = bc->num_tokens_to_commit; + if (num_tokens_to_commit > 0) { + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_tokens_to_commit; + commit_tokens_kernel<<>>( + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->committed_token_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_tokens_to_commit, + m->num_active_tokens, // number of active tokens in previous batch + BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num(), + m->hidden_size); + } +} + +template +__global__ void update_tree_branch_kv_cache( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + TreeVerifyBatchConfig::PerTokenInfo const *tokenInfos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_tokens_in_branch, + int processed_tokens_in_batch, + int total_tokens_in_batch, + int max_seq_len, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_tokens_in_branch * hidden_size) { + + int token_idx = i / (hidden_size); + int offset = i % hidden_size; + + token_idx += processed_tokens_in_batch; // get index in the whole batch + size_t val_idx = + token_idx * QKV_WEIGHT_NUM * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = tokenInfos[token_idx].request_index; + int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + kCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + tok_id * hidden_size + + offset] = vVal; + } +} + +template +__global__ void update_tree_branch_kv_cache_fused( + DT const *devQKVProjArray, + DT *kCache_ptr, + DT *vCache_ptr, + TreeVerifyBatchConfig::PerTokenInfo const *tokenInfos, + BatchConfig::PerRequestInfo *request_infos, + int qProjSize, + int kProjSize, + int vProjSize, + int num_new_tokens, + int max_seq_len, + int hidden_size) { + CUDA_KERNEL_LOOP(i, num_new_tokens * hidden_size) { + + int token_idx = i / hidden_size; + int offset = i % hidden_size; + size_t val_idx = + token_idx * QKV_WEIGHT_NUM * hidden_size + hidden_size + offset; + + DT kVal = devQKVProjArray[val_idx]; + DT vVal = devQKVProjArray[val_idx + hidden_size]; + + int const req_id = tokenInfos[token_idx].request_index; + // int const tok_id = tokenInfos[token_idx].abs_depth_in_request; + + int const request_token_offset = + request_infos[req_id].first_token_offset_in_batch; + int const first_token_depth = + request_infos[req_id].first_token_depth_in_request; + + // if(i % hidden_size == 0){ + // printf("update token request id: %d, %d, %d real id %d, value%.10f\n", + // req_id, token_idx, request_token_offset,(token_idx + first_token_depth + // - request_token_offset), kVal); + // } + kCache_ptr[req_id * (hidden_size * max_seq_len) + + (token_idx + first_token_depth - request_token_offset) * + hidden_size + + offset] = kVal; + vCache_ptr[req_id * (hidden_size * max_seq_len) + + (token_idx + first_token_depth - request_token_offset) * + hidden_size + + offset] = vVal; + } +} + +template +__global__ void tree_fill_entries_above_diagonal(DT *matrix, + size_t new_tokens, + size_t total_tokens_in_request, + size_t num_q_heads, + DT value) { + CUDA_KERNEL_LOOP(i, new_tokens * total_tokens_in_request * num_q_heads) { + // size_t head_idx = i / (new_tokens * total_tokens_in_request); + size_t src_idx = (i / new_tokens) % total_tokens_in_request; + size_t dst_idx = i % new_tokens + total_tokens_in_request - new_tokens; + // Casual Mask + if (src_idx > dst_idx) { + matrix[i] = value; + } + } +} + +template +void compute_attention_kernel(TreeIncMultiHeadSelfAttentionMeta const *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + DT *output_ptr, + DT const *bias_ptr, + DT const *weight_ptr, + cudaStream_t stream) { + checkCUDA(cublasSetStream(m->handle.blas, stream)); + checkCUDNN(cudnnSetStream(m->handle.dnn, stream)); + cudaDataType_t cublas_data_type = ff_to_cuda_datatype(m->output_type[0]); + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(m->output_type[0]); + assert(data_type_size(m->output_type[0]) == sizeof(DT)); +#if defined(CUDA_VERSION) && (CUDA_VERSION < 11000) + cudaDataType_t compute_type = cublas_data_type; +#else + // For best performance, set the default cublas compute type to + // CUBLAS_COMPUTE_16F for half precision and to + // CUBLAS_COMPUTE_32F_FAST_16F for full precision + cublasComputeType_t compute_type = CUBLAS_COMPUTE_16F; + if (m->output_type[0] == DT_FLOAT) { + compute_type = CUBLAS_COMPUTE_32F_FAST_16F; + } +#endif + // int num_requests = bc->num_active_requests(); + int processed_tokens_in_batch = 0; + // int qkv_block_size = + // (m->qProjSize + m->kProjSize + m->vProjSize) * bc->num_active_tokens(); + int q_block_size = m->qProjSize; + int kt_block_size = m->kProjSize; + int kt_req_block_size = + kt_block_size * m->num_q_heads * BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num(); + int vt_block_size = m->vProjSize; + int vt_req_block_size = + vt_block_size * m->num_q_heads * BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num(); + assert(m->qProjSize == m->kProjSize); + + for (int i = 0; i < bc->max_requests_per_batch(); i++) { + if (bc->request_completed[i]) { + continue; + } + assert(processed_tokens_in_batch == + bc->requestsInfo[i].first_token_offset_in_batch); + int last_token_idx_of_the_request = + processed_tokens_in_batch + bc->requestsInfo[i].num_tokens_in_batch - 1; + while (processed_tokens_in_batch <= last_token_idx_of_the_request) { + int num_new_tokens = 1; + int j = processed_tokens_in_batch; + while ((j + 1 <= last_token_idx_of_the_request) && + (bc->tokensInfo[j].abs_depth_in_request + 1 == + bc->tokensInfo[j + 1].abs_depth_in_request)) { + j++; + num_new_tokens++; + } + + int total_tokens_in_request = bc->tokensInfo[j].abs_depth_in_request + 1; + assert(num_new_tokens >= 1 && total_tokens_in_request >= num_new_tokens); + { + // update K-V cache + int parallelism = m->hidden_size * KV_WEIGHT_NUM * num_new_tokens; + update_tree_branch_kv_cache<<>>( + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_new_tokens, // num_tokens_in_branch + processed_tokens_in_batch, // num_processed_tokens_in_batch + m->num_active_tokens, // total_tokens_in_batch + BatchConfig::max_sequence_length(), + m->hidden_size); + } + + // bc->token_last_available_idx[i] + 1; + // Compute (QK^T/sqrt(d_k)) + int m_ = num_new_tokens; + int n = total_tokens_in_request; + int k = m->qProjSize; + int lda = k * m->num_q_heads * QKV_WEIGHT_NUM, ldb = k * m->num_q_heads, + ldc = m_; + int strideA = q_block_size; + int strideB = kt_block_size; + int strideC = num_new_tokens * total_tokens_in_request; + + // a flag of using this scaling alpha + DT alpha = 1.0f, beta = 0.0f; + if (*m->qk_prod_scaling) { + alpha = static_cast
(1.0f / sqrt(m->kProjSize)); + } + // To get A, skip over Q entries from previous requests (same head) + DT const *A = static_cast
(m->devQKVProjArray) + + processed_tokens_in_batch * m->qProjSize * m->num_q_heads * + QKV_WEIGHT_NUM; + // To get B, skip over K entries from previous requests (all heads + + // padding) + DT const *B = static_cast
(m->keyCache) + i * kt_req_block_size; + // To get C, skip over QK^T products from previous requests + DT *C = static_cast
(m->qk_prods); + + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + // add alibi position bias to qk production + // add alibi position bias to qk production + if (*m->position_bias) { + size_t parallelism = + m->num_q_heads * total_tokens_in_request * num_new_tokens; + apply_position_bias_qkprd<<>>(C, + num_new_tokens, + total_tokens_in_request, + m->num_q_heads, + m->global_num_q_heads, + shard_id); + } + + // Fill all elements above diagonal in qk prods with -inf to force + // causal attention. + assert(num_new_tokens <= total_tokens_in_request); + if (num_new_tokens > 1) { + size_t parallelism = + m->num_q_heads * num_new_tokens * total_tokens_in_request; + tree_fill_entries_above_diagonal<<>>( + C, + num_new_tokens, + total_tokens_in_request, + m->num_q_heads, + static_cast
(-INFINITY)); + } + // Compute Softmax(QK^T/sqrt(d_k)) + // Before modifying the parameters below, make sure to read the following + // description of the CUDNN_TENSOR_NCHW tensor layout, from + // https://docs.nvidia.com/deeplearning/cudnn/api/index.html#cudnnTensorFormat_t: + // This tensor format specifies that the data is laid out in the following + // order: batch size, feature maps, rows, columns. The strides are + // implicitly defined in such a way that the data are contiguous in memory + // with no padding between images, feature maps, rows, and columns; the + // columns are the inner dimension and the images are the outermost + // dimension. + int n_param = m->num_q_heads; + int c_param = total_tokens_in_request; + int h_param = 1; + int w_param = num_new_tokens; + checkCUDNN(cudnnSetTensor4dDescriptor(m->qk_tensor, + CUDNN_TENSOR_NCHW, + cudnn_data_type, + n_param, + c_param, + h_param, + w_param)); + float softmax_alpha = 1.0f, softmax_beta = 0.0f; + DT *C_softmax = static_cast
(m->qk_prods_softmax); + // The softmax operation below is executed according to the + // CUDNN_SOFTMAX_MODE_CHANNEL, which is also described in the docs: The + // softmax operation is computed per spatial location (H,W) per image (N) + // across dimension C. + checkCUDNN(cudnnSoftmaxForward(m->handle.dnn, + CUDNN_SOFTMAX_ACCURATE, + CUDNN_SOFTMAX_MODE_CHANNEL, + &softmax_alpha, + m->qk_tensor, + C, + &softmax_beta, + m->qk_tensor, + C_softmax)); + // Matmul softmax(QK^T/sqrt(d_k)) by V + alpha = 1.0f, beta = 0.0f; + m_ = m->vProjSize; + n = num_new_tokens; + k = total_tokens_in_request; + lda = m_ * m->num_q_heads, ldb = n, ldc = m_ * m->num_q_heads; + strideA = vt_block_size; + strideB = num_new_tokens * total_tokens_in_request; + strideC = m->vProjSize; + // To get A, skip over V^T entries from previous requests (all heads + + // padding) + A = static_cast
(m->valueCache) + i * vt_req_block_size; + // To get B, skip over softmax(QK^T/sqrt(d_k)) entries from previous + // requests (all heads) + B = C_softmax; + // To get C, skip over softmax(QK^T/sqrt(d_k))V products from previous + // requests + C = static_cast
(m->attn_heads) + + processed_tokens_in_batch * m->num_q_heads * m->vProjSize; + checkCUDA(cublasGemmStridedBatchedEx(m->handle.blas, + CUBLAS_OP_N, + CUBLAS_OP_T, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + strideA, + B, + cublas_data_type, + ldb, + strideB, + &beta, + C, + cublas_data_type, + ldc, + strideC, + m->num_q_heads, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + processed_tokens_in_batch += num_new_tokens; + } + // Before moving to the next request + // check that we have finished all tokens of the request + assert(last_token_idx_of_the_request + 1 == processed_tokens_in_batch); + } + // Project to output, save result directly on output tensor + DT alpha = 1.0f, beta = 0.0f; + int m_ = m->oProjSize; + int k = m->vProjSize * m->num_q_heads; + int n = processed_tokens_in_batch; + int lda = k, ldb = k, ldc = m_; + DT const *A = weight_ptr + m->qSize * (m->qProjSize * m->num_q_heads + + m->kProjSize * m->num_q_heads + + m->vProjSize * m->num_q_heads); + DT const *B = static_cast
(m->attn_heads); + DT *C = static_cast
(output_ptr); + + checkCUDA(cublasGemmEx(m->handle.blas, + CUBLAS_OP_T, + CUBLAS_OP_N, + m_, + n, + k, + &alpha, + A, + cublas_data_type, + lda, + B, + cublas_data_type, + ldb, + &beta, + C, + cublas_data_type, + ldc, + compute_type, + CUBLAS_GEMM_DEFAULT_TENSOR_OP)); + if (*m->final_bias && shard_id == 0) { + int parallelism = m->oProjSize * processed_tokens_in_batch; + int qkv_weight_size = m->qProjSize * m->global_num_q_heads + + m->kProjSize * m->global_num_q_heads + + m->vProjSize * m->global_num_q_heads; + apply_proj_bias_w<<>>(output_ptr, + bias_ptr, + processed_tokens_in_batch, + qkv_weight_size, + m->oProjSize); + } + + assert(processed_tokens_in_batch == bc->num_active_tokens()); +} + +#define LAUNCH_TREE_VERIFY_ATTENTION_SCORE_KERNEL( \ + DT, Dh, Dh_MAX, THDS_PER_KEY, THDS_PER_VALUE, THDS_PER_BLOCK, stream) \ + smem_size_in_bytes_tree
(m->qProjSize, \ + BatchConfig::max_sequence_length() + \ + BatchConfig::max_spec_tree_token_num(), \ + THDS_PER_VALUE, \ + THDS_PER_BLOCK, \ + bc, \ + smem_sz); \ + compute_attention_kernel_fused_kernel \ + <<>>( \ + static_cast
(m->devQKVProjArray), \ + static_cast
(m->keyCache), \ + static_cast
(m->valueCache), \ + output_ptr, \ + scale, \ + BatchConfig::max_sequence_length() + \ + BatchConfig::BatchConfig::max_spec_tree_token_num(), \ + BatchConfig::max_tokens_per_batch(), \ + m->qProjSize, \ + m->hidden_size, \ + m->request_infos, \ + m->num_q_heads, \ + bc->num_active_requests(), \ + m->causalMask, \ + m->request_completed, \ + smem_sz[0]) + +template +void compute_attention_kernel_fused(TreeIncMultiHeadSelfAttentionMeta const *m, + TreeVerifyBatchConfig const *bc, + DT *output_ptr, + cudaStream_t stream) { + + // update the kv cache + // update K-V cache + int num_new_tokens = bc->num_active_tokens(); + int parallelism = m->hidden_size * num_new_tokens; + update_tree_branch_kv_cache_fused<<>>( + static_cast
(m->devQKVProjArray), + static_cast
(m->keyCache), + static_cast
(m->valueCache), + m->token_infos, + m->request_infos, + m->qProjSize, + m->kProjSize, + m->vProjSize, + num_new_tokens, + BatchConfig::max_sequence_length() + + BatchConfig::max_spec_tree_token_num(), + m->hidden_size); + + dim3 grid(m->num_q_heads, bc->num_active_requests()); + int const per_head_size = m->qProjSize; + float scale = (*m->qk_prod_scaling) ? 1.0f / sqrt(m->kProjSize) : 1.0f; + // 0->qk production size, 1->total shared size + int smem_sz[2]; + if (per_head_size == 64) { + constexpr int THREADS_PER_VALUE_64 = threads_per_value_t::value; + LAUNCH_TREE_VERIFY_ATTENTION_SCORE_KERNEL( + DT, 64, 64, 4, THREADS_PER_VALUE_64, 128, stream); + } else if (per_head_size == 128) { + constexpr int THREADS_PER_VALUE_128 = threads_per_value_t::value; + LAUNCH_TREE_VERIFY_ATTENTION_SCORE_KERNEL( + DT, 128, 128, 4, THREADS_PER_VALUE_128, 128, stream); + } else { + assert(false && "a unsupported head size"); + } +} + +template +void inference_kernel(TreeIncMultiHeadSelfAttentionMeta *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + DT const *input_ptr, + DT const *weight_ptr, + DT *output_ptr, + DT const *bias_ptr, + cudaStream_t stream) { + // additional processing for weight uploading + if (m->handle.offload_reserve_space != nullptr) { + // Note that we update weight_ptr and bias_ptr when uploading weight and + // bias + cudaMemcpyAsync(m->weight_ptr, + weight_ptr, + m->weightSize, + cudaMemcpyHostToDevice, + stream); + weight_ptr = static_cast
(m->weight_ptr); + if (m->biasSize > 0) { + cudaMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, cudaMemcpyHostToDevice, stream); + bias_ptr = static_cast
(m->bias_ptr); + } + } + + // copy committed tokens info to GPU for the commit_tokens kernel + // Note that m->num_active_tokens stores the number of active + // tokens in the previous batch, which is needed for committing + // keys/values to the key-value cache + // std::cout << "tokens to be committed: " << bc->num_tokens_to_commit << + // "\n"; + + commit_tokens
(m, bc, stream); + + // After commit we update m->num_active_tokens to be the number of active + // tokens for the current batch + m->num_active_tokens = bc->num_active_tokens(); + + // here because we need postion info in infernece 1 + if (m->offload && m->biasSize > 0) { + cudaMemcpyAsync( + m->bias_ptr, bias_ptr, m->biasSize, cudaMemcpyHostToDevice, stream); + bias_ptr = static_cast
(m->bias_ptr); + } + // phase 1: Implement kernel to compute KQV for input tokens + compute_qkv_kernel(m, + bc, + shard_id, + input_ptr, + weight_ptr, + static_cast
(m->devQKVProjArray), + bias_ptr, + stream); + + // phase 2: No need to update key/val cache + // IncMultiHeadSelfAttention::update_kv_cache_kernel( + // m, bc, stream); + // use the new kernel + compute_attention_kernel_fused
( + m, bc, static_cast
(m->attn_heads), stream); + + int processed_tokens_in_batch = bc->num_active_tokens(); + + compute_o_prod_bias(m, + bc, + shard_id, + output_ptr, + weight_ptr, + bias_ptr, + processed_tokens_in_batch, + stream); +} + +} // namespace TreeIncMultiHeadAttention +} // namespace Kernels + +/*static*/ +void TreeIncMultiHeadSelfAttention::inference_kernel_wrapper( + TreeIncMultiHeadSelfAttentionMeta *m, + TreeVerifyBatchConfig const *bc, + int shard_id, + GenericTensorAccessorR const &input, + GenericTensorAccessorR const &weight, + GenericTensorAccessorW const &output, + GenericTensorAccessorR const &bias) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + bool use_bias = *m->qkv_bias || *m->final_bias; + + cudaEvent_t t_start, t_end; + if (m->profiling) { + cudaEventCreate(&t_start); + cudaEventCreate(&t_end); + cudaEventRecord(t_start, stream); + } + + // assert(input.data_type == weight.data_type); + assert(input.data_type == output.data_type); + if (use_bias) { + assert(input.data_type == bias.data_type); + } + + if (input.data_type == DT_HALF) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + + half const *bias_ptr = + use_bias ? bias.get_half_ptr() : static_cast(nullptr); + Kernels::TreeIncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_half_ptr(), + m->offload ? static_cast(m->weight_ptr) : weight.get_half_ptr(), + output.get_half_ptr(), + bias_ptr, + stream); + } else if (input.data_type == DT_FLOAT) { + if (m->offload) { + pre_build_weight_kernel(m, weight, input.data_type, stream); + } + float const *bias_ptr = + use_bias ? bias.get_float_ptr() : static_cast(nullptr); + Kernels::TreeIncMultiHeadAttention::inference_kernel( + m, + bc, + shard_id, + input.get_float_ptr(), + m->offload ? static_cast(m->weight_ptr) + : weight.get_float_ptr(), + output.get_float_ptr(), + bias_ptr, + stream); + } else { + assert(false && "Unspported data type"); + } + + if (m->profiling) { + cudaEventRecord(t_end, stream); + checkCUDA(cudaEventSynchronize(t_end)); + float elapsed = 0; + checkCUDA(cudaEventElapsedTime(&elapsed, t_start, t_end)); + cudaEventDestroy(t_start); + cudaEventDestroy(t_end); + } +} + +TreeIncMultiHeadSelfAttentionMeta::TreeIncMultiHeadSelfAttentionMeta( + FFHandler handler, + TreeIncMultiHeadSelfAttention const *attn, + GenericTensorAccessorR const &weight, + MemoryAllocator &gpu_mem_allocator, + int num_samples, + int _num_q_heads, + int _num_kv_heads) + : IncMultiHeadSelfAttentionMeta(handler, + TREE_VERIFY_MODE, + attn, + attn->qSize, + attn->kSize, + attn->vSize, + attn->qProjSize, + attn->kProjSize, + attn->vProjSize, + attn->oProjSize, + attn->apply_rotary_embedding, + attn->qkv_bias, + attn->scaling_query, + attn->qk_prod_scaling, + attn->position_bias, + attn->final_bias, + attn->scaling_factor, + weight, + gpu_mem_allocator, + num_samples, + attn->num_q_heads, + attn->num_kv_heads, + _num_q_heads, + _num_kv_heads, + attn->quantization_type, + attn->offload), + num_active_tokens(0) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDNN(cudnnSetStream(handler.dnn, stream)); + + // allocate memory for the seqArray and reserve space + { + + causalMask = reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + sizeof(BatchConfig::requestsInfo)); + committed_token_infos = + reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + + sizeof(BatchConfig::requestsInfo) + + sizeof(BatchConfig::causalMask)); + + request_completed = reinterpret_cast( + reinterpret_cast(handler.batch_config_metadata) + + sizeof(BatchConfig::tokensInfo) + sizeof(BatchConfig::requestsInfo) + + sizeof(BatchConfig::causalMask) + + sizeof(TreeVerifyBatchConfig::committed_tokens)); + } + + cudaStreamSynchronize(stream); +} + +TreeIncMultiHeadSelfAttentionMeta::~TreeIncMultiHeadSelfAttentionMeta(void) { + if (committed_token_reserve_inst != Realm::RegionInstance::NO_INST) { + committed_token_reserve_inst.destroy(); + } +} + +}; // namespace FlexFlow diff --git a/src/parallel_ops/allreduce.cc b/src/parallel_ops/allreduce.cc index 7052bb3ed5..903c089993 100644 --- a/src/parallel_ops/allreduce.cc +++ b/src/parallel_ops/allreduce.cc @@ -89,6 +89,17 @@ void AllReduce::create_input_partition(FFModel &ff) { return; } +void AllReduce::create_input_partition_inference( + FFModel &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + assert(batch_outputs[0]->part != LogicalPartition::NO_PART); + assert(batch_inputs[0]->part != LogicalPartition::NO_PART); + // Do nothing + return; +} + OpMeta *AllReduce::init_task(Task const *task, std::vector const ®ions, @@ -136,6 +147,85 @@ void AllReduce::init(FFModel const &ff) { set_opmeta_from_futuremap(ff, fm); } +void AllReduce::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + parallel_is = batch_outputs[0]->parallel_is; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ALLREDUCE_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(AllReduce)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +FutureMap AllReduce::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + assert(numOutputs == 1); + assert(numInputs == 1); + assert(batch_inputs[0]->data_type == batch_outputs[0]->data_type); + DataType data_type = batch_inputs[0]->data_type; + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(ALLREDUCE_INF_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(batch_inputs[0]->part, + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + + void AllReduce::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; @@ -232,6 +322,27 @@ bool AllReduce::append_parallel_op_info( } /*static*/ +void AllReduce::inference_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 2); + assert(task->regions.size() == 2); + + AllReduceMeta const *m = *((AllReduceMeta **)task->local_args); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + + assert(input.data_type == output.data_type); + inference_kernel_wrapper(m, bc, input, output); +} + +/*static*/ + void AllReduce::forward_task(Task const *task, std::vector const ®ions, Context ctx, diff --git a/src/parallel_ops/combine.cc b/src/parallel_ops/combine.cc index a4169ea306..acc5c414c7 100644 --- a/src/parallel_ops/combine.cc +++ b/src/parallel_ops/combine.cc @@ -58,6 +58,9 @@ CombineParams Combine::get_params() const { CombineParams params; params.combine_legion_dim = this->combine_dim; params.combine_degree = this->combine_degree; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -69,7 +72,7 @@ Combine::Combine(FFModel &model, input, params.combine_legion_dim, params.combine_degree, - name) {} + params.name) {} Combine::Combine(FFModel &model, const ParallelTensor _input, @@ -88,7 +91,7 @@ Combine::Combine(FFModel &model, dims[combine_dim].degree /= combine_degree; ParallelTensorBase::update_parallel_ids(numdim, dims); outputs[0] = model.create_parallel_tensor_legion_ordering( - numdim, dims, DT_FLOAT, this); + numdim, dims, _input->data_type, this); // inputs[0]->print("Combine::input"); // outputs[0]->print("Combine::output"); } @@ -97,11 +100,13 @@ OpMeta *Combine::init_task(Task const *task, std::vector const ®ions, Context ctx, Runtime *runtime) { - Combine *rep = (Combine *)task->args; - // FFHandler handle = *((FFHandler *)task->local_args); - // CombineMeta* m = new CombineMeta(handle); - // m->data_type = rep->outputs[0]->data_type; - return nullptr; + Combine *cmb = (Combine *)task->args; + FFHandler handle = *((FFHandler *)task->local_args); + CombineMeta *m = new CombineMeta(handle); + m->input_type[0] = cmb->inputs[0]->data_type; + m->output_type[0] = cmb->outputs[0]->data_type; + assert(m->input_type[0] == m->output_type[0]); + return m; } void Combine::init(FFModel const &ff) { @@ -111,6 +116,7 @@ void Combine::init(FFModel const &ff) { Runtime *runtime = ff.config.lg_hlr; assert(numOutputs == 1); assert(numInputs == 1); + set_argumentmap_for_init(ff, argmap); IndexLauncher launcher(COMBINE_INIT_TASK_ID, parallel_is, TaskArgument(this, sizeof(Combine)), @@ -130,6 +136,48 @@ void Combine::init(FFModel const &ff) { launcher.add_field(1, FID_DATA); FutureMap fm = runtime->execute_index_space(ctx, launcher); fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +void Combine::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + parallel_is = batch_outputs[0]->parallel_is; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(COMBINE_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Combine)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + assert(inference_input_lps.find(batch_inputs[0]) != + inference_input_lps.end()); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); } void Combine::create_input_partition(FFModel &ff) { @@ -147,6 +195,61 @@ void Combine::create_input_partition(FFModel &ff) { output_grad_lp); } +void Combine::create_input_partition_inference( + FFModel &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + assert(batch_outputs[0]->part != LogicalPartition::NO_PART); + assert(batch_inputs[0]->part != LogicalPartition::NO_PART); + // input_lp is a disjoint partition + ff.create_disjoint_partition(batch_outputs[0]->num_dims, + batch_outputs[0]->dims, + batch_outputs[0]->parallel_is, + batch_inputs[0]->region, + inference_input_lps[batch_inputs[0]]); +} + +FutureMap Combine::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + assert(numOutputs == 1); + assert(numInputs == 1); + assert(batch_inputs[0]->data_type == batch_outputs[0]->data_type); + DataType data_type = batch_inputs[0]->data_type; + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(COMBINE_FWD_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void Combine::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; @@ -157,7 +260,7 @@ void Combine::forward(FFModel const &ff) { DataType data_type = inputs[0]->data_type; IndexLauncher launcher(COMBINE_FWD_TASK_ID, outputs[0]->parallel_is, - TaskArgument(&data_type, sizeof(data_type)), + TaskArgument(nullptr, 0), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -261,8 +364,11 @@ void Combine::forward_task(Task const *task, Runtime *runtime) { assert(regions.size() == 2); assert(task->regions.size() == 2); - DataType data_type = *((DataType *)task->args); - if (data_type == DT_FLOAT) { + CombineMeta const *m = *((CombineMeta **)task->local_args); + DataType data_type = m->input_type[0]; + if (data_type == DT_HALF) { + forward_task_with_type(task, regions, ctx, runtime); + } else if (data_type == DT_FLOAT) { forward_task_with_type(task, regions, ctx, runtime); } else if (data_type == DT_DOUBLE) { forward_task_with_type(task, regions, ctx, runtime); diff --git a/src/parallel_ops/fused_parallel_op.cc b/src/parallel_ops/fused_parallel_op.cc index c0a97bdda1..1a76cbfc40 100644 --- a/src/parallel_ops/fused_parallel_op.cc +++ b/src/parallel_ops/fused_parallel_op.cc @@ -59,6 +59,9 @@ FusedParallelOpParams FusedParallelOp::get_params() const { std::vector ops(std::begin(this->parallel_ops), std::end(this->parallel_ops)); params.parallel_ops = ops; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } diff --git a/src/parallel_ops/kernels/allreduce_kernels.cpp b/src/parallel_ops/kernels/allreduce_kernels.cpp index 0aea27107d..b32cada626 100644 --- a/src/parallel_ops/kernels/allreduce_kernels.cpp +++ b/src/parallel_ops/kernels/allreduce_kernels.cpp @@ -25,6 +25,31 @@ AllReduceMeta::AllReduceMeta(FFHandler handle, AllReduce const *reduct) namespace Kernels { namespace AllReduce { +void inference_kernel_wrapper(AllReduceMeta const *m, + BatchConfig const *bc, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &output) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + assert(input.data_type == output.data_type); + assert(input.domain == output.domain); + size_t hidden_dim_size = input.domain.hi()[0] - input.domain.lo()[0] + 1; + size_t num_elements = bc->num_tokens * hidden_dim_size; +#ifdef FF_USE_NCCL + ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); + checkNCCL(ncclAllReduce(input.ptr, + output.ptr, + num_elements, + nccl_data_type, + ncclSum, + m->handle.ncclComm, + stream)); +#else + assert(false && "Must enable FF_USE_NCCL to use AllReduce operators"); +#endif +} + + void forward_kernel_wrapper(AllReduceMeta const *m, GenericTensorAccessorR const &input, GenericTensorAccessorW const &output) { @@ -34,6 +59,14 @@ void forward_kernel_wrapper(AllReduceMeta const *m, assert(input.domain == output.domain); size_t hidden_dim_size = input.domain.hi()[0] - input.domain.lo()[0] + 1; #ifdef FF_USE_NCCL + ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); + checkNCCL(ncclAllReduce(input.ptr, + output.ptr, + input.domain.get_volume(), + nccl_data_type, + ncclSum, + m->handle.ncclComm, + stream)); // ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); checkNCCL(ncclAllReduce(input.ptr, output.ptr, diff --git a/src/parallel_ops/kernels/allreduce_kernels.cu b/src/parallel_ops/kernels/allreduce_kernels.cu index 1e932d2b12..025d5c3ac5 100644 --- a/src/parallel_ops/kernels/allreduce_kernels.cu +++ b/src/parallel_ops/kernels/allreduce_kernels.cu @@ -24,19 +24,23 @@ AllReduceMeta::AllReduceMeta(FFHandler handle, AllReduce const *reduct) namespace Kernels { namespace AllReduce { -void forward_kernel_wrapper(AllReduceMeta const *m, - GenericTensorAccessorR const &input, - GenericTensorAccessorW const &output) { +void inference_kernel_wrapper(AllReduceMeta const *m, + BatchConfig const *bc, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &output) { + cudaStream_t stream; checkCUDA(get_legion_stream(&stream)); assert(input.data_type == output.data_type); assert(input.domain == output.domain); + size_t hidden_dim_size = input.domain.hi()[0] - input.domain.lo()[0] + 1; + size_t num_elements = bc->num_tokens * hidden_dim_size; #ifdef FF_USE_NCCL - // ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); + ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); checkNCCL(ncclAllReduce(input.ptr, output.ptr, - input.domain.get_volume(), - ncclFloat, + num_elements, + nccl_data_type, ncclSum, m->handle.ncclComm, stream)); @@ -45,6 +49,23 @@ void forward_kernel_wrapper(AllReduceMeta const *m, #endif } +void forward_kernel_wrapper(AllReduceMeta const *m, + GenericTensorAccessorR const &input, + GenericTensorAccessorW const &output) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + assert(input.data_type == output.data_type); + assert(input.domain == output.domain); +#ifdef FF_USE_NCCL + ncclDataType_t nccl_data_type = ff_to_nccl_datatype(input.data_type); + checkNCCL(ncclAllReduce(input.ptr, + output.ptr, + input.domain.get_volume(), + nccl_data_type, + ncclSum, + m->handle.ncclComm, + stream)); + void backward_kernel_wrapper(AllReduceMeta const *m, GenericTensorAccessorW const &input_grad, GenericTensorAccessorR const &output_grad) { @@ -68,6 +89,7 @@ void backward_kernel_wrapper(AllReduceMeta const *m, #endif } + } // namespace AllReduce } // namespace Kernels } // namespace FlexFlow diff --git a/src/parallel_ops/kernels/combine_kernels.cpp b/src/parallel_ops/kernels/combine_kernels.cpp index 2d748cfab3..d6e9568223 100644 --- a/src/parallel_ops/kernels/combine_kernels.cpp +++ b/src/parallel_ops/kernels/combine_kernels.cpp @@ -51,6 +51,9 @@ void backward_kernel(T const *output_grad_ptr, num_elements); } +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements); template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements); @@ -63,6 +66,9 @@ template void forward_kernel(int32_t const *input_ptr, template void forward_kernel(int64_t const *input_ptr, int64_t *output_ptr, size_t num_elements); +template void backward_kernel(half const *output_grad_ptr, + half *input_grad_ptr, + size_t num_elements); template void backward_kernel(float const *output_grad_ptr, float *input_grad_ptr, size_t num_elements); diff --git a/src/parallel_ops/kernels/combine_kernels.cu b/src/parallel_ops/kernels/combine_kernels.cu index d8f414ef0f..1ab79a7944 100644 --- a/src/parallel_ops/kernels/combine_kernels.cu +++ b/src/parallel_ops/kernels/combine_kernels.cu @@ -44,6 +44,9 @@ void backward_kernel(T const *output_grad_ptr, input_grad_ptr, output_grad_ptr, num_elements); } +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements); template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements); @@ -56,6 +59,9 @@ template void forward_kernel(int32_t const *input_ptr, template void forward_kernel(int64_t const *input_ptr, int64_t *output_ptr, size_t num_elements); +template void backward_kernel(half const *output_grad_ptr, + half *input_grad_ptr, + size_t num_elements); template void backward_kernel(float const *output_grad_ptr, float *input_grad_ptr, size_t num_elements); diff --git a/src/parallel_ops/kernels/reduction_kernels.cpp b/src/parallel_ops/kernels/reduction_kernels.cpp index 9143fee936..2a3fe5cca1 100644 --- a/src/parallel_ops/kernels/reduction_kernels.cpp +++ b/src/parallel_ops/kernels/reduction_kernels.cpp @@ -18,6 +18,10 @@ #include namespace FlexFlow { + +ReductionMeta::ReductionMeta(FFHandler handle, Reduction const *reduct) + : OpMeta(handle) {} + namespace Kernels { namespace Reduction { @@ -70,10 +74,18 @@ template __global__ void reduction_forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements, size_t num_replicas); +template __global__ void reduction_forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements, + size_t num_replicas); template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements, size_t num_replicas); +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements, + size_t num_replicas); template void backward_kernel(float const *output_grad_ptr, float *input_grad_ptr, size_t num_elements); diff --git a/src/parallel_ops/kernels/reduction_kernels.cu b/src/parallel_ops/kernels/reduction_kernels.cu index 8496a107e3..34ae8007da 100644 --- a/src/parallel_ops/kernels/reduction_kernels.cu +++ b/src/parallel_ops/kernels/reduction_kernels.cu @@ -17,6 +17,10 @@ #include "flexflow/utils/cuda_helper.h" namespace FlexFlow { + +ReductionMeta::ReductionMeta(FFHandler handle, Reduction const *reduct) + : OpMeta(handle) {} + namespace Kernels { namespace Reduction { @@ -63,10 +67,18 @@ template __global__ void reduction_forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements, size_t num_replicas); +template __global__ void reduction_forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements, + size_t num_replicas); template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements, size_t num_replicas); +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements, + size_t num_replicas); template void backward_kernel(float const *output_grad_ptr, float *input_grad_ptr, size_t num_elements); diff --git a/src/parallel_ops/kernels/replicate_kernels.cpp b/src/parallel_ops/kernels/replicate_kernels.cpp index c66995877e..10d91e3a16 100644 --- a/src/parallel_ops/kernels/replicate_kernels.cpp +++ b/src/parallel_ops/kernels/replicate_kernels.cpp @@ -18,6 +18,10 @@ #include namespace FlexFlow { + +ReplicateMeta::ReplicateMeta(FFHandler handle, Replicate const *repl) + : OpMeta(handle) {} + namespace Kernels { namespace Replicate { @@ -66,6 +70,9 @@ void backward_kernel(T const *output_grad_ptr, template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements); +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements); template __global__ void replicate_backward_kernel(float const *input_ptr, float *output_ptr, diff --git a/src/parallel_ops/kernels/replicate_kernels.cu b/src/parallel_ops/kernels/replicate_kernels.cu index 6ed4f424cf..11202323c1 100644 --- a/src/parallel_ops/kernels/replicate_kernels.cu +++ b/src/parallel_ops/kernels/replicate_kernels.cu @@ -17,6 +17,10 @@ #include "flexflow/utils/cuda_helper.h" namespace FlexFlow { + +ReplicateMeta::ReplicateMeta(FFHandler handle, Replicate const *repl) + : OpMeta(handle) {} + namespace Kernels { namespace Replicate { @@ -59,6 +63,9 @@ void backward_kernel(T const *output_grad_ptr, template void forward_kernel(float const *input_ptr, float *output_ptr, size_t num_elements); +template void forward_kernel(half const *input_ptr, + half *output_ptr, + size_t num_elements); template __global__ void replicate_backward_kernel(float const *input_ptr, float *output_ptr, diff --git a/src/parallel_ops/partition.cc b/src/parallel_ops/partition.cc index 727ffd3264..e6ab09d088 100644 --- a/src/parallel_ops/partition.cc +++ b/src/parallel_ops/partition.cc @@ -60,6 +60,9 @@ RepartitionParams Repartition::get_params() const { RepartitionParams params; params.repartition_legion_dim = this->repartition_dim; params.repartition_degree = this->repartition_degree; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -92,7 +95,7 @@ Repartition::Repartition(FFModel &model, input, params.repartition_legion_dim, params.repartition_degree, - name) {} + params.name) {} OpMeta *Repartition::init_task(Task const *task, std::vector const ®ions, @@ -101,6 +104,46 @@ OpMeta *Repartition::init_task(Task const *task, return nullptr; } +void Repartition::init_inference( + FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + parallel_is = batch_outputs[0]->parallel_is; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + IndexLauncher launcher(REPARTITION_INIT_TASK_ID, + parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + assert(inference_input_lps.find(batch_inputs[0]) != + inference_input_lps.end()); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); +} + void Repartition::init(FFModel const &ff) { ArgumentMap argmap; parallel_is = outputs[0]->parallel_is; @@ -130,6 +173,7 @@ void Repartition::init(FFModel const &ff) { } void Repartition::create_input_partition(FFModel &ff) { + assert(ff.config.computationMode == COMP_MODE_TRAINING); assert(outputs[0]->part != LogicalPartition::NO_PART); assert(inputs[0]->part != LogicalPartition::NO_PART); ff.create_disjoint_partition(outputs[0]->num_dims, @@ -144,6 +188,61 @@ void Repartition::create_input_partition(FFModel &ff) { output_grad_lp); } +void Repartition::create_input_partition_inference( + FFModel &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + assert(batch_outputs[0]->part != LogicalPartition::NO_PART); + assert(batch_inputs[0]->part != LogicalPartition::NO_PART); + ff.create_disjoint_partition(batch_outputs[0]->num_dims, + batch_outputs[0]->dims, + batch_outputs[0]->parallel_is, + batch_inputs[0]->region, + inference_input_lps[batch_inputs[0]]); +} + +FutureMap + Repartition::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + assert(batch_inputs[0]->data_type == batch_outputs[0]->data_type); + DataType data_type = batch_inputs[0]->data_type; + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + /* std::cout << "Partition op machine_view: " << *(MachineView const *)mv + << std::endl; */ + IndexLauncher launcher(REPARTITION_FWD_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(&data_type, sizeof(DataType)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); +} + void Repartition::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; diff --git a/src/parallel_ops/reduction.cc b/src/parallel_ops/reduction.cc index 737f86239c..5ca2b1301c 100644 --- a/src/parallel_ops/reduction.cc +++ b/src/parallel_ops/reduction.cc @@ -14,6 +14,7 @@ */ #include "flexflow/parallel_ops/reduction.h" +#include "flexflow/ffconst_utils.h" #include "flexflow/model.h" #include "flexflow/parallel_ops/kernels/reduction_kernels.h" #include "flexflow/utils/hash_utils.h" @@ -55,6 +56,9 @@ ReductionParams Reduction::get_params() const { ReductionParams params; params.reduction_legion_dim = this->reduction_dim; params.reduction_degree = this->reduction_degree; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -77,7 +81,7 @@ Reduction::Reduction(FFModel &model, dims[reduction_dim].size /= reduction_degree; ParallelTensorBase::update_parallel_ids(numdim, dims); outputs[0] = model.create_parallel_tensor_legion_ordering( - numdim, dims, DT_FLOAT, this); + numdim, dims, _input->data_type, this); } Reduction::Reduction(FFModel &model, @@ -88,7 +92,7 @@ Reduction::Reduction(FFModel &model, input, params.reduction_legion_dim, params.reduction_degree, - name) {} + params.name) {} void Reduction::create_input_partition(FFModel &ff) { assert(outputs[0]->part != LogicalPartition::NO_PART); @@ -108,16 +112,153 @@ void Reduction::create_input_partition(FFModel &ff) { output_grad_lp); } +void Reduction::create_input_partition_inference( + FFModel &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + assert(batch_outputs[0]->part != LogicalPartition::NO_PART); + assert(batch_inputs[0]->part != LogicalPartition::NO_PART); + // input_lp is a disjoint partition + ff.create_disjoint_partition(batch_outputs[0]->num_dims, + batch_outputs[0]->dims, + batch_outputs[0]->parallel_is, + batch_inputs[0]->region, + inference_input_lps[batch_inputs[0]]); +} + +OpMeta *Reduction::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + Reduction *reduct = (Reduction *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + ReductionMeta *meta = new ReductionMeta(handle, reduct); + meta->input_type[0] = reduct->inputs[0]->data_type; + meta->output_type[0] = reduct->outputs[0]->data_type; + assert(meta->input_type[0] == meta->output_type[0]); + return meta; +} + void Reduction::init(FFModel const &ff) { - forward(ff); + ArgumentMap argmap; + parallel_is = outputs[0]->parallel_is; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + set_argumentmap_for_init(ff, argmap); + IndexLauncher launcher(REDUCTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Reduction)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + outputs[0]->machine_view.hash()); + launcher.add_region_requirement(RegionRequirement( + input_lp, 0 /*projection id*/, READ_ONLY, EXCLUSIVE, inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +void Reduction::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + parallel_is = batch_outputs[0]->parallel_is; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(REDUCTION_INIT_TASK_ID, + parallel_is, + TaskArgument(this, sizeof(Reduction)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + assert(inference_input_lps.find(batch_inputs[0]) != + inference_input_lps.end()); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + +FutureMap Reduction::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + assert(numOutputs == 1); + assert(numInputs == 1); + assert(batch_inputs[0]->data_type == batch_outputs[0]->data_type); + DataType data_type = batch_inputs[0]->data_type; + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(REDUCTION_FWD_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); } void Reduction::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; + parallel_is = outputs[0]->parallel_is; assert(numOutputs == 1); assert(numInputs == 1); + set_argumentmap_for_forward(ff, argmap); IndexLauncher launcher(REDUCTION_FWD_TASK_ID, outputs[0]->parallel_is, TaskArgument(NULL, 0), @@ -211,6 +352,9 @@ void Reduction::forward_task(Task const *task, Runtime *runtime) { assert(regions.size() == 2); assert(task->regions.size() == 2); + + ReductionMeta const *m = *((ReductionMeta **)task->local_args); + Domain input_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); Domain output_domain = runtime->get_index_space_domain( @@ -222,12 +366,26 @@ void Reduction::forward_task(Task const *task, } size_t num_elements = output_domain.get_volume(); size_t num_replicas = input_domain.get_volume() / num_elements; - float const *input_ptr = helperGetTensorPointerRO( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - float *output_ptr = helperGetTensorPointerRW( - regions[1], task->regions[1], FID_DATA, ctx, runtime); - forward_kernel(input_ptr, output_ptr, num_elements, num_replicas); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + + assert(input.data_type == output.data_type); + if (input.data_type == DT_HALF) { + forward_kernel(input.get_half_ptr(), + output.get_half_ptr(), + num_elements, + num_replicas); + } else if (input.data_type == DT_FLOAT) { + forward_kernel(input.get_float_ptr(), + output.get_float_ptr(), + num_elements, + num_replicas); + } else { + assert(false && "Unspported data type"); + } } void Reduction::backward_task(Task const *task, diff --git a/src/parallel_ops/replicate.cc b/src/parallel_ops/replicate.cc index 322ab061e5..05ec5d6cfa 100644 --- a/src/parallel_ops/replicate.cc +++ b/src/parallel_ops/replicate.cc @@ -55,6 +55,9 @@ ReplicateParams Replicate::get_params() const { ReplicateParams params; params.replicate_legion_dim = this->replicate_dim; params.replicate_degree = this->replicate_degree; + if (this->name != nullptr) { + strcpy(params.name, this->name); + } return params; } @@ -88,7 +91,7 @@ Replicate::Replicate(FFModel &model, input, params.replicate_legion_dim, params.replicate_degree, - name) {} + params.name) {} void Replicate::create_input_partition(FFModel &ff) { assert(outputs[0]->part != LogicalPartition::NO_PART); @@ -108,16 +111,85 @@ void Replicate::create_input_partition(FFModel &ff) { output_grad_lp); } +void Replicate::create_input_partition_inference( + FFModel &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs) { + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + assert(batch_outputs[0]->part != LogicalPartition::NO_PART); + assert(batch_inputs[0]->part != LogicalPartition::NO_PART); + // input_lp is an aliased partitioning along the replica dim + ff.create_aliased_partition(batch_outputs[0]->num_dims, + batch_outputs[0]->dims, + replicate_dim, + batch_outputs[0]->parallel_is, + batch_inputs[0]->region, + inference_input_lps[batch_inputs[0]]); +} + +OpMeta *Replicate::init_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + Replicate *repl = (Replicate *)task->args; + FFHandler handle = *((FFHandler const *)task->local_args); + ReplicateMeta *meta = new ReplicateMeta(handle, repl); + meta->input_type[0] = repl->inputs[0]->data_type; + meta->output_type[0] = repl->outputs[0]->data_type; + assert(meta->input_type[0] == meta->output_type[0]); + return meta; +} + +void Replicate::init_inference(FFModel const &ff, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + parallel_is = batch_outputs[0]->parallel_is; + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + assert(numOutputs == 1); + assert(numInputs == 1); + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_init_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(REPLICATE_INIT_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(this, sizeof(Replicate)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap_inference(ff, fm, batch_outputs[0]); +} + void Replicate::init(FFModel const &ff) { - // Do nothing + parallel_is = outputs[0]->parallel_is; ArgumentMap argmap; Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; assert(numOutputs == 1); assert(numInputs == 1); + set_argumentmap_for_init(ff, argmap); IndexLauncher launcher(REPLICATE_INIT_TASK_ID, outputs[0]->parallel_is, - TaskArgument(NULL, 0), + TaskArgument(this, sizeof(Replicate)), argmap, Predicate::TRUE_PRED, false /*must*/, @@ -132,15 +204,58 @@ void Replicate::init(FFModel const &ff) { EXCLUSIVE, outputs[0]->region)); launcher.add_field(1, FID_DATA); - runtime->execute_index_space(ctx, launcher); + FutureMap fm = runtime->execute_index_space(ctx, launcher); + fm.wait_all_results(); + set_opmeta_from_futuremap(ff, fm); +} + +FutureMap Replicate::inference(FFModel const &ff, + BatchConfigFuture const &bc, + std::vector const &batch_inputs, + std::vector const &batch_outputs, + MachineView const *mv) { + ArgumentMap argmap; + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + parallel_is = batch_outputs[0]->parallel_is; + assert(numOutputs == 1); + assert(numInputs == 1); + DataType data_type = batch_inputs[0]->data_type; + size_t machine_view_hash = + mv ? mv->hash() : batch_outputs[0]->machine_view.hash(); + set_argumentmap_for_inference(ff, argmap, batch_outputs[0]); + IndexLauncher launcher(REPLICATE_FWD_TASK_ID, + batch_outputs[0]->parallel_is, + TaskArgument(NULL, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_region_requirement( + RegionRequirement(inference_input_lps[batch_inputs[0]], + 0 /*projection id*/, + READ_ONLY, + EXCLUSIVE, + batch_inputs[0]->region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement(RegionRequirement(batch_outputs[0]->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + batch_outputs[0]->region)); + launcher.add_field(1, FID_DATA); + return runtime->execute_index_space(ctx, launcher); } void Replicate::forward(FFModel const &ff) { ArgumentMap argmap; Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; + parallel_is = outputs[0]->parallel_is; assert(numOutputs == 1); assert(numInputs == 1); + set_argumentmap_for_forward(ff, argmap); DataType data_type = inputs[0]->data_type; IndexLauncher launcher(REPLICATE_FWD_TASK_ID, outputs[0]->parallel_is, @@ -240,28 +355,9 @@ void Replicate::forward_task(Task const *task, Runtime *runtime) { assert(regions.size() == 2); assert(task->regions.size() == 2); - DataType data_type = *((DataType *)task->args); - if (data_type == DT_FLOAT) { - forward_task_with_type(task, regions, ctx, runtime); - } else if (data_type == DT_DOUBLE) { - forward_task_with_type(task, regions, ctx, runtime); - } else if (data_type == DT_INT32) { - forward_task_with_type(task, regions, ctx, runtime); - } else if (data_type == DT_INT64) { - forward_task_with_type(task, regions, ctx, runtime); - } else { - assert(false && "Unsupported data type in Replicate forward"); - } -} + ReplicateMeta const *m = *((ReplicateMeta **)task->local_args); + -template -void Replicate::forward_task_with_type( - Task const *task, - std::vector const ®ions, - Context ctx, - Runtime *runtime) { - assert(regions.size() == 2); - assert(task->regions.size() == 2); Domain input_domain = runtime->get_index_space_domain( ctx, task->regions[0].region.get_index_space()); Domain output_domain = runtime->get_index_space_domain( @@ -272,12 +368,23 @@ void Replicate::forward_task_with_type( assert(output_domain.hi()[i] == input_domain.hi()[i]); } assert(input_domain.get_volume() == output_domain.get_volume()); - T const *input_ptr = helperGetTensorPointerRO( - regions[0], task->regions[0], FID_DATA, ctx, runtime); - T *output_ptr = helperGetTensorPointerRW( - regions[1], task->regions[1], FID_DATA, ctx, runtime); + GenericTensorAccessorR input = helperGetGenericTensorAccessorRO( + m->input_type[0], regions[0], task->regions[0], FID_DATA, ctx, runtime); + GenericTensorAccessorW output = helperGetGenericTensorAccessorWO( + m->output_type[0], regions[1], task->regions[1], FID_DATA, ctx, runtime); + + assert(input.data_type == output.data_type); - forward_kernel(input_ptr, output_ptr, input_domain.get_volume()); + if (input.data_type == DT_HALF) { + forward_kernel( + input.get_half_ptr(), output.get_half_ptr(), input_domain.get_volume()); + } else if (input.data_type == DT_FLOAT) { + forward_kernel(input.get_float_ptr(), + output.get_float_ptr(), + input_domain.get_volume()); + } else { + assert(false && "Unspported data type"); + } } void Replicate::backward_task(Task const *task, diff --git a/src/runtime/accessor.cc b/src/runtime/accessor.cc index 809d608402..d3b94bf14a 100644 --- a/src/runtime/accessor.cc +++ b/src/runtime/accessor.cc @@ -77,6 +77,15 @@ half const *GenericTensorAccessorR::get_half_ptr() const { } } +char const *GenericTensorAccessorR::get_byte_ptr() const { + if (data_type == DT_INT4 || data_type == DT_INT8) { + return static_cast(ptr); + } else { + assert(false && "Invalid Accessor Type"); + return static_cast(nullptr); + } +} + template TensorAccessorW::TensorAccessorW(PhysicalRegion region, RegionRequirement req, @@ -156,6 +165,15 @@ half *GenericTensorAccessorW::get_half_ptr() const { } } +char *GenericTensorAccessorW::get_byte_ptr() const { + if (data_type == DT_INT4 || data_type == DT_INT8) { + return static_cast(ptr); + } else { + assert(false && "Invalid Accessor Type"); + return static_cast(nullptr); + } +} + template const DT *helperGetTensorPointerRO(PhysicalRegion region, RegionRequirement req, @@ -261,6 +279,14 @@ GenericTensorAccessorR ptr = helperGetTensorPointerRO(region, req, fid, ctx, runtime); break; } + case DT_INT4: { + ptr = helperGetTensorPointerRO(region, req, fid, ctx, runtime); + break; + } + case DT_INT8: { + ptr = helperGetTensorPointerRO(region, req, fid, ctx, runtime); + break; + } default: { assert(false); } @@ -299,6 +325,14 @@ GenericTensorAccessorW ptr = helperGetTensorPointerWO(region, req, fid, ctx, runtime); break; } + case DT_INT4: { + ptr = helperGetTensorPointerWO(region, req, fid, ctx, runtime); + break; + } + case DT_INT8: { + ptr = helperGetTensorPointerWO(region, req, fid, ctx, runtime); + break; + } default: { assert(false); } @@ -337,6 +371,14 @@ GenericTensorAccessorW ptr = helperGetTensorPointerRW(region, req, fid, ctx, runtime); break; } + case DT_INT4: { + ptr = helperGetTensorPointerRW(region, req, fid, ctx, runtime); + break; + } + case DT_INT8: { + ptr = helperGetTensorPointerRW(region, req, fid, ctx, runtime); + break; + } default: { assert(false); } @@ -345,10 +387,14 @@ GenericTensorAccessorW } #define DIMFUNC(DIM) \ + template class TensorAccessorR; \ + template class TensorAccessorR; \ template class TensorAccessorR; \ template class TensorAccessorR; \ template class TensorAccessorR; \ template class TensorAccessorR; \ + template class TensorAccessorW; \ + template class TensorAccessorW; \ template class TensorAccessorW; \ template class TensorAccessorW; \ template class TensorAccessorW; \ @@ -371,6 +417,22 @@ template half *helperGetTensorPointerWO(PhysicalRegion region, Context ctx, Runtime *runtime); +template char const *helperGetTensorPointerRO(PhysicalRegion region, + RegionRequirement req, + FieldID fid, + Context ctx, + Runtime *runtime); +template char *helperGetTensorPointerRW(PhysicalRegion region, + RegionRequirement req, + FieldID fid, + Context ctx, + Runtime *runtime); +template char *helperGetTensorPointerWO(PhysicalRegion region, + RegionRequirement req, + FieldID fid, + Context ctx, + Runtime *runtime); + template float const *helperGetTensorPointerRO(PhysicalRegion region, RegionRequirement req, FieldID fid, diff --git a/src/runtime/batch_config.cc b/src/runtime/batch_config.cc new file mode 100644 index 0000000000..bd96dbb141 --- /dev/null +++ b/src/runtime/batch_config.cc @@ -0,0 +1,161 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/batch_config.h" +#include "flexflow/request_manager.h" +#include "legion.h" +#include +#include + +namespace FlexFlow { + +LegionRuntime::Logger::Category log_bc("BatchConfig"); +using Legion::Future; +using Legion::Memory; + +BatchConfig::BatchConfig() : num_tokens(0) { + for (int i = 0; i < MAX_NUM_REQUESTS; i++) { + requestsInfo[i].first_token_depth_in_request = 0; + requestsInfo[i].first_token_offset_in_batch = 0; + requestsInfo[i].num_tokens_in_batch = 0; + request_completed[i] = true; + } + for (int i = 0; i < MAX_NUM_TOKENS; i++) { + tokensInfo[i].abs_depth_in_request = 0; + tokensInfo[i].request_index = 0; + tokensInfo[i].token_id = 0; + } +} + +/*static*/ +BatchConfig const *BatchConfig::from_future(BatchConfigFuture const &future) { + BatchConfig const *bc = static_cast( + Future(future).get_buffer(Memory::SYSTEM_MEM)); + // Check future size + if (bc->get_mode() == INC_DECODING_MODE) { + assert(Future(future).get_untyped_size() == sizeof(BatchConfig)); + } else if (bc->get_mode() == BEAM_SEARCH_MODE) { + assert(Future(future).get_untyped_size() == sizeof(BeamSearchBatchConfig)); + } else if (bc->get_mode() == TREE_VERIFY_MODE) { + assert(Future(future).get_untyped_size() == sizeof(TreeVerifyBatchConfig)); + } else { + assert(false && "Unsupported inference mode"); + } + return bc; +} + +InferenceMode BatchConfig::get_mode() const { + return INC_DECODING_MODE; +} + +int BatchConfig::num_active_requests() const { + int num_requests = 0; + for (int i = 0; i < max_requests_per_batch(); i++) { + if (!request_completed[i]) { + num_requests++; + } + } + return num_requests; +} + +int BatchConfig::num_active_tokens() const { + return num_tokens; +} + +/*static*/ +int BatchConfig::max_requests_per_batch() { + return RequestManager::get_request_manager()->get_max_requests_per_batch(); +} + +/*static*/ +int BatchConfig::max_tokens_per_batch() { + return RequestManager::get_request_manager()->get_max_tokens_per_batch(); +} + +/*static*/ +int BatchConfig::max_verify_tokens_per_batch() { + return RequestManager::get_request_manager() + ->get_max_verify_tokens_per_batch(); +} + +/*static*/ +int BatchConfig::max_sequence_length() { + return RequestManager::get_request_manager()->get_max_sequence_length(); +} + +int BatchConfig::max_spec_tree_token_num() { + return RequestManager::get_request_manager()->get_max_spec_tree_token_num(); +} + +std::ostream &operator<<(std::ostream &os, BatchConfig const &bc) { + os << "@@@@@@@@@@@@@@ Batch Config (mode " << bc.get_mode() + << ") @@@@@@@@@@@@@@" << std::endl; + // Max values + os << "Max number of requests: " << bc.max_requests_per_batch() << std::endl; + os << "Max number of tokens: " << bc.max_tokens_per_batch() << std::endl; + os << "Max sequence length: " << bc.max_sequence_length() << std::endl; + // Current values + os << "Number of tokens: " << bc.num_active_tokens() << std::endl; + os << "Number of requests: " << bc.num_active_requests() << std::endl; + + // Per-request info + os << "Per-request info:\n"; + for (int i = 0; i < bc.max_requests_per_batch(); i++) { + if (!bc.request_completed[i]) { + os << " Request " << i << ":\n"; + os << " First token depth in request: " + << bc.requestsInfo[i].first_token_depth_in_request << std::endl; + os << " First token offset in batch: " + << bc.requestsInfo[i].first_token_offset_in_batch << std::endl; + os << " Number of tokens in batch: " + << bc.requestsInfo[i].num_tokens_in_batch << std::endl; + os << " GUID: " << bc.requestsInfo[i].request_guid << std::endl; + os << " Max sequence length: " + << bc.requestsInfo[i].max_sequence_length << std::endl; + os << " Request completed: " << bc.request_completed[i] << std::endl; + os << " Request running: " << bc.request_running[i] << std::endl; + } + } + + // Per-token info + os << "Per-token info:\n"; + for (int i = 0; i < bc.num_tokens; i++) { + os << " Token " << i << ":\n"; + os << " Absolute depth in request: " + << bc.tokensInfo[i].abs_depth_in_request << std::endl; + os << " Request index: " << bc.tokensInfo[i].request_index << std::endl; + os << " Token id: " << bc.tokensInfo[i].token_id << std::endl; + } + os << "@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@" << std::endl; + return os; +} + +void BatchConfig::print() const { + std::cout << *this << std::endl; +} + +void BatchConfig::save_to_file(std::string const &filename) const { + std::ofstream outputFile(filename); + if (outputFile.is_open()) { + outputFile << *this << std::endl; + outputFile.close(); + } else { + std::cerr << "Error: Unable to open the batch config output file: " + << filename << std::endl; + assert(false); + } +} + +}; // namespace FlexFlow diff --git a/src/runtime/beam_search_batch_config.cc b/src/runtime/beam_search_batch_config.cc new file mode 100644 index 0000000000..ff7bf1a819 --- /dev/null +++ b/src/runtime/beam_search_batch_config.cc @@ -0,0 +1,200 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/batch_config.h" +#include "flexflow/request_manager.h" +#include "legion.h" +#include +#include + +#define DEFAULT_BEAM_WIDTH 1 +#define DEFAULT_TARGET_ITERATIONS 3 + +namespace FlexFlow { + +LegionRuntime::Logger::Category log_beam_bc("BeamSearchBatchConfig"); + +BeamSearchBatchConfig::BeamSearchBatchConfig() : BatchConfig() { + this->beam_width = DEFAULT_BEAM_WIDTH; + this->target_iterations = DEFAULT_TARGET_ITERATIONS; + current_iteration = 0; +} + +BeamSearchBatchConfig::BeamSearchBatchConfig(int model_id) : BatchConfig() { + this->model_id = model_id; + std::cout << "==================\n" + << "Register Batch Config with Model " << this->model_id + << std::endl; + current_iteration = 0; +} + +BeamSearchBatchConfig::BeamSearchBatchConfig(size_t beam_width, + size_t target_iterations) + : BatchConfig() { + this->beam_width = beam_width; + this->target_iterations = target_iterations; + current_iteration = 0; +} + +BeamSearchBatchConfig::BeamSearchBatchConfig(BeamSearchBatchConfig const &other, + int model_id) + : BatchConfig() { + this->beam_width = other.beam_width; + this->target_iterations = other.target_iterations; + this->model_id = model_id; + current_iteration = 0; +} + +BeamSearchBatchConfig::~BeamSearchBatchConfig() {} + +InferenceMode BeamSearchBatchConfig::get_mode() const { + return BEAM_SEARCH_MODE; +} + +bool BeamSearchBatchConfig::done() const { + assert(current_iteration <= target_iterations); + return current_iteration == target_iterations; +} + +int BeamSearchBatchConfig::max_beam_depth_all_requests() const { + int max_depth_all_requests = 0; + for (int i = 0; i < BeamSearchBatchConfig::max_requests_per_batch(); i++) { + if (!request_completed[i] && + beamRequestsInfo[i].max_depth > max_depth_all_requests) { + /* printf("\treq %i has max_depth=%i. Increasing max_depth_all_requests " + "from %i\n", + i, + beamRequestsInfo[i].max_depth, + max_depth_all_requests); */ + max_depth_all_requests = beamRequestsInfo[i].max_depth; + } + } + assert(max_depth_all_requests <= BeamSearchBatchConfig::MAX_BEAM_DEPTH); + return max_depth_all_requests; +} + +int BeamSearchBatchConfig::get_speculative_request_num() const { + return speculative_request_num; +} + +int BeamSearchBatchConfig::current_depth_all_requests() const { + int current_depth = 0; + for (int i = 0; i < BeamSearchBatchConfig::max_requests_per_batch(); i++) { + if (!request_completed[i] && + beamRequestsInfo[i].current_depth > current_depth) { + /* printf("\treq %i has current_depth=%i. Increasing " + "current_depth_all_requests from %i\n", + i, + beamRequestsInfo[i].current_depth, + current_depth); */ + current_depth = beamRequestsInfo[i].current_depth; + } + } + assert(current_depth <= BeamSearchBatchConfig::MAX_BEAM_DEPTH + 1); + return current_depth; +} + +std::ostream &operator<<(std::ostream &os, BeamSearchBatchConfig const &bc) { + os << "@@@@@@@@@@@@@@ BeamSearchBatchConfig (mode " << bc.get_mode() + << ") @@@@@@@@@@@@@@" << std::endl; + // Max values + os << "Max number of requests: " << bc.max_requests_per_batch() << std::endl; + os << "Max number of tokens: " << bc.max_tokens_per_batch() << std::endl; + os << "Max sequence length: " << bc.max_sequence_length() << std::endl; + // Current values + os << "Number of tokens: " << bc.num_active_tokens() << std::endl; + os << "Number of requests: " << bc.num_active_requests() << std::endl; + // BeamSearch-specific + os << "Model ID: " << bc.model_id << std::endl; + os << "Max Beam Depth (all requests): " << bc.max_beam_depth_all_requests() + << std::endl; + os << "Current depth (all requests): " << bc.current_depth_all_requests() + << std::endl; + os << "Beam width: " << bc.beam_width << std::endl; + os << "Target Iterations: " << bc.target_iterations << std::endl; + os << "Current Iterations: " << bc.current_iteration << std::endl; + + os << "Per-request info:\n"; + for (int i = 0; i < bc.max_requests_per_batch(); i++) { + if (!bc.request_completed[i]) { + os << " Request " << i << ":\n"; + os << " First token depth in request: " + << bc.requestsInfo[i].first_token_depth_in_request << std::endl; + os << " First token offset in batch: " + << bc.requestsInfo[i].first_token_offset_in_batch << std::endl; + os << " Number of tokens in batch: " + << bc.requestsInfo[i].num_tokens_in_batch << std::endl; + os << " GUID: " << bc.requestsInfo[i].request_guid << std::endl; + os << " Max sequence length: " + << bc.requestsInfo[i].max_sequence_length << std::endl; + os << " Request completed: " << bc.request_completed[i] << std::endl; + os << " Request running: " << bc.request_running[i] << std::endl; + os << " Beam Search Specific: " << std::endl; + os << " beam_size: " << bc.beamRequestsInfo[i].beam_size + << std::endl; + os << " current_depth: " << bc.beamRequestsInfo[i].current_depth + << std::endl; + os << " max_depth: " << bc.beamRequestsInfo[i].max_depth + << std::endl; + os << " tokens: "; + for (int j = 0; j < bc.MAX_BEAM_WIDTH; j++) { + os << bc.beamRequestsInfo[i].tokens[j] << ", "; + } + os << std::endl; + os << " probs: "; + for (int j = 0; j < bc.MAX_BEAM_WIDTH; j++) { + os << bc.beamRequestsInfo[i].probs[j] << ", "; + } + os << std::endl; + os << " parent_id: "; + for (int j = 0; j < bc.MAX_BEAM_WIDTH; j++) { + os << bc.beamRequestsInfo[i].parent_id[j] << ", "; + } + os << std::endl; + } + } + + os << "Per-token info:\n"; + for (int i = 0; i < bc.num_tokens; i++) { + os << " Token " << i << ":\n"; + os << " Absolute depth in request: " + << bc.tokensInfo[i].abs_depth_in_request << std::endl; + os << " Request index: " << bc.tokensInfo[i].request_index << std::endl; + os << " Token id: " << bc.tokensInfo[i].token_id << std::endl; + os << " Beam Search Specific: " << std::endl; + os << " beam_size: " << bc.beamTokenInfo[i].sub_request_index + << std::endl; + } + os << "@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@" << std::endl; + return os; +} + +void BeamSearchBatchConfig::print() const { + std::cout << *this << std::endl; +} + +void BeamSearchBatchConfig::save_to_file(std::string const &filename) const { + std::ofstream outputFile(filename); + if (outputFile.is_open()) { + outputFile << *this << std::endl; + outputFile.close(); + } else { + std::cerr << "Error: Unable to open the batch config output file: " + << filename << std::endl; + assert(false); + } +} + +}; // namespace FlexFlow diff --git a/src/runtime/cuda_helper.cu b/src/runtime/cuda_helper.cu index a4a58e60fc..3903a74823 100644 --- a/src/runtime/cuda_helper.cu +++ b/src/runtime/cuda_helper.cu @@ -71,6 +71,14 @@ __global__ void copy_kernel_with_replicate(DT *dst, } } +template +__global__ void + copy_kernel_discrete(DT *dst, const DT *src, coord_t size, size_t *index) { + CUDA_KERNEL_LOOP(i, size) { + dst[i] = src[index[i]]; + } +} + template __global__ void reluBackward(DT *grad_ptr, const DT *output, size_t n) { CUDA_KERNEL_LOOP(i, n) { @@ -210,22 +218,24 @@ __host__ void updateGAS(float *para_ptr, } template -__host__ void - print_tensor(T const *ptr, size_t num_elements, char const *prefix) { - // device synchronize to make sure the data are ready - // checkCUDA(cudaDeviceSynchronize()); +__host__ void print_tensor(T const *ptr, + size_t num_elements, + char const *prefix, + int shard_id) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); T *host_ptr; checkCUDA(cudaHostAlloc(&host_ptr, sizeof(T) * num_elements, cudaHostAllocPortable | cudaHostAllocMapped)); - checkCUDA(cudaMemcpy( - host_ptr, ptr, sizeof(T) * num_elements, cudaMemcpyDeviceToHost)); - // checkCUDA(cudaDeviceSynchronize()); + checkCUDA(cudaMemcpyAsync( + host_ptr, ptr, sizeof(T) * num_elements, cudaMemcpyDeviceToHost, stream)); + cudaDeviceSynchronize(); int idx = 0; - printf("%s", prefix); + printf("%s, %d---->", prefix, shard_id); for (idx = 0; idx < num_elements; idx++) { - printf(" %.10lf", (float)host_ptr[idx]); - if (idx >= 16) { + printf(" %.20lf", (float)host_ptr[idx]); + if (idx >= 100) { break; } } @@ -234,24 +244,183 @@ __host__ void } template -__host__ void - save_tensor(T const *ptr, size_t num_elements, char const *file_name) { +__host__ void print_beam_tensor(T const *ptr, + size_t num_elements, + int skip, + int channel, + char const *prefix) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); T *host_ptr; checkCUDA(cudaHostAlloc(&host_ptr, - sizeof(T) * num_elements, + sizeof(T) * channel * skip, + cudaHostAllocPortable | cudaHostAllocMapped)); + checkCUDA(cudaMemcpyAsync(host_ptr, + ptr, + sizeof(T) * channel * skip, + cudaMemcpyDeviceToHost, + stream)); + // checkCUDA(cudaDeviceSynchronize()); + int idx = 0; + printf("%s", prefix); + + for (int i = 0; i < channel; i += 1) { + for (idx = 0; idx < num_elements; idx++) { + printf(" %.20lf", (float)host_ptr[idx + i * skip]); + if (idx >= 100) { + break; + } + } + printf("\n-----***********------\n"); + } + + checkCUDA(cudaFreeHost(host_ptr)); +} + +template <> +__host__ void + save_tensor(float const *ptr, size_t num_elements, char const *file_name) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + float *host_ptr; + checkCUDA(cudaHostAlloc(&host_ptr, + sizeof(float) * num_elements, + cudaHostAllocPortable | cudaHostAllocMapped)); + checkCUDA(cudaMemcpyAsync(host_ptr, + ptr, + sizeof(float) * num_elements, + cudaMemcpyDeviceToHost, + stream)); + checkCUDA(cudaDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%.9f, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%.9f", host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(cudaFreeHost(host_ptr)); +} + +template <> +__host__ void + save_tensor(half const *ptr, size_t num_elements, char const *file_name) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + half *host_ptr; + checkCUDA(cudaHostAlloc(&host_ptr, + sizeof(half) * num_elements, + cudaHostAllocPortable | cudaHostAllocMapped)); + checkCUDA(cudaMemcpyAsync(host_ptr, + ptr, + sizeof(half) * num_elements, + cudaMemcpyDeviceToHost, + stream)); + checkCUDA(cudaDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%.9f, ", (float)host_ptr[i]); + } else { + fprintf(tensor_file, "%.9f", (float)host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(cudaFreeHost(host_ptr)); +} + +template <> +__host__ void save_tensor(int32_t const *ptr, + size_t num_elements, + char const *file_name) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + int32_t *host_ptr; + checkCUDA(cudaHostAlloc(&host_ptr, + sizeof(int32_t) * num_elements, cudaHostAllocPortable | cudaHostAllocMapped)); - checkCUDA(cudaMemcpy( - host_ptr, ptr, sizeof(T) * num_elements, cudaMemcpyDeviceToHost)); + checkCUDA(cudaMemcpyAsync(host_ptr, + ptr, + sizeof(int32_t) * num_elements, + cudaMemcpyDeviceToHost, + stream)); + checkCUDA(cudaDeviceSynchronize()); FILE *tensor_file; tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); for (unsigned i = 0; i < num_elements; i++) { - fprintf(tensor_file, "%.8f, ", (float)host_ptr[i]); + if (i < num_elements - 1) { + fprintf(tensor_file, "%d, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%d", host_ptr[i]); + } } fclose(tensor_file); checkCUDA(cudaFreeHost(host_ptr)); } +template <> +__host__ void save_tensor(int64_t const *ptr, + size_t num_elements, + char const *file_name) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + int64_t *host_ptr; + checkCUDA(cudaHostAlloc(&host_ptr, + sizeof(int64_t) * num_elements, + cudaHostAllocPortable | cudaHostAllocMapped)); + checkCUDA(cudaMemcpyAsync(host_ptr, + ptr, + sizeof(int64_t) * num_elements, + cudaMemcpyDeviceToHost, + stream)); + checkCUDA(cudaDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%ld, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%ld", host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(cudaFreeHost(host_ptr)); +} + +template +__host__ T *download_tensor(T const *ptr, size_t num_elements) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + T *host_ptr; + checkCUDA(cudaHostAlloc(&host_ptr, + sizeof(T) * num_elements, + cudaHostAllocPortable | cudaHostAllocMapped)); + checkCUDA(cudaMemcpyAsync( + host_ptr, ptr, sizeof(T) * num_elements, cudaMemcpyDeviceToHost, stream)); + return host_ptr; +} + +template +__host__ bool download_tensor(T const *ptr, T *dst, size_t num_elements) { + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + assert(dst != nullptr); + checkCUDA(cudaMemcpyAsync( + dst, ptr, sizeof(T) * num_elements, cudaMemcpyDeviceToHost, stream)); + return true; +} cudnnStatus_t cudnnSetTensorDescriptorFromDomain4SoftMax( cudnnTensorDescriptor_t tensor, Domain domain, DataType data_type) { int dims[MAX_TENSOR_DIM]; @@ -304,21 +473,23 @@ cudnnStatus_t cudnnSetTensorDescriptorFromDomain4SoftMax( } cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, - Domain domain) { + Domain domain, + DataType data_type) { int dims[MAX_TENSOR_DIM]; + cudnnDataType_t cudnn_data_type = ff_to_cudnn_datatype(data_type); switch (domain.get_dim()) { case 1: { Rect<1> rect = domain; dims[0] = rect.hi[0] - rect.lo[0] + 1; return cudnnSetTensor4dDescriptor( - tensor, CUDNN_TENSOR_NCHW, CUDNN_DATA_FLOAT, dims[0], 1, 1, 1); + tensor, CUDNN_TENSOR_NCHW, cudnn_data_type, dims[0], 1, 1, 1); } case 2: { Rect<2> rect = domain; dims[0] = rect.hi[0] - rect.lo[0] + 1; dims[1] = rect.hi[1] - rect.lo[1] + 1; return cudnnSetTensor4dDescriptor( - tensor, CUDNN_TENSOR_NCHW, CUDNN_DATA_FLOAT, dims[1], dims[0], 1, 1); + tensor, CUDNN_TENSOR_NCHW, cudnn_data_type, dims[1], dims[0], 1, 1); } case 3: { Rect<3> rect = domain; @@ -327,7 +498,7 @@ cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, dims[2] = rect.hi[2] - rect.lo[2] + 1; return cudnnSetTensor4dDescriptor(tensor, CUDNN_TENSOR_NCHW, - CUDNN_DATA_FLOAT, + cudnn_data_type, dims[2], dims[1], dims[0], @@ -341,7 +512,7 @@ cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, dims[3] = rect.hi[3] - rect.lo[3] + 1; return cudnnSetTensor4dDescriptor(tensor, CUDNN_TENSOR_NCHW, - CUDNN_DATA_FLOAT, + cudnn_data_type, dims[3], dims[2], dims[1], @@ -357,7 +528,7 @@ cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, dims[3] = rect.hi[3] - rect.lo[3] + 1; return cudnnSetTensor4dDescriptor(tensor, CUDNN_TENSOR_NCHW, - CUDNN_DATA_FLOAT, + cudnn_data_type, dims[3], dims[2], dims[1], @@ -371,6 +542,8 @@ cudnnStatus_t cudnnSetTensorDescriptorFromDomain(cudnnTensorDescriptor_t tensor, cudnnDataType_t ff_to_cudnn_datatype(DataType type) { switch (type) { + case DT_HALF: + return CUDNN_DATA_HALF; case DT_FLOAT: return CUDNN_DATA_FLOAT; case DT_DOUBLE: @@ -385,6 +558,8 @@ cudnnDataType_t ff_to_cudnn_datatype(DataType type) { cudaDataType_t ff_to_cuda_datatype(DataType type) { switch (type) { + case DT_HALF: + return CUDA_R_16F; case DT_FLOAT: return CUDA_R_32F; case DT_DOUBLE: @@ -397,6 +572,52 @@ cudaDataType_t ff_to_cuda_datatype(DataType type) { return CUDA_R_32F; } +#ifdef FF_USE_NCCL +ncclDataType_t ff_to_nccl_datatype(DataType type) { + switch (type) { + case DT_HALF: + return ncclHalf; + case DT_FLOAT: + return ncclFloat; + case DT_DOUBLE: + return ncclDouble; + case DT_INT32: + return ncclInt; + default: + assert(false && "Unspoorted nccl data type"); + } + return ncclFloat; +} +#endif + +cudaDataType_t cudnn_to_cuda_datatype(cudnnDataType_t type) { + switch (type) { + case CUDNN_DATA_FLOAT: + return CUDA_R_32F; + case CUDNN_DATA_DOUBLE: + return CUDA_R_64F; + case CUDNN_DATA_INT32: + return CUDA_R_32I; + default: + assert(false && "Unsupported cuda data type"); + } + return CUDA_R_32F; +} + +cudnnDataType_t cuda_to_cudnn_datatype(cudaDataType_t type) { + switch (type) { + case CUDA_R_32F: + return CUDNN_DATA_FLOAT; + case CUDA_R_64F: + return CUDNN_DATA_DOUBLE; + case CUDA_R_32I: + return CUDNN_DATA_INT32; + default: + assert(false && "Unsupported cudnn data type"); + } + return CUDNN_DATA_FLOAT; +} + template __global__ void assign_kernel(half *ptr, coord_t size, half value); template __global__ void @@ -408,6 +629,8 @@ template __global__ void template __global__ void assign_kernel(int64_t *ptr, coord_t size, int64_t value); +template __global__ void + add_kernel(half *dst, half const *src, size_t size); template __global__ void add_kernel(float *dst, float const *src, size_t size); template __global__ void @@ -417,6 +640,8 @@ template __global__ void template __global__ void add_kernel(int64_t *dst, int64_t const *src, size_t size); +template __global__ void + copy_kernel(half *dst, half const *src, coord_t size); template __global__ void copy_kernel(float *dst, float const *src, coord_t size); template __global__ void copy_kernel_with_replicate(float *dst, @@ -427,11 +652,22 @@ template __global__ void copy_kernel_with_replicate( int32_t *dst, int32_t const *src, coord_t origin_size, coord_t size); template __global__ void copy_kernel_with_replicate( int64_t *dst, int64_t const *src, coord_t origin_size, coord_t size); +template __global__ void + copy_kernel(double *dst, double const *src, coord_t size); template __global__ void copy_kernel(int32_t *dst, int32_t const *src, coord_t size); template __global__ void copy_kernel(int64_t *dst, int64_t const *src, coord_t size); +template __global__ void copy_kernel_discrete(float *dst, + float const *src, + coord_t size, + size_t *index); +template __global__ void copy_kernel_discrete(int64_t *dst, + int64_t const *src, + coord_t size, + size_t *index); + template __global__ void apply_add_with_scale(float *data_ptr, float const *grad_ptr, size_t size, @@ -449,16 +685,74 @@ template __global__ void apply_add_with_scale(int64_t *data_ptr, size_t size, int64_t scale); -template __host__ void - print_tensor(float const *ptr, size_t rect, char const *prefix); -template __host__ void - print_tensor(double const *ptr, size_t rect, char const *prefix); -template __host__ void - print_tensor(int32_t const *ptr, size_t rect, char const *prefix); -template __host__ void - print_tensor(int64_t const *ptr, size_t rect, char const *prefix); +template __host__ void print_tensor(float const *ptr, + size_t rect, + char const *prefix, + int shard_id); +template __host__ void print_tensor(double const *ptr, + size_t rect, + char const *prefix, + int shard_id); +template __host__ void print_tensor(int32_t const *ptr, + size_t rect, + char const *prefix, + int shard_id); +template __host__ void print_tensor(int64_t const *ptr, + size_t rect, + char const *prefix, + int shard_id); +template __host__ void print_tensor(half const *ptr, + size_t rect, + char const *prefix, + int shard_id); + +template __host__ void print_beam_tensor(float const *ptr, + size_t num_elements, + int skip, + int channel, + char const *prefix); +template __host__ void print_beam_tensor(int32_t const *ptr, + size_t num_elements, + int skip, + int channel, + char const *prefix); +template __host__ void print_beam_tensor(int64_t const *ptr, + size_t num_elements, + int skip, + int channel, + char const *prefix); + template __host__ void save_tensor(float const *ptr, size_t rect, char const *file_name); template __host__ void save_tensor(int32_t const *ptr, size_t rect, char const *file_name); +template __host__ void save_tensor(int64_t const *ptr, + size_t rect, + char const *file_name); +template __host__ void + save_tensor(half const *ptr, size_t rect, char const *file_name); + +template __host__ float *download_tensor(float const *ptr, + size_t num_elements); +template __host__ half *download_tensor(half const *ptr, + size_t num_elements); +template __host__ double *download_tensor(double const *ptr, + size_t num_elements); +template __host__ int32_t *download_tensor(int32_t const *ptr, + size_t num_elements); +template __host__ int64_t *download_tensor(int64_t const *ptr, + size_t num_elements); +template __host__ bool + download_tensor(float const *ptr, float *dst, size_t num_elements); +template __host__ bool + download_tensor(half const *ptr, half *dst, size_t num_elements); +template __host__ bool download_tensor(double const *ptr, + double *dst, + size_t num_elements); +template __host__ bool download_tensor(int32_t const *ptr, + int32_t *dst, + size_t num_elements); +template __host__ bool download_tensor(int64_t const *ptr, + int64_t *dst, + size_t num_elements); diff --git a/src/runtime/ffconst_utils.cc b/src/runtime/ffconst_utils.cc index e2debfa2d5..257bc2fcdf 100644 --- a/src/runtime/ffconst_utils.cc +++ b/src/runtime/ffconst_utils.cc @@ -1,4 +1,5 @@ #include "flexflow/ffconst_utils.h" +#include "flexflow/accessor.h" #include namespace FlexFlow { @@ -45,6 +46,8 @@ std::string get_operator_type_name(OperatorType type) { return "Split"; case OP_EMBEDDING: return "Embedding"; + case OP_EXPERTS: + return "Experts"; case OP_GATHER: return "Gather"; case OP_GROUP_BY: @@ -111,6 +114,10 @@ std::string get_operator_type_name(OperatorType type) { return "Size"; case OP_TOPK: return "TopK"; + case OP_ARG_TOPK: + return "ArgTopK"; + case OP_BEAM_TOPK: + return "BeamTopK"; case OP_WHERE: return "Where"; case OP_CEIL: @@ -141,6 +148,12 @@ std::string get_operator_type_name(OperatorType type) { return "PReLU"; case OP_MULTIHEAD_ATTENTION: return "MultiHeadAttention"; + case OP_INC_MULTIHEAD_SELF_ATTENTION: + return "IncMultiHeadSelfAttention"; + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: + return "SpecIncMultiHeadSelfAttention"; + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: + return "TreeIncMultiHeadSelfAttention"; case OP_INPUT: return "Input"; case OP_WEIGHT: @@ -157,8 +170,24 @@ std::string get_operator_type_name(OperatorType type) { return "Mean"; case OP_LAYERNORM: return "LayerNorm"; + case OP_RESIDUAL_LAYERNORM: + return "ResidualLayerNorm"; + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: + return "AddBiasResidualLayerNorm"; + case OP_SIGMOID_SILU_MULTI: + return "SigmoidSiluMulti"; + case OP_RMS_NORM: + return "RMSNorm"; + case OP_RESIDUAL_RMS_NORM: + return "ResidualRMSNorm"; + case OP_GELU: + return "GELU"; case OP_IDENTITY: return "Identity"; + case OP_SAMPLING: + return "Sampling"; + case OP_ARGMAX: + return "ArgMax"; // Parallel Ops case OP_REPARTITION: return "Repartition"; @@ -182,6 +211,34 @@ std::string get_operator_type_name(OperatorType type) { } } +size_t data_type_size(DataType type) { + switch (type) { + case DT_HALF: + return sizeof(half); + case DT_FLOAT: + return sizeof(float); + case DT_DOUBLE: + return sizeof(double); + case DT_INT32: + return sizeof(int32_t); + case DT_INT64: + return sizeof(int64_t); + case DT_BOOLEAN: + return sizeof(bool); + default: + assert(false); + } +} + +size_t get_quantization_to_byte_size(DataType type, + DataType quantization_type, + size_t num_elements) { + assert(quantization_type == DT_INT4 || quantization_type == DT_INT8); + return (num_elements / (quantization_type == DT_INT4 ? 2 : 1)) + + (num_elements / INT4_NUM_OF_ELEMENTS_PER_GROUP) * 2 * + data_type_size(type); +} + std::ostream &operator<<(std::ostream &s, OperatorType op_type) { s << get_operator_type_name(op_type); diff --git a/src/runtime/fftype.cc b/src/runtime/fftype.cc index 91e0d077c4..819e6527e5 100644 --- a/src/runtime/fftype.cc +++ b/src/runtime/fftype.cc @@ -1,20 +1,33 @@ #include "flexflow/fftype.h" +#include "flexflow/config.h" #include namespace FlexFlow { -LayerID::LayerID() : id(0) {} +const LayerID LayerID::NO_ID = LayerID(); -LayerID::LayerID(size_t _id) : id(_id) { +LayerID::LayerID() + : id(0), transformer_layer_id(MAX_NUM_TRANSFORMER_LAYERS), model_id(0) {} + +LayerID::LayerID(size_t _id, size_t _transformer_layer_id, size_t _model_id) + : id(_id), transformer_layer_id(_transformer_layer_id), + model_id(_model_id) { assert(is_valid_id()); } bool LayerID::is_valid_id() const { - return (id >= LAYER_GUID_FIRST_VALID && id <= LAYER_GUID_LAST_VALID); + return (id >= LAYER_GUID_FIRST_VALID && id <= LAYER_GUID_LAST_VALID && + transformer_layer_id >= 0 && + transformer_layer_id < MAX_NUM_TRANSFORMER_LAYERS && model_id >= 0); } bool operator==(LayerID const &lhs, LayerID const &rhs) { + // id should be sufficient to distinguish different layers + if (lhs.id == rhs.id) { + assert(lhs.transformer_layer_id == rhs.transformer_layer_id); + assert(lhs.model_id == rhs.model_id); + } return lhs.id == rhs.id; } -}; // namespace FlexFlow \ No newline at end of file +}; // namespace FlexFlow diff --git a/src/runtime/file_loader.cc b/src/runtime/file_loader.cc new file mode 100644 index 0000000000..43ce9d7005 --- /dev/null +++ b/src/runtime/file_loader.cc @@ -0,0 +1,829 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/utils/file_loader.h" +#include "flexflow/ffconst_utils.h" +#include "flexflow/inference.h" + +#include +using namespace std; + +using namespace Legion; + +FileDataLoader::FileDataLoader(std::string _prompts_filepath, + std::string _weights_folder, + int _num_heads, + int _num_kv_heads, + size_t _hidden_dim, + size_t _qkv_inner_dim, + int _tensor_parallelism_degree, + bool _use_full_precision) + : prompts_filepath(_prompts_filepath), weights_folder(_weights_folder), + num_heads(_num_heads), num_kv_heads(_num_kv_heads), + hidden_dim(_hidden_dim), qkv_inner_dim(_qkv_inner_dim), + tensor_parallelism_degree(_tensor_parallelism_degree), + use_full_precision(_use_full_precision){}; + +BatchConfig::TokenId *FileDataLoader::generate_requests(int num, int length) { + + BatchConfig::TokenId *prompts = + (BatchConfig::TokenId *)malloc(sizeof(BatchConfig::TokenId) * 40); + std::ifstream in(prompts_filepath, std::ios::in | std::ios::binary); + int size = num * length; + std::vector host_array(size); + size_t loaded_data_size = sizeof(long) * size; + + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + + size_t in_get_size = in.gcount(); + if (in_get_size != loaded_data_size) { + std::cout << "load data error" << std::endl; + return prompts; + } + + assert(size == host_array.size()); + int index = 0; + int data_index = 0; + + for (auto v : host_array) { + prompts[data_index++] = v; + } + in.close(); + return prompts; +}; + +std::string removeGuidOperatorName(std::string const &input) { + // Find the last underscore in the string + size_t underscorePos = input.find_last_of('_'); + + if (underscorePos != std::string::npos) { + // Remove the underscore and the characters after it + return input.substr(0, underscorePos); + } else { + // No underscore found, return the original string + return input; + } +} + +template +void load_attention_weights_multi_query(DT *ptr, + std::string layer_name, + std::string weights_folder, + size_t hidden_dim, + int num_heads) { + + std::string qkv_file = layer_name.substr(0, layer_name.find("attention")) + + "attention_query_key_value_weight"; + std::string o_file = layer_name.substr(0, layer_name.find("attention")) + + "attention_dense_weight"; + + // q has n_heads heads, k and v only have one head, o have n_head heads + std::vector weight_filenames = {qkv_file, o_file}; + int file_index = 0; + int data_index = 0; + for (auto filename : weight_filenames) { + std::cout << "Loading weight file " << filename << std::endl; + std::string weight_filepath = join_path({weights_folder, filename}); + size_t partial_size = + file_index == 0 ? (hidden_dim + 2 * hidden_dim / num_heads) * hidden_dim + : hidden_dim * hidden_dim; + + std::ifstream in(weight_filepath, std::ios::in | std::ios::binary); + // std::cout << "Loading filename: " << weight_filepath << std::endl; + if (!in.good()) { + std::cout << "Could not open file: " << weight_filepath << std::endl; + } + assert(in.good() && "incorrect weight file path"); + std::vector
host_array(partial_size); + size_t loaded_data_size = sizeof(DT) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load data error " << in_get_size << ", " + << loaded_data_size; + assert(false && "data size mismatch"); + } + for (int i = 0; i < partial_size; i++) { + ptr[data_index++] = host_array.at(i); + } + file_index++; + } +} + +template +void load_attention_bias_v2(DT *ptr, + int num_heads, + int num_kv_heads, + size_t hidden_dim, + size_t qkv_inner_dim, + bool final_bias, + std::string layer_name, + std::string weights_folder) { + std::string q_file = layer_name + "_wq_bias"; + std::string k_file = layer_name + "_wk_bias"; + std::string v_file = layer_name + "_wv_bias"; + std::vector bias_files = {q_file, k_file, v_file}; + if (final_bias) { + std::string o_file = layer_name + "_wo_bias"; + bias_files.push_back(o_file); + } + + int file_index = 0; + + // now only opt use this. + // assert(num_heads == num_kv_heads); + int idx = 0; + + for (auto filename : bias_files) { + std::cout << "Loading weight file " << filename << std::endl; + std::string weight_filepath = join_path({weights_folder, filename}); + + int n_heads = file_index == 0 ? num_heads : num_kv_heads; + + int replicate_num = num_heads / num_kv_heads; + + size_t qkv_partial_size = qkv_inner_dim * n_heads; + size_t qkv_replicate_size = qkv_inner_dim * num_heads; + size_t out_partial_size = hidden_dim; + size_t partial_size = + (file_index < 3) ? qkv_partial_size : out_partial_size; + std::ifstream in(weight_filepath, std::ios::in | std::ios::binary); + assert(in.good() && "incorrect bias file path"); + std::vector
host_array(partial_size); + size_t loaded_data_size = sizeof(DT) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + printf( + "load bias data error: in_get_size (%lu) != loaded_data_size (%lu)\n", + in_get_size, + loaded_data_size); + assert(false); + } + assert(partial_size == host_array.size()); + + size_t data_index = 0; + + // q, o + if (file_index == 0 || file_index == 3) { + for (int i = 0; i < partial_size; i++) { + ptr[idx + i] = host_array.at(data_index); + data_index++; + } + } else { + // k, v + for (int i = 0; i < partial_size; i++) { + for (int j = 0; j < replicate_num; j++) { + ptr[idx + j * partial_size + i] = host_array.at(data_index); + } + data_index++; + } + } + + file_index++; + idx += qkv_replicate_size; + + in.close(); + } +} + +template +void load_attention_weights_v2(DT *ptr, + int num_heads, + int num_kv_heads, + size_t hidden_dim, + size_t qkv_inner_dim, + std::string layer_name, + std::string weights_folder, + size_t volume, + int tensor_parallelism_degree) { + // layers_0_attention_wq_weight + // layers_0_self_attn_q_proj_weight + std::string q_file = layer_name + "_wq_weight"; + std::string k_file = layer_name + "_wk_weight"; + std::string v_file = layer_name + "_wv_weight"; + std::string o_file = layer_name + "_wo_weight"; + std::vector weight_filenames = {q_file, k_file, v_file}; + int file_index = 0; + + int base_index = 0; + size_t single_proj_size = + hidden_dim * + qkv_inner_dim; // size of each of Q,K,V,O weights for a single head + size_t one_weight_file_size = + num_heads * single_proj_size; // size of each of Q/K/V/O for all heads + + size_t q_size = one_weight_file_size, o_size = one_weight_file_size; + size_t k_size = single_proj_size * num_kv_heads, + v_size = single_proj_size * num_kv_heads; + + size_t k_replicate_size = one_weight_file_size; + size_t v_replicate_size = one_weight_file_size; + + int replicate_num = num_heads / num_kv_heads; + + // stride for q, k, v, o + size_t stride_size = (q_size + v_replicate_size + k_replicate_size + o_size) / + tensor_parallelism_degree; + for (auto filename : weight_filenames) { + std::cout << "Loading weight file " << filename << std::endl; + std::string weight_filepath = join_path({weights_folder, filename}); + + int data_index = 0; + size_t partial_size = (file_index == 0 || file_index == 3) + ? one_weight_file_size + : single_proj_size * num_kv_heads; + size_t one_partition_size = + one_weight_file_size / tensor_parallelism_degree; + + std::ifstream in(weight_filepath, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << weight_filepath << std::endl; + } + assert(in.good() && "incorrect weight file path"); + std::vector
host_array(partial_size); + size_t loaded_data_size = sizeof(DT) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load attention data error " << in_get_size << ", " + << loaded_data_size << ", " << file_index << ", " + << weight_filepath << "\n"; + assert(false && "data size mismatch"); + } + // wq, wk, wo + if (file_index == 0) { + for (int i = 0; i < tensor_parallelism_degree; i++) { + for (int j = 0; j < one_partition_size; j++) { + ptr[base_index + i * stride_size + j] = host_array.at(data_index++); + } + } + } else { + for (int i = 0; i < num_heads; i++) { + int kv_idx = i / (num_heads / num_kv_heads); + int head_idx = i % (num_heads / tensor_parallelism_degree); + int tp_idx = (i / (num_heads / tensor_parallelism_degree)); + for (int j = 0; j < single_proj_size; j++) { + ptr[base_index + tp_idx * stride_size + single_proj_size * head_idx + + j] = host_array.at(kv_idx * single_proj_size + j); + } + } + } + + // assert(data_index == partial_size); + base_index += one_partition_size; + file_index++; + } + assert(base_index == (q_size + k_replicate_size + v_replicate_size) / + tensor_parallelism_degree); + + { + std::cout << "Loading weight file " << o_file << std::endl; + std::string weight_filepath = join_path({weights_folder, o_file}); + + std::ifstream in(weight_filepath, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << weight_filepath << std::endl; + } + assert(in.good() && "incorrect weight file path"); + std::vector
host_array(one_weight_file_size); + size_t loaded_data_size = sizeof(DT) * one_weight_file_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load data error" << std::endl; + assert(false); + } + assert(one_weight_file_size == host_array.size()); + int data_index = 0; + + int one_partition_size = + qkv_inner_dim * (num_heads / tensor_parallelism_degree); + for (int i = 0; i < one_weight_file_size; i++) { + int part_idx = (i / one_partition_size) % tensor_parallelism_degree; + int block_num = (i / one_partition_size); + int offset = block_num / tensor_parallelism_degree * one_partition_size + + (i % one_partition_size); + ptr[base_index + part_idx * stride_size + offset] = + host_array.at(data_index++); + } + + in.close(); + + assert(data_index == one_weight_file_size); + } +} + +template +void load_from_file(DT *ptr, size_t size, std::string filepath) { + std::ifstream in(filepath, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << filepath << std::endl; + } + assert(in.good() && "incorrect weight file path"); + std::vector
host_array(size); + size_t loaded_data_size = sizeof(DT) * size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + + size_t in_get_size = in.gcount(); + if (in_get_size != loaded_data_size) { + std::cout << "load weight data error " << in_get_size << ", " + << loaded_data_size << ", " << sizeof(DT) << std::endl; + assert(false); + } + assert(size == host_array.size()); + + // normal + long data_index = 0; + for (auto v : host_array) { + ptr[data_index++] = v; + } + in.close(); +} + +void FileDataLoader::load_positions(FFModel *ff, + Tensor pt, + ParallelTensor position_pt, + int max_seq_length, + int offset) { + size_t volume = 1; + std::vector dims_vec; + for (int i = 0; i < pt->num_dims; i++) { + volume *= pt->dims[i]; + dims_vec.push_back(pt->dims[i]); + } + + // load data; + int *data = (int *)malloc(sizeof(int) * volume); + for (int i = 0; i < volume; i++) { + data[i] = i % max_seq_length + offset; + } + // set tensor + + // ParallelTensor position_pt; + + // ff->get_parallel_tensor_from_tensor(pt, position_pt); + position_pt->set_tensor(ff, dims_vec, data); +} + +//--------------------- quantization functions ---------------------- +// the data layout is 32 * quantized data + 1 scaling factor + 1 offset factor +// in the decompression mode, the real data = quantized data * scaling factor + +// offset + +void load_attention_weights_quantized(char *ptr, + int num_heads, + size_t hidden_dim, + size_t qkv_inner_dim, + std::string layer_name, + std::string weights_folder, + DataType data_type, + bool use_full_precision) { + // layers_0_attention_wq_weight + // layers_0_self_attn_q_proj_weight + std::string q_file = layer_name + "_wq_weight"; + std::string k_file = layer_name + "_wk_weight"; + std::string v_file = layer_name + "_wv_weight"; + std::string o_file = layer_name + "_wo_weight"; + std::vector weight_filenames = {q_file, k_file, v_file, o_file}; + + int file_index = 0; + + size_t single_proj_size = + hidden_dim * + qkv_inner_dim; // size of each of Q,K,V,O weights for a single head + size_t one_weight_file_size = + num_heads * single_proj_size; // size of each of Q/K/V/O for all heads + + // q, k, v, o -> 0, 1, 2, 3 + for (auto filename : weight_filenames) { + std::cout << "Loading weight file " << filename << std::endl; + std::string weight_filepath = join_path({weights_folder, filename}); + + size_t partial_size = one_weight_file_size; + std::ifstream in(weight_filepath, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << weight_filepath << std::endl; + } + assert(in.good() && "incorrect weight file path"); + std::vector host_array(partial_size); + size_t loaded_data_size = sizeof(char) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load data error"; + return; + } + assert(partial_size == host_array.size()); + + size_t one_head_size = data_type == DT_INT8 + ? hidden_dim * (hidden_dim / num_heads) + : hidden_dim * (hidden_dim / num_heads) / 2; + + size_t data_index = 0; + for (int i = 0; i < num_heads; i++) { + size_t start_index = i * one_head_size * 4 + file_index * one_head_size; + for (size_t j = start_index; j < start_index + one_head_size; j++) { + if (data_type == DT_INT4) { + char v1 = host_array.at(data_index); + char v2 = host_array.at(data_index + 1); + ptr[j] = (v2 & 0XF) | (v1 << 4); + data_index += 2; + } else { + ptr[j] = host_array.at(data_index); + data_index += 1; + } + } + } + file_index++; + in.close(); + } + + // load scale and offset to the end of weight tensor + // the layout is like |values * 32 heads|offset|scale| + size_t offset = data_type == DT_INT8 ? one_weight_file_size * 4 + : (one_weight_file_size * 4) / 2; + for (auto filename : weight_filenames) { + std::cout << "Loading weight file " << filename << std::endl; + std::string weight_filepath = join_path({weights_folder, filename}); + + for (int i = 0; i < 2; i++) { + std::string meta_file = + i == 0 ? (weight_filepath + "_offset") : (weight_filepath + "_scale"); + size_t partial_size = + one_weight_file_size / INT4_NUM_OF_ELEMENTS_PER_GROUP; + std::ifstream in(meta_file, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << meta_file << std::endl; + } + assert(in.good() && "incorrect weight file path"); + + if (use_full_precision) { + // float + std::vector host_array(partial_size); + size_t loaded_data_size = sizeof(float) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load data error"; + return; + } + assert(partial_size == host_array.size()); + + for (auto v : host_array) { + *(float *)(ptr + offset) = v; + offset += sizeof(float); + } + } else { + // half + std::vector host_array(partial_size); + size_t loaded_data_size = sizeof(half) * partial_size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + size_t in_get_size = in.gcount(); + + if (in_get_size != loaded_data_size) { + std::cout << "load data error"; + return; + } + assert(partial_size == host_array.size()); + for (auto v : host_array) { + *(half *)(ptr + offset) = v; + offset += sizeof(half); + } + } + } + } +} + +void load_from_quantized_file(char *ptr, + size_t size, + std::string filename, + DataType data_type, + bool use_full_precision) { + assert(data_type == DT_INT4 || data_type == DT_INT8); + + std::string value_file = filename; + std::string offset_file = filename + "_offset"; + std::string scaling_file = filename + "_scale"; + size_t value_size = 0, offset_size = 0, scaling_size = 0; + + if (data_type == DT_INT4) { + // float/half + 4bit quantization + // size1 = volume / 2, size2 = volume / 32 * (sizeof(DT)), size3 = size2 + value_size = 2 * (use_full_precision ? (size * 2 / 3) : (size * 4 / 5)); + offset_size = use_full_precision ? (size / 6) : (size / 10); + scaling_size = use_full_precision ? (size / 6) : (size / 10); + } else if (data_type == DT_INT8) { + // float/half + 8bit quantization + // size1 = volume * 1, size2 = volume / 32 * (sizeof(DT)), size3 = size2 + value_size = use_full_precision ? (size * 4 / 5) : (size * 8 / 9); + offset_size = use_full_precision ? (size / 10) : (size / 18); + scaling_size = use_full_precision ? (size / 10) : (size / 18); + } + + std::vector quantized_files = { + value_file, offset_file, scaling_file}; + std::vector quantized_sizes = {value_size, offset_size, scaling_size}; + + int file_idx = 0; + long data_index = 0; + for (auto file : quantized_files) { + std::ifstream in(file, std::ios::in | std::ios::binary); + if (!in.good()) { + std::cout << "Could not open file: " << file << std::endl; + } + assert(in.good() && "incorrect weight file path"); + + // value file, every element is in one byte + if (file_idx == 0) { + size = quantized_sizes.at(file_idx); + std::vector host_array(size); + size_t loaded_data_size = size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + + size_t in_get_size = in.gcount(); + if (in_get_size != loaded_data_size) { + std::cout << "load weight data error quantized" << in_get_size << ", " + << loaded_data_size << ", " << sizeof(char) << std::endl; + return; + } + assert(size == host_array.size()); + + // normal + size_t idx = 0; + while (idx < host_array.size()) { + if (data_type == DT_INT4) { + // pack 2 elements into one byte + char v1 = host_array.at(idx); + char v2 = host_array.at(idx + 1); + // v1 in first 4 bit and v2 in last 4 bit; + ptr[data_index++] = (v2 & 0XF) | (v1 << 4); + idx += 2; + } else { + ptr[data_index++] = host_array.at(idx++); + } + } + } else if (use_full_precision) { + // load offset/scale in float type; + size = quantized_sizes.at(file_idx); + std::vector host_array(size / sizeof(float)); + size_t loaded_data_size = size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + + size_t in_get_size = in.gcount(); + if (in_get_size != loaded_data_size) { + std::cout << "load weight data error scale/offset" << in_get_size + << ", " << loaded_data_size << ", " << sizeof(float) << ", " + << file << ", " << size << std::endl; + return; + } + assert(size / sizeof(float) == host_array.size()); + for (auto v : host_array) { + *(float *)(ptr + data_index) = v; + data_index += sizeof(float); + } + + } else { + // load offset/scale in half type; + size = quantized_sizes.at(file_idx); + std::vector host_array(size / sizeof(half)); + size_t loaded_data_size = size; + in.seekg(0, in.end); + in.seekg(0, in.beg); + in.read((char *)host_array.data(), loaded_data_size); + + size_t in_get_size = in.gcount(); + if (in_get_size != loaded_data_size) { + std::cout << "load weight data error " << in_get_size << ", " + << loaded_data_size << ", " << sizeof(half) << std::endl; + return; + } + assert(size / sizeof(half) == host_array.size()); + // normal + for (auto v : host_array) { + *(half *)(ptr + data_index) = v; + data_index += sizeof(half); + } + } + in.close(); + file_idx++; + } +} + +void FileDataLoader::load_quantization_weight(FFModel *ff, + Layer *l, + int weight_idx) { + Tensor weight = l->weights[weight_idx]; + size_t volume = 1; + std::vector dims_vec; + for (int i = 0; i < weight->num_dims; i++) { + dims_vec.push_back(weight->dims[i]); + volume *= weight->dims[i]; + } + char *data = (char *)malloc(sizeof(char) * volume); + + std::string weight_filename = removeGuidOperatorName(std::string(l->name)); + + if (weight_filename.find("attention") != std::string::npos && + weight_filename.rfind("attention") == + weight_filename.length() - strlen("attention")) { + if (weight_idx == 0) { + load_attention_weights_quantized(data, + num_heads, + hidden_dim, + qkv_inner_dim, + weight_filename, + weights_folder, + weight->data_type, + use_full_precision); + } + // else { + // load_attention_bias_quantized(data, + // num_heads, + // hidden_dim, + // qkv_inner_dim, + // weight_filename, + // weights_folder); + // } + + } else { + if (weight_idx > 0) { + assert(weight_idx == 0 || weight_idx == 1); + if (weight_filename != "embed_tokens_weight_lm_head") { + weight_filename += weight_idx == 0 ? "_weight" : "_bias"; + } + } + load_from_quantized_file(data, + volume, + join_path({weights_folder, weight_filename}), + weight->data_type, + use_full_precision); + } + + ParallelTensor weight_pt; + ff->get_parallel_tensor_from_tensor(weight, weight_pt); + weight_pt->set_tensor(ff, dims_vec, data); + + delete data; +} + +template +void FileDataLoader::load_single_weight_tensor(FFModel *ff, + Layer *l, + int weight_idx) { + Tensor weight = l->weights[weight_idx]; + + // Create a buffer to store weight data from the file + size_t volume = 1; + std::vector dims_vec; + for (int i = 0; i < weight->num_dims; i++) { + dims_vec.push_back(weight->dims[i]); + volume *= weight->dims[i]; + } + assert(data_type_size(weight->data_type) == sizeof(DT)); + DT *data = (DT *)malloc(sizeof(DT) * volume); + + std::string weight_filename = removeGuidOperatorName(std::string(l->name)); + + if (ff->config.benchmarking) { + std::cout << "Initializing weight " << weight_filename + << " with random data (benchmarking mode)" << std::endl; + // If benchmarking, we don't need to load the weights + // We can just fill the weight tensor with random data + } else { + if (l->op_type == OP_INC_MULTIHEAD_SELF_ATTENTION || + l->op_type == OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION || + l->op_type == OP_TREE_INC_MULTIHEAD_SELF_ATTENTION) { + if (weight_filename.find("self_attention") != std::string::npos) { + load_attention_weights_multi_query( + data, weight_filename, weights_folder, hidden_dim, num_heads); + } else if (weight_filename.find("attention") != std::string::npos && + weight_filename.rfind("attention") == + weight_filename.length() - strlen("attention")) { + if (weight_idx == 0) { + load_attention_weights_v2(data, + num_heads, + num_kv_heads, + hidden_dim, + qkv_inner_dim, + weight_filename, + weights_folder, + volume, + tensor_parallelism_degree); + } else { + long long value; + l->get_int_property("final_bias", value); + bool final_bias = (bool)value; + load_attention_bias_v2(data, + num_heads, + num_kv_heads, + hidden_dim, + qkv_inner_dim, + final_bias, + weight_filename, + weights_folder); + } + + } else { + assert(false); + } + } else if (l->op_type == OP_ADD_BIAS_RESIDUAL_LAYERNORM) { + assert(weight_idx >= 0 || weight_idx <= 2); + weight_filename += (weight_idx == 0) + ? "_attn_bias" + : ((weight_idx == 1) ? "_weight" : "_bias"); + std::cout << "Loading weight file " << weight_filename << std::endl; + std::string weight_filepath = + join_path({weights_folder, weight_filename}); + load_from_file(data, volume, weight_filepath); + } else { + // default op + assert(weight_idx == 0 || weight_idx == 1); + // handle exception + if (weight_filename != "embed_tokens_weight_lm_head") { + weight_filename += weight_idx == 0 ? "_weight" : "_bias"; + } + std::cout << "Loading weight file " << weight_filename << std::endl; + std::string weight_filepath = + join_path({weights_folder, weight_filename}); + load_from_file(data, volume, weight_filepath); + } + } + + // Copy the weight data from the buffer to the weight's ParallelTensor + ParallelTensor weight_pt; + ff->get_parallel_tensor_from_tensor(weight, weight_pt); + weight_pt->set_tensor
(ff, dims_vec, data); + + // Free buffer memory + delete data; +} + +void FileDataLoader::load_weights(FFModel *ff) { + for (Layer *l : ff->layers) { + if (l->numWeights < 1 || l->name == NULL || strlen(l->name) < 1) { + continue; + } + for (int i = 0; i < l->numWeights; i++) { + Tensor weight = l->weights[i]; + if (weight == NULL) { + continue; + } + switch (weight->data_type) { + case DT_HALF: + load_single_weight_tensor(ff, l, i); + break; + case DT_FLOAT: + load_single_weight_tensor(ff, l, i); + break; + case DT_INT4: + case DT_INT8: + // load weights in quantization + load_quantization_weight(ff, l, i); + break; + default: + assert(false && "Unsupported data type"); + } + } + } +} diff --git a/src/runtime/gpt_tokenizer.cc b/src/runtime/gpt_tokenizer.cc new file mode 100644 index 0000000000..56fdd05b3b --- /dev/null +++ b/src/runtime/gpt_tokenizer.cc @@ -0,0 +1,324 @@ +// version 0.1 +// Licensed under the MIT License . +// SPDX-License-Identifier: MIT +// Copyright (c) 2019-2020 zili wang . + +#include + +using json = nlohmann::json; + +// codecvt abandoned in c++17 +std::wstring GPT_Tokenizer::utf8_to_wstring(std::string const &src) { + std::wstring_convert, wchar_t> converter; + return converter.from_bytes(src); +}; + +std::u32string GPT_Tokenizer::utf8_to_utf32(std::string const &src) { + std::wstring_convert, char32_t> converter; + return converter.from_bytes(src); +}; + +std::string GPT_Tokenizer::wstring_to_utf8(std::wstring const &src) { + std::wstring_convert, wchar_t> converter; + return converter.to_bytes(src); +}; + +std::string GPT_Tokenizer::utf32_to_utf8(std::u32string const &src) { + std::wstring_convert, char32_t> converter; + return converter.to_bytes(src); +}; + +wchar_t *GPT_Tokenizer::bytes_to_unicode() { + std::vector bs; + for (auto i = uint32_t(L'!'); i < uint32_t(L'~') + 1; ++i) { + bs.push_back(i); + } + for (auto i = uint32_t(L'¡'); i < uint32_t(L'¬') + 1; ++i) { + bs.push_back(i); + } + for (auto i = uint32_t(L'®'); i < uint32_t(L'ÿ') + 1; ++i) { + bs.push_back(i); + } + std::vector cs = bs; + uint32_t n = 0; + for (uint32_t b = 0; b < 256; ++b) { + auto p = find(bs.begin(), bs.end(), b); + if (p == bs.end()) { + bs.push_back(b); + cs.push_back(256 + n); + n++; + } + } + static wchar_t bytes_mapping[256] = {}; + for (size_t i = 0; i < 256; i++) { + bytes_mapping[i] = i; + } + for (size_t i = 0; i < bs.size(); i++) { + bytes_mapping[bs[i]] = cs[i]; + } + return bytes_mapping; +} + +void GPT_Tokenizer::unicode_to_bytes() { + for (int i = 0; i < 256; i++) { + bytes_decoder[bytes_encoder[i]] = (char)i; + } +} + +std::vector GPT_Tokenizer::split(std::string const &s, + std::regex rgx) { + std::vector elems; + std::sregex_token_iterator iter(s.begin(), s.end(), rgx, -1); + std::sregex_token_iterator end; + while (iter != end) { + elems.push_back(*iter); + ++iter; + } + return elems; +}; + +std::string GPT_Tokenizer::strip(std::string const &inpt) { + if (inpt.length() == 0) { + return inpt; + } + auto start_it = inpt.begin(); + auto end_it = inpt.rbegin(); + while (std::isspace(*start_it)) { + ++start_it; + } + if (start_it == inpt.end()) { + return ""; + } + while (std::isspace(*end_it)) { + ++end_it; + } + return std::string(start_it, end_it.base()); +} + +std::unordered_set + GPT_Tokenizer::get_pairs(std::vector word) { + std::unordered_set pairs; + std::wstring prev_char = word[0]; + for (size_t i = 1; i < word.size(); ++i) { + pairs.insert(wbigram_pair({prev_char, word[i]})); + prev_char = word[i]; + } + return pairs; +}; + +void GPT_Tokenizer::load_vocab(std::string const &vocab_file) { + std::ifstream file_handle(vocab_file); + assert(file_handle.good() && "file not exists"); + bool discard_first_line = false; + if (discard_first_line) { + std::string first_line_discard; + std::getline(file_handle, first_line_discard); // skip the first line + } + json vocab_data_ = json::parse(file_handle, + /*parser_callback_t */ nullptr, + /*allow_exceptions */ true, + /*ignore_comments */ true); + auto vocab_ = vocab_data_.get>(); + for (auto item : vocab_) { + vocab.insert({item.first, item.second}); + inverse_vocab.insert({item.second, item.first}); + } +}; + +void GPT_Tokenizer::load_merge(std::string const &merge_file) { + bpe_ranks.reserve(60000); + std::ifstream file_handle(merge_file); + assert(file_handle.good() && "file not exists"); + std::string line; + uint32_t curr_idx = 0; + std::string version_substring = "#version:"; + while (getline(file_handle, line)) { + if (line.size() == 0 || line.rfind(version_substring, 0) == 0) { + continue; + } + std::vector bigrams = split(line); + assert(bigrams.size() == 2 && "unk format"); + wbigram_pair curr(utf8_to_wstring(bigrams[0]), utf8_to_wstring(bigrams[1])); + bpe_ranks.insert({curr, curr_idx}); + curr_idx++; + } +}; + +std::vector GPT_Tokenizer::bpe(std::wstring token) { + // bpe use wstring + if (cache.find(token) != cache.end()) { + return cache[token]; + } + std::vector wword; + for (auto c : token) { + wword.push_back(std::wstring(1, c)); + } + std::unordered_set pairs = get_pairs(wword); + if (pairs.empty()) { + return {wstring_to_utf8(token)}; + } + + while (true) { + auto bigram = pairs.begin(); + if (pairs.size() > 1) { + bigram = std::min_element( + pairs.begin(), + pairs.end(), + [this](wbigram_pair const &a, wbigram_pair const &b) -> bool { + if (bpe_ranks.find(a) == bpe_ranks.end()) { + return false; + } + if (bpe_ranks.find(b) == bpe_ranks.end()) { + return true; + } + return bpe_ranks[a] < bpe_ranks[b]; + }); + } + if (bpe_ranks.find(*bigram) == bpe_ranks.end()) { + break; + } + std::wstring first = bigram->first; + std::wstring second = bigram->second; + decltype(wword) new_wword; + + auto i = wword.begin(); + while (i < wword.end()) { + auto j = std::find(i, wword.end(), first); + if (j == wword.end()) { + new_wword.insert(new_wword.end(), i, wword.end()); + break; + } + new_wword.insert(new_wword.end(), i, j); + i = j; + // i <= wword.end + if (*i == first && i < wword.end() - 1 && *(i + 1) == second) { + new_wword.push_back(first + second); + i += 2; + } else { + new_wword.push_back(*i); + i += 1; + } + } + wword = new_wword; + if (wword.size() == 1) { + break; + } else { + pairs = get_pairs(wword); + } + } + std::vector word; + for (auto w : wword) { + word.push_back(wstring_to_utf8(w)); + } + if (token.size() < cache_word_max_length && cache.size() < cache_max_size) { + cache.insert({token, word}); + } + return word; +}; + +std::vector GPT_Tokenizer::tokenize(std::string str) { + std::vector bpe_tokens; + std::wstring wstr = utf8_to_wstring(str); + std::wsregex_iterator iter(wstr.begin(), wstr.end(), pat); + std::wsregex_iterator end; + while (iter != end) { + std::wstring token; + for (char c : wstring_to_utf8(iter->str())) { + if (0 > c) { + token.push_back(*(bytes_encoder + c + 256)); + } else { + token.push_back(*(bytes_encoder + c)); + } + } + if (token.length() > 0) { + decltype(bpe_tokens) curr_bpe_tokens = bpe(token); + bpe_tokens.insert( + bpe_tokens.end(), curr_bpe_tokens.begin(), curr_bpe_tokens.end()); + } + ++iter; + } + return bpe_tokens; +} + +int32_t GPT_Tokenizer::convert_token_to_id(std::string token) { + auto p = vocab.find(token); + if (p != vocab.end()) { + return vocab[token]; + } else { + return vocab[unk_token]; + } +} + +void GPT_Tokenizer::encode(std::string str, + size_t max_length, + std::vector *input_ids, + std::vector *mask_ids) { + if (not input_ids->empty()) { + input_ids->clear(); + } + if (not mask_ids->empty()) { + mask_ids->clear(); + } + input_ids->reserve(max_length); + mask_ids->reserve(max_length); + // input_ids->push_back(vocab[bos_token]); + // mask_ids->push_back(1); + auto tokens = tokenize(str); + for (auto t : tokens) { + if (input_ids->size() == max_length - 1) { + break; + } + input_ids->push_back(convert_token_to_id(t)); + mask_ids->push_back(1); + } + // input_ids->push_back(vocab[eos_token]); + // mask_ids->push_back(1); + while (input_ids->size() < max_length) { + input_ids->push_back(vocab[pad_token]); + mask_ids->push_back(0); + } + if (mode == OPT_TOKENIZER) { + mask_ids->insert(mask_ids->begin(), 1); + input_ids->insert(input_ids->begin(), 2); + } +} + +std::string GPT_Tokenizer::decode(std::vector input_ids, + std::vector mask_ids) { + // look up each number in encoder.json dictionary + std::ostringstream oss; + int index = 0; + for (auto const &id : input_ids) { + if (index == 0) { + if (mode == OPT_TOKENIZER) { + if (id == 2) { + index++; + } + continue; + } + } + if (!mask_ids[index]) { + index++; + continue; + } + auto it = inverse_vocab.find(id); + if (it != inverse_vocab.end()) { + oss << it->second; + } else { + // Handle the case when the integer is not found in the inverse_vocab map. + // You can choose to ignore it, skip it, or handle it differently based on + // your requirements. + assert(false); + } + index++; + } + std::string concatenated_tokens = oss.str(); + // apply byte_decoder to each character in the input_ids string, then decode + // as utf-8 + std::wstring wstr = utf8_to_wstring(concatenated_tokens); + std::string result; + for (wchar_t ch : wstr) { + result += bytes_decoder[ch]; + } + return result; +} diff --git a/src/runtime/graph.cc b/src/runtime/graph.cc index 762c5911d6..0a6be7eab1 100644 --- a/src/runtime/graph.cc +++ b/src/runtime/graph.cc @@ -15,9 +15,13 @@ #include "flexflow/graph.h" #include "flexflow/dominators.h" #include "flexflow/ffconst_utils.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/aggregate.h" +#include "flexflow/ops/arg_topk.h" +#include "flexflow/ops/argmax.h" #include "flexflow/ops/attention.h" #include "flexflow/ops/batch_matmul.h" +#include "flexflow/ops/beam_topk.h" #include "flexflow/ops/cast.h" #include "flexflow/ops/concat.h" #include "flexflow/ops/conv_2d.h" @@ -25,19 +29,29 @@ #include "flexflow/ops/element_binary.h" #include "flexflow/ops/element_unary.h" #include "flexflow/ops/embedding.h" +#include "flexflow/ops/experts.h" #include "flexflow/ops/flat.h" #include "flexflow/ops/gather.h" #include "flexflow/ops/groupby.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/layer_norm.h" #include "flexflow/ops/linear.h" #include "flexflow/ops/noop.h" #include "flexflow/ops/pool_2d.h" #include "flexflow/ops/reduce.h" #include "flexflow/ops/reshape.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/residual_rms_norm.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/ops/sampling.h" +#include "flexflow/ops/sigmoid_silu_multi.h" #include "flexflow/ops/softmax.h" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" #include "flexflow/ops/split.h" #include "flexflow/ops/topk.h" #include "flexflow/ops/transpose.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/combine.h" #include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/fused_parallel_op.h" @@ -2000,15 +2014,89 @@ std::pair, std::unordered_map> // Perform the search std::unique_ptr curr_best_graph; std::unordered_map curr_optimal_views; - - // Main step to optimize the PCG of an FFModel - model->graph_optimize(model->config.search_budget, - model->config.only_data_parallel, - curr_best_graph, - curr_optimal_views, - perform_memory_search, - MemoryOptimConfig{lambda.first}, - lambda.second); + if (model->config.only_data_parallel) { + Graph *graph = new Graph(model); + std::unordered_map op_to_node_map; + for (FlexFlow::Op const *dstOp : model->operators) { + Node dstNode; + dstNode.ptr = dstOp; + dstNode.guid = model->node_global_guid++; + op_to_node_map[dstOp] = dstNode; + for (int j = 0; j < dstOp->numInputs; j++) { + FlexFlow::Op const *srcOp = dstOp->inputs[j]->owner_op; + assert(op_to_node_map.find(srcOp) != op_to_node_map.end()); + Node srcNode = op_to_node_map[srcOp]; + graph->add_edge(srcNode, dstNode, dstOp->inputs[j]->owner_idx, j); + } + } + curr_best_graph = std::unique_ptr(graph); + MachineView data_parallel_view; + int degree, num_transformer_layers_per_stage; + if (model->config.computationMode == COMP_MODE_TRAINING) { + data_parallel_view.device_type = MachineView::GPU; + data_parallel_view.ndims = 1; + data_parallel_view.dim[0] = + model->config.numNodes * model->config.workersPerNode; + data_parallel_view.stride[0] = 1; + data_parallel_view.start_device_id = 0; + } else { + // Currently assume a 1D machine view is needed + assert(model->config.data_parallelism_degree == 1 || + model->config.tensor_parallelism_degree == 1); + degree = model->config.data_parallelism_degree * + model->config.tensor_parallelism_degree; + num_transformer_layers_per_stage = + model->current_transformer_layer_id / + model->config.pipeline_parallelism_degree + + 1; + } + for (auto const &node : curr_best_graph->inEdges) { + Op const *op = node.first.ptr; + if (model->config.computationMode == COMP_MODE_TRAINING) { + curr_optimal_views[node.first] = data_parallel_view; + } else { + MachineView mv; + mv.device_type = MachineView::GPU; + mv.ndims = 1; + int total_parallel_degree = 1; + for (int i = 0; i < op->outputs[0]->num_dims; i++) { + total_parallel_degree *= op->outputs[0]->dims[i].degree; + } + mv.dim[0] = total_parallel_degree; + mv.stride[0] = 1; + LayerID layer_guid = op->layer_guid; + if (op->op_type == OP_INPUT) { + // All inputs are assigned to the first stage + layer_guid.transformer_layer_id = 0; + } else if (layer_guid == LayerID::NO_ID) { + // Assert that we only have a single input + while (op->layer_guid == LayerID::NO_ID) { + assert(op->numInputs == 1); + op = op->inputs[0]->owner_op; + assert(op != nullptr); + } + layer_guid = op->layer_guid; + } + mv.start_device_id = degree * (layer_guid.transformer_layer_id / + num_transformer_layers_per_stage); + assert(mv.start_device_id + degree - 1 < + model->config.numNodes * model->config.workersPerNode); + curr_optimal_views[node.first] = mv; + for (int i = 0; i < node.first.ptr->numOutputs; i++) { + assert(node.first.ptr->outputs[i]->is_valid_machine_view(mv)); + } + } + } + } else { + // Main step to optimize the PCG of an FFModel + model->graph_optimize(model->config.search_budget, + model->config.only_data_parallel, + curr_best_graph, + curr_optimal_views, + perform_memory_search, + MemoryOptimConfig{lambda.first}, + lambda.second); + } // Return the best result of the current search return std::make_pair(std::move(curr_best_graph), curr_optimal_views); }; @@ -2260,6 +2348,8 @@ GraphOptimalViewSerialized case OP_CONCAT: { Concat *concat = (Concat *)op; sez.serialize(concat->legion_axis); + sez.serialize(strlen(concat->name)); + sez.serialize(concat->name, strlen(concat->name)); break; } case OP_SPLIT: { @@ -2269,28 +2359,28 @@ GraphOptimalViewSerialized for (int i = 0; i < split->numOutputs; i++) { sez.serialize(split->outputs[i]->dims[split->legion_axis].size); } + sez.serialize(strlen(split->name)); + sez.serialize(split->name, strlen(split->name)); break; } case OP_EMBEDDING: { Embedding *embed = (Embedding *)op; sez.serialize(embed->layer_guid.id); + sez.serialize(embed->layer_guid.transformer_layer_id); + sez.serialize(embed->layer_guid.model_id); sez.serialize(embed->num_entries); sez.serialize(embed->out_channels); sez.serialize(embed->aggr); sez.serialize(embed->data_type); - break; - } - case OP_EW_ADD: - case OP_EW_SUB: - case OP_EW_MUL: - case OP_EW_MAX: - case OP_EW_MIN: { - sez.serialize(op->op_type); + sez.serialize(strlen(embed->name)); + sez.serialize(embed->name, strlen(embed->name)); break; } case OP_MULTIHEAD_ATTENTION: { MultiHeadAttention *attn = (MultiHeadAttention *)op; sez.serialize(attn->layer_guid.id); + sez.serialize(attn->layer_guid.transformer_layer_id); + sez.serialize(attn->layer_guid.model_id); sez.serialize(attn->oProjSize); sez.serialize(attn->num_heads); sez.serialize(attn->qProjSize); @@ -2299,6 +2389,85 @@ GraphOptimalViewSerialized sez.serialize(attn->bias); sez.serialize(attn->add_bias_kv); sez.serialize(attn->add_zero_attn); + sez.serialize(strlen(attn->name)); + sez.serialize(attn->name, strlen(attn->name)); + break; + } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + IncMultiHeadSelfAttention *attn = (IncMultiHeadSelfAttention *)op; + sez.serialize(attn->layer_guid.id); + sez.serialize(attn->layer_guid.transformer_layer_id); + sez.serialize(attn->layer_guid.model_id); + sez.serialize(attn->oProjSize); + sez.serialize(attn->num_q_heads); + sez.serialize(attn->qProjSize); + sez.serialize(attn->vProjSize); + sez.serialize(attn->dropout); + sez.serialize(attn->qkv_bias); + sez.serialize(attn->final_bias); + sez.serialize(attn->add_zero_attn); + sez.serialize(attn->apply_rotary_embedding); + sez.serialize(attn->scaling_query); + sez.serialize(attn->scaling_factor); + sez.serialize(attn->qk_prod_scaling); + sez.serialize(attn->position_bias); + sez.serialize(attn->quantization_type); + sez.serialize(attn->offload); + sez.serialize(attn->num_kv_heads); + sez.serialize(attn->tensor_parallelism_degree); + sez.serialize(strlen(attn->name)); + sez.serialize(attn->name, strlen(attn->name)); + break; + } + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: { + SpecIncMultiHeadSelfAttention *attn = + (SpecIncMultiHeadSelfAttention *)op; + sez.serialize(attn->layer_guid.id); + sez.serialize(attn->layer_guid.transformer_layer_id); + sez.serialize(attn->layer_guid.model_id); + sez.serialize(attn->oProjSize); + sez.serialize(attn->num_q_heads); + sez.serialize(attn->qProjSize); + sez.serialize(attn->vProjSize); + sez.serialize(attn->dropout); + sez.serialize(attn->qkv_bias); + sez.serialize(attn->final_bias); + sez.serialize(attn->add_zero_attn); + sez.serialize(attn->apply_rotary_embedding); + sez.serialize(attn->scaling_query); + sez.serialize(attn->scaling_factor); + sez.serialize(attn->qk_prod_scaling); + sez.serialize(attn->position_bias); + sez.serialize(attn->num_kv_heads); + sez.serialize(strlen(attn->name)); + sez.serialize(attn->name, strlen(attn->name)); + break; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + TreeIncMultiHeadSelfAttention *attn = + (TreeIncMultiHeadSelfAttention *)op; + sez.serialize(attn->layer_guid.id); + sez.serialize(attn->layer_guid.transformer_layer_id); + sez.serialize(attn->layer_guid.model_id); + sez.serialize(attn->oProjSize); + sez.serialize(attn->num_q_heads); + sez.serialize(attn->qProjSize); + sez.serialize(attn->vProjSize); + sez.serialize(attn->dropout); + sez.serialize(attn->qkv_bias); + sez.serialize(attn->final_bias); + sez.serialize(attn->add_zero_attn); + sez.serialize(attn->apply_rotary_embedding); + sez.serialize(attn->scaling_query); + sez.serialize(attn->scaling_factor); + sez.serialize(attn->qk_prod_scaling); + sez.serialize(attn->position_bias); + sez.serialize(attn->quantization_type); + sez.serialize(attn->offload); + sez.serialize(attn->num_kv_heads); + sez.serialize(attn->tensor_parallelism_degree); + sez.serialize(strlen(attn->name)); + sez.serialize(attn->name, strlen(attn->name)); break; } case OP_SOFTMAX: { @@ -2311,18 +2480,24 @@ GraphOptimalViewSerialized Repartition *repart = (Repartition *)op; sez.serialize(repart->repartition_dim); sez.serialize(repart->repartition_degree); + sez.serialize(strlen(repart->name)); + sez.serialize(repart->name, strlen(repart->name)); break; } case OP_REPLICATE: { Replicate *replicate = (Replicate *)op; sez.serialize(replicate->replicate_dim); sez.serialize(replicate->replicate_degree); + sez.serialize(strlen(replicate->name)); + sez.serialize(replicate->name, strlen(replicate->name)); break; } case OP_REDUCTION: { Reduction *reduction = (Reduction *)op; sez.serialize(reduction->reduction_dim); sez.serialize(reduction->reduction_degree); + sez.serialize(strlen(reduction->name)); + sez.serialize(reduction->name, strlen(reduction->name)); break; } case OP_ALLREDUCE: { @@ -2336,6 +2511,15 @@ GraphOptimalViewSerialized Combine *combine = (Combine *)op; sez.serialize(combine->combine_dim); sez.serialize(combine->combine_degree); + sez.serialize(strlen(combine->name)); + sez.serialize(combine->name, strlen(combine->name)); + break; + } + case OP_ALLREDUCE: { + AllReduce *allreduce = (AllReduce *)op; + sez.serialize(allreduce->allreduce_dim); + sez.serialize(strlen(allreduce->name)); + sez.serialize(allreduce->name, strlen(allreduce->name)); break; } case OP_FUSED_PARALLEL: { @@ -2344,6 +2528,8 @@ GraphOptimalViewSerialized for (int i = 0; i < fused->num_parallel_ops; i++) { sez.serialize(fused->parallel_ops[i]); } + sez.serialize(strlen(fused->name)); + sez.serialize(fused->name, strlen(fused->name)); break; } default: { @@ -2396,6 +2582,18 @@ void FFModel::register_all_machine_views( valid_views.push_back(view); } } + // No-parallelism views + for (int i = 1; i <= num_nodes * gpus_per_node; i++) { + if (num_nodes * gpus_per_node % i == 0) { + MachineView view; + view.device_type = MachineView::GPU; + view.ndims = 1; + view.dim[0] = i; + view.stride[0] = 0; + view.start_device_id = 0; + valid_views.push_back(view); + } + } // Two-dimensional views /* for (int i = 1; i <= num_nodes; i++) { */ /* for (int j = 1; j <= gpus_per_node; j++) { */ @@ -2529,6 +2727,10 @@ void FFModel::deserialize_graph_optimal_view( case OP_CONCAT: { int legion_axis; dez.deserialize(legion_axis); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node( {std::begin(inputs), std::begin(inputs) + num_inputs}, {legion_axis}); @@ -2545,6 +2747,10 @@ void FFModel::deserialize_graph_optimal_view( dez.deserialize(dim_size); splits.push_back(dim_size); } + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node(inputs[0], {splits, legion_axis}); break; } @@ -2552,14 +2758,20 @@ void FFModel::deserialize_graph_optimal_view( assert(num_inputs == 1); AggrMode aggr; int num_entries, out_channels; - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; DataType data_type; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); dez.deserialize(num_entries); dez.deserialize(out_channels); dez.deserialize(aggr); dez.deserialize(data_type); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); EmbeddingParams params; params.aggr = aggr; @@ -2567,6 +2779,7 @@ void FFModel::deserialize_graph_optimal_view( params.out_channels = out_channels; params.layer_guid = layer_guid; params.data_type = data_type; + strcpy(params.name, name); node = get_or_create_node(inputs[0], params); break; } @@ -2575,11 +2788,7 @@ void FFModel::deserialize_graph_optimal_view( case OP_EW_MUL: case OP_EW_MAX: case OP_EW_MIN: { - assert(num_inputs == 2); - OperatorType op_type; - dez.deserialize(op_type); - node = get_or_create_node({inputs[0], inputs[1]}, - {op_type}); + node = ElementBinary::deserialize(*this, dez, inputs, num_inputs); break; } case OP_CONV2D: { @@ -2621,6 +2830,19 @@ void FFModel::deserialize_graph_optimal_view( node = LayerNorm::deserialize(*this, dez, inputs, num_inputs); break; } + case OP_RESIDUAL_LAYERNORM: { + node = ResidualLayerNorm::deserialize(*this, dez, inputs, num_inputs); + break; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + node = AddBiasResidualLayerNorm::deserialize( + *this, dez, inputs, num_inputs); + break; + } + case OP_SIGMOID_SILU_MULTI: { + node = SigmoidSiluMulti::deserialize(*this, dez, inputs, num_inputs); + break; + } case OP_LINEAR: { node = Linear::deserialize(*this, dez, inputs, num_inputs); break; @@ -2630,9 +2852,11 @@ void FFModel::deserialize_graph_optimal_view( int embed_dim, num_heads, k_dim, v_dim; float dropout; bool bias, add_bias_kv, add_zero_attn; - size_t id; + size_t id, transformer_layer_id, deserialized_model_id; dez.deserialize(id); - LayerID layer_guid(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); dez.deserialize(embed_dim); dez.deserialize(num_heads); dez.deserialize(k_dim); @@ -2641,6 +2865,10 @@ void FFModel::deserialize_graph_optimal_view( dez.deserialize(bias); dez.deserialize(add_bias_kv); dez.deserialize(add_zero_attn); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); MultiHeadAttentionParams params; params.embed_dim = embed_dim; @@ -2652,30 +2880,217 @@ void FFModel::deserialize_graph_optimal_view( params.add_bias_kv = add_bias_kv; params.add_zero_attn = add_zero_attn; params.layer_guid = layer_guid; + strcpy(params.name, name); node = get_or_create_node( {inputs[0], inputs[1], inputs[2]}, params); break; } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + assert(num_inputs == 1); + int embed_dim, num_q_heads, k_dim, v_dim, num_kv_heads, + tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, offload, position_bias; + DataType quantization_type; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(embed_dim); + dez.deserialize(num_q_heads); + dez.deserialize(k_dim); + dez.deserialize(v_dim); + dez.deserialize(dropout); + dez.deserialize(qkv_bias); + dez.deserialize(final_bias); + dez.deserialize(add_zero_attn); + dez.deserialize(apply_rotary_embedding); + dez.deserialize(scaling_query); + dez.deserialize(scaling_factor); + dez.deserialize(qk_prod_scaling); + dez.deserialize(position_bias); + dez.deserialize(quantization_type); + dez.deserialize(offload); + dez.deserialize(num_kv_heads); + dez.deserialize(tensor_parallelism_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + IncMultiHeadSelfAttentionParams params; + params.embed_dim = embed_dim; + params.num_q_heads = num_q_heads; + params.kdim = k_dim; + params.vdim = v_dim; + params.dropout = dropout; + params.qkv_bias = qkv_bias; + params.final_bias = final_bias; + params.add_zero_attn = add_zero_attn; + params.layer_guid = layer_guid; + params.apply_rotary_embedding = apply_rotary_embedding; + params.scaling_query = scaling_query; + params.scaling_factor = scaling_factor; + params.qk_prod_scaling = qk_prod_scaling; + params.position_bias = position_bias; + params.quantization_type = quantization_type; + params.offload = offload; + params.num_kv_heads = num_kv_heads; + params.tensor_parallelism_degree = tensor_parallelism_degree; + strcpy(params.name, name); + node = get_or_create_node(inputs[0], params); + break; + } + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: { + assert(num_inputs == 1); + int embed_dim, num_q_heads, k_dim, v_dim, num_kv_heads; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, position_bias; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(embed_dim); + dez.deserialize(num_q_heads); + dez.deserialize(k_dim); + dez.deserialize(v_dim); + dez.deserialize(dropout); + dez.deserialize(qkv_bias); + dez.deserialize(final_bias); + dez.deserialize(add_zero_attn); + dez.deserialize(apply_rotary_embedding); + dez.deserialize(scaling_query); + dez.deserialize(scaling_factor); + dez.deserialize(qk_prod_scaling); + dez.deserialize(position_bias); + dez.deserialize(num_kv_heads); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + SpecIncMultiHeadSelfAttentionParams params; + params.embed_dim = embed_dim; + params.num_q_heads = num_q_heads; + params.kdim = k_dim; + params.vdim = v_dim; + params.dropout = dropout; + params.qkv_bias = qkv_bias; + params.final_bias = final_bias; + params.add_zero_attn = add_zero_attn; + params.layer_guid = layer_guid; + params.apply_rotary_embedding = apply_rotary_embedding; + params.scaling_query = scaling_query; + params.scaling_factor = scaling_factor; + params.qk_prod_scaling = qk_prod_scaling; + params.position_bias = position_bias; + params.num_kv_heads = num_kv_heads; + strcpy(params.name, name); + node = get_or_create_node(inputs[0], + params); + break; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + assert(num_inputs == 1); + int embed_dim, num_q_heads, k_dim, v_dim, num_kv_heads, + tensor_parallelism_degree; + float dropout, scaling_factor; + bool qkv_bias, final_bias, add_zero_attn, apply_rotary_embedding, + scaling_query, qk_prod_scaling, offload, position_bias; + DataType quantization_type; + size_t id, transformer_layer_id, deserialized_model_id; + dez.deserialize(id); + dez.deserialize(transformer_layer_id); + dez.deserialize(deserialized_model_id); + LayerID layer_guid(id, transformer_layer_id, deserialized_model_id); + dez.deserialize(embed_dim); + dez.deserialize(num_q_heads); + dez.deserialize(k_dim); + dez.deserialize(v_dim); + dez.deserialize(dropout); + dez.deserialize(qkv_bias); + dez.deserialize(final_bias); + dez.deserialize(add_zero_attn); + dez.deserialize(apply_rotary_embedding); + dez.deserialize(scaling_query); + dez.deserialize(scaling_factor); + dez.deserialize(qk_prod_scaling); + dez.deserialize(position_bias); + dez.deserialize(quantization_type); + dez.deserialize(offload); + dez.deserialize(num_kv_heads); + dez.deserialize(tensor_parallelism_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); + + TreeIncMultiHeadSelfAttentionParams params; + params.embed_dim = embed_dim; + params.num_q_heads = num_q_heads; + params.kdim = k_dim; + params.vdim = v_dim; + params.dropout = dropout; + params.qkv_bias = qkv_bias; + params.final_bias = final_bias; + params.add_zero_attn = add_zero_attn; + params.layer_guid = layer_guid; + params.apply_rotary_embedding = apply_rotary_embedding; + params.scaling_query = scaling_query; + params.scaling_factor = scaling_factor; + params.qk_prod_scaling = qk_prod_scaling; + params.position_bias = position_bias; + params.quantization_type = quantization_type; + params.offload = offload; + params.num_kv_heads = num_kv_heads; + params.tensor_parallelism_degree = tensor_parallelism_degree; + strcpy(params.name, name); + node = get_or_create_node(inputs[0], + params); + break; + } case OP_TOPK: { node = TopK::deserialize(*this, dez, inputs, num_inputs); break; } + case OP_ARG_TOPK: { + node = ArgTopK::deserialize(*this, dez, inputs, num_inputs); + break; + } + case OP_BEAM_TOPK: { + node = BeamTopK::deserialize(*this, dez, inputs, num_inputs); + break; + } + case OP_SAMPLING: { + node = Sampling::deserialize(*this, dez, inputs, num_inputs); + break; + } + case OP_ARGMAX: { + node = ArgMax::deserialize(*this, dez, inputs, num_inputs); + break; + } case OP_GROUP_BY: { node = Group_by::deserialize(*this, dez, inputs, num_inputs); break; } case OP_AGGREGATE: { - // node = Aggregate::deserialize(*this, dez, inputs, num_inputs); - int n; - float lambda_bal; - dez.deserialize(n); - dez.deserialize(lambda_bal); - assert(num_inputs == n + 4); - AggregateParams params; - params.n = n; - params.lambda_bal = lambda_bal; - node = get_or_create_node( - {std::begin(inputs), std::begin(inputs) + num_inputs}, params); + node = Aggregate::deserialize( + *this, + dez, + {std::begin(inputs), std::begin(inputs) + num_inputs}, + num_inputs); + break; + } + case OP_EXPERTS: { + node = Experts::deserialize( + *this, + dez, + {std::begin(inputs), std::begin(inputs) + num_inputs}, + num_inputs); break; } case OP_POOL2D: { @@ -2704,11 +3119,23 @@ void FFModel::deserialize_graph_optimal_view( node = Transpose::deserialize(*this, dez, inputs, num_inputs); break; } + case OP_RMS_NORM: { + node = RMSNorm::deserialize(*this, dez, inputs, num_inputs); + break; + } + case OP_RESIDUAL_RMS_NORM: { + node = ResidualRMSNorm::deserialize(*this, dez, inputs, num_inputs); + break; + } case OP_COMBINE: { assert(num_inputs == 1); int combine_dim, combine_degree; dez.deserialize(combine_dim); dez.deserialize(combine_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node(inputs[0], {combine_dim, combine_degree}); break; @@ -2718,6 +3145,10 @@ void FFModel::deserialize_graph_optimal_view( int repartition_dim, repartition_degree; dez.deserialize(repartition_dim); dez.deserialize(repartition_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node( inputs[0], {repartition_dim, repartition_degree}); break; @@ -2727,6 +3158,10 @@ void FFModel::deserialize_graph_optimal_view( int replicate_dim, replicate_degree; dez.deserialize(replicate_dim); dez.deserialize(replicate_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node(inputs[0], {replicate_dim, replicate_degree}); break; @@ -2736,6 +3171,10 @@ void FFModel::deserialize_graph_optimal_view( int reduction_dim, reduction_degree; dez.deserialize(reduction_dim); dez.deserialize(reduction_degree); + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node(inputs[0], {reduction_dim, reduction_degree}); break; @@ -2761,6 +3200,10 @@ void FFModel::deserialize_graph_optimal_view( dez.deserialize(info); parallel_ops.push_back(info); } + size_t name_len; + char name[MAX_OPNAME] = {0}; + dez.deserialize(name_len); + dez.deserialize(name, name_len); node = get_or_create_node(inputs[0], {parallel_ops}); break; } diff --git a/src/runtime/hip_helper.cpp b/src/runtime/hip_helper.cpp index 8617cb2ef3..3294b8566e 100644 --- a/src/runtime/hip_helper.cpp +++ b/src/runtime/hip_helper.cpp @@ -257,9 +257,212 @@ __host__ void checkCUDA(hipHostFree(host_ptr)); } +template <> +__host__ void + save_tensor(float const *ptr, size_t num_elements, char const *file_name) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + float *host_ptr; + checkCUDA(hipHostMalloc(&host_ptr, + sizeof(float) * num_elements, + hipHostMallocPortable | hipHostMallocMapped)); + checkCUDA(hipMemcpyAsync(host_ptr, + ptr, + sizeof(float) * num_elements, + hipMemcpyDeviceToHost, + stream)); + checkCUDA(hipDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%.9f, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%.9f", host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(hipHostFree(host_ptr)); +} + +template <> +__host__ void + save_tensor(half const *ptr, size_t num_elements, char const *file_name) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + half *host_ptr; + checkCUDA(hipHostMalloc(&host_ptr, + sizeof(half) * num_elements, + hipHostMallocPortable | hipHostMallocMapped)); + checkCUDA(hipMemcpyAsync(host_ptr, + ptr, + sizeof(half) * num_elements, + hipMemcpyDeviceToHost, + stream)); + checkCUDA(hipDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%.9f, ", (float)host_ptr[i]); + } else { + fprintf(tensor_file, "%.9f", (float)host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(hipHostFree(host_ptr)); +} + +template <> +__host__ void save_tensor(int32_t const *ptr, + size_t num_elements, + char const *file_name) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + int32_t *host_ptr; + checkCUDA(hipHostMalloc(&host_ptr, + sizeof(int32_t) * num_elements, + hipHostMallocPortable | hipHostMallocMapped)); + checkCUDA(hipMemcpyAsync(host_ptr, + ptr, + sizeof(int32_t) * num_elements, + hipMemcpyDeviceToHost, + stream)); + checkCUDA(hipDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%d, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%d", host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(hipHostFree(host_ptr)); +} + +template <> +__host__ void save_tensor(int64_t const *ptr, + size_t num_elements, + char const *file_name) { + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + int64_t *host_ptr; + checkCUDA(hipHostMalloc(&host_ptr, + sizeof(int64_t) * num_elements, + hipHostMallocPortable | hipHostMallocMapped)); + checkCUDA(hipMemcpyAsync(host_ptr, + ptr, + sizeof(int64_t) * num_elements, + hipMemcpyDeviceToHost, + stream)); + checkCUDA(hipDeviceSynchronize()); + FILE *tensor_file; + tensor_file = fopen(file_name, "w"); + assert(tensor_file != NULL); + for (unsigned i = 0; i < num_elements; i++) { + if (i < num_elements - 1) { + fprintf(tensor_file, "%ld, ", host_ptr[i]); + } else { + fprintf(tensor_file, "%ld", host_ptr[i]); + } + } + + fclose(tensor_file); + checkCUDA(hipHostFree(host_ptr)); +} + +template +__host__ T *download_tensor(T const *ptr, size_t num_elements) { + // device synchronize to make sure the data are ready + // checkCUDA(hipDeviceSynchronize()); + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + T *host_ptr; + checkCUDA(hipHostMalloc(&host_ptr, + sizeof(T) * num_elements, + hipHostMallocPortable | hipHostMallocMapped)); + checkCUDA(hipMemcpyAsync( + host_ptr, ptr, sizeof(T) * num_elements, hipMemcpyDeviceToHost, stream)); + // checkCUDA(hipDeviceSynchronize()); + return host_ptr; +} + +template +__host__ bool download_tensor(T const *ptr, T *dst, size_t num_elements) { + // device synchronize to make sure the data are ready + // checkCUDA(hipDeviceSynchronize()); + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + assert(dst != nullptr); + checkCUDA(hipMemcpyAsync( + dst, ptr, sizeof(T) * num_elements, hipMemcpyDeviceToHost, stream)); + // checkCUDA(hipDeviceSynchronize()); + return true; +} + +miopenStatus_t cudnnSetTensorDescriptorFromDomain( + miopenTensorDescriptor_t tensor, Domain domain, DataType data_type) { + int dims[MAX_TENSOR_DIM]; + miopenDataType_t cudnn_data_type = ff_to_cudnn_datatype(data_type); + switch (domain.get_dim()) { + case 1: { + Rect<1> rect = domain; + dims[0] = rect.hi[0] - rect.lo[0] + 1; + return miopenSet4dTensorDescriptor( + tensor, cudnn_data_type, dims[0], 1, 1, 1); + } + case 2: { + Rect<2> rect = domain; + dims[0] = rect.hi[0] - rect.lo[0] + 1; + dims[1] = rect.hi[1] - rect.lo[1] + 1; + return miopenSet4dTensorDescriptor( + tensor, cudnn_data_type, dims[1], dims[0], 1, 1); + } + case 3: { + Rect<3> rect = domain; + dims[0] = rect.hi[0] - rect.lo[0] + 1; + dims[1] = rect.hi[1] - rect.lo[1] + 1; + dims[2] = rect.hi[2] - rect.lo[2] + 1; + return miopenSet4dTensorDescriptor( + tensor, cudnn_data_type, dims[2], dims[1], dims[0], 1); + } + case 4: { + Rect<4> rect = domain; + dims[0] = rect.hi[0] - rect.lo[0] + 1; + dims[1] = rect.hi[1] - rect.lo[1] + 1; + dims[2] = rect.hi[2] - rect.lo[2] + 1; + dims[3] = rect.hi[3] - rect.lo[3] + 1; + return miopenSet4dTensorDescriptor( + tensor, cudnn_data_type, dims[3], dims[2], dims[1], dims[0]); + } + case 5: { + Rect<5> rect = domain; + int leading_dim_size = rect.hi[4] - rect.lo[4] + 1; + assert(leading_dim_size == 1); + dims[0] = rect.hi[0] - rect.lo[0] + 1; + dims[1] = rect.hi[1] - rect.lo[1] + 1; + dims[2] = rect.hi[2] - rect.lo[2] + 1; + dims[3] = rect.hi[3] - rect.lo[3] + 1; + return miopenSet4dTensorDescriptor( + tensor, cudnn_data_type, dims[3], dims[2], dims[1], dims[0]); + } + default: + assert(false && "Unsupported dim number"); + } + return miopenStatusBadParm; +} + miopenStatus_t - cudnnSetTensorDescriptorFromDomain(miopenTensorDescriptor_t tensor, - Domain domain) { + cudnnSetTensorDescriptorFromDomain4SoftMax(miopenTensorDescriptor_t tensor, + Domain domain) { int dims[MAX_TENSOR_DIM]; switch (domain.get_dim()) { case 1: { @@ -280,7 +483,7 @@ miopenStatus_t dims[1] = rect.hi[1] - rect.lo[1] + 1; dims[2] = rect.hi[2] - rect.lo[2] + 1; return miopenSet4dTensorDescriptor( - tensor, miopenFloat, dims[2], dims[1], dims[0], 1); + tensor, miopenFloat, dims[2] * dims[1], dims[0], 1, 1); } case 4: { Rect<4> rect = domain; @@ -289,7 +492,7 @@ miopenStatus_t dims[2] = rect.hi[2] - rect.lo[2] + 1; dims[3] = rect.hi[3] - rect.lo[3] + 1; return miopenSet4dTensorDescriptor( - tensor, miopenFloat, dims[3], dims[2], dims[1], dims[0]); + tensor, miopenFloat, dims[3] * dims[2] * dims[1], dims[0], 1, 1); } case 5: { Rect<5> rect = domain; @@ -361,6 +564,8 @@ miopenStatus_t miopenDataType_t ff_to_cudnn_datatype(DataType type) { switch (type) { + case DT_HALF: + return miopenHalf; case DT_FLOAT: return miopenFloat; case DT_DOUBLE: @@ -387,6 +592,23 @@ hipblasDatatype_t ff_to_cuda_datatype(DataType type) { } return HIPBLAS_R_32F; } +#ifdef FF_USE_NCCL +ncclDataType_t ff_to_nccl_datatype(DataType type) { + switch (type) { + case DT_HALF: + return ncclHalf; + case DT_FLOAT: + return ncclFloat; + case DT_DOUBLE: + return ncclDouble; + case DT_INT32: + return ncclInt; + default: + assert(false && "Unspoorted nccl data type"); + } + return ncclFloat; +} +#endif void handle_unimplemented_hip_kernel(OperatorType op_type) { throw std::runtime_error("Unimplemented hip kernel for Operator: " + @@ -404,14 +626,19 @@ template __global__ void template __global__ void assign_kernel(int64_t *ptr, coord_t size, int64_t value); +template __global__ void + add_kernel(half *dst, half const *src, size_t size); template __global__ void add_kernel(float *dst, float const *src, size_t size); template __global__ void add_kernel(double *dst, double const *src, size_t size); -template __global__ void add_kernel(int *dst, int const *src, size_t size); template __global__ void - add_kernel(long *dst, long const *src, size_t size); + add_kernel(int32_t *dst, int32_t const *src, size_t size); +template __global__ void + add_kernel(int64_t *dst, int64_t const *src, size_t size); +template __global__ void + copy_kernel(half *dst, half const *src, coord_t size); template __global__ void copy_kernel(float *dst, float const *src, coord_t size); @@ -424,6 +651,8 @@ template __global__ void copy_kernel_with_replicate( template __global__ void copy_kernel_with_replicate( int64_t *dst, int64_t const *src, coord_t origin_size, coord_t size); +template __global__ void + copy_kernel(double *dst, double const *src, coord_t size); template __global__ void copy_kernel(int32_t *dst, int32_t const *src, coord_t size); template __global__ void @@ -448,7 +677,44 @@ template __global__ void apply_add_with_scale(int64_t *data_ptr, template __host__ void print_tensor(float const *ptr, size_t rect, char const *prefix); +template __host__ void + print_tensor(double const *ptr, size_t rect, char const *prefix); template __host__ void print_tensor(int32_t const *ptr, size_t rect, char const *prefix); template __host__ void print_tensor(int64_t const *ptr, size_t rect, char const *prefix); +template __host__ void + print_tensor(half const *ptr, size_t rect, char const *prefix); + +template __host__ void + save_tensor(float const *ptr, size_t rect, char const *file_name); +template __host__ void save_tensor(int32_t const *ptr, + size_t rect, + char const *file_name); +template __host__ void save_tensor(int64_t const *ptr, + size_t rect, + char const *file_name); +template __host__ void + save_tensor(half const *ptr, size_t rect, char const *file_name); + +template __host__ float *download_tensor(float const *ptr, + size_t num_elements); +template __host__ half *download_tensor(half const *ptr, + size_t num_elements); +template __host__ double *download_tensor(double const *ptr, + size_t num_elements); +template __host__ int32_t *download_tensor(int32_t const *ptr, + size_t num_elements); +template __host__ int64_t *download_tensor(int64_t const *ptr, + size_t num_elements); +template __host__ bool + download_tensor(float const *ptr, float *dst, size_t num_elements); +template __host__ bool download_tensor(double const *ptr, + double *dst, + size_t num_elements); +template __host__ bool download_tensor(int32_t const *ptr, + int32_t *dst, + size_t num_elements); +template __host__ bool download_tensor(int64_t const *ptr, + int64_t *dst, + size_t num_elements); diff --git a/src/runtime/inference_manager.cc b/src/runtime/inference_manager.cc new file mode 100644 index 0000000000..2a94df8b4d --- /dev/null +++ b/src/runtime/inference_manager.cc @@ -0,0 +1,694 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/ffconst_utils.h" +#include "flexflow/graph.h" +#include "flexflow/model.h" +#include "flexflow/ops/fused.h" +#include "flexflow/ops/noop.h" +#include "flexflow/parallel_ops/parallel_op.h" +#include "flexflow/request_manager.h" + +namespace FlexFlow { + +using namespace Legion; + +LegionRuntime::Logger::Category log_inf_mgr("InferenceManager"); +LegionRuntime::Logger::Category log_offload("Offloading"); + +InferenceManager::InferenceManager() {} + +InferenceManager *inference_manager_singleton = nullptr; + +/*static*/ +InferenceManager *InferenceManager::get_inference_manager() { + if (inference_manager_singleton == nullptr) { + // FFConfig ffconfig; + inference_manager_singleton = new InferenceManager(); + } + return inference_manager_singleton; +} + +bool parallel_tensor_list_overlaps(std::vector const &list1, + std::vector const &list2) { + for (auto const &pt1 : list1) { + for (auto const &pt2 : list2) { + if (pt1 == pt2) { + return true; + } + } + } + return false; +} + +void InferenceManager::compile_model_and_allocate_buffer(FFModel *model) { + // TODO: currently assume there is a single data-parallel pipeline + // (i.e., data-parallel-degree == 1) + assert(model->config.data_parallelism_degree == 1); + model->config.batchSize = BatchConfig::max_tokens_per_batch(); + model->compile_inference(); + Context ctx = model->config.lg_ctx; + Runtime *runtime = model->config.lg_hlr; + + // std::cout << std::endl << std::endl << "Operators MVs:" << std::endl; + int num_transformer_layers_per_stage = + model->current_transformer_layer_id / + model->config.pipeline_parallelism_degree + + 1; + int degree = model->config.data_parallelism_degree * + model->config.tensor_parallelism_degree; + + for (int op_idx = 0; op_idx < model->operators.size(); op_idx++) { + Op const *op = model->operators[op_idx]; + // Skip weight operators + if (op->op_type == OP_WEIGHT) { + continue; + } + // Get machine views + std::vector machine_views; + for (int j = 0; j < model->config.data_parallelism_degree; j++) { + MachineView mv; + mv.device_type = MachineView::GPU; + mv.ndims = 1; + // mv.start_device_id = 0; + mv.stride[0] = 1; + int parallel_degree = 1; + for (int k = 0; k < op->outputs[0]->num_dims; k++) { + parallel_degree *= op->outputs[0]->dims[k].degree; + } + mv.dim[0] = parallel_degree; + LayerID layer_guid = op->layer_guid; + if (op->op_type == OP_INPUT) { + // All inputs are assigned to the first stage + layer_guid.transformer_layer_id = 0; + } else if (layer_guid == LayerID::NO_ID) { + Op const *op_with_guid = op; + // Assert that we only have a single input + while (op_with_guid->layer_guid == LayerID::NO_ID) { + assert(op_with_guid->numInputs == 1); + op_with_guid = op_with_guid->inputs[0]->owner_op; + assert(op_with_guid != nullptr); + } + layer_guid = op_with_guid->layer_guid; + } + mv.start_device_id = degree * (layer_guid.transformer_layer_id / + num_transformer_layers_per_stage); + assert(mv == op->outputs[0]->machine_view); + machine_views.push_back(mv); + } + // std::cout << "operator: " << op->name << std::endl; + // for (int i = 0; i < op->numInputs; i++) { + // op->inputs[i]->print("input pt"); + // std::cout << "input mv: " << op->inputs[i]->machine_view << std::endl; + // } + // std::cout << "Op " << op->name << ": "; + for (int i = 0; i < op->numOutputs; i++) { + ParallelTensor pt_base = op->outputs[i]; + assert(tensor_buffer.find(pt_base) == tensor_buffer.end()); + + if (op->op_type == OP_REPLICATE) { + assert(op->numInputs == 1 && op->numOutputs == 1); + } + // pt_base->print("output pt"); + // std::cout << "output mv: " << pt_base->machine_view << std::endl; + + std::vector list; + bool found_parallel_tensor = false; + // Always enable memory reuse + // if (model->cpu_offload) { + if (true) { + for (auto const &pre_pt : tensor_buffer) { + bool used_by_future_operator = false; + bool used_by_current_operator = false; + if (pre_pt.first->get_shape() != pt_base->get_shape()) { + // Continue if shape mismatches + continue; + } + // Skip if pre_pt and pt_base are in different pipeline stages + // we compare their pipeline stages using the machine views + // of the first data pipeline + if (pre_pt.second[0]->machine_view != machine_views[0]) { + continue; + } + // Check that pt cannot be used as an input to the current operator + for (int j = 0; j < op->numInputs; j++) { + if (parallel_tensor_list_overlaps(tensor_buffer[op->inputs[j]], + pre_pt.second)) { + used_by_current_operator = true; + } + } + for (int j = 0; j < i; j++) { + assert(tensor_buffer.find(op->outputs[j]) != tensor_buffer.end()); + if (parallel_tensor_list_overlaps(tensor_buffer[op->outputs[j]], + pre_pt.second)) { + used_by_current_operator = true; + } + } + // Check that pt cannot be used by any subsequent operators + for (int op_idx2 = op_idx; op_idx2 < model->operators.size(); + op_idx2++) { + Op const *op2 = model->operators[op_idx2]; + for (int j = 0; j < op2->numInputs; j++) { + if (tensor_buffer.find(op2->inputs[j]) != tensor_buffer.end()) { + if (parallel_tensor_list_overlaps(tensor_buffer[op2->inputs[j]], + pre_pt.second)) { + used_by_future_operator = true; + } + } + } + } + if (!used_by_future_operator && !used_by_current_operator) { + found_parallel_tensor = true; + list = pre_pt.second; + } + } + if (!found_parallel_tensor) { + log_offload.print( + "Cannot find a previous tensor for operator(%d) output_idx(%d)", + op_idx, + i); + } + } + if (!found_parallel_tensor) { + for (int j = 0; j < model->config.data_parallelism_degree; j++) { + // Copy the metadata from pt_base to pt + ParallelTensor pt = new ParallelTensorBase(*pt_base); + pt->region = + runtime->create_logical_region(ctx, + pt_base->region.get_index_space(), + pt_base->region.get_field_space()); + pt->part = runtime->get_logical_partition( + ctx, pt->region, pt_base->part.get_index_partition()); + pt->machine_view = machine_views[j]; + // std::cout << "output mv: " << pt->machine_view << std::endl; + Domain part_domain = + runtime->get_index_space_domain(ctx, pt_base->parallel_is); + assert(pt->machine_view.get_domain() == part_domain); + list.push_back(pt); + } + } + assert(tensor_buffer.find(pt_base) == tensor_buffer.end()); + tensor_buffer[pt_base] = list; + } + // std::cout << std::endl; + } + + // Perform fusion optimizations + if (model->config.perform_fusion) { + fprintf(stderr, "Applying fusion optimizations during compilation...\n"); + fprintf( + stderr, "%zu operators before fusion...\n", model->operators.size()); + std::vector new_operators; + std::vector old_operators = model->operators; + while ( + model->apply_fusion(model->operators, new_operators, &tensor_buffer)) { + for (size_t i = 0; i < new_operators.size(); i++) { + for (int idx = 0; idx < new_operators[i]->numInputs; idx++) { + for (size_t j = i + 1; j < new_operators.size(); j++) { + if (new_operators[i]->inputs[idx]->owner_op == new_operators[j]) { + assert(false); + } + } + } + } + model->operators = new_operators; + } + assert(model->check_operators_integrity(old_operators, &tensor_buffer)); + fprintf(stderr, "%zu operators after fusion...\n", model->operators.size()); + } + + // print optimized graph + for (size_t i = 0; i < model->operators.size(); i++) { + Op *op = model->operators[i]; + if (op->op_type == OP_INPUT || op->op_type == OP_WEIGHT) { + continue; + } + printf("operator[%zu]: type(%s) guid(%lu)\n", + i, + get_operator_type_name(model->operators[i]->op_type).c_str(), + model->operators[i]->op_guid); + for (int j = 0; j < op->numInputs; j++) { + assert(tensor_buffer.find(op->inputs[j]) != tensor_buffer.end()); + LogicalRegion handle = tensor_buffer[op->inputs[j]][0]->region; + printf("\tinputs[%d] mapped_region(%d,%d,%d)\n", + j, + handle.get_index_space().get_id(), + handle.get_field_space().get_id(), + handle.get_tree_id()); + } + for (int j = 0; j < op->numOutputs; j++) { + LogicalRegion handle = tensor_buffer[op->outputs[j]][0]->region; + printf("\toutputs[%d] mapped_region(%d,%d,%d)\n", + j, + handle.get_index_space().get_id(), + handle.get_field_space().get_id(), + handle.get_tree_id()); + } + for (int j = 0; j < op->numWeights; j++) { + LogicalRegion handle = op->weights[j]->region; + printf("\tweights[%d] mapped_region(%d,%d,%d)\n", + j, + handle.get_index_space().get_id(), + handle.get_field_space().get_id(), + handle.get_tree_id()); + } + } +} + +void InferenceManager::init_operators_inference(FFModel *model) { + for (int batch_index = 0; batch_index < model->config.data_parallelism_degree; + batch_index++) { + for (size_t o = 0; o < model->operators.size(); o++) { + Op *op = model->operators[o]; + if (op->op_type == OP_WEIGHT) { + continue; + } + std::vector inputs(op->numInputs); + std::vector outputs(op->numOutputs); + for (int i = 0; i < op->numInputs; i++) { + assert(op->inputs[i] != nullptr); + assert(op->inputs[i]->parallel_is != IndexSpace::NO_SPACE); + assert(tensor_buffer[op->inputs[i]].size() > batch_index); + inputs[i] = tensor_buffer[op->inputs[i]][batch_index]; + assert(inputs[i]->parallel_is != IndexSpace::NO_SPACE); + } + assert(op->numOutputs > 0); + for (int i = 0; i < op->numOutputs; i++) { + assert(op->outputs[i] != nullptr); + assert(op->outputs[i]->parallel_is != IndexSpace::NO_SPACE); + assert(tensor_buffer[op->outputs[i]].size() > batch_index); + outputs[i] = tensor_buffer[op->outputs[i]][batch_index]; + if (i > 0) { + assert(outputs[0]->machine_view == outputs[i]->machine_view); + } + assert(outputs[i]->parallel_is != IndexSpace::NO_SPACE); + } + if (op->is_parallel_op()) { + ((ParallelOp *)op) + ->create_input_partition_inference(*model, inputs, outputs); + } + op->init_inference(*model, inputs, outputs); + } + } +} + +FutureMap InferenceManager::inference(FFModel *model, + int index, + BatchConfig const &bc) { + if (bc.get_mode() == INC_DECODING_MODE) { + BatchConfigFuture bcf = Future::from_value(bc); + return inference(model, index, bcf); + } else if (bc.get_mode() == BEAM_SEARCH_MODE) { + BatchConfig const *bc_ptr = &bc; + BeamSearchBatchConfig const *bsbc_ptr = + static_cast(bc_ptr); + BeamSearchBatchConfigFuture bcf = + Future::from_value(*bsbc_ptr); + return inference(model, index, bcf); + } else if (bc.get_mode() == TREE_VERIFY_MODE) { + BatchConfig const *bc_ptr = &bc; + TreeVerifyBatchConfig const *tvbc_ptr = + static_cast(bc_ptr); + TreeVerifyBatchConfigFuture bcf = + Future::from_value(*tvbc_ptr); + return inference(model, index, bcf); + } else { + assert(false && "Unsupported inference mode"); + } +} + +FutureMap InferenceManager::inference(FFModel *model, + int index, + BatchConfigFuture const &bc) { + // log_inf_mgr.print("mode(%d) num_active_tokens(%d) num_active_requests(%d)", + // bc.get_mode(), + // bc.num_active_tokens(), + // bc.num_active_requests()); + // assert(bc.num_active_tokens() > 0 && bc.num_active_requests() > 0); + // We currently assume that the index-th batch will be placed + // on the device_index-th device (except for the experts layers) + int batch_index = index % model->config.data_parallelism_degree; + FutureMap fm; + bool found_input_operator = false; + for (size_t o = 0; o < model->operators.size(); o++) { + Op *op = model->operators[o]; + if (op->op_type == OP_WEIGHT) { + continue; + } + if (op->op_type == OP_INPUT) { + // FIXME: this is a hack, should be replace with an input ParallelTensor + if (found_input_operator) { + // there is another input for position embedding; + // now only used in opt model, this input should be init after token + // input. + assert(op->numOutputs == 1); + ParallelTensor pt = tensor_buffer[op->outputs[0]][batch_index]; + load_positions(model, bc, pt, model->position_offset); + } else { + found_input_operator = true; + assert(op->numOutputs == 1); + ParallelTensor pt = tensor_buffer[op->outputs[0]][batch_index]; + load_input_tokens_from_batch_config(model, bc, pt, model->handlers); + load_inference_metadata_batch_config(model, bc, model->handlers); + } + } + + std::vector inputs(op->numInputs); + std::vector outputs(op->numOutputs); + for (int i = 0; i < op->numInputs; i++) { + assert(op->inputs[i] != nullptr); + assert(op->inputs[i]->parallel_is != IndexSpace::NO_SPACE); + assert(tensor_buffer[op->inputs[i]].size() > batch_index); + inputs[i] = tensor_buffer[op->inputs[i]][batch_index]; + assert(inputs[i]->parallel_is != IndexSpace::NO_SPACE); + } + for (int i = 0; i < op->numOutputs; i++) { + assert(op->outputs[i] != nullptr); + assert(op->outputs[i]->parallel_is != IndexSpace::NO_SPACE); + if (op->op_type == OP_INPUT && + tensor_buffer[op->outputs[i]].size() == 0) { + continue; + } + assert(tensor_buffer[op->outputs[i]].size() > batch_index); + outputs[i] = tensor_buffer[op->outputs[i]][batch_index]; + assert(outputs[i]->parallel_is != IndexSpace::NO_SPACE); + } + fm = op->inference(*model, bc, inputs, outputs); + } + return fm; +}; + +void InferenceManager::load_input_tokens_from_batch_config( + FFModel *model, + BatchConfigFuture const &bc, + ParallelTensor const input, + FFHandler *handlers) { + Context ctx = model->config.lg_ctx; + Runtime *runtime = model->config.lg_hlr; + size_t machine_view_hash = input->machine_view.hash(); + ArgumentMap argmap; + Domain domain = runtime->get_index_space_domain(ctx, input->parallel_is); + + switch (domain.get_dim()) { +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + MachineView view = input->machine_view; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + argmap.set_point(*it, \ + TaskArgument(&handlers[view.get_device_id(*it)], \ + sizeof(FFHandler))); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } + + IndexLauncher launcher(RM_LOAD_TOKENS_TASK_ID, + input->parallel_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement( + input->part, 0 /*projection id*/, WRITE_ONLY, EXCLUSIVE, input->region)); + launcher.add_field(0, FID_DATA); + runtime->execute_index_space(ctx, launcher); +} + +void InferenceManager::load_inference_metadata_batch_config( + FFModel *model, BatchConfigFuture const &bc, FFHandler *handlers) { + Context ctx = model->config.lg_ctx; + Runtime *runtime = model->config.lg_hlr; + ArgumentMap argmap; + + Domain domain = + runtime->get_index_space_domain(ctx, model->config.all_gpu_task_is); + Rect<1> task_rect = domain; + + int idx = 0; + for (PointInRectIterator<1> it(task_rect); it(); it++) { + FFHandler handler = handlers[idx++]; + argmap.set_point(*it, TaskArgument(&handler, sizeof(FFHandler))); + } + + IndexLauncher launcher(RM_LOAD_BATCH_CONFIG_TASK_ID, + model->config.all_gpu_task_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + FFConfig::DataParallelism_GPU); + launcher.add_future(bc); + runtime->execute_index_space(ctx, launcher); +} + +void InferenceManager::load_positions(FFModel *model, + BatchConfigFuture const &bc, + ParallelTensor position_input, + int offset) { + Context ctx = model->config.lg_ctx; + Runtime *runtime = model->config.lg_hlr; + size_t machine_view_hash = position_input->machine_view.hash(); + ArgumentMap argmap; + IndexLauncher launcher(RM_LOAD_POSITION_TASK_ID, + position_input->parallel_is, + TaskArgument(&offset, sizeof(int)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + machine_view_hash); + launcher.add_future(bc); + launcher.add_region_requirement(RegionRequirement(position_input->part, + 0 /*projection id*/, + WRITE_ONLY, + EXCLUSIVE, + position_input->region)); + launcher.add_field(0, FID_DATA); + runtime->execute_index_space(ctx, launcher); +} + +void InferenceManager::register_model_weights_loader(FFModel *model, + FileDataLoader *loader) { + model_weights_loaders[model] = loader; +} + +void FFModel::set_transformer_layer_id(int id) { + // We assume that users call this function with + // monotonically increasing ids + assert(id == current_transformer_layer_id + 1 || + (id == 0 && current_transformer_layer_id == 0)); + current_transformer_layer_id = id; + assert(id < MAX_NUM_TRANSFORMER_LAYERS); +} + +void FFModel::set_position_offset(int offset) { + assert(offset == 0 || offset == 2); + position_offset = offset; +} + +void FFModel::compile_inference() { + // Request at least four CPU processors for inference runs + assert( + config.cpusPerNode >= 4 && + "FlexFlow Serve requires at least four CPU cores per node, please add " + "`-ll:cpu 4` in the command line if you are using the C++ interface or " + "set `num_cpus` in `ff.init` if you are using the Python interface"); + Context ctx = config.lg_ctx; + Runtime *runtime = config.lg_hlr; + config.computationMode = COMP_MODE_INFERENCE; + create_operators_from_layers(); + // Launch the graph optimize task + { + FFModel *model = this; + TaskLauncher launcher(GRAPH_OPTIMIZE_TASK_ID, + TaskArgument(&model, sizeof(FFModel *))); + Future future = runtime->execute_task(ctx, launcher); + + PCG::GraphOptimalViewSerialized ret = + future.get_result(); + Deserializer dez(ret.data, ret.total_bytes); + // Reconstruct operators + PCG::Graph *best_graph = new PCG::Graph(this); + std::unordered_map optimal_views; + deserialize_graph_optimal_view(dez, best_graph, optimal_views); + operators.clear(); + convert_graph_to_operators(best_graph, optimal_views); + best_graph->print_dot(); + delete best_graph; + for (auto const &layer : layers) { + // map inputs to parallel tensor + if (layer->op_type == OP_INPUT) { + Tensor tensor = layer->outputs[0]; + ParallelTensor parallel_tensor = nullptr; + for (auto const &op : operators) { + if (op->op_type == OP_INPUT) { + NoOp *noop = (NoOp *)op; + if (noop->input_tensor_guid == tensor->tensor_guid) { + parallel_tensor = op->outputs[0]; + } + } + } + assert(parallel_tensor != nullptr); + tensor->parallel_tensor = parallel_tensor; + } + // map weights to parallel_tensor + for (int i = 0; i < layer->numWeights; i++) { + assert(layer->weights[i] != nullptr); + Tensor weight = layer->weights[i]; + ParallelTensor parallel_weight = nullptr; + for (auto const &op : operators) { + if (op->layer_guid == layer->layer_guid) { + assert(op->op_type == layer->op_type); + assert(op->numWeights == layer->numWeights); + parallel_weight = op->weights[i]; + } + } + assert(parallel_weight != nullptr); + weight->parallel_tensor = parallel_weight; + } + } + } + loss_op = nullptr; + metrics_op = nullptr; + // Perform inplace optimizations + if (config.enable_inplace_optimizations) { + for (size_t l = 1; l < operators.size(); l++) { + if (operators[l]->can_inplace_output()) { + // Assume outputs[0] is inplace with inputs[0] + assert(operators[l]->numOutputs == 1); + if (operators[l]->inputs[0]->owner_op != NULL) { + // int dim1 = operators[l]->outputs[0]->num_dims; + // int dim2 = operators[l]->inputs[0]->num_dims; + MachineView view1 = operators[l]->outputs[0]->machine_view; + MachineView view2 = operators[l]->inputs[0]->machine_view; + if (view1 == view2) { + // Check no others also need operators[l]->inputs[0] + bool found = false; + for (size_t i = 0; i < operators.size(); i++) { + if (i == l) { + continue; + } + for (int j = 0; j < operators[i]->numInputs; j++) { + if ((operators[i]->inputs[j]->owner_op == + operators[l]->inputs[0]->owner_op) && + (operators[i]->inputs[j]->owner_idx == + operators[l]->inputs[0]->owner_idx)) { + found = true; + } + } + } + if (!found) { + // Perform inplace + operators[l]->do_inplace_output(); + } + } + } + } + } + } + + for (size_t l = 0; l < operators.size(); l++) { + Op *op = operators[l]; + + for (int i = 0; i < op->numInputs; i++) { + assert(op->inputs[i]->owner_op != NULL); + } + for (int i = 0; i < op->numWeights; i++) { + assert(op->weights[i]->owner_op != NULL); + assert(op->weights[i]->region != LogicalRegion::NO_REGION); + parameters.push_back(op->weights[i]); + } + op->map_output_tensors(*this); + } + + // Check correctness + for (size_t l = 0; l < operators.size(); l++) { + Op *op = operators[l]; + for (int i = 0; i < op->numOutputs; i++) { + assert(op->outputs[i]->owner_op == op); + assert(op->outputs[i]->owner_idx == i); + assert(op->outputs[i]->parallel_tensor_guid != 0); + } + } + +#ifdef FF_USE_NCCL + for (size_t l = 0; l < operators.size(); l++) { + // Only create nccl for allreduce and fusedop for inference + // (fusedop may include allreduces) + if (operators[l]->op_type == OP_ALLREDUCE || + operators[l]->op_type == OP_FUSED) { + MachineView view = operators[l]->outputs[0]->machine_view; + if (view_hash_to_nccl_comms.find(view.hash()) == + view_hash_to_nccl_comms.end()) { + TaskLauncher launcher(NCCL_GETUNIQUEID_TASK_ID, TaskArgument(NULL, 0)); + Future future = runtime->execute_task(ctx, launcher); + ncclUniqueId ncclId = future.get_result(); + IndexSpace task_is = get_or_create_task_is(view); + ArgumentMap argmap; + IndexLauncher index_launcher( + NCCL_INIT_COMMS_TASK_ID, + task_is, + TaskArgument(&ncclId, sizeof(ncclUniqueId)), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + view.hash() /*MappingTagID*/); + FutureMap fm = runtime->execute_index_space(ctx, index_launcher); + fm.wait_all_results(); + int idx = 0; + Domain task_domain = runtime->get_index_space_domain(ctx, task_is); + ncclComm_t *nccl_comms = + (ncclComm_t *)malloc(sizeof(ncclComm_t) * task_domain.get_volume()); + for (Domain::DomainPointIterator it(task_domain); it; it++, idx++) { + nccl_comms[idx] = fm.get_result(*it); + } + view_hash_to_nccl_comms[view.hash()] = nccl_comms; + } + } + } +#endif +} + +std::string join_path(std::vector const &paths) { + std::string joined; + for (auto const &path : paths) { + if (joined.empty()) { + joined = path; + } else { + if (path[0] == '/') { + joined = path; + } else if (joined.back() != '/') { + joined += '/'; + joined += path; + } else { + joined += path; + } + } + } + return joined; +} + +}; // namespace FlexFlow diff --git a/src/runtime/initializer_kernel.cpp b/src/runtime/initializer_kernel.cpp index 6a0ebe3ba9..1005d93cec 100644 --- a/src/runtime/initializer_kernel.cpp +++ b/src/runtime/initializer_kernel.cpp @@ -19,7 +19,7 @@ #include "flexflow/utils/hip_helper.h" #include #include -#include +#include #include namespace FlexFlow { diff --git a/src/runtime/layer.cc b/src/runtime/layer.cc index 6dfd5f2f35..8f33f6db87 100644 --- a/src/runtime/layer.cc +++ b/src/runtime/layer.cc @@ -16,8 +16,10 @@ Layer::Layer(FFModel *model, const Tensor _input3, const Tensor _input4) : op_type(_otype), data_type(_dtype), - layer_guid(model->layer_global_guid++), numInputs(_numInputs), - numWeights(_numWeights), numOutputs(_numOutputs) { + layer_guid(model->layer_global_guid++, + model->current_transformer_layer_id, + model->model_id), + numInputs(_numInputs), numWeights(_numWeights), numOutputs(_numOutputs) { std::string pcname; if (_name == nullptr) { pcname = get_operator_type_name(op_type); @@ -50,8 +52,10 @@ Layer::Layer(FFModel *model, int _numOutputs, Tensor const *_tensors) : op_type(_otype), data_type(_dtype), - layer_guid(model->layer_global_guid++), numInputs(_numInputs), - numWeights(_numWeights), numOutputs(_numOutputs) { + layer_guid(model->layer_global_guid++, + model->current_transformer_layer_id, + model->model_id), + numInputs(_numInputs), numWeights(_numWeights), numOutputs(_numOutputs) { std::string pcname; if (_name == nullptr) { pcname = get_operator_type_name(op_type); diff --git a/src/runtime/memory_allocator.cc b/src/runtime/memory_allocator.cc new file mode 100644 index 0000000000..06a7c468a4 --- /dev/null +++ b/src/runtime/memory_allocator.cc @@ -0,0 +1,54 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/utils/memory_allocator.h" + +namespace FlexFlow { + +// declare Legion names +using Legion::coord_t; +using Legion::Memory; +using Realm::RegionInstance; + +MemoryAllocator::MemoryAllocator(Memory _memory) + : memory(_memory), reserved_ptr(nullptr), instance_ptr(nullptr), + reserved_total_size(0), reserved_allocated_size(0), + instance_total_size(0), instance_allocated_size(0) {} + +void MemoryAllocator::create_legion_instance(RegionInstance &inst, + size_t size) { + // Assert that we have used up previously created region instance + assert(instance_total_size == instance_allocated_size); + Realm::Rect<1, coord_t> bounds(Realm::Point<1, coord_t>(0), + Realm::Point<1, coord_t>(size - 1)); + std::vector field_sizes; + field_sizes.push_back(sizeof(char)); + Realm::RegionInstance::create_instance( + inst, memory, bounds, field_sizes, 0, Realm::ProfilingRequestSet()) + .wait(); + instance_ptr = inst.pointer_untyped(0, 0); + instance_total_size = size; + instance_allocated_size = 0; +} + +void MemoryAllocator::register_reserved_work_space(void *base, size_t size) { + // Assert that we haven't allocated anything before + assert(reserved_total_size == 0); + reserved_ptr = base; + reserved_total_size = size; + reserved_allocated_size = 0; +} + +}; // namespace FlexFlow diff --git a/src/runtime/model.cc b/src/runtime/model.cc index 6feddcd03c..a6d71ad1d2 100644 --- a/src/runtime/model.cc +++ b/src/runtime/model.cc @@ -22,11 +22,15 @@ #include "flexflow/ffconst_utils.h" #include "flexflow/graph.h" #include "flexflow/mapper.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/aggregate.h" #include "flexflow/ops/aggregate_spec.h" +#include "flexflow/ops/arg_topk.h" +#include "flexflow/ops/argmax.h" #include "flexflow/ops/attention.h" #include "flexflow/ops/batch_matmul.h" #include "flexflow/ops/batch_norm.h" +#include "flexflow/ops/beam_topk.h" #include "flexflow/ops/cache.h" #include "flexflow/ops/cast.h" #include "flexflow/ops/concat.h" @@ -35,27 +39,38 @@ #include "flexflow/ops/element_binary.h" #include "flexflow/ops/element_unary.h" #include "flexflow/ops/embedding.h" +#include "flexflow/ops/experts.h" #include "flexflow/ops/flat.h" #include "flexflow/ops/fused.h" #include "flexflow/ops/gather.h" #include "flexflow/ops/groupby.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/layer_norm.h" #include "flexflow/ops/linear.h" #include "flexflow/ops/noop.h" #include "flexflow/ops/pool_2d.h" #include "flexflow/ops/reduce.h" #include "flexflow/ops/reshape.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/residual_rms_norm.h" #include "flexflow/ops/reverse.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/ops/sampling.h" +#include "flexflow/ops/sigmoid_silu_multi.h" #include "flexflow/ops/softmax.h" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" #include "flexflow/ops/split.h" #include "flexflow/ops/topk.h" #include "flexflow/ops/transpose.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" + #include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/combine.h" #include "flexflow/parallel_ops/fused_parallel_op.h" #include "flexflow/parallel_ops/partition.h" #include "flexflow/parallel_ops/reduction.h" #include "flexflow/parallel_ops/replicate.h" +#include "flexflow/request_manager.h" #include "flexflow/substitution.h" #include "flexflow/utils/random_utils.h" #include "flexflow/utils/test_utils.h" @@ -108,7 +123,8 @@ Op::Op(FFModel &model, ParallelTensor const _input4) : op_type(_otype), data_type(_dtype), op_guid(model.op_global_guid++), numInputs(_numInputs), numWeights(_numWeights), numOutputs(_numOutputs), - profiling(model.config.profiling) { + profiling(model.config.profiling), + inference_debugging(model.config.inference_debugging) { for (int i = 0; i < MAX_NUM_INPUTS; i++) { inputs[i] = NULL; } @@ -153,7 +169,8 @@ Op::Op(FFModel &model, ParallelTensor const *_inputs) : op_type(_otype), data_type(_dtype), op_guid(model.op_global_guid++), numInputs(_numInputs), numWeights(_numWeights), numOutputs(_numOutputs), - profiling(model.config.profiling) { + profiling(model.config.profiling), + inference_debugging(model.config.inference_debugging) { std::string pcname; if (_name == NULL) { pcname = get_operator_type_name(op_type); @@ -596,13 +613,48 @@ ncclComm_t Op::init_nccl_comms_task(Task const *task, ncclId); return ncclComm; } + +void Op::finish_nccl_comms_task(Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + ncclComm_t comm = *((ncclComm_t *)task->local_args); +#if (NCCL_MAJOR == 2) && (NCCL_MINOR >= 14) + checkNCCL(ncclCommFinalize(comm)); +#endif + checkNCCL(ncclCommDestroy(comm)); +} #endif +/** + * @brief The ParallelDimMappingRecord class's constructor. It sets the object's + * type field equal to the value passed as the constructor's argument, and + * initializes all other fields to -1. + * + * @param[in] type The MappingRecordType to use to initialize the + * ParallelDimMappingRecord. + */ ParallelDimMappingRecord::ParallelDimMappingRecord(MappingRecordType type) : type(type), output_dim(-1), input_dim(-1), weight_dim(-1), output_idx(-1), input_idx(-1), weight_idx(-1) {} /*static*/ +/** + * @brief Builds and initializes a ParallelDimMappingRecord object of + * INPUT_OUTPUT MappingRecordType. + * + * This function should be used to create a ParallelDimMappingRecord to track an + * operator's dimension relation between the input and the output tensor + * + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] input_dim The index of the input dimension part of the + * dimension relation + * @param[in] output_idx The index of the output tensor (nonzero if there are + * multiple outputs) + * @param[in] output_dim The index of the output dimension part of the + * dimension relation + */ ParallelDimMappingRecord ParallelDimMappingRecord::input_output_record( int input_idx, int input_dim, @@ -626,6 +678,22 @@ ParallelDimMappingRecord ParallelDimMappingRecord::input_output_record( } /*static*/ +/** + * @brief Builds and initializes a ParallelDimMappingRecord object of + * INPUT_WEIGHT MappingRecordType. + * + * This function should be used to create a ParallelDimMappingRecord to track an + * operator's dimension relation between the input and the weights tensor + * + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] input_dim The index of the input dimension part of the + * dimension relation + * @param[in] weight_idx The index of the weight tensor (nonzero if there are + * multiple weights) + * @param[in] weight_dim The index of the weight dimension part of the + * dimension relation + */ ParallelDimMappingRecord ParallelDimMappingRecord::input_weight_record( int input_idx, int input_dim, @@ -653,6 +721,39 @@ MappingRecordType ParallelDimMappingRecord::get_type() const { } /*static*/ +/** @brief A wrapper around the main version of the + * construct_weight_parallel_dims function. + * + * This wrapper allows you to append multiple dimension relations at once to a + * vector of ParallelDimMappingRecord entries. The relations must be between + * dimensions of the same pair of input and weight tensors. Unlike the other + * construct_weight_parallel_dims wrapper below, this function allows you to + * specify the MappingOperation for each pair of dimensions for which you will + * be creating a new ParallelDimMappingRecord. + * + * The function takes a vector of (int, MappingOperation, int) tuples, where the + * int members represent the indexes of the two dimensions in a relation, and + * the MappingOperation member specifies the type of mapping operation. Just + * like the other wrapper, this function simply calls the main version of + * construct_weight_parallel_dims for each pair, using the same values across + * all calls for all other parameters. + * + * This function should NOT be used to track dimension relations between the + * input and weights tensors; construct_weight_parallel_dims should be used + * instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] mappings A vector of tuples, each including a pair of + * integers (representing the indexes of the input and weight dimensions in a + * relation), and a MappingOperation, specifying the mapping operation for the + * pair of dimensions. + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] weight_idx The index of the weight tensor (nonzero if there are + * multiple weights) + * + */ void Op::construct_weight_parallel_dims( std::vector &records, std::vector> mappings, @@ -669,6 +770,30 @@ void Op::construct_weight_parallel_dims( } /*static*/ +/** @brief A wrapper around the main version of the + * construct_weight_parallel_dims function. + * + * This wrapper allows you to append multiple dimension relations at once to a + * vector of ParallelDimMappingRecord entries. The relations must be between + * dimensions of the same pair of input and weight tensors. The function takes a + * vector of (input, weight) dimension index pairs and simply calls the main + * version of construct_weight_parallel_dims for each such pair, using the same + * values across all calls for all other parameters. + * + * This function should NOT be used to track dimension relations between the + * input and weights tensors; construct_weight_parallel_dims should be used + * instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] mappings A vector of integer pairs, each representing the + * indexes of the input and weight dimensions in a relation. + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] weight_idx The index of the weight tensor (nonzero if there are + * multiple weights) + * + */ void Op::construct_weight_parallel_dims( std::vector &records, std::vector> mappings, @@ -681,6 +806,30 @@ void Op::construct_weight_parallel_dims( } /*static*/ +/** + * @brief Creates a new ParallelDimMappingRecord (of the INPUT_WEIGHT + * MappingRecordType flavor) and appends it to an existing vector of + * ParallelDimMappingRecord entries. + * + * This function creates a new ParallelDimMappingRecord to track a dimension + * relation between a dimension from the input tensor and a dimension from the + * weight tensor. This function should NOT be used to track dimension relations + * between the input and output tensors; construct_output_parallel_dims should + * be used instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] input_dim The index of the input dimension part of the + * dimension relation + * @param[in] weight_dim The index of the weight dimension part of the + * dimension relation + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] weight_idx The index of the weight tensor (nonzero if there are + * multiple weights) + * @param[in] operation The parallelization operation (partition or + * replication) associated with the dimension relation + */ void Op::construct_weight_parallel_dims( std::vector &records, int input_dim, @@ -692,12 +841,20 @@ void Op::construct_weight_parallel_dims( input_idx, input_dim, weight_idx, weight_dim, operation)); } +/** @brief Calls the corresponding version of construct_weight_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_weight_parallel_dims( std::vector> mappings, int input_idx, int weight_idx) { Op::construct_weight_parallel_dims( *this->parallel_dims_mapping, mappings, input_idx, weight_idx); } +/** @brief Calls the corresponding version of construct_weight_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_weight_parallel_dims( std::vector> mappings, int input_idx, @@ -706,6 +863,10 @@ void Op::register_weight_parallel_dims( *this->parallel_dims_mapping, mappings, input_idx, weight_idx); } +/** @brief Calls the corresponding version of construct_weight_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_weight_parallel_dims( int input_dim, int weight_dim, @@ -721,6 +882,39 @@ void Op::register_weight_parallel_dims( } /*static*/ +/** @brief A wrapper around the main version of the + * construct_output_parallel_dims function. + * + * This wrapper allows you to append multiple dimension relations at once to a + * vector of ParallelDimMappingRecord entries. The relations must be between + * dimensions of the same pair of input and output tensors. Unlike the other + * construct_output_parallel_dims wrapper below, this function allows you to + * specify the MappingOperation for each pair of dimensions for which you will + * be creating a new ParallelDimMappingRecord. + * + * The function takes a vector of (int, MappingOperation, int) tuples, where the + * int members represent the indexes of the two dimensions in a relation, and + * the MappingOperation member specifies the type of mapping operation. Just + * like the other wrapper, this function simply calls the main version of + * construct_output_parallel_dims for each pair, using the same values across + * all calls for all other parameters. + * + * This function should NOT be used to track dimension relations between the + * input and weights tensors; construct_weight_parallel_dims should be used + * instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] mappings A vector of tuples, each including a pair of + * integers (representing the indexes of the input and output dimensions in a + * relation), and a MappingOperation, specifying the mapping operation for the + * pair of dimensions. + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] output_idx The index of the output tensor (nonzero if there are + * multiple outputs) + * + */ void Op::construct_output_parallel_dims( std::vector &records, std::vector> mappings, @@ -737,6 +931,30 @@ void Op::construct_output_parallel_dims( } /*static*/ +/** @brief A wrapper around the main version of the + * construct_output_parallel_dims function. + * + * This wrapper allows you to append multiple dimension relations at once to a + * vector of ParallelDimMappingRecord entries. The relations must be between + * dimensions of the same pair of input and output tensors. The function takes a + * vector of (input, output) dimension index pairs and simply calls the main + * version of construct_output_parallel_dims for each such pair, using the same + * values across all calls for all other parameters. + * + * This function should NOT be used to track dimension relations between the + * input and weights tensors; construct_weight_parallel_dims should be used + * instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] mappings A vector of integer pairs, each representing the + * indexes of the input and output dimensions in a relation. + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] output_idx The index of the output tensor (nonzero if there are + * multiple outputs) + * + */ void Op::construct_output_parallel_dims( std::vector &records, std::vector> mappings, @@ -749,6 +967,30 @@ void Op::construct_output_parallel_dims( } /*static*/ +/** + * @brief Creates a new ParallelDimMappingRecord (of the INPUT_OUTPUT + * MappingRecordType flavor) and appends it to an existing vector of + * ParallelDimMappingRecord entries. + * + * This function creates a new ParallelDimMappingRecord to track a dimension + * relation between a dimension from the input tensor and a dimension from the + * output tensor. This function should NOT be used to track dimension relations + * between the input and weights tensors; construct_weight_parallel_dims should + * be used instead. + * + * @param[out] records The (potentially empty) vector of existing + * ParallelDimMappingRecord entries + * @param[in] input_dim The index of the input dimension part of the + * dimension relation + * @param[in] output_dim The index of the output dimension part of the + * dimension relation + * @param[in] input_idx The index of the input tensor (nonzero if there are + * multiple inputs) + * @param[in] output_idx The index of the output tensor (nonzero if there are + * multiple outputs) + * @param[in] operation The parallelization operation (partition or + * replication) associated with the dimension relation + */ void Op::construct_output_parallel_dims( std::vector &records, int input_dim, @@ -760,12 +1002,20 @@ void Op::construct_output_parallel_dims( input_idx, input_dim, output_idx, output_dim, operation)); } +/** @brief Calls the corresponding version of construct_output_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_output_parallel_dims( std::vector> mappings, int input_idx, int output_idx) { Op::construct_output_parallel_dims( *this->parallel_dims_mapping, mappings, input_idx, output_idx); } +/** @brief Calls the corresponding version of construct_output_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_output_parallel_dims( std::vector> mappings, int input_idx, @@ -774,6 +1024,10 @@ void Op::register_output_parallel_dims( *this->parallel_dims_mapping, mappings, input_idx, output_idx); } +/** @brief Calls the corresponding version of construct_output_parallel_dims, + * and passes the Op class's parallel_dims_mapping vector, so that the resulting + * ParallelDimMappingRecord are appended to it + */ void Op::register_output_parallel_dims( int input_dim, int output_dim, @@ -992,6 +1246,50 @@ void Op::set_argumentmap_for_init(FFModel const &ff, ArgumentMap &argmap) { } } +void Op::set_argumentmap_for_init_inference(FFModel const &ff, + ArgumentMap &argmap, + ParallelTensor const output0) { + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + Domain domain = runtime->get_index_space_domain(ctx, this->parallel_is); + MachineView const view = output0->machine_view; + assert(ff.config.computationMode == COMP_MODE_INFERENCE); + switch (domain.get_dim()) { +#ifdef FF_USE_NCCL +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + FFHandler handle = ff.handlers[view.get_device_id(*it)]; \ + if (op_type == OP_ALLREDUCE) { \ + ncclComm_t *nccl_comms = ff.find_nccl_comms(view); \ + handle.ncclComm = nccl_comms[idx++]; \ + } \ + argmap.set_point(*it, TaskArgument(&handle, sizeof(FFHandler))); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC +#else +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + for (PointInRectIterator it(rect); it(); it++) { \ + FFHandler handle = ff.handlers[view.get_device_id(*it)]; \ + argmap.set_point(*it, TaskArgument(&handle, sizeof(FFHandler))); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC +#endif + default: + assert(false); + } +} + void Op::set_opmeta_from_futuremap(FFModel const &ff, FutureMap const &fm) { Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; @@ -1013,6 +1311,29 @@ void Op::set_opmeta_from_futuremap(FFModel const &ff, FutureMap const &fm) { } } +void Op::set_opmeta_from_futuremap_inference(FFModel const &ff, + FutureMap const &fm, + ParallelTensor const output) { + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + Domain domain = runtime->get_index_space_domain(ctx, parallel_is); + switch (domain.get_dim()) { +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + inference_meta[output][idx++] = fm.get_result(*it); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } +} + void Op::set_argumentmap_for_forward(FFModel const &ff, ArgumentMap &argmap) { Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; @@ -1035,6 +1356,30 @@ void Op::set_argumentmap_for_forward(FFModel const &ff, ArgumentMap &argmap) { } } +void Op::set_argumentmap_for_inference(FFModel const &ff, + ArgumentMap &argmap, + ParallelTensor const output) { + Context ctx = ff.config.lg_ctx; + Runtime *runtime = ff.config.lg_hlr; + Domain domain = runtime->get_index_space_domain(ctx, parallel_is); + switch (domain.get_dim()) { +#define DIMFUNC(DIM) \ + case DIM: { \ + Rect rect = domain; \ + int idx = 0; \ + for (PointInRectIterator it(rect); it(); it++) { \ + OpMeta *mp = inference_meta[output][idx++]; \ + argmap.set_point(*it, TaskArgument(&mp, sizeof(OpMeta *))); \ + } \ + break; \ + } + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } +} + void Op::set_argumentmap_for_backward(FFModel const &ff, ArgumentMap &argmap) { Context ctx = ff.config.lg_ctx; Runtime *runtime = ff.config.lg_hlr; @@ -1147,7 +1492,8 @@ bool Op::get_weight_parameter(TNParameter tnp, return true; } -OpMeta::OpMeta(FFHandler _handle) : handle(_handle), profiling(false) { +OpMeta::OpMeta(FFHandler _handle) + : handle(_handle), profiling(false), inference_debugging(false) { for (int i = 0; i < MAX_NUM_INPUTS; i++) { trainableInputs[i] = true; } @@ -1160,6 +1506,7 @@ OpMeta::OpMeta(FFHandler _handle) : handle(_handle), profiling(false) { for (int i = 0; i < MAX_NUM_OUTPUTS; i++) { output_type[i] = DT_NONE; } + decoding_step = 0; } OpMeta::OpMeta(FFHandler _handle, Op const *op) : OpMeta(_handle) { @@ -1172,44 +1519,14 @@ OpMeta::OpMeta(FFHandler _handle, Op const *op) : OpMeta(_handle) { for (int i = 0; i < op->numOutputs; i++) { output_type[i] = op->outputs[i]->data_type; } + decoding_step = 0; } -FFModel::FFModel(FFConfig &_config) - : op_global_guid(OP_GUID_FIRST_VALID), - layer_global_guid(LAYER_GUID_FIRST_VALID), - tensor_global_guid(TENSOR_GUID_FIRST_VALID), - parallel_tensor_global_guid(PARALLEL_TENSOR_GUID_FIRST_VALID), - node_global_guid(NODE_GUID_FIRST_VALID), config(_config), optimizer(NULL), - loss_op(NULL), metrics_op(NULL), simulator(NULL) { - this->search = new PCG::SearchHelper(this); - this->graph_search = new PCG::GraphSearchHelper(this); - +FFRuntime::FFRuntime(FFConfig &config) { Runtime *runtime = config.lg_hlr; Context ctx = config.lg_ctx; - // Register machine views - register_all_machine_views(config.numNodes, - config.workersPerNode, - config.cpusPerNode, - all_valid_views); - metrics_input = -1; - // Load strategy file - // Create field space - { - FieldAllocator allocator = - runtime->create_field_allocator(ctx, config.field_space); - allocator.allocate_field(sizeof(float), FID_DATA); - } - // Build training dataset - // if (config.datasetPath.length() == 0) { - // dataLoader = NULL; - //} else { - // dataLoader = new DataLoader(config.datasetPath); - //} ArgumentMap argmap; - // Rect<1> task_rect(Point<1>(0), - // Point<1>(config.workersPerNode * config.numNodes - 1)); - // IndexSpaceT<1> task_is = runtime->create_index_space(ctx, task_rect); Domain domain = runtime->get_index_space_domain(ctx, config.all_gpu_task_is); Rect<1> task_rect = domain; @@ -1219,6 +1536,9 @@ FFModel::FFModel(FFConfig &_config) // info.myRank = rank++; // info.allRanks = config.workersPerNode * config.numNodes; info.workSpaceSize = config.workSpaceSize; + info.offload_reserve_space_size = + config.cpu_offload ? config.offload_reserve_space_size : 0; + info.quantization_type = config.quantization_type; info.allowTensorOpMathConversion = config.allow_tensor_op_math_conversion; argmap.set_point(*it, TaskArgument(&info, sizeof(FFInitInfo))); } @@ -1240,6 +1560,92 @@ FFModel::FFModel(FFConfig &_config) } } +FFRuntime *ffruntime_singleton = nullptr; + +int FFModel::model_counter = 0; + +FFModel::FFModel(FFConfig &_config, bool cpu_offload) + : op_global_guid(OP_GUID_FIRST_VALID), + layer_global_guid(LAYER_GUID_FIRST_VALID), + tensor_global_guid(TENSOR_GUID_FIRST_VALID), + parallel_tensor_global_guid(PARALLEL_TENSOR_GUID_FIRST_VALID), + node_global_guid(NODE_GUID_FIRST_VALID), current_transformer_layer_id(0), + config(_config), optimizer(NULL), loss_op(NULL), metrics_op(NULL), + simulator(NULL) { + this->search = new PCG::SearchHelper(this); + this->graph_search = new PCG::GraphSearchHelper(this); + this->cpu_offload = cpu_offload; + + if (ffruntime_singleton == nullptr) { + ffruntime_singleton = new FFRuntime(_config); + } + + Runtime *runtime = config.lg_hlr; + Context ctx = config.lg_ctx; + // Register machine views + register_all_machine_views(config.numNodes, + config.workersPerNode, + config.cpusPerNode, + all_valid_views); + metrics_input = -1; + // Load strategy file + // Create field space + //{ + // FieldAllocator allocator = + // runtime->create_field_allocator(ctx, config.field_space); + // allocator.allocate_field(sizeof(float), FID_DATA); + //} + // Build training dataset + // if (config.datasetPath.length() == 0) { + // dataLoader = NULL; + //} else { + // dataLoader = new DataLoader(config.datasetPath); + //} + for (int idx = 0; idx < config.workersPerNode * config.numNodes; idx++) { + handlers[idx] = ffruntime_singleton->handlers[idx]; + } + model_id = model_counter++; +} + +FFModel::~FFModel() { + // Destroy nccl communication groups +#ifdef FF_USE_NCCL + if (config.computationMode == COMP_MODE_TRAINING) { + Context ctx = config.lg_ctx; + Runtime *runtime = config.lg_hlr; + for (auto const &comm : view_hash_to_nccl_comms) { + // Find the machine view that has the hash + MachineView view; + for (size_t l = 0; l < operators.size(); l++) { + view = operators[l]->outputs[0]->machine_view; + if (view.hash() == comm.first) { + break; + } + } + assert(view.hash() == comm.first && "Cannot find the machine view"); + IndexSpace task_is = get_or_create_task_is(view); + Domain domain = runtime->get_index_space_domain(ctx, task_is); + ArgumentMap argmap; + int idx = 0; + for (Domain::DomainPointIterator it(domain); it; it++, idx++) { + argmap.set_point(*it, + TaskArgument(&comm.second[idx], sizeof(ncclComm_t))); + } + IndexLauncher index_launcher(NCCL_FINISH_COMMS_TASK_ID, + task_is, + TaskArgument(nullptr, 0), + argmap, + Predicate::TRUE_PRED, + false /*must*/, + 0 /*mapper_id*/, + comm.first); + FutureMap fm = runtime->execute_index_space(ctx, index_launcher); + fm.wait_all_results(); + } + } +#endif +} + void FFModel::clear_graph_search_cache() { this->graph_search->clear_cache(); this->search->clear_cache(); @@ -1250,7 +1656,7 @@ ncclComm_t *FFModel::find_nccl_comms(MachineView const &view) const { auto const &it = view_hash_to_nccl_comms.find(view.hash()); if (it == view_hash_to_nccl_comms.end()) { assert(config.computationMode == COMP_MODE_INFERENCE); - return NULL; + return nullptr; } else { return it->second; } @@ -1506,6 +1912,7 @@ ParallelParameter FFModel::create_parallel_weight(ParallelDim const dims[], for (int i = 0; i < NDIM; i++) { p->dims[i] = dims[NDIM - 1 - i]; } + assert(p->get_volume() > 0); assert(p->check_valid()); return p; @@ -1620,6 +2027,12 @@ void FFModel::map_tensor_with_dim2(ParallelTensor tensor, case DT_INT64: allocator.allocate_field(sizeof(int64_t), FID_DATA); break; + case DT_INT4: + allocator.allocate_field(sizeof(char), FID_DATA); + break; + case DT_INT8: + allocator.allocate_field(sizeof(char), FID_DATA); + break; default: assert(false); } @@ -1668,8 +2081,10 @@ void FFModel::map_tensor_with_dim2(ParallelTensor tensor, runtime->get_logical_partition(ctx, tensor->region_grad, ip); } } - // Step 3: initialize the tensor - if (tensor->initializer != NULL) { + // Step 3: initialize the tensor; don't randomly initialize weights + // for inference + if (tensor->initializer != NULL && + config.computationMode == COMP_MODE_TRAINING) { tensor->initializer->init(this, tensor); } } @@ -1706,6 +2121,7 @@ void FFModel::map_weight_with_dim(ParallelTensor weight, switch (parallel_op->op_type) { case OP_LINEAR: case OP_EMBEDDING: + case OP_EXPERTS: case OP_MULTIHEAD_ATTENTION: { switch (tdim) { #define DIMFUNC(TDIM) \ @@ -2515,8 +2931,11 @@ void FFModel::compile(Optimizer *_optimizer, compile(loss_type, metrics, comp_mode); } -bool FFModel::apply_fusion(std::vector const &operators, - std::vector &new_operators) { +bool FFModel::apply_fusion( + std::vector const &operators, + std::vector &new_operators, + std::unordered_map> + *parallel_tensor_mapping) { // Context ctx = config.lg_ctx; // Runtime* runtime = config.lg_hlr; for (size_t l = 1; l < operators.size() - 1; l++) { @@ -2526,7 +2945,8 @@ bool FFModel::apply_fusion(std::vector const &operators, operators[l]->op_type == OP_WEIGHT) { continue; } - // don't fuse parallel op except allReduce since they have different + // don't fuse parallel op except allReduce since they have different + // parallel_is in forward/backward if (operators[l]->is_parallel_op() && operators[l]->op_type != OP_ALLREDUCE) { @@ -2581,7 +3001,8 @@ bool FFModel::apply_fusion(std::vector const &operators, fused_op = new FusedOp(*this, operators[i]); allocate_new_fused_op = true; } - if (fused_op->add_operator(*this, operators[l])) { + if (fused_op->add_operator( + *this, operators[l], parallel_tensor_mapping)) { // Construct new operators new_operators.clear(); for (size_t j = 0; j < i; j++) { @@ -2599,7 +3020,9 @@ bool FFModel::apply_fusion(std::vector const &operators, (op->inputs[idx]->owner_op == operators[i])) { int found = -1; for (int k = 0; k < fused_op->numOutputs; k++) { - if (fused_op->outputs[k]->region == op->inputs[idx]->region) { + if (fused_op->use_same_regions(fused_op->outputs[k], + op->inputs[idx], + parallel_tensor_mapping)) { assert(found == -1); found = k; } @@ -2615,7 +3038,6 @@ bool FFModel::apply_fusion(std::vector const &operators, assert(new_operators.size() + 1 == operators.size()); return true; } else { - // TODO: delete fused_op to avoid memory leakage if (allocate_new_fused_op) { delete fused_op; } @@ -2647,11 +3069,13 @@ Op *FFModel::create_operator_from_layer( dims[num_dims].degree = 1; dims[num_dims].parallel_idx = -1; dims[num_dims].is_replica_dim = true; + if (config.tensor_parallelism_degree > 1 && num_inputs != 1) { dims[num_dims].size *= config.tensor_parallelism_degree; dims[num_dims].degree *= config.tensor_parallelism_degree; dims[num_dims].parallel_idx = 0; } + //TODO temporary fix for input to attention QK, fix it after fuse the attention block else if(config.tensor_parallelism_degree > 1){ //n heads @@ -2659,6 +3083,7 @@ Op *FFModel::create_operator_from_layer( dims[num_dims].degree *= config.tensor_parallelism_degree; dims[num_dims].parallel_idx = 0; } + // create_parallel_tensor adds an NoOp into operators ParallelTensor pt = create_parallel_tensor_legion_ordering(num_dims + 1, @@ -2668,6 +3093,7 @@ Op *FFModel::create_operator_from_layer( 0, true /*gradients*/, tensor->tensor_guid); + assert(pt->get_shape().is_valid()); // assert that this tensor hasn't been mapped before assert(tensor->parallel_tensor == nullptr); tensor->parallel_tensor = pt; @@ -2688,6 +3114,24 @@ Op *FFModel::create_operator_from_layer( operators.push_back(op); return op; } + case OP_SPEC_INC_MULTIHEAD_SELF_ATTENTION: { + Op *op = SpecIncMultiHeadSelfAttention::create_operator_from_layer( + *this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + Op *op = IncMultiHeadSelfAttention::create_operator_from_layer( + *this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + Op *op = TreeIncMultiHeadSelfAttention::create_operator_from_layer( + *this, layer, inputs); + operators.push_back(op); + return op; + } case OP_BATCHMATMUL: { Op *op = BatchMatmul::create_operator_from_layer(*this, layer, inputs); operators.push_back(op); @@ -2762,6 +3206,35 @@ Op *FFModel::create_operator_from_layer( operators.push_back(op); return op; } + case OP_RESIDUAL_LAYERNORM: { + Op *op = + ResidualLayerNorm::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + Op *op = AddBiasResidualLayerNorm::create_operator_from_layer( + *this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_SIGMOID_SILU_MULTI: { + Op *op = + SigmoidSiluMulti::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_RMS_NORM: { + Op *op = RMSNorm::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_RESIDUAL_RMS_NORM: { + Op *op = + ResidualRMSNorm::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } case OP_LINEAR: { Op *op = Linear::create_operator_from_layer(*this, layer, inputs); operators.push_back(op); @@ -2802,6 +3275,26 @@ Op *FFModel::create_operator_from_layer( operators.push_back(op); return op; } + case OP_ARG_TOPK: { + Op *op = ArgTopK::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_BEAM_TOPK: { + Op *op = BeamTopK::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_SAMPLING: { + Op *op = Sampling::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } + case OP_ARGMAX: { + Op *op = ArgMax::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } case OP_GROUP_BY: { Op *op = Group_by::create_operator_from_layer(*this, layer, inputs); operators.push_back(op); @@ -2817,11 +3310,17 @@ Op *FFModel::create_operator_from_layer( operators.push_back(op); return op; } + case OP_EXPERTS: { + Op *op = Experts::create_operator_from_layer(*this, layer, inputs); + operators.push_back(op); + return op; + } default: assert(false); } } + bool FFModel::is_transformer_block(int layer_idx) const { auto const &l = layers[layer_idx]; if (l->op_type == OP_DROPOUT && layer_idx >= 4 && @@ -2856,6 +3355,7 @@ bool FFModel::is_mlp_block(int layer_idx) const { void FFModel::create_operators_from_layers() { std::map tensors_to_parallel_tensors; + // for (auto const &l : layers) { for (int layer_idx = 0; layer_idx < layers.size(); layer_idx++) { auto const &l = layers[layer_idx]; std::vector inputs; @@ -2865,6 +3365,7 @@ void FFModel::create_operators_from_layers() { tensors_to_parallel_tensors.end()); inputs.push_back(tensors_to_parallel_tensors[l->inputs[i]]); } + // Op *op = create_operator_from_layer(l, inputs); Op *op = nullptr; if (config.tensor_parallelism_degree > 1 && l->op_type == OP_LAYERNORM && @@ -2881,6 +3382,7 @@ void FFModel::create_operators_from_layers() { op = create_operator_from_layer(l, inputs); } + // add replicate operators after op if needed if (config.tensor_parallelism_degree > 1 && l->op_type == OP_EMBEDDING) { // assert(op->numOutputs == 1); @@ -2890,6 +3392,7 @@ void FFModel::create_operators_from_layers() { // config.tensor_parallelism_degree); // operators.push_back(repl); // op = repl; + } else if (config.tensor_parallelism_degree > 1 && (is_transformer_block(layer_idx) || is_mlp_block(layer_idx) || // llama mlp layer @@ -2980,6 +3483,7 @@ void FFModel::compile(LossType loss_type, ParallelTensor parallel_weight = nullptr; for (auto const &op : operators) { if (op->layer_guid == layer->layer_guid) { + std::cout << "opopop: " << op->name << "\n"; assert(op->op_type == layer->op_type); assert(op->numWeights == layer->numWeights); parallel_weight = op->weights[i]; @@ -3039,6 +3543,7 @@ void FFModel::compile(LossType loss_type, for (size_t l = 0; l < operators.size(); l++) { Op *op = operators[l]; + for (int i = 0; i < op->numInputs; i++) { assert(op->inputs[i]->owner_op != NULL); } @@ -3047,13 +3552,16 @@ void FFModel::compile(LossType loss_type, assert(op->weights[i]->region != LogicalRegion::NO_REGION); parameters.push_back(op->weights[i]); } + op->map_output_tensors(*this); // for (int i = 0; i < op->numOutputs; i++) { // // Output tensor // map_tensor(op->outputs[i], op); // } - if (op->is_parallel_op()) { - ((ParallelOp *)op)->create_input_partition(*this); + if (config.computationMode == COMP_MODE_TRAINING) { + if (op->is_parallel_op()) { + ((ParallelOp *)op)->create_input_partition(*this); + } } // op->map_output_tensors(*this); } @@ -3152,53 +3660,7 @@ void FFModel::compile(LossType loss_type, } operators = new_operators; } - // Check integrity - for (size_t l = 0; l < operators.size(); l++) { - if (operators[l]->op_type == OP_FUSED) { - FusedOp *fused = (FusedOp *)operators[l]; - int ioff = 0, woff = 0, ooff = 0; - for (int op = 0; op < fused->numOperators; op++) { - Op *old_op = fused->operators[op]; - for (int i = 0; i < fused->op_num_inputs[op]; i++) { - int my_off = fused->op_input_idx[i + ioff]; - if (fused->op_input_source[i + ioff] == FusedOp::SOURCE_INPUT) { - assert(fused->inputs[my_off]->region == - old_op->inputs[i]->region); - } else if (fused->op_input_source[i + ioff] == - FusedOp::SOURCE_OUTPUT) { - assert(fused->outputs[my_off]->region == - old_op->inputs[i]->region); - } else { - assert(false); - } - } - for (int i = 0; i < fused->op_num_weights[op]; i++) { - int my_off = fused->op_weight_idx[i + woff]; - assert(fused->op_weight_source[i + woff] == FusedOp::SOURCE_WEIGHT); - assert(fused->weights[my_off]->region == - old_op->weights[i]->region); - } - for (int i = 0; i < fused->op_num_outputs[op]; i++) { - int my_off = fused->op_output_idx[i + ooff]; - assert(fused->op_output_source[i + ooff] == FusedOp::SOURCE_OUTPUT); - assert(fused->outputs[my_off]->region == - old_op->outputs[i]->region); - } - ioff += fused->op_num_inputs[op]; - woff += fused->op_num_weights[op]; - ooff += fused->op_num_outputs[op]; - } - } else { - bool found = false; - for (size_t i = 0; i < old_operators.size(); i++) { - if (old_operators[i] == operators[l]) { - assert(!found); - found = true; - } - } - assert(found); - } - } + assert(check_operators_integrity(old_operators)); fprintf(stderr, "%zu operators after fusion...\n", operators.size()); for (size_t i = 0; i < operators.size(); i++) { Op *op = operators[i]; @@ -3208,7 +3670,7 @@ void FFModel::compile(LossType loss_type, operators[i]->op_guid); for (int j = 0; j < op->numInputs; j++) { LogicalRegion handle = op->inputs[j]->region; - printf("inputs[%d] region(%d,%d,%d)\n", + printf("\tinputs[%d] region(%d,%d,%d)\n", j, handle.get_index_space().get_id(), handle.get_field_space().get_id(), @@ -3216,7 +3678,7 @@ void FFModel::compile(LossType loss_type, } for (int j = 0; j < op->numOutputs; j++) { LogicalRegion handle = op->outputs[j]->region; - printf("outputs[%d] region(%d,%d,%d)\n", + printf("\toutputs[%d] region(%d,%d,%d)\n", j, handle.get_index_space().get_id(), handle.get_field_space().get_id(), @@ -3224,7 +3686,7 @@ void FFModel::compile(LossType loss_type, } for (int j = 0; j < op->numWeights; j++) { LogicalRegion handle = op->weights[j]->region; - printf("weights[%d] region(%d,%d,%d)\n", + printf("\tweights[%d] region(%d,%d,%d)\n", j, handle.get_index_space().get_id(), handle.get_field_space().get_id(), @@ -3237,22 +3699,22 @@ void FFModel::compile(LossType loss_type, assert(final_operator->numOutputs == 1); for (size_t i = 0; i < operators.size(); i++) { Op *op = operators[i]; - printf("operator[%zu]: type(%d)\n", i, operators[i]->op_type); + log_model.print("operator[%zu]: type(%d)", i, operators[i]->op_type); for (int j = 0; j < op->numInputs; j++) { LogicalRegion handle = op->inputs[j]->region; - printf("inputs[%d] region(%d,%d,%d)\n", - j, - handle.get_index_space().get_id(), - handle.get_field_space().get_id(), - handle.get_tree_id()); + log_model.print("\tinputs[%d] region(%d,%d,%d)", + j, + handle.get_index_space().get_id(), + handle.get_field_space().get_id(), + handle.get_tree_id()); } for (int j = 0; j < op->numOutputs; j++) { LogicalRegion handle = op->outputs[j]->region; - printf("outputs[%d] region(%d,%d,%d)\n", - j, - handle.get_index_space().get_id(), - handle.get_field_space().get_id(), - handle.get_tree_id()); + log_model.print("\toutputs[%d] region(%d,%d,%d)", + j, + handle.get_index_space().get_id(), + handle.get_field_space().get_id(), + handle.get_tree_id()); } } // assert(final_operator->outputs[0].num_dims == 2); @@ -3295,18 +3757,17 @@ void FFModel::compile(LossType loss_type, assert(false && "Unsupported dim"); } } - // init optimizer - assert(optimizer != NULL); - optimizer->init(); + if (config.computationMode == COMP_MODE_TRAINING) { + // init optimizer + assert(optimizer != NULL); + optimizer->init(); + } #ifdef FF_USE_NCCL - if (config.computationMode == COMP_MODE_TRAINING) { - // init all nccl communicators - for (size_t l = 0; l < operators.size(); l++) { - // Only create nccl for weights - if (operators[l]->op_type != OP_WEIGHT) { - continue; - } + for (size_t l = 0; l < operators.size(); l++) { + // Only create nccl for weights in training + if ((operators[l]->op_type == OP_WEIGHT && + config.computationMode == COMP_MODE_TRAINING)) { MachineView view = operators[l]->outputs[0]->machine_view; if (view_hash_to_nccl_comms.find(view.hash()) == view_hash_to_nccl_comms.end()) { @@ -3341,6 +3802,59 @@ void FFModel::compile(LossType loss_type, #endif } +bool FFModel::check_operators_integrity( + std::vector const &old_operators, + std::unordered_map> + *pt_mapping) { + // Check integrity + for (size_t l = 0; l < operators.size(); l++) { + if (operators[l]->op_type == OP_FUSED) { + FusedOp *fused = (FusedOp *)operators[l]; + int ioff = 0, woff = 0, ooff = 0; + for (int op = 0; op < fused->numOperators; op++) { + Op *old_op = fused->operators[op]; + for (int i = 0; i < fused->op_num_inputs[op]; i++) { + int my_off = fused->op_input_idx[i + ioff]; + if (fused->op_input_source[i + ioff] == FusedOp::SOURCE_INPUT) { + assert(FusedOp::use_same_regions( + fused->inputs[my_off], old_op->inputs[i], pt_mapping)); + } else if (fused->op_input_source[i + ioff] == + FusedOp::SOURCE_OUTPUT) { + assert(FusedOp::use_same_regions( + fused->outputs[my_off], old_op->inputs[i], pt_mapping)); + } else { + assert(false); + } + } + for (int i = 0; i < fused->op_num_weights[op]; i++) { + int my_off = fused->op_weight_idx[i + woff]; + assert(fused->op_weight_source[i + woff] == FusedOp::SOURCE_WEIGHT); + assert(fused->weights[my_off]->region == old_op->weights[i]->region); + } + for (int i = 0; i < fused->op_num_outputs[op]; i++) { + int my_off = fused->op_output_idx[i + ooff]; + assert(fused->op_output_source[i + ooff] == FusedOp::SOURCE_OUTPUT); + assert(FusedOp::use_same_regions( + fused->outputs[my_off], old_op->outputs[i], pt_mapping)); + } + ioff += fused->op_num_inputs[op]; + woff += fused->op_num_weights[op]; + ooff += fused->op_num_outputs[op]; + } + } else { + bool found = false; + for (size_t i = 0; i < old_operators.size(); i++) { + if (old_operators[i] == operators[l]) { + assert(!found); + found = true; + } + } + assert(found); + } + } + return true; +} + struct PropagationEdgeInfo { Op *dstOp; size_t size; @@ -3645,18 +4159,25 @@ struct DefaultConfig { // const static int iterations = 1; static int const batchSize = 64; static bool const profiling = false; + static bool const benchmarking = false; + static bool const inference_debugging = false; constexpr static float learningRate = 0.01f; constexpr static float weightDecay = 0.0001f; - static size_t const workSpaceSize = (size_t)2 * 1024 * 1024 * 1024; // 2GB + static size_t const workSpaceSize = (size_t)128 * 1024 * 1024; // 128 MB + static int const numNodes = 1; static int const workersPerNode = 0; static int const cpusPerNode = 0; static size_t const searchBudget = -1; static size_t const simulatorWorkSpaceSize = - (size_t)2 * 1024 * 1024 * 1024; // 2GB + (size_t)2 * 1024 * 1024 * 1024; // 2 GB constexpr static float searchAlpha = 1.2f; static bool const searchOverlapBackwardUpdate = false; - static bool const onlyDataParallel = false; + static size_t const offloadReserveSpaceSize = + (size_t)8 * 1024 * 1024 * 1024; // 8 GB + static bool const cpuOffload = false; + static bool const onlyDataParallel = true; + static bool const enableSampleParallel = true; static bool const enableParameterParallel = false; static bool const enableAttributeParallel = false; @@ -3676,6 +4197,8 @@ FFConfig::FFConfig() { // iterations = DefaultConfig::iterations; batchSize = DefaultConfig::batchSize; profiling = DefaultConfig::profiling; + benchmarking = DefaultConfig::benchmarking; + inference_debugging = DefaultConfig::inference_debugging; learningRate = DefaultConfig::learningRate; weightDecay = DefaultConfig::weightDecay; workSpaceSize = DefaultConfig::workSpaceSize; @@ -3687,9 +4210,14 @@ FFConfig::FFConfig() { search_alpha = DefaultConfig::searchAlpha; search_overlap_backward_update = DefaultConfig::searchOverlapBackwardUpdate; computationMode = COMP_MODE_TRAINING; + cpu_offload = DefaultConfig::cpuOffload; + offload_reserve_space_size = DefaultConfig::offloadReserveSpaceSize; + quantization_type = DT_NONE; only_data_parallel = DefaultConfig::onlyDataParallel; data_parallelism_degree = 1; tensor_parallelism_degree = 1; + pipeline_parallelism_degree = 1; + enable_sample_parallel = DefaultConfig::enableSampleParallel; enable_parameter_parallel = DefaultConfig::enableParameterParallel; enable_attribute_parallel = DefaultConfig::enableAttributeParallel; @@ -3708,7 +4236,7 @@ FFConfig::FFConfig() { export_strategy_computation_graph_file = ""; dataset_path = ""; substitution_json_path = tl::nullopt; - syntheticInput = false; + benchmarking = false; perform_fusion = false; base_optimize_threshold = DefaultConfig::base_optimize_threshold; perform_memory_search = false; @@ -3738,6 +4266,7 @@ FFConfig::FFConfig() { Rect<1> task_rect(Point<1>(0), Point<1>(workersPerNode * numNodes - 1)); // Create an index space for tasks running on all GPUs all_gpu_task_is = runtime->create_index_space(lg_ctx, task_rect); + field_space = runtime->create_field_space(lg_ctx); } @@ -3794,6 +4323,22 @@ void FFConfig::parse_args(char **argv, int argc) { export_strategy_file = std::string(argv[++i]); continue; } + if ((!strcmp(argv[i], "-offload"))) { + cpu_offload = true; + continue; + } + if (!strcmp(argv[i], "-offload-reserve-space-size")) { + offload_reserve_space_size = atoll(argv[++i]) * 1024 * 1024; + continue; + } + if ((!strcmp(argv[i], "--4bit-quantization"))) { + quantization_type = DT_INT4; + continue; + } + if ((!strcmp(argv[i], "--8bit-quantization"))) { + quantization_type = DT_INT8; + continue; + } if ((!strcmp(argv[i], "--only-data-parallel"))) { only_data_parallel = true; continue; @@ -3808,6 +4353,12 @@ void FFConfig::parse_args(char **argv, int argc) { tensor_parallelism_degree = std::stoi(argv[++i]); continue; } + // pipeline parallelism degree + if (!strcmp(argv[i], "-pipeline-parallelism-degree")) { + pipeline_parallelism_degree = std::stoi(argv[++i]); + continue; + } + if ((!strcmp(argv[i], "--enable-parameter-parallel"))) { enable_parameter_parallel = true; continue; @@ -3839,6 +4390,14 @@ void FFConfig::parse_args(char **argv, int argc) { profiling = true; continue; } + if (!strcmp(argv[i], "--benchmarking")) { + benchmarking = true; + continue; + } + if (!strcmp(argv[i], "--inference-debugging")) { + inference_debugging = true; + continue; + } if (!strcmp(argv[i], "--allow-tensor-op-math-conversion")) { allow_tensor_op_math_conversion = true; continue; @@ -3940,6 +4499,159 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar); } } + // RequestManager load_tokens + { + TaskVariantRegistrar registrar(RM_LOAD_TOKENS_TASK_ID, + "RequestManager Load Tokens"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "RequestManager Load Tokens Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // RequestManager load position tokens + { + TaskVariantRegistrar registrar(RM_LOAD_POSITION_TASK_ID, + "RequestManager Load Position tokens"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "RequestManager Load Position Tokens Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // RequestManager load metadata + { + TaskVariantRegistrar registrar(RM_LOAD_BATCH_CONFIG_TASK_ID, + "RequestManager Load meta data"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "RequestManager Load metadata Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // RequestManager prepare_next_batch + { + TaskVariantRegistrar registrar(RM_PREPARE_NEXT_BATCH_TASK_ID, + "RequestManager Prepare Next Batch"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + BatchConfig, + RequestManager::prepare_next_batch_task>( + registrar, "RequestManager Prepare Next Batch Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // RequestManager prepare_next_batch_beam + { + TaskVariantRegistrar registrar(RM_PREPARE_NEXT_BATCH_BEAM_TASK_ID, + "RequestManager Prepare Next Batch (Beam)"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + BeamSearchBatchConfig, + RequestManager::prepare_next_batch_beam_task>( + registrar, "RequestManager Prepare Next Batch (Beam) Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime + ->register_task_variant( + registrar); + } + } + // RequestManager prepare_next_batch_init + { + TaskVariantRegistrar registrar( + RM_PREPARE_NEXT_BATCH_INIT_TASK_ID, + "RequestManager Prepare Next Batch (Init Beam)"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + BeamSearchBatchConfig, + RequestManager::prepare_next_batch_init_task>( + registrar, "RequestManager Prepare Next Batch (Init Beam) Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime + ->register_task_variant( + registrar); + } + } + // RequestManager prepare_next_batch_verify + { + TaskVariantRegistrar registrar( + RM_PREPARE_NEXT_BATCH_VERIFY_TASK_ID, + "RequestManager Prepare Next Batch (Verify)"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + TreeVerifyBatchConfig, + RequestManager::prepare_next_batch_verify_task>( + registrar, "RequestManager Prepare Next Batch (Verify) Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant< + TreeVerifyBatchConfig, + RequestManager::prepare_next_batch_verify_task>(registrar); + } + } + // RequestManager background serving task + { + TaskVariantRegistrar registrar(RM_BACKGROUND_SERVING_TASK_ID, + "RequestManager Background Serving Task"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + // registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + RequestManager::background_serving_task>( + registrar, "RequestManager Background Serving Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } // ElementUnary task { TaskVariantRegistrar registrar(ELEMENTUNARY_INIT_TASK_ID, @@ -3957,6 +4669,21 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar); } } + { + TaskVariantRegistrar registrar(ELEMENTUNARY_INF_TASK_ID, + "ElementWiseUnary Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ElementWiseUnary Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(ELEMENTUNARY_FWD_TASK_ID, "ElementWiseUnary Forward"); @@ -4004,6 +4731,21 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar); } } + { + TaskVariantRegistrar registrar(ELEMENTBINARY_INF_TASK_ID, + "ElementWiseBinary Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ElementWiseBinary Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(ELEMENTBINARY_FWD_TASK_ID, "ElementWiseBinary Forward"); @@ -4034,6 +4776,63 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + // Experts + { + TaskVariantRegistrar registrar(EXPERTS_INIT_TASK_ID, "Experts Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Experts Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(EXPERTS_FWD_TASK_ID, "Experts Forward"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Experts Forward Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(EXPERTS_BWD_TASK_ID, "Experts Backward"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Experts Backward Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(EXPERTS_INF_TASK_ID, "Experts Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Experts Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } // Cast { TaskVariantRegistrar registrar(CAST_INIT_TASK_ID, "Cast Init"); @@ -4199,6 +4998,20 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + { + TaskVariantRegistrar registrar(EMBED_INF_TASK_ID, "Embedding Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Embedding Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(EMBED_BWD_TASK_ID, "Embedding Backward"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); @@ -4600,6 +5413,21 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + { + TaskVariantRegistrar registrar(LAYERNORM_INF_TASK_ID, + "LayerNorm Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "LayerNorm Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(LAYERNORM_FWD_TASK_ID, "layernorm_fwd_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); @@ -4614,119 +5442,311 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + // ResidualLayerNorm task { - TaskVariantRegistrar registrar(LAYERNORM_BWD_TASK_ID, "layernorm_bwd_task"); + TaskVariantRegistrar registrar(RESIDUAL_LAYERNORM_INIT_TASK_ID, + "residual_layernorm_init_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "layernorm_bwd_task"); + Runtime::preregister_task_variant( + registrar, "residual_layernorm_init_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } - // Linear task { - TaskVariantRegistrar registrar(LINEAR_INIT_TASK_ID, "Linear Init"); + TaskVariantRegistrar registrar(RESIDUAL_LAYERNORM_INF_TASK_ID, + "residual_layernorm_fwd_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "Linear Init Task"); + Runtime::preregister_task_variant( + registrar, "residual_layernorm_inference_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } + // AddBiasResidualLayerNorm task { - TaskVariantRegistrar registrar(LINEAR_FWD_TASK_ID, "Linear Forward"); + TaskVariantRegistrar registrar(ADD_BIAS_RESIDUAL_LAYERNORM_INIT_TASK_ID, + "add_bias_residual_layernorm_init_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "Linear Forward Task"); + Runtime::preregister_task_variant( + registrar, "add_bias_residual_layernorm_init_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } { - TaskVariantRegistrar registrar(LINEAR_BWD_TASK_ID, "Linear Backward"); + TaskVariantRegistrar registrar(ADD_BIAS_RESIDUAL_LAYERNORM_INF_TASK_ID, + "add_bias_residual_layernorm_fwd_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "Linear Backward Task"); + Runtime::preregister_task_variant< + AddBiasResidualLayerNorm::inference_task>( + registrar, "add_bias_residual_layernorm_inference_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } - // Flat task + // SigmoidSiluMulti task { - TaskVariantRegistrar registrar(FLAT_INIT_TASK_ID, "flat_init_task"); + TaskVariantRegistrar registrar(SIGMOID_SILU_MULTI_INIT_TASK_ID, + "SigmoidSiluMulti Init"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "flat_init_task"); + Runtime::preregister_task_variant( + registrar, "SigmoidSiluMulti Init Task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } { - TaskVariantRegistrar registrar(FLAT_FWD_TASK_ID, "flat_fwd_task"); + TaskVariantRegistrar registrar(SIGMOID_SILU_MULTI_INF_TASK_ID, + "SigmoidSiluMulti Inference"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant(registrar, - "flat_fwd_task"); + Runtime::preregister_task_variant( + registrar, "SigmoidSiluMulti Inference Task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant( + registrar); } } + // rms norm task { - TaskVariantRegistrar registrar(FLAT_BWD_TASK_ID, "flat_bwd_task"); + TaskVariantRegistrar registrar(RMSNORM_INIT_TASK_ID, "rmsnorm_init_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant(registrar, - "flat_bwd_task"); + Runtime::preregister_task_variant( + registrar, "rmsnorm_init_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant(registrar); } } - // Softmax task { - TaskVariantRegistrar registrar(SOFTMAX_INIT_TASK_ID, "softmax_init_task"); + TaskVariantRegistrar registrar(RMSNORM_FWD_TASK_ID, "rmsnorm_fwd_task"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "softmax_init_task"); + Runtime::preregister_task_variant( + registrar, "rmsnorm_fwd_task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(RMSNORM_INF_TASK_ID, "RMS Norm Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "RMS Norm Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + // rms norm task + { + TaskVariantRegistrar registrar(RESIDUAL_RMSNORM_INIT_TASK_ID, + "Residual RMS Norm Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Residual RMS Norm Init"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar(RESIDUAL_RMSNORM_INF_TASK_ID, + "Residual RMS Norm Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "RMS Norm Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar(LAYERNORM_BWD_TASK_ID, "layernorm_bwd_task"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "layernorm_bwd_task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + // Linear task + { + TaskVariantRegistrar registrar(LINEAR_INIT_TASK_ID, "Linear Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Linear Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(LINEAR_INF_TASK_ID, "Linear Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Linear Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(LINEAR_FWD_TASK_ID, "Linear Forward"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Linear Forward Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(LINEAR_BWD_TASK_ID, "Linear Backward"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Linear Backward Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + // Flat task + { + TaskVariantRegistrar registrar(FLAT_INIT_TASK_ID, "flat_init_task"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "flat_init_task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(FLAT_FWD_TASK_ID, "flat_fwd_task"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant(registrar, + "flat_fwd_task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(FLAT_BWD_TASK_ID, "flat_bwd_task"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant(registrar, + "flat_bwd_task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + // Softmax task + { + TaskVariantRegistrar registrar(SOFTMAX_INIT_TASK_ID, "softmax_init_task"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "softmax_init_task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); } } { @@ -4757,6 +5777,20 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + { + TaskVariantRegistrar registrar(SOFTMAX_INF_TASK_ID, "Softmax Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Softmax Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } // compute Loss { TaskVariantRegistrar registrar(LOSS_BWD_TASK_ID, "Loss Backward"); @@ -5071,6 +6105,167 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + // ArgTopk task + { + TaskVariantRegistrar registrar(ARG_TOPK_INIT_TASK_ID, "ArgTopK Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgTopK Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(ARG_TOPK_INF_TASK_ID, "ArgTopK Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgTopK Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar(ARG_TOPK_INF_SPECULATIVE_TASK_ID, + "ArgTopK Speculative Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgTopK Speculative Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // BeamTopk task + { + TaskVariantRegistrar registrar(BEAM_TOPK_INIT_TASK_ID, "BeamTopK Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "BeamTopK Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(BEAM_TOPK_INF_TASK_ID, "BeamTopK Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "BeamTopK Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + // Sampling task + { + TaskVariantRegistrar registrar(SAMPLING_INIT_TASK_ID, "Sampling Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Sampling Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(SAMPLING_INF_TASK_ID, "Sampling Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Sampling Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // ArgMax task + { + TaskVariantRegistrar registrar(ARGMAX_INIT_TASK_ID, "ArgMax Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgMax Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(ARGMAX_BEAM_INF_TASK_ID, + "ArgMax Beam Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgMax Inference Task Beam"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } + { + TaskVariantRegistrar registrar(ARGMAX_NORM_INF_TASK_ID, + "ArgMax Norm Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "ArgMax Inference Task Norm"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime + ->register_task_variant( + registrar); + } + } // Transpose task { TaskVariantRegistrar registrar(TRANSPOSE_INIT_TASK_ID, "Transpose Init"); @@ -5164,6 +6359,119 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar); } } + // MultiHeadAttention task + { + TaskVariantRegistrar registrar(INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + "IncMultiHeadSelfAttention Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "IncMultiHeadSelfAttention Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar(INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + "IncMultiHeadSelfAttention Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + IncMultiHeadSelfAttention::inference_task>( + registrar, "IncMultiHeadSelfAttention Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + // speculative MultiHeadAttention task + { + TaskVariantRegistrar registrar( + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + "Speculative IncMultiHeadSelfAttention Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + OpMeta *, + SpecIncMultiHeadSelfAttention::init_task>( + registrar, "Speculative IncMultiHeadSelfAttention Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar( + SPEC_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + "Speculative IncMultiHeadSelfAttention Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + SpecIncMultiHeadSelfAttention::inference_task>( + registrar, "Speculative IncMultiHeadSelfAttention Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant< + SpecIncMultiHeadSelfAttention::inference_task>(registrar); + } + } + { + TaskVariantRegistrar registrar( + TREE_INC_MULTIHEAD_SELF_ATTENTION_INIT_TASK_ID, + "TreeIncMultiHeadSelfAttention Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + OpMeta *, + TreeIncMultiHeadSelfAttention::init_task>( + registrar, "TreeIncMultiHeadSelfAttention Init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant( + registrar); + } + } + { + TaskVariantRegistrar registrar( + TREE_INC_MULTIHEAD_SELF_ATTENTION_INF_TASK_ID, + "TreeIncMultiHeadSelfAttention Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant< + TreeIncMultiHeadSelfAttention::inference_task>( + registrar, "TreeIncMultiHeadSelfAttention Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant< + TreeIncMultiHeadSelfAttention::inference_task>(registrar); + } + } // NoOp { TaskVariantRegistrar registrar(NOOP_INIT_TASK_ID, "Weight NCCL Init"); @@ -5208,6 +6516,20 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + { + TaskVariantRegistrar registrar(FUSEDOP_INF_TASK_ID, "FusedOp Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "FusedOp Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(FUSEDOP_BWD_TASK_ID, "FusedOp Backward"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); @@ -5319,13 +6641,13 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { - Runtime::preregister_task_variant( - registrar, "Replicate Init Task"); + Runtime::preregister_task_variant( + registrar, "Replicate init Task"); } else { if (enable_control_replication) { registrar.global_registration = false; } - runtime->register_task_variant(registrar); + runtime->register_task_variant(registrar); } } { @@ -5357,6 +6679,20 @@ void register_flexflow_internal_tasks(Runtime *runtime, } } // Reduction + { + TaskVariantRegistrar registrar(REDUCTION_INIT_TASK_ID, "Reduction Init"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Reduction init Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(REDUCTION_FWD_TASK_ID, "Reduction Forward"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); @@ -5400,6 +6736,21 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + { + TaskVariantRegistrar registrar(ALLREDUCE_INF_TASK_ID, + "AllReduce Inference"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "AllReduce Inference Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } { TaskVariantRegistrar registrar(ALLREDUCE_FWD_TASK_ID, "AllReduce Forward"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); @@ -5673,15 +7024,30 @@ void register_flexflow_internal_tasks(Runtime *runtime, registrar); } } + { + TaskVariantRegistrar registrar(NCCL_FINISH_COMMS_TASK_ID, + "NCCL Finish Communicators"); + registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "NCCL Finish Communicators Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime->register_task_variant(registrar); + } + } #endif // Search { - TaskVariantRegistrar registrar(STRATEGY_SEARCH_TASK_ID, "Stretegy Search"); + TaskVariantRegistrar registrar(STRATEGY_SEARCH_TASK_ID, "Strategy Search"); registrar.add_constraint(ProcessorConstraint(Processor::TOC_PROC)); registrar.set_leaf(); if (pre_register) { Runtime::preregister_task_variant( - registrar, "Stretegy Search Task"); + registrar, "Strategy Search Task"); } else { if (enable_control_replication) { registrar.global_registration = false; @@ -5723,6 +7089,24 @@ void register_flexflow_internal_tasks(Runtime *runtime, runtime->register_task_variant(registrar); } } + // Tensor Equal task + { + TaskVariantRegistrar registrar(TENSOR_EQUAL_TASK_ID, "Tensor Equal"); + registrar.add_constraint(ProcessorConstraint(Processor::LOC_PROC)); + registrar.set_leaf(); + if (pre_register) { + Runtime::preregister_task_variant( + registrar, "Tensor Equal Task"); + } else { + if (enable_control_replication) { + registrar.global_registration = false; + } + runtime + ->register_task_variant( + registrar); + } + } } // template instantiations diff --git a/src/runtime/model.cpp b/src/runtime/model.cpp index d6ae0ec948..ad2b781567 100644 --- a/src/runtime/model.cpp +++ b/src/runtime/model.cpp @@ -54,7 +54,8 @@ void Op::inner_measure_operator_cost(Simulator *sim, checkCUDA(hipEventRecord(sim->end_event, stream)); checkCUDA(hipEventSynchronize(sim->end_event)); float milliseconds; - hipEventElapsedTime(&milliseconds, sim->start_event, sim->end_event); + checkCUDA( + hipEventElapsedTime(&milliseconds, sim->start_event, sim->end_event)); cost_metrics.forward_time = milliseconds / sim->repeat_times; // measure backward time @@ -68,7 +69,8 @@ void Op::inner_measure_operator_cost(Simulator *sim, } checkCUDA(hipEventRecord(sim->end_event, stream)); checkCUDA(hipEventSynchronize(sim->end_event)); - hipEventElapsedTime(&milliseconds, sim->start_event, sim->end_event); + checkCUDA( + hipEventElapsedTime(&milliseconds, sim->start_event, sim->end_event)); cost_metrics.backward_time = milliseconds / sim->repeat_times; } else { cost_metrics.backward_time = 0.0f; @@ -129,6 +131,54 @@ FFHandler .wait(); handle.workSpace = workspaceInst.pointer_untyped(0, sizeof(char)); } + if (handle.offload_reserve_space_size > 0) { + // allocate memory for offload reserve space + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + Realm::Rect<1, coord_t> bounds( + Realm::Point<1, coord_t>(0), + Realm::Point<1, coord_t>(handle.offload_reserve_space_size - 1)); + std::vector field_sizes; + field_sizes.push_back(sizeof(char)); + Realm::RegionInstance workspaceInst; + Realm::RegionInstance::create_instance(workspaceInst, + gpu_mem, + bounds, + field_sizes, + 0, + Realm::ProfilingRequestSet()) + .wait(); + handle.offload_reserve_space = + workspaceInst.pointer_untyped(0, sizeof(char)); + } else { + handle.offload_reserve_space = nullptr; + } + if (handle.batch_config_metadata_size > 0) { + // allocate memory for offload reserve space + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + Realm::Rect<1, coord_t> bounds( + Realm::Point<1, coord_t>(0), + Realm::Point<1, coord_t>(handle.batch_config_metadata_size - 1)); + std::vector field_sizes; + field_sizes.push_back(sizeof(char)); + Realm::RegionInstance workspaceInst; + Realm::RegionInstance::create_instance(workspaceInst, + gpu_mem, + bounds, + field_sizes, + 0, + Realm::ProfilingRequestSet()) + .wait(); + handle.batch_config_metadata = + workspaceInst.pointer_untyped(0, sizeof(char)); + } else { + handle.batch_config_metadata = nullptr; + } // checkCUDA(hipMalloc(&handle.workSpace, handle.workSpaceSize)); #ifdef FF_USE_NCCL handle.ncclComm = NULL; diff --git a/src/runtime/model.cu b/src/runtime/model.cu index e07a7465a9..23b7f0efbe 100644 --- a/src/runtime/model.cu +++ b/src/runtime/model.cu @@ -86,6 +86,8 @@ FFHandler printf("workSpaceSize (%zu MB)\n", info->workSpaceSize / 1024 / 1024); FFHandler handle; handle.workSpaceSize = info->workSpaceSize; + handle.offload_reserve_space_size = info->offload_reserve_space_size; + handle.quantization_type = info->quantization_type; handle.allowTensorOpMathConversion = info->allowTensorOpMathConversion; checkCUDA(cublasCreate(&handle.blas)); if (handle.allowTensorOpMathConversion) { @@ -125,6 +127,55 @@ FFHandler .wait(); handle.workSpace = workspaceInst.pointer_untyped(0, sizeof(char)); } + if (handle.offload_reserve_space_size > 0) { + // allocate memory for offload reserve space + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + Realm::Rect<1, coord_t> bounds( + Realm::Point<1, coord_t>(0), + Realm::Point<1, coord_t>(handle.offload_reserve_space_size - 1)); + std::vector field_sizes; + field_sizes.push_back(sizeof(char)); + Realm::RegionInstance workspaceInst; + Realm::RegionInstance::create_instance(workspaceInst, + gpu_mem, + bounds, + field_sizes, + 0, + Realm::ProfilingRequestSet()) + .wait(); + handle.offload_reserve_space = + workspaceInst.pointer_untyped(0, sizeof(char)); + } else { + handle.offload_reserve_space = nullptr; + } + if (handle.batch_config_metadata_size > 0) { + // allocate memory for offload reserve space + Memory gpu_mem = Machine::MemoryQuery(Machine::get_machine()) + .only_kind(Memory::GPU_FB_MEM) + .best_affinity_to(task->target_proc) + .first(); + Realm::Rect<1, coord_t> bounds( + Realm::Point<1, coord_t>(0), + Realm::Point<1, coord_t>(handle.batch_config_metadata_size - 1)); + std::vector field_sizes; + field_sizes.push_back(sizeof(char)); + Realm::RegionInstance workspaceInst; + Realm::RegionInstance::create_instance(workspaceInst, + gpu_mem, + bounds, + field_sizes, + 0, + Realm::ProfilingRequestSet()) + .wait(); + handle.batch_config_metadata = + workspaceInst.pointer_untyped(0, sizeof(char)); + } else { + handle.batch_config_metadata = nullptr; + } + // checkCUDA(cudaMalloc(&handle.workSpace, handle.workSpaceSize)); #ifdef FF_USE_NCCL handle.ncclComm = NULL; diff --git a/src/runtime/operator.cc b/src/runtime/operator.cc index 08b1af8ca5..36ac02a3a3 100644 --- a/src/runtime/operator.cc +++ b/src/runtime/operator.cc @@ -3,6 +3,14 @@ #include "flexflow/simulator.h" #include +#include +#include +#if defined(FF_USE_CUDA) || defined(FF_USE_HIP_CUDA) +#include "flexflow/utils/cuda_helper.h" +#else +#include "flexflow/utils/hip_helper.h" +#endif + namespace FlexFlow { size_t Op::get_untyped_params_hash() const { diff --git a/src/runtime/operator_params.cc b/src/runtime/operator_params.cc index 322d7840fb..91673682d4 100644 --- a/src/runtime/operator_params.cc +++ b/src/runtime/operator_params.cc @@ -1,9 +1,13 @@ #include "flexflow/operator_params.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/aggregate.h" #include "flexflow/ops/aggregate_spec.h" +#include "flexflow/ops/arg_topk.h" +#include "flexflow/ops/argmax.h" #include "flexflow/ops/attention.h" #include "flexflow/ops/batch_matmul.h" #include "flexflow/ops/batch_norm.h" +#include "flexflow/ops/beam_topk.h" #include "flexflow/ops/cache.h" #include "flexflow/ops/cast.h" #include "flexflow/ops/concat.h" @@ -15,6 +19,7 @@ #include "flexflow/ops/flat.h" #include "flexflow/ops/gather.h" #include "flexflow/ops/groupby.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/layer_norm.h" #include "flexflow/ops/linear.h" #include "flexflow/ops/mean.h" @@ -22,11 +27,19 @@ #include "flexflow/ops/pool_2d.h" #include "flexflow/ops/reduce.h" #include "flexflow/ops/reshape.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/residual_rms_norm.h" #include "flexflow/ops/reverse.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/ops/sampling.h" +#include "flexflow/ops/sigmoid_silu_multi.h" #include "flexflow/ops/softmax.h" +#include "flexflow/ops/spec_inc_multihead_self_attention.h" #include "flexflow/ops/split.h" #include "flexflow/ops/topk.h" #include "flexflow/ops/transpose.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/combine.h" #include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/fused_parallel_op.h" @@ -79,8 +92,18 @@ tl::optional get_op_parameters(Op const *op) { return ((Gather *)op)->get_params(); case OP_MULTIHEAD_ATTENTION: return ((MultiHeadAttention *)op)->get_params(); + case OP_INC_MULTIHEAD_SELF_ATTENTION: + return ((IncMultiHeadSelfAttention *)op)->get_params(); + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: + return ((TreeIncMultiHeadSelfAttention *)op)->get_params(); case OP_LAYERNORM: return ((LayerNorm *)op)->get_params(); + case OP_RESIDUAL_LAYERNORM: + return ((ResidualLayerNorm *)op)->get_params(); + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: + return ((AddBiasResidualLayerNorm *)op)->get_params(); + case OP_SIGMOID_SILU_MULTI: + return ((SigmoidSiluMulti *)op)->get_params(); case OP_REDUCE_SUM: return ((Reduce *)op)->get_params(); case OP_RESHAPE: @@ -113,6 +136,18 @@ tl::optional get_op_parameters(Op const *op) { return ((Aggregate *)op)->get_params(); case OP_AGG_SPEC: return ((AggregateSpec *)op)->get_params(); + case OP_RMS_NORM: + return ((RMSNorm *)op)->get_params(); + case OP_RESIDUAL_RMS_NORM: + return ((ResidualRMSNorm *)op)->get_params(); + case OP_ARG_TOPK: + return ((ArgTopK *)op)->get_params(); + case OP_BEAM_TOPK: + return ((BeamTopK *)op)->get_params(); + case OP_SAMPLING: + return ((Sampling *)op)->get_params(); + case OP_ARGMAX: + return ((ArgMax *)op)->get_params(); // TODO: implement the get_params() function for the operators below and // uncomment the lines below diff --git a/src/runtime/parallel_tensor.cc b/src/runtime/parallel_tensor.cc index b9f3dc89f7..2d6b1f8fe4 100644 --- a/src/runtime/parallel_tensor.cc +++ b/src/runtime/parallel_tensor.cc @@ -1,3 +1,4 @@ +#include "flexflow/ffconst_utils.h" #include "flexflow/model.h" #include "flexflow/ops/attention.h" #include "flexflow/ops/concat.h" @@ -274,7 +275,7 @@ void ParallelTensorBase::attach_raw_ptr(FFConfig &config, Runtime *runtime = config.lg_hlr; AttachLauncher launcher(EXTERNAL_INSTANCE, region, region); std::vector fields(1, FID_DATA); - const Memory local_sysmem = + Memory const local_sysmem = Machine::MemoryQuery(Machine::get_machine()) .has_affinity_to(runtime->get_executing_processor(ctx)) .only_kind(Memory::SYSTEM_MEM) @@ -682,21 +683,7 @@ bool ParallelTensorBase::set_tensor(FFModel const *ff, for (size_t i = 0; i < dim_sizes.size(); i++) { volume = volume * dim_sizes[i]; } - // Debug prints - { - std::string tensor_name; - if (owner_op == nullptr) { - tensor_name = "No OwnerOp"; - } else { - tensor_name = std::string(owner_op->name); - } - std::ostringstream oss; - for (int i = 0; i < dim_sizes.size(); i++) - oss << dim_sizes[i] << ", "; - printf("%s num_replicas(%zu) volume(%zu) dims(%s)\n", tensor_name.c_str(), - num_replicas, volume, oss.str().c_str()); - } - RegionRequirement req(region, READ_WRITE, EXCLUSIVE, region); + RegionRequirement req(region, WRITE_ONLY, EXCLUSIVE, region); req.add_field(FID_DATA); InlineLauncher launcher(req); PhysicalRegion pr = runtime->map_region(ctx, launcher); @@ -704,7 +691,7 @@ bool ParallelTensorBase::set_tensor(FFModel const *ff, switch (num_dims) { #define DIMFUNC(DIM) \ case DIM: { \ - TensorAccessorW acc(pr, req, FID_DATA, ctx, runtime, true); \ + TensorAccessorW acc(pr, req, FID_DATA, ctx, runtime, false); \ assert(acc.rect.volume() == volume * num_replicas); \ T *ptr = acc.ptr; \ for (size_t i = 0; i < num_replicas; i++) { \ @@ -776,6 +763,65 @@ bool ParallelTensorBase::get_tensor(FFModel const *ff, return true; } +template +bool ParallelTensorBase::tensor_equal(FFConfig &config, + ParallelTensorBase &tensor) { + Context ctx = config.lg_ctx; + Runtime *runtime = config.lg_hlr; + TaskLauncher launcher(TENSOR_EQUAL_TASK_ID, + TaskArgument(&num_dims, sizeof(num_dims))); + launcher.add_region_requirement( + RegionRequirement(region, READ_ONLY, EXCLUSIVE, region)); + launcher.add_field(0, FID_DATA); + launcher.add_region_requirement( + RegionRequirement(tensor.region, READ_ONLY, EXCLUSIVE, tensor.region)); + launcher.add_field(1, FID_DATA); + Future result = runtime->execute_task(ctx, launcher); + bool equals = result.get_result(); + return equals; +} + +bool ParallelTensorBase::tensor_equal_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 2); + int dim = *(int const *)task->args; + switch (dim) { +#define DIMFUNC(DIM) \ + case DIM: \ + return tensor_equal_task_with_dim(task, regions, ctx, runtime); + LEGION_FOREACH_N(DIMFUNC) +#undef DIMFUNC + default: + assert(false); + } + assert(false); +} + +template +bool ParallelTensorBase::tensor_equal_task_with_dim( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + TensorAccessorR acc1( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + TensorAccessorR acc2( + regions[1], task->regions[1], FID_DATA, ctx, runtime); + float const *data1 = acc1.ptr; + float const *data2 = acc2.ptr; + bool equal = true; + for (int i = 0; i < acc1.rect.volume(); i++) { + if (data1[i] != data2[i]) { + equal = false; + break; + } + } + return equal; +} + template float *ParallelTensorBase::get_raw_ptr(FFConfig &config); template int32_t *ParallelTensorBase::get_raw_ptr(FFConfig &config); @@ -804,6 +850,20 @@ template bool TensorBase::get_tensor(FFModel const *ff, int64_t *data, bool get_gradients); +template bool ParallelTensorBase::set_tensor(FFModel const *ff, + std::vector const &dims, + half const *data); +template bool ParallelTensorBase::get_tensor(FFModel const *ff, + half *data, + bool get_gradients); + +template bool ParallelTensorBase::set_tensor(FFModel const *ff, + std::vector const &dims, + char const *data); +template bool ParallelTensorBase::get_tensor(FFModel const *ff, + char *data, + bool get_gradients); + template bool ParallelTensorBase::set_tensor( FFModel const *ff, std::vector const &dims, float const *data); template bool ParallelTensorBase::get_tensor(FFModel const *ff, @@ -825,6 +885,10 @@ template bool ParallelTensorBase::get_tensor(FFModel const *ff, int64_t *data, bool get_gradients); +template bool + ParallelTensorBase::tensor_equal(FFConfig &config, + ParallelTensorBase &tensor); + template bool TensorBase::get_output_parallel_tensor(FFModel const *ff, float *data, bool get_gradients); diff --git a/src/runtime/request_manager.cc b/src/runtime/request_manager.cc new file mode 100644 index 0000000000..16513e918a --- /dev/null +++ b/src/runtime/request_manager.cc @@ -0,0 +1,2559 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/request_manager.h" +#include "flexflow/parallel_ops/parallel_op.h" +// #include "flexflow/tokenizers.h" +#include +#include +#include +#include +#include +#include +#include + +namespace FlexFlow { + +using namespace Legion; +using tokenizers::Tokenizer; + +LegionRuntime::Logger::Category log_req_mgr("RequestManager"); + +std::string LoadBytesFromFile(std::string const &path) { + std::ifstream fs(path, std::ios::in | std::ios::binary); + assert(!fs.fail() && "no such file"); + std::string data; + fs.seekg(0, std::ios::end); + size_t size = static_cast(fs.tellg()); + fs.seekg(0, std::ios::beg); + data.resize(size); + fs.read(data.data(), size); + return data; +} + +RequestManager::RequestManager() + : request_manager_status(INITIALIZED), verbose(false), + next_available_guid(1000000), num_processed_requests(0), + total_request_run_time(0.0f) { + // The following config parameters are set + // during ffmodel.compile() + // Initialize them to -1 to make sure no one + // gets an incorrect value of them before + // ffmodel.compile() + max_requests_per_batch = -1; + max_tokens_per_batch = -1; + max_spec_tree_token_num = -1; + max_sequence_length = -1; +} + +void RequestManager::set_max_requests_per_batch(int max_num_requests) { + assert(max_requests_per_batch == -1 || + max_requests_per_batch == max_num_requests); + max_requests_per_batch = max_num_requests; + assert(max_requests_per_batch <= BatchConfig::MAX_NUM_REQUESTS); +} + +int RequestManager::get_max_requests_per_batch() { + assert(max_requests_per_batch > 0); + return max_requests_per_batch; +} + +void RequestManager::set_max_tokens_per_batch(int max_num_tokens) { + assert(max_tokens_per_batch == -1 || max_tokens_per_batch == max_num_tokens); + max_tokens_per_batch = max_num_tokens; + assert(max_tokens_per_batch <= BatchConfig::MAX_NUM_TOKENS); +} + +void RequestManager::set_max_spec_tree_token_num(int max_num_tokens) { + assert(max_spec_tree_token_num == -1 || + max_spec_tree_token_num == max_num_tokens); + max_spec_tree_token_num = max_num_tokens; + assert(max_spec_tree_token_num <= BatchConfig::MAX_SPEC_TREE_TOKEN_NUM); +} + +int RequestManager::get_max_tokens_per_batch() { + assert(max_tokens_per_batch > 0); + return max_tokens_per_batch; +} + +int RequestManager::get_max_spec_tree_token_num() { + assert(max_spec_tree_token_num > 0); + return max_spec_tree_token_num; +} + +int RequestManager::get_max_verify_tokens_per_batch() { + assert(max_tokens_per_batch > 0); + return max_tokens_per_batch + + max_spec_tree_token_num * max_requests_per_batch; +} + +void RequestManager::set_max_sequence_length(int max_seq_length) { + assert(max_sequence_length == -1 || max_sequence_length == max_seq_length); + max_sequence_length = max_seq_length; +} + +int RequestManager::get_max_sequence_length() { + assert(max_sequence_length > 0); + return max_sequence_length; +} + +void RequestManager::push_spec_infer_tree_width(int tree_width) { + assert(tree_width <= BeamSearchBatchConfig::MAX_BEAM_WIDTH); + spec_infer_tree_width.emplace_back(tree_width); +} + +void RequestManager::register_tokenizer(ModelType type, + int bos_token_id, + int eos_token_id, + std::string const &path) { + this->model_type = type; + this->bos_token_id = bos_token_id; + this->eos_token_id = eos_token_id; + std::string tokenizer_folder = + (!path.empty() && path.back() != '/') ? path + '/' : path; + if (model_type == ModelType::LLAMA) { + bool path_to_file = !path.empty() && + (path.size() >= strlen("tokenizer.model")) && + path.find("tokenizer.model") == + (path.size() - strlen("tokenizer.model")); + std::string tokenizer_filepath = + path_to_file ? path : tokenizer_folder + "tokenizer.model"; + this->tokenizer_ = + Tokenizer::FromBlobSentencePiece(LoadBytesFromFile(tokenizer_filepath)); + } else if (model_type == ModelType::OPT) { + std::string vocab_file = tokenizer_folder + "vocab.json"; + std::string merges_file = tokenizer_folder + "merges.txt"; + std::string added_tokens_file = + tokenizer_folder + "special_tokens_map.json"; + std::filesystem::path path1(vocab_file); + std::filesystem::path path2(merges_file); + std::filesystem::path path3(added_tokens_file); + assert(std::filesystem::exists(path1) && + "Vocab file vocab.json does not exist at the specified path"); + assert(std::filesystem::exists(path2) && + "Merge file merges.txt does not exist at the specified path"); + // opt_tokenizer = new OptTokenizer(vocab_file, merges_file); + std::string vocab = LoadBytesFromFile(path1.string()); + std::string merges = LoadBytesFromFile(path2.string()); + std::string added_tokens = LoadBytesFromFile(path3.string()); + + this->tokenizer_ = + Tokenizer::FromBlobByteLevelBPE(vocab, merges, added_tokens); + } else if (model_type == ModelType::FALCON || + model_type == ModelType::STARCODER || + model_type == ModelType::MPT) { + std::string falcon_tokenizer_path = join_path({path, "tokenizer.json"}); + this->tokenizer_ = + Tokenizer::FromBlobJSON(LoadBytesFromFile(falcon_tokenizer_path)); + } +} + +void RequestManager::register_output_filepath( + std::string const &_output_filepath) { + this->output_filepath = _output_filepath; +} + +int RequestManager::register_ssm_model(FFModel *model) { + int model_id = ssm_models.size(); + ssm_models.push_back(model); + std::cout << "Register new ssm model with id: " << model_id << std::endl; + return model_id; +} + +FFModel *RequestManager::get_ssm_model(int model_id) { + assert(model_id < ssm_models.size()); + return ssm_models[model_id]; +} + +size_t RequestManager::get_num_ssms() { + return ssm_models.size(); +} + +RequestManager::RequestGuid + RequestManager::register_new_request(std::vector const &prompt, + int max_sequence_length) { + const std::lock_guard lock(request_queue_mutex); + + // Add a new request + Request request; + request.status = Request::PENDING; + request.guid = next_available_guid++; + request.max_sequence_length = max_sequence_length; + + if (prompt.size() >= get_max_sequence_length()) { + std::cout << "Warning: too many tokens in prompt, only load up to " + << get_max_sequence_length() << " tokens, but got " + << prompt.size() << ".\n"; + + printf("tokens size: %zu\n", request.tokens.size()); + return INVALID_GUID; + } else { + request.initial_len = prompt.size(); + request.tokens = prompt; + } + + if (get_num_ssms() == 0) { + std::cout << "No small speculative model registered, using incremental " + "decoding." + << std::endl; + } else { + std::cout << "Num of SSMs: " << get_num_ssms() << std::endl; + for (int i = 0; i < get_num_ssms(); i++) { + BeamTree beam_tree = BeamTree{}; + request.beam_trees.push_back(beam_tree); + } + } + + pending_request_queue.push(request); + all_requests[request.guid] = request; + { + const std::lock_guard lock(request_to_promise_mutex); + request_to_promise[request.guid] = new std::promise(); + } + + if (verbose) { + std::cout << "new req: " << request.tokens.size() << std::endl; + for (int i = 0; i < request.tokens.size(); i++) { + std::cout << i << " : " << request.tokens[i] << std::endl; + } + } + + GenerationResult gr; + gr.guid = request.guid; + gr.input_text = ""; + gr.input_tokens = prompt; + gr.output_text = ""; + gr.output_tokens = prompt; + request_generation_results[request.guid] = gr; + + return request.guid; +} + +RequestManager::RequestGuid + RequestManager::register_new_request(std::string const &prompt, + int max_sequence_length) { + const std::lock_guard lock(request_queue_mutex); + // Add a new request + Request request; + request.status = Request::PENDING; + request.guid = next_available_guid++; + request.max_sequence_length = max_sequence_length; + if (bos_token_id >= 0 && model_type != ModelType::FALCON) { + request.tokens.push_back(bos_token_id); + } + std::vector tokens = this->tokenizer_->Encode(prompt); + if (tokens.size() >= get_max_sequence_length()) { + std::cout << "Warning: too many tokens in prompt, only load up to " + << get_max_sequence_length() << " tokens, but got " + << tokens.size() << ".\n"; + + printf("tokens size: %zu\n", tokens.size()); + return INVALID_GUID; + } + for (int i = 0; i < tokens.size(); i++) { + std::cout << "[" << i << "]" << tokens.at(i) << "\n"; + } + request.tokens.insert(request.tokens.end(), tokens.begin(), tokens.end()); + request.initial_len = request.tokens.size(); + + if (get_num_ssms() == 0) { + std::cout << "No small speculative model registered, using incremental " + "decoding." + << std::endl; + } else { + std::cout << "Num of SSMs: " << get_num_ssms() << std::endl; + for (int i = 0; i < get_num_ssms(); i++) { + BeamTree beam_tree = BeamTree{}; + request.beam_trees.push_back(beam_tree); + } + } + + pending_request_queue.push(request); + all_requests[request.guid] = request; + { + const std::lock_guard lock(request_to_promise_mutex); + request_to_promise[request.guid] = new std::promise(); + } + + { + std::string output = "New request tokens:"; + output = "[" + std::to_string(request.guid) + "]" + output; + for (int i = 0; i < request.tokens.size(); i++) { + output = output + " " + std::to_string(request.tokens[i]); + } + log_req_mgr.print("%s", output.c_str()); + } + + GenerationResult gr; + gr.guid = request.guid; + gr.input_text = prompt; + gr.input_tokens = request.tokens; + gr.output_text = prompt; + gr.output_tokens = request.tokens; + request_generation_results[request.guid] = gr; + return request.guid; +} + +bool RequestManager::is_request_completed(RequestGuid const &guid) { + const std::lock_guard lock(request_queue_mutex); + assert(all_requests.find(guid) != all_requests.end()); + Request const &request = all_requests[guid]; + // return request.tokens.size() >= request.max_sequence_length; + return request.status == Request::COMPLETED; +} + +GenerationResult + RequestManager::get_generation_result(RequestGuid const &guid) { + // First get the future of the request + std::future future; + { + const std::lock_guard lock(request_to_promise_mutex); + assert(request_to_promise.find(guid) != request_to_promise.end()); + future = request_to_promise[guid]->get_future(); + } + // Wait until the result is completed + future.get(); + // Get the generation result + { + const std::lock_guard lock(request_queue_mutex); + assert(request_generation_results.find(guid) != + request_generation_results.end()); + return request_generation_results[guid]; + } +} + +size_t RequestManager::get_num_processed_requests() { + return num_processed_requests; +} + +BatchConfigFuture + RequestManager::prepare_next_batch(BatchConfigFuture const &old_bc, + InferenceResultFuture const &result, + Context ctx, + Runtime *runtime) { + RequestManager *rm = this; + TaskLauncher launcher(RM_PREPARE_NEXT_BATCH_TASK_ID, + TaskArgument(&rm, sizeof(RequestManager *))); + launcher.add_future(old_bc); + launcher.add_future(result); + return runtime->execute_task(ctx, launcher); +} + +BatchConfig RequestManager::prepare_next_batch_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RequestManager *rm = *((RequestManager **)task->args); + BatchConfig const *bc = BatchConfig::from_future(task->futures[0]); + InferenceResult const &result = + Future(task->futures[1]).get_result(); + return rm->prepare_next_batch(*bc, result); +} + +BatchConfig RequestManager::prepare_next_batch(BatchConfig const &old_bc, + InferenceResult const &result) { + const std::lock_guard lock(request_queue_mutex); + + // Step 1: append result from previous iteration to request's tokens + for (int i = 0; i < old_bc.num_tokens; i++) { + size_t guid = + old_bc.requestsInfo[old_bc.tokensInfo[i].request_index].request_guid; + Request &request = all_requests[guid]; + if (old_bc.tokensInfo[i].abs_depth_in_request + 1 < request.tokens.size()) { + // This is a prompt token + continue; + } else { + assert(old_bc.tokensInfo[i].abs_depth_in_request + 1 == + request.tokens.size()); + // This is a decoding token + log_req_mgr.print("Output token is: %d", result.token_ids[i]); + request.tokens.push_back(result.token_ids[i]); + // std::string output = this->tokenizer_->Decode(request.tokens); + // log_req_mgr.print("Output: %s", output.c_str()); + } + } + int num_generation_tokens = 0; + int num_active_req = -1; + + // Step 2: prepare the next batch for existing requests + BatchConfig new_bc; + for (int i = 0; i < BatchConfig::max_requests_per_batch(); i++) { + if (old_bc.request_completed[i]) { // add new requests to the next batch + continue; + } else { + assert(old_bc.requestsInfo[i].num_tokens_in_batch > 0); + Request &request = all_requests[old_bc.requestsInfo[i].request_guid]; + int processed_tokens = + old_bc.requestsInfo[i].first_token_depth_in_request + + old_bc.requestsInfo[i].num_tokens_in_batch; + assert(processed_tokens < request.tokens.size()); + bool request_completed = false; + // printf("model_type = %d\n", this->model_type); + if (request.tokens.size() >= old_bc.requestsInfo[i].max_sequence_length) { + request_completed = true; + } else if (request.tokens.back() == eos_token_id) { + // Encounter EOS token id + request_completed = true; + } + if (request_completed) { + std::string output = this->tokenizer_->Decode(request.tokens); + // Unlike Huggingface, the sentencepiece C++ library automatically + // removes the BOS token + if (model_type == ModelType::LLAMA && + request.tokens.at(0) == bos_token_id) { + output = " " + output; + } + { + // update generation result + GenerationResult &gr = request_generation_results[request.guid]; + assert(gr.guid == request.guid); + gr.output_tokens = request.tokens; + gr.output_text = output; + } + request.status = Request::COMPLETED; + trigger_request_completion_future(request.guid); + log_req_mgr.print("[Done] guid(%zu) final_length(%zu)", + old_bc.requestsInfo[i].request_guid, + request.tokens.size()); + log_req_mgr.print("Final output: %s", output.c_str()); + num_processed_requests++; + ProfileInfo profile_info = profiling_requests[request.guid]; + profile_info.finish_time = Realm::Clock::current_time_in_microseconds(); + total_request_run_time += + profile_info.finish_time - profile_info.start_time; + profiling_requests[request.guid] = profile_info; + log_req_mgr.print( + "[Profile] guid(%zu) llm_decoding_steps(%d) start(%.1lf) " + "finish(%.1lf) latency(%.1lf)", + request.guid, + profile_info.llm_decoding_steps, + profile_info.start_time, + profile_info.finish_time, + profile_info.finish_time - profile_info.start_time); + // Write output to file if needed: + if (!output_filepath.empty()) { + std::ofstream outputFile(output_filepath, std::ios::app); + if (outputFile.is_open()) { + outputFile << "end-to-end latency: " << std::fixed + << std::setprecision(3) << total_request_run_time + << std::endl; + outputFile << "num decoding steps: " + << profile_info.llm_decoding_steps << std::endl; + outputFile << "token IDs: "; + for (int i = 0; i < request.tokens.size(); i++) { + outputFile << request.tokens[i]; + if (i < request.tokens.size() - 1) { + outputFile << ","; + } + } + outputFile << std::endl; + outputFile << output; + outputFile.close(); + } else { + std::cout << "Unable to open the output file: " << output_filepath + << std::endl; + assert(false); + } + } + + } else { + new_bc.request_completed[i] = false; + new_bc.requestsInfo[i].first_token_depth_in_request = processed_tokens; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = + old_bc.requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_bc.requestsInfo[i].max_sequence_length; + num_active_req++; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + if (new_bc.requestsInfo[i].first_token_depth_in_request + 1 == + request.tokens.size()) { + // Incremental phase + new_bc.requestsInfo[i].num_tokens_in_batch = 1; + num_generation_tokens++; + new_bc.requestsInfo[i].prompt_phase = false; + } else { + // Prompt phase + new_bc.requestsInfo[i].num_tokens_in_batch = + std::min(get_max_tokens_per_batch() - new_bc.num_tokens, + (int)request.tokens.size() - + new_bc.requestsInfo[i].first_token_depth_in_request); + new_bc.requestsInfo[i].prompt_phase = true; + } + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + int depth = new_bc.requestsInfo[i].first_token_depth_in_request + j; + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = depth; + assert(depth < request.tokens.size()); + new_bc.tokensInfo[new_bc.num_tokens].token_id = request.tokens[depth]; + new_bc.num_tokens++; + } + // Update profiling + profiling_requests[new_bc.requestsInfo[i].request_guid] + .llm_decoding_steps++; + } + } + } + new_bc.num_generation_tokens = num_generation_tokens; + + // Step 3: add new requests to the next batch + for (int i = 0; i < BatchConfig::max_requests_per_batch(); i++) { + if (new_bc.request_completed[i]) { + if (!pending_request_queue.empty() && + new_bc.num_tokens < get_max_tokens_per_batch()) { + Request new_request = pending_request_queue.front(); + pending_request_queue.pop(); + // all_requests[new_request.guid] = new_request; + + new_bc.requestsInfo[i].first_token_depth_in_request = 0; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = new_request.guid; + new_bc.requestsInfo[i].num_tokens_in_batch = + std::min(get_max_tokens_per_batch() - new_bc.num_tokens, + (int)new_request.tokens.size()); + new_bc.requestsInfo[i].max_sequence_length = + new_request.max_sequence_length; + new_bc.request_completed[i] = false; + new_bc.requestsInfo[i].prompt_phase = true; + num_active_req++; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + // add profile_info for the new request + ProfileInfo profile_info; + profile_info.llm_decoding_steps = 1; + profile_info.start_time = Realm::Clock::current_time_in_microseconds(); + profiling_requests[new_request.guid] = profile_info; + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + int depth = new_bc.requestsInfo[i].first_token_depth_in_request + j; + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = depth; + assert(depth < new_request.tokens.size()); + new_bc.tokensInfo[new_bc.num_tokens].token_id = + new_request.tokens[depth]; + new_bc.num_tokens++; + } + if (new_bc.num_tokens == get_max_tokens_per_batch()) { + break; + } + } + } + } + + return new_bc; +} + +/* ----- Speculative Inference Specific functions ----- */ + +/***** Request Init Phase *****/ +BeamSearchBatchConfigFuture RequestManager::prepare_next_batch_init( + TreeVerifyBatchConfigFuture const &old_bc, + InferenceResultFuture const &result, + int model_id, + Context ctx, + Runtime *runtime) { + + RequestManager *rm = this; + TaskLauncher launcher(RM_PREPARE_NEXT_BATCH_INIT_TASK_ID, + TaskArgument(&rm, sizeof(RequestManager *))); + launcher.add_future(old_bc); + launcher.add_future(result); + launcher.add_future(Future::from_value(model_id)); + return runtime->execute_task(ctx, launcher); +} + +BeamSearchBatchConfig RequestManager::prepare_next_batch_init_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RequestManager *rm = *((RequestManager **)task->args); + TreeVerifyBatchConfig const &bc = + Future(task->futures[0]).get_result(); + InferenceResult const &result = + Future(task->futures[1]).get_result(); + int model_id = Future(task->futures[2]).get_result(); + return rm->prepare_next_batch_init(bc, result, model_id); +} + +BeamSearchBatchConfig + RequestManager::prepare_next_batch_init(TreeVerifyBatchConfig const &old_bc, + InferenceResult const &result, + int model_id) { + const std::lock_guard lock(request_queue_mutex); + if (verbose) { + std::cout << "\n############### prepare_next_batch_init ###############\n"; + } + + // Step 1: use result to update requests + BeamSearchBatchConfig new_bc; + new_bc.num_tokens = 0; + new_bc.model_id = model_id; + int result_index = 0; + + int num_generation_tokens = 0; + int num_active_req = -1; + + for (int i = 0; i < BatchConfig::max_requests_per_batch(); i++) { + if (old_bc.request_completed[i]) { + continue; + } + size_t guid = old_bc.requestsInfo[i].request_guid; + Request &request = all_requests[guid]; + + std::cout << "[ " << guid << " ]" << std::endl; + + // Verify this: get verified tokens from result + std::vector> tree_outputs = + std::vector>(); + + assert(old_bc.num_tokens > 0); + + // reset committed_tokens + if (committed_tokens.count(guid) == 0) { + committed_tokens[guid] = {}; + } else { + committed_tokens[guid].clear(); + } + + // iterate through all the tokens that belong to request i + int root_abs_depth = request.tokens.size() - 1; + + while (result_index < old_bc.num_tokens && + old_bc.tokensInfo[result_index].request_index == i) { + int abs_depth = old_bc.tokensInfo[result_index].abs_depth_in_request; + int token_id = result.token_ids[result_index]; + + if (request.status == Request::PENDING) { + committed_tokens[guid].emplace_back(abs_depth, result_index); + } else if (abs_depth >= root_abs_depth) { + tree_outputs.emplace_back(token_id, abs_depth + 1); + // std::cout << "committred tokens push: " << abs_depth + // << " ,result index: " << result_index << "\n"; + committed_tokens[guid].emplace_back(abs_depth, result_index); + + if (verbose) { + std::cout << "Index within old batch: " << result_index << std::endl; + printf(" Input: [%d] %d ---> [%d] %d \n", + abs_depth, + old_bc.tokensInfo[result_index].token_id, + tree_outputs.back().second, + token_id); + } + // std::cout << "Index within old batch: " << result_index << std::endl; + // printf(" Input: [%d] %d ---> [%d] %d \n", + // abs_depth, + // old_bc.tokensInfo[result_index].token_id, + // tree_outputs.back().second, + // token_id); + } + result_index++; + } + + if (request.status == Request::RUNNING) { + + std::vector> verified_tokens = + traverse_verify_tree(guid, dfs_tree_inputs.at(guid), tree_outputs); + + log_req_mgr.print("Number of Verified Tokens = %zu", + verified_tokens.size()); + // check if the request is finished + if (verified_tokens.size() + request.tokens.size() >= + request.max_sequence_length) { + // Append all verified tokens to the request + for (auto const &token_pair : verified_tokens) { + if (token_pair.second < request.max_sequence_length) { + request.tokens.push_back(token_pair.first); + } + } + log_req_mgr.print("[Done] guid(%zu) with final length(%zu)", + request.guid, + request.tokens.size()); + std::string output = this->tokenizer_->Decode(request.tokens); + // Unlike Huggingface, the sentencepiece C++ library automatically + // removes the BOS token + if (model_type == ModelType::LLAMA && + request.tokens.at(0) == bos_token_id) { + output = " " + output; + } + { + // update generation result + GenerationResult &gr = request_generation_results[request.guid]; + assert(gr.guid == request.guid); + gr.output_tokens = request.tokens; + gr.output_text = output; + } + request.status = Request::COMPLETED; + trigger_request_completion_future(request.guid); + log_req_mgr.print("Final output: %s", output.c_str()); + + new_bc.request_completed[i] = true; + new_bc.request_running[i] = false; + num_processed_requests++; + + // Log profiling info + ProfileInfo profile_info = profiling_requests[request.guid]; + profile_info.finish_time = Realm::Clock::current_time_in_microseconds(); + profile_info.ssm_decoding_steps = 0; + total_request_run_time += + profile_info.finish_time - profile_info.start_time; + profiling_requests[request.guid] = profile_info; + log_req_mgr.print( + "[Profile] guid(%zu) llm_decoding_steps(%d) start(%.1lf) " + "finish(%.1lf) latency(%.1lf)", + request.guid, + profile_info.llm_decoding_steps, + profile_info.start_time, + profile_info.finish_time, + profile_info.finish_time - profile_info.start_time); + + // Write output to file if needed: + if (!output_filepath.empty()) { + std::ofstream outputFile(output_filepath, std::ios::app); + if (outputFile.is_open()) { + outputFile << "end-to-end latency: " << std::fixed + << std::setprecision(3) << total_request_run_time + << std::endl; + outputFile << "num decoding steps: " + << profile_info.llm_decoding_steps << std::endl; + outputFile << "token IDs: "; + for (int i = 0; i < request.tokens.size(); i++) { + outputFile << request.tokens[i]; + if (i < request.tokens.size() - 1) { + outputFile << ","; + } + } + outputFile << std::endl; + outputFile << output; + + outputFile.close(); + } else { + std::cout << "Unable to open the output file: " << output_filepath + << std::endl; + assert(false); + } + } + + // delete the old input tree from cache + dfs_tree_inputs.erase(request.guid); + + } else { // Request not finished, pass verified_tokens to next iteration + + new_bc.request_completed[i] = false; + new_bc.request_running[i] = true; + num_active_req++; + + // Normal Request Info + new_bc.requestsInfo[i].first_token_depth_in_request = + verified_tokens.front().second; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = + old_bc.requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_bc.requestsInfo[i].max_sequence_length; + new_bc.requestsInfo[i].num_tokens_in_batch = verified_tokens.size(); + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + // TODO: Beam Request Info, missing from VerifyTreeBatchConfig + int new_max_depth = + new_bc.requestsInfo[i].max_sequence_length - + new_bc.requestsInfo[i].first_token_depth_in_request - + verified_tokens.size(); + new_bc.beamRequestsInfo[i].current_depth = 1; + + profiling_requests[request.guid].ssm_decoding_steps = 0; + new_bc.requestsInfo[i].prompt_phase = true; + + int ssm_decoding_steps = 0; + new_bc.beamRequestsInfo[i].beam_size = + spec_infer_tree_width.size() > ssm_decoding_steps + ? spec_infer_tree_width[ssm_decoding_steps] + : 1; + new_bc.beamRequestsInfo[i].max_depth = + std::min(new_max_depth, BeamSearchBatchConfig::MAX_BEAM_DEPTH); + for (int j = 0; + j < BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES; + j++) { + new_bc.beamRequestsInfo[i].parent_id[j] = 0; + new_bc.beamRequestsInfo[i].probs[j] = 1; + } + + new_bc.beamRequestsInfo[i].sub_request_num = 1; + + new_bc.sub_requests[i] = 1; + + updateBitMask(new_bc.causalMask[i], + verified_tokens.size(), + request.tokens.size()); + + // Token Info + for (int j = 0; j < verified_tokens.size(); j++) { + auto token = verified_tokens.at(j); + + // Normal Token Info + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].token_id = token.first; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = + token.second; + + // Beam Token Info + new_bc.beamTokenInfo[new_bc.num_tokens].sub_request_index = 0; + new_bc.num_tokens++; + + // Add verified token to request's token list + request.tokens.push_back(token.first); + + if (new_bc.num_tokens == get_max_tokens_per_batch()) { + break; + } + } + + std::string output = this->tokenizer_->Decode(request.tokens); + // Unlike Huggingface, the sentencepiece C++ library automatically + // removes the BOS token + if (model_type == ModelType::LLAMA && + request.tokens.at(0) == bos_token_id) { + output = " " + output; + } + log_req_mgr.print("Output: %s", output.c_str()); + } + + } else if (request.status == Request::PENDING) { + new_bc.request_completed[i] = false; + new_bc.request_running[i] = false; + num_active_req++; + + std::cout << "ssm_cache_size: " << request.ssm_cache_size << ", " + << "initial_len: " << request.initial_len << std::endl; + assert(request.ssm_cache_size == request.initial_len); + + // Normal Request Info + new_bc.requestsInfo[i].first_token_depth_in_request = + request.ssm_cache_size; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = old_bc.requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_bc.requestsInfo[i].max_sequence_length; + new_bc.requestsInfo[i].num_tokens_in_batch = 0; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + // TODO: Beam Request Info, missing from VerifyTreeBatchConfig + new_bc.beamRequestsInfo[i].current_depth = 1; + int ssm_decoding_steps = + profiling_requests[request.guid].ssm_decoding_steps; + new_bc.beamRequestsInfo[i].beam_size = + spec_infer_tree_width.size() > ssm_decoding_steps + ? spec_infer_tree_width[ssm_decoding_steps] + : 1; + new_bc.beamRequestsInfo[i].max_depth = 0; + for (int j = 0; j < BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES; + j++) { + new_bc.beamRequestsInfo[i].parent_id[j] = 0; + new_bc.beamRequestsInfo[i].probs[j] = 1; + } + + new_bc.beamRequestsInfo[i].sub_request_num = 1; + + new_bc.sub_requests[i] = 1; + + // Token Info + std::string output = this->tokenizer_->Decode(request.tokens); + // Unlike Huggingface, the sentencepiece C++ library automatically removes + // the BOS token + if (model_type == ModelType::LLAMA && + request.tokens.at(0) == bos_token_id) { + output = " " + output; + } + log_req_mgr.print("Output: %s", output.c_str()); + } else { + assert(false); + } + } + + // Step 2: Initialize new request + for (int i = 0; i < BeamSearchBatchConfig::max_requests_per_batch(); i++) { + if (new_bc.request_completed[i]) { + if (!pending_request_queue.empty() && + new_bc.num_tokens < get_max_tokens_per_batch()) { + Request new_request = pending_request_queue.front(); + pending_request_queue.pop(); + // all_requests[new_request.guid] = new_request; + num_active_req++; + new_bc.requestsInfo[i].first_token_depth_in_request = 0; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = new_request.guid; + new_bc.requestsInfo[i].num_tokens_in_batch = + std::min(get_max_tokens_per_batch() - new_bc.num_tokens, + (int)new_request.tokens.size()); + new_bc.requestsInfo[i].max_sequence_length = + new_request.max_sequence_length; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + // add profile_info for the new request + ProfileInfo profile_info; + profile_info.llm_decoding_steps = 0; + profile_info.ssm_decoding_steps = 0; + profile_info.start_time = Realm::Clock::current_time_in_microseconds(); + profiling_requests[new_request.guid] = profile_info; + // init the beam search metadata per request + int ssm_decoding_steps = profile_info.ssm_decoding_steps; + + new_bc.beamRequestsInfo[i].beam_size = + spec_infer_tree_width.size() > ssm_decoding_steps + ? spec_infer_tree_width[ssm_decoding_steps] + : 1; + new_bc.beamRequestsInfo[i].current_depth = 1; + new_bc.beamRequestsInfo[i].max_depth = + std::min(BeamSearchBatchConfig::MAX_BEAM_DEPTH, + get_max_tokens_per_batch() - + new_bc.requestsInfo[i].num_tokens_in_batch - 1); + for (int j = 0; + j < BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES; + j++) { + new_bc.beamRequestsInfo[i].parent_id[j] = 0; + new_bc.beamRequestsInfo[i].probs[j] = 1; + } + + new_bc.request_completed[i] = false; + new_bc.requestsInfo[i].prompt_phase = true; + + new_bc.beamRequestsInfo[i].sub_request_num = 1; + printf("sub request num == 1, %d \n", + new_bc.beamRequestsInfo[i].beam_size); + + new_bc.sub_requests[i] = 1; + + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + int depth = new_bc.requestsInfo[i].first_token_depth_in_request + j; + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = depth; + assert(depth < new_request.tokens.size()); + new_bc.tokensInfo[new_bc.num_tokens].token_id = + new_request.tokens[depth]; + + // beam search meta data, indicate which sub request this token + // belongs to, init to 0; + new_bc.beamTokenInfo[new_bc.num_tokens].sub_request_index = 0; + new_bc.num_tokens++; + } + + initBitMask(new_bc.causalMask[i], + new_bc.requestsInfo[i].num_tokens_in_batch); + + // if (new_bc.requestsInfo[i].num_tokens_in_batch < + // new_request.initial_len) { + // all_requests[new_request.guid].status = Request::PENDING; + // new_bc.request_running[i] = false; + // std::cout << "Request " << new_request.guid << " is pending" + // << std::endl; + // } else { + // all_requests[new_request.guid].status = Request::RUNNING; + // new_bc.request_running[i] = true; + // std::cout << "Request " << new_request.guid << " is running" + // << std::endl; + // } + all_requests[new_request.guid].status = Request::PENDING; + all_requests[new_request.guid].ssm_cache_size = + new_bc.requestsInfo[i].num_tokens_in_batch; + new_bc.request_running[i] = false; + std::cout << "SSM KV Cache Size init: " + << all_requests[new_request.guid].ssm_cache_size << std::endl; + std::cout << "LLM KV Cache Size init: " + << all_requests[new_request.guid].llm_cache_size << std::endl; + + std::cout << "load " << new_bc.requestsInfo[i].num_tokens_in_batch + << " tokens for request " << new_request.guid << std::endl; + std::cout << "total prompt in request: " << new_request.initial_len + << std::endl; + + if (new_bc.num_tokens == get_max_tokens_per_batch()) { + break; + } + } + } + } + new_bc.num_generation_tokens = num_generation_tokens; + + if (verbose) { + std::cout << "prepare_next_batch_init OLD vs NEW batchconfigs below:" + << std::endl; + old_bc.print(); + new_bc.print(); + } + return new_bc; +} + +/***** Beam Search Phase *****/ +BeamSearchBatchConfigFuture RequestManager::prepare_next_batch_beam( + BeamSearchBatchConfigFuture const &old_bc, + BeamInferenceResultFuture const &result, + Context ctx, + Runtime *runtime) { + + RequestManager *rm = this; + TaskLauncher launcher(RM_PREPARE_NEXT_BATCH_BEAM_TASK_ID, + TaskArgument(&rm, sizeof(RequestManager *))); + launcher.add_future(old_bc); + launcher.add_future(result); + return runtime->execute_task(ctx, launcher); +} + +BeamSearchBatchConfig RequestManager::prepare_next_batch_beam_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RequestManager *rm = *((RequestManager **)task->args); + BeamSearchBatchConfig const &bc = + Future(task->futures[0]).get_result(); + BeamInferenceResult const &result = + Future(task->futures[1]).get_result(); + return rm->prepare_next_batch_beam(bc, result); +} + +// update beam search metadata +BeamSearchBatchConfig + RequestManager::prepare_next_batch_beam(BeamSearchBatchConfig const &old_bc, + BeamInferenceResult const &result) { + const std::lock_guard lock(request_queue_mutex); + if (verbose) { + std::cout << "\n############### prepare_next_batch_beam ###############\n"; + } + if (verbose) { + std::cout << "print all results" + << "\n"; + for (int i = 0; i < 40; i++) { + std::cout << result.token_ids[i] << ", "; + } + std::cout << "Current Beam Depth: " + << old_bc.beamRequestsInfo[0].current_depth << "\n"; + std::cout << "Current sub request num: " + << old_bc.beamRequestsInfo[0].sub_request_num << "\n"; + } + // Step 1: Store result to the beam tree struct + store_beam_metadata(old_bc, result); + + // Step 2: preparing the next batch for existing requests + BeamSearchBatchConfig new_bc; + new_bc.model_id = old_bc.model_id; + // std::cout << "old_bc.model_id: " << old_bc.model_id << "\n"; + int num_generation_tokens = 0; + + // Add incremental tokens to the batch + int num_active_req = -1; + for (int i = 0; i < BatchConfig::max_requests_per_batch(); i++) { + if (old_bc.request_completed[i] || !old_bc.request_running[i]) { + continue; + } + num_active_req++; + // Comment out this assertion since num_tokens_in_batch can be + // zero when beam search has reached required sequence length + // assert(old_bc.requestsInfo[i].num_tokens_in_batch > 0); + Request &request = all_requests[old_bc.requestsInfo[i].request_guid]; + int processed_tokens = old_bc.requestsInfo[i].first_token_depth_in_request + + old_bc.requestsInfo[i].num_tokens_in_batch; + + // assert(processed_tokens < request.tokens.size()); + log_req_mgr.debug() << "processed_tokens: " << processed_tokens << "\n"; + { + log_req_mgr.debug() << "num tokens: " << old_bc.num_tokens << ", " + << new_bc.num_tokens; + new_bc.request_completed[i] = false; + new_bc.requestsInfo[i].first_token_depth_in_request = processed_tokens; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = old_bc.requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_bc.requestsInfo[i].max_sequence_length; + profiling_requests[request.guid].ssm_decoding_steps += 1; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + // update the beam search metadata + // how many sub request in current request + // why is sub_requests has max_requests_per_batch() * MAX_BEAM_WIDTH + // entries? + // update the parentid, accumalated_probs, depth, and token_ids + int ssm_decoding_steps = + profiling_requests[request.guid].ssm_decoding_steps; + + new_bc.beamRequestsInfo[i].beam_size = + spec_infer_tree_width.size() > ssm_decoding_steps + ? spec_infer_tree_width[ssm_decoding_steps] + : 1; + + new_bc.beamRequestsInfo[i].max_depth = + old_bc.beamRequestsInfo[i].max_depth; + + new_bc.sub_requests[i] = + old_bc.sub_requests[i] * new_bc.beamRequestsInfo[i].beam_size; + new_bc.beamRequestsInfo[i].sub_request_num = + old_bc.beamRequestsInfo[i].sub_request_num * + old_bc.beamRequestsInfo[i].beam_size; + + assert(new_bc.beamRequestsInfo[i].sub_request_num <= + BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES && + "exceed maximum nodes per layer"); + + if (request.status == Request::RUNNING) { + new_bc.beamRequestsInfo[i].current_depth = + old_bc.beamRequestsInfo[i].current_depth + 1; + new_bc.request_running[i] = true; + // do the slot exchange to minimize the cache exchange in kernel. + update_beam_metadata( + new_bc, old_bc, request.beam_trees.at(old_bc.model_id), i); + + } else { + assert(false && "Request should not be pending in beam search phase"); + } + + // do the slot exchange to minimize the cache exchange in kernel. + // update_beam_metadata(new_bc, request.beam_trees.at(old_bc.model_id), + // i); + if (new_bc.requestsInfo[i].first_token_depth_in_request >= + request.tokens.size()) { + // Incremental phase + if (request.status == Request::RUNNING) { + // todo this is replaced by this_layer_size, but should check it + new_bc.requestsInfo[i].num_tokens_in_batch = 1; + } else { + assert(false && "Request should be done"); + // new_bc.requestsInfo[i].num_tokens_in_batch = 0; + } + + if (verbose) { + std::cout << "[ Beam Spec] " << request.guid << std::endl; + std::cout << "Incremental phase: " << request.tokens.size() + << ", num_tokens_in_batch: " + << new_bc.requestsInfo[i].num_tokens_in_batch << std::endl; + } + } + + if (verbose) { + std::cout << "SSM KV Cache Size beam: " << request.ssm_cache_size + << std::endl; + std::cout << "LLM KV Cache Size beam: " << request.llm_cache_size + << std::endl; + } + + // register more tokens due to the beam width + + // copy metadata + memcpy(&new_bc.causalMask[i], + &old_bc.causalMask[i], + sizeof(BatchConfig::BitMask)); + BeamTree tree = request.beam_trees[old_bc.model_id]; + appendBitMask(new_bc.causalMask[i], + new_bc.beamRequestsInfo[i].sub_request_num, + old_bc.beamRequestsInfo[i].beam_size, + old_bc.beamRequestsInfo[i].sub_request_num, + tree, + old_bc.beamRequestsInfo[i].current_depth); + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + int depth = new_bc.requestsInfo[i].first_token_depth_in_request + j; + for (int k = 0; k < new_bc.beamRequestsInfo[i].sub_request_num; k++) { + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = depth; + + // get value from requestinfo + new_bc.tokensInfo[new_bc.num_tokens].token_id = + new_bc.beamRequestsInfo[i].tokens[k]; + + new_bc.beamTokenInfo[new_bc.num_tokens].sub_request_index = k; + new_bc.num_tokens++; + + num_generation_tokens++; + } + } + } + } + + // how many requests is in speculative phase + new_bc.speculative_request_num = num_active_req + 1; + + // Add prompt tokens to the batch + for (int i = 0; i < BatchConfig::max_requests_per_batch(); i++) { + if (old_bc.request_completed[i] || old_bc.request_running[i]) { + continue; + } + num_active_req++; + // Comment out this assertion since num_tokens_in_batch can be + // zero when beam search has reached required sequence length + // assert(old_bc.requestsInfo[i].num_tokens_in_batch > 0); + Request &request = all_requests[old_bc.requestsInfo[i].request_guid]; + int processed_tokens = old_bc.requestsInfo[i].first_token_depth_in_request + + old_bc.requestsInfo[i].num_tokens_in_batch; + + // assert(processed_tokens < request.tokens.size()); + log_req_mgr.debug() << "processed_tokens: " << processed_tokens << "\n"; + + { + log_req_mgr.debug() << "num tokens: " << old_bc.num_tokens << ", " + << new_bc.num_tokens; + new_bc.request_completed[i] = false; + new_bc.requestsInfo[i].first_token_depth_in_request = processed_tokens; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = old_bc.requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_bc.requestsInfo[i].max_sequence_length; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + // update the beam search metadata + // how many sub request in current request + // why is sub_requests has max_requests_per_batch() * MAX_BEAM_WIDTH + // entries? + int ssm_decoding_steps = + profiling_requests[request.guid].ssm_decoding_steps; + + new_bc.beamRequestsInfo[i].beam_size = 1; + // printf("beam size: %d, %d\n", + // new_bc.beamRequestsInfo[i].beam_size, + // ssm_decoding_steps); + new_bc.beamRequestsInfo[i].max_depth = + old_bc.beamRequestsInfo[i].max_depth; + // new_bc.sub_requests[i] = + // old_bc.sub_requests[i] * new_bc.beamRequestsInfo[i].beam_size; + new_bc.sub_requests[i] = 1; + new_bc.beamRequestsInfo[i].sub_request_num = + old_bc.beamRequestsInfo[i].sub_request_num; + + assert(new_bc.beamRequestsInfo[i].sub_request_num <= + BeamSearchBatchConfig::MAX_SPECULATIVE_TREE_BRANCHES && + "exceed maximum nodes per layer"); + + // update the parentid, accumalated_probs, depth, and token_ids + + if (request.status == Request::PENDING) { + // if the request is pending, we need to update the beam search + // metadata based on the initial length + new_bc.beamRequestsInfo[i].current_depth = + old_bc.beamRequestsInfo[i].current_depth; + new_bc.request_running[i] = false; + } else { + assert(false && "Request should be pending"); + } + + memcpy(&new_bc.causalMask[i], + &old_bc.causalMask[i], + sizeof(BatchConfig::BitMask)); + + new_bc.requestsInfo[i].prompt_phase = true; + if (new_bc.requestsInfo[i].first_token_depth_in_request >= + request.tokens.size()) { + // request is done + new_bc.requestsInfo[i].num_tokens_in_batch = 0; + new_bc.causalMask[i].this_layer_size = 0; + new_bc.beamRequestsInfo[i].sub_request_num = 0; + new_bc.beamRequestsInfo[i].beam_size = 1; + } else { + // Prompt phase + new_bc.requestsInfo[i].num_tokens_in_batch = + std::min(get_max_tokens_per_batch() - new_bc.num_tokens - + BatchConfig::max_requests_per_batch() + i, + (int)request.tokens.size() - + new_bc.requestsInfo[i].first_token_depth_in_request); + request.ssm_cache_size += new_bc.requestsInfo[i].num_tokens_in_batch; + BeamTree tree = request.beam_trees[old_bc.model_id]; + appendPendingRequest(new_bc.causalMask[i], + new_bc.requestsInfo[i].num_tokens_in_batch); + } + + if (verbose) { + std::cout << "[ Beam Spec] " << request.guid << std::endl; + std::cout << "Prompt phase: " << request.tokens.size() + << ", num_tokens_in_batch:" + << new_bc.requestsInfo[i].num_tokens_in_batch << std::endl; + std::cout << "Update ssm cache size: " << request.ssm_cache_size + << std::endl; + + std::cout << "SSM KV Cache Size beam: " << request.ssm_cache_size + << std::endl; + std::cout << "LLM KV Cache Size beam: " << request.llm_cache_size + << std::endl; + } + + // register more tokens due to the beam width + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + int depth = new_bc.requestsInfo[i].first_token_depth_in_request + j; + for (int k = 0; k < new_bc.beamRequestsInfo[i].sub_request_num; k++) { + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = depth; + + // get value from requestinfo + new_bc.tokensInfo[new_bc.num_tokens].token_id = + request.tokens[request.tokens.size() - + new_bc.requestsInfo[i].num_tokens_in_batch + j]; + + new_bc.beamTokenInfo[new_bc.num_tokens].sub_request_index = k; + new_bc.num_tokens++; + } + } + } + } + + new_bc.num_generation_tokens = num_generation_tokens; + if (verbose) { + std::cout << "prepare_next_batch_beam OLD vs NEW batchconfigs:" + << std::endl; + old_bc.print(); + new_bc.print(); + } + return new_bc; +} + +/***** Verify Phase *****/ + +TreeVerifyBatchConfigFuture RequestManager::prepare_next_batch_verify( + std::vector const &old_batches, + Context ctx, + Runtime *runtime) { + + RequestManager *rm = this; + TaskLauncher launcher(RM_PREPARE_NEXT_BATCH_VERIFY_TASK_ID, + TaskArgument(&rm, sizeof(RequestManager *))); + for (auto const &bcf : old_batches) { + launcher.add_future(bcf); + } + return runtime->execute_task(ctx, launcher); +} + +TreeVerifyBatchConfig RequestManager::prepare_next_batch_verify_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RequestManager *rm = *((RequestManager **)task->args); + std::vector old_batches; + for (auto const &bcf : task->futures) { + old_batches.push_back(Future(bcf).get_result()); + } + return rm->prepare_next_batch_verify(old_batches); +} + +TreeVerifyBatchConfig RequestManager::prepare_next_batch_verify( + std::vector const &old_batches) { + const std::lock_guard lock(request_queue_mutex); + + if (verbose) { + std::cout + << "\n############### prepare_next_batch_verify ###############\n"; + } + + assert(old_batches.size() > 0); + + TreeVerifyBatchConfig new_bc; + new_bc.num_tokens_to_commit = 0; + new_bc.num_tokens = 0; + + int max_prompt_load_size = get_max_verify_tokens_per_batch(); + for (int i = 0; i < TreeVerifyBatchConfig::max_requests_per_batch(); i++) { + if (old_batches.at(0).request_completed[i]) { + continue; + } else if (old_batches.at(0).request_running[i]) { + max_prompt_load_size -= (BeamSearchBatchConfig::MAX_BEAM_DEPTH + 1); + } else { + max_prompt_load_size -= 1; + } + } + int num_active_req = -1; + for (int i = 0; i < TreeVerifyBatchConfig::max_requests_per_batch(); i++) { + if (old_batches.at(0).request_completed[i]) { + continue; + } + num_active_req++; + size_t guid = old_batches.at(0).requestsInfo[i].request_guid; + Request &request = all_requests[guid]; + + // Profiling + profiling_requests[request.guid].llm_decoding_steps += 1; + + if (request.status == Request::RUNNING) { + new_bc.request_running[i] = true; + + // Get the dfs tree + std::vector>> + all_dfs_trees; + + for (int j = 0; j < old_batches.size(); j++) { + std::vector> new_tree = + traverse_beam_tree(old_batches.at(j), i, request.tokens.size() - 1); + all_dfs_trees.push_back(new_tree); + } + assert(all_dfs_trees.size() == old_batches.size()); + std::vector> dfs_tree_inputs = + merge_dfs_trees(all_dfs_trees, request.tokens.size() - 1, guid); + + if (verbose) { + std::cout << "Request Tokens Size: " << request.tokens.size() + << std::endl; + for (int k = 0; k < request.tokens.size(); k++) { + std::cout << k << ": " << request.tokens[k] << std::endl; + } + } + + // Normal Request Info + new_bc.requestsInfo[i].first_token_depth_in_request = + dfs_tree_inputs.front().second; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = + old_batches.at(0).requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_batches.at(0).requestsInfo[i].max_sequence_length; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + // copy bitmask to verify batchconfig + memcpy(&(new_bc.causalMask[i]), + &(old_batches.at(0).causalMask[i]), + sizeof(BatchConfig::BitMask)); + // TODO: Check this + new_bc.requestsInfo[i].num_tokens_in_batch = 0; + new_bc.request_completed[i] = false; + + // std::cout << "dfs_tree_inputs: " << dfs_tree_inputs.size() << ", " + // << new_bc.causalMask[i].tree_size << ", " + // << new_bc.causalMask[i].non_tree_cache_size << "\n"; + // std::cout << "mask: " << std::bitset<64>(new_bc.causalMask[i].mask[0]) + // << "\n"; + + // Committed Tokens + if (committed_tokens.find(guid) != committed_tokens.end()) { + for (int j = 0; j < committed_tokens.at(guid).size(); j++) { + // if (j < committed_tokens.at(guid).size()) { + + auto committed_token = committed_tokens.at(guid).at(j); + new_bc.committed_tokens[new_bc.num_tokens_to_commit].token_index = + committed_token.second; + new_bc.committed_tokens[new_bc.num_tokens_to_commit].request_index = + i; + new_bc.committed_tokens[new_bc.num_tokens_to_commit].token_depth = + committed_token.first; + if (verbose) { + std::cout << new_bc.num_tokens_to_commit + << "- committed_token.token_depth: " + << committed_token.first + << ", token_index: " << committed_token.second + << std::endl; + } + new_bc.num_tokens_to_commit++; + request.llm_cache_size++; + // } + } + } + if (verbose) { + std::cout << "new_bc.num_tokens_to_commit: " + << new_bc.num_tokens_to_commit << std::endl; + } + + // Incremental phase: only add the last committed token + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].token_id = request.tokens.back(); + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = + request.tokens.size() - 1; + + new_bc.num_tokens++; + new_bc.requestsInfo[i].num_tokens_in_batch++; + + if (new_bc.num_tokens > get_max_verify_tokens_per_batch()) { + assert(false && + "Exceeding the space available in the TreeVerify batch"); + break; + } + + new_bc.requestsInfo[i].first_token_depth_in_request = + request.tokens.size() - 1; + + bool cutLayer = false; + // Add Tokens from the DFS Tree to the next batch + for (int j = 1; j < dfs_tree_inputs.size(); j++) { + auto token = dfs_tree_inputs.at(j); + if (verbose) { + std::cout << "[" << j << "] Token: " << token.first + << ", Depth:" << token.second << std::endl; + } + // Normal Token Info + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].token_id = token.first; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = + token.second; + + new_bc.num_tokens++; + new_bc.requestsInfo[i].num_tokens_in_batch++; + + if (new_bc.num_tokens == get_max_verify_tokens_per_batch() && + (j != dfs_tree_inputs.size() - 1)) { + cutLayer = true; + break; + } + } + + // delete the last incomplete layer + if (cutLayer) { + int total_tokens = new_bc.num_tokens; + for (int j = total_tokens - 1; j >= 1; j--) { + new_bc.num_tokens--; + new_bc.requestsInfo[i].num_tokens_in_batch--; + // std::cout << "cut: " << j << "\n"; + if (new_bc.tokensInfo[j].abs_depth_in_request != + new_bc.tokensInfo[j - 1].abs_depth_in_request) { + break; + } + } + } + + } else if (request.status == Request::PENDING) { + new_bc.request_running[i] = false; + if (verbose) { + std::cout << "[Verify] Request " << request.guid + << " is pending in loading prompt phase" << std::endl; + std::cout << "SSM KV Cache Size verify: " << request.ssm_cache_size + << std::endl; + std::cout << "LLM KV Cache Size verify: " << request.llm_cache_size + << std::endl; + } + + // Commit all tokens from the last loading batch + if (committed_tokens.find(guid) != committed_tokens.end()) { + for (int j = 0; j < committed_tokens.at(guid).size(); j++) { + auto token = committed_tokens.at(guid).at(j); + new_bc.committed_tokens[new_bc.num_tokens_to_commit].token_index = + token.second; + new_bc.committed_tokens[new_bc.num_tokens_to_commit].request_index = + i; + new_bc.committed_tokens[new_bc.num_tokens_to_commit].token_depth = + token.first; + + new_bc.num_tokens_to_commit++; + request.llm_cache_size++; + } + std::cout << "[Verify] Committed Tokens from last loading batch: " + << new_bc.num_tokens_to_commit << std::endl; + } + + memcpy(&(new_bc.causalMask[i]), + &(old_batches.at(0).causalMask[i]), + sizeof(BatchConfig::BitMask)); + + // Normal Request Info + new_bc.requestsInfo[i].first_token_depth_in_request = + request.llm_cache_size; + new_bc.requestsInfo[i].first_token_offset_in_batch = new_bc.num_tokens; + new_bc.requestsInfo[i].request_guid = + old_batches.at(0).requestsInfo[i].request_guid; + new_bc.requestsInfo[i].max_sequence_length = + old_batches.at(0).requestsInfo[i].max_sequence_length; + new_bc.requestsInfo[num_active_req].batch_config_request_id = i; + + new_bc.request_completed[i] = false; + + new_bc.requestsInfo[i].num_tokens_in_batch = + std::min(max_prompt_load_size, + (int)request.initial_len - + new_bc.requestsInfo[i].first_token_depth_in_request); + max_prompt_load_size -= new_bc.requestsInfo[i].num_tokens_in_batch; + + std::cout << "max_prompt_load_size: " << max_prompt_load_size + << std::endl; + + if (request.llm_cache_size < request.initial_len) { + // std::cout << "Initialization (prompt) phase: " + // << new_bc.requestsInfo[i].num_tokens_in_batch << ", " + // << old_batches.at(0).beamRequestsInfo[i].beam_size << "\n"; + // Initialization (prompt) phase + for (int j = 0; j < new_bc.requestsInfo[i].num_tokens_in_batch; j++) { + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].token_id = + request.tokens[request.llm_cache_size + j]; + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = + request.llm_cache_size + j; + new_bc.num_tokens++; + } + + if (new_bc.num_tokens > get_max_verify_tokens_per_batch()) { + printf("Exceeding (%i) the space available (%i) in the TreeVerify " + "batch\n", + new_bc.num_tokens, + get_max_verify_tokens_per_batch()); + assert(false); + } + + if (new_bc.requestsInfo[i].num_tokens_in_batch + + request.llm_cache_size >= + request.initial_len) { + // launch the request into running phase after loading all prompt + request.status = Request::RUNNING; + new_bc.request_running[i] = true; + + // std::cout << "new_bc.requestsInfo[i].num_tokens_in_batch: " + // << new_bc.requestsInfo[i].num_tokens_in_batch << + // std::endl; + new_bc.requestsInfo[i].prompt_phase = true; + + dfs_tree_inputs[guid] = + std::vector>{std::make_pair( + request.tokens.back(), request.tokens.size() - 1)}; + } + } else { // launch the request into running phase after loading all prompt + if (get_max_verify_tokens_per_batch() - new_bc.num_tokens > 0) { + // std::cout << "Initialization running phase: " + // << new_bc.requestsInfo[i].num_tokens_in_batch << "\n"; + request.status = Request::RUNNING; + new_bc.request_running[i] = true; + + new_bc.tokensInfo[new_bc.num_tokens].request_index = i; + new_bc.tokensInfo[new_bc.num_tokens].token_id = request.tokens.back(); + new_bc.tokensInfo[new_bc.num_tokens].abs_depth_in_request = + request.tokens.size() - 1; + + new_bc.num_tokens++; + new_bc.requestsInfo[i].num_tokens_in_batch++; + // std::cout << "new_bc.requestsInfo[i].num_tokens_in_batch2: " + // << new_bc.requestsInfo[i].num_tokens_in_batch << + // std::endl; + + new_bc.requestsInfo[i].prompt_phase = true; + dfs_tree_inputs[guid] = + std::vector>{std::make_pair( + request.tokens.back(), request.tokens.size() - 1)}; + } + } + + } else { + assert(false && "Request status is not RUNNING or PENDING"); + } + } + + return new_bc; +} + +void RequestManager::store_beam_metadata(BeamSearchBatchConfig const &old_bc, + BeamInferenceResult const &result) { + // step1 store the outputs + if (old_bc.num_tokens <= 0) { + return; + } + auto guid = + old_bc.requestsInfo[old_bc.tokensInfo[0].request_index].request_guid; + auto start_depth = old_bc.tokensInfo[0].abs_depth_in_request; + int result_index = 0; + + if (verbose) { + std::cout << "Store total of " << old_bc.num_tokens + << " tokens in the current batch.\n"; + } + + for (int i = 0; i <= old_bc.num_tokens; i++) { + if (i == old_bc.num_tokens || + old_bc.requestsInfo[old_bc.tokensInfo[i].request_index].request_guid != + guid) { + + // std::cout << "i is: " << i << "old guid" << guid << " new guid" + // << old_bc.requestsInfo[old_bc.tokensInfo[i].request_index] + // .request_guid + // << "\n"; + + int index = old_bc.tokensInfo[i - 1].request_index; + int beam_size = old_bc.beamRequestsInfo[index].beam_size; + + // int leaf_node_num = old_bc.sub_requests[index]; + int leaf_node_num = + old_bc.beamRequestsInfo[index].sub_request_num * beam_size; + int depth = old_bc.beamRequestsInfo[index].current_depth; + + // Each token yields (beam_width) results + // int beam_width = old_bc.beamRequestsInfo[index].beam_size; + + // Count tokens sent to model in this request to find the final token's + // index + result_index += + (old_bc.tokensInfo[i - 1].abs_depth_in_request - start_depth) * + beam_size; + + if (verbose) { + std::cout << "i = " << i << ", result index = " << result_index + << ", value: " << result.token_ids[result_index] + << ", leaf node num: " << leaf_node_num << ", depth" << depth + << ", beam size: " << beam_size << "\n"; + } + + Request &request = all_requests[old_bc.requestsInfo[index].request_guid]; + + if (old_bc.requestsInfo[index].num_tokens_in_batch == 0) { + continue; + } + + if (depth == 1) { + // store the last input into the tree; + if (verbose) { + std::cout << "try to store the input" + << "\n"; + } + + request.beam_trees.at(old_bc.model_id).treeLayers[0].tokens[0] = + request.tokens.back(); + request.beam_trees.at(old_bc.model_id).treeLayers[0].probs[0] = 1; + request.beam_trees.at(old_bc.model_id).treeLayers[0].parent_ids[0] = -1; + request.beam_trees.at(old_bc.model_id) + .treeLayers[0] + .nodes_num_this_layer = 1; + + if (verbose) { + std::cout << "Store the previous last token to the tree root: " + << request.tokens.back() << "\n"; + } + } + request.beam_trees.at(old_bc.model_id) + .treeLayers[depth] + .nodes_num_this_layer = leaf_node_num; + for (int beam_id = 0; beam_id < leaf_node_num; beam_id++) { + + request.beam_trees.at(old_bc.model_id) + .treeLayers[depth] + .tokens[beam_id] = result.token_ids[result_index]; + request.beam_trees.at(old_bc.model_id) + .treeLayers[depth] + .probs[beam_id] = result.probs[result_index]; + request.beam_trees.at(old_bc.model_id) + .treeLayers[depth] + .parent_ids[beam_id] = result.parent_id[result_index]; + + if (verbose) { + std::cout << "tree value: " << depth << "token: " + << request.beam_trees.at(old_bc.model_id) + .treeLayers[depth] + .tokens[beam_id] + << "result tokens: " << result.token_ids[result_index]; + } + result_index += 1; + } + // update the guid and start_depth for current request + if (i < old_bc.num_tokens) { + int new_req_idx = old_bc.tokensInfo[i].request_index; + guid = old_bc.requestsInfo[new_req_idx].request_guid; + start_depth = old_bc.tokensInfo[i].abs_depth_in_request; + } + } + } +} + +// for updating the beam search metadata in requests in incremental phase +void RequestManager::update_beam_metadata(BeamSearchBatchConfig &new_bc, + BeamSearchBatchConfig const &old_bc, + BeamTree &tree, + int request_index) { + + // do the exchange + if (new_bc.request_completed[request_index]) { + assert(false); + } + int depth = new_bc.beamRequestsInfo[request_index].current_depth - 1; + int beam_size = new_bc.beamRequestsInfo[request_index].beam_size; + + // int leaf_node_num = old_bc.sub_requests[request_index]; + int leaf_node_num = new_bc.beamRequestsInfo[request_index].sub_request_num; + + if (new_bc.beamRequestsInfo[request_index].current_depth == + 1) { // TODO: check if this is correct + // for (int j = 0; j < beam_size; j++) { + // new_bc.beamRequestsInfo[request_index].parent_id[j] = j; + // new_bc.beamRequestsInfo[request_index].probs[j] = + // tree.treeLayers[depth].probs[j]; // ? + // new_bc.beamRequestsInfo[request_index].tokens[j] = + // tree.treeLayers[depth].tokens[j]; // ? + // } + // Do nothing + // assert(false); + } else { + for (int j = 0; j < leaf_node_num; j++) { + new_bc.beamRequestsInfo[request_index].parent_id[j] = + tree.treeLayers[depth].parent_ids[j]; + new_bc.beamRequestsInfo[request_index].probs[j] = + tree.treeLayers[depth].probs[j]; + new_bc.beamRequestsInfo[request_index].tokens[j] = + tree.treeLayers[depth].tokens[j]; + // std::cout << "token: " << j << ": " + // << new_bc.beamRequestsInfo[request_index].tokens[j] << "\n"; + } + } + if (verbose) { + std::cout << "-----------after parent id exchange-----------" << std::endl; + for (int j = 0; j < beam_size; j++) { + std::cout << "after request id: " << request_index << "beam id = " << j + << "parent: " + << new_bc.beamRequestsInfo[request_index].parent_id[j] + << "token: " << new_bc.beamRequestsInfo[request_index].tokens[j] + << "probs: " << new_bc.beamRequestsInfo[request_index].probs[j] + << std::endl; + } + } +} + +// bit mask related function + +// prompt phase, init task +void RequestManager::initBitMask(BatchConfig::BitMask &bitmask, + int initLength) { + assert(initLength > 0); + // eg. 4 tokens: t1: 0000000..1111, t2: 0000000..1110, t3: 0000000..1100, t4: + // 0000000..1000 + bitmask.non_tree_cache_size = 0; + bitmask.tree_size = 1; + + bitmask.prompt_size = initLength; + bitmask.this_layer_size = initLength; + // std::cout << "see bit mask" << bitmask.prompt_size << "\n"; + // std::cout << "see bit mask" << std::bitset<64>(bitmask.mask[0]) << "\n"; + // std::cout << "see bit mask" << std::bitset<64>(bitmask.mask[1]) << "\n"; + // std::cout << "see bit mask" << std::bitset<64>(bitmask.mask[2]) << "\n"; +} + +// prepare next init +void RequestManager::updateBitMask(BatchConfig::BitMask &bitmask, + int initLength, + int non_tree_size) { + // assert(initLength == 1); + // eg. 4 tokens: t1: 0000000..1111, t2: 0000000..1110, t3: 0000000..1100, t4: + // 0000000..1000 + assert(initLength <= BatchConfig::MAX_SPEC_TREE_TOKEN_NUM && + "do not support tree size > 64"); + assert(initLength >= 1 && "verified token num should >= 1"); + + // std::cout << "non tree size: " << non_tree_size << ", " + // << bitmask.non_tree_cache_size << "\n"; + + bitmask.non_tree_cache_size = non_tree_size + initLength - 1; + bitmask.tree_size = 1; + bitmask.this_layer_size = initLength; + // std::cout << "non_tree_size: " << non_tree_size << "\n"; + bitmask.prompt_size = 1; + for (int i = 0; i < bitmask.prompt_size; i++) { + for (int j = i; j < bitmask.prompt_size; j++) { + bitmask.mask[i] |= (1 << j); + } + } + + // std::cout << "see bit mask update" << bitmask.prompt_size << "\n"; + // std::cout << "see bit mask update" << std::bitset<64>(bitmask.mask[0]) + // << "\n"; +} + +// prompt phase, init task +void RequestManager::appendPendingRequest(BatchConfig::BitMask &bitmask, + int initLength) { + assert(initLength > 0); + // std::cout << "append pending bit mask: " << initLength << "\n"; + // eg. 4 tokens: t1: 0000000..1111, t2: 0000000..1110, t3: 0000000..1100, t4: + // 0000000..1000 + bitmask.non_tree_cache_size = 0; + bitmask.tree_size = 1; + bitmask.prompt_size += initLength; + bitmask.this_layer_size = initLength; + + // for (int i = 0; i < bitmask.prompt_size; i++) { + // for (int j = i; j < bitmask.prompt_size; j++) { + // bitmask.mask[i] |= (1 << j); + // } + // } +} + +// prepare next beam, append layers to the tree +void RequestManager::appendBitMask(BatchConfig::BitMask &bitmask, + int newNodes, + int preBeamSize, + int old_sub_num, + BeamTree const tree, + int currentDepth) { + int pre_tree_size = bitmask.tree_size; + bitmask.tree_size += newNodes; + bitmask.this_layer_size = newNodes; + assert(bitmask.tree_size <= BatchConfig::MAX_SPEC_TREE_TOKEN_NUM && + "do not support tree size > 64"); + // preBeamSize: replicate num + + // add relationship with input/prompt + for (int i = 0; i < bitmask.prompt_size; i++) { + for (int j = pre_tree_size; j < bitmask.tree_size; j++) { + bitmask.mask[i] |= (1 << j); + // std::cout << "see bit mask append: " << i << ", to" << j + // << std::bitset<64>(bitmask.mask[i]) << "\n"; + } + } + + // std::cout << "bitmask.tree_size: " << bitmask.tree_size << ", " + // << pre_tree_size << ", " << bitmask.prompt_size << ", " + // << preBeamSize << "\n"; + + // int num_groups = newNodes / preBeamSize; + // int group_size = newNodes / num_groups; + // add relations to branch + // requests in same groups share same relations, except the last token. + + // set middle layers + // skip the root prompt/tokens + int token_idx = bitmask.prompt_size; + int new_nodes_start_idx = pre_tree_size; + // std::cout << "new nodes start " << new_nodes_start_idx << "\n"; + for (int i = 1; i < currentDepth; i++) { + new_nodes_start_idx = pre_tree_size; + int nodes_this_layer = tree.treeLayers[i].nodes_num_this_layer; + // std::cout << "tree layer: " << i << " nodes:" << nodes_this_layer + // << "group size: " << newNodes / nodes_this_layer << "\n"; + for (int j = 0; j < nodes_this_layer; j++) { + int group_size = newNodes / nodes_this_layer; + for (int k = 0; k < group_size; k++) { + bitmask.mask[token_idx] |= (1 << new_nodes_start_idx); + new_nodes_start_idx += 1; + } + token_idx += 1; + } + } + + assert(token_idx == pre_tree_size); + assert(currentDepth <= 1 || new_nodes_start_idx == bitmask.tree_size); + + // assert(currentDepth <= 2); + // set last layer, all tokens are only relevant to it self; + for (int i = token_idx; i < bitmask.tree_size; i++) { + bitmask.mask[i] |= (1 << i); + // std::cout << "set rel: " << i << "to: " << i << "\n"; + } + + // if(bitmask.non_tree_cache_size == 19 && bitmask.tree_size > 2){ + // assert(false); + // } + + // std::cout << "see bit mask append" << bitmask.prompt_size << "\n"; + // std::cout << "see bit mask append" << bitmask.non_tree_cache_size << "\n"; + // std::cout << "see bit mask append" << std::bitset<64>(bitmask.mask[0]) + // << "\n"; +} + +bool PreOrder( + BeamTree const &tree, + int max_depth, + int current_depth, + int beam_width, + int id, + std::vector> &serializedTree, + bool verbose) { + // terminate + if (current_depth >= max_depth) { + serializedTree.push_back(std::make_pair( + tree.treeLayers[current_depth].tokens[id], current_depth)); + if (verbose) { + std::cout << "last tokens: " << tree.treeLayers[current_depth].tokens[id] + << "\n"; + std::cout << "return true" + << "\n"; + } + return true; + } + + // add to tree; + // std::cout<<"node: " << current_depth << ", id: " << + serializedTree.push_back( + std::make_pair(tree.treeLayers[current_depth].tokens[id], current_depth)); + if (verbose) { + std::cout << "push something: " << tree.treeLayers[current_depth].tokens[id] + << ", " << current_depth << std::endl; + } + int index = serializedTree.size() - 1; + int next_layers = current_depth + 1; + + bool flag = false; + // recursion + for (int i = 0; i < beam_width; i++) { + int child_id = i; + int child_parent = tree.treeLayers[next_layers].parent_ids[i]; + + // for all childs, do preOrder + if (child_parent == id) { + if (verbose) { + std::cout << "current depth: " << current_depth << ", child_parent, " + << child_parent << ", child_id, " << child_id << "\n"; + } + bool res = PreOrder(tree, + max_depth, + current_depth + 1, + beam_width, + child_id, + serializedTree, + verbose); + flag = flag || res; + } + } + // if (!flag) { + // // no child for this token, delete it + // std::cout << "delete a node: " << + // tree.treeLayers[current_depth].tokens[id] + // << ", " << current_depth << std::endl; + // serializedTree.erase(serializedTree.begin() + index); + // } + return flag; +} + +std::vector> + RequestManager::traverse_verify_tree( + size_t guid, + std::vector> const + &inputSerializedTree, + std::vector> const + &outputSerializedTree) { + std::vector> verifiedTree; + // verifiedTree.push_back(inputSerializedTree.at(0)); + std::vector> new_committed_tokens = + std::vector>(); + + log_req_mgr.print("Input tree size (%zu) Output tree size (%zu)", + inputSerializedTree.size(), + outputSerializedTree.size()); + { // Input tree + std::ostringstream oss; + // inputSerializedTree is the dfs_tree_inputs_map[guid] array og (token id, + // depth) pairs + for (auto const &pair : inputSerializedTree) { + oss << " " << pair.second << ":" << pair.first; + // log_req_mgr.print("(%d, %d)", pair.first, pair.second); + } + log_req_mgr.print("Input tree:%s", oss.str().c_str()); + } + { // Output tree + // log_req_mgr.print("========Output============"); + // outputSerializedTree is an array of (token id, depth + 1) pairs + std::ostringstream oss; + for (auto const &pair : outputSerializedTree) { + // log_req_mgr.print("(%d, %d)", pair.first, pair.second); + oss << " " << pair.second << ":" << pair.first; + } + log_req_mgr.print("Output tree:%s", oss.str().c_str()); + } + { + // log_req_mgr.print("========Committed============"); + // committed_tokens[guid] is an array of (depth, result_index) pairs for + // the given request + std::ostringstream oss; + for (auto const &pair : committed_tokens.at(guid)) { + // log_req_mgr.print("(%d, %d)", pair.first, pair.second); + oss << " " << pair.second << ":" << pair.first; + } + log_req_mgr.print("Committed tokens:%s", oss.str().c_str()); + } + + // It's safe to have inputSerializedTree.size() > outputSerializedTree.size() + // In this case the inputSeriedTree ends with padding 0s + assert(inputSerializedTree.size() >= outputSerializedTree.size()); + + int *treeLayers = new int[inputSerializedTree.size()]; + int node_num = 1; + int layer_num = 0; + for (int token_id = 0; token_id < inputSerializedTree.size(); token_id++) { + if (token_id == (inputSerializedTree.size() - 1) || + inputSerializedTree.at(token_id + 1).second != + inputSerializedTree.at(token_id).second) { + treeLayers[layer_num] = node_num; + layer_num += 1; + node_num = 1; + } else { + node_num++; + } + } + + // to avoid branch switch when same tokens in input tree. + // todo, only checked for N->1->1->1 cases + + bool findFirst = false; + layer_num = -1; + int first_layer_slot = 0; + int first_layer_slot_total = 0; + int processed_whole_layer_tokens = 0; + + for (int i = 0; i < outputSerializedTree.size(); i++) { + auto input = inputSerializedTree.at(i); + auto output = outputSerializedTree.at(i); + + if (i == 0 || inputSerializedTree.at(i - 1).second != + inputSerializedTree.at(i).second) { + layer_num += 1; + processed_whole_layer_tokens += i == 0 ? 0 : treeLayers[layer_num - 1]; + } + + if (i == 0) { + verifiedTree.push_back(output); + + new_committed_tokens.push_back(std::make_pair( + input.second, + committed_tokens.at(guid).at(i).second)); // + // std::cout << committed_tokens.at(guid).at(i).first << ", " + // << committed_tokens.at(guid).at(i).second << std::endl; + // std::cout << input.first << ", " << input.second << std::endl; + + assert(committed_tokens.at(guid).at(i).first == input.second); + continue; + } + + if (input.first == verifiedTree.back().first && + input.second == verifiedTree.back().second) { + if (findFirst) { + // must in this branch. + int layer_slot = i - processed_whole_layer_tokens; + int layer_slot_total = treeLayers[layer_num]; + if ((first_layer_slot == layer_slot)) { + verifiedTree.push_back(output); + new_committed_tokens.push_back(std::make_pair( + input.second, committed_tokens.at(guid).at(i).second)); + // at this point, you'll not go other branches + // std::cout << "verify tree push back: " << output.first + // << ", tree size is: " << verifiedTree.size() + // << ", ??: " << input.first << ", " << input.second << + // "\n"; + + } else { + printf("not correct slot\n"); + } + } else { + verifiedTree.push_back(output); + first_layer_slot = i - processed_whole_layer_tokens; + first_layer_slot_total = treeLayers[layer_num]; + findFirst = true; + new_committed_tokens.push_back(std::make_pair( + input.second, + committed_tokens.at(guid).at(i).second)); // + // at this point, you'll not go other branches + // std::cout << "verify tree push back: " << output.first + // << ", tree size is: " << verifiedTree.size() + // << ", ??: " << input.first << ", " << input.second << "\n"; + } + + assert(committed_tokens.at(guid).at(i).first == input.second); + } + } + committed_tokens[guid] = new_committed_tokens; + { + // log_req_mgr.print("========Verified============"); + std::ostringstream oss; + for (auto const &pair : verifiedTree) { + // log_req_mgr.print("(%d, %d)", pair.first, pair.second); + oss << " " << pair.second << ":" << pair.first; + } + log_req_mgr.print("Verified:%s", oss.str().c_str()); + } + { + // log_req_mgr.print("========New Committed============"); + std::ostringstream oss; + for (auto const &pair : committed_tokens.at(guid)) { + // log_req_mgr.print("(%d, %d)", pair.first, pair.second); + oss << " " << pair.second << ":" << pair.first; + } + log_req_mgr.print("New committed:%s", oss.str().c_str()); + } + + return verifiedTree; +} + +std::vector> + RequestManager::traverse_beam_tree(BeamSearchBatchConfig const &old_bc, + int request_index, + int first_token_depth_in_request) { + if (verbose) { + std::cout << "[Traverse Beam Tree] request_index: " << request_index + << "\n"; + std::cout << "[Traverse Beam Tree] max_depth: " + << old_bc.beamRequestsInfo[request_index].max_depth << "\n"; + std::cout << "[Traverse Beam Tree] current_depth: " + << old_bc.beamRequestsInfo[request_index].current_depth << "\n"; + std::cout << "[Traverse Beam Tree] beam_width: " + << old_bc.beamRequestsInfo[request_index].beam_size << "\n"; + std::cout << "[Traverse Beam Tree] start index: " + << first_token_depth_in_request << "\n"; + } + + auto guid = old_bc.requestsInfo[request_index].request_guid; + Request &request = all_requests[guid]; + // std::cout << "request.beam_trees.size(): " << request.beam_trees.size() + // << std::endl; + BeamTree tree = request.beam_trees.at(old_bc.model_id); + + // std::cout << "print beam tree: " + // << "\n"; + std::vector> serializedTree; + for (int i = 0; i <= old_bc.beamRequestsInfo[request_index].max_depth; i++) { + // std::cout << "tree layer: " << i + // << ", num_nodes: " << tree.treeLayers[i].nodes_num_this_layer + // << "\n"; + // push tokens into tree + for (int j = 0; j < tree.treeLayers[i].nodes_num_this_layer; j++) { + // std::cout << "token: " << tree.treeLayers[i].tokens[j] << "\n"; + serializedTree.push_back(std::make_pair(tree.treeLayers[i].tokens[j], i)); + } + } + // token, index + // todo make this one global for different stages + + // PreOrder(tree, + // old_bc.beamRequestsInfo[request_index].max_depth, + // 0, + // old_bc.beamRequestsInfo[request_index].beam_size, + // 0, + // serializedTree, + // verbose); + + // print it + if (verbose) { + std::cout << "Print serialized tree: size:" << request_index + << serializedTree.size() << "\n"; + } + for (int k = 0; k < serializedTree.size(); k++) { + serializedTree.at(k).second += first_token_depth_in_request; + if (verbose) { + std::cout << "token id: " << serializedTree.at(k).first + << ", depth: " << serializedTree.at(k).second << "\n"; + } + } + + // if (dfs_tree_inputs.find(old_bc.requestsInfo[request_index].request_guid) + // != + // dfs_tree_inputs.end()) { + // dfs_tree_inputs[old_bc.requestsInfo[request_index].request_guid] = + // serializedTree; + // } else { + // dfs_tree_inputs.insert(std::make_pair( + // old_bc.requestsInfo[request_index].request_guid, serializedTree)); + // } + + return serializedTree; + // } +} + +std::vector> + RequestManager::merge_dfs_trees( + std::vector>> + input_trees, + int root_depth, + RequestGuid guid) { + assert(input_trees.size() == 1 && "currently using one ssm"); + dfs_tree_inputs[guid] = input_trees.at(0); + return input_trees.at(0); + + std::vector> merged_tree; + + std::unordered_map> childrens; + std::unordered_map curr_path; + + // convert pair to an integer + auto root = input_trees.at(0).at(0); + int root_id = root.first * 10000 + root.second; + + for (int i = 0; i < input_trees.size(); i++) { + auto tree = input_trees.at(i); + // all trees should have the same root + assert(tree.at(0) == root); + + for (auto const &pair : tree) { + int id = pair.first * 10000 + pair.second; // current node + curr_path[pair.second] = id; // log node in current search + + if (childrens.find(id) == childrens.end()) { + // init empty set + childrens[id] = std::set(); + } + + if (pair.second > root_depth) { + int parent_id = curr_path[pair.second - 1]; + childrens[parent_id].insert(id); + } + } + } + + std::stack q; + q.push(root_id); + + while (!q.empty()) { + int curr = q.top(); + q.pop(); + merged_tree.push_back(std::make_pair(curr / 10000, curr % 10000)); + for (int child : childrens[curr]) { + q.push(child); + } + } + + if (verbose) { + for (auto &pair : merged_tree) { + std::cout << pair.first << ", depth: " << pair.second << std::endl; + } + } + + dfs_tree_inputs[guid] = merged_tree; + + return merged_tree; +} + +std::vector + FFModel::generate(std::vector &prompts, int max_seq_length) { + RequestManager *rm = RequestManager::get_request_manager(); + std::vector guids; + for (int i = 0; i < prompts.size(); i++) { + RequestManager::RequestGuid guid = + rm->register_new_request(prompts.at(i), max_seq_length); + if (guid != RequestManager::INVALID_GUID) { + guids.push_back(guid); + } + } + std::vector results; + for (int i = 0; i < guids.size(); i++) { + results.push_back(rm->get_generation_result(guids[i])); + } + return results; +} + +void RequestManager::start_background_server(FFModel *model) { + assert(request_manager_status == INITIALIZED); + request_manager_status = SERVING; + // Start background task + Runtime *runtime = Runtime::get_runtime(); + Context ctx = Runtime::get_context(); + TaskLauncher launcher(RM_BACKGROUND_SERVING_TASK_ID, + TaskArgument(&model, sizeof(FFModel *))); + background_server_handler = runtime->execute_task(ctx, launcher); + // Register callbacks for normal exit + { + int ret = std::atexit(RequestManager::terminate_background_server_at_exit); + assert(ret == 0); // make sure the callback is successfully registered + } + // Register callbacks for termination + { + std::set_terminate([]() { + RequestManager::terminate_background_server_at_exit(); + std::abort(); + }); + } +} + +void RequestManager::background_serving_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + RequestManager *rm = RequestManager::get_request_manager(); + FFModel *llm = *(FFModel **)task->args; + { + // Update FFModel's lg_hlr and lg_ctx to the current + // task's runtime and ctx, since all future legion tasks are + // launched in this task + llm->config.lg_hlr = runtime; + llm->config.lg_ctx = ctx; + // Update the lg_hlr and lg_ctx of all SSMs' FFConfig + // since all future legion tasks are launched in this task + for (size_t i = 0; i < rm->get_num_ssms(); i++) { + FFModel *ssm = rm->get_ssm_model(i); + ssm->config.lg_hlr = runtime; + ssm->config.lg_ctx = ctx; + } + } + if (rm->get_num_ssms() == 0) { + // No SSMs: perform incremental decoding + rm->serve_incr_decoding(llm); + } else { + // Registered SSMs: perform speculative inference + rm->serve_spec_infer(llm); + } +} + +/*static*/ +void RequestManager::serve_incr_decoding(FFModel *llm) { + Context ctx = llm->config.lg_ctx; + Runtime *runtime = llm->config.lg_hlr; + // Compile the llm + InferenceManager *im = InferenceManager::get_inference_manager(); + im->compile_model_and_allocate_buffer(llm); + assert(im->model_weights_loaders.find(llm) != + im->model_weights_loaders.end()); + // Load model weights + im->model_weights_loaders[llm]->load_weights(llm); + // init operators + im->init_operators_inference(llm); + // Legion futures for inc_decoding and spec_infer + BatchConfigFuture last_bcf; + InferenceResultFuture last_irf; + { + // Initialize futures for incr decoding + BatchConfig bc; + InferenceResult ir; + last_bcf = Future::from_value(bc); + last_irf = Future::from_value(ir); + } + + std::queue> + batch_pipeline; + { batch_pipeline.push(std::make_pair(last_bcf, last_irf)); } + + while (!is_background_server_terminated()) { + + if (batch_pipeline.size() >= 4) { + // Block here to avoid launching too many batches + auto const &batch = batch_pipeline.front(); + batch.second.get_void_result(); + } + // deque finished batches + while (batch_pipeline.size() > 1) { + auto const &batch = batch_pipeline.front(); + if (batch.second.is_ready()) { + batch_pipeline.pop(); + } else { + break; + } + } + runtime->begin_trace(ctx, 12346 /*trace_id*/); + auto const &next_batch = batch_pipeline.back(); + BatchConfigFuture bcf = + prepare_next_batch(next_batch.first, next_batch.second, ctx, runtime); + FutureMap fm = im->inference(llm, 0, bcf); + assert(fm.get_future_map_domain().get_volume() == 1); + InferenceResultFuture irf = fm.get_future(0); + batch_pipeline.push(std::make_pair(bcf, irf)); + last_bcf = bcf; + last_irf = irf; + runtime->end_trace(ctx, 12346 /*trace_id*/); + } +} + +/*static*/ +void RequestManager::serve_spec_infer(FFModel *llm) { + Context ctx = llm->config.lg_ctx; + Runtime *runtime = llm->config.lg_hlr; + InferenceManager *im = InferenceManager::get_inference_manager(); + { + // Compile the llm + im->compile_model_and_allocate_buffer(llm); + assert(im->model_weights_loaders.find(llm) != + im->model_weights_loaders.end()); + // Load model weights + im->model_weights_loaders[llm]->load_weights(llm); + // init operators + im->init_operators_inference(llm); + } + for (size_t i = 0; i < get_num_ssms(); i++) { + // Compile the i-th ssm + FFModel *ssm = get_ssm_model(i); + im->compile_model_and_allocate_buffer(ssm); + assert(im->model_weights_loaders.find(llm) != + im->model_weights_loaders.end()); + // Load model weights + im->model_weights_loaders[ssm]->load_weights(ssm); + // init operators + im->init_operators_inference(ssm); + } + + std::queue> + batch_pipeline; + // Legion futures for inc_decoding and spec_infer + TreeVerifyBatchConfigFuture last_tree_bcf; + InferenceResultFuture last_tree_irf; + { + // Initialize futures for spec infer + TreeVerifyBatchConfig tree_bc; + InferenceResult tree_ir; + last_tree_bcf = Future::from_value(tree_bc); + last_tree_irf = Future::from_value(tree_ir); + } + batch_pipeline.push(std::make_pair(last_tree_bcf, last_tree_irf)); + + while (!is_background_server_terminated()) { + + if (batch_pipeline.size() >= 4) { + // Block here to avoid launching too many batches + auto const &batch = batch_pipeline.front(); + batch.second.get_void_result(); + } + // deque finished batches + while (batch_pipeline.size() > 1) { + auto const &batch = batch_pipeline.front(); + if (batch.second.is_ready()) { + batch_pipeline.pop(); + } else { + break; + } + } + auto const &next_batch = batch_pipeline.back(); + BeamSearchBatchConfigFuture beam_bcf = prepare_next_batch_init( + next_batch.first, next_batch.second, 0, ctx, runtime); + std::vector beam_bcf_vec(get_num_ssms()); + for (size_t ssm_id = 0; ssm_id < get_num_ssms(); ssm_id++) { + beam_bcf_vec[ssm_id] = beam_bcf; + } + runtime->begin_trace(ctx, 12345 /*trace_id*/); + + for (size_t i = 0; i < get_num_ssms(); i++) { + for (int depth = 0; depth < BeamSearchBatchConfig::MAX_BEAM_DEPTH; + depth++) { + beam_bcf = beam_bcf_vec[i]; + + FutureMap fm = im->inference(get_ssm_model(i), 0, beam_bcf_vec[i]); + assert(fm.get_future_map_domain().get_volume() == 1); + BeamInferenceResultFuture beam_irf = fm.get_future(0); + beam_bcf_vec[i] = + prepare_next_batch_beam(beam_bcf_vec[i], beam_irf, ctx, runtime); + } + } + // Token Tree Verification + { + TreeVerifyBatchConfigFuture tree_bcf = + prepare_next_batch_verify(beam_bcf_vec, ctx, runtime); + FutureMap fm = im->inference(llm, 0, tree_bcf); + assert(fm.get_future_map_domain().get_volume() == 1); + InferenceResultFuture tree_irf = fm.get_future(0); + batch_pipeline.push(std::make_pair(tree_bcf, tree_irf)); + last_tree_bcf = tree_bcf; + last_tree_irf = tree_irf; + } + runtime->end_trace(ctx, 12345 /*trace_id*/); + } +} + +void RequestManager::trigger_request_completion_future( + RequestGuid const &guid) { + const std::lock_guard lock(request_to_promise_mutex); + assert(request_to_promise.find(guid) != request_to_promise.end()); + // Set the completion promise in case other threads are waiting + request_to_promise[guid]->set_value(); +} + +/*static*/ +void RequestManager::terminate_background_server_at_exit() { + RequestManager *rm = RequestManager::get_request_manager(); + rm->terminate_background_server(); +} + +void RequestManager::terminate_background_server() { + if (request_manager_status == SERVING) { + request_manager_status = TERMINATED; + // Wait for the background server to terminate + Runtime *runtime = Runtime::get_runtime(); + Context ctx = Runtime::get_context(); + background_server_handler.get_void_result(); + } +} + +bool RequestManager::is_background_server_terminated() { + return request_manager_status == TERMINATED; +} + +RequestManager *request_manager_singleton = nullptr; + +/*static*/ +RequestManager *RequestManager::get_request_manager() { + if (request_manager_singleton == nullptr) { + request_manager_singleton = new RequestManager(); + } + return request_manager_singleton; +} + +}; // namespace FlexFlow diff --git a/src/runtime/request_manager.cpp b/src/runtime/request_manager.cpp new file mode 100644 index 0000000000..fadbf80d6d --- /dev/null +++ b/src/runtime/request_manager.cpp @@ -0,0 +1,174 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/request_manager.h" +#include "flexflow/utils/hip_helper.h" +#include + +namespace FlexFlow { + +using namespace Legion; + +void RequestManager::load_tokens_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 1); + assert(task->regions.size() == 1); + + // BatchConfig const batch_config = *((BatchConfig *)task->args); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + BatchConfig::TokenId dram_copy[BatchConfig::MAX_NUM_TOKENS]; + + // Extreme long prompts are not supported, only load up to + // max_tokens_per_batch as prompt + if (batch_config->num_tokens > BatchConfig::max_tokens_per_batch()) { + printf("Warning: too many tokens in prompt, only load up to %d tokens\n", + BatchConfig::max_tokens_per_batch()); + printf("Got: %d tokens\n", batch_config->num_tokens); + } + + for (int i = 0; i < batch_config->num_tokens; i++) { + dram_copy[i] = batch_config->tokensInfo[i].token_id; + } + TokenId *fb_ptr = helperGetTensorPointerWO( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + Domain domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + assert(batch_config->num_tokens <= domain.get_volume()); + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDA(hipMemcpyAsync(fb_ptr, + dram_copy, + sizeof(TokenId) * batch_config->num_tokens, + hipMemcpyHostToDevice, + stream)); +} + +void RequestManager::load_batch_config_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 0); + assert(task->regions.size() == 0); + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + // BatchConfig const batch_config = *((BatchConfig *)task->args); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + + // copy meta data to workSpace + FFHandler handle = *((FFHandler const *)task->local_args); + size_t total_copy_size = 0; + checkCUDA(hipMemcpyAsync(handle.batch_config_metadata, + &(batch_config->tokensInfo), + sizeof(BatchConfig::tokensInfo), + hipMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::tokensInfo); + + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(batch_config->requestsInfo), + sizeof(BatchConfig::requestsInfo), + hipMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::requestsInfo); + + // load speculative metadata + if (batch_config->get_mode() == BEAM_SEARCH_MODE) { + BeamSearchBatchConfig const *beam_batch_config = + static_cast(batch_config); + + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(beam_batch_config->beamTokenInfo), + sizeof(BeamSearchBatchConfig::beamTokenInfo), + hipMemcpyHostToDevice, + stream)); + + total_copy_size += sizeof(BeamSearchBatchConfig::beamTokenInfo); + + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(beam_batch_config->beamRequestsInfo), + sizeof(BeamSearchBatchConfig::beamRequestsInfo), + hipMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BeamSearchBatchConfig::beamRequestsInfo); + + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(beam_batch_config->causalMask), + sizeof(BatchConfig::causalMask), + hipMemcpyHostToDevice, + stream)); + + total_copy_size += sizeof(BatchConfig::causalMask); + } else if (batch_config->get_mode() == TREE_VERIFY_MODE) { + TreeVerifyBatchConfig const *tree_batch_config = + static_cast(batch_config); + + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(tree_batch_config->causalMask), + sizeof(BatchConfig::causalMask), + hipMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::causalMask); + checkCUDA(hipMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(tree_batch_config->committed_tokens), + sizeof(TreeVerifyBatchConfig::committed_tokens), + hipMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(TreeVerifyBatchConfig::committed_tokens); + } + + // add a size check + assert(total_copy_size <= handle.batch_config_metadata_size); +} + +void RequestManager::load_positions_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 1); + assert(task->regions.size() == 1); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + + int const offset = *((int const *)task->args); + int *pos_ptr = helperGetTensorPointerWO( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + Domain domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + int dram_copy[BatchConfig::MAX_NUM_TOKENS]; + + for (int i = 0; i < batch_config->num_tokens; i++) { + dram_copy[i] = batch_config->tokensInfo[i].abs_depth_in_request + offset; + } + hipStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDA(hipMemcpyAsync(pos_ptr, + dram_copy, + sizeof(int) * batch_config->num_tokens, + hipMemcpyHostToDevice, + stream)); +} + +}; // namespace FlexFlow diff --git a/src/runtime/request_manager.cu b/src/runtime/request_manager.cu new file mode 100644 index 0000000000..8380d6be73 --- /dev/null +++ b/src/runtime/request_manager.cu @@ -0,0 +1,201 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/request_manager.h" +#include "flexflow/utils/cuda_helper.h" + +namespace FlexFlow { + +using namespace Legion; + +void RequestManager::load_tokens_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 1); + assert(task->regions.size() == 1); + + // BatchConfig const batch_config = *((BatchConfig *)task->args); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + + BatchConfig::TokenId dram_copy[BatchConfig::MAX_NUM_TOKENS]; + + // Extreme long prompts are not supported, only load up to + // BatchConfig::max_tokens_per_batch() as prompt + if (batch_config->num_tokens > BatchConfig::max_tokens_per_batch() && + batch_config->get_mode() == INC_DECODING_MODE) { + printf("Warning: too many tokens in prompt, only load up to %d tokens\n", + BatchConfig::max_tokens_per_batch()); + printf("Got: %d tokens\n", batch_config->num_tokens); + } else if (batch_config->num_tokens > + BatchConfig::max_verify_tokens_per_batch()) { + printf("Warning: Speculative decoding. too many tokens in prompt, only " + "load up to %d tokens\n", + BatchConfig::max_verify_tokens_per_batch()); + printf("Got: %d tokens\n", batch_config->num_tokens); + } + + for (int i = 0; i < batch_config->num_tokens; i++) { + dram_copy[i] = batch_config->tokensInfo[i].token_id; + } + TokenId *fb_ptr = helperGetTensorPointerWO( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + Domain domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + assert(batch_config->num_tokens <= domain.get_volume()); + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDA(cudaMemcpyAsync(fb_ptr, + dram_copy, + sizeof(TokenId) * batch_config->num_tokens, + cudaMemcpyHostToDevice, + stream)); +} + +void RequestManager::load_batch_config_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 0); + assert(task->regions.size() == 0); + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + + // BatchConfig const batch_config = *((BatchConfig *)task->args); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + + // copy meta data to workSpace + FFHandler handle = *((FFHandler const *)task->local_args); + size_t total_copy_size = 0; + checkCUDA(cudaMemcpyAsync(handle.batch_config_metadata, + &(batch_config->tokensInfo), + sizeof(BatchConfig::tokensInfo), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::tokensInfo); + + checkCUDA(cudaMemcpyAsync(static_cast(handle.batch_config_metadata) + + total_copy_size, + &(batch_config->requestsInfo), + sizeof(BatchConfig::requestsInfo), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::requestsInfo); + + // load speculative metadata + if (batch_config->get_mode() == BEAM_SEARCH_MODE) { + BeamSearchBatchConfig const *beam_batch_config = + static_cast(batch_config); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(beam_batch_config->beamTokenInfo), + sizeof(BeamSearchBatchConfig::beamTokenInfo), + cudaMemcpyHostToDevice, + stream)); + + total_copy_size += sizeof(BeamSearchBatchConfig::beamTokenInfo); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(beam_batch_config->beamRequestsInfo), + sizeof(BeamSearchBatchConfig::beamRequestsInfo), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BeamSearchBatchConfig::beamRequestsInfo); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(beam_batch_config->causalMask), + sizeof(BatchConfig::causalMask), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::causalMask); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(batch_config->request_completed), + sizeof(BatchConfig::request_completed), + cudaMemcpyHostToDevice, + stream)); + + total_copy_size += sizeof(BatchConfig::request_completed); + } else if (batch_config->get_mode() == TREE_VERIFY_MODE) { + TreeVerifyBatchConfig const *tree_batch_config = + static_cast(batch_config); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(tree_batch_config->causalMask), + sizeof(BatchConfig::causalMask), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(BatchConfig::causalMask); + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(tree_batch_config->committed_tokens), + sizeof(TreeVerifyBatchConfig::committed_tokens), + cudaMemcpyHostToDevice, + stream)); + total_copy_size += sizeof(TreeVerifyBatchConfig::committed_tokens); + + checkCUDA(cudaMemcpyAsync( + static_cast(handle.batch_config_metadata) + total_copy_size, + &(batch_config->request_completed), + sizeof(BatchConfig::request_completed), + cudaMemcpyHostToDevice, + stream)); + + total_copy_size += sizeof(BatchConfig::request_completed); + } + + // add a size check + assert(total_copy_size <= handle.batch_config_metadata_size); +} + +void RequestManager::load_positions_task( + Task const *task, + std::vector const ®ions, + Context ctx, + Runtime *runtime) { + assert(regions.size() == 1); + assert(task->regions.size() == 1); + + // BatchConfig const batch_config = *((BatchConfig *)task->args); + BatchConfig const *batch_config = BatchConfig::from_future(task->futures[0]); + + int const offset = *((int const *)task->args); + int *pos_ptr = helperGetTensorPointerWO( + regions[0], task->regions[0], FID_DATA, ctx, runtime); + Domain domain = runtime->get_index_space_domain( + ctx, task->regions[0].region.get_index_space()); + int dram_copy[BatchConfig::MAX_NUM_TOKENS]; + + for (int i = 0; i < batch_config->num_tokens; i++) { + dram_copy[i] = batch_config->tokensInfo[i].abs_depth_in_request + offset; + } + + cudaStream_t stream; + checkCUDA(get_legion_stream(&stream)); + checkCUDA(cudaMemcpyAsync(pos_ptr, + dram_copy, + sizeof(int) * batch_config->num_tokens, + cudaMemcpyHostToDevice, + stream)); +} + +}; // namespace FlexFlow diff --git a/src/runtime/simulator.cc b/src/runtime/simulator.cc index c363cdd296..d943376416 100644 --- a/src/runtime/simulator.cc +++ b/src/runtime/simulator.cc @@ -14,6 +14,7 @@ */ #include "flexflow/simulator.h" +#include "flexflow/ffconst_utils.h" #include "flexflow/model.h" #include "flexflow/parallel_ops/combine.h" #include "flexflow/parallel_ops/partition.h" @@ -349,25 +350,6 @@ void Simulator::free_all() { offset = 0; } -size_t data_type_size(DataType type) { - switch (type) { - case DT_HALF: - return sizeof(half); - case DT_FLOAT: - return sizeof(float); - case DT_DOUBLE: - return sizeof(double); - case DT_INT32: - return sizeof(int32_t); - case DT_INT64: - return sizeof(int64_t); - case DT_BOOLEAN: - return sizeof(bool); - default: - assert(false); - } -} - void *Simulator::allocate(size_t num_elements, DataType type) { size_t element_size = data_type_size(type); void *ret_ptr = base_ptr + offset; diff --git a/src/runtime/simulator.cpp b/src/runtime/simulator.cpp index f1d076b4c9..0daf151d2c 100644 --- a/src/runtime/simulator.cpp +++ b/src/runtime/simulator.cpp @@ -80,13 +80,13 @@ Simulator::Simulator(FFModel const *model, size_t max_num_tasks = 1024 * 1024; - hipEventCreate(&start_event); - hipEventCreate(&end_event); + checkCUDA(hipEventCreate(&start_event)); + checkCUDA(hipEventCreate(&end_event)); conv2d_meta = new Conv2DMeta(handler); - linear_meta = new LinearMeta(handler, 4096); + // linear_meta = new LinearMeta(handler, 4096); pool2d_meta = new Pool2DMeta(handler); ele_unary_meta = new ElementUnaryMeta(handler); - ele_binary_meta = new ElementBinaryMeta(handler); + // ele_binary_meta = new ElementBinaryMeta(handler); // embedding_meta = new EmbeddingMeta(handler); // softmax_meta = new SoftmaxMeta(handler); batch_matmul_meta = new BatchMatmulMeta(handler); diff --git a/src/runtime/simulator.cu b/src/runtime/simulator.cu index 8f109d0edb..b44ce1690a 100644 --- a/src/runtime/simulator.cu +++ b/src/runtime/simulator.cu @@ -82,10 +82,10 @@ Simulator::Simulator(FFModel const *model, cudaEventCreate(&start_event); cudaEventCreate(&end_event); conv2d_meta = new Conv2DMeta(handler); - linear_meta = new LinearMeta(handler, 4096); + // linear_meta = new LinearMeta(handler, 4096); pool2d_meta = new Pool2DMeta(handler); ele_unary_meta = new ElementUnaryMeta(handler); - ele_binary_meta = new ElementBinaryMeta(handler); + // ele_binary_meta = new ElementBinaryMeta(handler); // embedding_meta = new EmbeddingMeta(handler); // softmax_meta = new SoftmaxMeta(handler); batch_matmul_meta = new BatchMatmulMeta(handler); @@ -106,7 +106,6 @@ Simulator::~Simulator(void) { delete conv2d_meta; delete pool2d_meta; delete ele_unary_meta; - delete ele_binary_meta; delete batch_matmul_meta; delete concat_meta; delete transpose_meta; diff --git a/src/runtime/substitution.cc b/src/runtime/substitution.cc index 4f44a3a574..16b7b8c7c5 100644 --- a/src/runtime/substitution.cc +++ b/src/runtime/substitution.cc @@ -18,6 +18,7 @@ #include "flexflow/ffconst_utils.h" #include "flexflow/graph.h" #include "flexflow/graph_structures.h" +#include "flexflow/ops/add_bias_residual_layer_norm.h" #include "flexflow/ops/aggregate.h" #include "flexflow/ops/attention.h" #include "flexflow/ops/concat.h" @@ -26,12 +27,20 @@ #include "flexflow/ops/element_binary.h" #include "flexflow/ops/element_unary.h" #include "flexflow/ops/embedding.h" +#include "flexflow/ops/experts.h" #include "flexflow/ops/flat.h" +#include "flexflow/ops/inc_multihead_self_attention.h" #include "flexflow/ops/linear.h" #include "flexflow/ops/noop.h" #include "flexflow/ops/pool_2d.h" +#include "flexflow/ops/residual_layer_norm.h" +#include "flexflow/ops/residual_rms_norm.h" +#include "flexflow/ops/rms_norm.h" +#include "flexflow/ops/sigmoid_silu_multi.h" #include "flexflow/ops/softmax.h" #include "flexflow/ops/split.h" +#include "flexflow/ops/tree_inc_multihead_self_attention.h" +#include "flexflow/parallel_ops/allreduce.h" #include "flexflow/parallel_ops/combine.h" #include "flexflow/parallel_ops/fused_parallel_op.h" #include "flexflow/parallel_ops/allreduce.h" @@ -894,8 +903,11 @@ bool GraphXfer::create_new_operator(OpX const *opx, Node &op) { case OP_EW_MUL: case OP_EW_MAX: case OP_EW_MIN: { + ElementBinaryParams params; + params.type = opx->type; + params.inplace_a = false; op = model->get_or_create_node({inputs[0], inputs[1]}, - {opx->type}); + params); break; } case OP_RELU: { @@ -947,8 +959,12 @@ bool GraphXfer::create_new_operator(OpX const *opx, Node &op) { } case OP_SOFTMAX: { int softmax_dim; + assert(opx->matchOpX != NULL); + assert(opx->matchOpX->mapOp.ptr != NULL); + Softmax *softmax = (Softmax *)opx->matchOpX->mapOp.ptr; assert(opx->get_pm_constraint(PM_SOFTMAX_DIM, softmax_dim)); - op = model->get_or_create_node(inputs[0], {softmax_dim}); + SoftmaxParams params = softmax->get_params(); + op = model->get_or_create_node(inputs[0], params); break; } case OP_REPARTITION: { @@ -1482,6 +1498,8 @@ OpX *create_opx(sl::Operator const &op, case OP_REPLICATE: degree_key = PM_REPLICATE_DEGREE; break; + default: + break; } if (degree_key.has_value()) { @@ -1504,6 +1522,8 @@ OpX *create_opx(sl::Operator const &op, case OP_REPLICATE: dim_key = PM_REPLICATE_DIM; break; + default: + break; } if (dim_key.has_value()) { @@ -3655,6 +3675,13 @@ bool FFModel::convert_graph_to_operators( new_op = new Aggregate(*this, inputs, aggr->n, aggr->lambda_bal, NULL); break; } + case OP_EXPERTS: { + Experts *exp = (Experts *)node.ptr; + ExpertsParams params = exp->get_params(); + new_op = new Experts( + *this, params, {std::begin(inputs), std::end(inputs)}, true); + break; + } case OP_SPLIT: { Split *split = (Split *)node.ptr; std::vector splits; @@ -3675,8 +3702,13 @@ bool FFModel::convert_graph_to_operators( case OP_EW_MIN: { assert(inList.size() == 2); ElementBinary *eb = (ElementBinary *)node.ptr; - new_op = new ElementBinary( - *this, eb->op_type, inputs[0], inputs[1], eb->inplace_a, NULL); + new_op = new ElementBinary(*this, + eb->layer_guid, + eb->op_type, + inputs[0], + inputs[1], + eb->inplace_a, + NULL); break; } case OP_POOL2D: { @@ -3701,6 +3733,25 @@ bool FFModel::convert_graph_to_operators( new_op = new MultiHeadAttention( *this, *attn, inputs[0], inputs[1], inputs[2], true); break; + } + case OP_INC_MULTIHEAD_SELF_ATTENTION: { + assert(inList.size() == 1); + IncMultiHeadSelfAttention *attn = (IncMultiHeadSelfAttention *)node.ptr; + new_op = new IncMultiHeadSelfAttention(*this, *attn, inputs[0], true); + break; + } + case OP_TREE_INC_MULTIHEAD_SELF_ATTENTION: { + assert(inList.size() == 1); + TreeIncMultiHeadSelfAttention *attn = + (TreeIncMultiHeadSelfAttention *)node.ptr; + new_op = + new TreeIncMultiHeadSelfAttention(*this, *attn, inputs[0], true); + break; + } + case OP_RMS_NORM: { + assert(inList.size() == 1); + RMSNorm *rms = (RMSNorm *)node.ptr; + new_op = new RMSNorm(*this, *rms, inputs[0], true); break; } case OP_SOFTMAX: { @@ -3760,6 +3811,30 @@ bool FFModel::convert_graph_to_operators( new_op = new FusedParallelOp(*this, inputs[0], parallel_ops); break; } + case OP_ADD_BIAS_RESIDUAL_LAYERNORM: { + assert(inList.size() == 2); + AddBiasResidualLayerNorm *abr_ln = (AddBiasResidualLayerNorm *)node.ptr; + AddBiasResidualLayerNormParams params = abr_ln->get_params(); + new_op = new AddBiasResidualLayerNorm(*this, + abr_ln->layer_guid, + inputs[0], + inputs[1], + abr_ln->axes, + abr_ln->elementwise_affine, + abr_ln->use_bias, + abr_ln->eps, + true, + NULL); + break; + } + case OP_SIGMOID_SILU_MULTI: { + assert(inList.size() == 2); + SigmoidSiluMulti *ssm = (SigmoidSiluMulti *)node.ptr; + SigmoidSiluMultiParams params = ssm->get_params(); + new_op = new SigmoidSiluMulti( + *this, ssm->layer_guid, inputs[0], inputs[1], NULL); + break; + } default: { new_op = node.ptr->materialize(*this, inputs, num_inputs); break; diff --git a/src/runtime/tree_verify_batch_config.cc b/src/runtime/tree_verify_batch_config.cc new file mode 100644 index 0000000000..841c735f59 --- /dev/null +++ b/src/runtime/tree_verify_batch_config.cc @@ -0,0 +1,104 @@ +/* Copyright 2023 CMU, Stanford, Facebook, LANL + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include "flexflow/batch_config.h" +#include "flexflow/request_manager.h" +#include "legion.h" +#include +#include + +namespace FlexFlow { + +LegionRuntime::Logger::Category log_tree_bc("TreeVerifyBatchConfig"); + +TreeVerifyBatchConfig::TreeVerifyBatchConfig() : BatchConfig() {} + +TreeVerifyBatchConfig::~TreeVerifyBatchConfig() {} + +InferenceMode TreeVerifyBatchConfig::get_mode() const { + return TREE_VERIFY_MODE; +} + +std::ostream &operator<<(std::ostream &os, TreeVerifyBatchConfig const &bc) { + os << "@@@@@@@@@@@@@@ TreeVerifyBatchConfig (mode " << bc.get_mode() + << ") @@@@@@@@@@@@@@" << std::endl; + // Max values + os << "Max number of requests: " << bc.max_requests_per_batch() << std::endl; + os << "Max number of tokens: " << bc.max_tokens_per_batch() << std::endl; + os << "Max sequence length: " << bc.max_sequence_length() << std::endl; + // Current values + os << "Number of tokens: " << bc.num_active_tokens() << std::endl; + os << "Number of requests: " << bc.num_active_requests() << std::endl; + os << "Number of tokens to commit: " << bc.num_tokens_to_commit << std::endl; + + os << "Per-request info:\n"; + for (int i = 0; i < bc.max_requests_per_batch(); i++) { + if (!bc.request_completed[i]) { + os << " Request " << i << ":\n"; + os << " First token depth in request: " + << bc.requestsInfo[i].first_token_depth_in_request << std::endl; + os << " First token offset in batch: " + << bc.requestsInfo[i].first_token_offset_in_batch << std::endl; + os << " Number of tokens in batch: " + << bc.requestsInfo[i].num_tokens_in_batch << std::endl; + os << " GUID: " << bc.requestsInfo[i].request_guid << std::endl; + os << " Max sequence length: " + << bc.requestsInfo[i].max_sequence_length << std::endl; + os << " Request completed: " << bc.request_completed[i] << std::endl; + os << " Request running: " << bc.request_running[i] << std::endl; + } + } + + os << "Per-token info:\n"; + for (int i = 0; i < bc.num_tokens; i++) { + os << " Token " << i << ":\n"; + os << " Absolute depth in request: " + << bc.tokensInfo[i].abs_depth_in_request << std::endl; + os << " Request index: " << bc.tokensInfo[i].request_index << std::endl; + os << " Token id: " << bc.tokensInfo[i].token_id << std::endl; + } + + os << "Tokens to commit info:\n"; + for (int i = 0; i < bc.num_tokens_to_commit; i++) { + os << " Token " << i << ":\n"; + os << " token_index: " << bc.committed_tokens[i].token_index + << std::endl; + os << " request_index: " << bc.committed_tokens[i].request_index + << std::endl; + os << " token_depth: " << bc.committed_tokens[i].token_depth + << std::endl; + } + + os << "@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@" << std::endl; + return os; +} + +void TreeVerifyBatchConfig::print() const { + std::cout << *this << std::endl; +} + +void TreeVerifyBatchConfig::save_to_file(std::string const &filename) const { + std::ofstream outputFile(filename); + if (outputFile.is_open()) { + outputFile << *this << std::endl; + outputFile.close(); + } else { + std::cerr << "Error: Unable to open the batch config output file: " + << filename << std::endl; + assert(false); + } +} + +}; // namespace FlexFlow diff --git a/tests/.gitignore b/tests/.gitignore new file mode 100644 index 0000000000..f3732d54f4 --- /dev/null +++ b/tests/.gitignore @@ -0,0 +1 @@ +inference/python_test_configs/*.json diff --git a/tests/align/align_create_tensor_ff.py b/tests/align/align_create_tensor_ff.py index 2dbcb942d3..6c8774a33e 100644 --- a/tests/align/align_create_tensor_ff.py +++ b/tests/align/align_create_tensor_ff.py @@ -1,7 +1,7 @@ import os import sys import torch -import argparse +import json from flexflow.core import * from flexflow.core.flexflow_cffi import Linear, Op, Parameter from flexflow.type import AggrMode @@ -20,8 +20,14 @@ param_bias_op = {'conv2d': Conv2D, 'layernorm': LayerNorm, 'linear': Linear} -def create_single_operator_ff(): +def top_level_task(): args = parse_create_tensor_args() + configs_dict = None + if args.config_file is not None: + with open(args.config_file) as f: + configs_dict = json.load(f) + init_flexflow_runtime(configs_dict) + operator_name = args.operator OUT_DIR = os.path.join("tests", "align", "out", operator_name) @@ -669,4 +675,4 @@ def create_tensors_for_gather_ff(ffmodel): if __name__ == "__main__": - create_single_operator_ff() + top_level_task() diff --git a/tests/align/align_create_tensor_torch.py b/tests/align/align_create_tensor_torch.py index 8b835a5276..ca1be143ed 100644 --- a/tests/align/align_create_tensor_torch.py +++ b/tests/align/align_create_tensor_torch.py @@ -2,7 +2,6 @@ import sys import torch - sys.path.append("./align/") from align_utils import gen_tensor, parse_create_tensor_args, create_general_test_tensor_torch, BATCH_SIZE, INPUT_SIZE, SEQ_LENGTH diff --git a/tests/align/align_utils.py b/tests/align/align_utils.py index 34f07a4928..d53e5cbba9 100644 --- a/tests/align/align_utils.py +++ b/tests/align/align_utils.py @@ -102,7 +102,7 @@ def align_tensors(tensor_alignment_data_iter: Iterable[TensorAlignmentData]): ff_tensor = torch.load(ff_filepath).cpu() torch_tensor = torch.load(torch_filepath).cpu() print(f"Checking {tensor_alignment_data.tensor_name} alignment...") - torch.testing.assert_close(ff_tensor, torch_tensor) + torch.testing.assert_close(ff_tensor, torch_tensor, rtol=1e-2, atol=1e-4) def parse_create_tensor_args(): @@ -112,7 +112,12 @@ def parse_create_tensor_args(): parser = ArgumentParser(description='Pytorch Aligment Test Suite') parser.add_argument("-o", "--operator", dest="operator", required=False, metavar="", help="operator needs to be test") - + parser.add_argument( + "-config-file", + help="The path to a JSON file with the configs. If omitted, a sample model and configs will be used instead.", + type=str, + default=None, + ) args, unknown = parser.parse_known_args() return args diff --git a/tests/align/test_all_operators.sh b/tests/align/test_all_operators.sh index 484e121eee..3fb361f25c 100755 --- a/tests/align/test_all_operators.sh +++ b/tests/align/test_all_operators.sh @@ -4,7 +4,7 @@ eval "$(conda shell.bash hook)" rm -rf align/out function generate_ff_tensor(){ - ./build/flexflow_python tests/align/align_create_tensor_ff.py -ll:py 1 -ll:gpu 1 -ll:fsize 5000 -ll:zsize 4096 -b 16 -o "$1" + ./build/flexflow_python tests/align/align_create_tensor_ff.py -ll:gpu 1 -ll:fsize 5000 -ll:zsize 4096 -b 16 -o "$1" } function generate_torch_tensor(){ diff --git a/tests/cpp_gpu_tests.sh b/tests/cpp_gpu_tests.sh index 92d3280a1f..1e8dd4298f 100755 --- a/tests/cpp_gpu_tests.sh +++ b/tests/cpp_gpu_tests.sh @@ -13,6 +13,9 @@ BATCHSIZE=$((GPUS * 64)) FSIZE=13800 ZSIZE=12192 +GPU_AVAILABLE=$(nvidia-smi --query-gpu=name --format=csv,noheader | wc -l) +if [ $(( GPUS )) -gt $(( GPU_AVAILABLE )) ]; then echo "The test requires $GPUS GPUs, but only $GPU_AVAILABLE are available. Try reducing the number of nodes, or the number of gpus/node." ; exit; fi + remove_mnist() { rm -f train-images-idx3-ubyte.gz train-labels-idx1-ubyte.gz train-images-idx3-ubyte train-labels-idx1-ubyte } diff --git a/tests/gpt_tokenizer.cpp b/tests/gpt_tokenizer.cpp new file mode 100644 index 0000000000..eb8ea069af --- /dev/null +++ b/tests/gpt_tokenizer.cpp @@ -0,0 +1,80 @@ +/* Copyright 2023 CMU, Facebook, LANL, MIT, NVIDIA, and Stanford (alphabetical) + * + * Licensed under the Apache License, Version 2.0 (the "License"); + * you may not use this file except in compliance with the License. + * You may obtain a copy of the License at + * + * http://www.apache.org/licenses/LICENSE-2.0 + * + * Unless required by applicable law or agreed to in writing, software + * distributed under the License is distributed on an "AS IS" BASIS, + * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + * See the License for the specific language governing permissions and + * limitations under the License. + */ + +#include + +#include + +int main(int argc, char *argv[]) { + if (argc != 2 || (strcmp(argv[1], "gpt-2") && strcmp(argv[1], "opt"))) { + fprintf(stderr, "Usage: %s \n", argv[0]); + return 1; + } + tokenizer_mode mode = + strcmp(argv[1], "gpt-2") == 0 ? GPT2_TOKENIZER : OPT_TOKENIZER; + std::string vocab_file = mode == GPT2_TOKENIZER ? "./gpt2_bpe/vocab.bpe" + : "opt_bpe/gpt2-merges.txt"; + std::string merge_file = mode == GPT2_TOKENIZER ? "./gpt2_bpe/encoder.json" + : "opt_bpe/gpt2-vocab.json"; + + GPT_Tokenizer tokenizer(mode, merge_file, vocab_file); + + std::string line; + std::vector lines; + std::ifstream infile("./wikitext-103-raw/wiki.valid.raw"); + if (!infile) { + std::cout << "Error opening input file" << std::endl; + return -1; + } + std::ofstream outfile(mode == GPT2_TOKENIZER + ? "./wikitext-103-raw/wiki.valid.bpe.flexflow.gpt2" + : "./wikitext-103-raw/wiki.valid.bpe.flexflow.opt", + std::ofstream::out); + if (!outfile) { + std::cout << "Error opening output file" << std::endl; + return -1; + } + while (std::getline(infile, line)) { + lines.push_back(line); + } + + std::vector input_ids; + std::vector mask_ids; + for (auto l = lines.begin(); l != lines.end(); ++l) { + std::string stripped_line = tokenizer.strip(*l); + if (stripped_line.length() == 0) { + outfile << *l << std::endl; + } else { + tokenizer.encode( + stripped_line, stripped_line.length(), &input_ids, &mask_ids); + bool first = true; + for (std::size_t i = 0; i < input_ids.size(); ++i) { + if (mask_ids[i]) { + if (!first) { + outfile << " "; + } else { + first = false; + } + outfile << input_ids[i]; + } + } + outfile << std::endl; + std::string decoded_line = tokenizer.decode(input_ids, mask_ids); + assert(decoded_line == stripped_line); + input_ids.clear(); + mask_ids.clear(); + } + } +} diff --git a/tests/gpt_tokenizer_test.sh b/tests/gpt_tokenizer_test.sh new file mode 100755 index 0000000000..de6d018372 --- /dev/null +++ b/tests/gpt_tokenizer_test.sh @@ -0,0 +1,107 @@ +#! /usr/bin/env bash +set -x +set -e + +cleanup() { + rm -rf wikitext-103-raw-v1.zip wikitext-103-raw gpt2_bpe opt_bpe gpt_tokenizer pytokenizer.py bpe.py hf_tokenizer.py +} + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +# Clean up before test (just in case) +cleanup + +# Compile the FlexFlow C++ tokenizer stand-alone +g++ -std=c++11 -I../deps/json/include -I../include -o gpt_tokenizer gpt_tokenizer.cpp ../src/runtime/gpt_tokenizer.cc +chmod +x gpt_tokenizer + +# Download and inflate wikitext dataset +wget https://s3.amazonaws.com/research.metamind.io/wikitext/wikitext-103-raw-v1.zip +unzip wikitext-103-raw-v1.zip +rm wikitext-103-raw-v1.zip + +############################################################################################### +##################################### GPT-2 tests ############################################# +############################################################################################### + +# Download GPT-2 BPE vocab and merges files +mkdir -p gpt2_bpe +wget -O gpt2_bpe/encoder.json https://dl.fbaipublicfiles.com/fairseq/gpt2_bpe/encoder.json +wget -O gpt2_bpe/vocab.bpe https://dl.fbaipublicfiles.com/fairseq/gpt2_bpe/vocab.bpe + +# Download minGPT bpe tokenizer for comparison +wget -O bpe.py https://raw.githubusercontent.com/karpathy/minGPT/master/mingpt/bpe.py +chmod +x bpe.py + +# Run the FlexFlow C++ tokenizer (standard GPT-2) +./gpt_tokenizer gpt-2 + +# Run the minGPT tokenizer +cat << EOF > pytokenizer.py +#!/usr/bin/env python +from bpe import BPETokenizer + +tokenizer = BPETokenizer() +inp="./wikitext-103-raw/wiki.valid.raw" +outp="./wikitext-103-raw/wiki.valid.bpe.minGPT" +with open(inp, "r") as infile: + with open(outp, "w+") as outfile: + for l in infile.readlines(): + if len(l.strip()) == 0: + outfile.write(l) + else: + out = tokenizer(l.strip()).tolist()[0] + out = [str(x) for x in out] + out = " ".join(out) + outfile.write(out) + outfile.write("\n") +EOF +chmod +x pytokenizer.py +./pytokenizer.py + +# Check that the outputs match +diff ./wikitext-103-raw/wiki.valid.bpe.flexflow.gpt2 ./wikitext-103-raw/wiki.valid.bpe.minGPT + +############################################################################################### +##################################### OPT tests ############################################### +############################################################################################### + +# Download OPT vocab and merge files +mkdir -p opt_bpe +wget -O opt_bpe/gpt2-vocab.json https://raw.githubusercontent.com/facebookresearch/metaseq/main/projects/OPT/assets/gpt2-vocab.json +wget -O opt_bpe/gpt2-merges.txt https://raw.githubusercontent.com/facebookresearch/metaseq/main/projects/OPT/assets/gpt2-merges.txt + +# Run the FlexFlow C++ tokenizer (OPT) +./gpt_tokenizer opt + +# Run the Huggingface tokenizer +pip3 install transformers +cat << EOF > hf_tokenizer.py +#!/usr/bin/env python +from transformers import GPT2Tokenizer +model_id = "facebook/opt-6.7b" +tokenizer = GPT2Tokenizer.from_pretrained(model_id) +inp="./wikitext-103-raw/wiki.valid.raw" +outp="./wikitext-103-raw/wiki.valid.bpe.OPT" +with open(inp, "r") as infile: + with open(outp, "w+") as outfile: + for l in infile.readlines(): + if len(l.strip()) == 0: + outfile.write(l) + else: + input_ids = tokenizer(l.strip(), return_tensors="pt", padding=False).input_ids + out = input_ids.tolist()[0] + out = [str(x) for x in out] + out = " ".join(out) + outfile.write(out) + outfile.write("\n") +EOF +chmod +x hf_tokenizer.py +./hf_tokenizer.py + +# Check that the outputs match +diff ./wikitext-103-raw/wiki.valid.bpe.flexflow.opt ./wikitext-103-raw/wiki.valid.bpe.OPT + +# Clean up after test +cleanup diff --git a/tests/inference/cpp_inference_tests.sh b/tests/inference/cpp_inference_tests.sh new file mode 100755 index 0000000000..8beea55999 --- /dev/null +++ b/tests/inference/cpp_inference_tests.sh @@ -0,0 +1,259 @@ +#! /usr/bin/env bash +set -x +set -e + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +############################################################################################### +############################ Speculative inference tests ###################################### +############################################################################################### + +# LLAMA +../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_llama.txt -pipeline-parallelism-degree 4 +# LLAMA (half precision) +../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_llama_half.txt -pipeline-parallelism-degree 4 + +# OPT +../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-6.7b -ssm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_opt.txt -pipeline-parallelism-degree 4 +# OPT (half precision) +../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-6.7b -ssm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_opt_half.txt -pipeline-parallelism-degree 4 + +# Tensor parallelism tests +if [ "$TENSOR_PARALLELISM_TESTS" = "ON" ]; then + # LLAMA + ../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_llama_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + # LLAMA (half precision) + ../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model meta-llama/Llama-2-7b-hf -ssm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_llama_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + + # OPT + ../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-6.7b -ssm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_opt_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + # OPT (half precision) + ../../build/inference/spec_infer/spec_infer -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-6.7b -ssm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/spec_inference_opt_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 +fi + +############################################################################################### +############################ Incremental decoding tests ####################################### +############################################################################################### + +# LLAMA (small model) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M.txt -pipeline-parallelism-degree 4 + +../../build/inference/incr_decoding/incr_decoding -ll:gpu 1 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M.txt -pipeline-parallelism-degree 1 + +# LLAMA (small model, half precision) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M_half.txt -pipeline-parallelism-degree 4 + +# LLAMA (big model) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model meta-llama/Llama-2-7b-hf -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_2_7B.txt -pipeline-parallelism-degree 4 +# LLAMA (big model, half precision) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model meta-llama/Llama-2-7b-hf -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_2_7B_half.txt -pipeline-parallelism-degree 4 + +# OPT (small model) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M.txt -pipeline-parallelism-degree 4 +# OPT (small model, half precision) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M_half.txt -pipeline-parallelism-degree 4 + +# OPT (big model) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-6.7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_6B.txt -pipeline-parallelism-degree 4 +# OPT (big model, half precision) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-6.7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_6B_half.txt -pipeline-parallelism-degree 4 + +# Falcon (full precision) +../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 40000 --fusion --use-full-precision -llm-model tiiuae/falcon-7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_falcon_7B.txt -pipeline-parallelism-degree 4 +# Falcon (half precision) +# ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model tiiuae/falcon-7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_falcon_7B.txt -pipeline-parallelism-degree 4 + +# # StarCoder (full precision) +# ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model bigcode/starcoderbase-7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_starcoder_7B.txt -pipeline-parallelism-degree 4 +# # StarCoder (half precision) +# ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model bigcode/starcoderbase-7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_starcoder_7B_half.txt -pipeline-parallelism-degree 4 + +# Tensor parallelism tests +if [ "$TENSOR_PARALLELISM_TESTS" = "ON" ]; then + # LLAMA (small model) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M_tp4.txt -pipeline-parallelism-degree 1 -tensor-parallelism-degree 4 + # LLAMA (small model, half precision) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model JackFram/llama-160m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_160M_half_tp4.txt -pipeline-parallelism-degree 1 -tensor-parallelism-degree 4 + + # LLAMA (big model) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model meta-llama/Llama-2-7b-hf -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_2_7B_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + # LLAMA (big model, half precision) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model meta-llama/Llama-2-7b-hf -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_llama_2_7B_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + + # OPT (small model) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M_tp4.txt -pipeline-parallelism-degree 1 -tensor-parallelism-degree 4 + # OPT (small model, half precision) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-125m -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_125M_half_tp.txt -pipeline-parallelism-degree 1 -tensor-parallelism-degree 4 + + # OPT (big model) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion --use-full-precision -llm-model facebook/opt-6.7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_6B_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 + # OPT (big model, half precision) + ../../build/inference/incr_decoding/incr_decoding -ll:gpu 4 -ll:fsize 14000 -ll:zsize 30000 --fusion -llm-model facebook/opt-6.7b -prompt ../../inference/prompt/test.json -output-file ../../inference/output/incr_decoding_opt_6B_half_tp.txt -pipeline-parallelism-degree 2 -tensor-parallelism-degree 2 +fi + +############################################################################################### +############################### Alignment and Speed tests ##################################### +############################################################################################### + +##################################### Helper functions ####################################### +function check_partial_token_match { + local file1="$1" + local file2="$2" + local num_tokens_to_match=30 + + # Read the second line of the first file + third_line=$(sed -n '3p' "$file1") + read -r line1 <<< "$third_line" + tokens1=${line1#*: } + IFS=',' read -ra arr1 <<< "$tokens1" + + # Read the second line of the second file + third_line=$(sed -n '3p' "$file2") + read -r line2 <<< "$third_line" + tokens2=${line2#*: } + IFS=',' read -ra arr2 <<< "$tokens2" + + # Compare the first few integers in the two lists + for ((i = 0; i < num_tokens_to_match; i++)); do + if [[ "${arr1[$i]}" != "${arr2[$i]}" ]]; then + echo "The first $num_tokens_to_match tokens in files $file1 and $file2 are not identical." + exit 1 + fi + done + #echo "The first $num_tokens_to_match integers are identical." +} + +function compare_speed_spec_infer_incr_decoding { + local incrDec_file="$1" + local specInf_file="$2" + + # Read the float numbers from the first line of the files + incrDec=$(sed -n '1 s/end-to-end latency: \(.*\)/\1/p' "$incrDec_file") + specInf=$(sed -n '1 s/end-to-end latency: \(.*\)/\1/p' "$specInf_file") + + if ! command -v bc &> /dev/null; then + echo "bc is not installed. Installing..." + sudo apt-get install -y bc + fi + + # Perform the comparison + threshold=$(bc <<< "$specInf * 1.5") + if (( $(echo "$incrDec >= $threshold" | bc -l) )); then + #echo "The latency in $specInf_file is at least 1.5x smaller than the latency from $incrDec_file." + : + else + echo "Error: The latency in $specInf_file is not at least 1.5x smaller than the latency in $incrDec_file!" + exit 1 + fi +} + +function compare_decoding_steps_spec_infer_incr_decoding { + local incrDec_file="$1" + local specInf_file="$2" + + # Read the number of decoding steps from the second line of the files + second_line=$(sed -n '2p' "$incrDec_file") + read -r line <<< "$second_line" + incrDec=${line#*: } + second_line=$(sed -n '2p' "$specInf_file") + read -r line <<< "$second_line" + specInf=${line#*: } + + if ! command -v bc &> /dev/null; then + echo "bc is not installed. Installing..." + sudo apt-get install -y bc + fi + + # Perform the comparison + threshold=$(bc <<< "$specInf * 1.5") + if (( $(echo "$incrDec >= $threshold" | bc -l) )); then + #echo "The decoding steps in $specInf_file are at least 1.5x less than those in $incrDec_file." + : + else + echo "Error: The decoding steps in $specInf_file are not at least 1.5x less than those in $incrDec_file!" + exit 1 + fi +} + +############ Alignment between speculative inference and incremental decoding ################# +# Full precision +diff <(tail -n +3 "../../inference/output/incr_decoding_llama_2_7B.txt") <(tail -n +3 "../../inference/output/spec_inference_llama.txt") +diff <(tail -n +3 "../../inference/output/incr_decoding_opt_6B.txt") <(tail -n +3 "../../inference/output/spec_inference_opt.txt") +# Half precision +check_partial_token_match "../../inference/output/incr_decoding_llama_2_7B_half.txt" "../../inference/output/spec_inference_llama_half.txt" +check_partial_token_match "../../inference/output/incr_decoding_opt_6B_half.txt" "../../inference/output/spec_inference_opt_half.txt" + +# Speed test: speculative inference should be at very least 1.5x faster than incremental decoding +# Full precision +#compare_speed_spec_infer_incr_decoding "../../inference/output/incr_decoding_llama_2_7B.txt" "../../inference/output/spec_inference_llama.txt" +#compare_speed_spec_infer_incr_decoding "../../inference/output/incr_decoding_opt_6B.txt" "../../inference/output/spec_inference_opt.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_decoding_llama_2_7B.txt" "../../inference/output/spec_inference_llama.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_decoding_opt_6B.txt" "../../inference/output/spec_inference_opt.txt" +# Half precision +#compare_speed_spec_infer_incr_decoding "../../inference/output/incr_decoding_llama_2_7B_half.txt" "../../inference/output/spec_inference_llama_half.txt" +#compare_speed_spec_infer_incr_decoding "../../inference/output/incr_decoding_opt_6B_half.txt" "../../inference/output/spec_inference_opt_half.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_decoding_llama_2_7B_half.txt" "../../inference/output/spec_inference_llama_half.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_decoding_opt_6B_half.txt" "../../inference/output/spec_inference_opt_half.txt" + +############ Alignment between tensor model parallelism and pipeline parallelism only ################# +if [ "$TENSOR_PARALLELISM_TESTS" = "ON" ]; then + diff <(tail -n +3 "../../inference/output/spec_inference_llama_tp.txt") <(tail -n +3 "../../inference/output/spec_inference_llama.txt") + diff <(tail -n +3 "../../inference/output/spec_inference_opt_tp.txt") <(tail -n +3 "../../inference/output/spec_inference_opt.txt") + check_partial_token_match "../../inference/output/spec_inference_llama_half_tp.txt" "../../inference/output/spec_inference_llama_half.txt" + check_partial_token_match "../../inference/output/spec_inference_opt_half_tp.txt" "../../inference/output/spec_inference_opt_half.txt" + diff <(tail -n +3 "../../inference/output/incr_decoding_llama_160M_tp.txt") <(tail -n +3 "../../inference/output/incr_decoding_llama_160M.txt") + check_partial_token_match "../../inference/output/incr_decoding_llama_160M_half_tp.txt" "../../inference/output/incr_decoding_llama_160M_half.txt" + diff <(tail -n +3 "../../inference/output/incr_decoding_llama_2_7B_tp.txt") <(tail -n +3 "../../inference/output/incr_decoding_llama_2_7B.txt") + check_partial_token_match "../../inference/output/incr_decoding_llama_2_7B_half_tp.txt" "../../inference/output/incr_decoding_llama_2_7B_half.txt" + diff <(tail -n +3 "../../inference/output/incr_decoding_opt_125M_tp.txt") <(tail -n +3 "../../inference/output/incr_decoding_opt_125M.txt") + check_partial_token_match "../../inference/output/incr_decoding_opt_125M_half_tp.txt" "../../inference/output/incr_decoding_opt_125M_half.txt" + diff <(tail -n +3 "../../inference/output/incr_decoding_opt_6B_tp.txt") <(tail -n +3 "../../inference/output/incr_decoding_opt_6B.txt") + check_partial_token_match "../../inference/output/incr_decoding_opt_6B_half_tp.txt" "../../inference/output/incr_decoding_opt_6B_half.txt" +fi + +######################### Alignment tests with HuggingFace #################################### + +# LLAMA (small model, full precision) +python3 ./huggingface_inference.py --model-name "JackFram/llama-160m" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_160M.txt" --gpu + +# LLAMA (small model, half precision) +python3 ./huggingface_inference.py --model-name "JackFram/llama-160m" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_160M_half.txt" --gpu + +# LLAMA (big model, full precision) +python3 ./huggingface_inference.py --model-name "meta-llama/Llama-2-7b-hf" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_2_7B.txt" + +# LLAMA (big model, half precision) +python3 ./huggingface_inference.py --model-name "meta-llama/Llama-2-7b-hf" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_2_7B_half.txt" --gpu + +# OPT (small model, full precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-125m" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_125M.txt" --gpu --max-length 128 + +# OPT (small model, half precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-125m" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_125M_half.txt" --gpu --max-length 128 + +# OPT (big model, full precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-6.7b" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_6B.txt" --max-length 128 + +# OPT (big model, half precision) +# python3 ./huggingface_inference.py --model-name "facebook/opt-6.7b" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_6B_half.txt" --gpu --max-length 128 + +# Falcon (full precision) +python3 ./huggingface_inference.py --model-name "tiiuae/falcon-7b" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_falcon_7B.txt" --max-length 128 + + +diff "../../inference/output/huggingface_llama_160M.txt" <(tail -n +4 "../../inference/output/incr_decoding_llama_160M.txt") +diff <( < ../../inference/output/huggingface_llama_160M_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_decoding_llama_160M_half.txt" | tr -s '[:space:]' '\n' | head -n 20) +diff "../../inference/output/huggingface_llama_2_7B.txt" <(tail -n +4 "../../inference/output/incr_decoding_llama_2_7B.txt") +diff <( < ../../inference/output/huggingface_llama_2_7B_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_decoding_llama_2_7B_half.txt" | tr -s '[:space:]' '\n' | head -n 20) + +diff "../../inference/output/huggingface_opt_125M.txt" <(tail -n +4 "../../inference/output/incr_decoding_opt_125M.txt") +diff <( < ../../inference/output/huggingface_opt_125M_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_decoding_opt_125M_half.txt" | tr -s '[:space:]' '\n' | head -n 20) +diff "../../inference/output/huggingface_opt_6B.txt" <(tail -n +4 "../../inference/output/incr_decoding_opt_6B.txt") +# diff "../../inference/output/huggingface_opt_6B_half.txt" <(tail -n +4 "../../inference/output/incr_decoding_opt_6B_half.txt") +diff "../../inference/output/huggingface_falcon_7B.txt" <(tail -n +4 "../../inference/output/incr_decoding_falcon_7B.txt") + diff --git a/tests/inference/huggingface_inference.py b/tests/inference/huggingface_inference.py new file mode 100644 index 0000000000..6857b5cbc1 --- /dev/null +++ b/tests/inference/huggingface_inference.py @@ -0,0 +1,135 @@ +import argparse +import json +import os +import shutil +import torch +from transformers import ( + AutoModelForCausalLM, + AutoTokenizer, + AutoConfig, + LlamaTokenizer, + GenerationConfig, +) +######################### debugging helper functions ######################### +def pre_forward_hook(module, input): + assert module.name is not None and module.decoding_step is not None + name = module.name.replace("model.", "") + print( + f"Pre-forward hook activated on module: {name}, decoding step: {module.decoding_step}" + ) + print("Pre-Input: ", input[0].shape) + torch.save( + input, f"./hf_tensors/decoding_step_{module.decoding_step}_{name}.input" + ) +def post_forward_hook(module, input, output): + assert module.name is not None and module.decoding_step is not None + name = module.name.replace("model.", "") + print( + f"Post-forward Hook activated for module: {name}, decoding step: {module.decoding_step}" + ) + print("Post-Input/Output: ", input[0].shape, output[0].shape) + torch.save( + output, f"./hf_tensors/decoding_step_{module.decoding_step}_{name}.output" + ) + print("===") + module.decoding_step += 1 +############################################################################## + +def main(): + # Change working dir to folder storing this script + abspath = os.path.abspath(__file__) + dname = os.path.dirname(abspath) + os.chdir(dname) + + # Parse command line arguments + parser = argparse.ArgumentParser() + parser.add_argument("--model-name", type=str, required=True) + parser.add_argument("--max-length", type=int, default=128) + parser.add_argument("--prompt-file", type=str, required=True) + parser.add_argument("--output-file", type=str, required=True) + parser.add_argument( + "--use-full-precision", action="store_true", help="Use full precision" + ) + parser.add_argument("--do-sample", action="store_true", help="Use sampling") + parser.add_argument("--gpu", action="store_true", help="Run on GPU") + parser.add_argument( + "--inference-debugging", + action="store_true", + help="Print debugging info and save hidden states/weights to file", + ) + args = parser.parse_args() + # Check if max-length is greater than 0 + if args.max_length <= 0: + print("Error: max-length must be greater than 0.") + return + # Check if prompt-file exists + if not os.path.isfile(args.prompt_file): + print(f"Error: {args.prompt_file} does not exist.") + return + + # Read prompt-file into a list of strings + with open(args.prompt_file, "r") as f: + try: + prompt_list = json.load(f) + except json.JSONDecodeError: + print(f"Error: Unable to parse {args.prompt_file} as JSON.") + return + + # Set default tensor type depending on argument indicating the float type to use + if not args.use_full_precision: + torch.set_default_tensor_type(torch.HalfTensor) + + # Run huggingface model + cuda_availble = torch.cuda.is_available() + device = "cuda" if args.gpu and cuda_availble else "cpu" + # Get Model + model = AutoModelForCausalLM.from_pretrained(args.model_name).to(device) + # Get Tokenizer + hf_config = AutoConfig.from_pretrained(args.model_name, trust_remote_code=True) + hf_arch = getattr(hf_config, "architectures")[0] + if hf_arch == "LLaMAForCausalLM" or hf_arch == "LlamaForCausalLM": + tokenizer = LlamaTokenizer.from_pretrained(args.model_name, use_fast=True) + else: + tokenizer = AutoTokenizer.from_pretrained(args.model_name) + generation_config = GenerationConfig.from_pretrained(args.model_name) + generation_config.do_sample = args.do_sample + ################# debugging ################# + if args.inference_debugging: + # Print model and configs + print(hf_config) + print(model) + # Save weights to file + shutil.rmtree("./hf_tensors") + # Check that the output folder exists + os.makedirs("./hf_tensors", exist_ok=True) + # Save weights + for name, params in model.named_parameters(): + torch.save(params, f"./hf_tensors/{name}") + # params.detach().cpu().numpy().tofile(f"./hf_tensors/{name}") + # Register hooks to save per-op hidden states + for name, layer in dict(model.named_modules()).items(): + layer.name = name + layer.decoding_step = 0 + print(f"Adding hooks to layer {layer.name}") + layer.register_forward_pre_hook(pre_forward_hook) + layer.register_forward_hook(post_forward_hook) + ############################################### + # Generate output + with open(args.output_file, "w") as f: + for i, prompt in enumerate(prompt_list): + batch = tokenizer(prompt, return_tensors="pt", add_special_tokens=True).to( + device + ) + generated = model.generate( + batch["input_ids"], + max_length=args.max_length, + generation_config=generation_config, + ) + out = tokenizer.decode(generated[0]) + # Write output to file + out_str = out if i == (len(prompt_list) - 1) else out + "\n" + f.write(out_str) + + +if __name__ == "__main__": + main() diff --git a/tests/inference/python_inference_tests.sh b/tests/inference/python_inference_tests.sh new file mode 100755 index 0000000000..a1ee281914 --- /dev/null +++ b/tests/inference/python_inference_tests.sh @@ -0,0 +1,196 @@ +#! /usr/bin/env bash +set -x +set -e + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +# Generate test configs +rm -rf python_test_configs/*.json +python python_test_configs/generate_configs.py + +# Run all tests +# Loop through .json files in the ./python_test_configs dir +for file in ./python_test_configs/*.json; do + # Check filename prefix + if [[ $file == *"incr_dec"* ]]; then + script="../../inference/python/incr_decoding.py" + elif [[ $file == *"spec_infer"* ]]; then + script="../../inference/python/spec_infer.py" + fi + # Run script + python "$script" -config-file "$file" +done + + +############################################################################################### +############################### Alignment and Speed tests ##################################### +############################################################################################### + +##################################### Helper functions ####################################### +function check_partial_token_match { + local file1="$1" + local file2="$2" + local num_tokens_to_match=30 + + # Read the second line of the first file + third_line=$(sed -n '3p' "$file1") + read -r line1 <<< "$third_line" + tokens1=${line1#*: } + IFS=',' read -ra arr1 <<< "$tokens1" + + # Read the second line of the second file + third_line=$(sed -n '3p' "$file2") + read -r line2 <<< "$third_line" + tokens2=${line2#*: } + IFS=',' read -ra arr2 <<< "$tokens2" + + # Compare the first few integers in the two lists + for ((i = 0; i < num_tokens_to_match; i++)); do + if [[ "${arr1[$i]}" != "${arr2[$i]}" ]]; then + echo "The first $num_tokens_to_match tokens in files $file1 and $file2 are not identical." + exit 1 + fi + done + #echo "The first $num_tokens_to_match integers are identical." +} + +function compare_speed_spec_infer_incr_decoding { + local incrDec_file="$1" + local specInf_file="$2" + + # Read the float numbers from the first line of the files + incrDec=$(sed -n '1 s/end-to-end latency: \(.*\)/\1/p' "$incrDec_file") + specInf=$(sed -n '1 s/end-to-end latency: \(.*\)/\1/p' "$specInf_file") + + if ! command -v bc &> /dev/null; then + echo "bc is not installed. Installing..." + sudo apt-get install -y bc + fi + + # Perform the comparison + threshold=$(bc <<< "$specInf * 1.5") + if (( $(echo "$incrDec >= $threshold" | bc -l) )); then + #echo "The latency in $specInf_file is at least 1.5x smaller than the latency from $incrDec_file." + : + else + echo "Error: The latency in $specInf_file is not at least 1.5x smaller than the latency in $incrDec_file!" + exit 1 + fi +} + +function compare_decoding_steps_spec_infer_incr_decoding { + local incrDec_file="$1" + local specInf_file="$2" + + # Read the number of decoding steps from the second line of the files + second_line=$(sed -n '2p' "$incrDec_file") + read -r line <<< "$second_line" + incrDec=${line#*: } + second_line=$(sed -n '2p' "$specInf_file") + read -r line <<< "$second_line" + specInf=${line#*: } + + if ! command -v bc &> /dev/null; then + echo "bc is not installed. Installing..." + sudo apt-get install -y bc + fi + + # Perform the comparison + threshold=$(bc <<< "$specInf * 1.5") + if (( $(echo "$incrDec >= $threshold" | bc -l) )); then + #echo "The decoding steps in $specInf_file are at least 1.5x less than those in $incrDec_file." + : + else + echo "Error: The decoding steps in $specInf_file are not at least 1.5x less than those in $incrDec_file!" + exit 1 + fi +} + +############ Alignment between speculative inference and incremental decoding ################# +# Full precision +diff <(tail -n +3 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") <(tail -n +3 "../../inference/output/spec_infer-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") +diff <(tail -n +3 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-1_tp_4_pp.txt") <(tail -n +3 "../../inference/output/spec_infer-python-opt-6.7b-full_prec-1_tp_4_pp.txt") +# Half precision +check_partial_token_match "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" +check_partial_token_match "../../inference/output/incr_dec-python-opt-6.7b-half_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-opt-6.7b-half_prec-1_tp_4_pp.txt" + +# Speed test: speculative inference should be at very least 1.5x faster than incremental decoding +# Full precision +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_dec-python-opt-6.7b-full_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-opt-6.7b-full_prec-1_tp_4_pp.txt" +# Half precision +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" +compare_decoding_steps_spec_infer_incr_decoding "../../inference/output/incr_dec-python-opt-6.7b-half_prec-1_tp_4_pp.txt" "../../inference/output/spec_infer-python-opt-6.7b-half_prec-1_tp_4_pp.txt" + +############ Alignment between tensor model parallelism and pipeline parallelism only ################# +## Specinfer +# LLAMA +diff <(tail -n +3 "../../inference/output/spec_infer-python-llama-2-7b-hf-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/spec_infer-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/spec_infer-python-llama-2-7b-hf-half_prec-2_tp_2_pp.txt" "../../inference/output/spec_infer-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" +# OPT +diff <(tail -n +3 "../../inference/output/spec_infer-python-opt-6.7b-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/spec_infer-python-opt-6.7b-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/spec_infer-python-opt-6.7b-half_prec-2_tp_2_pp.txt" "../../inference/output/spec_infer-python-opt-6.7b-half_prec-1_tp_4_pp.txt" + +## Incremental decoding +# Small LLAMA +diff <(tail -n +3 "../../inference/output/incr_dec-python-llama-160m-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-llama-160m-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-llama-160m-half_prec-2_tp_2_pp.txt" "../../inference/output/incr_dec-python-llama-160m-half_prec-1_tp_4_pp.txt" +diff <(tail -n +3 "../../inference/output/incr_dec-python-llama-160m-full_prec-4_tp_1_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-llama-160m-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-llama-160m-half_prec-4_tp_1_pp.txt" "../../inference/output/incr_dec-python-llama-160m-half_prec-1_tp_4_pp.txt" +# Big LLAMA +diff <(tail -n +3 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-2_tp_2_pp.txt" "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" +#diff <(tail -n +3 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-4_tp_1_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") +#check_partial_token_match "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-4_tp_1_pp.txt" "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" +# Small OPT +diff <(tail -n +3 "../../inference/output/incr_dec-python-opt-125m-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-opt-125m-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-opt-125m-half_prec-2_tp_2_pp.txt" "../../inference/output/incr_dec-python-opt-125m-half_prec-1_tp_4_pp.txt" +diff <(tail -n +3 "../../inference/output/incr_dec-python-opt-125m-full_prec-4_tp_1_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-opt-125m-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-opt-125m-half_prec-4_tp_1_pp.txt" "../../inference/output/incr_dec-python-opt-125m-half_prec-1_tp_4_pp.txt" +# Big OPT +diff <(tail -n +3 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-2_tp_2_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-1_tp_4_pp.txt") +check_partial_token_match "../../inference/output/incr_dec-python-opt-6.7b-half_prec-2_tp_2_pp.txt" "../../inference/output/incr_dec-python-opt-6.7b-half_prec-1_tp_4_pp.txt" +#diff <(tail -n +3 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-4_tp_1_pp.txt") <(tail -n +3 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-1_tp_4_pp.txt") +#check_partial_token_match "../../inference/output/incr_dec-python-opt-6.7b-half_prec-4_tp_1_pp.txt" "../../inference/output/incr_dec-python-opt-6.7b-half_prec-1_tp_4_pp.txt" + + +######################### Alignment tests with HuggingFace #################################### + +# LLAMA (small model, full precision) +python3 ./huggingface_inference.py --model-name "JackFram/llama-160m" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_160M.txt" --gpu + +# LLAMA (small model, half precision) +python3 ./huggingface_inference.py --model-name "JackFram/llama-160m" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_160M_half.txt" --gpu + +# LLAMA (big model, full precision) +python3 ./huggingface_inference.py --model-name "meta-llama/Llama-2-7b-hf" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_7B.txt" + +# LLAMA (big model, half precision) +python3 ./huggingface_inference.py --model-name "meta-llama/Llama-2-7b-hf" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_llama_7B_half.txt" --gpu + +# OPT (small model, full precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-125m" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_125M.txt" --gpu --max-length 128 + +# OPT (small model, half precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-125m" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_125M_half.txt" --gpu --max-length 128 + +# OPT (big model, full precision) +python3 ./huggingface_inference.py --model-name "facebook/opt-6.7b" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_6B.txt" --max-length 128 + +# OPT (big model, half precision) +#python3 ./huggingface_inference.py --model-name "facebook/opt-6.7b" --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_opt_6B_half.txt" --gpu --max-length 128 + +# Falcon (full precision) +python3 ./huggingface_inference.py --model-name "tiiuae/falcon-7b" --use-full-precision --prompt-file "../../inference/prompt/test.json" --output-file "../../inference/output/huggingface_falcon_7B.txt" --max-length 128 + +diff "../../inference/output/huggingface_llama_160M.txt" <(tail -n +4 "../../inference/output/incr_dec-python-llama-160m-full_prec-1_tp_4_pp.txt") +diff <( < ../../inference/output/huggingface_llama_160M_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_dec-python-llama-160m-half_prec-1_tp_4_pp.txt" | tr -s '[:space:]' '\n' | head -n 20) +diff "../../inference/output/huggingface_llama_7B.txt" <(tail -n +4 "../../inference/output/incr_dec-python-llama-2-7b-hf-full_prec-1_tp_4_pp.txt") +diff <( < ../../inference/output/huggingface_llama_7B_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_dec-python-llama-2-7b-hf-half_prec-1_tp_4_pp.txt" | tr -s '[:space:]' '\n' | head -n 20) + +diff "../../inference/output/huggingface_opt_125M.txt" <(tail -n +4 "../../inference/output/incr_dec-python-opt-125m-full_prec-1_tp_4_pp.txt") +diff <( < ../../inference/output/huggingface_opt_125M_half.txt tr -s '[:space:]' '\n' | head -n 20) <(tail -n +4 "../../inference/output/incr_dec-python-opt-125m-half_prec-1_tp_4_pp.txt" | tr -s '[:space:]' '\n' | head -n 20) +diff "../../inference/output/huggingface_opt_6B.txt" <(tail -n +4 "../../inference/output/incr_dec-python-opt-6.7b-full_prec-1_tp_4_pp.txt") +#diff "../../inference/output/huggingface_opt_6B_half.txt" <(tail -n +4 "../../inference/output/incr_dec-python-opt-6.7b-half_prec-1_tp_4_pp.txt") +diff "../../inference/output/huggingface_falcon_7B.txt" <(tail -n +4 "../../inference/output/incr_dec-python-falcon-7b-full_prec-1_tp_4_pp.txt") diff --git a/tests/inference/python_test_configs/generate_configs.py b/tests/inference/python_test_configs/generate_configs.py new file mode 100644 index 0000000000..41703cf431 --- /dev/null +++ b/tests/inference/python_test_configs/generate_configs.py @@ -0,0 +1,146 @@ +#!/usr/bin/env python +import os, json + +# Base configs dictionaries +ff_init_configs = { + # required parameters + "num_gpus": 4, + "memory_per_gpu": 14000, + "zero_copy_memory_per_node": 40000, + # optional parameters + "num_cpus": 4, + "legion_utility_processors": 4, + "data_parallelism_degree": 1, + "tensor_parallelism_degree": 1, + "pipeline_parallelism_degree": 4, + "offload": False, + "offload_reserve_space_size": 1024**2, + "use_4bit_quantization": False, + "use_8bit_quantization": False, + "profiling": False, + "benchmarking": False, + "inference_debugging": False, + "fusion": True, +} +llm_configs = { + # required parameters + "llm_model": "tiiuae/falcon-7b", + # optional parameters + "cache_path": os.environ.get("FF_CACHE_PATH", ""), + "refresh_cache": False, + "full_precision": True, + "prompt": "", + "output_file": "", +} +ssm_configs = { + "ssms": [ + { + # required ssm parameter + "ssm_model": "JackFram/llama-160m", + # optional ssm parameters + "cache_path": "", + "refresh_cache": False, + "full_precision": False, + }, + ] +} +# Merge dictionaries +ff_init_configs.update(llm_configs) + +# Test parameters to fill in +llama_models = ["meta-llama/Llama-2-7b-hf", "JackFram/llama-160m"] +opt_models = ["facebook/opt-6.7b", "facebook/opt-125m"] +falcon_models = [ + "tiiuae/falcon-7b", +] +mpt_models = [ + "mosaicml/mpt-7b", +] +# starcoder_models = ["bigcode/starcoderbase-7b",] +parallelism_settings = [(1, 4), (2, 2), (4, 1)] + +# The paths below should be with respect to the folder from which the tests are launched (FF_HOME/tests/inference) +prompt_file = "../../inference/prompt/test.json" +output_folder = "../../inference/output" + +# Change working dir to folder storing this script +abspath = os.path.abspath(__file__) +dname = os.path.dirname(abspath) +os.chdir(dname) + + +# Generate incremental decoding configs +all_models = llama_models + opt_models + falcon_models + mpt_models +for model_name in all_models: + for full_precision in (True, False): + for parallelism_degrees in parallelism_settings: + tp, pp = parallelism_degrees + + # Tensor parallelism not supported by small Falcon model atm + if tp > 1 and ("falcon" in model_name): + continue + # skip tp=4 for big models + if tp > 2 and ("7b" in model_name or "6.7b" in model_name): + continue + + # Run Falcon only in full precision, Starcoder only in half precision + if (not full_precision and "falcon" in model_name) or (full_precision and "starcoder" in model_name): + continue + + _, after_slash = model_name.rsplit("/", maxsplit=1) + filename = ( + "incr_dec-" + + "python-" + + after_slash.lower() + + ("-full_prec-" if full_precision else "-half_prec-") + + f"{tp}_tp_{pp}_pp" + ) + test_configs_file = "./" + filename + ".json" + output_file = os.path.join(output_folder, filename + ".txt") + + ff_init_configs["tensor_parallelism_degree"] = tp + ff_init_configs["pipeline_parallelism_degree"] = pp + ff_init_configs["llm_model"] = model_name + ff_init_configs["full_precision"] = full_precision + ff_init_configs["output_file"] = output_file + ff_init_configs["prompt"] = prompt_file + + with open(test_configs_file, "w+") as outfile: + json.dump(ff_init_configs, outfile, indent=4) + +# Generate speculative inference configs +model_pairs = [llama_models, opt_models] +for model_pair in model_pairs: + for full_precision in (True, False): + for parallelism_degrees in parallelism_settings: + big_model, small_model = model_pair + tp, pp = parallelism_degrees + + # Skip fully tp tests + if tp > 2: + continue + + _, after_slash = big_model.rsplit("/", maxsplit=1) + filename = ( + "spec_infer-" + + "python-" + + after_slash.lower() + + ("-full_prec-" if full_precision else "-half_prec-") + + f"{tp}_tp_{pp}_pp" + ) + test_configs_file = "./" + filename + ".json" + output_file = os.path.join(output_folder, filename + ".txt") + + ff_init_configs["tensor_parallelism_degree"] = tp + ff_init_configs["pipeline_parallelism_degree"] = pp + ff_init_configs["llm_model"] = big_model + ff_init_configs["full_precision"] = full_precision + ff_init_configs["output_file"] = output_file + ff_init_configs["prompt"] = prompt_file + + ssm_configs["ssms"][0]["ssm_model"] = small_model + ssm_configs["ssms"][0]["full_precision"] = full_precision + ff_init_configs.update(ssm_configs) + + with open(test_configs_file, "w+") as outfile: + json.dump(ff_init_configs, outfile, indent=4) diff --git a/tests/inference_tests.sh b/tests/inference_tests.sh new file mode 100755 index 0000000000..895b74c798 --- /dev/null +++ b/tests/inference_tests.sh @@ -0,0 +1,51 @@ +#! /usr/bin/env bash +set -x +set -e + +cleanup() { + rm -rf ../inference/prompt ../inference/output +} + +# Cd into directory holding this script +cd "${BASH_SOURCE[0]%/*}" + +# Enable Python tests (on by default) +PYTHON_INFERENCE_TESTS=${PYTHON_INFERENCE_TESTS:-ON} +# Enable C++ tests, (off by default) +CPP_INFERENCE_TESTS=${CPP_INFERENCE_TESTS:-OFF} +# Enable model parallelism tests in C++, if desired +TENSOR_PARALLELISM_TESTS=${TENSOR_PARALLELISM_TESTS:-OFF} + +# Token to access private huggingface models (e.g. LLAMA-2) +HUGGINGFACE_TOKEN=${HUGGINGFACE_TOKEN:-none} +if [[ "$HUGGINGFACE_TOKEN" != "none" ]]; then + huggingface-cli login --token "$HUGGINGFACE_TOKEN" +fi + +# Clean up before test (just in case) +cleanup + +# Make sure supported version of protobuf is installed +pip3 install protobuf==3.20.3 + +# Create test prompt file +mkdir -p ../inference/prompt +echo '["Three tips for staying healthy are: "]' > ../inference/prompt/test.json + +# Create output folder +mkdir -p ../inference/output + +# Enable backtrace in case we run into a segfault or assertion failure +export LEGION_BACKTRACE=1 + +if [[ "$PYTHON_INFERENCE_TESTS" == "ON" ]]; then + echo "Running Python inference tests..." + ./inference/python_inference_tests.sh +fi +if [[ "$CPP_INFERENCE_TESTS" == "ON" ]]; then + # Manually download the weights in both half and full precision + python3 ../inference/utils/download_hf_model.py "meta-llama/Llama-2-7b-hf" "JackFram/llama-160m" "facebook/opt-6.7b" "facebook/opt-125m" "tiiuae/falcon-7b" + echo "Running C++ inference tests..." + ./inference/cpp_inference_tests.sh +fi + diff --git a/tests/multi_gpu_tests.sh b/tests/multi_gpu_tests.sh deleted file mode 100755 index 0321068641..0000000000 --- a/tests/multi_gpu_tests.sh +++ /dev/null @@ -1,82 +0,0 @@ -#! /usr/bin/env bash -set -x -set -e - -# Default to single-node, single GPU -GPUS=${1:-1} # number of GPUS per node -NUM_NODES=${2:-1} # number of nodes -BATCHSIZE=$(( NUM_NODES * GPUS * 64)) -FSIZE=13800 -ZSIZE=12192 - -FF_HOME="$(realpath "${BASH_SOURCE[0]%/*}/..")" -export FF_HOME -# Edit the folder below if you did not build FlexFlow in $FF_HOME/build -BUILD_FOLDER="${FF_HOME}/build" -export BUILD_FOLDER - -if [[ $NUM_NODES -gt 1 ]]; then - export GPUS - export NUM_NODES - EXE="$FF_HOME"/tests/multinode_helpers/mpi_wrapper1.sh -else - if [[ -f "$BUILD_FOLDER/flexflow_python" ]]; then - EXE="$BUILD_FOLDER"/flexflow_python - else - EXE="flexflow_python" - fi -fi - -echo "Running GPU tests with $NUM_NODES node(s) and $GPUS gpu(s)/node" -GPU_AVAILABLE=$(nvidia-smi --query-gpu=name --format=csv,noheader | wc -l) -GPU_REQUESTED=$(( GPUS * NUM_NODES)) -if [ $GPU_REQUESTED -gt $(( GPU_AVAILABLE )) ]; then echo "The test requires $GPU_REQUESTED GPUs, but only $GPU_AVAILABLE are available. Try reducing the number of nodes, or the number of gpus/node." ; exit; fi - -#Sequential model tests -$EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -#$EXE "$FF_HOME"/examples/python/keras/seq_reuters_mlp.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/seq_cifar10_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp_net2net.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn_net2net.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn_nested.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel - -#Keras other -$EXE "$FF_HOME"/examples/python/keras/callback.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/unary.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/reshape.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/elementwise_mul_broadcast.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/reduce_sum.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/identity_loss.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/elementwise_max_min.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/rsqrt.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/gather.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/regularizer.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel - -#Functional API -$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_concat.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_concat2.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_mnist_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_mnist_cnn_concat.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_nested.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_alexnet.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_net2net.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_net2net.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel - -#Python -$EXE "$FF_HOME"/examples/python/native/print_layers.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 5 -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/split.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/alexnet.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 40 --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/mnist_mlp.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 5 -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/mnist_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 5 -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/cifar10_cnn.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 40 --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/cifar10_cnn_attach.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 5 --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/mnist_mlp_attach.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 5 --only-data-parallel - -#Possible crash -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat_model.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat_seq_model.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel -$EXE "$FF_HOME"/examples/python/native/cifar10_cnn_concat.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" --epochs 40 --only-data-parallel diff --git a/tests/multinode_helpers/mpi_wrapper1.sh b/tests/multinode_helpers/mpi_wrapper1.sh index 2e493f63e7..076fd2d66c 100755 --- a/tests/multinode_helpers/mpi_wrapper1.sh +++ b/tests/multinode_helpers/mpi_wrapper1.sh @@ -3,11 +3,10 @@ set -x set -e if [ -z "$FF_HOME" ]; then echo "FF_HOME variable is not defined, aborting tests"; exit; fi -if [ -z "$BUILD_FOLDER" ]; then echo "BUILD_FOLDER variable is not defined, aborting tests"; exit; fi if [ -z "$NUM_NODES" ]; then echo "NUM_NODES variable is not defined, aborting tests"; exit; fi if [ -z "$GPUS" ]; then echo "GPUS variable is not defined, aborting tests"; exit; fi # We need to wrap the instruction below in its own script because MPI throws an error if we try # to run "mpirun" more than once in the same script. Hence, we cannot simply call "mpirun" in the -# multi_gpu_tests.sh script +# training_tests.sh script mpirun -np "$NUM_NODES" "$FF_HOME"/tests/multinode_helpers/mpi_wrapper2.sh "$@" diff --git a/tests/multinode_helpers/mpi_wrapper2.sh b/tests/multinode_helpers/mpi_wrapper2.sh index a4e871d700..57812884dc 100755 --- a/tests/multinode_helpers/mpi_wrapper2.sh +++ b/tests/multinode_helpers/mpi_wrapper2.sh @@ -2,8 +2,6 @@ set -x set -e -if [ -z "$FF_HOME" ]; then echo "FF_HOME variable is not defined, aborting tests"; exit; fi -if [ -z "$BUILD_FOLDER" ]; then echo "BUILD_FOLDER variable is not defined, aborting tests"; exit; fi if [ -z "$NUM_NODES" ]; then echo "NUM_NODES variable is not defined, aborting tests"; exit; fi if [ -z "$GPUS" ]; then echo "GPUS variable is not defined, aborting tests"; exit; fi @@ -13,11 +11,4 @@ if [ -z "$GPUS" ]; then echo "GPUS variable is not defined, aborting tests"; exi CUDA_VISIBLE_DEVICES=$(seq -s, $((OMPI_COMM_WORLD_RANK * GPUS )) $(( OMPI_COMM_WORLD_RANK * GPUS +1 )) ) export CUDA_VISIBLE_DEVICES -if [[ -f "$BUILD_FOLDER/flexflow_python" ]]; then - EXE="$BUILD_FOLDER"/flexflow_python -else - EXE="flexflow_python" -fi - -$EXE "$@" - +python "$@" diff --git a/tests/python_interface_test.sh b/tests/python_interface_test.sh index 6c452bd10f..5ce4d9803b 100755 --- a/tests/python_interface_test.sh +++ b/tests/python_interface_test.sh @@ -8,12 +8,19 @@ check_python_interface() { BATCHSIZE=$((GPUS * 64)) FSIZE=14048 ZSIZE=12192 + ONLY_DATA_PARALLEL=true interpreter=${1:-python} installation_status=${2:-"before-installation"} + + # Generate configs JSON files + test_params=$(jq -n --arg num_gpus "$GPUS" --arg memory_per_gpu "$FSIZE" --arg zero_copy_memory_per_node "$ZSIZE" --arg batch_size "$BATCHSIZE" --arg only_data_parallel "$ONLY_DATA_PARALLEL" '{"num_gpus":$num_gpus,"memory_per_gpu":$memory_per_gpu,"zero_copy_memory_per_node":$zero_copy_memory_per_node,"batch_size":$batch_size,"only_data_parallel":$only_data_parallel}') + mkdir -p /tmp/flexflow/training_tests + echo "$test_params" > /tmp/flexflow/training_tests/test_params.json + if [[ "$interpreter" == "python" ]]; then EXE="python" echo "Running a single-GPU Python test to check the Python interface (native python interpreter)" - $EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel + $EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -config-file /tmp/flexflow/training_tests/test_params.json elif [[ "$interpreter" == "flexflow_python" ]]; then if [[ "$installation_status" == "before-installation" ]]; then EXE="$BUILD_FOLDER"/flexflow_python @@ -21,7 +28,7 @@ check_python_interface() { EXE="flexflow_python" fi echo "Running a single-GPU Python test to check the Python interface (flexflow_python interpreter)" - $EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -ll:py 1 -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel + $EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -ll:gpu "$GPUS" -ll:fsize "$FSIZE" -ll:zsize "$ZSIZE" -b ${BATCHSIZE} --only-data-parallel else echo "Invalid Python interpreter" exit 1 @@ -38,10 +45,10 @@ export BUILD_FOLDER installation_status=${1:-"before-installation"} echo "Running Python interface tests (installation status: ${installation_status})" if [[ "$installation_status" == "before-installation" ]]; then - # Import flexflow.core module in Python + # Check availability of flexflow modules in Python export PYTHONPATH="${FF_HOME}/python:${BUILD_FOLDER}/deps/legion/bindings/python:${PYTHONPATH}" export LD_LIBRARY_PATH="${BUILD_FOLDER}:${LD_LIBRARY_PATH}" - python -c "import flexflow.core; exit()" + python -c "import flexflow.core; import flexflow.serve as ff; exit()" unset PYTHONPATH unset LD_LIBRARY_PATH # Run a single-gpu test using the flexflow_python interpreter @@ -53,8 +60,8 @@ if [[ "$installation_status" == "before-installation" ]]; then unset PYTHONPATH unset LD_LIBRARY_PATH elif [[ "$installation_status" == "after-installation" ]]; then - # Import flexflow.core module in Python - python -c "import flexflow.core; exit()" + # Check availability of flexflow modules in Python + python -c "import flexflow.core; import flexflow.serve as ff; exit()" # Run a single-gpu test using the flexflow_python interpreter check_python_interface flexflow_python after-installation # Run a single-gpu test using the native python interpreter diff --git a/tests/training_tests.sh b/tests/training_tests.sh new file mode 100755 index 0000000000..a6cab7d117 --- /dev/null +++ b/tests/training_tests.sh @@ -0,0 +1,93 @@ +#! /usr/bin/env bash +set -x +set -e + +# Enable backtrace in case we run into a segfault or assertion failure +export LEGION_BACKTRACE=1 + +# Default to single-node, single GPU +GPUS=${1:-1} # number of GPUS per node +NUM_NODES=${2:-1} # number of nodes +BATCHSIZE=$(( NUM_NODES * GPUS * 64)) +FSIZE=13800 +ZSIZE=12192 +ONLY_DATA_PARALLEL=true + +FF_HOME="$(realpath "${BASH_SOURCE[0]%/*}/..")" +export FF_HOME + +if [[ $NUM_NODES -gt 1 ]]; then + export GPUS + export NUM_NODES + EXE="$FF_HOME"/tests/multinode_helpers/mpi_wrapper1.sh +else + EXE="python" +fi + +# Check that number of GPUs requested is available +echo "Running GPU tests with $NUM_NODES node(s) and $GPUS gpu(s)/node" +GPU_AVAILABLE=$(nvidia-smi --query-gpu=name --format=csv,noheader | wc -l) +GPU_REQUESTED=$(( GPUS * NUM_NODES)) +if [ $GPU_REQUESTED -gt $(( GPU_AVAILABLE )) ]; then echo "The test requires $GPU_REQUESTED GPUs, but only $GPU_AVAILABLE are available. Try reducing the number of nodes, or the number of gpus/node." ; exit; fi + +# Generate configs JSON files +test_params=$(jq -n --arg num_gpus "$GPUS" --arg memory_per_gpu "$FSIZE" --arg zero_copy_memory_per_node "$ZSIZE" --arg batch_size "$BATCHSIZE" --arg only_data_parallel "$ONLY_DATA_PARALLEL" '{"num_gpus":$num_gpus,"memory_per_gpu":$memory_per_gpu,"zero_copy_memory_per_node":$zero_copy_memory_per_node,"batch_size":$batch_size,"only_data_parallel":$only_data_parallel}') +test_params_5_epochs=$(echo "$test_params" | jq '. + {"epochs": 5}') +test_params_40_epochs=$(echo "$test_params" | jq '. + {"epochs": 40}') +test_params_5_epochs_no_batch_size=$(echo "$test_params_5_epochs" | jq 'del(.batch_size)') +test_params_40_epochs_no_batch_size=$(echo "$test_params_40_epochs" | jq 'del(.batch_size)') +mkdir -p /tmp/flexflow/training_tests +echo "$test_params" > /tmp/flexflow/training_tests/test_params.json +echo "$test_params_5_epochs" > /tmp/flexflow/training_tests/test_params_5_epochs.json +echo "$test_params_5_epochs_no_batch_size" > /tmp/flexflow/training_tests/test_params_5_epochs_no_batch_size.json +echo "$test_params_40_epochs_no_batch_size" > /tmp/flexflow/training_tests/test_params_40_epochs_no_batch_size.json + +#Sequential model tests +$EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn.py -config-file /tmp/flexflow/training_tests/test_params.json +#$EXE "$FF_HOME"/examples/python/keras/seq_reuters_mlp.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/seq_cifar10_cnn.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/seq_mnist_mlp_net2net.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn_net2net.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/seq_mnist_cnn_nested.py -config-file /tmp/flexflow/training_tests/test_params.json + +#Keras other +$EXE "$FF_HOME"/examples/python/keras/callback.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/unary.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/reshape.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/elementwise_mul_broadcast.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/reduce_sum.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/identity_loss.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/elementwise_max_min.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/rsqrt.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/gather.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/regularizer.py -config-file /tmp/flexflow/training_tests/test_params.json + +#Functional API +$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_concat.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_concat2.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_mnist_cnn.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_mnist_cnn_concat.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_nested.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_alexnet.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_mnist_mlp_net2net.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_net2net.py -config-file /tmp/flexflow/training_tests/test_params.json + +#Python +$EXE "$FF_HOME"/examples/python/native/print_layers.py -config-file /tmp/flexflow/training_tests/test_params_5_epochs.json +$EXE "$FF_HOME"/examples/python/native/split.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/native/alexnet.py -config-file /tmp/flexflow/training_tests/test_params_40_epochs_no_batch_size.json +$EXE "$FF_HOME"/examples/python/native/mnist_mlp.py -config-file /tmp/flexflow/training_tests/test_params_5_epochs.json +$EXE "$FF_HOME"/examples/python/native/mnist_cnn.py -config-file /tmp/flexflow/training_tests/test_params_5_epochs.json +$EXE "$FF_HOME"/examples/python/native/cifar10_cnn.py -config-file /tmp/flexflow/training_tests/test_params_40_epochs_no_batch_size.json +$EXE "$FF_HOME"/examples/python/native/cifar10_cnn_attach.py -config-file /tmp/flexflow/training_tests/test_params_5_epochs_no_batch_size.json +$EXE "$FF_HOME"/examples/python/native/mnist_mlp_attach.py -config-file /tmp/flexflow/training_tests/test_params_5_epochs_no_batch_size.json + +#Possible crash +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat_model.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/keras/func_cifar10_cnn_concat_seq_model.py -config-file /tmp/flexflow/training_tests/test_params.json +$EXE "$FF_HOME"/examples/python/native/cifar10_cnn_concat.py -config-file /tmp/flexflow/training_tests/test_params_40_epochs_no_batch_size.json + diff --git a/triton/src/model.cc b/triton/src/model.cc index a61b207bdd..6d5da30bea 100644 --- a/triton/src/model.cc +++ b/triton/src/model.cc @@ -22,20 +22,22 @@ using namespace Legion; -namespace triton { namespace backend { namespace legion { - -TRITONSERVER_Error* -LegionModelState::Create( - TRITONBACKEND_Model* triton_model, const std::string& name, - uint64_t version, LegionTritonRuntime* runtime, LegionModelState** state) -{ +namespace triton { +namespace backend { +namespace legion { + +TRITONSERVER_Error *LegionModelState::Create(TRITONBACKEND_Model *triton_model, + std::string const &name, + uint64_t version, + LegionTritonRuntime *runtime, + LegionModelState **state) { std::unique_ptr lstate; try { lstate.reset(new LegionModelState(triton_model, runtime, name, version)); - } - catch (const BackendModelException& ex) { + } catch (BackendModelException const &ex) { RETURN_ERROR_IF_TRUE( - ex.err_ == nullptr, TRITONSERVER_ERROR_INTERNAL, + ex.err_ == nullptr, + TRITONSERVER_ERROR_INTERNAL, std::string("unexpected nullptr in BackendModelException")); RETURN_IF_ERROR(ex.err_); } @@ -45,15 +47,15 @@ LegionModelState::Create( // Auto-complete the configuration if requested... bool auto_complete_config = false; - RETURN_IF_ERROR(TRITONBACKEND_ModelAutoCompleteConfig( - triton_model, &auto_complete_config)); + RETURN_IF_ERROR(TRITONBACKEND_ModelAutoCompleteConfig(triton_model, + &auto_complete_config)); if (auto_complete_config) { RETURN_IF_ERROR(lstate->AutoCompleteConfig()); triton::common::TritonJson::WriteBuffer json_buffer; lstate->ModelConfig().Write(&json_buffer); - TRITONSERVER_Message* message; + TRITONSERVER_Message *message; RETURN_IF_ERROR(TRITONSERVER_MessageNewFromSerializedJson( &message, json_buffer.Base(), json_buffer.Size())); RETURN_IF_ERROR(TRITONBACKEND_ModelSetConfig( @@ -62,21 +64,21 @@ LegionModelState::Create( RETURN_IF_ERROR(lstate->ValidateModelConfig()); *state = lstate.release(); runtime->RecordModel(*state); - return nullptr; // success + return nullptr; // success } -LegionModelState::~LegionModelState(void) -{ +LegionModelState::~LegionModelState(void) { FreeLayers(); - for (auto& input : inputs_) delete input.second; - if (strategy_) + for (auto &input : inputs_) { + delete input.second; + } + if (strategy_) { delete strategy_; + } runtime_->RemoveModel(this); } -TRITONSERVER_Error* -LegionModelState::LoadModel() -{ +TRITONSERVER_Error *LegionModelState::LoadModel() { // TODO: load files based on the default / cc file name that may be set // in model config auto model_path = JoinPath({RepositoryPath(), std::to_string(Version())}); @@ -87,12 +89,16 @@ LegionModelState::LoadModel() // load the ONNX model description as a list of layers // with tensor dependences between then and put them in layers_ RETURN_IF_ERROR(OnnxParser::LoadModel( - [this]( - Realm::Processor::Kind kind) -> const std::vector& { + [this](Realm::Processor::Kind kind) + -> std::vector const & { return runtime_->FindLocalProcessors(kind); }, - this, strategy_, JoinPath({model_path, "model.onnx"}), &inputs_, - &outputs_, &layers_)); + this, + strategy_, + JoinPath({model_path, "model.onnx"}), + &inputs_, + &outputs_, + &layers_)); RETURN_IF_ERROR(SetOutputInfos()); // Should have the same number of layers in both cases @@ -107,18 +113,14 @@ LegionModelState::LoadModel() return nullptr; } -unsigned -LegionModelState::ReserveInstance(void) -{ +unsigned LegionModelState::ReserveInstance(void) { AutoLock lock(lock_); unsigned result = instances_.size(); instances_.resize(result + 1, nullptr); return result; } -void -LegionModelState::RecordInstance(LegionModelInstance* instance) -{ +void LegionModelState::RecordInstance(LegionModelInstance *instance) { assert(instance->model_state_ == this); AutoLock lock(lock_, false /*exclusive*/); assert(instance->index_ < instances_.size()); @@ -126,27 +128,30 @@ LegionModelState::RecordInstance(LegionModelInstance* instance) instances_[instance->index_] = instance; } -void -LegionModelState::initialize( - LegionModelInstance* instance, const unsigned instance_index, - Runtime* runtime, Context ctx, MapperID mapper) -{ +void LegionModelState::initialize(LegionModelInstance *instance, + unsigned const instance_index, + Runtime *runtime, + Context ctx, + MapperID mapper) { // First create logical regions for all the input tensors - for (auto& input : inputs_) instance->create_tensor_region(input.second); + for (auto &input : inputs_) { + instance->create_tensor_region(input.second); + } - for (auto layer : layers_) + for (auto layer : layers_) { layer->initialize(instance, instance_index, runtime, ctx, mapper); + } } -void -LegionModelState::forward( - LegionModelInstance* instance, const unsigned instance_index, - Runtime* runtime, Context ctx, MapperID mapper, - const std::vector& inputs, - const std::vector& outputs, - std::vector& compute_input_end_ns, - std::vector& compute_output_start_ns) -{ +void LegionModelState::forward(LegionModelInstance *instance, + unsigned const instance_index, + Runtime *runtime, + Context ctx, + MapperID mapper, + std::vector const &inputs, + std::vector const &outputs, + std::vector &compute_input_end_ns, + std::vector &compute_output_start_ns) { assert(inputs.size() == inputs_.size()); assert(outputs.size() == outputs_.size()); // Attach the external memory allocations to the logical regions for the @@ -154,34 +159,40 @@ LegionModelState::forward( const std::vector fields(1, FID_DATA); std::vector input_regions(inputs.size()); for (unsigned idx = 0; idx < inputs.size(); idx++) { - const InputTensor& input = inputs[idx]; + InputTensor const &input = inputs[idx]; assert(input.buffers_.size() == 1); assert(input.buffer_locations_.size() == 1); assert(input.buffer_memories_.size() == 1); assert(input.strides_.size() == inputs_[idx].second->bounds.size()); LogicalRegion region = inputs_[idx].second->region[instance_index]; - AttachLauncher launcher( - LEGION_EXTERNAL_INSTANCE, region, region, false /*restricted*/, - false /*mapped*/); - launcher.attach_array_soa( - const_cast(input.buffers_[0]), false /*not column major*/, - fields, input.buffer_memories_[0]); + AttachLauncher launcher(LEGION_EXTERNAL_INSTANCE, + region, + region, + false /*restricted*/, + false /*mapped*/); + launcher.attach_array_soa(const_cast(input.buffers_[0]), + false /*not column major*/, + fields, + input.buffer_memories_[0]); input_regions[idx] = runtime->attach_external_resource(ctx, launcher); } std::vector output_regions(outputs.size()); for (unsigned idx = 0; idx < outputs.size(); idx++) { - const OutputTensor& output = outputs[idx]; + OutputTensor const &output = outputs[idx]; assert(output.buffers_.size() == 1); assert(output.buffer_locations_.size() == 1); assert(output.buffer_memories_.size() == 1); assert(output.strides_.size() == outputs_[idx].second->bounds.size()); LogicalRegion region = outputs_[idx].second->region[instance_index]; - AttachLauncher launcher( - LEGION_EXTERNAL_INSTANCE, region, region, false /*restricted*/, - false /*mapped*/); - launcher.attach_array_soa( - output.buffers_[0], false /*not column major*/, fields, - output.buffer_memories_[0]); + AttachLauncher launcher(LEGION_EXTERNAL_INSTANCE, + region, + region, + false /*restricted*/, + false /*mapped*/); + launcher.attach_array_soa(output.buffers_[0], + false /*not column major*/, + fields, + output.buffer_memories_[0]); output_regions[idx] = runtime->attach_external_resource(ctx, launcher); } // Execution fence for timing operation @@ -191,45 +202,50 @@ LegionModelState::forward( // We can trace the execution of this model since it should be the same runtime->begin_trace(ctx, 0 /*only ever have one trace*/); - for (auto layer : layers_) + for (auto layer : layers_) { layer->forward(instance, instance_index, runtime, ctx, mapper); + } runtime->end_trace(ctx, 0 /*only ever have one trace*/); // Execution fence for timing operation runtime->issue_execution_fence(ctx); Future stop = runtime->issue_timing_measurement(ctx, timing_launcher); // Detach the external memory allocations - for (unsigned idx = 0; idx < input_regions.size(); idx++) + for (unsigned idx = 0; idx < input_regions.size(); idx++) { runtime->detach_external_resource(ctx, input_regions[idx], false /*flush*/); - for (unsigned idx = 0; idx < output_regions.size(); idx++) + } + for (unsigned idx = 0; idx < output_regions.size(); idx++) { runtime->detach_external_resource(ctx, output_regions[idx], true /*flush*/); + } const uint64_t start_time = start.get_result(); - for (unsigned idx = 0; idx < compute_input_end_ns.size(); idx++) + for (unsigned idx = 0; idx < compute_input_end_ns.size(); idx++) { compute_input_end_ns[idx] = start_time; + } const uint64_t stop_time = stop.get_result(); - for (unsigned idx = 0; idx < compute_output_start_ns.size(); idx++) + for (unsigned idx = 0; idx < compute_output_start_ns.size(); idx++) { compute_output_start_ns[idx] = stop_time; + } // Wait for everything to be done before we return Future done = runtime->issue_execution_fence(ctx); done.wait(); } -void -LegionModelState::finalize( - LegionModelInstance* instance, const unsigned instance_index, - Runtime* runtime, Context ctx, MapperID mapper) -{ - for (auto layer : layers_) +void LegionModelState::finalize(LegionModelInstance *instance, + unsigned const instance_index, + Runtime *runtime, + Context ctx, + MapperID mapper) { + for (auto layer : layers_) { layer->finalize(instance, instance_index, runtime, ctx, mapper); + } } -LegionModelInstance* -LegionModelState::FindInstance( - unsigned instance_index, bool external, bool need_lock) -{ +LegionModelInstance *LegionModelState::FindInstance(unsigned instance_index, + bool external, + bool need_lock) { if (need_lock) { if (external) { AutoLock lock(lock_, false /*exclusive*/); @@ -243,23 +259,17 @@ LegionModelState::FindInstance( return instances_[instance_index]; } -const PartitionStrategy* -LegionModelState::GetStrategy(void) const -{ +PartitionStrategy const *LegionModelState::GetStrategy(void) const { assert(strategy_ != nullptr); return strategy_; } -TRITONSERVER_Error* -LegionModelState::AutoCompleteConfig() -{ +TRITONSERVER_Error *LegionModelState::AutoCompleteConfig() { // FIXME: Check with the FFModel - return nullptr; // success + return nullptr; // success } -TRITONSERVER_Error* -LegionModelState::ValidateModelConfig() -{ +TRITONSERVER_Error *LegionModelState::ValidateModelConfig() { // Constraints that apply to models in general { triton::common::TritonJson::Value igs; @@ -295,8 +305,8 @@ LegionModelState::ValidateModelConfig() { // Build a map from name to tensors of the model for easy lookup - std::map tensors; - for (const auto& io : inputs_) { + std::map tensors; + for (auto const &io : inputs_) { tensors.emplace(io.first, io.second); } @@ -306,10 +316,10 @@ LegionModelState::ValidateModelConfig() if (ios.ArraySize() != tensors.size()) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies " + - std::to_string(ios.ArraySize()) + " inputs, the model has " + - std::to_string(tensors.size())) + (std::string("configuration for model '" + Name() + "' specifies " + + std::to_string(ios.ArraySize()) + + " inputs, the model has " + + std::to_string(tensors.size())) .c_str())); } @@ -322,10 +332,11 @@ LegionModelState::ValidateModelConfig() // Check datatypes std::string io_dtype; RETURN_IF_ERROR(io.MemberAsString("data_type", &io_dtype)); - RETURN_ERROR_IF_TRUE( - (io_dtype == "TYPE_STRING"), TRITONSERVER_ERROR_INVALID_ARG, - std::string("unsupported datatype '") + io_dtype + "' for tensor '" + - io_name + "' for model '" + Name() + "'"); + RETURN_ERROR_IF_TRUE((io_dtype == "TYPE_STRING"), + TRITONSERVER_ERROR_INVALID_ARG, + std::string("unsupported datatype '") + io_dtype + + "' for tensor '" + io_name + "' for model '" + + Name() + "'"); // If a reshape is provided for the input then use that when // validating that the model matches what is expected. std::vector dims; @@ -335,11 +346,12 @@ LegionModelState::ValidateModelConfig() } else { RETURN_IF_ERROR(ParseShape(io, "dims", &dims)); } - for (const auto dim : dims) { + for (auto const dim : dims) { RETURN_ERROR_IF_TRUE( - (dim == WILDCARD_DIM), TRITONSERVER_ERROR_INVALID_ARG, - std::string( - "dynamic tensor is not supported for model '" + Name() + "'")); + (dim == WILDCARD_DIM), + TRITONSERVER_ERROR_INVALID_ARG, + std::string("dynamic tensor is not supported for model '" + Name() + + "'")); } // Check the properties against the corresponding tensor @@ -347,28 +359,26 @@ LegionModelState::ValidateModelConfig() if (it == tensors.end()) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' which is not found in the model") + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + + "' which is not found in the model") .c_str())); } - const auto& tensor = it->second; + auto const &tensor = it->second; if (ToDataType(ModelConfigDataTypeToTritonServerDataType(io_dtype)) != tensor->type) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' with type '" + io_dtype + - "', the tensor in the model has type '" + - DataTypeString(tensor->type) + "'") + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + "' with type '" + + io_dtype + "', the tensor in the model has type '" + + DataTypeString(tensor->type) + "'") .c_str())); } else if (tensor->type == DT_NONE) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "tensor '" + io_name + "' in the model '" + Name() + - "' has unknown type") + (std::string("tensor '" + io_name + "' in the model '" + Name() + + "' has unknown type") .c_str())); } if (max_batch_size_ != 0) { @@ -376,17 +386,17 @@ LegionModelState::ValidateModelConfig() } // put tensor's bound in int64_t to utilize backend common utilities std::vector tensor_bounds; - for (const auto bound : tensor->bounds) { + for (auto const bound : tensor->bounds) { tensor_bounds.emplace_back(bound); } if (dims != tensor_bounds) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' with full shape " + ShapeToString(dims) + - ", the tensor in the model has shape " + - ShapeToString(tensor_bounds)) + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + + "' with full shape " + ShapeToString(dims) + + ", the tensor in the model has shape " + + ShapeToString(tensor_bounds)) .c_str())); } } @@ -395,8 +405,8 @@ LegionModelState::ValidateModelConfig() // Outputs { // Build a map from name to tensors of the model for easy lookup - std::map tensors; - for (const auto& io : outputs_) { + std::map tensors; + for (auto const &io : outputs_) { tensors.emplace(io.first, io.second); } @@ -407,10 +417,10 @@ LegionModelState::ValidateModelConfig() if (ios.ArraySize() > tensors.size()) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies " + - std::to_string(ios.ArraySize()) + " outputs, the model has " + - std::to_string(tensors.size())) + (std::string("configuration for model '" + Name() + "' specifies " + + std::to_string(ios.ArraySize()) + + " outputs, the model has " + + std::to_string(tensors.size())) .c_str())); } @@ -422,10 +432,11 @@ LegionModelState::ValidateModelConfig() // Check datatypes std::string io_dtype; RETURN_IF_ERROR(io.MemberAsString("data_type", &io_dtype)); - RETURN_ERROR_IF_TRUE( - (io_dtype == "TYPE_STRING"), TRITONSERVER_ERROR_INVALID_ARG, - std::string("unsupported datatype '") + io_dtype + "' for tensor '" + - io_name + "' for model '" + Name() + "'"); + RETURN_ERROR_IF_TRUE((io_dtype == "TYPE_STRING"), + TRITONSERVER_ERROR_INVALID_ARG, + std::string("unsupported datatype '") + io_dtype + + "' for tensor '" + io_name + "' for model '" + + Name() + "'"); // If a reshape is provided for the input then use that when // validating that the model matches what is expected. std::vector dims; @@ -435,11 +446,12 @@ LegionModelState::ValidateModelConfig() } else { RETURN_IF_ERROR(ParseShape(io, "dims", &dims)); } - for (const auto dim : dims) { + for (auto const dim : dims) { RETURN_ERROR_IF_TRUE( - (dim == WILDCARD_DIM), TRITONSERVER_ERROR_INVALID_ARG, - std::string( - "dynamic tensor is not supported for model '" + Name() + "'")); + (dim == WILDCARD_DIM), + TRITONSERVER_ERROR_INVALID_ARG, + std::string("dynamic tensor is not supported for model '" + Name() + + "'")); } // Check the properties against the corresponding tensor @@ -447,28 +459,26 @@ LegionModelState::ValidateModelConfig() if (it == tensors.end()) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' which is not found in the model") + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + + "' which is not found in the model") .c_str())); } - const auto& tensor = it->second; + auto const &tensor = it->second; if (ToDataType(ModelConfigDataTypeToTritonServerDataType(io_dtype)) != tensor->type) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' with type '" + io_dtype + - "', the tensor in the model has type '" + - DataTypeString(tensor->type) + "'") + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + "' with type '" + + io_dtype + "', the tensor in the model has type '" + + DataTypeString(tensor->type) + "'") .c_str())); } else if (tensor->type == DT_NONE) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "tensor '" + io_name + "' in the model '" + Name() + - "' has unknown type") + (std::string("tensor '" + io_name + "' in the model '" + Name() + + "' has unknown type") .c_str())); } if (max_batch_size_ != 0) { @@ -476,80 +486,78 @@ LegionModelState::ValidateModelConfig() } // put tensor's bound in int64_t to utilize backend common utilities std::vector tensor_bounds; - for (const auto bound : tensor->bounds) { + for (auto const bound : tensor->bounds) { tensor_bounds.emplace_back(bound); } if (dims != tensor_bounds) { return TRITONSERVER_ErrorNew( TRITONSERVER_ERROR_INVALID_ARG, - (std::string( - "configuration for model '" + Name() + "' specifies tensor '" + - io_name + "' with full shape " + ShapeToString(dims) + - ", the tensor in the model has shape " + - ShapeToString(tensor_bounds)) + (std::string("configuration for model '" + Name() + + "' specifies tensor '" + io_name + + "' with full shape " + ShapeToString(dims) + + ", the tensor in the model has shape " + + ShapeToString(tensor_bounds)) .c_str())); } } } - return nullptr; // success + return nullptr; // success } -TRITONSERVER_Error* -LegionModelState::SetOutputInfos() -{ - for (const auto& output : outputs_) { +TRITONSERVER_Error *LegionModelState::SetOutputInfos() { + for (auto const &output : outputs_) { std::vector tensor_bounds; - for (const auto bound : output.second->bounds) { + for (auto const bound : output.second->bounds) { tensor_bounds.emplace_back(bound); } auto triton_dtype = ToTritonDataType(output.second->type); output_infos_.emplace_back(output.first, triton_dtype, tensor_bounds); } - return nullptr; // success + return nullptr; // success } -void -LegionModelState::LoadLayers(void) const -{ +void LegionModelState::LoadLayers(void) const { std::vector loaded_events; for (unsigned idx1 = 0; idx1 < layers_.size(); idx1++) { - Operator* op = layers_[idx1]; - const LayerStrategy* config = strategy_->layers[idx1]; + Operator *op = layers_[idx1]; + LayerStrategy const *config = strategy_->layers[idx1]; for (unsigned idx2 = 0; idx2 < config->nProcs; idx2++) { Realm::Processor proc = config->local_processors[idx2]; loaded_events.push_back(runtime_->LoadLayer(proc, op)); } } const Realm::Event wait_on = Realm::Event::merge_events(loaded_events); - if (wait_on.exists() && !wait_on.has_triggered()) + if (wait_on.exists() && !wait_on.has_triggered()) { wait_on.external_wait(); + } } -void -LegionModelState::FuseLayers(void) -{ +void LegionModelState::FuseLayers(void) { // FIXME: add support for layer fusion } -void -LegionModelState::FreeLayers(void) const -{ +void LegionModelState::FreeLayers(void) const { std::vector freed_events; for (unsigned idx1 = 0; idx1 < layers_.size(); idx1++) { - Operator* op = layers_[idx1]; - const LayerStrategy* config = strategy_->layers[idx1]; + Operator *op = layers_[idx1]; + LayerStrategy const *config = strategy_->layers[idx1]; for (unsigned idx2 = 0; idx2 < config->nProcs; idx2++) { Realm::Processor proc = config->local_processors[idx2]; freed_events.push_back(runtime_->FreeLayer(proc, op)); } } const Realm::Event wait_on = Realm::Event::merge_events(freed_events); - if (wait_on.exists() && !wait_on.has_triggered()) + if (wait_on.exists() && !wait_on.has_triggered()) { wait_on.external_wait(); + } // Delete layers back to front - for (std::vector::const_reverse_iterator it = layers_.rbegin(); - it != layers_.rend(); it++) + for (std::vector::const_reverse_iterator it = layers_.rbegin(); + it != layers_.rend(); + it++) { delete (*it); + } } -}}} // namespace triton::backend::legion +} // namespace legion +} // namespace backend +} // namespace triton diff --git a/triton/src/types.h b/triton/src/types.h index a034d5f685..b964f3455c 100644 --- a/triton/src/types.h +++ b/triton/src/types.h @@ -151,6 +151,7 @@ enum OperatorType { OP_PRELU, // https://github.com/onnx/onnx/blob/master/docs/Operators.md#PRelu OP_GELU, OP_MULTIHEAD_ATTENTION, + OP_INC_MULTIHEAD_SELF_ATTENTION, OP_FUSED, // Fused operator type for internal fusion optimizations // Parallel Ops OP_REPARTITION,